
kernelport


Bring CUDA-only kernels to Mac, AMD, browsers, and CPU, with proof they are correct.
kernelport is an MCP server + agent skill + CLI. Your coding agent (Claude Code, Codex, Cursor, Gemini CLI) writes the ports; kernelport runs them on real hardware and checks every one against a reference that was itself validated against the original CUDA kernel. A port is only ever reported as PASS if its current code ran on real hardware and matched.
Status: early release (0.2.0, changelog). Triton, CPU and WebGPU backends work and are verified; Metal is verified on Apple Silicon in CI; the HIP runner and zoo ports are written but not yet verified on an AMD GPU. See PROGRESS.md.
A real session on an RTX 5060, with the steps an agent takes through the MCP tools run here from the CLI. Re-record it with scripts/record_demo.py.
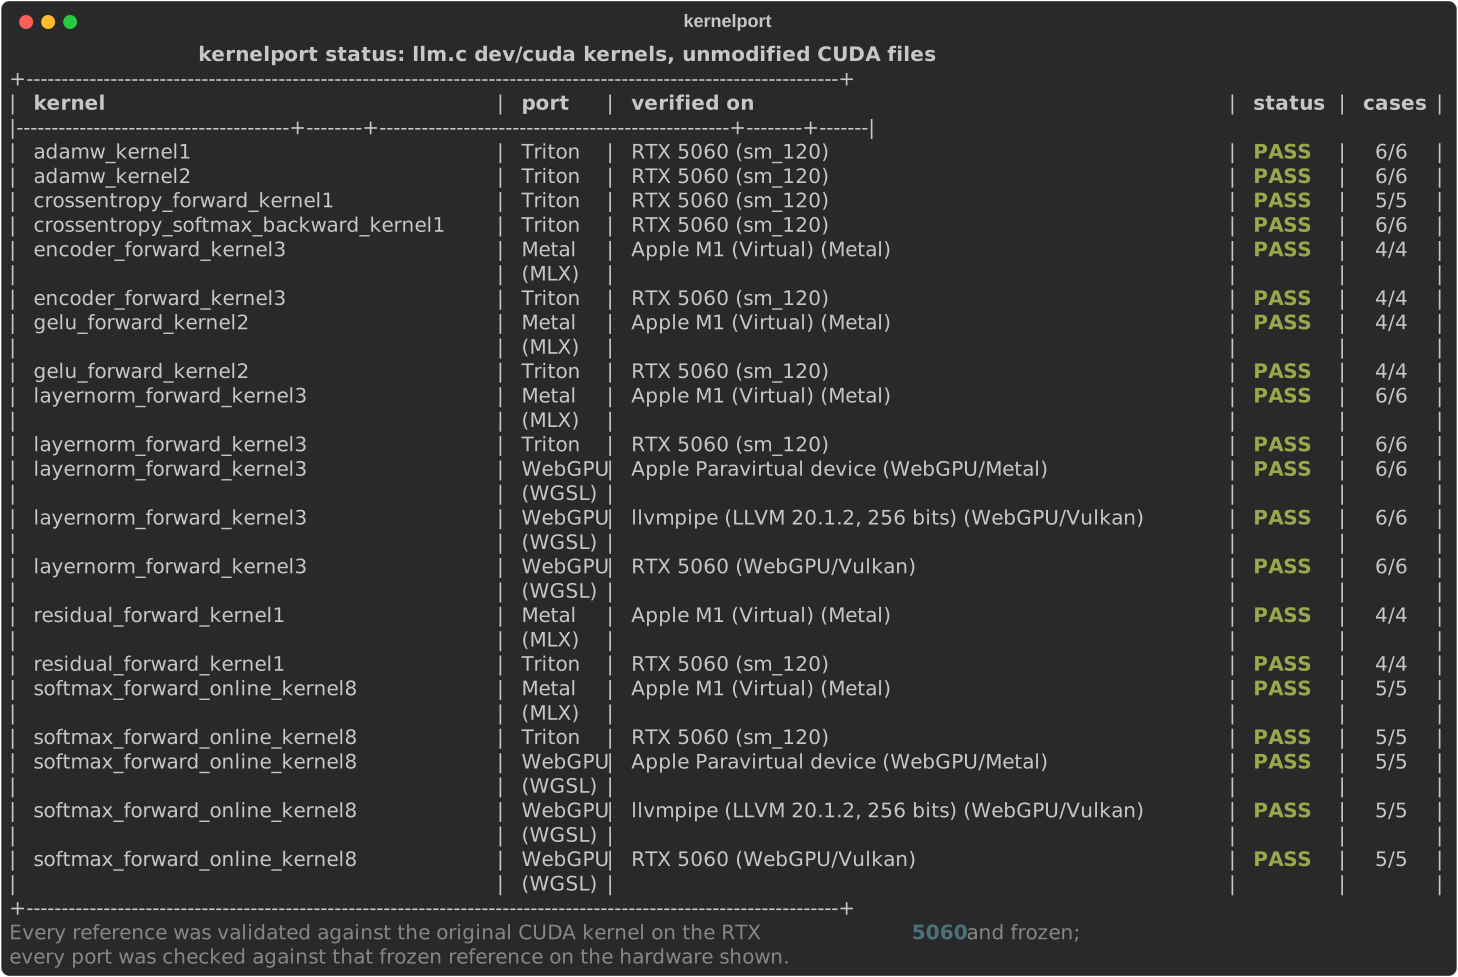
Real code, real hardware: examples/llm.c.
How it works
your repo: kernels/*.cu
      │  scan_kernels                    (lexical CUDA analyzer: params, kinds, features)
      ▼
 PyTorch reference + input spec          written by the agent
      │  validate_reference              runs the ORIGINAL CUDA kernel on every case
      ▼
 frozen reference (sha256 manifest)      only a passing validation can freeze it
      │  write_port / verify_port        port vs frozen reference, every case and dtype
      ▼
 PASS / FAIL (+ compact failure report) / UNVERIFIED (backend not available here)
      │  bench_port                      only after PASS on this machine
      ▼
 report.html / report.md
The agent never sets tolerances, never edits the frozen reference, and gets at most 6 failed verification attempts per port. Those rules are enforced in the tools, not just in the skill. Details: docs/how-it-works.md.
Quick start
# 1. install (CUDA build of torch first; see docs/installation.md)
pip install --index-url https://download.pytorch.org/whl/cu128 torch
pip install "kernelport[cuda,triton,cpu]"

# 2. check what can run here
kernelport doctor

# 3. register the MCP server and skill with your agents (shows every change, asks first)
kernelport setup            # --print to only show instructions, --uninstall to undo
Then, in your repo, ask your agent:
port the CUDA kernels in this repo to Triton and verify them
Real code: llm.c's CUDA kernels on a Mac
examples/llm.c takes nine kernels from Karpathy's
llm.c dev/cuda/ (unmodified files, host code and all):
layernorm, GELU, residual, encoder, online softmax, AdamW and cross-entropy, including bf16 and
128-bit packed loads. References were validated against the original CUDA kernels and frozen on
an RTX 5060, and all nine Triton ports pass there. The Metal ports pass on Apple Silicon in CI
against those same frozen references. Four of the nine were ported by a fresh coding agent
given only the one-line request and kernelport's guide; each of its ports passed on the first
verification. Validation also found an undocumented precondition in llm.c:
softmax_forward_online_kernel8 leaves rows unwritten when C < block size.
examples/flash-attention-minimal
does the same for a FlashAttention forward pass (unmodified flash.cu, PyTorch-extension host
code). The Triton port passes and runs 23x faster than the original on the same GPU; the WGSL
port passes on three WebGPU adapters and the Metal port on Apple M1 (CI). Its README documents where the original's own
__expf and float32 rounding stay within kernelport's fixed tolerance (N <= 384), rather than
loosening it.
Backends
| backend | port language | runs on | status |
|---|---|---|---|
triton |
Triton (Python) | NVIDIA (triton / triton-windows), AMD ROCm | working |
cpu |
Numba (Python) | any machine | working (float32/float64) |
metal |
Metal kernel bodies via MLX metal_kernel |
Apple Silicon | working (float32/float16/bfloat16), verified in CI on an Apple M1 |
webgpu |
WGSL | any Vulkan / Metal / D3D12 GPU via wgpu-native (core WebGPU only, so browser-portable) | working (float32/float16); verified on NVIDIA (Vulkan), Apple (Metal) and llvmpipe (software Vulkan), and in a browser (Edge) on NVIDIA and Intel GPUs |
hip |
HIP C++ via hipRTC (CuPy ROCm) | AMD ROCm | written, launch path tested on NVIDIA, not yet verified on AMD |
Ports for a backend that is not available on the current machine are saved as UNVERIFIED,
never PASS. Commit .kernelport/ and run kernelport verify on the right machine to verify them there.
No coding agent? Use the built-in one (optional)
pip install "kernelport[agent]"
export ANTHROPIC_API_KEY=...        # or: ant auth login
kernelport agent "port the CUDA kernels in this repo to Triton and verify them"
kernelport agent runs Claude (default claude-opus-5-5) in a tool-use loop over the same 15
tools the MCP server exposes, with the workflow skill as its system prompt. It can only act
through those tools, so all writes stay in .kernelport/ and it cannot run shell commands.
Runs are billed to your Anthropic account, so it asks before starting (--yes skips the
prompt). The run stops at --max-turns (default 80). Server-side refusal fallbacks are on by
default (--no-fallbacks to disable).
The kernel zoo
zoo/ holds 12 CUDA kernels with launch specs and references: vector_add, relu, saxpy,
transpose, reduce_sum, softmax, layernorm, rmsnorm, matmul_naive, rope, embedding_gather and
cumsum. Between them they use templates, shared memory, __syncthreads, warp shuffles,
atomics, block reductions, scans, gathers and int64 indices. Every original passes its reference.
kernelport zoo --backend triton|cpu validates them and verifies the stored ports.
Measured on an RTX 5060 Laptop GPU (sm_120) and an i7-14700HX (28 threads), bench case of each spec (the largest), float32. Every stored port passes every case: Triton in fp32/fp16/bf16, cpu in fp32, webgpu in fp32/fp16, metal in fp32/fp16/bf16 (on an Apple M1 GitHub Actions runner, checked on every push; no timings, a virtualized runner is not a fair benchmark). CI also runs the WGSL ports on Apple Metal and on llvmpipe; there the largest embedding_gather cases exceed those adapters' binding limits (128 MiB on llvmpipe) and are reported as not tested.
| kernel | triton vs original CUDA | cpu (Numba) | webgpu (WGSL) | metal (MLX) |
|---|---|---|---|---|
| vector_add | PASS, 1.00x | PASS, 7.8 ms (n/c) | PASS, 1.12 ms (n/c) | PASS |
| relu | PASS, 1.04x | PASS, 5.7 ms (n/c) | PASS, 1.06 ms (n/c) | PASS |
| saxpy | PASS, 1.00x | PASS, 6.4 ms (n/c) | PASS, 1.08 ms (n/c) | PASS |
| transpose | PASS, 1.00x | PASS, 11.2 ms (n/c) | PASS, 1.06 ms (n/c) | PASS |
| reduce_sum | PASS, 1.04x | PASS, 3.4 ms (n/c) | PASS, 0.58 ms (n/c) | PASS |
| softmax | PASS, 1.00x | PASS, 35.5 ms (n/c) | PASS, 0.67 ms (n/c) | PASS |
| layernorm | PASS, 1.00x | PASS, 9.1 ms (n/c) | PASS, 0.96 ms (n/c) | PASS |
| rmsnorm | PASS, 1.00x | PASS, 7.0 ms (n/c) | PASS, 1.13 ms (n/c) | PASS |
| matmul_naive | PASS, 6.20x (tiled tl.dot, IEEE fp32) |
PASS, 40.3 ms (n/c) | PASS, 4.21 ms (n/c) | PASS |
| rope | PASS, 1.00x | PASS, 13.1 ms (n/c) | PASS, 1.42 ms (n/c) | PASS |
| embedding_gather | PASS, 1.02x | PASS, 11.8 ms (n/c) | PASS, 1.46 ms (n/c) | PASS |
| cumsum | PASS, 1.30x | PASS, 6.9 ms (n/c) | PASS, 1.18 ms (n/c) | PASS |
(n/c = wall-clock time (CPU, or WebGPU including submission), not comparable to GPU kernel time.)
Check the WGSL ports in your browser
docs/web/ is a single page with no
dependencies. It runs the 12 WGSL ports on your GPU through the browser's WebGPU and compares every
output with the frozen reference, using kernelport's tolerances, in float32 and (where the GPU has shader-f16) float16. The inputs, expected outputs,
tolerances and shaders come from kernelport's own harness (scripts/build_web_demo.py).
python -m http.server -d docs/web 8000     # then open http://localhost:8000
python scripts/check_web_demo.py           # or headless, in Chrome/Edge (add --discrete for the dGPU)
All 12 ports pass in both dtypes (24/24, 114 cases) in Edge on an RTX 5060 and on Intel UHD Graphics (the i7-14700HX's iGPU). The page also caught a
real portability bug: the softmax port wrote -3.4028235e38, a decimal just above the largest f32.
wgpu-native rounds it, but browsers reject the shader. The webgpu runner now refuses such literals.
CLI
Every MCP tool has a CLI equivalent, so you can drive the workflow by hand or from CI:
| command | MCP tool | what it does |
|---|---|---|
kernelport doctor |
kernelport_doctor |
OS, GPU, extras, each backend with a reason |
kernelport scan [path] |
scan_kernels |
find __global__ kernels (also CUDA strings in .py) |
kernelport read <id> |
read_kernel |
source, parsed signature, suggested input spec |
kernelport skill [name] |
read_skill |
workflow, common_bugs, or a backend guide |
kernelport write-reference |
write_reference |
save a candidate reference + spec |
kernelport validate <id> or --all |
validate_reference |
original CUDA vs reference; freeze on PASS |
kernelport write-port |
write_port |
save a port |
kernelport verify |
verify_port |
port vs frozen reference |
kernelport bench |
bench_port |
time port vs original (after PASS) |
kernelport tune <id> <backend> |
tune_port |
verify + time every TUNE variant, keep the fastest that passes |
kernelport pipeline [name] |
write_pipeline, verify_pipeline |
run ported kernels in a chain; check every stage on real intermediate data |
kernelport pipeline <name> --bench |
bench_pipeline |
time the chain of ports vs the original CUDA chain, whole and per stage (after PASS) |
kernelport status |
list_status |
kernel × backend × hardware table |
kernelport report [--md] |
make_report |
HTML or Markdown report |
kernelport setup |
– | register with Claude Code / Codex / Cursor / Gemini CLI |
kernelport mcp |
– | run the MCP server on stdio |
kernelport agent "<task>" |
– | optional built-in agent (your Anthropic API key) |
Development
python -m venv .venv && .venv/Scripts/activate      # or source .venv/bin/activate
pip install --index-url https://download.pytorch.org/whl/cu128 torch
pip install -e ".[cuda,triton,cpu,dev]"
python -m pytest -q        # ~4 min; GPU tests skip without CUDA, cpu tests need only numba
License
MIT
1 maintainer

Metadata
1 maintainer
Release files for kernelport 0.2.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| kernelport-0.2.0.tar.gz | 345.9 kB | With provenance | Details for kernelport-0.2.0.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| kernelport-0.2.0-py3-none-any.whl | Python 3 | none | any | Details for kernelport-0.2.0-py3-none-any.whl |
Total release size: 511.6 kB
Release files / kernelport-0.2.0.tar.gz
| Download URL | kernelport-0.2.0.tar.gz |
|---|---|
| Size | 345.9 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
fbc83bed8a212be386de39736fad6b61548c6aaac91f6013a4e2ec2a6837381a
|
|
BLAKE2b-256 checksum How to use checksums |
2e5dba2a58bd089e82502c818307d29d3c8cc396d51cbf08a07c8f111c0c0912
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 2, 2026.
Transparency logRelease files / kernelport-0.2.0-py3-none-any.whl
| Download URL | kernelport-0.2.0-py3-none-any.whl |
|---|---|
| Size | 165.7 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
3c48e47f8e3f02ab98ea0647aca1e8d898e9e52a8c1b25c642d05e5e765f8ab4
|
|
BLAKE2b-256 checksum How to use checksums |
d83f5a8a6bea86537c07c42e84bbc4f399079b42ac73260f0f17b1b2490b954b
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 2, 2026.
Transparency logSecurity for kernelport 0.2.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
All 2 files in this release have been uploaded with provenance metadata.
Attestation for kernelport-0.2.0.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 2, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














