
Khazad — You shall not pass.


Transparent, transport-layer semantic cache for LLM API calls powered by Redis Vector Sets.
~50% fewer API calls · ~96% faster on hits · ~50% lower spend · 100% transparent
Illustrative figures at a 0.50 hit rate (280ms cache replay vs. ~7900ms upstream call). Your numbers depend on traffic.
Khazad intercepts LLM HTTP traffic at the transport layer and serves semantically equivalent requests from a Redis vector cache, with zero changes to your application code.
How it works

Key properties:
- Model-aware — each
(provider, model)pair gets its own vector set, so agpt-4oanswer is never served to agpt-4o-minicall, no matter how similar the prompt. Setcache_scope="host"to scope by provider host only, letting every model or deployment on the same provider share one cache (different providers stay isolated — see Configuration). - Conversation-aware — the whole message list (system, user, assistant) is embedded, not just the last user turn. Two different conversations ending with the same follow-up question ("What about its population?") never collide.
- Streaming both ways — cache hits replay as real SSE streams (sync and async clients); cache misses that stream are captured chunk-by-chunk with no added latency and reassembled into a canonical JSON response, so a streamed answer can later serve a non-streamed request and vice versa. Aborted streams are never cached.
Why use it
Semantic caching trades exactness for cost and latency. Know the trade before turning it on. Use it when you have:
- High-volume, repetitive traffic: FAQ bots, support assistants, RAG front-ends where many users ask near-identical questions
- Dev / test / CI environments — stop paying for the same prompt on every run
- Demos and load tests where deterministic, instant responses are a feature
- Cost ceilings on internal tools
Operational caveats:
- Privacy: prompts are embedded and responses are stored in clear text in Redis. If prompts may contain PII or secrets, set a
ttl, enable Redis AUTH/TLS, and treat the Redis instance with the same care as your logs. - Process-wide patch: Khazad wraps every
httpx.Client/AsyncClientcreated afterinit()— non-LLM httpx traffic passes through untouched, but the patch is process-global. Callstop()on shutdown. Usehosts=[...]to restrict interception to the endpoints you actually want cached. - httpx-only: SDKs built on
httpxare covered (OpenAI, Anthropic, Gemini viagoogle-genai, Mistral, and most proxies). SDKs usingrequests,aiohttp, orboto3(AWS Bedrock) are not intercepted. - Single process: the patch lives in the Python process that called
init(). Multiple workers share the Redis cache but each needs its owninit(). - False-positive control: start at
threshold=0.90and raise it if you see wrong hits. Watchavg_hit_similarityinget_stats()— if it sits near your threshold, your traffic may be too diverse to cache safely.
Getting Started
Prerequisites
- Python >= 3.10
- Redis 8 (Vector Sets support required)
docker run -d --name redis8 -p 6379:6379 redis:8
Installation
From PyPI:
uv add khazad
For the OpenAI embedding backend (optional):
uv add khazad[openai-embeddings]
Local / development install:
git clone https://github.com/GuglielmoCerri/khazad.git
cd khazad
uv sync --group dev
uv sync reads pyproject.toml, creates .venv if it doesn't exist, and installs the project itself in editable mode — no separate pip install -e . needed.
To use the local checkout from another project:
uv add --editable /path/to/khazad
Usage
Use the Khazad class directly when you need explicit control over the instance, useful in long-running services, tests, or dependency injection:
from khazad import Khazad

cache = Khazad(
    redis_url="redis://localhost:6379",
    threshold=0.90,
    ttl=3600,
    log_level="DEBUG",
)

print(cache.is_active())   # True
print(cache.get_stats())   # Stats(total_requests=0, ...)
Available functions: init(), stop(), get_stats(), flush(), is_active(). See API Reference for details.
Examples
Khazad activates once and intercepts every LLM SDK that uses httpx underneath, no per-provider wiring needed. For further examples see the examples folder.
Pick the provider you use:
OpenAI — official SDK against api.openai.com
import os
import time

from openai import OpenAI

from khazad import Khazad

cache = Khazad(redis_url="redis://localhost:6379", threshold=0.90, log_level="DEBUG")

client = OpenAI(api_key=os.environ["OPENAI_API_KEY"])

prompt = "What is the capital of Italy?"

for i in range(2):
    start = time.perf_counter()
    response = client.chat.completions.create(
        model="gpt-4o",
        messages=[{"role": "user", "content": prompt}],
    )
    elapsed = (time.perf_counter() - start) * 1000
    print(f"[call {i + 1}] {elapsed:.1f}ms — {response.choices[0].message.content}")

print(cache.get_stats().to_dict())
cache.stop()
Matches */chat/completions and */responses paths. Streaming requests also cached.
Azure OpenAI — Azure deployments with Entra ID auth via AzureOpenAI SDK
import os
import time

from azure.identity import DefaultAzureCredential, get_bearer_token_provider
from openai import AzureOpenAI

from khazad import CacheScope, Khazad

cache = Khazad(
    redis_url="redis://localhost:6379",
    threshold=0.90,
    cache_scope=CacheScope.HOST,
    namespace="azure_openai_example",
)

endpoint = os.environ["AZURE_OPENAI_ENDPOINT"]
deployment = os.environ.get("AZURE_OPENAI_DEPLOYMENT", "gpt-4.1")
token_provider = get_bearer_token_provider(
    DefaultAzureCredential(), "https://cognitiveservices.azure.com/.default"
)
api_version = os.environ.get("AZURE_OPENAI_API_VERSION", "2024-12-01-preview")

client = AzureOpenAI(
    api_version=api_version,
    azure_endpoint=endpoint,
    azure_ad_token_provider=token_provider,
)

prompt = "What is the capital of Spain?"

for i in range(2):
    start = time.perf_counter()
    response = client.chat.completions.create(
        model=deployment,
        messages=[{"role": "user", "content": prompt}],
    )
    elapsed = (time.perf_counter() - start) * 1000
    print(f"[call {i + 1}] {elapsed:.1f}ms — {response.choices[0].message.content}")

print(cache.get_stats().to_dict())
cache.stop()
It authenticates with Microsoft Entra ID (DefaultAzureCredential) — no API key needed — and uses cache_scope=CacheScope.HOST so every deployment on the same Azure resource shares one cache. API-key auth works too: Khazad matches the request path (/chat/completions), not the auth method or host.
OpenAI-compatible proxies — LiteLLM, vLLM, Ollama, …
import time

from openai import OpenAI

from khazad import Khazad

cache = Khazad(redis_url="redis://localhost:6379", threshold=0.90, namespace="ollama_example")

client = OpenAI(base_url="http://localhost:11434/v1", api_key="ollama")
model = "llama3"

prompt = "What is the capital of Spain?"

for i in range(2):
    start = time.perf_counter()
    response = client.chat.completions.create(
        model=model,
        messages=[{"role": "user", "content": prompt}],
    )
    elapsed = (time.perf_counter() - start) * 1000
    print(f"[call {i + 1}] {elapsed:.1f}ms — {response.choices[0].message.content}")

print(cache.get_stats().to_dict())
cache.stop()
Any host whose URL path ends with /chat/completions or /responses is cached. Covers vLLM (http://host:8000/v1/...), Ollama (http://localhost:11434/v1/...), Mistral, etc.
Anthropic — Claude via official SDK
import os
import time

from anthropic import Anthropic

from khazad import Khazad

cache = Khazad(redis_url="redis://localhost:6379", threshold=0.90, namespace="anthropic_example")

client = Anthropic(api_key=os.environ["ANTHROPIC_API_KEY"])
model = "claude-haiku-4-5-20251001"

prompt = "What is the capital of France?"

for i in range(2):
    start = time.perf_counter()
    message = client.messages.create(
        model=model,
        max_tokens=256,
        messages=[{"role": "user", "content": prompt}],
    )
    elapsed = (time.perf_counter() - start) * 1000
    print(f"[call {i + 1}] {elapsed:.1f}ms — {message.content[0].text}")

print(cache.get_stats().to_dict())
cache.stop()
Matches api.anthropic.com/v1/messages. Streaming responses replayed from cache as SSE.
Google Gemini — google-genai SDK
import os
import time

from google import genai

from khazad import Khazad

cache = Khazad(redis_url="redis://localhost:6379", threshold=0.90)
client = genai.Client(api_key=os.environ["GEMINI_API_KEY"])

for i in range(2):
    start = time.perf_counter()
    response = client.models.generate_content(
        model="gemini-2.5-flash",
        contents="What is the capital of Italy?",
    )
    elapsed = (time.perf_counter() - start) * 1000
    print(f"[call {i + 1}] {elapsed:.1f}ms — {response.text}...")

print(cache.get_stats().to_dict())
cache.stop()
Matches generativelanguage.googleapis.com/*/models/*:generateContent. Gemini streaming (:streamGenerateContent) passes through uncached.
Supported Providers
| Provider | URL pattern matched | Streaming |
|---|---|---|
| OpenAI Chat Completions | any host, path ending /chat/completions |
cached + replayed |
| OpenAI Responses API | any host, path ending /responses |
cached + replayed |
| Azure OpenAI | covered by chat/completions matcher | cached + replayed |
| OpenAI-compatible proxies | covered by chat/completions matcher | cached + replayed |
| Anthropic | api.anthropic.com/v1/messages |
cached + replayed |
| Google Gemini | generativelanguage.googleapis.com/*:generateContent |
pass-through |
API Reference
The module exposes five functions as the singleton API. The Khazad class exposes the same surface as instance methods (no init, instantiation does that).
| Function | Description |
|---|---|
init(...) |
Activate the global singleton: builds the embedder, connects to Redis, installs the httpx transport patch. Required before any LLM traffic; calling twice without stop() is a no-op. See Configuration for parameters. |
stop() |
Restore original httpx transports, close Redis, and clear the singleton. Idempotent. Cached data in Redis stays. |
get_stats() |
Returns a dictionary with a thread-safe snapshot of cache metrics (requests, hits, misses, hit rate, avg similarity). |
flush() |
Clear all cached entries in the current namespace and reset stats counters. Destructive. |
is_active() |
Returns True if Khazad is currently running (initialized and not stopped). |
Configuration
All parameters are the same whether you use khazad.init() or Khazad(...):
Khazad(
    redis_url="redis://localhost:6379",
    threshold=0.90,
    ttl=3600,
    namespace="khazad",
    embedder="huggingface",
    embedding_model="redis/langcache-embed-v2",
    log_level="INFO",
    hosts=None,
    cache_scope="model"
)
| Parameter | Default | Description |
|---|---|---|
redis_url |
"redis://localhost:6379" |
Connection URL for the Redis 8 instance that stores vectors and cached responses. |
threshold |
0.90 |
Cosine similarity threshold (0.0-1.0) above which a request counts as a cache hit. |
ttl |
3600 |
Time-to-live in seconds for cached response bodies; None means no expiry. |
namespace |
"khazad" |
Prefix for all Redis keys, isolating this cache from other data and other namespaces. |
embedder |
"huggingface" |
Embedding backend: "huggingface" (free, local) or "openai" (paid API). |
embedding_model |
"redis/langcache-embed-v2" |
Model used to embed prompts; must match the chosen embedder. |
log_level |
"INFO" |
Logging verbosity: DEBUG, INFO, WARNING, or ERROR. |
hosts |
None |
Opt-in host allowlist; None means all matching hosts (see below). |
cache_scope |
"model" |
Cache partitioning: "model" (per (host, model)) or "host" (per provider, see below). |
hosts — opt-in allowlist. By default Khazad considers traffic to any host that matches a provider URL pattern. Pass an explicit allowlist to restrict interception to the endpoints you intend to cache; everything else passes through untouched. Supports exact hosts and *. wildcard subdomains:
khazad.init(hosts=["api.openai.com", "*.openai.azure.com"])
cache_scope — share one cache across a provider's models. Driven by the CacheScope enum (importable from khazad); the string values "model" and "host" are accepted too. By default (CacheScope.MODEL) each (host, model) pair gets its own vector set, so a gpt-4o answer never serves a gpt-4o-mini call. Set it to CacheScope.HOST to scope by host only — every model or deployment on the same provider then shares a single cache:
from khazad import CacheScope

khazad.init(cache_scope=CacheScope.HOST)   # or cache_scope="host"
The host always stays part of the scope, so different providers never mix (an Azure OpenAI response is never replayed to a Gemini client). Use it only for format-compatible pools — e.g. multiple Azure OpenAI deployments, or treating gpt-4o and gpt-4o-mini as interchangeable. The trade-off is semantic: a smaller model may serve an answer originally produced by a larger one.
Threshold guidance:
0.95+— strict, near-identical prompts only0.90— recommended default0.85— aggressive, higher hit rate
TTL: the response body expires in Redis after ttl seconds. Khazad prunes the matching vector automatically the next time it is found without a body, so expired entries clean themselves up.
Embedding Backends
| Backend | Cost | Notes |
|---|---|---|
huggingface (default) |
Free | Downloads model on first use |
openai |
Paid | uv add khazad[openai-embeddings] |
Observability
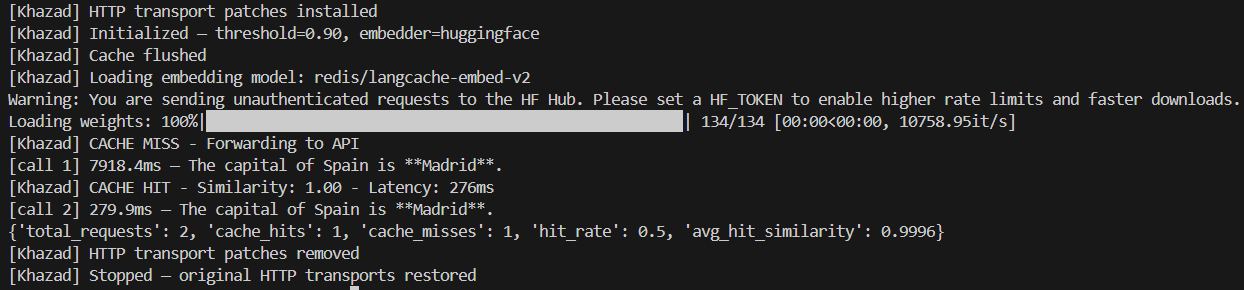
Khazad emits a log line for every intercepted request, so you can watch cache behaviour in real time. A hit reports the cosine similarity that triggered it and the replay latency; a miss notes that the request was forwarded upstream. Raise log_level to DEBUG for per-request detail, or keep it at INFO for just hits and misses.
[Khazad] CACHE HIT - Similarity: 0.94 - Latency: 4ms
[Khazad] CACHE MISS - Forwarding to API
For aggregate metrics, call get_stats() at any time. It returns a thread-safe snapshot of total requests, hits, misses, the resulting hit rate, and the average similarity of served hits — ideal for periodic logging or exposing as a Prometheus gauge. Watch avg_hit_similarity: if it hovers near your threshold, your traffic may be too diverse to cache safely and you should raise the threshold.
cache.get_stats().to_dict()
# {'total_requests': 1000, 'cache_hits': 720, 'cache_misses': 280,
#  'hit_rate': 0.72, 'avg_hit_similarity': 0.943}
Contributing
Contributions welcome — see CONTRIBUTING.md. Please read it before opening a pull request, as it covers the branching model, coding conventions, and the lint and test checks your changes are expected to pass.
The unit and integration suites use fake embedders and mock transports, so the full test run needs neither a live Redis instance nor real API keys.
License
1 maintainer

Release files for khazad 0.1.3
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| khazad-0.1.3.tar.gz | 6.2 MB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| khazad-0.1.3-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 6.2 MB
Release files / khazad-0.1.3.tar.gz
| Download URL | khazad-0.1.3.tar.gz |
|---|---|
| Size | 6.2 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
45e084b8f80cad02d7ee9f6a58273e06b4fd60730b87f65495d45cc78578ea66
|
|
BLAKE2b-256 checksum How to use checksums |
28a64c7faa390902df0f441ddb974e8e45b3f8ef53002eb629cde4233fb197a7
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.13.12
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Jun 29, 2026.
Transparency logRelease files / khazad-0.1.3-py3-none-any.whl
| Download URL | khazad-0.1.3-py3-none-any.whl |
|---|---|
| Size | 30.5 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
caf6c343fc86ccfc0fc62e66ff94ebaf36940c518434e62296940ded5e925286
|
|
BLAKE2b-256 checksum How to use checksums |
cabab09020fa6c75057b96ede56c5a96e421d0689650604bfebffadbffa48208
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.13.12
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Jun 29, 2026.
Transparency log













