
kvleak
Find out where your AI coding agent leaks prompt-cache money, and how to stop it. · 中文



A 99.0% cache hit rate, and the session still leaked $82. On Claude Fable 5.1 one cache miss costs as much as 80 hits. In a 30-day audit of real Claude Code use, 2% of calls carried more than half of all uncached input. See the numbers →
Your agent probably reports a 90%+ cache hit rate, and you are still overpaying. A cache miss costs about 12× more than a hit, and the misses are rare but huge. They come from idle gaps that outlive the 5-minute TTL, from model switches, and from subagents that start cold. In real audits, about 5% of calls burn about half of all uncached input.
kvleak reads the transcripts that are already on your disk, finds every
expensive miss, says why it happened, and puts a dollar figure on it.
uvx kvleak # or: pipx run kvleak · pip install kvleak
No API key, no config, no network calls, no dependencies. It reads
~/.claude/projects by default and any JSONL with token usage via --path.
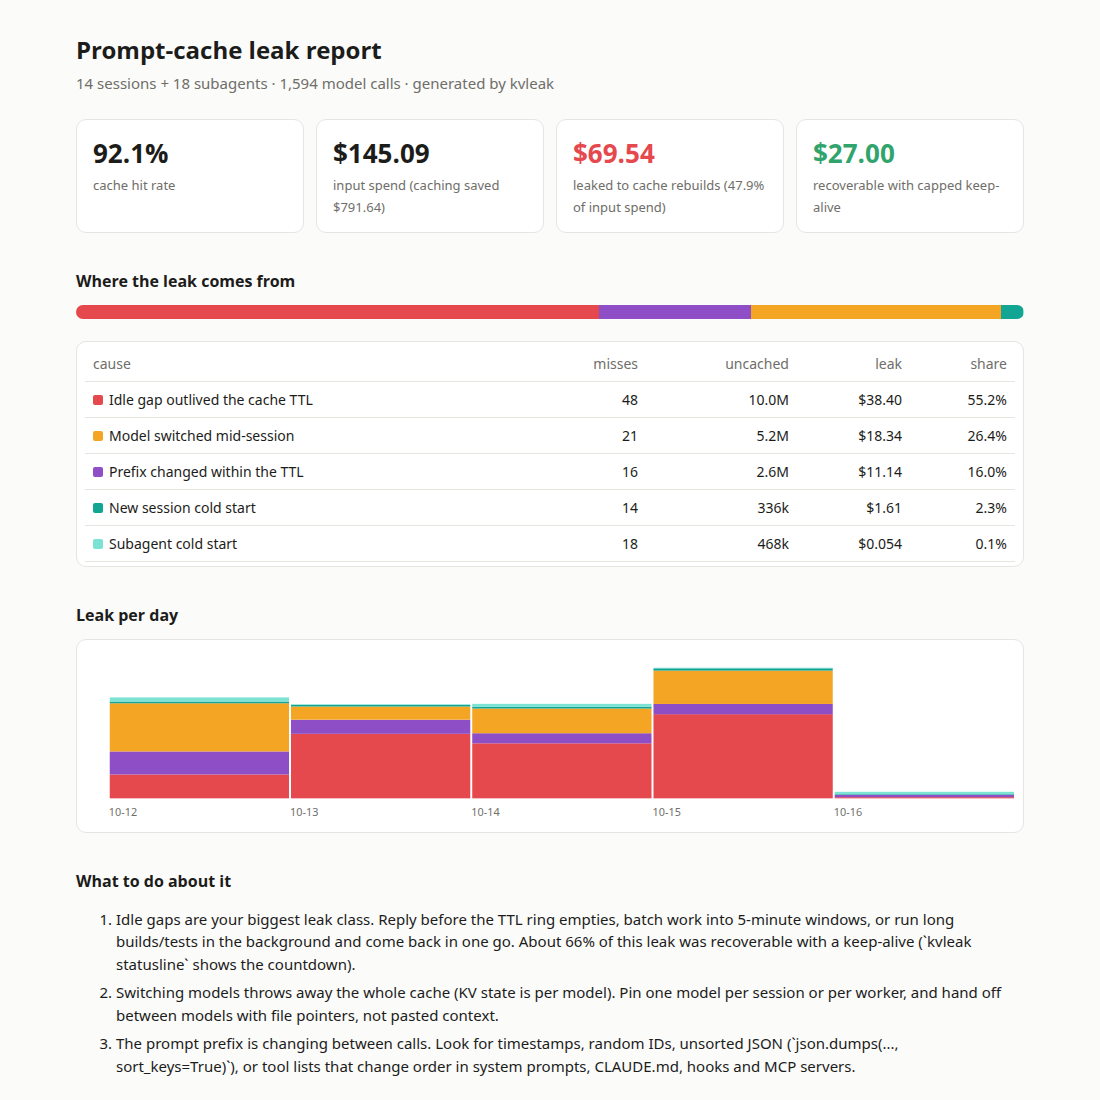
 kvleak · prompt-cache leak report
 14 sessions + 18 subagents · 1,594 model calls · 10.0k min miss size

  Cache hit rate    92.1%  ██████████████████████
  Input spend       $145.09   caching already saved you $791.64
  Leaked to misses   $69.54   47.9% of input spend went to cache rebuilds and cold starts
  Recoverable        $27.00   with break-even-capped keep-alive pings alone

 Where the leak comes from
  cause                            misses  uncached    leak  share
  Idle gap outlived the cache TTL      48     10.0M  $38.40  55.2%  ████████▊
  Model switched mid-session           21      5.2M  $18.34  26.4%  ████▏
  Prefix changed within the TTL        16      2.6M  $11.14  16.0%  ██▌
  New session cold start               14      336k   $1.61   2.3%  ▎
  Subagent cold start                  18      468k  $0.054   0.1%

 What to do about it
  1. Idle gaps are your biggest leak class. Reply before the TTL ring empties, ...
  2. Switching models throws away the whole cache (KV state is per model). ...
Output from the bundled synthetic demo: python examples/make_demo.py demo && kvleak --path demo
Real numbers
| 30 days of interactive Claude Code sessions | 97.5% hit rate, but 27.5% of input spend went to cache rebuilds |
| Share of that leak caused by idle gaps | 82% (median gap 2.8 h; Claude Code now uses the 1 h TTL) |
| Cost of one miss on a 200k context | $3.95 on Fable 5.1, $1.56 on Opus 5.5 (1 h TTL) |
| 6-worker swarm, pointers + warm workers + pinned models | −86% input cost in simulation |
| Compaction advisor replayed on real history (compact only above 200k) | −58% input spend with 98 compactions in 30 days (≈3 per session); −40% with 23 above 400k |
kvleak tune --apply on the same 30 days |
−$909 (−45%) from four settings Claude Code already has; auto-compact at 200k instead of ~967k is −58% alone |
What filled the context (kvleak diet --all, 33 sessions, 20.8M tokens) |
29% shell output, 21% scripts the model sent to the shell, 14% thinking (kept in context on current models), 10% pasted text, 6% the ~40k system prompt; whole-file reads only 4% |
| Long tool loops (≥20 calls) replayed as subagents | 114 loops re-read their starting history 4,707 times for $351; in fresh subagents −$319 |
Mechanical chains (3+ consecutive ls/cat/grep/read steps with no decision between them) |
493 chains, 2,235 of 9,924 calls; as single scripts, up to −$160 |
kvleak refine on the same history |
5 rules for CLAUDE.md, each with its evidence; together they cover ≈$640 / 30 d of measured waste |
Methodology and reproduction commands: docs/benchmarks.md.
What you get
| Command | What it does |
|---|---|
kvleak |
Audits every session: hit rate, dollars leaked, leak broken down by cause, leakiest sessions, worst single misses, and concrete next steps. |
kvleak --since 7d --html report.html |
A self-contained HTML report (light/dark, no JS) you can share with your team. --markdown and --json also work. |
kvleak session <id> |
Call-by-call timeline of one session, with each miss flagged and explained. |
kvleak statusline --install |
Adds a live cache TTL countdown to Claude Code: ◕ cache 3:41 · 182k ctx · rebuild $0.89. |
kvleak advise |
Tells you whether to /compact or hand off to a fresh session now, and when that pays for itself. --backtest replays your history with the advisor in the loop. |
kvleak tune --apply |
Backtests Claude Code's own cache settings (auto-compact window, cache TTLs, idle compaction) on your history and writes the winners to settings.json. |
kvleak diet |
Shows what filled the context (tool results, your pastes, the replies themselves, the system prompt) and what each piece cost to carry, with the costliest single items named. --all aggregates 30 days. |
kvleak hooks --install |
Claude Code hooks that keep long shell output out of the context (the model sees head + tail + error lines + a path to the rest) and make compaction lossless (everything dropped is archived and the model is told how to search it). |
kvleak recall "<regex>" |
Searches what a compaction dropped. The model runs it too. |
kvleak refine --apply |
Writes evidence-backed context-hygiene rules to CLAUDE.md, each gated on a dollar figure from your own history; --probe later tells you which rules changed behaviour. |
kvleak breakeven 150k --idle 20m |
Tells you whether to keep this cache alive or let it die. |
kvleak pointer build.log --status FAIL |
Turns a huge file into a ~60-token hand-off message for multi-agent boards. |
kvleak --fail-over 15 |
Exits with code 2 when more than 15% of input spend leaked, so it can gate CI or nightly jobs. |
Every miss gets a cause
| Cause | What happened | Typical fix |
|---|---|---|
| Idle gap outlived the TTL | You were away for more than 5 min (or 1 h), so the next message rebuilt everything. | Watch the statusline countdown, batch work, or use capped keep-alive pings. |
| Prefix changed within the TTL | Something near the top of the prompt changed: a timestamp, unsorted JSON, or a different tool list. | Make the prefix deterministic. |
| Model switched mid-session | KV caches are per model, so a switch always means a full-price rebuild. | Pin one model per session or worker and hand off with pointers. |
| History compacted | /compact or auto-compact rewrote the history. |
Compact once at a natural break, not mid-task. |
| Cold start / subagent cold start | A fresh agent paid full price for its system prompt and tool schemas. | Reuse warm workers; keep system prompts identical. |
Only the avoidable part counts as leak: the context the cache already held, priced at write cost minus read cost. A new user message or new tool output would be paid for anyway, so it is not counted. Details: docs/how-it-works.md.
Live TTL countdown in Claude Code
kvleak statusline --install # backs up settings.json; refuses to overwrite an existing statusLine without --force
◕ cache 3:41 · 182k ctx · rebuild $0.89        (green → yellow → red as the TTL drains)
○ cache cold · next msg rebuilds 182k ($0.89)
When the ring is almost empty, sending your next message now refreshes the
TTL at the cost of a cache read. If you already have a statusline script, call
kvleak statusline from it; it reads the same JSON on stdin.
When is a big context costing more than it saves?
Caching makes a long context cheap, but not free. Every call re-reads the whole prefix at the cache-read price, and every miss rebuilds all of it. So a 400k-token session costs you on every call. Compacting costs money once and makes every later call cheaper:
pays off after R* = one-time cost / ((C − S) · (read + miss_rate · (write − read))) calls
kvleak advise fills that in for your newest session. It learns how long your
sessions usually run, and how often they miss, from your own history:
$ kvleak advise

  933c7e07 · my-project · claude-opus-5-5
  Context now          207k  (+1.0k/call)
  Carrying it costs    $0.077 per call (cache read + 2.2% miss risk)
  Calls so far         106  ·  expected still to come ≈ 130 (from your history)

  option                      new context  one-time cost  pays off after  expected saving
  /compact                          33.0k         $0.265       4.1 calls            $8.20
  hand-off doc + new session        28.0k         $0.125       1.9 calls            $8.58

  → Write a short hand-off doc and start a fresh session (or /compact; both pay off within 4 calls).
The statusline shows the same advice live: ● cache 59:47 · 249k ctx · rebuild $1.99 · ⚠ /compact saves ~$9.42.
Once the cache has gone cold it switches to ⚠ /compact first saves ~$X: the
next message would rewrite the whole context at 2× anyway, and one full-price
read followed by a small prefix is cheaper than that.
In a backtest on 30 days of real sessions, an advisor that only knew the past would have cut input spend by 58% compacting about 3 times per session (only above 200k context), or by 40% compacting 23 times in total (only above 400k). See docs/benchmarks.md. These numbers cover money only. Compact when the summary would still carry what the rest of the session needs.
Let Claude Code do it: kvleak tune
Claude Code can compact for you (autoCompactWindow), pick the cache TTL
(promptCacheTtl, subagentPromptCacheTtl) and compact idle sessions before
the cache dies (CLAUDE_CODE_IDLE_COMPACT_MIN_TOKENS). The defaults are tuned
for nobody in particular. kvleak tune replays your last 30 days under each
value and shows what it would have saved:
$ kvleak tune

  setting                                         now           best   saving / 30d  why
  autoCompactWindow                               auto (~967k)  200k        $720.52  98 compactions over 33 sessions instead of 32 · −57.7% of input spend
  promptCacheTtl                                  1h            1h                –  33 interactive sessions: 1h costs $1,347, 5m costs $3,231
  subagentPromptCacheTtl                          5m            5m                –  271 subagents: 5m costs $274, 1h costs $386
  `claude -p` runs: CLAUDE_CODE_PROMPT_CACHE_TTL  1h            5m          $169.11  20535 one-shot runs: 5m costs $301, 1h costs $471 · set it in the batch script
  CLAUDE_CODE_IDLE_COMPACT_MIN_TOKENS             200k          100k         $19.72  153 idle gaps ≥54 min · compacting there nets $212 at 200k, $232 at 100k
  subagent cold starts                            271 × 19.8k   staggered    $11.04  140 of 271 started with nothing cached · launch one, let it warm the 10.9k shared prefix, then the rest

  Total if applied: $740.43 per 30d  (+$180.15 from the habits above)
  Write these to ~/.claude/settings.json: kvleak tune --apply  (undo: kvleak tune --reset)
--apply backs up settings.json first; --reset removes exactly the keys it
wrote. --min-window 300k keeps auto-compaction from firing below 300k if you
would rather keep more detail. The audit also reports dead writes: tokens
written at the 1h cache-write premium (2×) that nothing ever read back. For
one-shot claude -p batches that is about 42% of their bill, which is why the
5m TTL wins there.
What filled the context in the first place?
Compaction treats the context as a blob. kvleak diet opens it up: every tool
result, pasted message and reply is a block that entered the context at some
call and was re-read on every call after it until a compaction dropped it.
Token counts are calibrated to the API's own usage numbers (images priced by
pixels, not base64 length), and each block gets a carried cost: tokens ×
calls it stayed × cache-read price.
$ kvleak diet --all

  What filled the context · 33 sessions · 9,824 calls · 20.8M tokens entered · carrying it cost $958
  source                 items  tokens  share  biggest  carried cost
  Bash results           7,760    6.1M  29.2%    15.9k       $297.87
  Bash inputs            7,761    4.5M  21.5%    10.2k       $205.07
  Thinking               6,472    3.0M  14.2%    12.4k       $140.21
  Your messages          1,891    2.0M   9.6%    49.7k        $82.10
  System prompt & tools     33    1.3M   6.3%    61.6k        $61.91
  Write inputs             349    999k   4.8%    27.1k        $46.95
  Read results             421    925k   4.4%    25.2k        $38.88
  Assistant text         3,761    875k   4.2%     6.4k        $37.27

  Long turns (≥20 calls before you spoke again)
  114 turns · 4,707 calls · re-reading the history they started with cost $351.12 · in fresh subagents: −$318.66

  Thinking  3.0M of 10.1M output tokens (29.4%); kept in context until compaction on current models
            · opus-5-5 at medium: 238/call · fable-5-1 at high: 497/call · opus-5-5 at high: 299/call

  How to shrink it
  1. Bash results is 29% of what entered the context. Pipe through `tail -n 40` / `head`, redirect long
     logs to a file and `kvleak pointer` it, and run long jobs in the background ...
  2. Bash inputs is 21% of what entered the context. Every inline script or heredoc the model sends to
     Bash is re-read on every later call. Put multi-line scripts in a file once and run the file ...
Two surprises in that table. Half of the context is the shell: what came
back from it (29%) and the scripts the model sent to it (21%), and both have
cheap fixes (tail, a file instead of a heredoc, bashOutputMaxChars, which
kvleak tune now backtests). And on current models thinking stays in the
context until a compaction, so it is 14% of what gets re-read; but on this
history dropping /effort from high to medium would have saved only $3, so
the lever is compaction, not effort. The biggest single number is the long
turns: 114 tool loops of 20+ calls re-read the history they started with
4,707 times. Run those loops in a fresh subagent and $319 of that goes away.
diet also counts mechanical chains: three or more consecutive calls that
each run one ls, cat, grep, find or small read with no real decision
in between (under 200 thinking tokens, under 300 characters of reply). Every
step re-reads the whole context; a script would read it once. On the same
history: 493 chains, 2,235 of 9,924 calls, up to −$160 as scripts. Calls, not
tokens, are the bill.
Borrowed from REPL harnesses: hooks, recall, refine
Harnesses that give the model a persistent REPL instead of a tool list
(Prime Agent) keep tool
output in variables: the model prints what it needs, the rest stays out of
the prompt, and the history a compaction replaces stays retrievable. Harness
improvement loops (Harness²)
edit the files around a fixed model and keep only edits that evidence
supports. Claude Code can't change its tool model, but its hooks and
CLAUDE.md are enough to get most of both.
kvleak hooks --install # four hooks in ~/.claude/settings.json (undo: --uninstall)
| hook | what it does |
|---|---|
PostToolUse on Bash |
A result over 8,000 characters (--max-chars) is written to ~/.cache/kvleak/outputs/<session>/<id>.txt. The model sees the head, the tail, every line that looks like an error (with the two lines after it), repeated lines collapsed to (×N), and the path. Nothing is lost; it is one grep away. |
PreCompact |
Every tool result, message and reply in the transcript is appended to ~/.cache/kvleak/history/<session>/history.jsonl before the summary replaces them. |
PostCompact |
The summary is saved next to it, so you can see what the summary kept. |
SessionStart (compact) |
The model is told the archive exists, gets a one-line map of every request in it, and the kvleak recall command. The first thing it does after a compaction is no longer "re-run the tests to see what failed". |
$ kvleak recall "AssertionError" --session 7ff95ce0
#312 result Bash pytest -q tests/test_policy.py
    > FAILED tests/test_policy.py::test_window_sweep - AssertionError: assert 98 == 96
$ kvleak recall --show 312 | head -40
kvleak refine is the continual-harness half. It takes what diet and tune
measured and proposes a short block for ~/.claude/CLAUDE.md (or
./CLAUDE.md with --local). A rule appears only when its evidence is worth
at least --min-usd (default $5) over the window, and the evidence is written
into the rule so the model knows why:
$ kvleak refine

  5 rules with evidence from 33 sessions · 30d
  • loops-in-subagents  ~$320 / 30d
    Long loops: when a task will take more than ~20 tool calls (...), run it in a subagent that reports back a few lines
    evidence: 116 loops of 20+ calls re-read 4,754 calls of history for $353; in subagents that would have been $320 less
  • batch-steps  ~$160 / 30d
    Mechanical steps: combine sequences of `ls`, `cat`, `grep`, `find` and small reads into one command or one script
    evidence: 493 chains of 3+ mechanical calls (2,235 calls); as single scripts they would have saved up to $160
  • scripts-in-files  ~$103 / 30d
  • shell-output      ~$32 / 30d
  • edit-not-write    ~$24 / 30d
--apply writes the block (backed up, removable with --remove; it costs
about 150 tokens per call to carry) and records today's behaviour numbers.
A week later, kvleak refine --probe contrasts the sessions since with the
ones before, one metric per rule (tokens per Bash result, share of calls in
chains, share of calls in 20+ call loops, ...), and says which rules moved
their number and which did not. That is Harness²'s probe step run on your
real sessions instead of a benchmark; it shows whether behaviour changed, not
that the rule caused it.
Should I keep this cache alive?
$ kvleak breakeven 100k --model claude-sonnet-5 --idle 20m

  Cached prefix 100k on claude-sonnet-5 (5m TTL)
  Rebuild if it expires   125k tok-equiv  ($0.250)
  ...of which avoidable   115k tok-equiv  ($0.230)
  One keep-alive ping     10.0k tok-equiv  ($0.020)
  Break-even              11 pings ≈ 54m30s of idle time

  Idle 20m00s: 4 pings cost 40.0k tok-equiv  ($0.080), saving 75.0k tok-equiv  ($0.150). Keep it alive.
The rule is K_max = floor((write − read) / read): 11 pings at 0.10× reads,
24 at 0.05×, 49 at 0.025×. Past that, let the cache expire.
Running multi-agent swarms?
Multi-agent and multi-model setups multiply leaks in three ways:
- caches never cross models
- shared boards make every agent re-read everyone's logs, which costs O(N²)
- one-shot subagents each pay a cold-start tax
The multi-agent cache playbook describes six layers of
practice: pinned models with pointer hand-offs, a script → small model → large
model funnel, warm workers with TTL batching, a slim board contract,
deterministic prefixes, and deliberate compaction. It includes a contract you
can paste straight into your swarm's instructions, and kvleak measures each
layer.
$ kvleak pointer /tmp/build.log --status FAIL --note "3 tests failing in //pkg"
{"bytes":40211,"lines":512,"note":"3 tests failing in //pkg","path":"/tmp/build.log","sha256":"9f2c1e07a1b4c3d2","status":"FAIL","tail":[...]}
Supported logs
| Source | How |
|---|---|
| Claude Code (incl. subagents) | automatic: ~/.claude/projects, respects $CLAUDE_CONFIG_DIR |
| Any JSONL with usage counters | --path <dir-or-file>. Auto-detects Anthropic (cache_read_input_tokens), OpenAI (prompt_tokens_details.cached_tokens), Gemini (cachedContentTokenCount) and flat agent-framework keys (input_tokens, cache_read_tokens, created_at). |
Prices for current Claude models are built in (kvleak models). For other
providers, add a pricing file; see examples/pricing.json.
Models without a price still get full token-level analysis.
Want your agent harness supported natively? A reader is one small function
that yields Steps. See src/kvleak/sources.py and CONTRIBUTING.md.
Use it as a library
from kvleak import analyze, load

report = analyze([load("session.jsonl")])
print(report.hit_rate, report.leak_usd, report.buckets["ttl_expiry"])
FAQ
Is my data sent anywhere? No. kvleak only reads local files and makes no network calls.
I'm on a subscription, not the API. Does this matter? Yes. Cache misses use up your rate-limit headroom the same way they would cost money on the API. Read the dollar figures as relative weights.
My hit rate is 95%. Am I fine? Maybe not. Hit rate counts tokens, not dollars, and one 800k-token rebuild weighs as much as thousands of cheap hits. Look at the Leaked line instead.
How accurate is the cause detection? It follows the rules in docs/how-it-works.md. The main blind spot is very long generations: timestamps are written when a response ends, so a few TTL expiries can show up as prefix busts.
Credits
Inspired by the cache-countdown idea in
olddonkey/cache-refresher, by
production audits of multi-agent swarms, and for hooks/recall/refine by
the REPL-harness ideas in Prime Agent
(context as a variable, retrievable history, /refine) and
Harness² (propose, probe,
compose; keep only evidence-backed edits).
MIT licensed. Contributions welcome!
1 maintainer

Metadata
1 maintainer
Release files for kvleak 0.6.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| kvleak-0.6.0.tar.gz | 227.6 kB | Without provenance | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| kvleak-0.6.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 300.1 kB
Release files / kvleak-0.6.0.tar.gz
| Download URL | kvleak-0.6.0.tar.gz |
|---|---|
| Size | 227.6 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
0c86dc1a32ccb8a834c75be4bc1e7be8cdd5cccca8847581dff4e590baa1b13b
|
|
BLAKE2b-256 checksum How to use checksums |
fe4fd2e402c122ac42ac9dfb273bd8472c37ba34ec64e752e7b982213bd3f227
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.12.7
|
Release files / kvleak-0.6.0-py3-none-any.whl
| Download URL | kvleak-0.6.0-py3-none-any.whl |
|---|---|
| Size | 72.5 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
31b298c541a3bd844718a3258ccf2ed98f9f295b089f1521ddf7427e9f3c3059
|
|
BLAKE2b-256 checksum How to use checksums |
518b31d9418018e7408321e1a1ce44786932d580657e47bb8421d4d06813cfa7
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.12.7
|
Security for kvleak 0.6.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.














