
l9gpu


Built by Last9 — send GPU telemetry to Last9 or any OTLP backend. See the Last9 docs.
DCGM exporter tells you a GPU is hot. It won't tell you whose job is frying it.
Most GPU observability stops at the hardware — utilization, temperature, ECC —
and hands you a gpu.uuid with no answer to the only question that matters:
who's paying for this idle H100?
l9gpu closes the loop. One agent per node emits vendor-neutral OTLP with
workload attribution baked in — Kubernetes pod, namespace, deployment;
Slurm job, user, partition. You point it at any OTLP backend and get
per-team, per-job, per-model accounting without building a pipeline.
It works on NVIDIA, AMD, and Intel Gaudi today. It will keep working on whatever comes next because it emits OpenTelemetry, not a bespoke format. There's no vendor backend in the agent itself. That's deliberate.

Quick Start — Kubernetes
# Classic Helm repo
helm repo add l9gpu https://last9.github.io/gpu-telemetry
helm install l9gpu l9gpu/l9gpu -n monitoring --create-namespace \
  --set monitoring.sink=otel \
  --set monitoring.cluster=my-cluster \
  --set otlpSecretName=l9gpu-otlp

# or OCI
helm install l9gpu oci://ghcr.io/last9/gpu-telemetry/l9gpu --version 0.2.2 -n monitoring
Create the OTLP secret first:
kubectl create secret generic l9gpu-otlp -n monitoring \
  --from-literal=OTEL_EXPORTER_OTLP_ENDPOINT=<your-otlp-endpoint> \
  --from-literal=OTEL_EXPORTER_OTLP_HEADERS="Authorization=Bearer <your-token>"
AMD / Gaudi nodes: --set collectors.nvidia=false --set collectors.amd=true
(or collectors.gaudi=true).
Full Helm guide: docs/HELM.md. Topology examples
(EKS + DCGM, multi-GPU, sidecar collector): deploy/helm/l9gpu/examples/.
Quick Start — Bare Metal / systemd
pip install l9gpu
export OTEL_EXPORTER_OTLP_ENDPOINT=<your-otlp-endpoint>
export OTEL_EXPORTER_OTLP_HEADERS="Authorization=Bearer <your-token>"

l9gpu nvml_monitor  --sink otel --cluster my-cluster  # NVIDIA
l9gpu amd_monitor   --sink otel --cluster my-cluster  # AMD
l9gpu gaudi_monitor --sink otel --cluster my-cluster  # Intel Gaudi
Sanity-check without OTLP: l9gpu nvml_monitor --sink stdout --once.
systemd unit files: systemd/.
What l9gpu is not
- Not a Prometheus exporter. It emits OTLP. Your Collector handles Prometheus scraping if you want it.
- Not a backend.
l9gpuexports standard OTLP to whatever speaks OTLP. There's no Last9 lock-in in the agent. - Not a DCGM replacement. DCGM profiling (SM occupancy, tensor pipe, NVLink) is complementary — bundle both through one Collector pipeline.
- Not only NVIDIA. AMD MI300X / MI325X and Intel Gaudi 2/3 are first-class.
Architecture
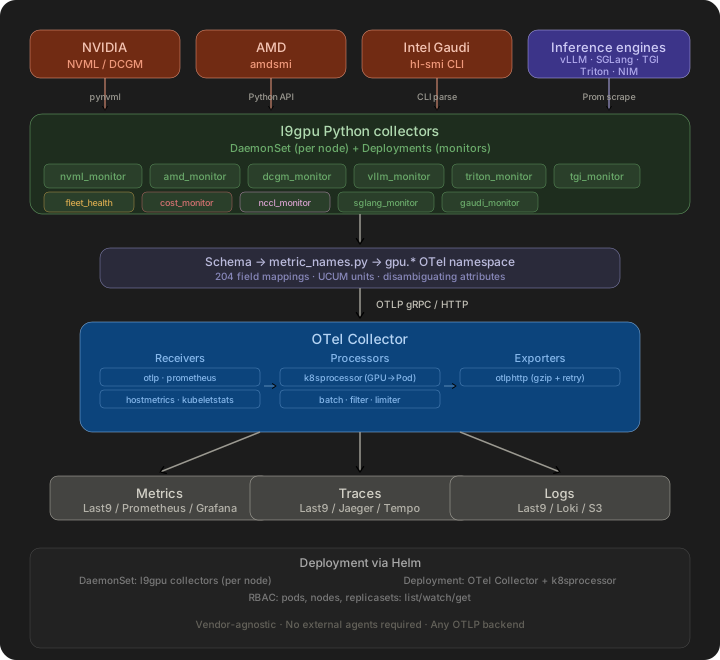
Collectors on each node normalize NVML / DCGM / amdsmi / hl-smi into the
gpu.* OTel namespace and ship OTLP to a Collector. The Collector enriches
with k8sprocessor or slurmprocessor
and fans out.
Every cycle (default 60s) emits metrics (one OTLP gauge per GPU per metric) and logs (one OTLP log per GPU per cycle with the full snapshot — useful for backends that prefer log-shaped events or for replaying history).
Full walk-through: docs/ARCHITECTURE.md.
Workload attribution
Kubernetes — k8sprocessor enriches each GPU data
point with k8s.pod.name, k8s.namespace.name, k8s.deployment.name,
k8s.job.name, cloud.availability_zone, cloud.region. Setup,
RBAC, label allow-lists: docs/K8S_WORKLOAD_ATTRIBUTION.md.
Slurm — slurmprocessor attaches slurm.job.id,
slurm.user, slurm.account, partition, QoS:
processors:
  slurm:
    cache_duration: 60
    cache_filepath: /tmp/slurmprocessor_cache.json
    query_slurmctld: false
Full config: slurmprocessor/README.md.
Dashboards & alerts
Pre-built Grafana dashboards in dashboards/grafana/ —
multi-cluster fleet, per-pod workload, health/reliability (ECC, throttling,
XID), DCGM profiling, inference engines (vLLM, SGLang, TGI, Triton, NIM),
fleet efficiency / idle detection.
Alert rules in alerts/prometheus/ — 17 pre-built
alert rules across 3 PrometheusRule CRDs (fleet, GPU infrastructure, LLM
inference) — and alerts/grafana/. Enable via Helm:
helm upgrade --set alerts.enabled=true ….
Pre-built collector
Skip ocb and run a ready-made Collector with k8sprocessor +
slurmprocessor baked in:
docker run --rm -v $PWD/config.yaml:/etc/l9gpu/config.yaml:ro \
  ghcr.io/last9/l9gpu-collector:latest --config=/etc/l9gpu/config.yaml
Details and binary/tarball install: docs/COLLECTOR.md.
Components
| Directory | Language | Role |
|---|---|---|
l9gpu/ |
Python | Node-level collector (DaemonSet / systemd). Emits OTLP metrics + logs. |
k8sprocessor/ |
Go | OTel Collector processor. Enriches with K8s pod / workload / cloud metadata. |
slurmprocessor/ |
Go | OTel Collector processor. Enriches with Slurm job metadata. |
k8shelper/ |
Go | Shared K8s API helper library. |
shelper/ |
Go | Shared Slurm helper library. |
Hardware support
NVIDIA A100, H100 / H200, B200 / GB200, T4, A10, L4 (NVML + DCGM) · AMD MI300X, MI325X (amdsmi) · Intel Gaudi 2, Gaudi 3 (hl-smi).
Full metric catalog with units and attributes: docs/METRICS.md.
Demo
One-command EKS stack — vLLM + SGLang + TGI + Triton alongside l9gpu NVML, DCGM, cost, fleet-health, and per-engine monitors:
./deploy/demo/launch.sh
Documentation
- Architecture — system design, topology, data flow
- Metrics reference — every metric, unit, attribute
- Integration guide — PromQL, OTel Collector recipes, cloud notes
- K8s workload attribution — RBAC, enrichment, label allow-lists
- Scaling — cardinality management for large fleets
- GPU & LLM observability — vLLM / NIM / Triton specifics
- Helm install · Pre-built collector
- AWS testing cookbook — end-to-end EC2 and EKS walk-through
l9gpuCLI reference ·slurmprocessor·shelper
Contributing
PRs welcome. See CONTRIBUTING.md for dev setup, tests,
and PR flow. By contributing you agree your work is licensed under the same
terms as the rest of the project. Security reports: SECURITY.md.
Credits & attribution
l9gpu (the Python package), shelper, and slurmprocessor are derived
from Meta's facebookresearch/gcm
project (MIT and Apache-2.0). We extended them with Kubernetes workload
attribution, AMD / Intel Gaudi collectors, vLLM / SGLang / TGI / Triton /
NIM monitors, cost and fleet-health signals, and OTLP-native export.
k8shelper/ and k8sprocessor/ are original Last9 work. See
NOTICE for the full breakdown.
License
MIT for l9gpu, k8shelper, k8sprocessor. Apache-2.0 for slurmprocessor,
shelper. Each subdirectory carries its own LICENSE where it differs from
the repo root.
1 maintainer

Metadata
1 maintainer
Release files for l9gpu 0.2.3
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| l9gpu-0.2.3.tar.gz | 857.3 kB | With provenance | Details for l9gpu-0.2.3.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| l9gpu-0.2.3-py3-none-any.whl | Python 3 | none | any | Details for l9gpu-0.2.3-py3-none-any.whl |
Total release size: 1.6 MB
Release files / l9gpu-0.2.3.tar.gz
| Download URL | l9gpu-0.2.3.tar.gz |
|---|---|
| Size | 857.3 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
9d3f63e218c13c1880d34f88ea9d4d815e63d0b6b45bee0f68687fc215824413
|
|
BLAKE2b-256 checksum How to use checksums |
0b9f4f59b279d0b3f17764856abf1f3301d162daa6549cffb970e2162bb982e3
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 26, 2026.
Transparency logRelease files / l9gpu-0.2.3-py3-none-any.whl
| Download URL | l9gpu-0.2.3-py3-none-any.whl |
|---|---|
| Size | 713.1 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
9d148c48d4d5eecd88b89615c608a550be550f653e9f8b4e92c004cd81be69eb
|
|
BLAKE2b-256 checksum How to use checksums |
2f57876748f51eaaa8440abedc34fb8fbad5a9e63800d4394501e95c0a6415bf
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 26, 2026.
Transparency logSecurity for l9gpu 0.2.3
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
All 2 files in this release have been uploaded with provenance metadata.
Attestation for l9gpu-0.2.3.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 26, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














