
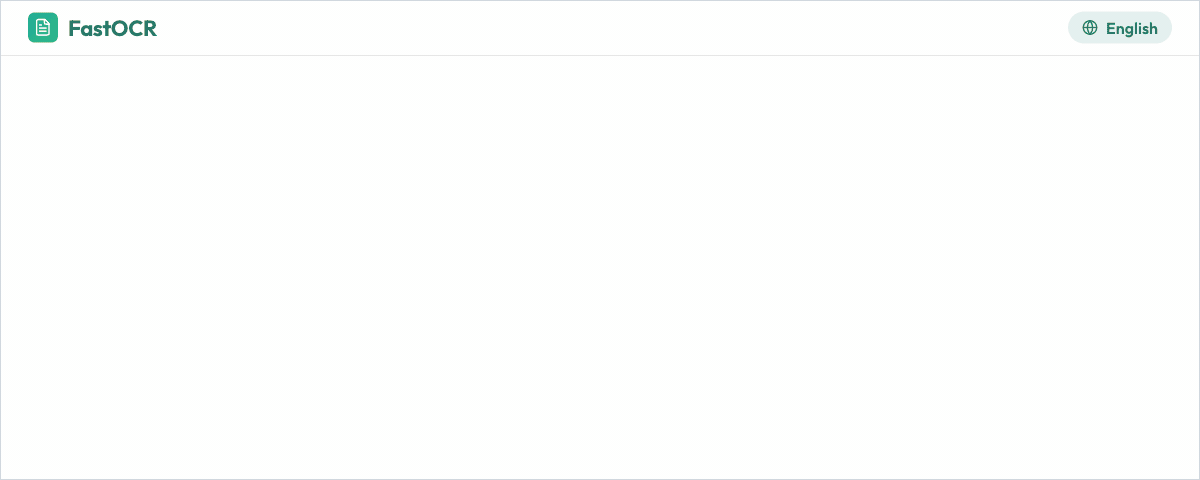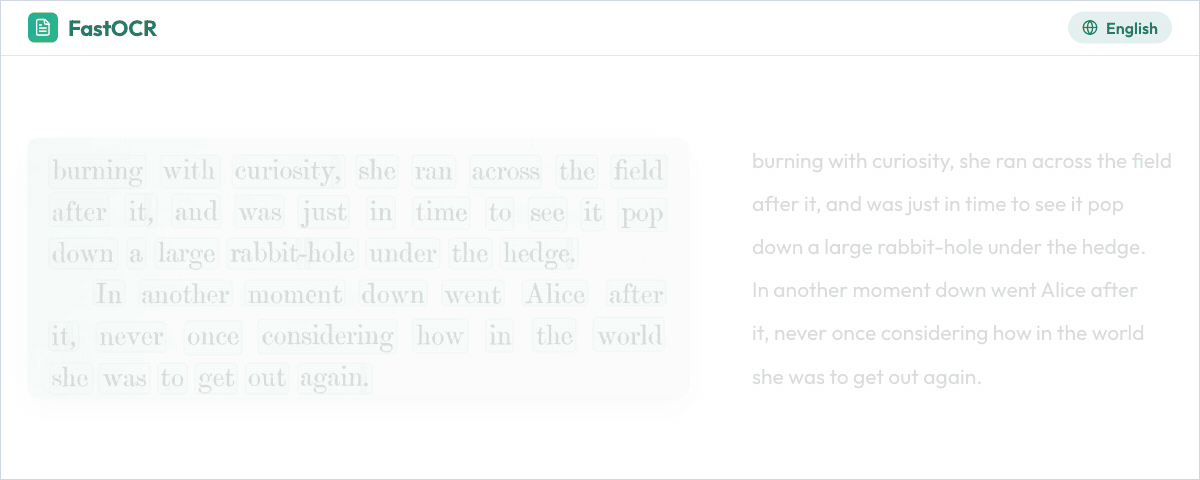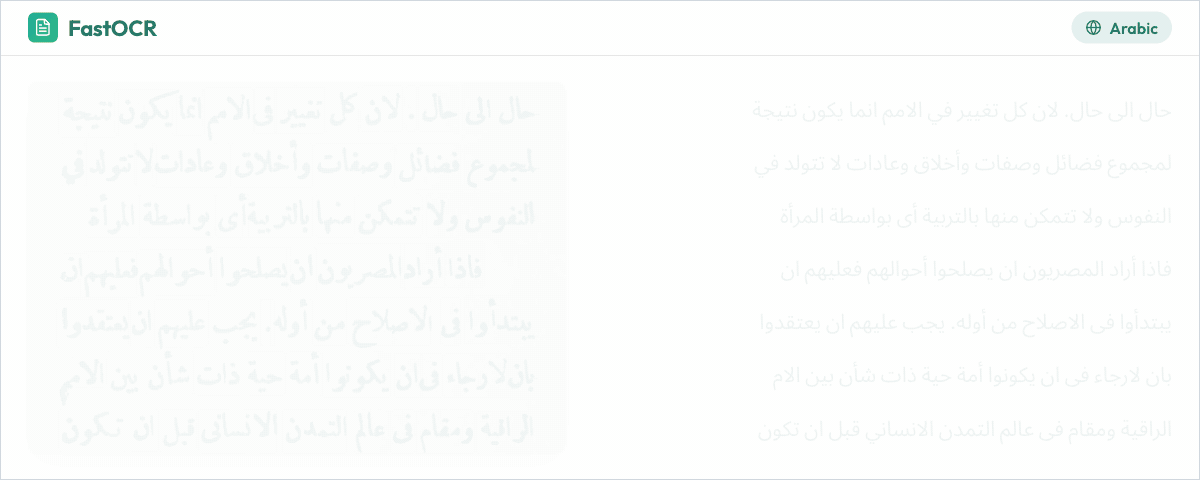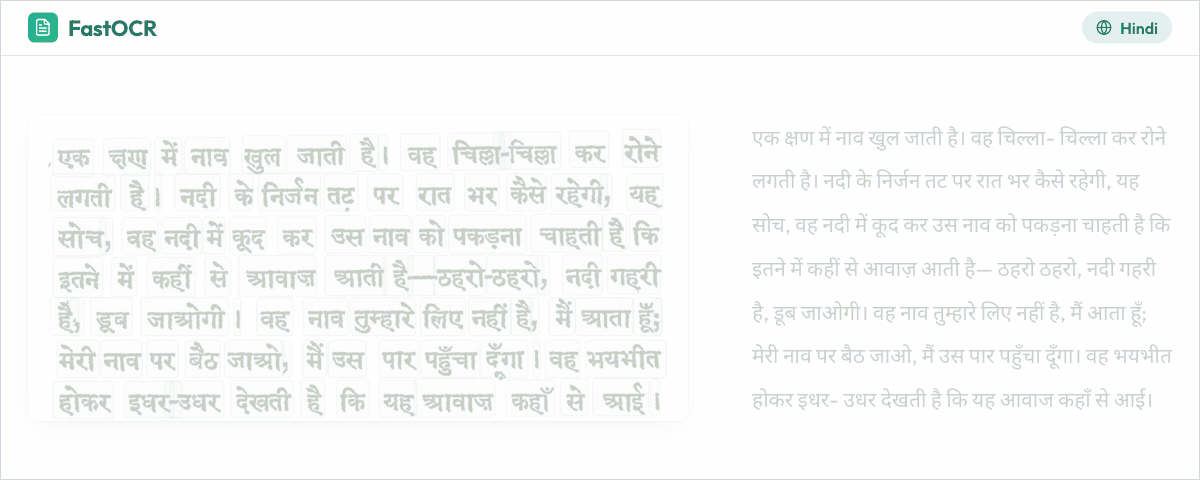
A LangChain document loader that reads scanned PDFs and images with FastOCR.




Website · Docs · Get an API key
Quickstart
pip install langchain-fastocr
export FASTOCR_API_KEY="your_api_key"
from langchain_fastocr import FastOCRLoader

documents = FastOCRLoader("scanned_contract.pdf").load()
print(documents[0].page_content)
Python 3.10 or newer. The distribution is langchain-fastocr and the import is langchain_fastocr.
What you get back
FastOCRLoader returns one Document per file.
| You get | Where |
|---|---|
| The text of the whole file | page_content |
| The file's path and name | metadata["source"], metadata["file_name"] |
| The FastOCR document id | metadata["fastocr_document_id"] |
| Pages billed | metadata["pages_billed"] |
completed or partial |
metadata["status"] |
A searchable PDF, with output="pdf" |
saved as <name>.searchable.pdf beside the input; its path is in metadata["searchable_pdf_path"] |
If the account runs out of API pages partway through a file, you still get the text of the pages that were processed, with status set to partial and a warning in the log. A document that fails raises the error from fastocr-sdk with its message and code.
Languages and files
- 100+ languages, detected automatically. No language setting is needed.
- PDF files up to 1 GiB, and PNG, JPG, JPEG, GIF, WebP and BMP images up to 20 MiB. An image counts as one page.
Get an API key and pages
Any signed-in FastOCR account can create an API key and start right away.
- Sign in and create an API key in the developer console. You accept the API terms with your first key.
- Set the key as
FASTOCR_API_KEY, or passapi_key=to the loader. - When you need more than the free pages, buy a prepaid API page pack by card in the developer console.
Each account gets 50 free document pages per month.
Examples
RAG over scanned PDFs
from langchain_core.vectorstores import InMemoryVectorStore
from langchain_fastocr import FastOCRLoader
from langchain_openai import OpenAIEmbeddings
from langchain_text_splitters import RecursiveCharacterTextSplitter

documents = FastOCRLoader("scanned_contract.pdf").load()
chunks = RecursiveCharacterTextSplitter(chunk_size=1000, chunk_overlap=150).split_documents(documents)

store = InMemoryVectorStore.from_documents(chunks, OpenAIEmbeddings())
for hit in store.as_retriever(search_kwargs={"k": 3}).invoke("When can the contract be terminated?"):
    print(hit.metadata["file_name"], hit.page_content[:200])
Each chunk keeps its file's metadata, so answers can cite the source file. This example also needs pip install langchain-openai langchain-text-splitters numpy and an OpenAI key; any other embeddings class works the same way.
A folder of scans
from pathlib import Path

from langchain_fastocr import FastOCRLoader

scans = sorted(p for p in Path("scans").iterdir() if p.suffix.lower() in {".pdf", ".png", ".jpg", ".jpeg"})
for document in FastOCRLoader(scans).lazy_load():
    print(document.metadata["file_name"], document.metadata["pages_billed"])
lazy_load() yields each document as soon as its file is finished. The loader runs one file at a time.
Searchable PDFs for an archive
from langchain_fastocr import FastOCRLoader

documents = FastOCRLoader(["invoice-001.pdf", "invoice-002.pdf"], output="pdf").load()
for document in documents:
    print(document.metadata["searchable_pdf_path"])
Each searchable PDF is saved beside its input, as invoice-001.searchable.pdf. An existing file with that name is replaced. Index the text and keep the PDF.
Options
| Argument | Default | Meaning |
|---|---|---|
file_path |
required | One path or a list of paths |
api_key |
FASTOCR_API_KEY |
Your FastOCR API key |
output |
"text" |
"pdf" also saves a searchable PDF beside each input |
base_url |
FASTOCR_BASE_URL, then https://api.fastocr.org |
API address |
timeout |
300.0 |
Seconds to wait for each document |
Support and license
Questions: support@fastocr.org. Bugs and requests: GitHub issues. MIT license; see LICENSE.
1 maintainer

Metadata
1 maintainer
Release files for langchain-fastocr 0.1.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| langchain_fastocr-0.1.0.tar.gz | 3.1 MB | With provenance | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| langchain_fastocr-0.1.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 3.1 MB
Release files / langchain_fastocr-0.1.0.tar.gz
| Download URL | langchain_fastocr-0.1.0.tar.gz |
|---|---|
| Size | 3.1 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
fb46c1dc16c1ce47112641cb18c1f6d045f7efb9227af292d7ebaefa91f8554b
|
|
BLAKE2b-256 checksum How to use checksums |
fad7c50fbcc4da4e4c8b2fbf3551e5a8a2e8a44260452a7af87ecf3734e5da04
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 25, 2026.
Transparency logRelease files / langchain_fastocr-0.1.0-py3-none-any.whl
| Download URL | langchain_fastocr-0.1.0-py3-none-any.whl |
|---|---|
| Size | 6.8 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
75f019b809bd94e3bcc6cc13f1ba7f36158a9c7860c381204279b1f5f2ec2139
|
|
BLAKE2b-256 checksum How to use checksums |
e7debb32244a5fec44837127c30b494fc9e6dfc3cbf846eea4c57bb2d650a5fe
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 25, 2026.
Transparency logSecurity for langchain-fastocr 0.1.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
All 2 files in this release have been uploaded with provenance metadata.
Attestation for langchain_fastocr-0.1.0.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 25, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.













