
Whisper
[Blog] [Paper] [Model card] [Colab example]
Whisper is a general-purpose speech recognition model. It is trained on a large dataset of diverse audio and is also a multitasking model that can perform multilingual speech recognition, speech translation, and language identification.
Approach
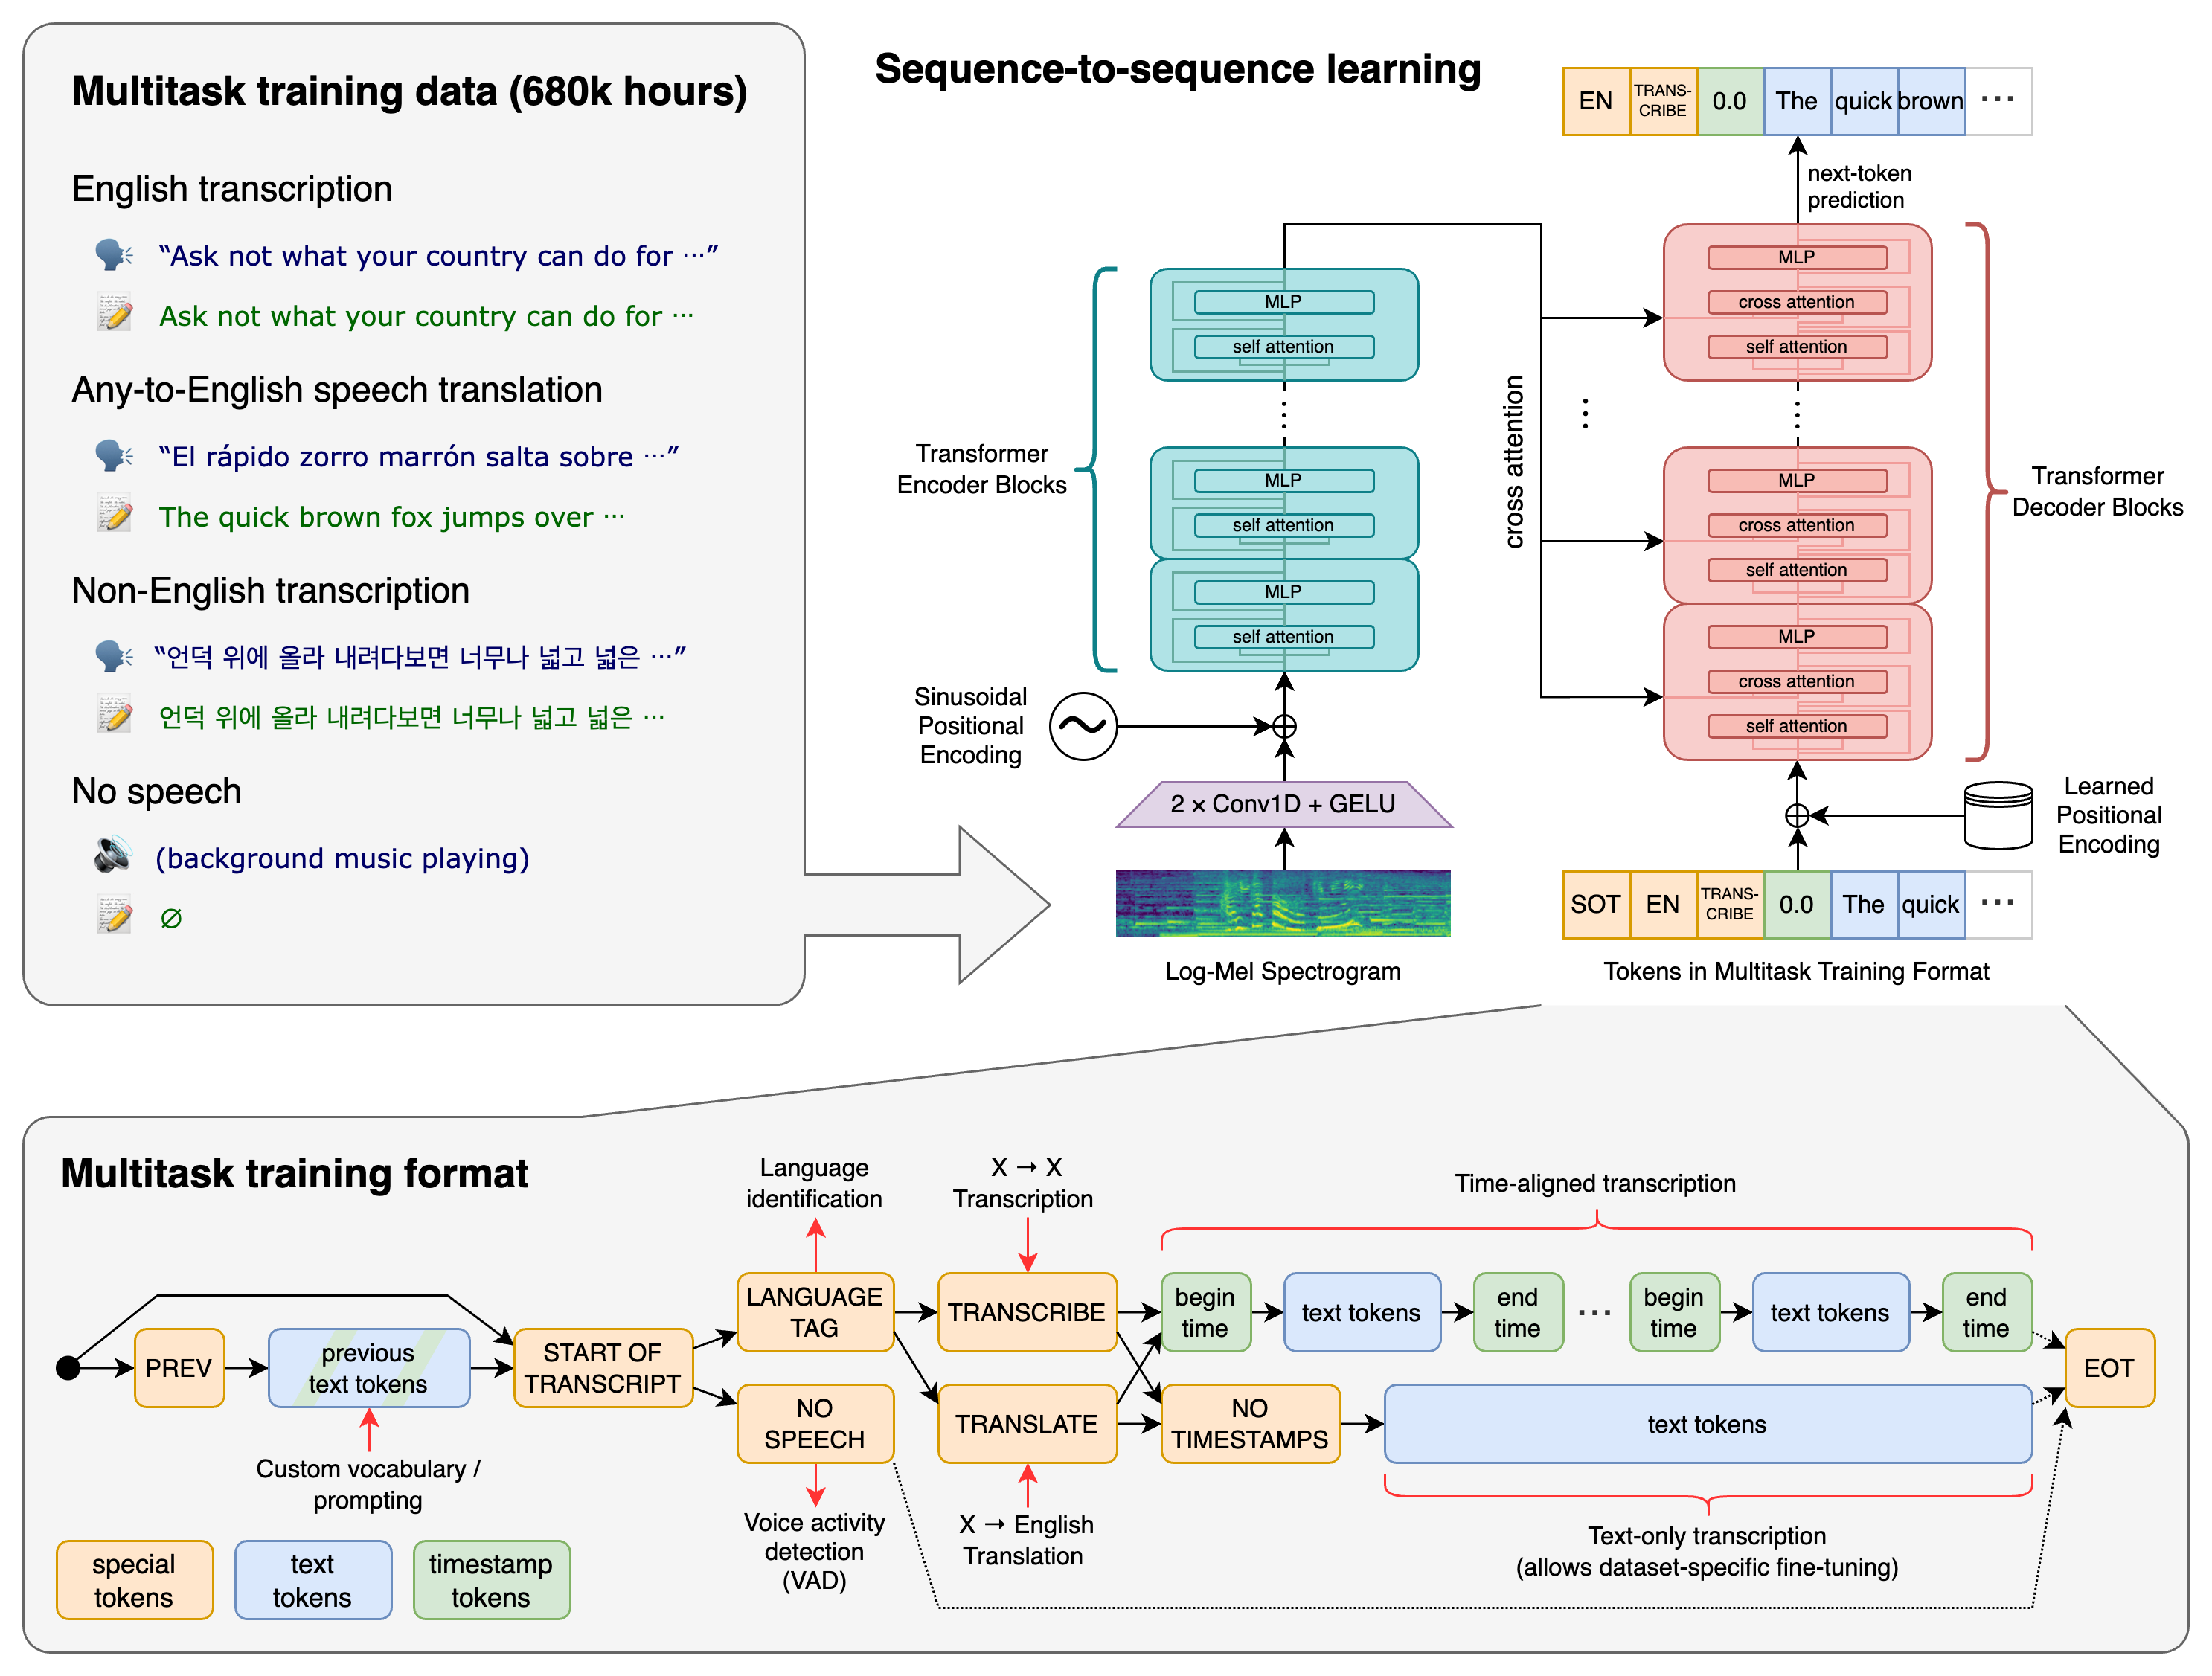
A Transformer sequence-to-sequence model is trained on various speech processing tasks, including multilingual speech recognition, speech translation, spoken language identification, and voice activity detection. These tasks are jointly represented as a sequence of tokens to be predicted by the decoder, allowing a single model to replace many stages of a traditional speech-processing pipeline. The multitask training format uses a set of special tokens that serve as task specifiers or classification targets.
Setup
We used Python 3.9.9 and PyTorch 1.10.1 to train and test our models, but the codebase is expected to be compatible with Python 3.8-3.11 and recent PyTorch versions. The codebase also depends on a few Python packages, most notably OpenAI's tiktoken for their fast tokenizer implementation. You can download and install (or update to) the latest release of Whisper with the following command:
pip install -U openai-whisper
Alternatively, the following command will pull and install the latest commit from this repository, along with its Python dependencies:
pip install git+https://github.com/openai/whisper.git
To update the package to the latest version of this repository, please run:
pip install --upgrade --no-deps --force-reinstall git+https://github.com/openai/whisper.git
It also requires the command-line tool ffmpeg to be installed on your system, which is available from most package managers:
# on Ubuntu or Debian
sudo apt update && sudo apt install ffmpeg

# on Arch Linux
sudo pacman -S ffmpeg

# on MacOS using Homebrew (https://brew.sh/)
brew install ffmpeg

# on Windows using Chocolatey (https://chocolatey.org/)
choco install ffmpeg

# on Windows using Scoop (https://scoop.sh/)
scoop install ffmpeg
You may need rust installed as well, in case tiktoken does not provide a pre-built wheel for your platform. If you see installation errors during the pip install command above, please follow the Getting started page to install Rust development environment. Additionally, you may need to configure the PATH environment variable, e.g. export PATH="$HOME/.cargo/bin:$PATH". If the installation fails with No module named 'setuptools_rust', you need to install setuptools_rust, e.g. by running:
pip install setuptools-rust
Available models and languages
There are five model sizes, four with English-only versions, offering speed and accuracy tradeoffs. Below are the names of the available models and their approximate memory requirements and inference speed relative to the large model; actual speed may vary depending on many factors including the available hardware.
| Size | Parameters | English-only model | Multilingual model | Required VRAM | Relative speed |
|---|---|---|---|---|---|
| tiny | 39 M | tiny.en |
tiny |
~1 GB | ~32x |
| base | 74 M | base.en |
base |
~1 GB | ~16x |
| small | 244 M | small.en |
small |
~2 GB | ~6x |
| medium | 769 M | medium.en |
medium |
~5 GB | ~2x |
| large | 1550 M | N/A | large |
~10 GB | 1x |
The .en models for English-only applications tend to perform better, especially for the tiny.en and base.en models. We observed that the difference becomes less significant for the small.en and medium.en models.
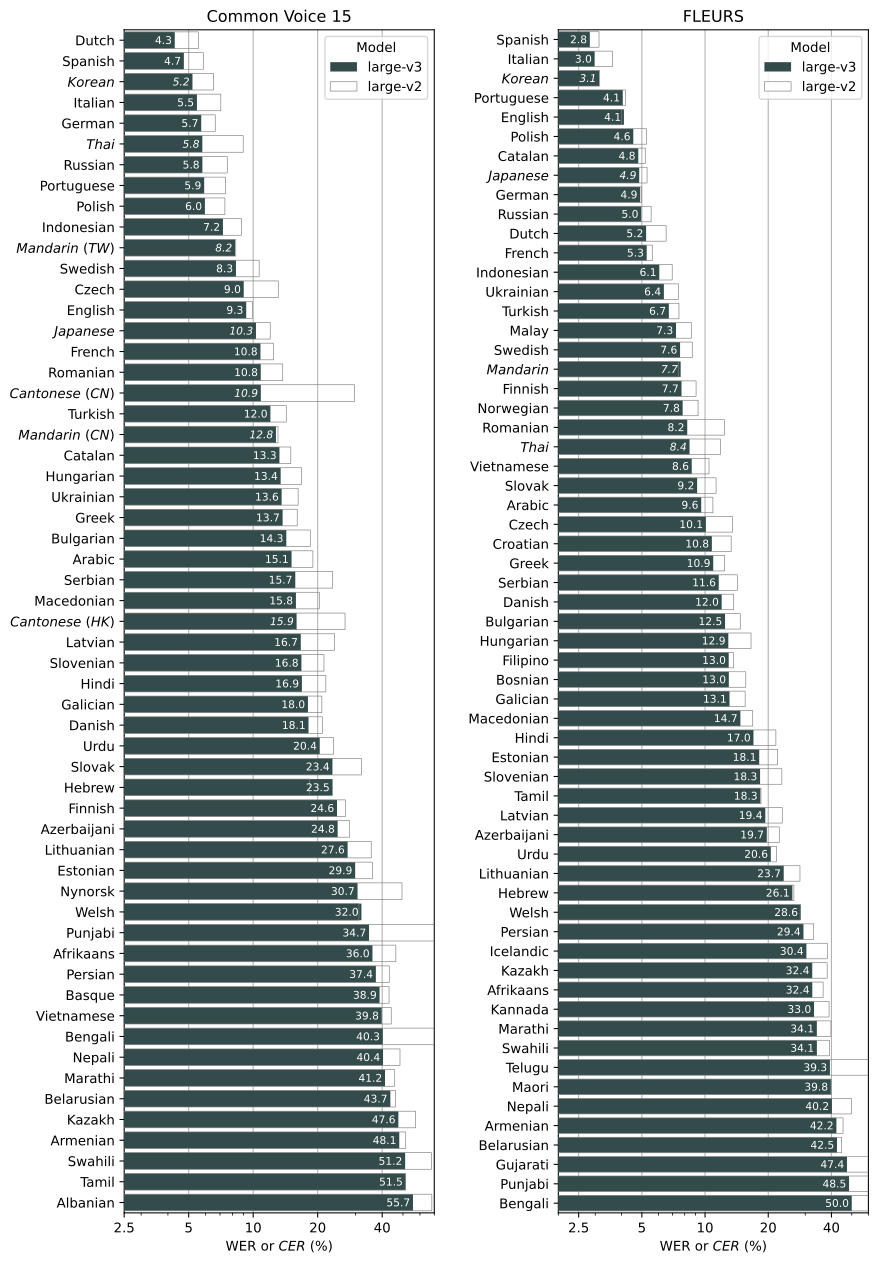
Whisper's performance varies widely depending on the language. The figure below shows a performance breakdown of large-v3 and large-v2 models by language, using WERs (word error rates) or CER (character error rates, shown in Italic) evaluated on the Common Voice 15 and Fleurs datasets. Additional WER/CER metrics corresponding to the other models and datasets can be found in Appendix D.1, D.2, and D.4 of the paper, as well as the BLEU (Bilingual Evaluation Understudy) scores for translation in Appendix D.3.
Command-line usage
The following command will transcribe speech in audio files, using the medium model:
whisper audio.flac audio.mp3 audio.wav --model medium
The default setting (which selects the small model) works well for transcribing English. To transcribe an audio file containing non-English speech, you can specify the language using the --language option:
whisper japanese.wav --language Japanese
Adding --task translate will translate the speech into English:
whisper japanese.wav --language Japanese --task translate
Run the following to view all available options:
whisper --help
See tokenizer.py for the list of all available languages.
Python usage
Transcription can also be performed within Python:
import whisper

model = whisper.load_model("base")
result = model.transcribe("audio.mp3")
print(result["text"])
Internally, the transcribe() method reads the entire file and processes the audio with a sliding 30-second window, performing autoregressive sequence-to-sequence predictions on each window.
Below is an example usage of whisper.detect_language() and whisper.decode() which provide lower-level access to the model.
import whisper

model = whisper.load_model("base")

# load audio and pad/trim it to fit 30 seconds
audio = whisper.load_audio("audio.mp3")
audio = whisper.pad_or_trim(audio)

# make log-Mel spectrogram and move to the same device as the model
mel = whisper.log_mel_spectrogram(audio).to(model.device)

# detect the spoken language
_, probs = model.detect_language(mel)
print(f"Detected language: {max(probs, key=probs.get)}")

# decode the audio
options = whisper.DecodingOptions()
result = whisper.decode(model, mel, options)

# print the recognized text
print(result.text)
More examples
Please use the 🙌 Show and tell category in Discussions for sharing more example usages of Whisper and third-party extensions such as web demos, integrations with other tools, ports for different platforms, etc.
License
Whisper's code and model weights are released under the MIT License. See LICENSE for further details.
1 maintainer

Metadata
1 maintainer
Release files for learnbyvideo-whisper 20231117
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| learnbyvideo-whisper-20231117.tar.gz | 808.0 kB | Without provenance | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| learnbyvideo_whisper-20231117-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 1.6 MB
Release files / learnbyvideo-whisper-20231117.tar.gz
| Download URL | learnbyvideo-whisper-20231117.tar.gz |
|---|---|
| Size | 808.0 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
09a90454a124ad1b6f77506e672311238909a21ad12d571e8881c74028206a34
|
|
BLAKE2b-256 checksum How to use checksums |
bd8ec2b0229bb89b3e557a179e3ce3749966b26e48fabd6b46b5bd5872532fd6
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/5.0.0 CPython/3.11.2
|
Release files / learnbyvideo_whisper-20231117-py3-none-any.whl
| Download URL | learnbyvideo_whisper-20231117-py3-none-any.whl |
|---|---|
| Size | 812.2 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
5686e61e6102ea88bb14ac778e5084d32d59f7b60cc91c256ffba459f638c469
|
|
BLAKE2b-256 checksum How to use checksums |
77f226b8b406f2273d72238d0f1fb087a6ebbb2ffaea0a9e64a88d8df13b4a39
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/5.0.0 CPython/3.11.2
|
Security for learnbyvideo-whisper 20231117
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.













