
LePika
One command → local AI chat in your browser.
(luh-PEE-ka)


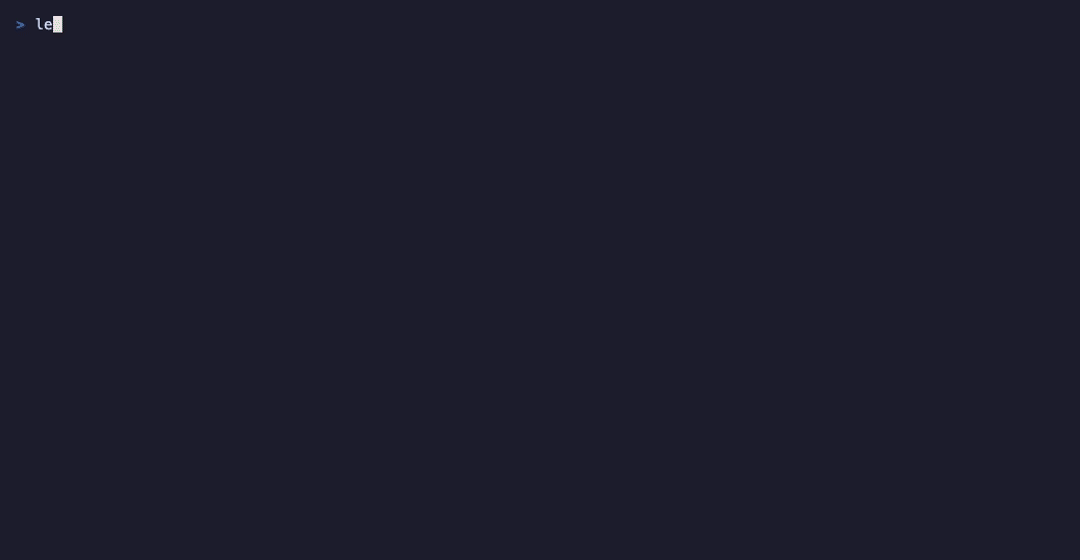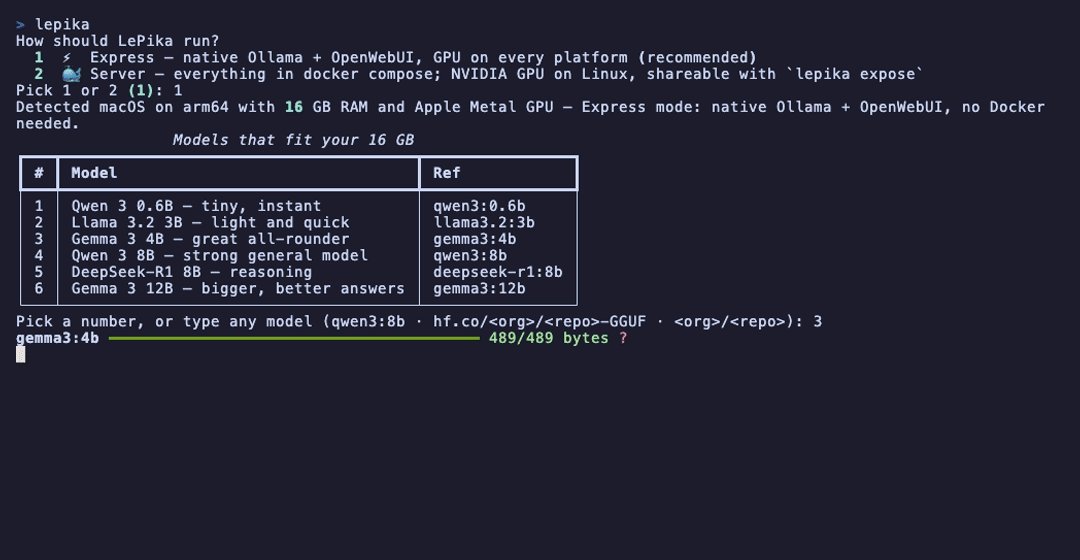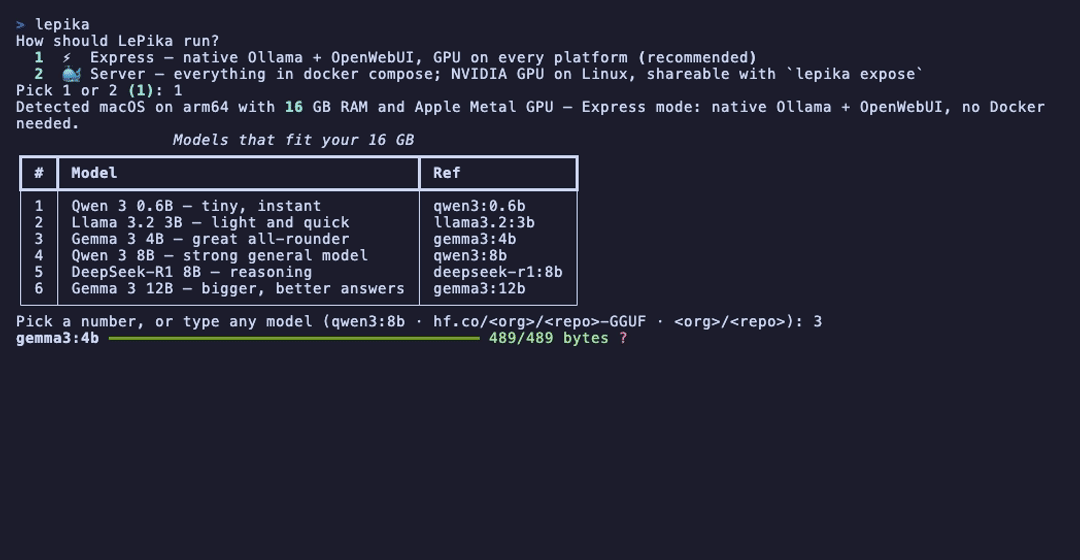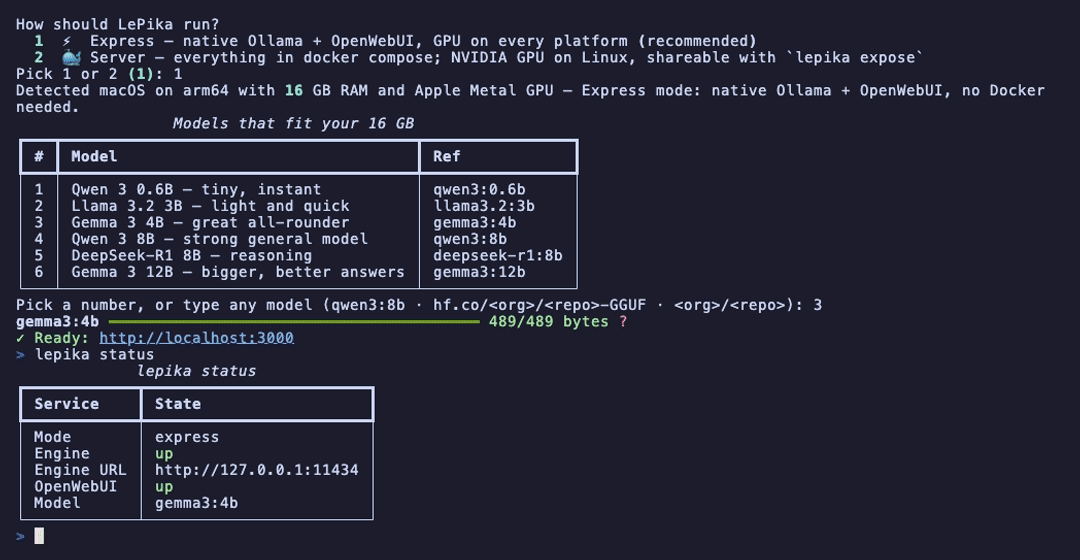
Your gaming GPU is already an AI machine. LePika self-hosts LLMs on the hardware you already own — Mac (Metal), Linux and Windows (NVIDIA) — with zero configuration. No Docker, no API keys, no monthly bill, and nothing you type ever leaves the box.
Named after Pika, the cat who supervises this project. Like any cat, Pika has everything worth having at home and no use for the cloud. Same idea, for your AI.
Install
Mac / Linux
curl -fsSL https://raw.githubusercontent.com/MikaelSabuhi/lepika/main/install.sh | sh
Windows (PowerShell)
irm https://raw.githubusercontent.com/MikaelSabuhi/lepika/main/install.ps1 | iex
Already have uv?
uv tool install lepika
Then run lepika. It detects your OS, GPU, and RAM, offers the models that actually
fit your machine, installs Ollama +
OpenWebUI, pulls your pick, and opens the chat UI at
http://localhost:3000.
LePika installs into
~/.local/bin— if a new terminal can't find thelepikacommand, add that directory to yourPATHor restart your shell.
Prefer to read the source first, or hack on it?
git clone https://github.com/MikaelSabuhi/lepika && cd lepika && uv run lepika —
git and uv are the only
prerequisites; uv fetches its own Python.
What it does
- Native GPU, no containers — Apple Metal on macOS, CUDA on Linux/Windows.
Ollama arrives via Homebrew, the official install script, or winget; OpenWebUI via
uv tool. CPU-only machines work too (LePika warns you they'll be slow). - Models that fit — a curated list filtered to your RAM, so there's no guessing whether a 27B fits in 16 GB.
- Any model, one field — Ollama tags, Hugging Face GGUF builds, or full-weight safetensors repos. Model guide →
- Private by default — Express listens on
127.0.0.1, full stop. Sharing the stack with your network is a Server-mode feature (lepika expose). - Two modes — ⚡ Express (default): everything native, no Docker.
🐳 Server: the same thing as one readable
docker composestack, for the box under the desk. Server guide →
LePika reuses an Ollama you already have instead of installing a second copy.
Everyday commands
| Command | What it does |
|---|---|
lepika |
The setup wizard: detect → pick a model → install → chat |
lepika up / lepika down |
Start / stop the local AI stack |
lepika status |
Mode, engine, UI, and default model at a glance |
lepika doctor |
Diagnose the setup; every ✗ has a one-line fix |
lepika logs |
Tail LePika's logs (--lines, default 50) |
lepika update |
Upgrade the engine and OpenWebUI — chats kept |
lepika model add [ref] |
Download a model and make it the default (no ref → browse) |
lepika model import <dir> |
Import safetensors weights already on disk (--quant picks the format) |
lepika model list / lepika model rm |
List / remove downloaded models |
lepika expose |
Share engine + UI on your network behind a generated key (Server mode) |
lepika connect <url> |
Use an engine on another machine (--local to go back) |
Global flags: --version, --mode express|server (the wizard's, not a per-command
switch), --dry-run, and --help on every command.
All state lives in one place: ~/.lepika — config, logs, and (in Express mode)
OpenWebUI's own chats and uploads. That is what makes lepika update keep your chats.
Point LEPIKA_HOME somewhere else if you prefer.
Why not just use Ollama directly?
You absolutely can. LePika drives Ollama and OpenWebUI; it doesn't replace them. What it saves you:
| By hand | With LePika | |
|---|---|---|
| First run | Install Ollama, install Python, install open-webui, set OLLAMA_BASE_URL, start both, find the port |
One command |
| Choosing a model | Guess, download 20 GB, find out it swaps | A list filtered to the RAM you actually have |
| Wiring UI ↔ engine | Environment variables, by hand, per shell | Done for you |
| Something's broken | Two sets of logs, two projects' issue trackers | lepika doctor, one fix hint per failure |
| Staying current | Update each piece separately, per platform | lepika update |
If you'd rather run the raw tools, their docs are excellent and LePika gets out of your
way. Curious what it's doing on your behalf? It's a few files of plain Python in
src/lepika/: three dependencies, no magic.
Requirements
- Disk for the models: ~0.5 GB for a tiny one, ~5 GB for a good all-rounder, 40 GB+ for the flagships.
- 8 GB RAM recommended. Less works: LePika steers you to smaller models.
- A GPU is optional. CPU-only machines run everything, slowly, and LePika says so up front.
- macOS: Homebrew (without it, LePika points you at the Ollama.app download). Windows: winget, which ships with Windows 10/11. Full-weight imports have their own fine print — see the model guide.
Documentation
- Model guide — every model-ref shape, full-weight imports, gated repos
- Server mode — the compose stack, using a GPU box remotely, security
- Architecture — design rules and how it's built
- Changelog — what changed in each release
Contributing
Issues and pull requests are welcome — including an issue for what you'd want next. CONTRIBUTING.md has the short version of how a change gets in. Found a security problem? SECURITY.md says how to report it privately.
uv sync --dev && uv run pre-commit install && uv run pytest -q
License
MIT © Mikael Sabuhi
1 maintainer

Metadata
1 maintainer
Release files for lepika 0.1.2
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| lepika-0.1.2.tar.gz | 1.2 MB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| lepika-0.1.2-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 1.3 MB
Release files / lepika-0.1.2.tar.gz
| Download URL | lepika-0.1.2.tar.gz |
|---|---|
| Size | 1.2 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
2980f8a8018610e929e4be6644bdb4c55a490e7a7e8ed5f99e7d8a01c38fcec4
|
|
BLAKE2b-256 checksum How to use checksums |
3e0da7ad500b48ba6f6576809f9693488acc571a268e46bd0e792fda6a0453b7
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Aug 31, 2026.
Transparency logRelease files / lepika-0.1.2-py3-none-any.whl
| Download URL | lepika-0.1.2-py3-none-any.whl |
|---|---|
| Size | 70.2 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
f2ac3b8646ad085c8fb6352d8fe3777629c97bd0e6f789037a478608e7a10a73
|
|
BLAKE2b-256 checksum How to use checksums |
e176dbbac84eaa55665e7c91065dbb8b9af2bfae6a504478be3b476c025372bc
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Aug 31, 2026.
Transparency log













