
lerobot_env_so101


A standalone SO-101 (SO-ARM101) pick-cube MuJoCo environment, packaged as a
lerobot_env_* plugin (auto-detected by lerobot v0.6.0+ via
@EnvConfig.register_subclass, see
lerobot#3823) and usable
standalone as a plain gymnasium environment.
Documentation — getting started, action space, API reference.
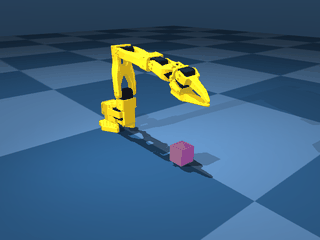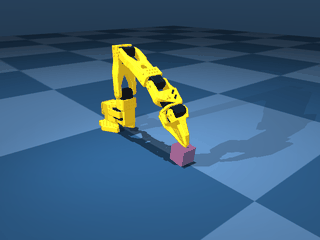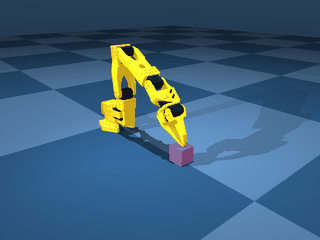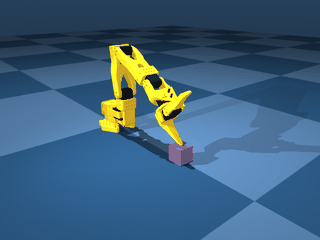
A hand-written controller driving a reach→gripper-close motion — not a successful pick-and-lift. A top-down grasp is not yet reachable with the position-only IK; see Known limitations.
Installation
pip install lerobot-env-so101
Or from a checkout of the parent repo, for development:
pip install -e packages/lerobot_env_so101
Usage
Standalone (plain gymnasium)
Works without lerobot installed — only mujoco, gymnasium, and numpy:
import gymnasium as gym
import numpy as np

import lerobot_env_so101  # registers the env

env = gym.make("lerobot_env_so101/SO101PickCube-v0", render_mode="rgb_array")
obs, info = env.reset(seed=0)
for _ in range(100):
    action = env.action_space.sample() * 0.1  # keep deltas small, see Known limitations
    obs, reward, terminated, truncated, info = env.step(action)
    if terminated or truncated:
        obs, info = env.reset()
env.close()
gym.make kwargs: image_obs (add a pixels.front camera view to the
observation), reward_type ("sparse" or "dense"), and
random_block_position.
With lerobot (v0.6.0+)
Installing the package is all the wiring you need. lerobot's
register_third_party_plugins() discovers any installed lerobot_env_*
distribution at startup and imports it, which registers the env config under
the type name so101:
pip install lerobot lerobot-env-so101
lerobot-eval --policy.path=<your_policy> --env.type=so101
Config fields (--env.<field> on the CLI) are defined in
configuration_so101.py: task (default SO101PickCube-v0), fps (10,
matching the env's 0.1 s control step), episode_length (100), image_obs,
reward_type, random_block_position.
Driving it from 7-dim teleop tooling
import gymnasium as gym

import lerobot_env_so101
from lerobot_env_so101.wrappers import SevenDofToFourDofAdapter

env = SevenDofToFourDofAdapter(gym.make("lerobot_env_so101/SO101PickCube-v0"))
# env now accepts [dx, dy, dz, drx, dry, drz, grasp]; drx/dry/drz are
# explicitly discarded (documented in the class docstring, not silent).
Action space
The native action space is 4-dim: [dx, dy, dz, grasp].
dx, dy, dz(bounds[-1, 1]): end-effector position deltas, scaled byaction_scale(see Known limitations below).grasp(bounds[0, 1]): an absolute gripper target, not a delta —0= fully closed,1= fully open, written directly to the gripper actuator each step (gripper.normalized_to_ctrl). Since v0.2.0; before that it was a normalized increment added to the current position each step.
SO-101's arm has 5 DOF (6 joints, one of which is the gripper), and the IK
controller in this package only solves for end-effector position. A 6-dim
Cartesian pose target (position + orientation) is not something this
robot/controller pair can track, so orientation deltas are not part of the
action space at all — there is no dead dimension to silently ignore. This was
verified with sim/check_dead_action_dims.py in the parent repo: all 4
dims move the state (0/4 dead).
Contrast with the upstream gym-hil design this was ported from, which kept
the Panda-derived 7-dim [dx,dy,dz,drx,dry,drz,grasp] action space and
silently dropped drx,dry,drz inside the IK solver — 3 of 7 dimensions were
dead, meaning a policy could learn to depend on inputs that had zero effect
on the simulation.
7-dim adapter
Teleop devices and HIL tooling written against the 7-dim Panda convention can
still be used via lerobot_env_so101.wrappers.SevenDofToFourDofAdapter,
which wraps a native env and accepts 7-dim actions, explicitly discarding
drx, dry, drz (see the class docstring — the discard is documented, not
silent).
What changed vs. the upstream port
Ported from
lohpaul9/gym-hil SO-101 branch
(Apache-2.0), submitted upstream as
huggingface/gym-hil#36 /
#37 and self-closed by the
author without review. Authored by Paul Loh (github.com/lohpaul9). See
the parent repo's README.md and notes/references.md for the full context
on why this became a standalone package instead of an upstream PR.
- Action space narrowed from 7-dim to native 4-dim (see above). The
7→4 adapter (
wrappers.py) is new. FrankaGymEnvand theRobotGymEnvabstract base were dropped.RobotGymEnvonly ever had one concrete subclass (SO101GymEnv), so it added an abstraction layer without abstracting anything;SO101GymEnvnow inherits directly fromMujocoGymEnv. No Panda/Franka code is present in this package.- Fixed: dead mocap body. Upstream's
SO101GymEnv.reset_robot()wrotemocap_pos/mocap_quat, butapply_action()never read them — the IK controller tracks its target in a plain Python attribute (self._target_ee_pos), not a MuJoCo mocap body. This package removes the mocap writes fromreset_robot()and removes the corresponding unusedmocap="true"targetbody frompick_scene.xml. - Fixed (v0.2.0): gripper is now an absolute, normalized command. The
graspaction is a normalized[0, 1](0=closed, 1=open) absolute target, mapped to the gripper actuator's native radianctrlrangebygripper.normalized_to_ctrl— see Action space above. Breaking change: before v0.2.0,graspwas a normalized increment added to the current gripper position each step, sograsp=0meant "no change"; as of v0.2.0 it means "fully closed". This does not by itself make LeRobot policy training pick up the new convention — see Known limitations below. - Fixed (v0.3.0): arm
ctrlnow carries IK target joint angles. The arm actuators are declared<position>in the MJCF, so theirctrlis a target angle; upstream wrote a joint-space PD torque (plus gravity compensation) into it, which drove the command far outside each joint'sctrlrangeand saturated the actuators into bang-bang tracking.solve_ik(renamed fromik_control) now returns the target joint angles and the environment writes them toctrl, leaving the proportional position tracking (kponly; damping comes from the passive joint damping) to the<position>actuators. The IK is also solved once per control step rather than once per physics substep, since the target angle is held across the substeps. - Fixed (v0.4.0): the gripper polarity was inverted.
grasp=1("open") closed the jaw andgrasp=0("closed") opened it, because thegripperjoint closes at its lower limit and the mapping assumed the opposite. Breaking change:graspnow does what the action space documents, andgripper_posein the observation is-1when closed and+1when open, the reverse of v0.3.0. A policy trained on v0.3.0 or earlier has to be retrained. - Not fixed, inherited as-is: unverified motor parameters.
damping/frictionloss/armaturefor the STS3215 servos are carried over unchanged from the upstream MJCF, which itself adapted them from the Open Duck Mini project rather than measuring the actual SO-101. See the parent repo'snotes/references.mdfor the cross-check againstmujoco_menagerie/robotstudio_so101(same values, same unverified lineage). System identification is out of scope for this package (see the parent repo's Phase 2 notes). - Not fixed: the arm settles below its target under gravity. The
proportional-only
<position>actuators leave a steady-state gap under gravity load (about 17 mm at the end-effector in the home pose). See the parent repo'sdocs/limitations.md. - Dropped: teleop/gamepad/keyboard wrappers,
PassiveViewerWrapper,GripperPenaltyWrapper,ResetDelayWrapper,EEActionWrapper,InputsControlWrapper, and thewrap_env/make_envfactory. These are HIL-teleop infrastructure orthogonal to the environment itself and out of scope for this package; only the base env, the pick-cube task, and the 7→4 action adapter were ported. - Dropped:
joints_properties.xml. Its contents are already inlined intoso101_new_calib.xmlupstream (see the comment there) and no MJCF file<include>s it separately — it was dead weight in the source repo. mujoco>=3.0.0,<4.0.0(same major-version bump the upstream fork made from vanillagym-hil's<3.0.0). Verified working against MuJoCo 3.10.0.- Fixed: sparse-mode success no longer ignores the gripper. Upstream gym-hil (both its Panda environments and the SO-101 port) computes a strict success check and then discards it in sparse mode, replacing it with a lift-only test — so a block knocked upward without ever being grasped terminates the episode as a success. Measured on this environment before the fix: gripper 0.092 m from the block (threshold 0.05 m) with the block lifted 0.20 m still reported success. Sparse mode now also requires the gripper to be near the block.
Known limitations
-
Action deltas default to unscaled metres. With the default
action_scale=1.0, an action component of magnitude 1.0 is added directly to the end-effector target as 1.0 metres, while the reachable workspace spans at most 0.6 m — over most of the declared [-1, 1] range the action behaves closer to bang-bang than to a proportional delta. This default is inherited from gym-hil, where actions come from human teleoperation and are naturally small. Since v0.1.1, passaction_scale(metres per unit action; position deltas only,graspis absolute and unaffected) to make the full [-1, 1] range meaningful for an RL policy:env = gym.make("lerobot_env_so101/SO101PickCube-v0", action_scale=0.025) # or on the lerobot CLI: --env.type=so101 --env.action_scale=0.025
-
SO101GymEnvis a base class, not a usable environment. It implements robot control but notstep()/reset(); instantiateSO101PickCubeGymEnv(orgym.make("lerobot_env_so101/SO101PickCube-v0")) instead. -
Top-down grasp is not reachable with the default IK. The gripper's fixed jaw (including the wrist_roll_follower mesh in the wrist servo bracket) hits the block's top face before the moving jaw can descend far enough to straddle it. A correct grasp pose — approaching vertically, gripper straddling the block — does exist kinematically, but the default position-only IK tracks a continuous Cartesian path from the HOME pose and converges monotonically onto a different solution branch (approach axis tilted roughly 36° from vertical) instead.
top_down_ik=True(set bylerobot_env_so101/SO101PickPlace-v0) adds an approach-axis constraint that reaches the vertical branch;SO101PickCube-v0does not use it. -
SO101PickPlace-v0grasps with collision pads the real gripper does not have. MuJoCo collides the jaw meshes as convex hulls, which touch the block at a point or two each and let it pivot out during the lift.jaw_pads=True(set by that environment) enables an invisible box pad on each fingertip, roughly 5 to 7 mm proud of the mesh. Block and goal are sampled from x = 0.15 to 0.30 m; farther out the gripper can no longer be held vertical. See the parent repo'sdocs/limitations.md. -
LeRobot policy training does not automatically pick up the new grasp convention. LeRobot's policy eval does not read a gym env's
action_spacebounds; it scales actions using the training dataset's own normalization statistics. Makinggraspabsolute and[0, 1](this section, above) is correct for this package as a plain gym/RL environment, but a LeRobot policy will only actually train against this convention if its dataset was collected/labeled that way.
Policies
Scripted reach-and-close and the BC policy
lerobot_env_so101.scripted.scripted_reach_close is a hand-written controller
that moves the end effector over the block, descends onto it, and closes the
gripper. It is reach-and-close, not a pick: the position-only IK cannot
reach a vertical straddling approach (see "Top-down grasp is not reachable
with the default IK" above), so the block is never lifted. The end effector settles about
0.027 m above the block's centre, where the fixed jaw contacts its top face.
The controller is a pure function of the flattened 17-dim state observation
(agent_pos 14 + environment_state 3), which makes it usable directly as a
behaviour-cloning label. sim/ trains a 2×128 MLP on those labels and exports
it to ONNX for the browser viewer; lerobot_env_so101.policy holds the
observation layout, the model, and the export. The exported graph applies the
normalization and output squashing internally, so it maps a raw observation to
a ready-to-execute [dx, dy, dz, grasp] action.
Reproduce (needs the train extra: pip install -e "packages/lerobot_env_so101[train]"):
python sim/collect_demos.py --episodes 300 --out sim/data/reach_close_demos.npz
python sim/train_bc.py sim/data/reach_close_demos.npz --out sim/data/bc_reach_close.pt
python sim/export_onnx.py sim/data/bc_reach_close.pt --out web/assets/policies/reach_close.onnx
python sim/eval_reachclose_policy.py web/assets/policies/reach_close.onnx --episodes 100 --update-manifest
Demonstrations are collected DART-style: the stored label is the noise-free scripted action, while the executed action carries Gaussian noise on the position deltas, so the dataset covers the states an imperfect policy visits. The close phase is exempt — it depends on an exactly-zero position delta to trigger the environment's hold-position lock.
Measured success (gripper commanded closed within 0.05 m of the block, 100-step
episodes, random_block_position=True, action_scale=0.025):
| Controller | Episodes | Success rate |
|---|---|---|
Scripted scripted_reach_close |
300 (seeds 0–299) | 1.000 |
| BC policy via ONNX / onnxruntime | 100 (seeds 1000–1099) | 1.000 |
The BC policy's mean final end-effector-to-block distance is 0.032 m.
Attribution
- SO-101 MJCF/URDF and control code: ported from lohpaul9/gym-hil (Apache-2.0), authored by Paul Loh (github.com/lohpaul9).
- Base
gym-hilproject structure and license headers: Copyright 2024 The HuggingFace Inc. team (Apache-2.0). - Asset provenance (CAD source, motor parameters): see
lerobot_env_so101/assets/README.md.
Licensed under Apache-2.0 — see LICENSE.
Testing
pip install -e "packages/lerobot_env_so101[test]"
pytest packages/lerobot_env_so101/tests -q
1 maintainer

Metadata
1 maintainer
Release files for lerobot-env-so101 0.4.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| lerobot_env_so101-0.4.0.tar.gz | 6.0 MB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| lerobot_env_so101-0.4.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 12.0 MB
Release files / lerobot_env_so101-0.4.0.tar.gz
| Download URL | lerobot_env_so101-0.4.0.tar.gz |
|---|---|
| Size | 6.0 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
4427ed03464482c79f7bd2b3c709a1f565374cff57fbfe6c03228e10d0e8fcf4
|
|
BLAKE2b-256 checksum How to use checksums |
909e1a5fe1094c6ea918bdf9c7e3a7bb40fd7cf737d0b67ed1660a9f5354775a
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 12, 2026.
Transparency logRelease files / lerobot_env_so101-0.4.0-py3-none-any.whl
| Download URL | lerobot_env_so101-0.4.0-py3-none-any.whl |
|---|---|
| Size | 6.0 MB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
56144425a61e8f9d2fb4b640961a08f2d4250f615e63656b4f9fdc0b481dbdf2
|
|
BLAKE2b-256 checksum How to use checksums |
61224c400c2d1d7029e763ff04d2f4d4f1ed4b57887ea12b1abdf4cb1f38636f
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 12, 2026.
Transparency log













