
GitHub Repo - https://github.com/ihp-lab/LibreFace


This is the Python package for LibreFace: An Open-Source Toolkit for Deep Facial Expression Analysis. LibreFace is an open-source and comprehensive toolkit for accurate and real-time facial expression analysis with both CPU and GPU acceleration versions. LibreFace eliminates the gap between cutting-edge research and an easy and free-to-use non-commercial toolbox. We propose to adaptively pre-train the vision encoders with various face datasets and then distill them to a lightweight ResNet-18 model in a feature-wise matching manner. We conduct extensive experiments of pre-training and distillation to demonstrate that our proposed pipeline achieves comparable results to state-of-the-art works while maintaining real-time efficiency. LibreFace2 uses a lightweight RepVGG backbone for the AU detection, AU intensity, and facial expression heads.
LibreFace2 additionally supports gaze estimation using a MediaPipe landmark-based MLP pipeline. Gaze yaw and pitch (in degrees) are returned alongside the existing facial attribute outputs.
Dependencies
Python 3.9
- You should have cmake installed in your system.
For Linux users -
sudo apt-get install cmake. If you run into trouble, consider upgrading to the latest version (instructions).For Mac users -
brew install cmake.
Installation
You can first create a new Python 3.9 environment using conda and then install this package using pip from the PyPI hub:
conda create -n libreface_env python=3.9
conda activate libreface_env
pip install --upgrade libreface
Usage
Commandline
You can use this package through the command line using the following command.
libreface --input_path="path/to/your_image_or_video"Note that the above script would save results in a CSV at the default location - sample_results.csv. If you want to specify your own path, use the --output_path command line argument,
libreface --input_path="path/to/your_image_or_video" --output_path="path/to/save_results.csv"To change the device used for inference, use the --device command line argument,
libreface --input_path="path/to/your_image_or_video" --device="cuda:0"To save intermediate files, libreface uses a temporary directory that defaults to ./tmp. To change the temporary directory path,
libreface --input_path="path/to/your_image_or_video" --temp="your/temp/path"For video inference, our code processes the frames of your video in batches. You can specify the batch size and the number of workers for data loading as follows,
libreface --input_path="path/to/your_video" --batch_size=256 --num_workers=2 --device="cuda:0"Note that by default, the --batch_size argument is 256, and --num_workers argument is 2. You can increase or decrease these values according to your machine’s capacity.
Examples
Download a sample image from our GitHub repository. To get the facial attributes for this image and save to a CSV file, simply run,
libreface --input_path="sample_disfa.png"Download a sample video from our GitHub repository. To run the inference on this video using a GPU and save the results to my_custom_file.csv run the following command,
libreface --input_path="sample_disfa.avi" --output_path="my_custom_file.csv" --device="cuda:0"Note that for videos, each row in the saved CSV file corresponds to individual frames in the given video.
Python API
Here’s how to use this package in your Python scripts.
To assign the results to a Python variable,
import libreface
detected_attributes = libreface.get_facial_attributes(image_or_video_path)
To save the results to a csv file,
import libreface
libreface.get_facial_attributes(image_or_video_path,
                                output_save_path = "your_save_path.csv")
To change the device used for inference, use the device parameter,
import libreface
libreface.get_facial_attributes(image_or_video_path,
                                device = "cuda:0") # can be "cpu" or "cuda:0", "cuda:1", ...
To save intermediate files, libreface uses a temporary directory that defaults to ./tmp. To change the temporary directory path,
import libreface
libreface.get_facial_attributes(image_or_video_path,
                                temp_dir = "your/temp/path")
For video inference, our code processes the frames of your video in batches. You can specify the batch size and the number of workers for data loading as follows,
import libreface
libreface.get_facial_attributes(video_path,
                                batch_size = 256,
                                num_workers = 2)
Note that by default, the batch_size is 256, and num_workers is 2. You can increase or decrease these values according to your machine’s capacity.
Gaze Estimation
Gaze yaw and pitch are returned by default in the get_facial_attributes output (keys gaze_yaw and gaze_pitch, or columns of the same name for video).
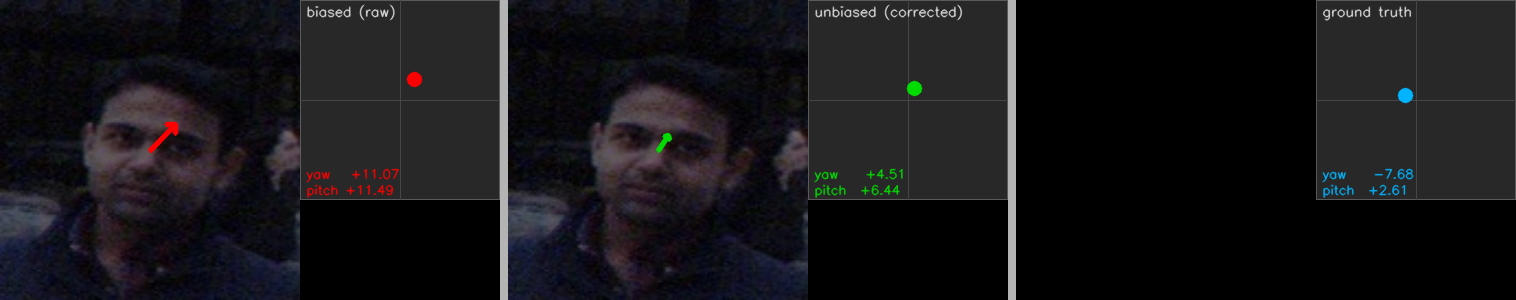
The figure above shows a Gaze360 example with three panels: biased (raw) model output (red, yaw=+11.07°, pitch=+11.43°), unbiased (bias-corrected) prediction (green, yaw=+4.51°, pitch=+6.44°), and ground truth (blue, yaw=-7.68°, pitch=+2.61°). Bias correction subtracts the systematic offset measured on the held-out test set (+6.55° yaw, +5.05° pitch).
If you only need gaze and want to skip AU and expression inference, call estimate_gaze (image) or estimate_gaze_video (list of aligned frames) directly. Both expect an already aligned face image — use libreface.get_aligned_image to produce one from a raw image.
import libreface

aligned_image_path, _, _ = libreface.get_aligned_image("path/to/your_image.png", temp_dir="./tmp")
gaze = libreface.estimate_gaze(aligned_image_path, device="cpu")
print(gaze)  # {'gaze_yaw': <float>, 'gaze_pitch': <float>}
For videos, pass a list of aligned frame paths:
import libreface

gaze_df = libreface.estimate_gaze_video(aligned_frames_path_list,
                                        device="cuda:0",
                                        batch_size=256,
                                        num_workers=2)
# gaze_df has columns "gaze_yaw" and "gaze_pitch", one row per frame.
Downloading Model Weights
Weights of the model are automatically downloaded at ./libreface_weights/ directory. If you want to download and save the weights to a separate directory, please specify the parent folder for weights as follows,
import libreface
libreface.get_facial_attributes(image_or_video_path,
                                weights_download_dir = "your/directory/path")
Output Format
For an image processed through LibreFace, we save the following information in the CSV file,
lm_mp_idx_x,lm_mp_idx_y,lm_mp_idx_z: x, y, z co-ordinate of the 3D landmark indexed atidx(total 478) obtained from mediapipe. Refer to the mediapipe documentation for getting the index to landmark map.pitch,yaw,roll: contains the angles in degrees for the 3D head pose for the person.facial_expression: contains the detected facial expression. Can be “Neutral”, “Happiness”, “Sadness”, “Surprise”, “Fear”, “Disgust”, “Anger”, or “Contempt”.au_idx: contains the output of our action unit (AU) detection model, which predicts whether an action unit at indexidxis activated. 0 means not activated, and 1 means activated. We detect AU at the indices[1, 2, 4, 6, 7, 10, 12, 14, 15, 17, 23, 24].au_idx_intensity: contains the output of our action unit (AU) intensity prediction model, which predicts the intensity of an action unit at indexidxbetween 0 and 5. 0 is least intensity and 5 is maximum intensity. We predict AU intensities for the AU indices[1, 2, 4, 5, 6, 9, 12, 15, 17, 20, 25, 26].gaze_yaw,gaze_pitch: estimated gaze angles in degrees, predicted by a MediaPipe landmark-based MLP. Yaw is the horizontal angle (left/right) and pitch is the vertical angle (up/down).
For a video, we save the same features for each frame in the video at index frame_idx and timestamp frame_time_in_ms.
Inference Speed
LibreFace is able to process long-form videos at ~30 FPS, on a machine that has a 13th Gen Intel Core i9-13900K CPU and a NVIDIA GeForce RTX 3080 GPU. Please note that the default code runs on CPU and you have to use the device parameter for Python or the --device command line option to specify your GPU device (“cuda:0”, “cuda:1”, …).
Contributing
We welcome contributions! Here’s how you can help:
Fork the GitHub repository.
Create a new branch for your feature (git checkout -b feature-branch).
Commit your changes (git commit -m ‘Add some feature’).
Push to the branch (git push origin feature-branch).
Create a Pull Request.
If you have questions about this package, please direct them to achaubey@usc.edu or achaubey@ict.usc.edu
License
Please refer to our github repo for License


Release files for libreface 0.2.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| libreface-0.2.0.tar.gz | 67.7 kB | Without provenance | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| libreface-0.2.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 142.6 kB
Release files / libreface-0.2.0.tar.gz
| Download URL | libreface-0.2.0.tar.gz |
|---|---|
| Size | 67.7 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
e14d5d66f335f10ab1b7c4e041a2fa38c1b00b55a68a5eb2c06d7354def0ce56
|
|
BLAKE2b-256 checksum How to use checksums |
be08a03e804312040f862339af66462992108833fffe7784625fc34972b1b07c
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.1.0 CPython/3.9.21
|
Release files / libreface-0.2.0-py3-none-any.whl
| Download URL | libreface-0.2.0-py3-none-any.whl |
|---|---|
| Size | 74.9 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
96db24e02b574a20492ae4ec74f365bd200f0aee4f7f94ccf9585b482b997a90
|
|
BLAKE2b-256 checksum How to use checksums |
8680c2fce17d485d7ae515a98f0c8e83fdcb6881d395285c454be5cf54b18299
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.1.0 CPython/3.9.21
|
Security for libreface 0.2.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
















