



LiftOn is a homology-based lift-over tool using both DNA-DNA alignments (from Liftoff, credits to Dr. Alaina Shumate) and protein-DNA alignments (from miniprot, credits to Dr. Heng Li) to accurately map annotations between genome assemblies of the same or different species. LiftOn employs a two-step protein maximization algorithm to improve the annotation of protein-coding genes in the T2T-CHM13 JHU RefSeqv110 + Liftoff v5.1 annotation. The latest T2T-CHM13 annotation generated by LiftOn is available as JHU_LiftOn_v1.0.14_chm13v2.0.gff3 , lifted from the GRCh38.p14 RefSeq annotation (release RS_2025_08) with LiftOn v1.0.14.
What's new in v1.0.14#
Selenoproteins and other declared recoded codons (RefSeq transl_except; Ensembl/GENCODE selenocysteine rows) are now read through instead of treated as premature stops, and transl_except is written in the lifted model's own coordinates: on GRCh38 to T2T-CHM13 all 25 human selenoprotein genes rise from a mean protein identity of 0.666 to 0.998.
LiftOn now uses each annotation's declared genetic code, accepts sparse coding references and GTF input more reliably, and can place a reference gene at a second unoccupied target locus. The second-locus rescue is on by default; --no-rescue-second-locus restores the earlier behavior. The release also bounds isoform-rescue prefetch memory and improves the windowed aligner.
Output fixes prevent duplicated or intron-spanning CDS blocks, overlapping exons, and misbound trans-spliced gene fragments. On assembly-matched sorghum RefSeq annotation, 51 of 53 new rice-to-sorghum second-locus models match distinct protein-coding target genes at reciprocal CDS overlap of at least 50%; all baseline feature rows remain present. The changelog gives the full changes and validation details.
What's new in v1.0.12#
v1.0.12 makes very large-genome runs safer and diagnosable. For targets above 4 billion bases, LiftOn now runs Liftoff/minimap2 before miniprot so the two index-memory peaks do not overlap; --parallel-aligners explicitly overrides that safeguard. Native process signals are named correctly (for example, -11 is SIGSEGV), and run_manifest.json records target size, the resolved schedule, commands, stages, bounded stderr tails, and signals. It also fixes trans-spliced copies whose children could bind to a same-ID parent on the wrong sequence. It also fixes a flat annotation -- a prokaryotic GFF3 with top-level CDS rows and no gene -- selecting nothing and failing several steps later, and adds -dir/--intermediate-dir so concurrent runs stop sharing one lifton_output/.
v1.0.12 also recovers far more genes between distantly related species, and gives miniprot-derived models their stop codon. The miniprot-only rescue judged a candidate by its genomic span, which includes introns and so follows genome size: lifting from human into the compact fish, bird and frog genomes it discarded 75-83 % of the missed genes miniprot found, although their alignments covered the whole reference protein. A second rescue sub-pass now judges exactly those by protein coverage, each rescued gene carries its other transcripts, and miniprot-derived CDS rows gain the stop codon the reference convention includes. Primary-assembly gene recall rises from 0.32 to 0.59 (human → zebrafish), 0.36 to 0.62 (human → chicken) and 0.36 to 0.64 (human → xenopus). Each ships with an opt-out; see the changelog.
Several defaults CHANGE the output annotation relative to earlier versions (each ships with an opt-out flag that restores the previous behaviour):
A protein-coverage rescue sub-pass is default-ON (v1.0.12): it reconsiders miniprot-only candidates the rescue's genomic length band rejected, admitting those whose hit covers at least 0.8 of the reference protein at the same identity floor. Pass
--no-coverage-rescue-gateto opt out.Rescued genes carry their isoforms (v1.0.12): each rescued gene also receives the other transcripts of the same reference gene whose miniprot hits lie at its locus; gene placement is unchanged. Pass
--no-rescue-isoformsto opt out.Miniprot-derived models carry their stop codon (v1.0.12): miniprot's CDS ends at the last aligned codon, while the reference convention includes the stop. The terminal CDS and its exon now grow by those three bases when the genome has them, and only when the model does not get worse. Pass
--no-orf-stop-completionto opt out.
From earlier releases:
A third merge candidate is now default-ON: alongside {chained merge, Liftoff-only}, LiftOn scores miniprot's native CDS-only model and adopts it only when its ORF-rescued protein identity is strictly higher, so per-transcript identity never decreases. Pass
--no-miniprot-candidateto restore the two-way merge.The miniprot-only rescue floor is now divergence-adaptive: the fixed 0.50 protein-identity floor is lowered toward 0.30 as the DNA lift's gene recall drops, recovering more genuinely missing genes at large evolutionary distance while staying inert on same- and close-species lifts. Pass
--no-adaptive-rescue-floorto restore the fixed floor.CDS rows are richer and spec-valid: rebuilt CDS lines used to lose the reference's descriptive attributes (
Dbxref,product,protein_id, ...) and carried noIDat all; they now inherit those attributes and share oneID=cds-<transcript>. Coding transcripts are also harmonized tomRNA. Coordinates and the encoded protein are untouched, and output grows 12–43%.Gene-like lift is now default-ON: LiftOn now lifts every reference gene-like top-level type (pseudogenes,
ncRNA_genes, structured mobile elements, ...), not justgene. Pass--gene-onlyto restore the oldgene-only lift.Miniprot-only rescue is now default-ON: when the DNA lift misses a reference coding gene entirely, LiftOn fills it in from the miniprot model (tagged
lifton_rescue=miniprot_only), recovering genes at large evolutionary distance. Pass--no-miniprot-rescueto opt out.Best-of-outcome merge is now default-ON: per transcript, LiftOn keeps whichever of {chained Liftoff↔miniprot merge, Liftoff-only} scores higher against the reference protein, instead of applying the chained CDS unconditionally. Pass
--legacy-mergeto restore the unconditional (published-manuscript) merge.Banded / windowed alignment is now default-ON: the protein/DNA aligner is anchor-windowed above ~2500 aa / 8000 nt, so giant genes are memory-bounded (no more titin-scale OOM) while same-species lifts stay identity-exact. Pass
--full-dp-alignto restore the exact giant-only full-DP path.
Installation#
Install through pip#
Install LiftOn's Python runtime from PyPI. Fresh standard lifts also require the minimap2 and miniprot executables on PATH; pip does not install them.
$ pip install lifton
Install the external aligners through Conda with strict channel priority:
conda install --override-channels -c conda-forge -c bioconda --strict-channel-priority minimap2 miniprot
Standard pip installs do not require mappy. The optional experimental binding is available through pip install "lifton[native]"; its source builds need a C compiler and zlib development headers. Conda supplies a prebuilt mappy alternative. See the installation guide for complete Conda, macOS and Seqera environments.
Install from source#
You can also install LiftOn from source. Check out the latest version !
$ git clone https://github.com/Kuanhao-Chao/LiftOn
$ cd LiftOn
$ python -m pip install .
Why LiftOn❓#
Burgeoning number of genome assemblies: As of December 2023, there are 30,530 eukaryotic genomes, 567,228 prokaryotic genomes, and 66,429 viruses listed on NCBI (NCBI genome browser). However, genome annotation is lagging behind. As more high-quality assemblies are generated, we need an accurate lift-over tool to annotate them.
Improved protein-coding gene mapping: The popular Liftoff tool maps genes based on DNA alignments alone. Miniprot maps genes based on protein alignments but, without gene structure information, may not be as accurate on their own (See FAQ Common mistakes of Liftoff and miniprot). LiftOn combines both DNA-to-genome and protein-to-genome alignments and produces better gene mapping results! LiftOn improves upon the current released T2T-CHM13 annotation (JHU RefSeqv110 + Liftoff v5.1).
Improved distantly related species lift-over: A key limitation of DNA-based lift-over tools is that they do not perform well when the reference and target genomes have significantly diverged. With the help of protein alignments and the protein maximization algorithm, LiftOn improves the lift-over process between distantly related species. See "Mouse to Rat" and "Drosophila melanogaster to Drosophila erecta" result sections.
LiftOn is free, it's open source, it's easy to install , and it's in Python!
Who is it for❓#
LiftOn is designed for researchers and bioinformaticians who are interested in genome annotation. It is an easy-to-install and easy-to-run command-line tool. Specifically, it is beneficial in the following scenarios:
If you have sequenced and assembled a new genome and require annotation, LiftOn provides an efficient solution for generating annotations for your genome.
LiftOn is an excellent tool for those looking to perform comparative genomics analysis. It facilitates the lifting over and comparison of gene contents between different genomes, aiding in understanding evolutionary relationships and functional genomics.
For researchers interested in using T2T-CHM13 annotations, try LiftOn! We have pre-generated the JHU_LiftOn_v1.0.14_chm13v2.0.gff3 file for your convenience.
What does LiftOn do❓#
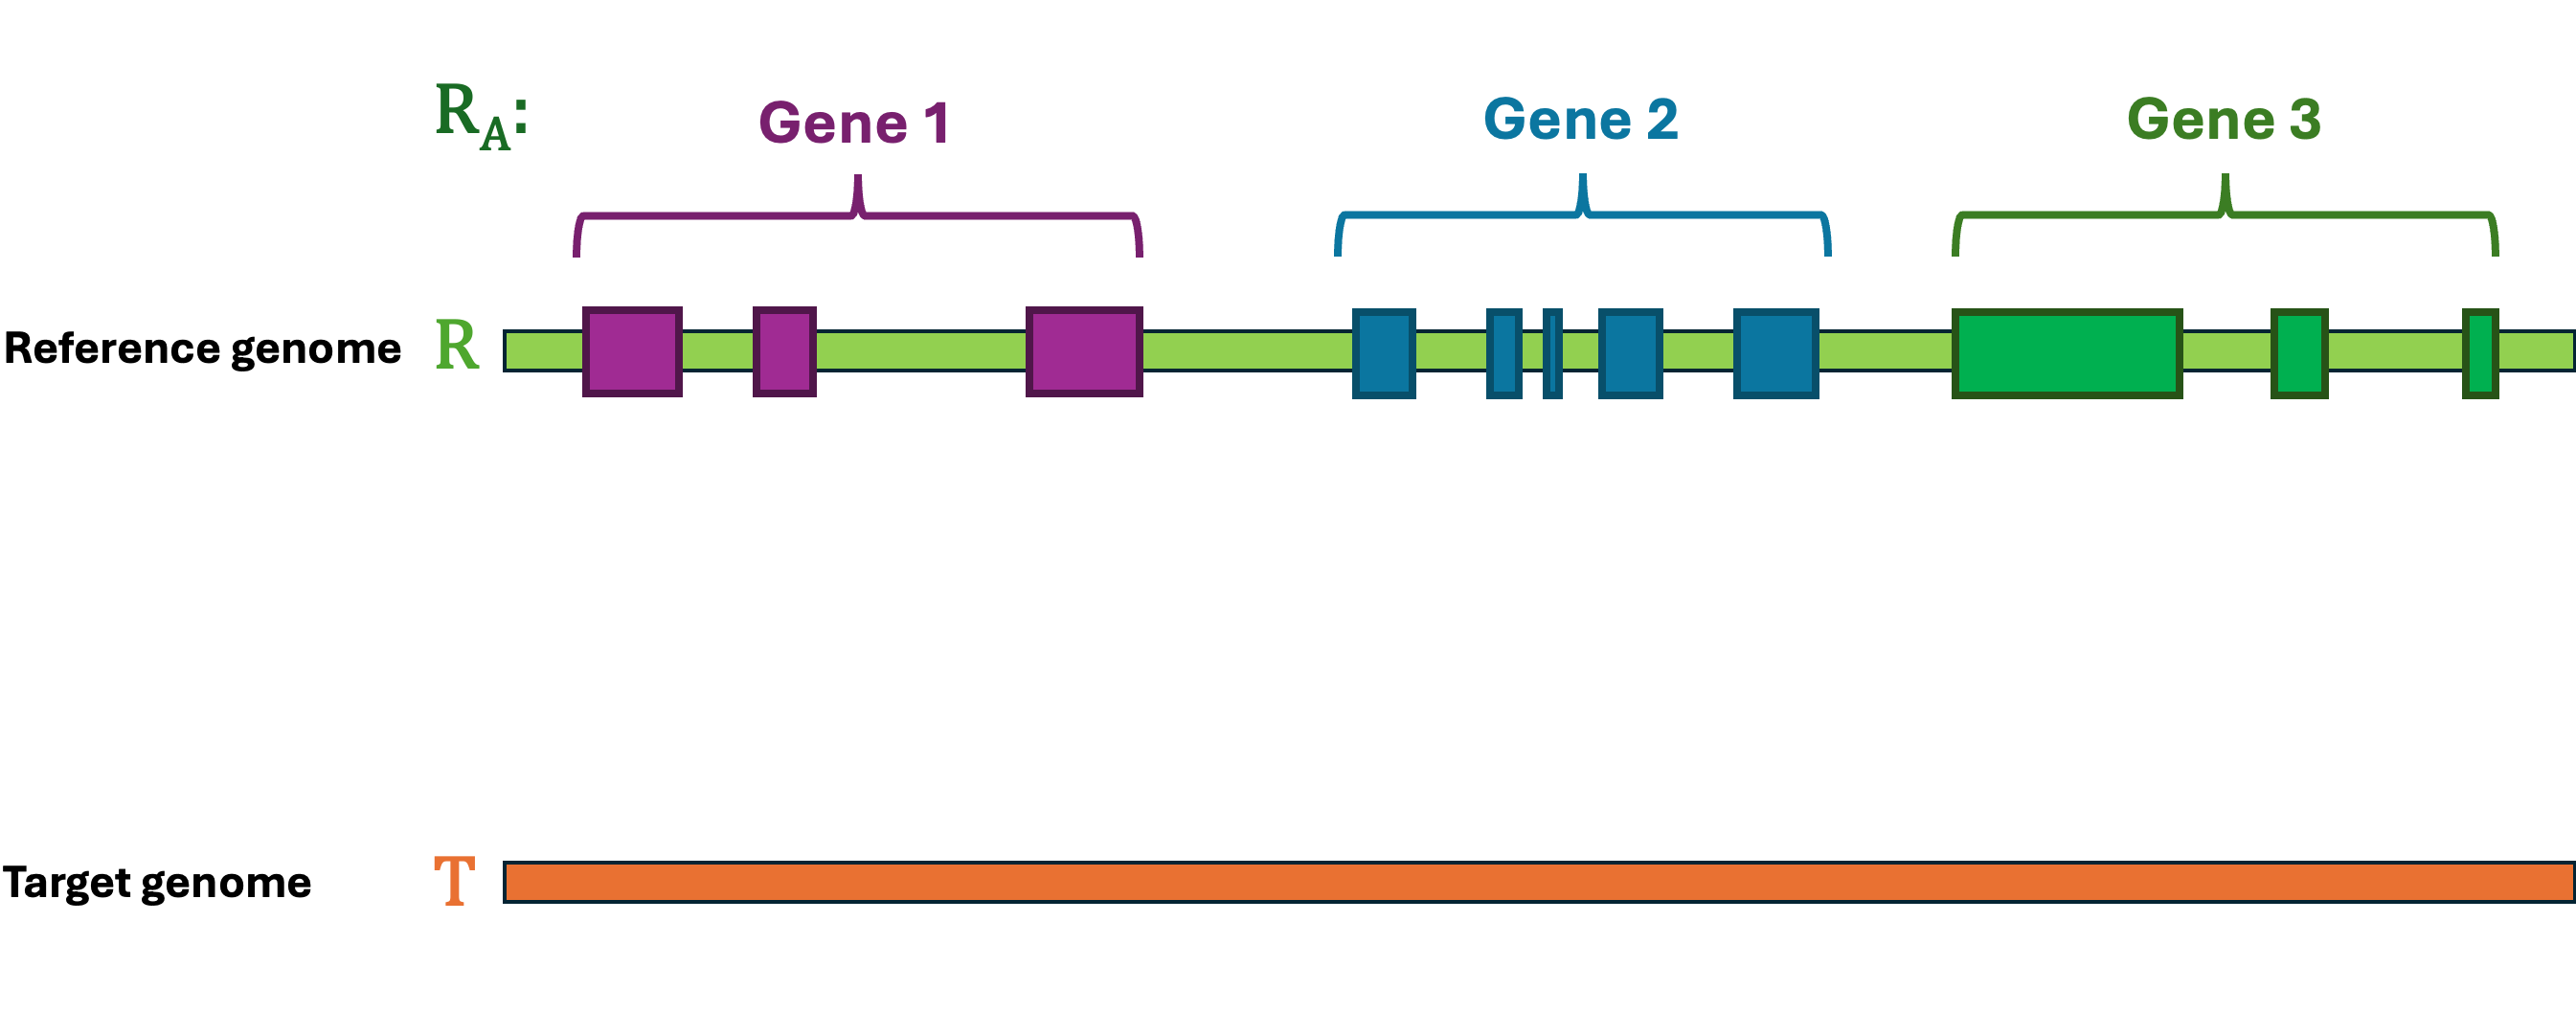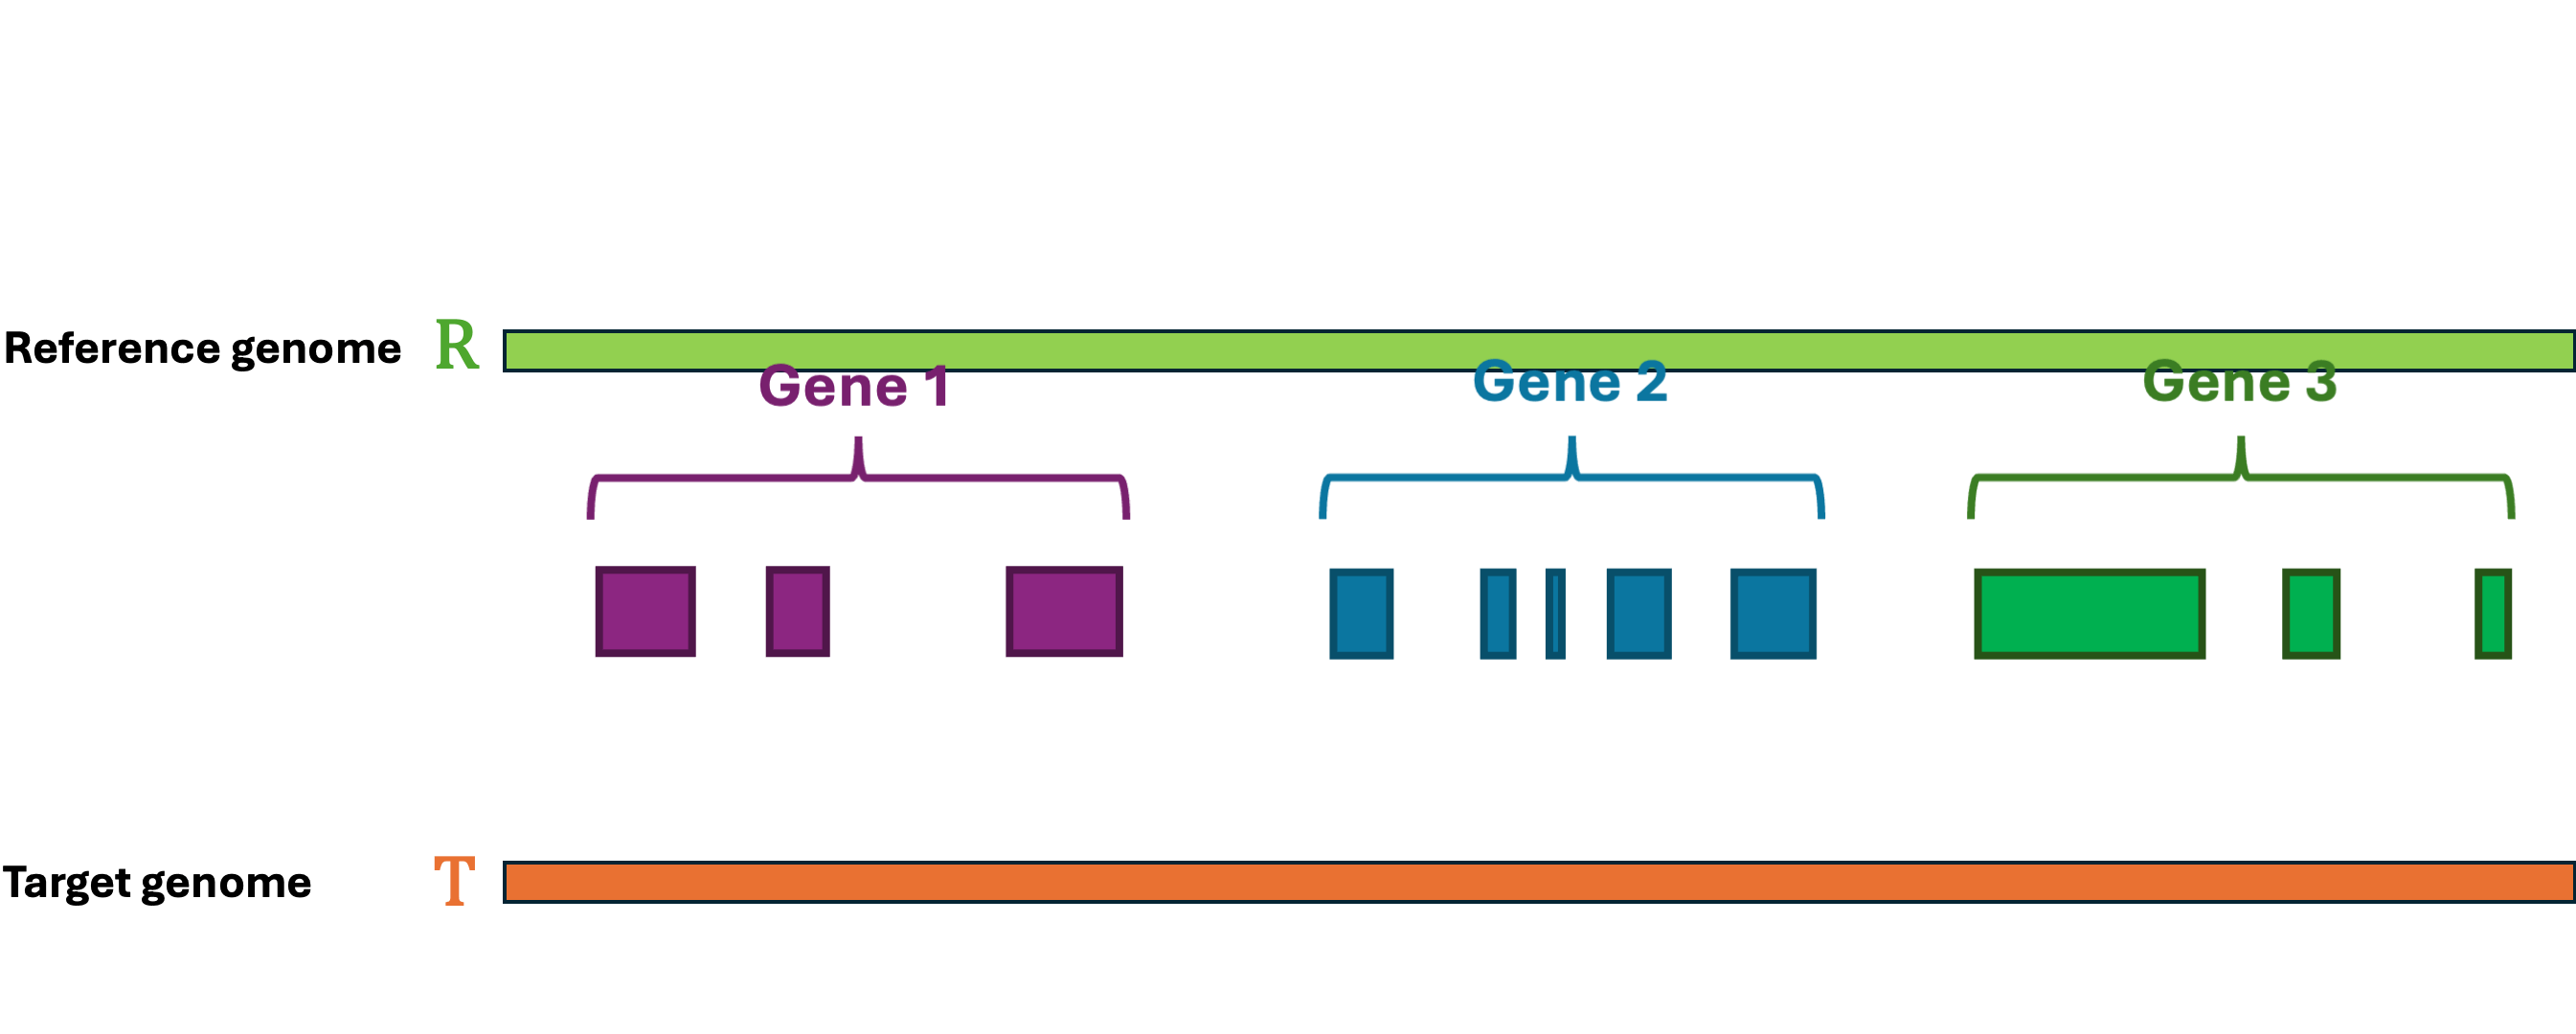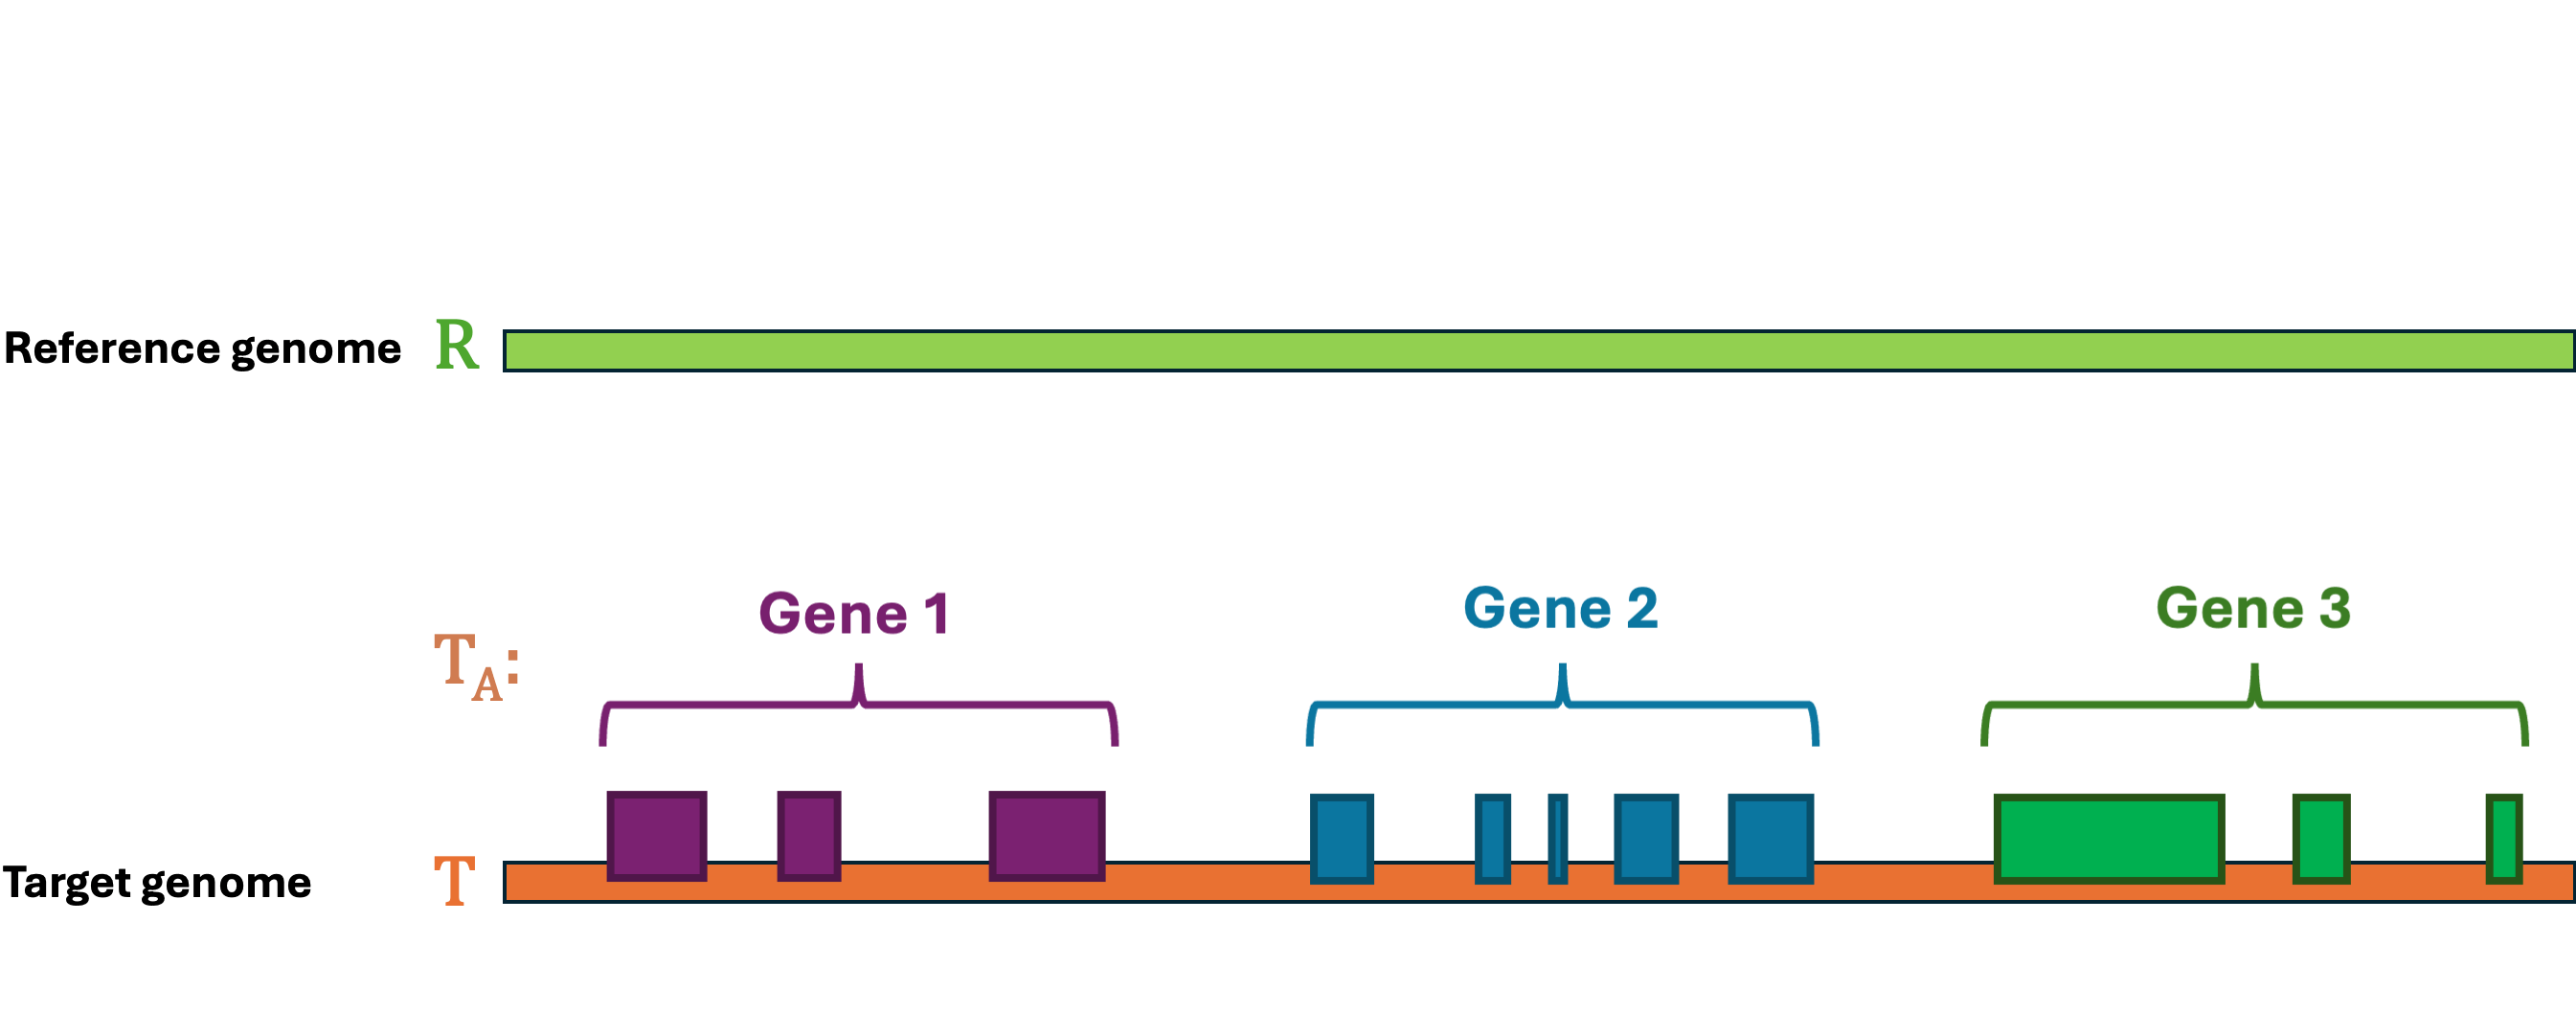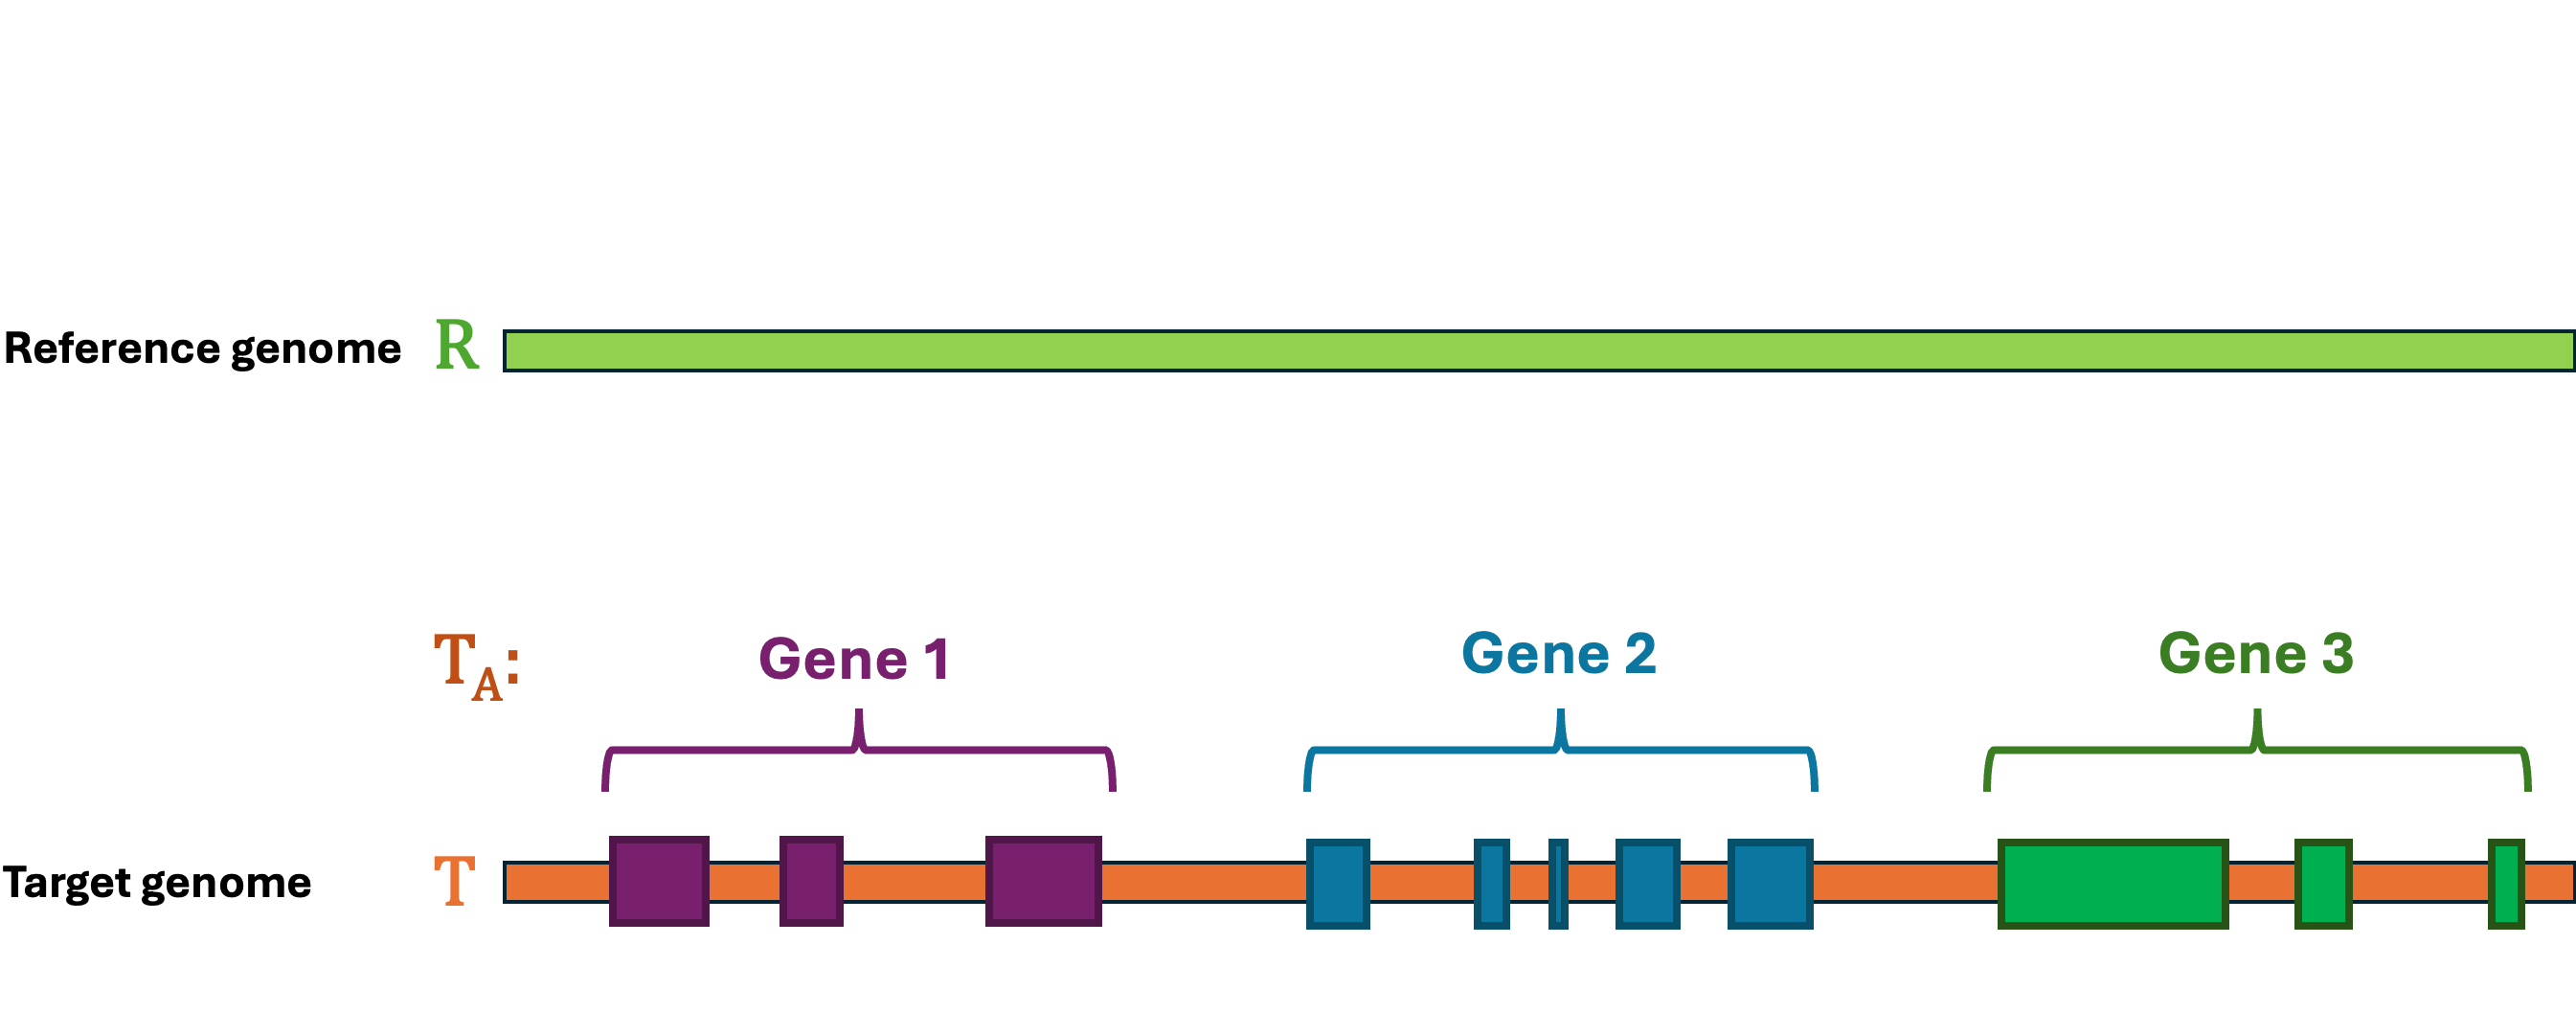
Let's first define the problem: Given a reference Genome , an Annotation , and a target Genome . The lift-over problem is defined as the process of changing the coordinates of Annotation from Genome to Genome , and generate a new annotation file Annotation . A simple illustration of the lift-over problem is shown in Figure 1.
LiftOn is the best tool to help you solve this problem! LiftOn employs a two-step protein maximization algorithm (PM algorithm).
The first module is the chaining algorithm. It starts by extracting protein sequences annotated by Liftoff and miniprot. LiftOn then aligns these sequences to full-length reference proteins. For each gene locus, LiftOn compares each section of the protein alignments from Liftoff and miniprot, chaining together the best combinations.
The second module is the open-reading frame search (ORF search) algorithm. In the case of truncated protein-coding transcripts, this algorithm examines alternative frames to identify the ORF that produces the longest match with the reference protein.
Inputs & outputs#
- Input:
target Genome in FASTA format.
reference Genome in FASTA format.
reference Annotation in GFF3 format.
- Output:
LiftOn annotation file, Annotation , in GFF3 format.
Protein sequence identities & mutation types
Features with extra copies
Unmapped features
User support#
Please go through the documentation below first. If you have questions about using the package, a bug report, or a feature request, please use the GitHub issue tracker here:
https://github.com/Kuanhao-Chao/LiftOn/issues
Key contributors#
LiftOn was designed and developed by Kuan-Hao Chao. This documentation was written by Kuan-Hao Chao and Alan Man. The LiftOn logo was designed by Alan Man.
Table of contents#
Examples
Info
LiftOn's limitation#
LiftOn's chaining algorithm currently only utilizes miniprot alignment results to fix the Liftoff annotation. However, it can be extended to chain together multiple DNA- and protein-based annotation files or aasembled RNA-Seq transcripts.
DNA- and protein-based methods still have some limitations. We are developing a module to merge the LiftOn annotation with the released curated annotations to generate better annotations.
As of v1.0.9 the per-locus processing step (the wall-clock hot spot) runs multi-threaded via --threads N --locus-pipeline; output is emitted in submission order, so a multi-threaded run is byte-for-byte identical to --threads 1.
Cite us#
Kua-Hao Chao, Jakob M. Heinz, Celine Hoh, Alan Mao, Alaina Shumate, Mihaela Pertea, and Steven L. Salzberg. "Combining DNA and protein alignments to improve genome annotation with LiftOn." Genome Research 35.2, 311-325 (2025), doi: https://doi.org/10.1101/gr.279620.124.
Alaina Shumate, and Steven L. Salzberg. "Liftoff: accurate mapping of gene annotations." Bioinformatics 37.12 (2021): 1639-1643.
1 maintainer

Release files for lifton 1.0.14
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| lifton-1.0.14.tar.gz | 413.6 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| lifton-1.0.14-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 857.3 kB
Release files / lifton-1.0.14.tar.gz
| Download URL | lifton-1.0.14.tar.gz |
|---|---|
| Size | 413.6 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
dc5e48e481227a33d52cd141fb7ceca36465788a0c721d533848c30547aabffe
|
|
BLAKE2b-256 checksum How to use checksums |
4876867ae562f3f6d73f1831c1ee5f85423f0268938a9ab909a850520debb66b
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 25, 2026.
Transparency logRelease files / lifton-1.0.14-py3-none-any.whl
| Download URL | lifton-1.0.14-py3-none-any.whl |
|---|---|
| Size | 443.7 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
259fdbbb7519fbfb8ca367a0f68882bb5525f8094bead1a372764205ee1b12ac
|
|
BLAKE2b-256 checksum How to use checksums |
213be85193ef994de9e4036b8425fb9aa389b3c81af2d5db28889594507eb1f6
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 25, 2026.
Transparency log













