
Fabric is the fast and lightweight way to scale PyTorch models without boilerplate
Website • Docs • Getting started • FAQ • Help • Discord


Lightning Fabric: Expert control.
Run on any device at any scale with expert-level control over PyTorch training loop and scaling strategy. You can even write your own Trainer.
Fabric is designed for the most complex models like foundation model scaling, LLMs, diffusion, transformers, reinforcement learning, active learning. Of any size.
| What to change | Resulting Fabric Code (copy me!) |
|---|---|
+ import lightning as L
  import torch; import torchvision as tv

  dataset = tv.datasets.CIFAR10("data", download=True,
                                train=True,
                                transform=tv.transforms.ToTensor())

+ fabric = L.Fabric()
+ fabric.launch()

  model = tv.models.resnet18()
  optimizer = torch.optim.SGD(model.parameters(), lr=0.001)
- device = "cuda" if torch.cuda.is_available() else "cpu"
- model.to(device)
+ model, optimizer = fabric.setup(model, optimizer)

  dataloader = torch.utils.data.DataLoader(dataset, batch_size=8)
+ dataloader = fabric.setup_dataloaders(dataloader)

  model.train()
  num_epochs = 10
  for epoch in range(num_epochs):
      for batch in dataloader:
          inputs, labels = batch
-         inputs, labels = inputs.to(device), labels.to(device)
          optimizer.zero_grad()
          outputs = model(inputs)
          loss = torch.nn.functional.cross_entropy(outputs, labels)
-         loss.backward()
+         fabric.backward(loss)
          optimizer.step()
|
import lightning as L
import torch; import torchvision as tv

dataset = tv.datasets.CIFAR10("data", download=True,
                              train=True,
                              transform=tv.transforms.ToTensor())

fabric = L.Fabric()
fabric.launch()

model = tv.models.resnet18()
optimizer = torch.optim.SGD(model.parameters(), lr=0.001)
model, optimizer = fabric.setup(model, optimizer)

dataloader = torch.utils.data.DataLoader(dataset, batch_size=8)
dataloader = fabric.setup_dataloaders(dataloader)

model.train()
num_epochs = 10
for epoch in range(num_epochs):
    for batch in dataloader:
        inputs, labels = batch
        optimizer.zero_grad()
        outputs = model(inputs)
        loss = torch.nn.functional.cross_entropy(outputs, labels)
        fabric.backward(loss)
        optimizer.step()
|
Key features
Easily switch from running on CPU to GPU (Apple Silicon, CUDA, …), TPU, multi-GPU or even multi-node training
# Use your available hardware
# no code changes needed
fabric = Fabric()

# Run on GPUs (CUDA or MPS)
fabric = Fabric(accelerator="gpu")

# 8 GPUs
fabric = Fabric(accelerator="gpu", devices=8)

# 256 GPUs, multi-node
fabric = Fabric(accelerator="gpu", devices=8, num_nodes=32)

# Run on TPUs
fabric = Fabric(accelerator="tpu")
Use state-of-the-art distributed training strategies (DDP, FSDP, DeepSpeed) and mixed precision out of the box
# Use state-of-the-art distributed training techniques
fabric = Fabric(strategy="ddp")
fabric = Fabric(strategy="deepspeed")
fabric = Fabric(strategy="fsdp")

# Switch the precision
fabric = Fabric(precision="16-mixed")
fabric = Fabric(precision="64")
All the device logic boilerplate is handled for you
  # no more of this!
- model.to(device)
- batch.to(device)
Build your own custom Trainer using Fabric primitives for training checkpointing, logging, and more
import lightning as L


class MyCustomTrainer:
    def __init__(self, accelerator="auto", strategy="auto", devices="auto", precision="32-true"):
        self.fabric = L.Fabric(accelerator=accelerator, strategy=strategy, devices=devices, precision=precision)

    def fit(self, model, optimizer, dataloader, max_epochs):
        self.fabric.launch()

        model, optimizer = self.fabric.setup(model, optimizer)
        dataloader = self.fabric.setup_dataloaders(dataloader)
        model.train()

        for epoch in range(max_epochs):
            for batch in dataloader:
                input, target = batch
                optimizer.zero_grad()
                output = model(input)
                loss = loss_fn(output, target)
                self.fabric.backward(loss)
                optimizer.step()
You can find a more extensive example in our examples
Continuous Integration
Lightning is rigorously tested across multiple CPUs and GPUs and against major Python and PyTorch versions.
*Codecov is > 90%+ but build delays may show less
Current build statuses
| System / PyTorch ver. | 1.12 | 1.13 | 2.0 | 2.1 |
|---|---|---|---|---|
| Linux py3.9 [GPUs] |  |
|||
| Linux (multiple Python versions) |  |
|
|
|
| OSX (multiple Python versions) | |
|
|
|
| Windows (multiple Python versions) | |
|
|
|
Getting started
Install Lightning
Prerequisites
TIP: We strongly recommend creating a virtual environment first. Don’t know what this is? Follow our beginner guide here.
- Python 3.8.x or later (3.8.x, 3.9.x, 3.10.x, ...)
pip install -U lightning
Convert your PyTorch to Fabric
-
Create the
Fabricobject at the beginning of your training code.import Lightning as L fabric = L.Fabric() -
Call
setup()on each model and optimizer pair andsetup_dataloaders()on all your data loaders.model, optimizer = fabric.setup(model, optimizer) dataloader = fabric.setup_dataloaders(dataloader) -
Remove all
.toand.cudacalls -> Fabric will take care of it.- model.to(device) - batch.to(device)
-
Replace
loss.backward()byfabric.backward(loss).- loss.backward() + fabric.backward(loss)
-
Run the script from the terminal with
lightning run model path/to/train.py
or use the launch() method in a notebook. Learn more about launching distributed training.
FAQ
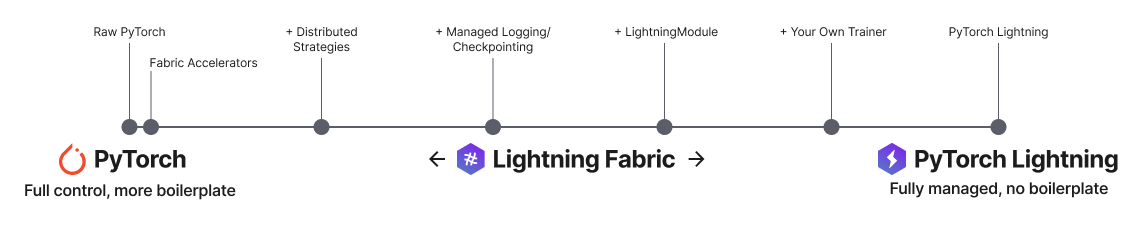
When to use Fabric?
- Minimum code changes- You want to scale your PyTorch model to use multi-GPU or use advanced strategies like DeepSpeed without having to refactor. You don’t care about structuring your code- you just want to scale it as fast as possible.
- Maximum control- Write your own training and/or inference logic down to the individual optimizer calls. You aren’t forced to conform to a standardized epoch-based training loop like the one in Lightning Trainer. You can do flexible iteration based training, meta-learning, cross-validation and other types of optimization algorithms without digging into framework internals. This also makes it super easy to adopt Fabric in existing PyTorch projects to speed-up and scale your models without the compromise on large refactors. Just remember: With great power comes a great responsibility.
- Maximum flexibility- You want to have full control over your entire training- in Fabric all features are opt-in, and it provides you with a tool box of primitives so you can build your own Trainer.
When to use the Lightning Trainer?
- You want to have all the engineering boilerplate handled for you - dozens of features like checkpointing, logging and early stopping out of the box. Less hassle, less error prone, easy to try different techniques and features.
- You want to have good defaults chosen for you - so you can have a better starting point.
- You want your code to be modular, readable and well structured - easy to share between projects and with collaborators.
Can I use Fabric with my LightningModule or Lightning Callback?
Yes :) Fabric works with PyTorch LightningModules and Callbacks, so you can choose how to structure your code and reuse existing models and callbacks as you wish. Read more here.
Examples
Asking for help
If you have any questions please:
Metadata
Release files for lightning-fabric 2.6.6
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| lightning_fabric-2.6.6.tar.gz | 202.5 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| lightning_fabric-2.6.6-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 459.5 kB
Release files / lightning_fabric-2.6.6.tar.gz
| Download URL | lightning_fabric-2.6.6.tar.gz |
|---|---|
| Size | 202.5 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
c22b4b5149e1c4b837b610ced0bbc19ac85d7a0626f38307e3044497c45b3aeb
|
|
BLAKE2b-256 checksum How to use checksums |
d9e7a64759f80e58b5be309c92550a1dd8e040313aabda9d64cf7b1eb50edc3f
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.13.7
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 10, 2026.
Transparency logRelease files / lightning_fabric-2.6.6-py3-none-any.whl
| Download URL | lightning_fabric-2.6.6-py3-none-any.whl |
|---|---|
| Size | 257.1 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
58244e08eddb4bbd2787fe91cc6e14499fee06ee0e22a43b45772204c75e2627
|
|
BLAKE2b-256 checksum How to use checksums |
246c8d7aa12604de485453924e56615bac019fcd78b401705e3c0cc4d5a68662
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.13.7
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 10, 2026.
Transparency log













