
🚅 LiteLLM
LiteLLM AI Gateway
Open Source AI Gateway for 100+ LLMs. Self-hosted. Enterprise-ready. Call any LLM in OpenAI format.


LiteLLM Proxy Server (AI Gateway) | Hosted Proxy | Enterprise Tier | Website



What is LiteLLM
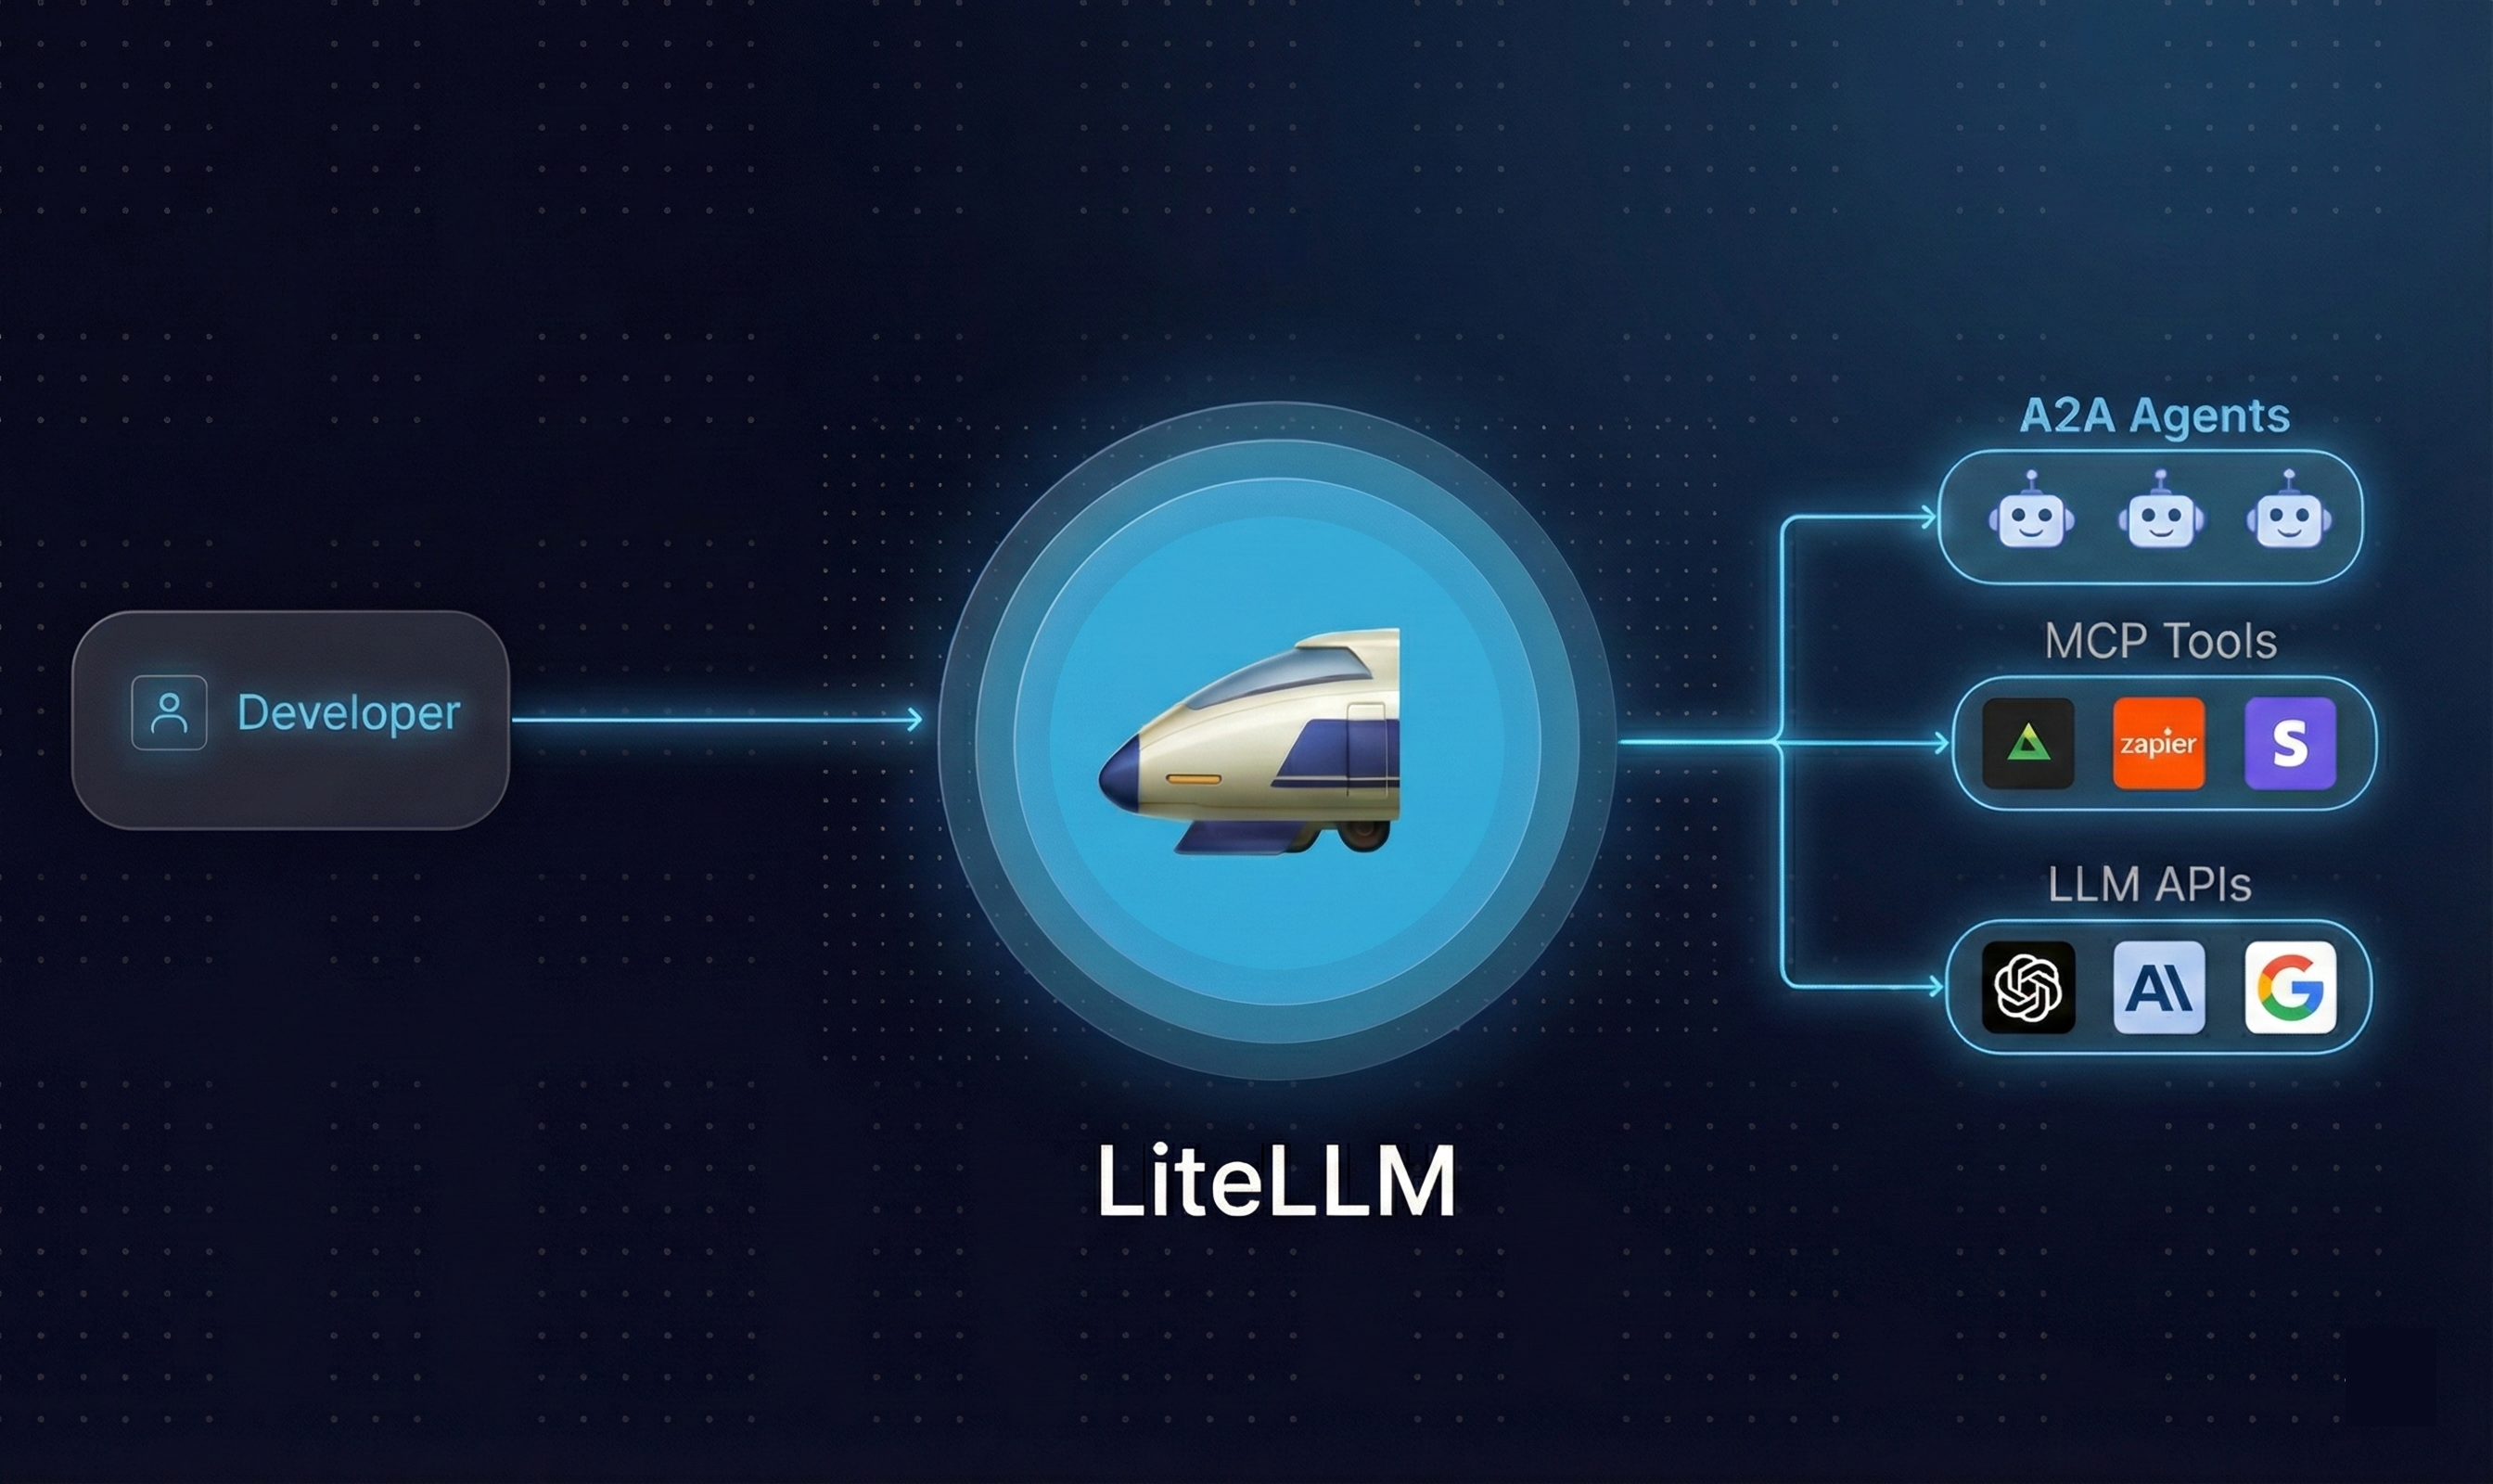
LiteLLM is an open source AI Gateway that gives you a single, unified interface to call 100+ LLM providers — OpenAI, Anthropic, Gemini, Bedrock, Azure, and more — using the OpenAI format.
Use it as a Python SDK for direct library integration, or deploy the AI Gateway (Proxy Server) as a centralized service for your team or organization.
Jump to LiteLLM Proxy (LLM Gateway) Docs
Jump to Supported LLM Providers
Why LiteLLM
Managing LLM calls across providers gets complicated fast — different SDKs, auth patterns, request formats, and error types for every model. LiteLLM removes that friction:
- Unified API — one interface for 100+ LLMs, no provider-specific SDK juggling
- Drop-in OpenAI compatibility — swap providers without rewriting your code
- Production-ready gateway — virtual keys, spend tracking, guardrails, load balancing, and an admin dashboard out of the box
- 8ms P95 latency at 1k RPS (benchmarks)
OSS Adopters
 |
 |
 |
 |
 |
Netflix |
 |
Features
LLMs - Call 100+ LLMs (Python SDK + AI Gateway)
All Supported Endpoints - /chat/completions, /responses, /embeddings, /images, /audio, /batches, /rerank, /a2a, /messages and more.
Python SDK
uv add litellm
An independent litellm-core distribution provides the Python SDK with the same
import litellm API and runtime dependencies. It has no optional extras, CLI entry
points, or bundled dashboard. Install one SDK distribution per environment because
litellm and litellm-core own overlapping Python files. Use litellm for the
proxy, CLI, and optional extras
Build and install core from this checkout while its release integration is pending:
python scripts/build_core_distribution.py --out-dir dist/core
python -m pip install dist/core/litellm_core-*.whl
The builder requires Git, uv and the Rust build toolchain. It reads the release version
from the root pyproject.toml, leaves source files unchanged, and produces a wheel
and a self-contained sdist in dist/core. Run installation in a fresh environment
without litellm
from litellm import completion
import os

os.environ["OPENAI_API_KEY"] = "your-openai-key"
os.environ["ANTHROPIC_API_KEY"] = "your-anthropic-key"

# OpenAI
response = completion(model="openai/gpt-4o", messages=[{"role": "user", "content": "Hello!"}])

# Anthropic
response = completion(model="anthropic/claude-sonnet-4-20250514", messages=[{"role": "user", "content": "Hello!"}])
AI Gateway (Proxy Server)
Getting Started - E2E Tutorial - Setup virtual keys, make your first request
uv tool install 'litellm[proxy]'
litellm --model gpt-4o
import openai

client = openai.OpenAI(api_key="anything", base_url="http://0.0.0.0:4000")
response = client.chat.completions.create(
    model="gpt-4o",
    messages=[{"role": "user", "content": "Hello!"}]
)
Agents - Invoke A2A Agents (Python SDK + AI Gateway)
Supported Providers - LangGraph, Vertex AI Agent Engine, Azure AI Foundry, Bedrock AgentCore, Pydantic AI
Python SDK - A2A Protocol
from litellm.a2a_protocol import A2AClient
from a2a.types import SendMessageRequest, MessageSendParams
from uuid import uuid4

client = A2AClient(base_url="http://localhost:10001")

request = SendMessageRequest(
    id=str(uuid4()),
    params=MessageSendParams(
        message={
            "role": "user",
            "parts": [{"kind": "text", "text": "Hello!"}],
            "messageId": uuid4().hex,
        }
    )
)
response = await client.send_message(request)
AI Gateway (Proxy Server)
Step 1. Add your Agent to the AI Gateway — set protocolVersion to 1.0 or 0.3 per agent
Step 2. Call Agent via A2A SDK (requires a2a-sdk>=1.1.0)
import httpx
from a2a.client import A2ACardResolver, ClientConfig, ClientFactory
from a2a.types import Message, Part, Role, SendMessageRequest
from a2a.utils.constants import TransportProtocol
from uuid import uuid4

base_url = "http://localhost:4000/a2a/my-agent"  # LiteLLM proxy + agent name
headers = {"Authorization": "Bearer <your-master-key>"}    # LiteLLM master key or a virtual key

async with httpx.AsyncClient(headers=headers, timeout=60.0) as http_client:
    resolver = A2ACardResolver(httpx_client=http_client, base_url=base_url)
    agent_card = await resolver.get_agent_card()
    config = ClientConfig(
        httpx_client=http_client,
        streaming=False,
        supported_protocol_bindings=[TransportProtocol.JSONRPC, TransportProtocol.HTTP_JSON],
    )
    client = ClientFactory(config).create(agent_card)

    request = SendMessageRequest(
        message=Message(
            message_id=uuid4().hex,
            role=Role.ROLE_USER,
            parts=[Part(text="Hello!")],
        )
    )
    async for event in client.send_message(request):
        populated = event.ListFields()
        if populated and populated[0][0].name in ("message", "msg"):
            print("".join(getattr(p, "text", "") or "" for p in populated[0][1].parts))
MCP Tools - Connect MCP servers to any LLM (Python SDK + AI Gateway)
Python SDK - MCP Bridge
from mcp import ClientSession, StdioServerParameters
from mcp.client.stdio import stdio_client
from litellm import experimental_mcp_client
import litellm

server_params = StdioServerParameters(command="python", args=["mcp_server.py"])

async with stdio_client(server_params) as (read, write):
    async with ClientSession(read, write) as session:
        await session.initialize()

        # Load MCP tools in OpenAI format
        tools = await experimental_mcp_client.load_mcp_tools(session=session, format="openai")

        # Use with any LiteLLM model
        response = await litellm.acompletion(
            model="gpt-4o",
            messages=[{"role": "user", "content": "What's 3 + 5?"}],
            tools=tools
        )
AI Gateway - MCP Gateway
Step 1. Add your MCP Server to the AI Gateway
Step 2. Call MCP tools via /chat/completions
curl -X POST 'http://0.0.0.0:4000/v1/chat/completions' \
  -H 'Authorization: Bearer <your-master-key>' \
  -H 'Content-Type: application/json' \
  -d '{
    "model": "gpt-4o",
    "messages": [{"role": "user", "content": "Summarize the latest open PR"}],
    "tools": [{
      "type": "mcp",
      "server_url": "litellm_proxy/mcp/github",
      "server_label": "github_mcp",
      "require_approval": "never"
    }]
  }'
Use with Cursor IDE
{
  "mcpServers": {
    "LiteLLM": {
      "url": "http://localhost:4000/mcp/",
      "headers": {
        "x-litellm-api-key": "Bearer <your-master-key>"
      }
    }
  }
}
For MCP OAuth, an upstream may advertise dynamic client registration but refuse requests with HTTP 401 or 403. If the provider requires a pre-registered OAuth app, configure its credentials.client_id and, when required, credentials.client_secret on the MCP server. This skips dynamic registration in the gateway sign-in flow. The provider must approve the app for MCP access; reaching its authorization page does not establish that login or tool calls will succeed
Agents - Run Claude Code, Codex, OpenCode or Deep Agents on any model (Python SDK)
Python SDK - Agents
import litellm
from litellm import Harness, sandbox

result = litellm.agent(
    Harness.CLAUDE_CODE,  # or Harness.CODEX, Harness.OPENCODE, Harness.DEEPAGENTS
    "Find why tests/test_router.py is flaky and fix it.",
    sandbox=sandbox.local("./repo"),
    model="litellm_proxy/claude-sonnet-4-5",  # a model group on your AI Gateway
)

print(result.text, result.cost, [f.path for f in result.files])
Set LITELLM_PROXY_API_BASE and LITELLM_PROXY_API_KEY and every model call the agent makes goes through your AI Gateway, tagged harness,claude_code. Drop the litellm_proxy/ prefix to call a provider directly. Install starlette uvicorn plus the agent's CLI (claude, codex or opencode), or deepagents langchain-litellm for Deep Agents.
Supported Providers (Website Supported Models | Docs)
Get Started
You can use LiteLLM through either the Proxy Server or Python SDK. Both give you a unified interface to access multiple LLMs (100+ LLMs). Choose the option that best fits your needs:
| LiteLLM AI Gateway | LiteLLM Python SDK | |
|---|---|---|
| Use Case | Central service (LLM Gateway) to access multiple LLMs | Use LiteLLM directly in your Python code |
| Who Uses It? | Gen AI Enablement / ML Platform Teams | Developers building LLM projects |
| Key Features | Centralized API gateway with authentication and authorization, multi-tenant cost tracking and spend management per project/user, per-project customization (logging, guardrails, caching), virtual keys for secure access control, admin dashboard UI for monitoring and management | Direct Python library integration in your codebase, Router with retry/fallback logic across multiple deployments (e.g. Azure/OpenAI) - Router, application-level load balancing and cost tracking, exception handling with OpenAI-compatible errors, observability callbacks (Lunary, MLflow, Langfuse, etc.) |
Stable Release: Use docker images with the -stable tag. These have undergone 12 hour load tests, before being published. More information about the release cycle here
Support for more providers. Missing a provider or LLM Platform, raise a feature request.
Deploy on AWS or GCP with Terraform
Run the LiteLLM proxy as a production-ready componentized stack (gateway, backend, UI on separate services; managed Postgres + Redis + object store) using the published Terraform modules. Both modules are on the public Terraform Registry — no auth needed.
AWS — ECS Fargate + Aurora + ElastiCache + ALB
git clone https://github.com/BerriAI/litellm.git
cd litellm/terraform/litellm/aws/examples/default
cp terraform.tfvars.example terraform.tfvars   # edit region/tenant/env
terraform init && terraform apply
Or call the module from your own root config:
# main.tf
terraform {
  required_version = ">= 1.6.0"
  required_providers {
    aws = { source = "hashicorp/aws", version = "~> 5.60" }
  }
}

provider "aws" {
  region = "us-west-2"
}

module "litellm" {
  source  = "BerriAI/litellm/aws"
  version = "~> 1.89"

  region = "us-west-2"
  azs    = ["us-west-2a", "us-west-2b"]
  tenant = "acme"
  env    = "prod"

  # Production: provide an ACM cert. Without one, set allow_plaintext_alb = true
  # (dev/trial only).
  # acm_certificate_arn = "arn:aws:acm:us-west-2:111122223333:certificate/..."
  allow_plaintext_alb = true
}

output "litellm_url" {
  value = module.litellm.alb_dns_name
}
terraform init
terraform apply
Provider API keys live in AWS Secrets Manager; reference ARNs via gateway_extra_secrets. Full input list and architecture diagram on the registry page.
GCP — Cloud Run + Cloud SQL + Memorystore + HTTPS LB
Real 1-click. Opens Cloud Shell, clones this repo, and walks you through terraform apply via a built-in DeployStack tutorial — pick the project, the tutorial sets up the Artifact Registry remote repo, writes terraform.tfvars from your answers, and runs apply.
To call the module from your own config instead, Cloud Run can't pull from ghcr.io directly, so first set up a one-time Artifact Registry remote repo backed by GHCR:
gcloud artifacts repositories create litellm \
  --location=us-central1 \
  --repository-format=docker \
  --mode=remote-repository \
  --remote-docker-repo=https://ghcr.io \
  --project=my-gcp-project
Then:
# main.tf
terraform {
  required_version = ">= 1.6.0"
  required_providers {
    google      = { source = "hashicorp/google",      version = "~> 6.10" }
    google-beta = { source = "hashicorp/google-beta", version = "~> 6.10" }
  }
}

provider "google"      { project = "my-gcp-project"; region = "us-central1" }
provider "google-beta" { project = "my-gcp-project"; region = "us-central1" }

module "litellm" {
  source  = "BerriAI/litellm/google"
  version = "~> 1.89"

  project_id = "my-gcp-project"
  region     = "us-central1"
  tenant     = "acme"
  env        = "prod"

  # Replace my-gcp-project with your GCP project ID (same value as project_id above).
  image_registry = "us-central1-docker.pkg.dev/my-gcp-project/litellm/berriai"

  # Production: provide DNS already pointing at the LB IP for Google-managed certs.
  # Without one, set allow_plaintext_lb = true (dev/trial only).
  # lb_domains         = ["proxy.example.com"]
  allow_plaintext_lb = true
}

output "litellm_url" {
  value = module.litellm.load_balancer_url
}
terraform init
terraform apply
Provider API keys live in Secret Manager; reference resource IDs (e.g. projects/my-gcp-project/secrets/openai-api-key) via gateway_extra_secrets. Full input list and architecture diagram on the registry page.
Both stacks include
- The full componentized split (gateway / backend / UI as independent services)
- Managed Postgres (writer + reader) and Redis
- Versioned object store for proxy state + file uploads
- An auto-generated
LITELLM_MASTER_KEYin your cloud's secret manager - A one-off migration job that runs
prisma migrate deploybefore the proxy starts - The same
proxy_configsurface as the Helm chart — pass YAML as a typed map
The Terraform modules live at terraform/litellm/aws/ and terraform/litellm/gcp/ in this repo; the registry entries are read-only mirrors updated on each release.
Run in Developer Mode
Services
- Setup .env file in root
- Run dependent services
docker-compose up db prometheus
Backend
- Run
make bootstrap - Start proxy backend:
uv run python litellm/proxy/proxy_cli.py
Frontend
- Navigate to
ui/litellm-dashboard(dependencies were already installed w/make bootstrap) - Start dashboard:
npm run dev
Verify Docker Image Signatures
All LiteLLM Docker images published to GHCR are signed with cosign. Every release is signed with the same key introduced in commit 0112e53.
Verify using the pinned commit hash (recommended):
A commit hash is cryptographically immutable, so this is the strongest way to ensure you are using the original signing key:
cosign verify \
  --key https://raw.githubusercontent.com/BerriAI/litellm/0112e53046018d726492c814b3644b7d376029d0/cosign.pub \
  ghcr.io/berriai/litellm:<release-tag>
Verify using a release tag (convenience):
Tags are protected in this repository and resolve to the same key. This option is easier to read but relies on tag protection rules:
cosign verify \
  --key https://raw.githubusercontent.com/BerriAI/litellm/<release-tag>/cosign.pub \
  ghcr.io/berriai/litellm:<release-tag>
Replace <release-tag> with the version you are deploying (e.g. v1.83.0-stable).
Enterprise
For companies that need better security, user management and professional support
Get an Enterprise License Talk to founders
This covers:
- ✅ Features under the LiteLLM Commercial License:
- ✅ Feature Prioritization
- ✅ Custom Integrations
- ✅ Professional Support - Dedicated discord + slack
- ✅ Custom SLAs
- ✅ Secure access with Single Sign-On
Contributing
We welcome contributions to LiteLLM! Whether you're fixing bugs, adding features, or improving documentation, we appreciate your help.
Quick Start for Contributors
This requires uv to be installed.
git clone https://github.com/BerriAI/litellm.git
cd litellm
make install-dev    # Install development dependencies
make format         # Format your code
make lint           # Run all linting checks
make test-unit      # Run unit tests
make format-check   # Check formatting only
For detailed contributing guidelines, see CONTRIBUTING.md.
📖 Contributing to documentation? The LiteLLM docs have moved to a separate repository: BerriAI/litellm-docs. Please open doc PRs there. Docs are served at docs.litellm.ai.
Code Quality / Linting
LiteLLM follows the Google Python Style Guide.
Our automated checks include:
- Ruff for formatting, linting, and code quality
- basedpyright for type checking
- Circular import detection
- Import safety checks
All these checks must pass before your PR can be merged.
Support / talk with founders
- Schedule Demo 👋
- Community Discord 💭
- Community Slack 💭
- Our emails ✉️ ishaan@berri.ai / krrish@berri.ai
Contributors
Metadata
Release files for litellm-core 1.106.3
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| litellm_core-1.106.3.tar.gz | 15.3 MB | Without provenance | Details |
Built distributions (wheels)
| File | Reset | |||
|---|---|---|---|---|
| litellm_core-1.106.3-cp310-abi3-win_amd64.whl | CPython 3.10 | abi3 | Windows x86-64 | Details |
| litellm_core-1.106.3-cp310-abi3-musllinux_1_2_x86_64.whl | CPython 3.10 | abi3 | Linux musl 1.2+ x86-64 | Details |
| litellm_core-1.106.3-cp310-abi3-musllinux_1_2_aarch64.whl | CPython 3.10 | abi3 | Linux musl 1.2+ ARM64 | Details |
| litellm_core-1.106.3-cp310-abi3-manylinux_2_28_x86_64.whl | CPython 3.10 | abi3 | Linux glibc 2.28+ x86-64 | Details |
| litellm_core-1.106.3-cp310-abi3-manylinux_2_28_aarch64.whl | CPython 3.10 | abi3 | Linux glibc 2.28+ ARM64 | Details |
| litellm_core-1.106.3-cp310-abi3-macosx_11_0_arm64.whl | CPython 3.10 | abi3 | macOS 11.0+ ARM64 | Details |
| litellm_core-1.106.3-cp310-abi3-macosx_10_12_x86_64.whl | CPython 3.10 | abi3 | macOS 10.12+ x86-64 | Details |
Total release size: 223.6 MB
Release files / litellm_core-1.106.3.tar.gz
| Download URL | litellm_core-1.106.3.tar.gz |
|---|---|
| Size | 15.3 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
f12c24276db1ea8294dab1863e40664070d040cdd11bf227365a28526213fef9
|
|
BLAKE2b-256 checksum How to use checksums |
cc39bba2b89dd6cd03c73a1bbf46940e748d7d2ce4615f095b24860135ebb26a
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.13.7
|
Release files / litellm_core-1.106.3-cp310-abi3-win_amd64.whl
| Download URL | litellm_core-1.106.3-cp310-abi3-win_amd64.whl |
|---|---|
| Size | 30.9 MB |
| Tags | CPython 3.10 Windows x86-64 abi3 |
|
SHA-256 checksum How to use checksums |
9c78d8c58d3b2dc7ae309d260ffb3bf7a08ecfd9e167151b88b6a8ea5b814ae9
|
|
BLAKE2b-256 checksum How to use checksums |
46ea28ba3b26b029e7466d7451df0dc1dbf2de453fc62a2f948e7383232383ad
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.13.7
|
Release files / litellm_core-1.106.3-cp310-abi3-musllinux_1_2_x86_64.whl
| Download URL | litellm_core-1.106.3-cp310-abi3-musllinux_1_2_x86_64.whl |
|---|---|
| Size | 30.3 MB |
| Tags | CPython 3.10 Linux musl 1.2+ x86-64 abi3 |
|
SHA-256 checksum How to use checksums |
12fdad08c1ab7471760ec3e25c4df496ae1006e22cb907546e3f9e6bef078161
|
|
BLAKE2b-256 checksum How to use checksums |
2ace433e63c4c32c320a951b01072a6ede425e6002772b9a1125b87033f37f8a
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.13.7
|
Release files / litellm_core-1.106.3-cp310-abi3-musllinux_1_2_aarch64.whl
| Download URL | litellm_core-1.106.3-cp310-abi3-musllinux_1_2_aarch64.whl |
|---|---|
| Size | 29.3 MB |
| Tags | CPython 3.10 Linux musl 1.2+ ARM64 abi3 |
|
SHA-256 checksum How to use checksums |
37518e10b0cb512e048d5ecc5e664b366d75ee31b96d094ee26b8017058802b5
|
|
BLAKE2b-256 checksum How to use checksums |
1f9dd64e1f4294cbf2ceec2d55571cf2db2ab1f6116b8a1ed609b78aabf15b14
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.13.7
|
Release files / litellm_core-1.106.3-cp310-abi3-manylinux_2_28_x86_64.whl
| Download URL | litellm_core-1.106.3-cp310-abi3-manylinux_2_28_x86_64.whl |
|---|---|
| Size | 30.2 MB |
| Tags | CPython 3.10 Linux glibc 2.28+ x86-64 abi3 |
|
SHA-256 checksum How to use checksums |
e50c00192802bf41071d15dc9da38ce92b1f8ed1ad7035772825fa6cab5c6600
|
|
BLAKE2b-256 checksum How to use checksums |
d77d5453d7d72cb39e5507e1b45a11f81311fedf6ea8ac929467eecef5b84980
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.13.7
|
Release files / litellm_core-1.106.3-cp310-abi3-manylinux_2_28_aarch64.whl
| Download URL | litellm_core-1.106.3-cp310-abi3-manylinux_2_28_aarch64.whl |
|---|---|
| Size | 29.2 MB |
| Tags | CPython 3.10 Linux glibc 2.28+ ARM64 abi3 |
|
SHA-256 checksum How to use checksums |
54445754fa4ea302c14a854f27acce4b87b1cc735f09a4040171cd73ea88b806
|
|
BLAKE2b-256 checksum How to use checksums |
4e2af76c4e28b41fe3e1d76b6668705bf3460e8b102e600047eab8b2a9b65e8e
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.13.7
|
Release files / litellm_core-1.106.3-cp310-abi3-macosx_11_0_arm64.whl
| Download URL | litellm_core-1.106.3-cp310-abi3-macosx_11_0_arm64.whl |
|---|---|
| Size | 28.7 MB |
| Tags | CPython 3.10 abi3 macOS 11.0+ ARM64 |
|
SHA-256 checksum How to use checksums |
e9d0c29badd3585d1efbfce9f820c5ccb78cf54573f25765086b964a6bcd6021
|
|
BLAKE2b-256 checksum How to use checksums |
cf9562d13370d99bd6a89376c5197fc02cc6b2b093ee337e513716466d9db57f
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.13.7
|
Release files / litellm_core-1.106.3-cp310-abi3-macosx_10_12_x86_64.whl
| Download URL | litellm_core-1.106.3-cp310-abi3-macosx_10_12_x86_64.whl |
|---|---|
| Size | 29.7 MB |
| Tags | CPython 3.10 abi3 macOS 10.12+ x86-64 |
|
SHA-256 checksum How to use checksums |
a9b5eca47aa55c7763c990f32017557409477282ef9565ee073f632e5511eda5
|
|
BLAKE2b-256 checksum How to use checksums |
f105a583c4a17871281982685ef1a94063a856960163b269c626506534461d76
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.13.7
|
Security for litellm-core 1.106.3
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














