
 LLM Compressor
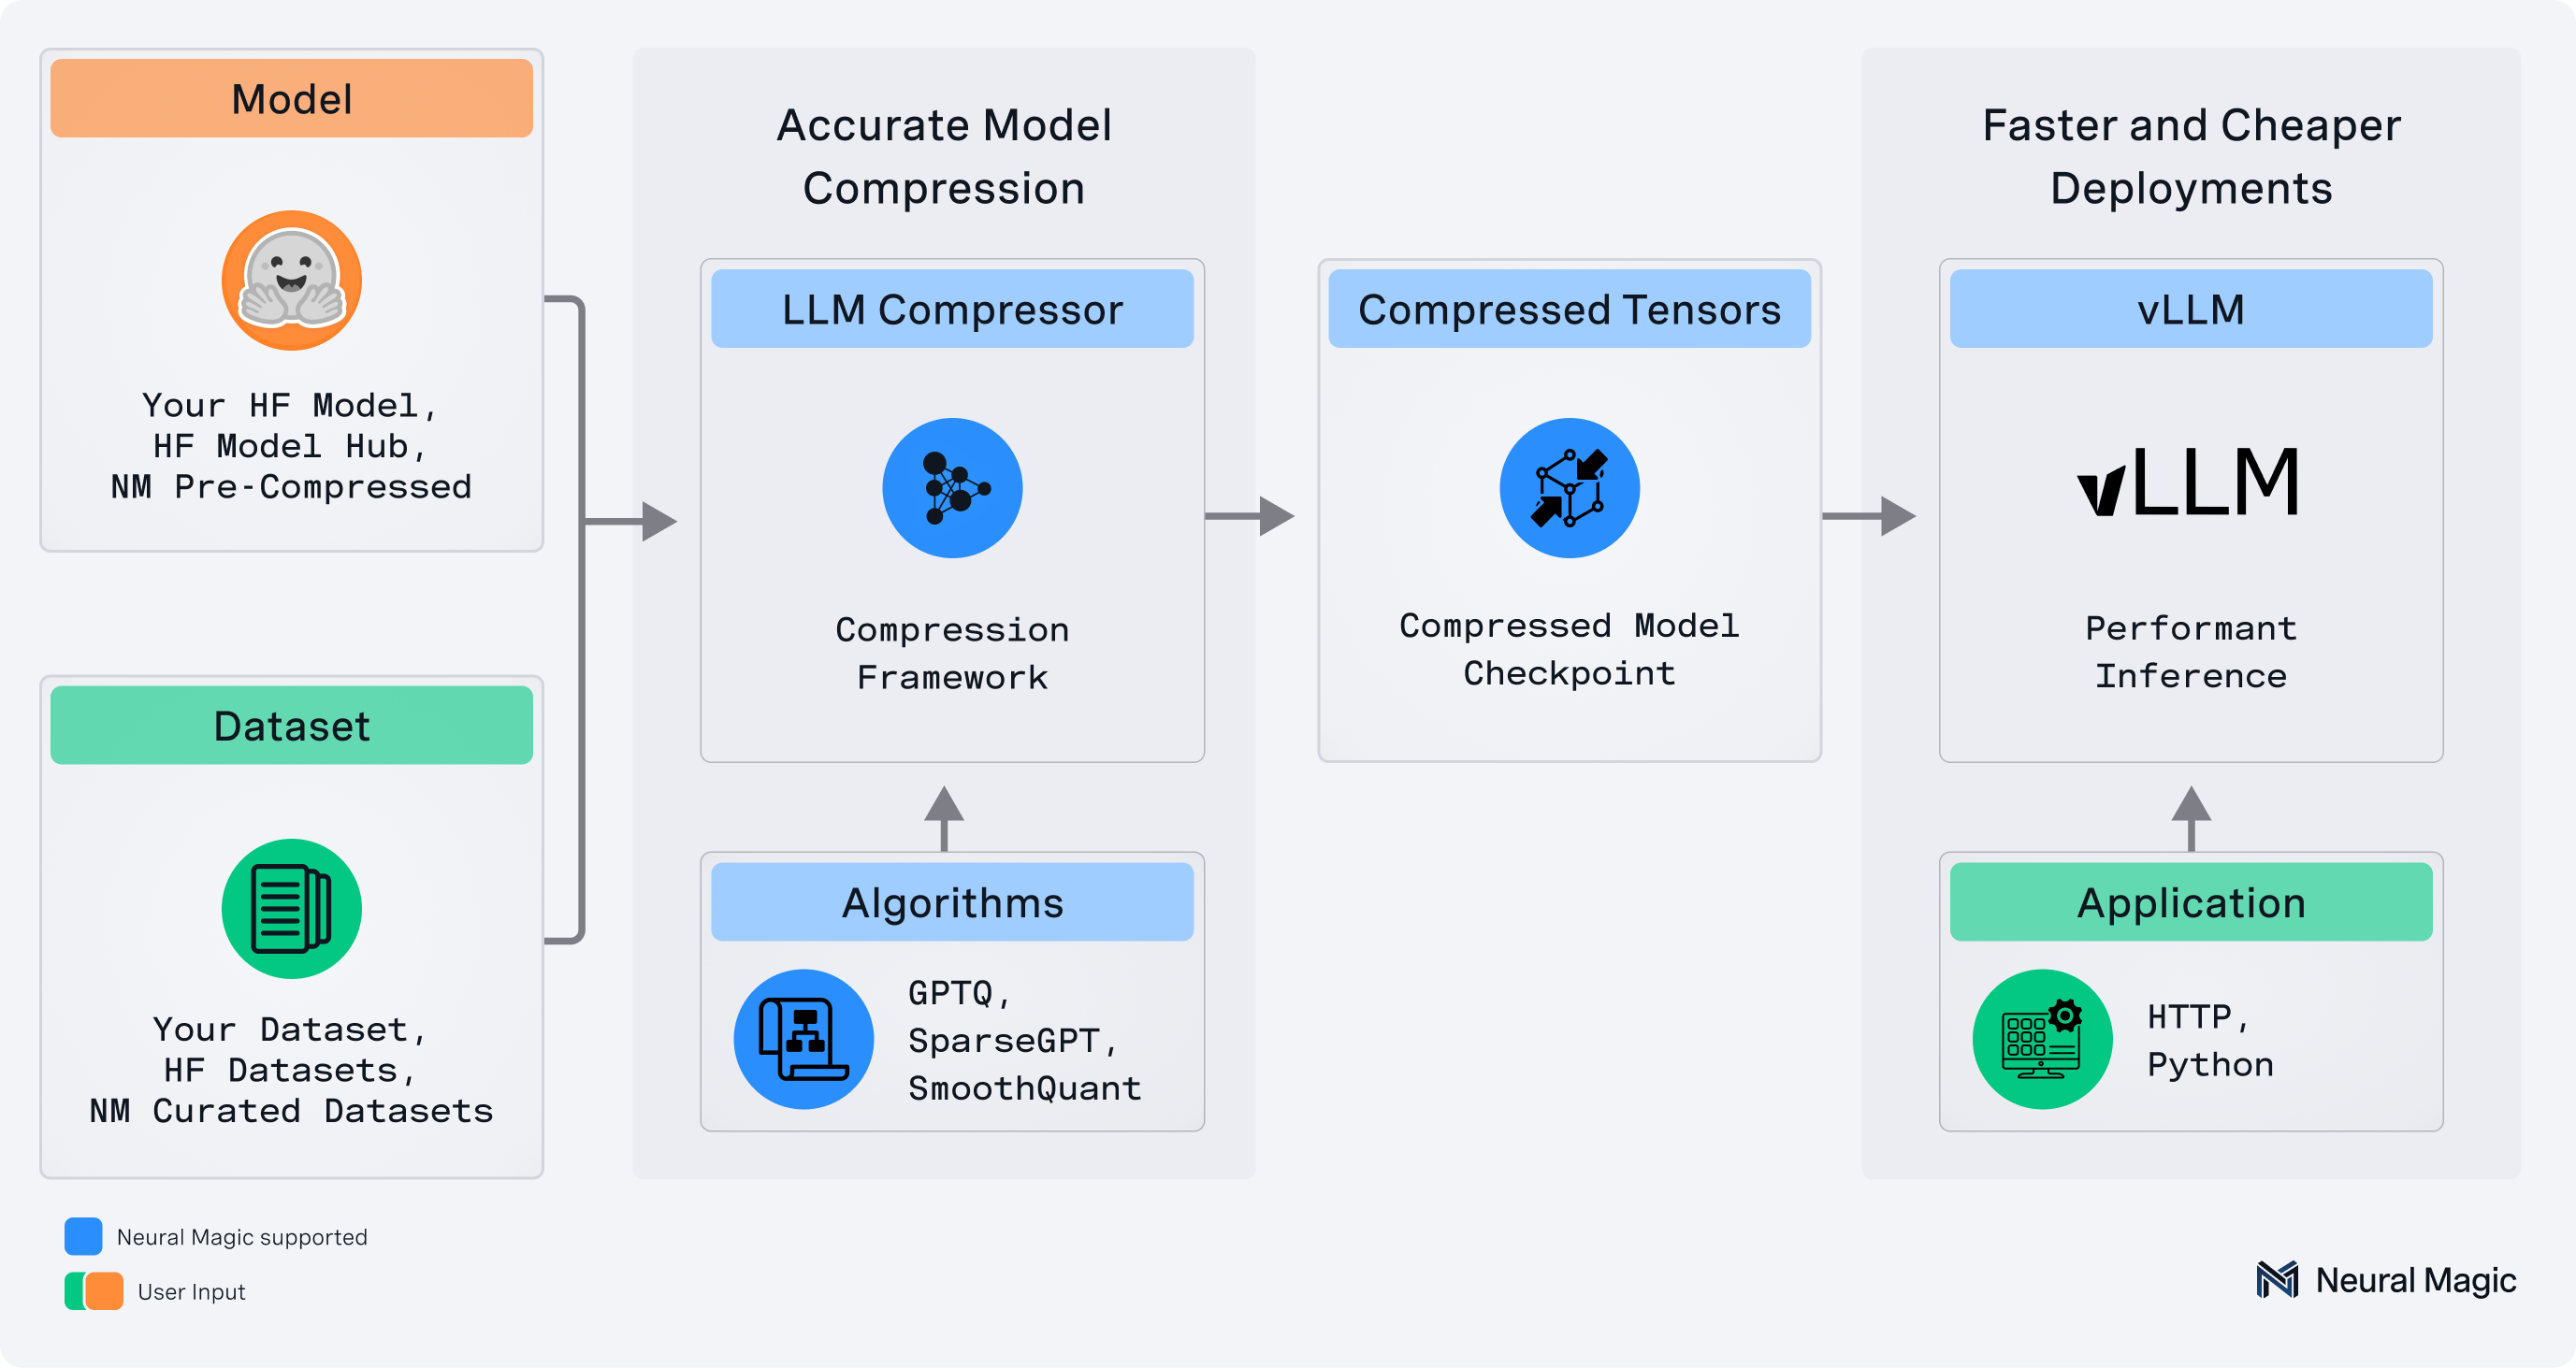
llmcompressor is an easy-to-use library for optimizing models for deployment with vllm, including:
- Comprehensive set of quantization algorithms for weight-only and activation quantization
- Seamless integration with Hugging Face models and repositories
safetensors-based file format compatible withvllm- Large model support via
accelerate
✨ Read the announcement blog here! ✨
Supported Formats
- Activation Quantization: W8A8 (int8 and fp8)
- Mixed Precision: W4A16, W8A16
- 2:4 Semi-structured and Unstructured Sparsity
Supported Algorithms
- Simple PTQ
- GPTQ
- SmoothQuant
- SparseGPT
Installation
pip install llmcompressor
Get Started
End-to-End Examples
Applying quantization with llmcompressor:
- Activation quantization to
int8 - Activation quantization to
fp8 - Weight only quantization to
int4 - Quantizing MoE LLMs
- Quantizing Vision-Language Models
- Quantizing Audio-Language Models
User Guides
Deep dives into advanced usage of llmcompressor:
Quick Tour
Let's quantize TinyLlama with 8 bit weights and activations using the GPTQ and SmoothQuant algorithms.
Note that the model can be swapped for a local or remote HF-compatible checkpoint and the recipe may be changed to target different quantization algorithms or formats.
Apply Quantization
Quantization is applied by selecting an algorithm and calling the oneshot API.
from llmcompressor.modifiers.smoothquant import SmoothQuantModifier
from llmcompressor.modifiers.quantization import GPTQModifier
from llmcompressor.transformers import oneshot

# Select quantization algorithm. In this case, we:
#   * apply SmoothQuant to make the activations easier to quantize
#   * quantize the weights to int8 with GPTQ (static per channel)
#   * quantize the activations to int8 (dynamic per token)
recipe = [
    SmoothQuantModifier(smoothing_strength=0.8),
    GPTQModifier(scheme="W8A8", targets="Linear", ignore=["lm_head"]),
]

# Apply quantization using the built in open_platypus dataset.
#   * See examples for demos showing how to pass a custom calibration set
oneshot(
    model="TinyLlama/TinyLlama-1.1B-Chat-v1.0",
    dataset="open_platypus",
    recipe=recipe,
    output_dir="TinyLlama-1.1B-Chat-v1.0-INT8",
    max_seq_length=2048,
    num_calibration_samples=512,
)
Inference with vLLM
The checkpoints created by llmcompressor can be loaded and run in vllm:
Install:
pip install vllm
Run:
from vllm import LLM
model = LLM("TinyLlama-1.1B-Chat-v1.0-INT8")
output = model.generate("My name is")
Questions / Contribution
- If you have any questions or requests open an issue and we will add an example or documentation.
- We appreciate contributions to the code, examples, integrations, and documentation as well as bug reports and feature requests! Learn how here.
1 maintainer

Metadata
1 maintainer
Release files for llmcompressor-nightly 0.4.1.20250220
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| llmcompressor-nightly-0.4.1.20250220.tar.gz | 194.0 kB | Without provenance | Details for llmcompressor-nightly-0.4.1.20250220.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| llmcompressor_nightly-0.4.1.20250220-py3-none-any.whl | Python 3 | none | any | Details for llmcompressor_nightly-0.4.1.20250220-py3-none-any.whl |
Total release size: 449.3 kB
Release files / llmcompressor-nightly-0.4.1.20250220.tar.gz
| Download URL | llmcompressor-nightly-0.4.1.20250220.tar.gz |
|---|---|
| Size | 194.0 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
8534bf68fc3270a3f0b7888b521fe88538cef0d89ae4dd41e41c868bd24d084c
|
|
BLAKE2b-256 checksum How to use checksums |
2092e44a1354698018d692d66fbeae44be2f7c5b87176c68b2f85f19161dead8
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.1.0 CPython/3.10.12
|
Release files / llmcompressor_nightly-0.4.1.20250220-py3-none-any.whl
| Download URL | llmcompressor_nightly-0.4.1.20250220-py3-none-any.whl |
|---|---|
| Size | 255.3 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
681141c0481525c70a008082c5dbcce3a58b11d5b506f51d41ce9784a681695e
|
|
BLAKE2b-256 checksum How to use checksums |
fa90e29f16d7452290470ca3cfc8e704d11f7f89f8580dad40b828cdf94c9db7
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.1.0 CPython/3.10.12
|
Security for llmcompressor-nightly 0.4.1.20250220
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














