
lobstrio
Command-line interface for the Lobstr.io scraping API







Run web scrapers, manage squids, download results — all from your terminal.
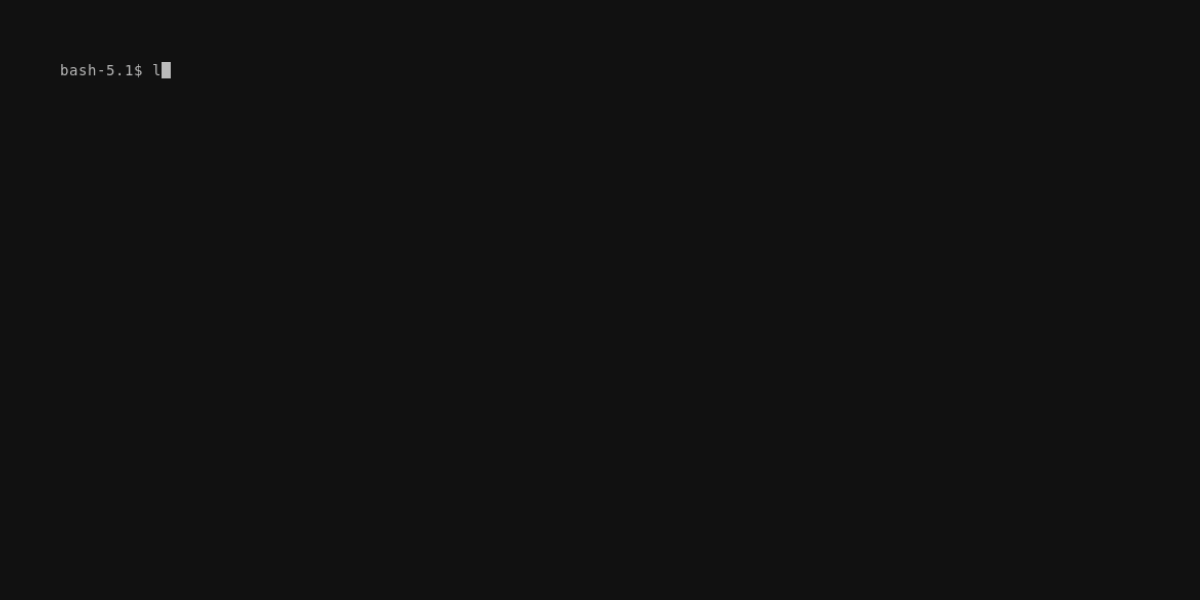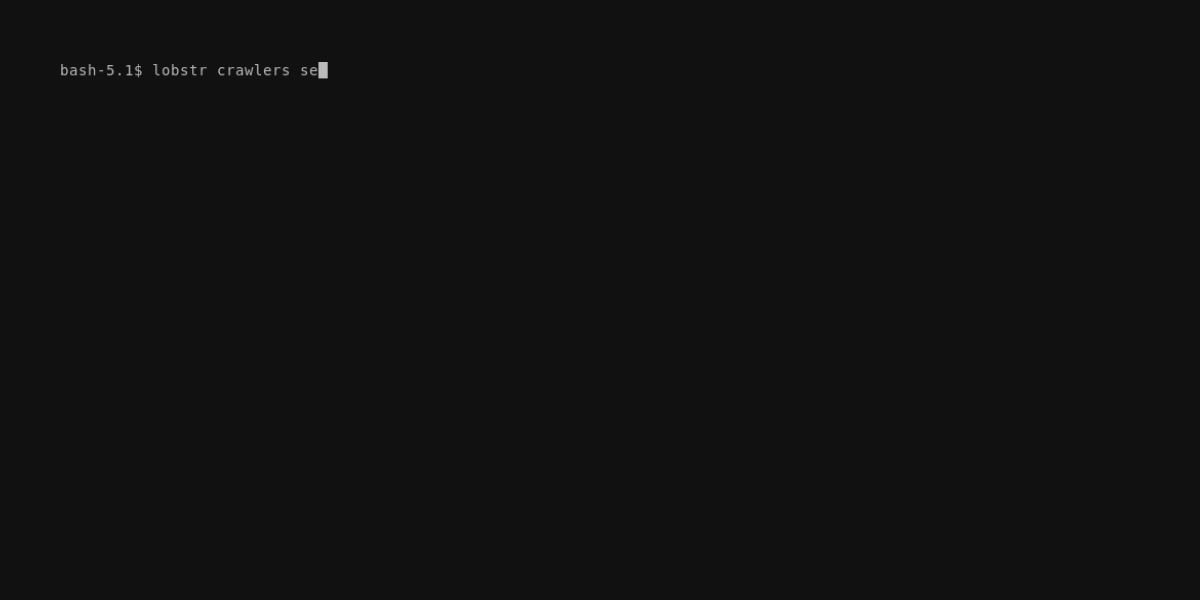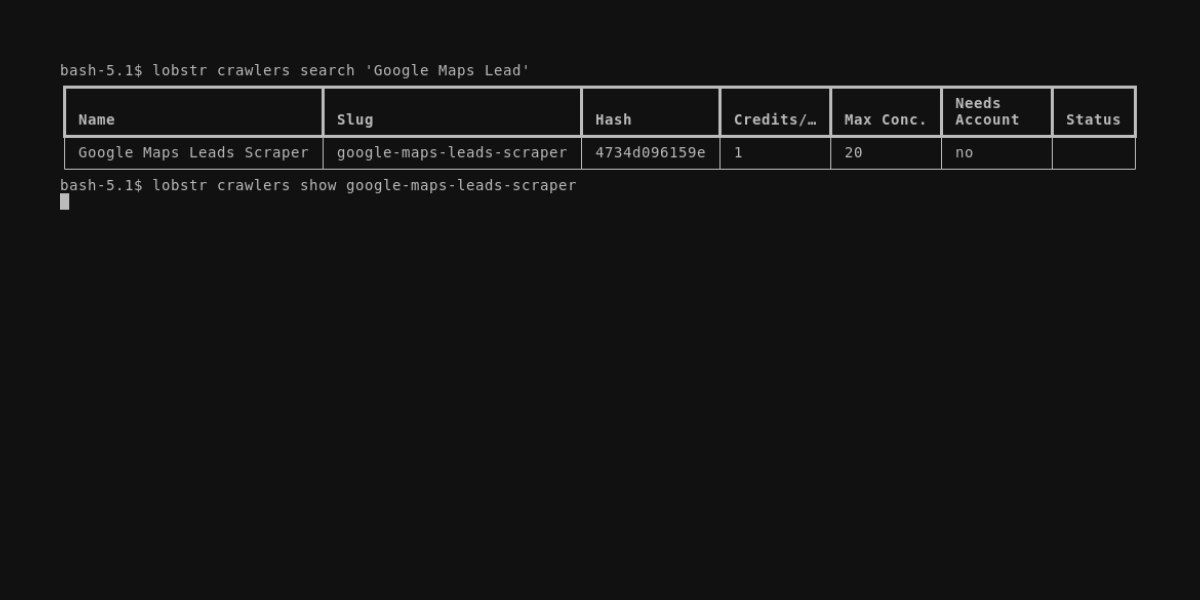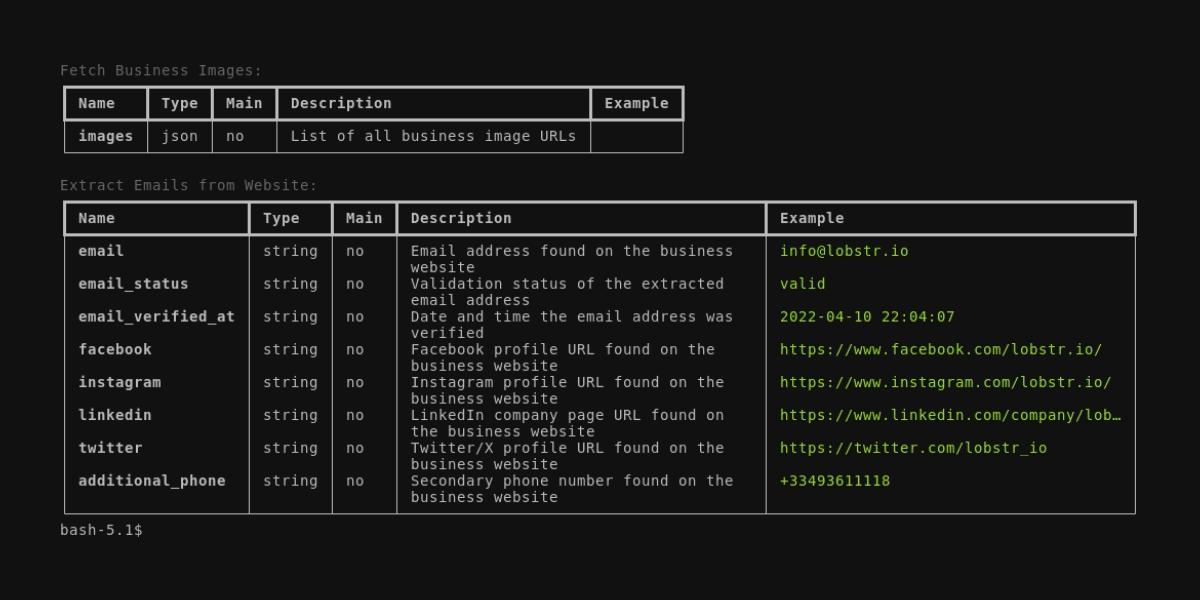
Demo
Installation
pip install lobstrio
Requires Python 3.10+.
Quick start
# Save your API token (find it at https://app.lobstr.io/dashboard/api)
lobstr config set-token YOUR_TOKEN

# One-command scrape: create squid, add tasks, run, download
lobstr go google-maps-leads-scraper "https://maps.google.com/maps/place/..." -o leads.csv

# Multiple URLs
lobstr go google-maps-leads-scraper url1 url2 url3 -o results.csv

# From a file
lobstr go google-maps-leads-scraper --file urls.txt -o results.csv
Commands
Account & config
lobstr whoami                          # Show account info and balance
lobstr config set-token TOKEN          # Save API token
lobstr config show                     # Show current config
lobstr config set-alias maps SQUID     # Create alias for a squid
Crawlers — browse the scraper catalog
lobstr crawlers ls                                   # List all available crawlers
lobstr crawlers show google-maps-leads-scraper       # Show crawler details
lobstr crawlers search "Google Maps"                 # Search by name
lobstr crawlers params google-maps-leads-scraper     # Show crawler parameters
lobstr crawlers attrs google-maps-leads-scraper      # Show result attributes
ls, show, and search show which account type a crawler needs (e.g.
sales-nav-sync) in the "Needs Account" column, instead of a plain yes/no —
that's the value to pass --account's matching account for. --json output
is unaffected.
Squids — manage scraper instances
lobstr squid create google-maps-leads-scraper --name "My Scraper"
lobstr squid ls                        # List your squids
lobstr squid show SQUID                # Show details
lobstr squid update SQUID --concurrency 5 --param max_results=200

# Link an account (crawlers that need one, e.g. sales-navigator-leads-scraper).
# Merged into whatever the squid already has by default — the API's `accounts`
# field is full-replace, so a naive call would detach anything already linked:
lobstr squid update SQUID --account jane@example.com
# Replace the whole account list instead of merging (empty = detach all):
lobstr squid update SQUID --replace-accounts --account jane@example.com

lobstr squid empty SQUID               # Remove all tasks
lobstr squid rm SQUID --force          # Delete squid
squid create has no --account — the API doesn't accept accounts at
creation, only on squid update. lobstr go on an account-backed crawler
handles this for you (see below): create, then link, in one command.
Tasks — manage input URLs and keywords
lobstr task add SQUID url1 url2        # Add tasks
lobstr task add SQUID "pizza" --key keyword  # Keyword-based crawlers
lobstr task ls SQUID                   # List tasks
lobstr task show FULL_TASK_HASH        # Show task details
lobstr task rm FULL_TASK_HASH          # Delete task
lobstr task upload SQUID tasks.csv     # Bulk upload from CSV
lobstr task upload-status UPLOAD_ID    # Check upload progress
Runs — start, monitor, and download
lobstr run start SQUID                 # Start a run
lobstr run start SQUID --wait          # Start and wait for completion
lobstr run start SQUID --download results.csv  # Start, wait, download
lobstr run ls SQUID                    # List runs
lobstr run show FULL_RUN_HASH          # Show run details
lobstr run stats FULL_RUN_HASH         # Show run statistics
lobstr run tasks FULL_RUN_HASH         # List tasks in a run
lobstr run watch FULL_RUN_HASH         # Live progress bar
lobstr run abort FULL_RUN_HASH         # Stop a run
lobstr run download FULL_RUN_HASH      # Download results CSV
Results — fetch scraped data
lobstr results get SQUID               # Fetch results (JSON)
lobstr results get SQUID --format csv  # Fetch as CSV
lobstr results get SQUID -o data.json  # Save to file
Accounts — manage connected platform accounts
lobstr accounts ls                     # List all accounts
lobstr accounts show ACCOUNT           # Show account details
lobstr accounts types                  # List available account types
lobstr accounts sync --type google --cookies-file cookies.json  # Sync account
lobstr accounts sync-status SYNC_ID    # Check sync progress
lobstr accounts update ACCOUNT --param daily_limit=100
lobstr accounts rm ACCOUNT --force     # Delete account
Delivery — configure result delivery
lobstr delivery email SQUID --email you@example.com
lobstr delivery googlesheet SQUID --url "https://docs.google.com/..."
lobstr delivery s3 SQUID --bucket my-bucket --target-path scrapes/
lobstr delivery webhook SQUID --url "https://your-server.com/hook"
lobstr delivery sftp SQUID --host ftp.example.com --username user --password pass

# Test connectivity
lobstr delivery test-email --email you@example.com
lobstr delivery test-s3 --bucket my-bucket
Go — full workflow in one command
# Basic usage
lobstr go google-maps-leads-scraper "https://maps.google.com/..." -o results.csv

# Keyword-based crawler
lobstr go google-search-scraper "pizza delivery" --key keyword

# With crawler parameters
lobstr go google-maps-leads-scraper url1 --param max_results=200 --param language=English

# Set concurrency
lobstr go google-maps-leads-scraper url1 --concurrency 3

# Start without waiting for download
lobstr go google-maps-leads-scraper url1 --no-download

# Reuse existing squid by name
lobstr go google-maps-leads-scraper url1 --name "My Leads"

# Clear old tasks when reusing squid
lobstr go google-maps-leads-scraper url1 --name "My Leads" --empty

# Delete squid after completion
lobstr go google-maps-leads-scraper url1 --delete

# Custom output file
lobstr go google-maps-leads-scraper url1 -o my_leads.csv

# Crawlers that need a synced account (e.g. LinkedIn, Sales Navigator):
# auto-picks the one healthy account of the right type if there's exactly one
lobstr go sales-navigator-leads-scraper "https://linkedin.com/..."

# ...or name it explicitly (needed when you have more than one candidate)
lobstr go sales-navigator-leads-scraper "https://linkedin.com/..." --account jane@example.com
For an account-backed crawler, go links an account automatically: exactly
one healthy account of the crawler's account type (not its name — two
LinkedIn crawlers can need different types) is picked for you; zero or
several fail with a message telling you what to do, and pass --account to
pick one yourself. A reused squid (--name) that already has an account
attached is left alone — go never auto-picks onto it.
Global flags
| Flag | Description |
|---|---|
--json |
Output raw JSON (for piping/scripting) |
--quiet |
Suppress non-essential output |
--verbose |
Show HTTP request details |
--token TOKEN |
Override API token for this command |
--version |
Show version |
Aliases
Create shortcuts for frequently used squids:
lobstr config set-alias maps abc123def456...
lobstr task ls @maps
lobstr run start @maps
Identifier resolution
| Resource | Resolution order | Example |
|---|---|---|
| Crawlers | Hash prefix → Slug (exact/prefix) → Name (exact/substring) | google-maps, 4734d096, "Google Maps" |
| Squids | @alias → Hash prefix → Name (exact/substring) |
@maps, abc1, "My Scraper" |
| Accounts | Hash prefix → Username (exact/substring) | f9a2, "john@gmail.com" |
| Runs & Tasks | Full 32-character hash only | a1b2c3d4e5f6... |
Configuration
Config is stored at ~/.config/lobstr/config.toml. The API token can also be set via the LOBSTR_TOKEN environment variable.
CLI vs SDK
CLI (pip install lobstrio) |
SDK (pip install lobstrio-sdk) |
|
|---|---|---|
| Use case | Terminal workflows, quick scrapes, cron jobs | Scripts, pipelines, applications |
| Interface | Shell commands | Python API |
| Output | Rich tables, progress bars, CSV files | Typed dataclass models |
| Async | No | Yes (AsyncLobstrClient) |
| Pagination | Manual (--page, --limit) |
Auto (client.squids.iter()) |
For programmatic access, see lobstrio-sdk.
FAQ
Where do I get an API token?
Go to Dashboard → API to find your token. It's always available there, pre-generated.
How do I use keyword-based crawlers?
Some crawlers accept keywords, or a field other than url, instead of a URL.
go defaults --key from the crawler's own declared task params: the one
param when it declares exactly one, url when it declares several including
url, and url when it declares none. When it declares several and none of
them is url, go won't guess — it names the choices and asks you to pass
one:
lobstr go google-search-scraper "pizza delivery" --key keyword
--key always overrides the default when you pass it. Use
lobstr crawlers params <crawler> to see what parameters a crawler accepts.
Can I use short hashes for runs and tasks?
No. Run and task endpoints require the full 32-character hash. Use lobstr run ls SQUID or lobstr task ls SQUID to see full hashes. Crawlers and squids support prefix matching.
How do I pipe results to other tools?
Use --json for machine-readable output:
lobstr --json results get SQUID | jq '.[].email'
lobstr --json crawlers ls | jq '.[] | .name'
Can I run scrapes in the background?
Yes. Use --no-download with go, or start a run without --wait:
lobstr go google-maps-leads-scraper urls.txt --no-download
lobstr run start SQUID  # returns immediately
lobstr run watch RUN_HASH  # check progress later
Releasing
Publishing to PyPI (the lobstrio package) is triggered by a GitHub Release,
not by merging to main. Merging alone does not publish. To cut a release:
- Bump
versioninpyproject.toml(e.g.0.5.1). - Add a matching entry to
CHANGELOG.md. - Merge to
main(via PR; CI must be green). - Create a GitHub Release tagged
vX.Y.Zonmain:gh release create v0.5.1 --target main --title "v0.5.1" --notes "…"
Creating the release fires .github/workflows/publish.yml (on: release: published),
which builds with uv and publishes to PyPI using the PYPI_TOKEN repo secret.
Confirm it went out: pip index versions lobstrio (or check the PyPI page).
Note: a PyPI version cannot be overwritten — bump the version for every release.
Contributing
Contributions are welcome! See CONTRIBUTING.md for development setup, code style, and versioning guidelines.
Changelog
See CHANGELOG.md for release history.
License
1 maintainer

Metadata
1 maintainer
Release files for lobstrio 0.7.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| lobstrio-0.7.1.tar.gz | 591.4 kB | Without provenance | Details for lobstrio-0.7.1.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| lobstrio-0.7.1-py3-none-any.whl | Python 3 | none | any | Details for lobstrio-0.7.1-py3-none-any.whl |
Total release size: 630.6 kB
Release files / lobstrio-0.7.1.tar.gz
| Download URL | lobstrio-0.7.1.tar.gz |
|---|---|
| Size | 591.4 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
a417f3d03ac38a480f7803d1f4a340dd22978ebcc61e071474488c86d83555c0
|
|
BLAKE2b-256 checksum How to use checksums |
8defa13822acf12f7792c2a7acde9b084b8321059af7f7c3464359337f2e8f0a
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
uv/0.12.15 {"installer":{"name":"uv","version":"0.12.15","subcommand":["publish"]},"python":null,"implementation":{"name":null,"version":null},"distro":{"name":"Ubuntu","version":"24.04","id":"noble","libc":null},"system":{"name":null,"release":null},"cpu":null,"openssl_version":null,"setuptools_version":null,"rustc_version":null,"ci":true}
|
Release files / lobstrio-0.7.1-py3-none-any.whl
| Download URL | lobstrio-0.7.1-py3-none-any.whl |
|---|---|
| Size | 39.2 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
8788834fecf57650e8a354f08cabe04b73eebce6f44eed85c01913f593dee2bc
|
|
BLAKE2b-256 checksum How to use checksums |
c33c5701870db7085975c0db1579d763a35c3b0aee21a636d9558b5e26196062
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
uv/0.12.15 {"installer":{"name":"uv","version":"0.12.15","subcommand":["publish"]},"python":null,"implementation":{"name":null,"version":null},"distro":{"name":"Ubuntu","version":"24.04","id":"noble","libc":null},"system":{"name":null,"release":null},"cpu":null,"openssl_version":null,"setuptools_version":null,"rustc_version":null,"ci":true}
|
Security for lobstrio 0.7.1
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














