
London's rental bicycle network usage
15-minute snapshots of every docking station in London's cycle hire scheme, collected from the TfL BikePoint API since 2022-04-29.
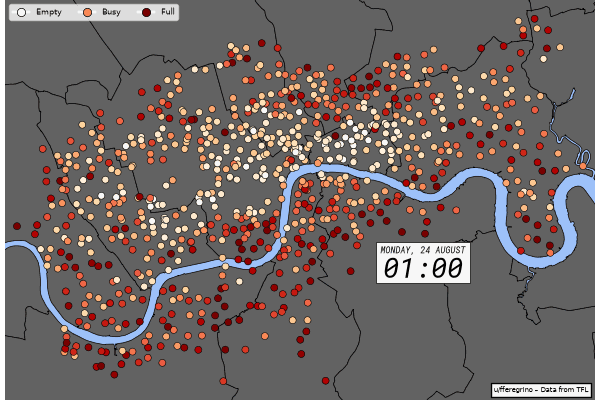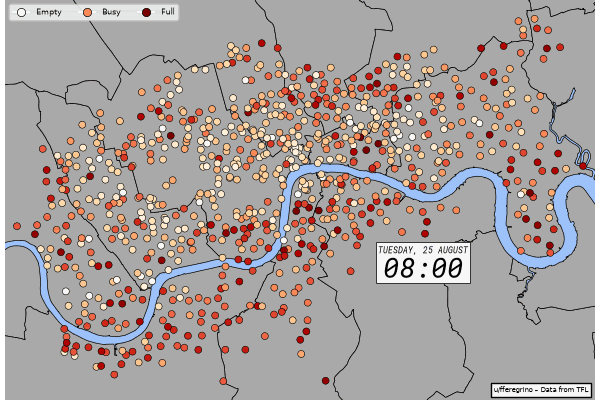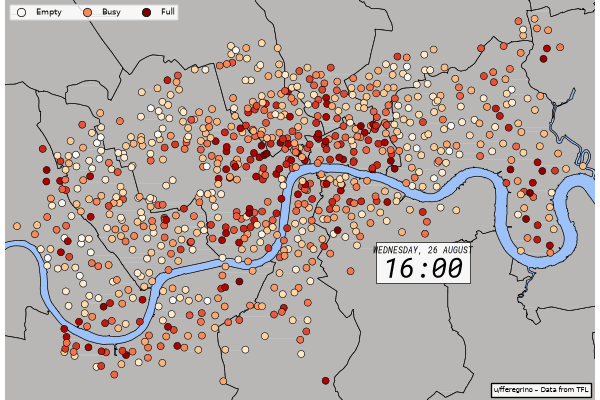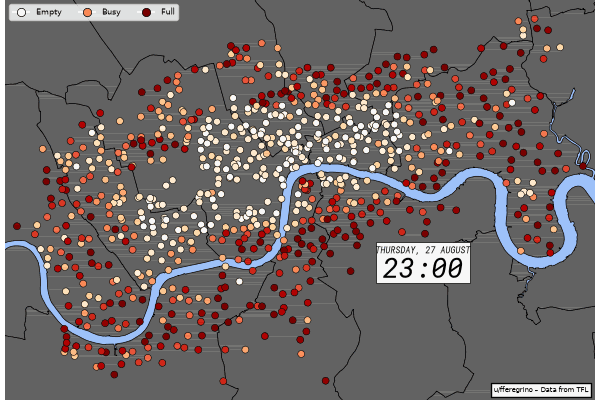
Data is published to the Hugging Face Hub: feregrino/london-cycles. This repository holds the reader package, the collection code, and the station reference table; it does not hold the observations.
Reading the data
pip install london-cycles
Only huggingface_hub is required. Set HF_TOKEN if you point repo_id= at a private fork; the cycles dataset itself is public.
from london_cycles import stream, stations, jitter_events

for event in stream(start="2023-07-01", end="2023-07-02"):
    print(event)  # {'place_id': 'BikePoints_1', 'query_time': ..., 'bikes': 12, ...}
Streaming a range
The full history runs to hundreds of millions of rows, so stream takes inclusive day bounds and fetches one file at a time rather than snapshotting the repo. Files arrive in chronological order and are cached under HF_HOME, so a re-run reads from disk. Bounds select whole days; they do not trim rows inside a day.
list_files(start="2023-07-01", end="2023-07-31")  # what would be read
stream(loop=True)  # replay forever, for a demo feed
stream_local("./mirror")  # a local copy of the same layout
Station attributes
stations() returns one row per station per version, oldest first, valid over [valid_from, valid_to); see stations.csv below for the columns. Resolving a fact row to its coordinates is an as-of join on query_time against that interval.
stations() # [{'place_id': 'BikePoints_14', 'valid_from': '2022-04-29', 'valid_to': '2023-07-18', ...}]
Jitter
Every station in a poll is stamped with the same query_time, to the second, which makes event-time windows degenerate — each one holds a single instant. jitter_events nudges each row forward by up to spread seconds, derived from a hash of (seed, place_id, query_time):
jitter_events(stream(start="2023-07-01"), spread=45.0)
The offset is reproducible (a pure function of the row, so a second reader sees the same instants) and forward-only, so as long as spread stays under the 15-minute polling interval, event time still advances across the replay. Downstream watermark tolerance has to be at least spread. Pass spread=0 to replay the stored timestamps verbatim.
Layout
data/year=YYYY/month=MM/day=DD/part.csv     one row per station per snapshot
stations.csv                                versioned station attributes
During the current day you will also see HHMMSS.csv files in that day's directory, one per 15-minute run. A nightly job merges them into part.csv.
Fact rows
| column | type | description |
|---|---|---|
query_time |
naive UTC timestamp, whole seconds | when the API was queried; identical across all rows of one snapshot |
place_id |
string | station identifier, e.g. BikePoints_1; joins to stations.csv |
bikes |
integer | bikes available |
empty_docks |
integer | free docks |
docks |
integer | total docks |
Rows carry no coordinates. lat/lon are station attributes rather than measurements, and repeating them on every row was about 40% of the compressed dataset. They live in stations.csv.
stations.csv
One row per station per version of its attributes, valid over [valid_from, valid_to). An empty valid_to means "still current" (it reads as NULL in DuckDB, pandas, and friends).
| column | description |
|---|---|
place_id |
joins to the fact rows |
common_name |
human-readable station name |
lat, lon |
position during this version's interval |
terminal_name |
TfL terminal identifier |
installed, temporary |
TfL status flags |
install_date, removal_date |
UTC dates (YYYY-MM-DD), or empty |
valid_from, valid_to |
UTC dates bounding this version |
The table is versioned because station attributes are not static. Over 2022-2026: 34 stations changed coordinates (relocations of up to ~82 m), 31 were renamed, and the set of live stations churned by several dozen. A current-state table would mislocate the movers and would have no row at all for retired stations, making years of their observations unjoinable.
Joining
Pick the version of each place_id whose interval contains the row's query_time:
SELECT f.query_time, f.place_id, s.common_name, s.lat, s.lon,
       f.bikes, f.empty_docks, f.docks
FROM read_csv_auto('data/**/part.csv', hive_partitioning = true) AS f
JOIN read_csv_auto('stations.csv') AS s
  ON s.place_id = f.place_id
 AND s.valid_from <= CAST(f.query_time AS DATE)
 AND (s.valid_to IS NULL OR CAST(f.query_time AS DATE) < s.valid_to)
Joining on place_id alone will multiply rows for the ~100 stations that have more than one version.
Known data quirks
These are artifacts of the upstream API, kept documented rather than silently patched:
- Coordinates of
0,0. TfL has reported null-island coordinates for a station (BikePoints_852, 2022). These never open a new version; the last known good position is carried forward instead. - One-hour shifts in
install_date/removal_date. TfL reports these as epoch milliseconds and shifts them by exactly 3,600,000 ms across British Summer Time boundaries — every observed change to these fields was ±1 hour. They are reduced to UTC dates, which absorbs the shift except for a handful of values that sit near midnight. - Two positions in one day. During a relocation TfL may report both the old and new position on the same day (
BikePoints_244, 2025-04-15, 299 m apart). Day-granularity versioning records the majority position, so a small number of observations resolve to the stable location rather than the transient one. - Gaps. Snapshots are taken every 15 minutes, but the count per day varies and you should never assume a fixed cadence. Collection runs on GitHub Actions, whose
scheduleevents are best-effort: delayed triggers are dropped rather than backfilled. Asking for 96 triggers a day yielded about 26, so the job is now triggered hourly and takes four snapshots per run, which needs GitHub to honour one trigger an hour instead of four. Historic coverage is worse than current: 2022-2024 averaged ~85-95 snapshots/day, 2025 ~65, and early 2026 fell as low as ~16/day before the collection job was repaired. lockedis not recorded. It is live dock status rather than a station attribute, and flips constantly (32,794 changes across the history, against 34 for coordinates). It was excluded rather than pollute the version table.
Collecting the data
The london_cycles package above reads the archive; london_cycles_db writes it. The repository is a uv workspace so the two stay separate distributions — the collector lives in collector/, is never published, and its TfL dependency never reaches anyone installing the reader.
| module | role |
|---|---|
london_cycles_db.dataset |
polls TfL and publishes one snapshot |
london_cycles_db.compact |
merges a day's snapshots into part.csv |
london_cycles_db.stations |
maintains the versioned station table |
london_cycles_db.hf_publish |
wraps the Hub commits |
london_cycles_db.backfill |
one-off migration of the original git-stored CSVs |
Visualization lives in viz/.
uv sync --all-packages

export HF_TOKEN=...                          # write access to the dataset repo
export HF_DATASET_REPO=feregrino/london-cycles

uv run -m london_cycles_db.dataset                             # publish one snapshot
uv run -m london_cycles_db.compact 2026-08-25                  # merge a day's snapshots
uv run -m london_cycles_db.backfill --dry-run --out /tmp/out   # migrate historical CSVs, locally
To run the visualization animation:
uv run --group viz viz/animate.py
Development
make fmt     # ruff format + ruff check --fix
make lint    # check without writing
make test    # pytest over tests/ (the Hub is stubbed, nothing reaches the network)
uv build produces the reader alone; london_cycles_db is excluded by construction, since it is a separate project under collector/.
Licence
Data: CC-BY-SA 3.0, per TfL's terms. Powered by TfL Open Data. Contains OS data © Crown copyright and database rights 2016.
1 maintainer

Metadata
1 maintainer
Release files for london-cycles 0.1.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| london_cycles-0.1.0.tar.gz | 16.5 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| london_cycles-0.1.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 29.0 kB
Release files / london_cycles-0.1.0.tar.gz
| Download URL | london_cycles-0.1.0.tar.gz |
|---|---|
| Size | 16.5 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
4032762e0b39a6772b2b232688613fcb2b713d4d4f87f239fd69e3bb92f17c8d
|
|
BLAKE2b-256 checksum How to use checksums |
092e8f7b3a031792d1b638f70018b0cff1e49187249f3cb52283c1e1995a4f06
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
uv/0.12.7 {"installer":{"name":"uv","version":"0.12.7","subcommand":["publish"]},"python":null,"implementation":{"name":null,"version":null},"distro":{"name":"Ubuntu","version":"24.04","id":"noble","libc":null},"system":{"name":null,"release":null},"cpu":null,"openssl_version":null,"setuptools_version":null,"rustc_version":null,"ci":true}
|
Release files / london_cycles-0.1.0-py3-none-any.whl
| Download URL | london_cycles-0.1.0-py3-none-any.whl |
|---|---|
| Size | 12.5 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
6e3bb9cf29102da83d83cadf5effe6f726c13faa63834e7c8c81e7590a8c9bf0
|
|
BLAKE2b-256 checksum How to use checksums |
355bd35d533d3414b19a6a27204b75bd632e10e74bb6869b3301b9a052a0d7cc
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
uv/0.12.7 {"installer":{"name":"uv","version":"0.12.7","subcommand":["publish"]},"python":null,"implementation":{"name":null,"version":null},"distro":{"name":"Ubuntu","version":"24.04","id":"noble","libc":null},"system":{"name":null,"release":null},"cpu":null,"openssl_version":null,"setuptools_version":null,"rustc_version":null,"ci":true}
|













