
Sub-second RAG regression testing for production pipelines



Quick Start • Documentation • Python API • CI/CD
Overview
"Did my last commit break retrieval?" — now you know in seconds.
LongProbe is a sub-second RAG regression harness. Define your Golden Questions once, run longprobe check on every commit, and get an exact diff of which document chunks were lost in your latest change — before your users notice.
Think pytest --watch for your RAG pipeline.
🎬 Demos
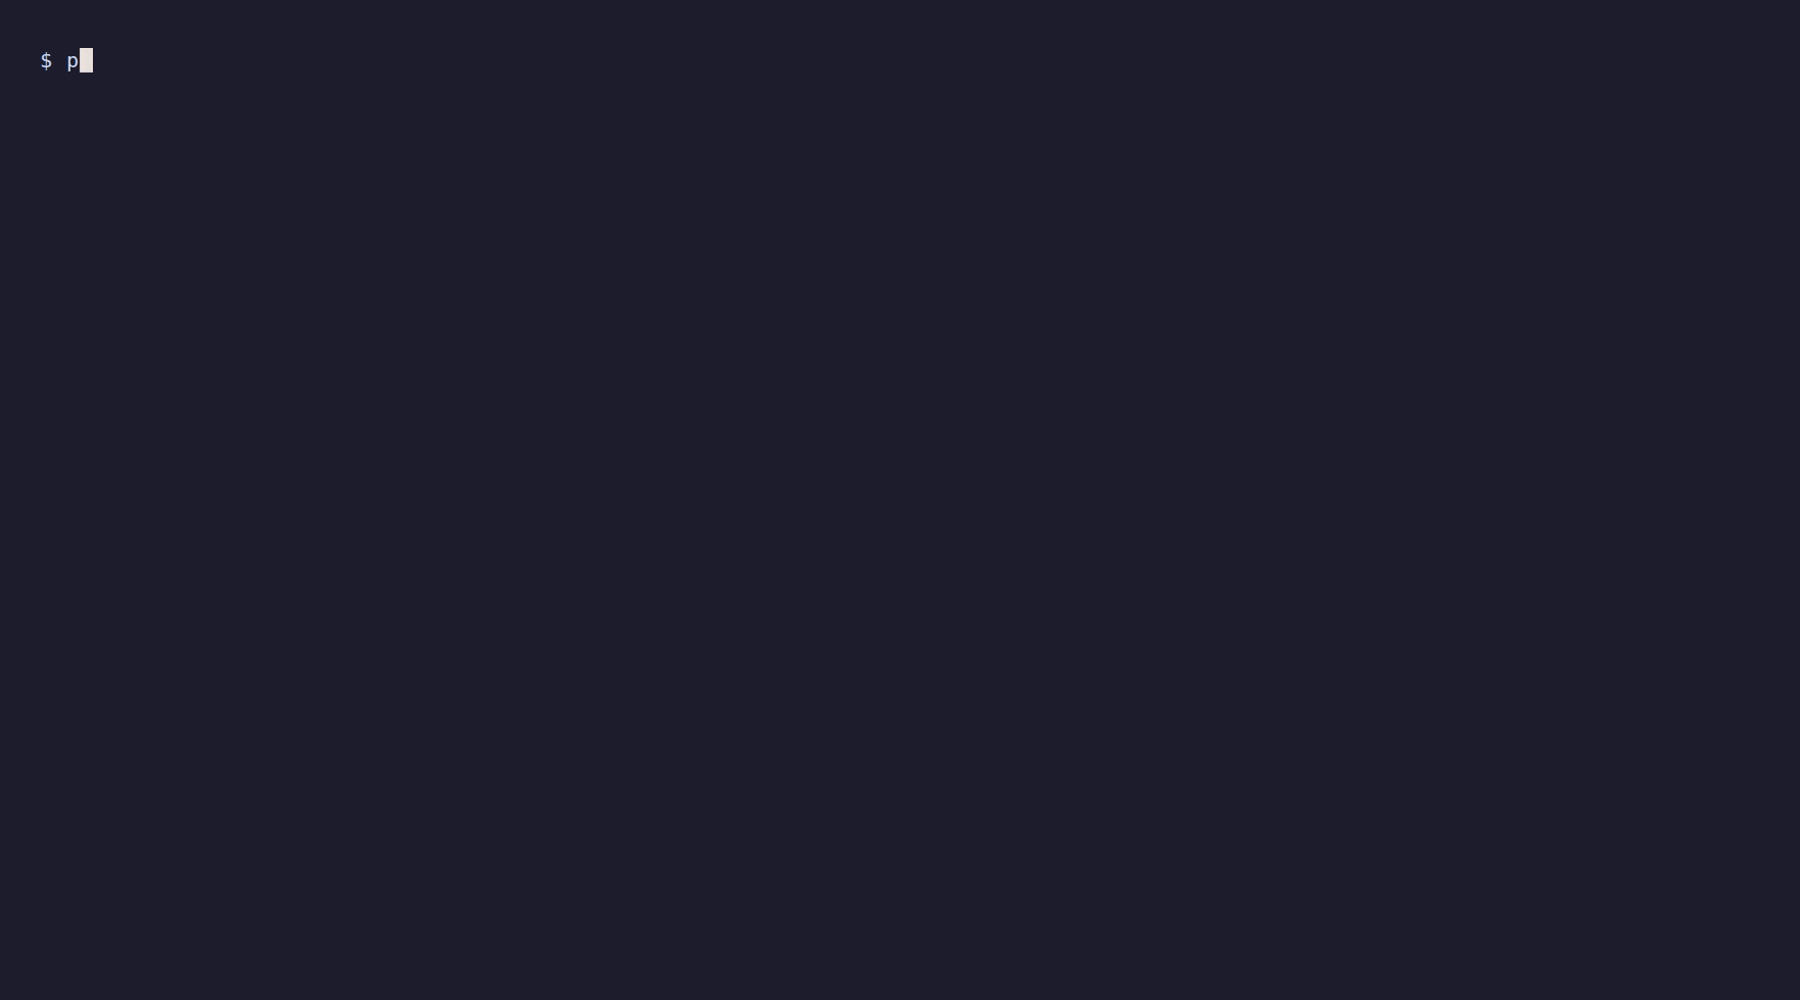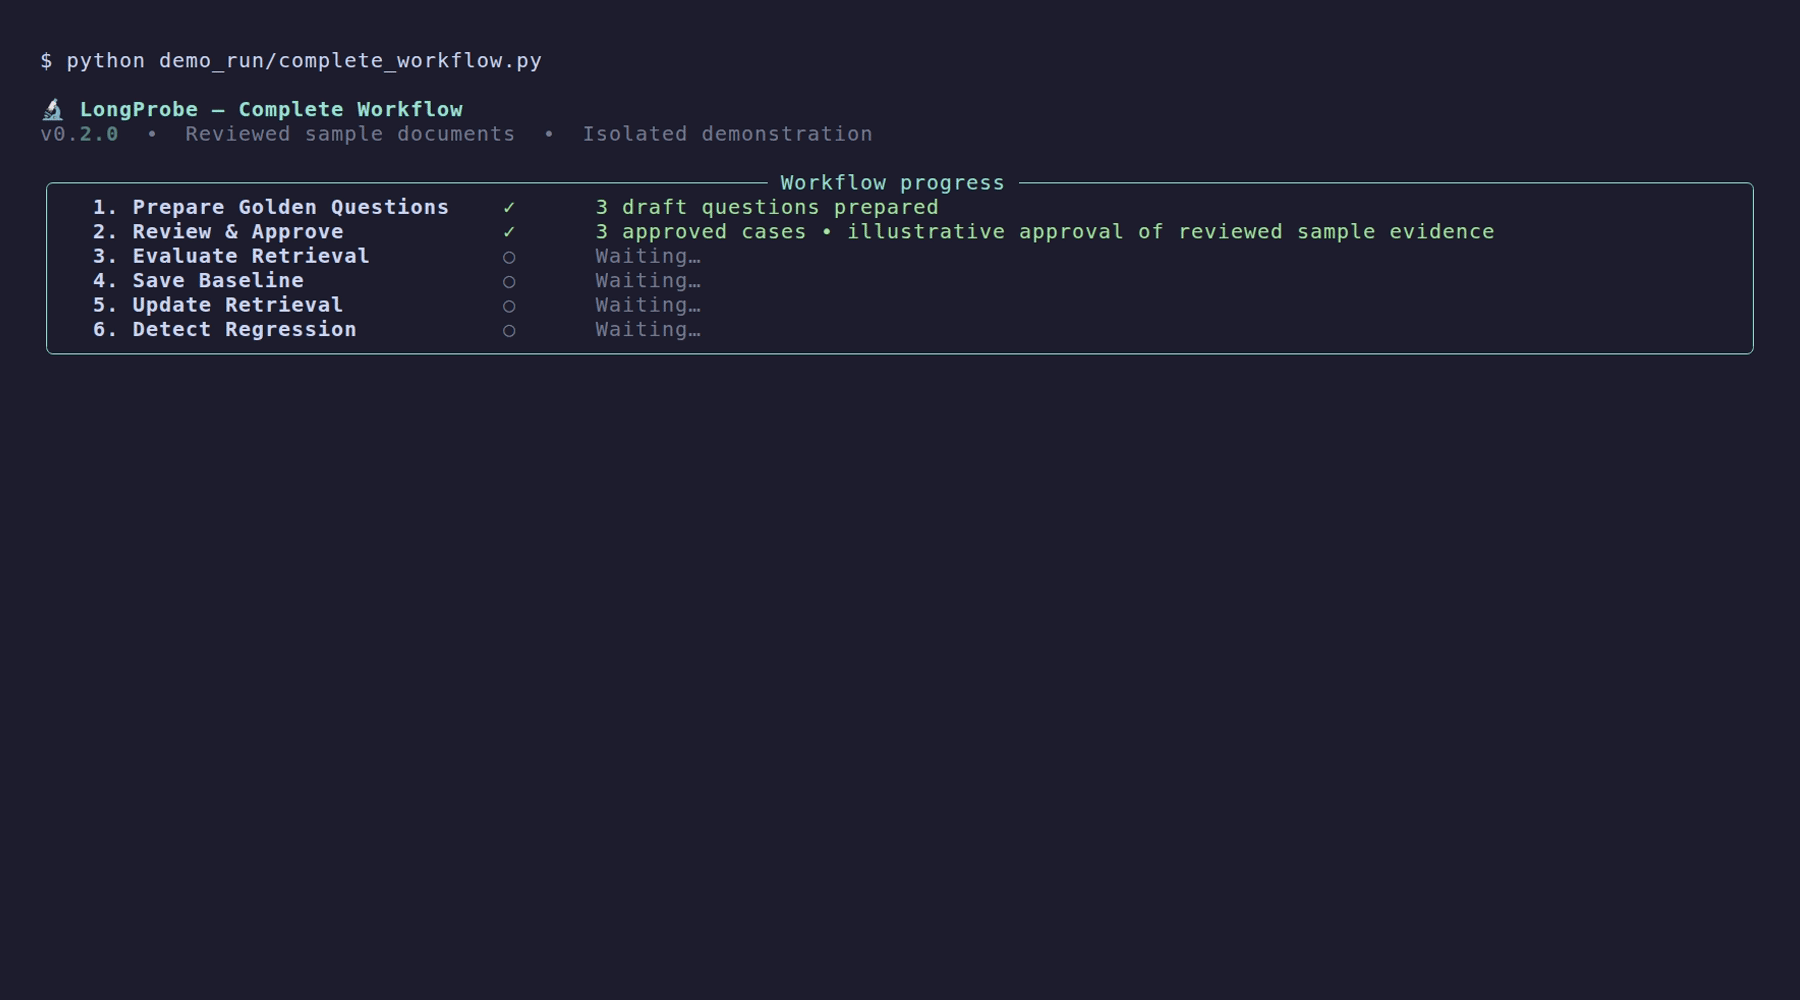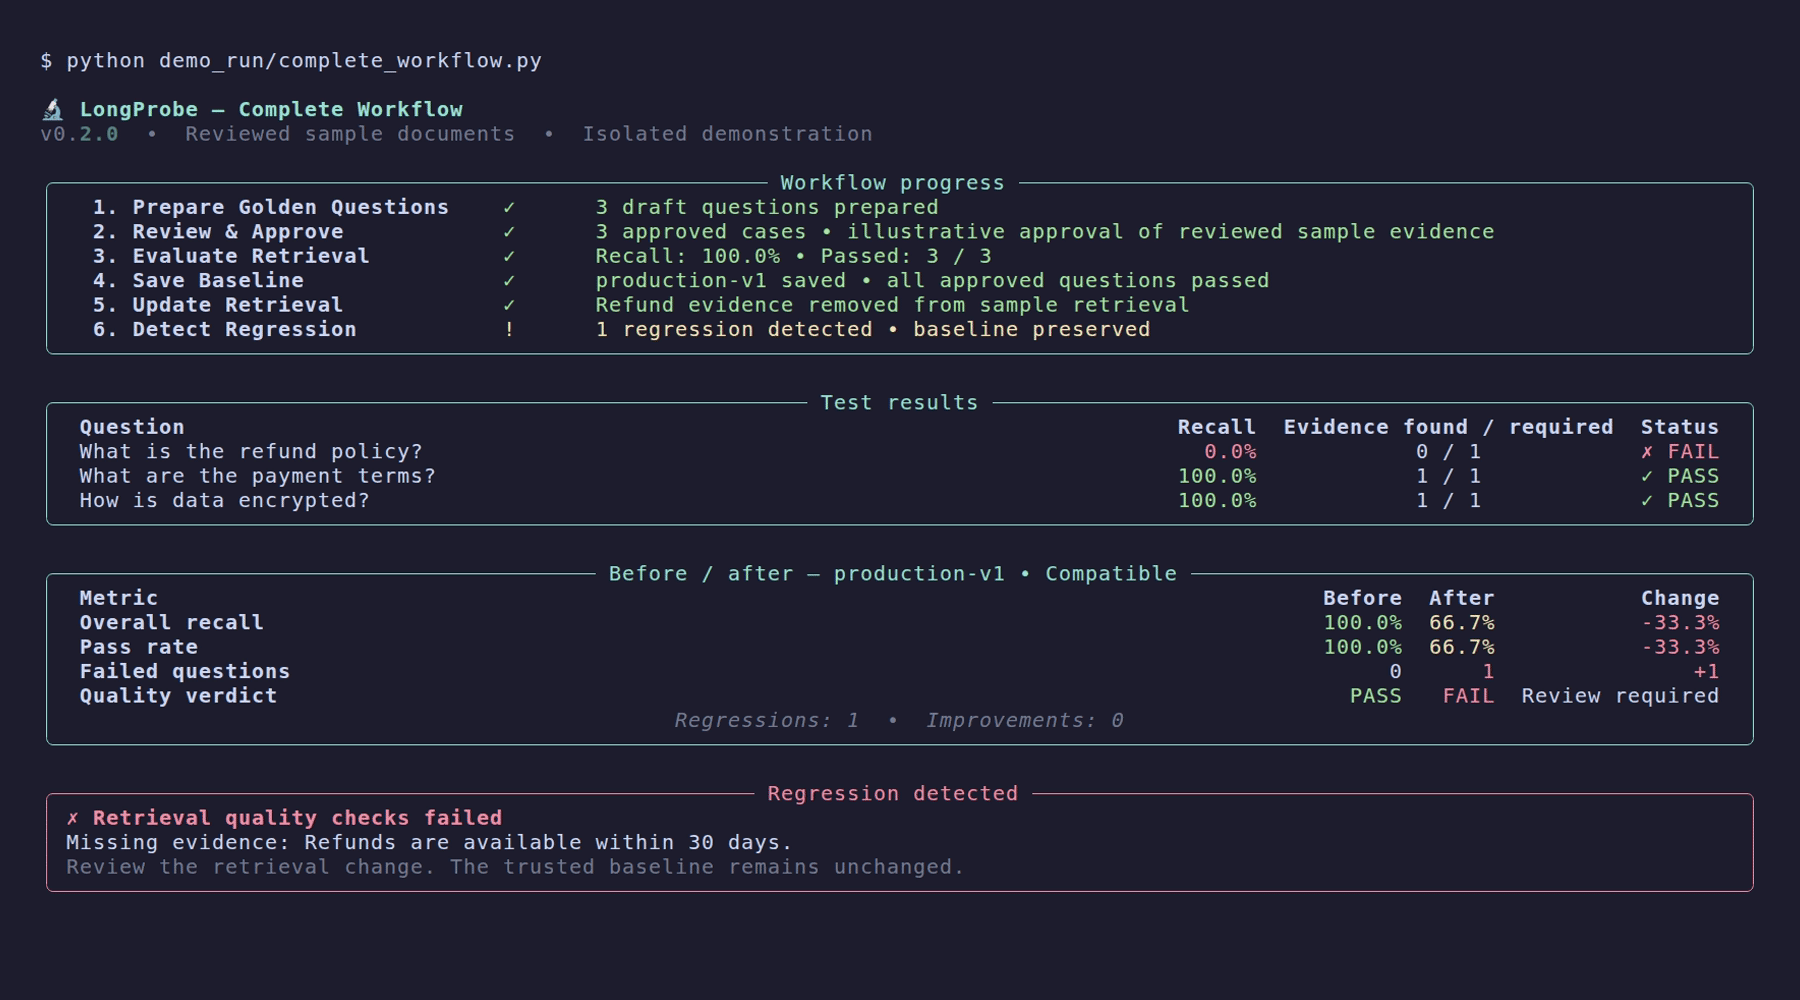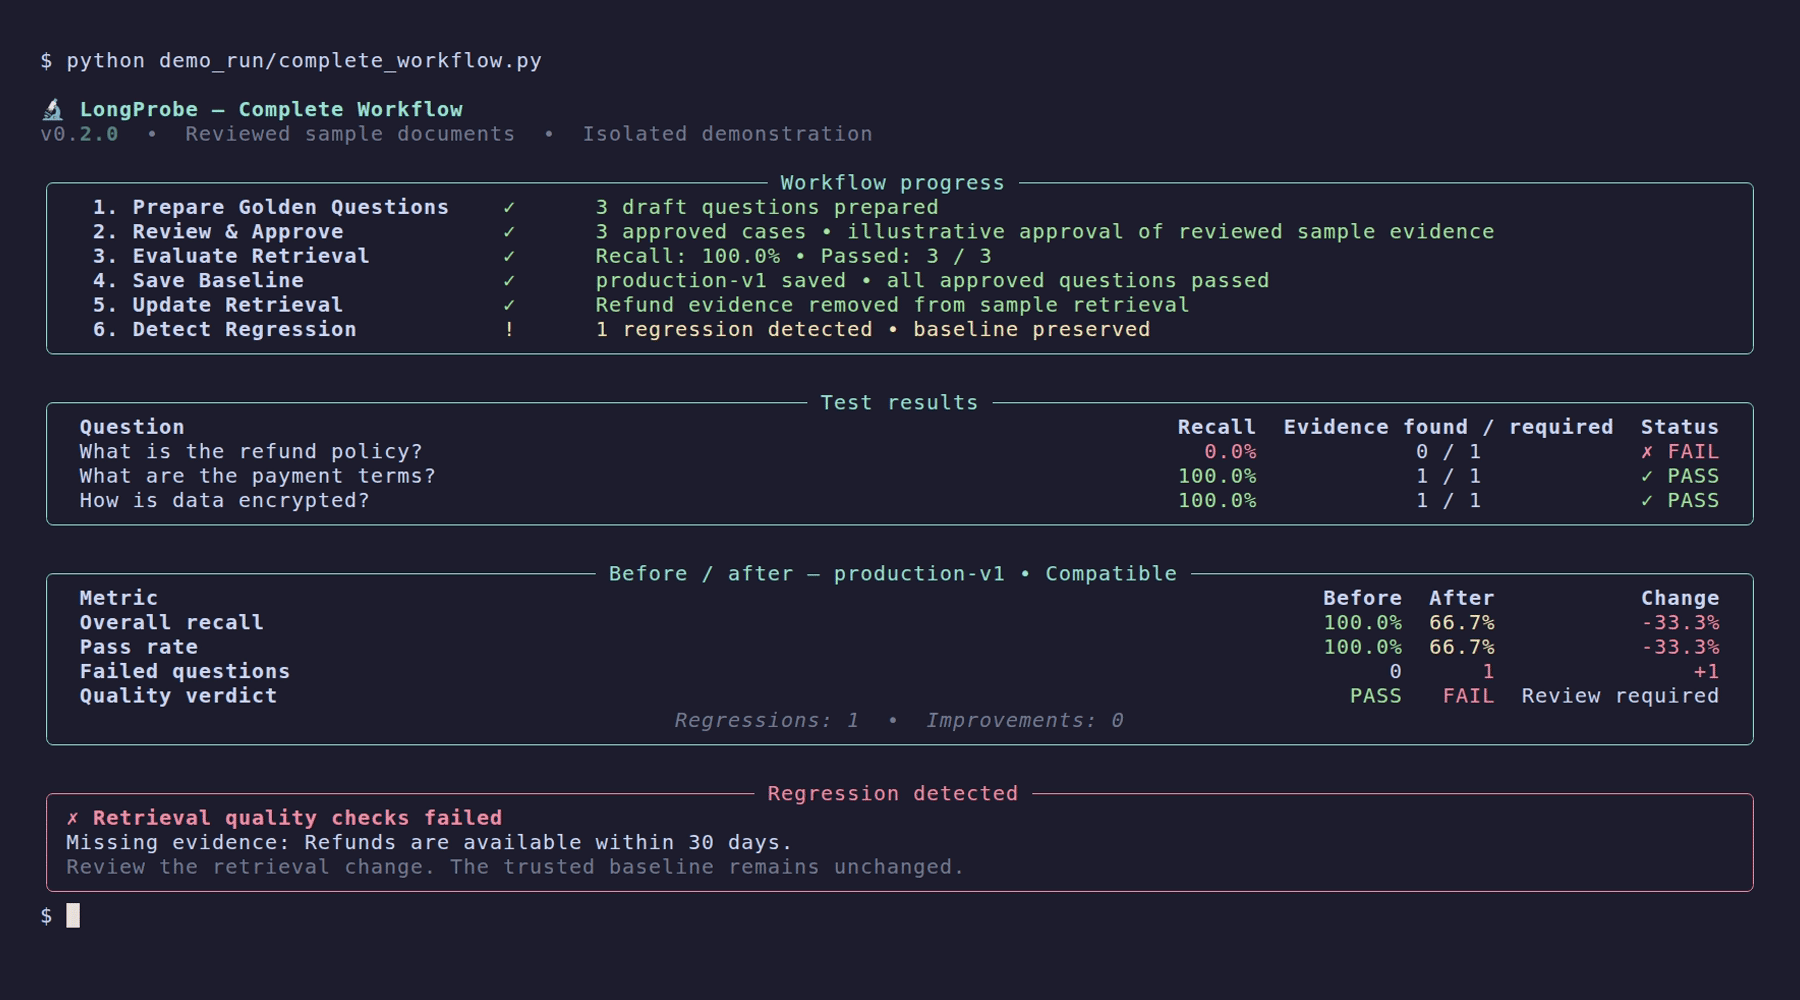
Complete Workflow
Review golden evidence, save a trusted baseline, and detect missing evidence with a Before / After / Change results table.
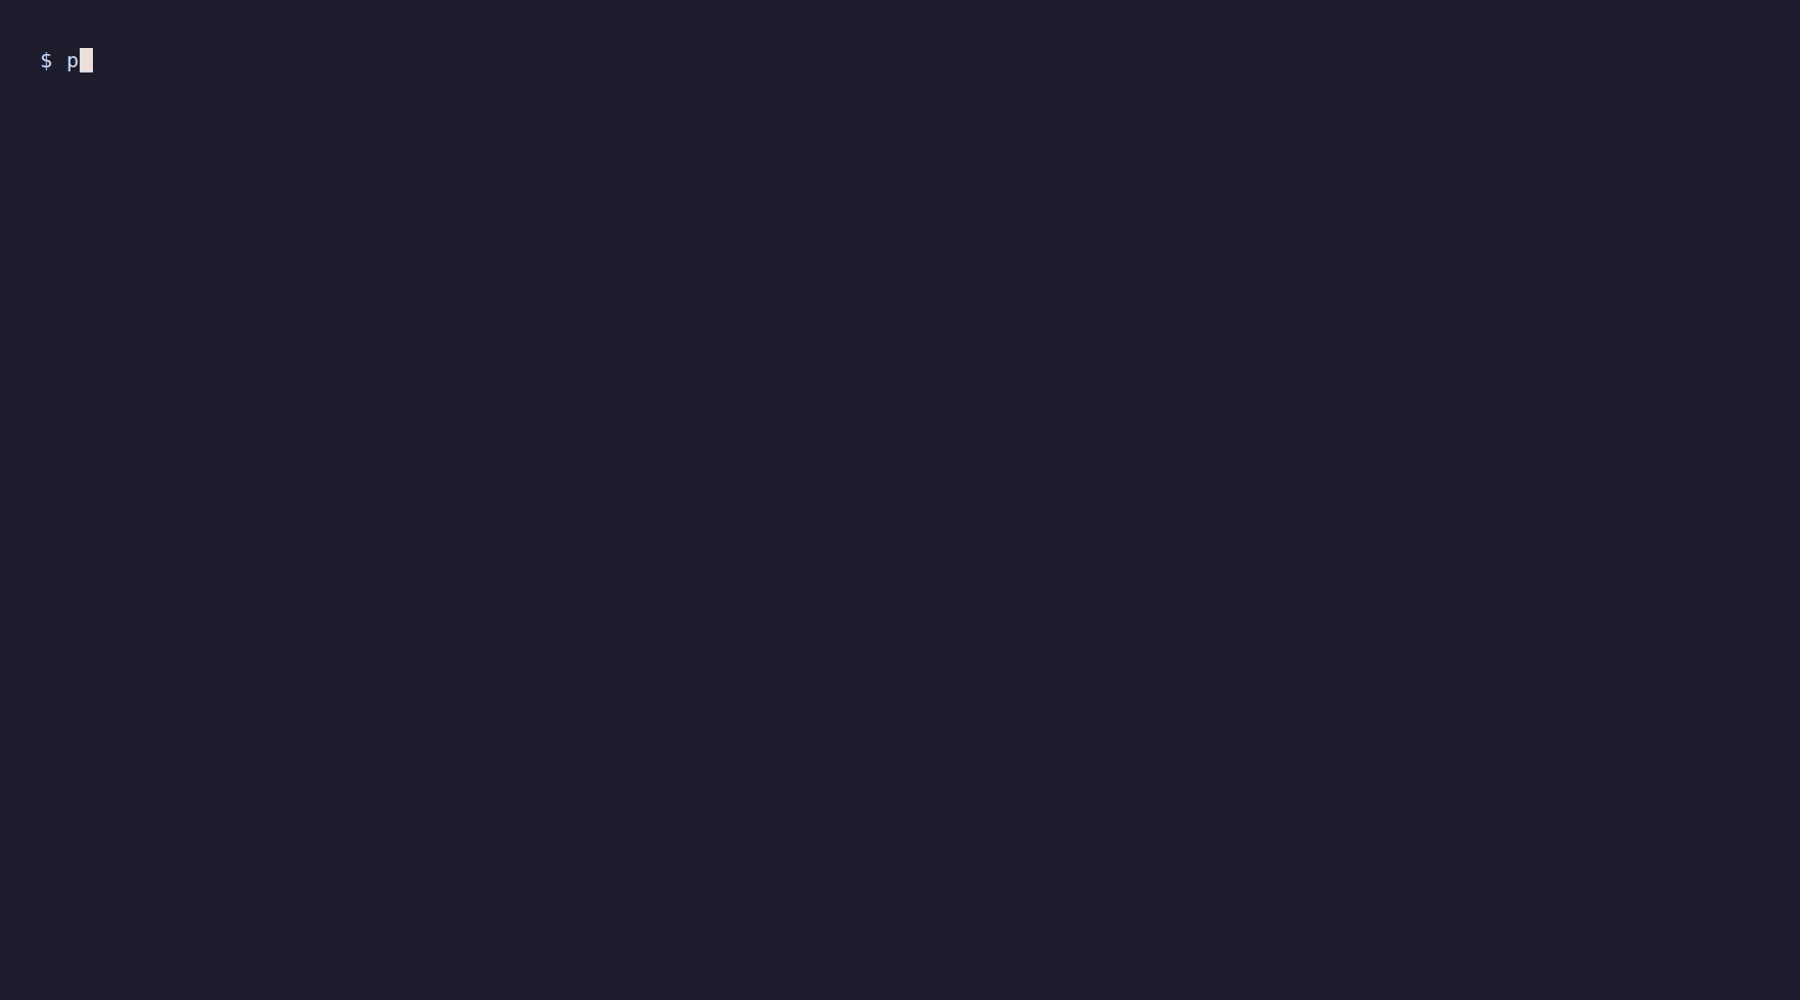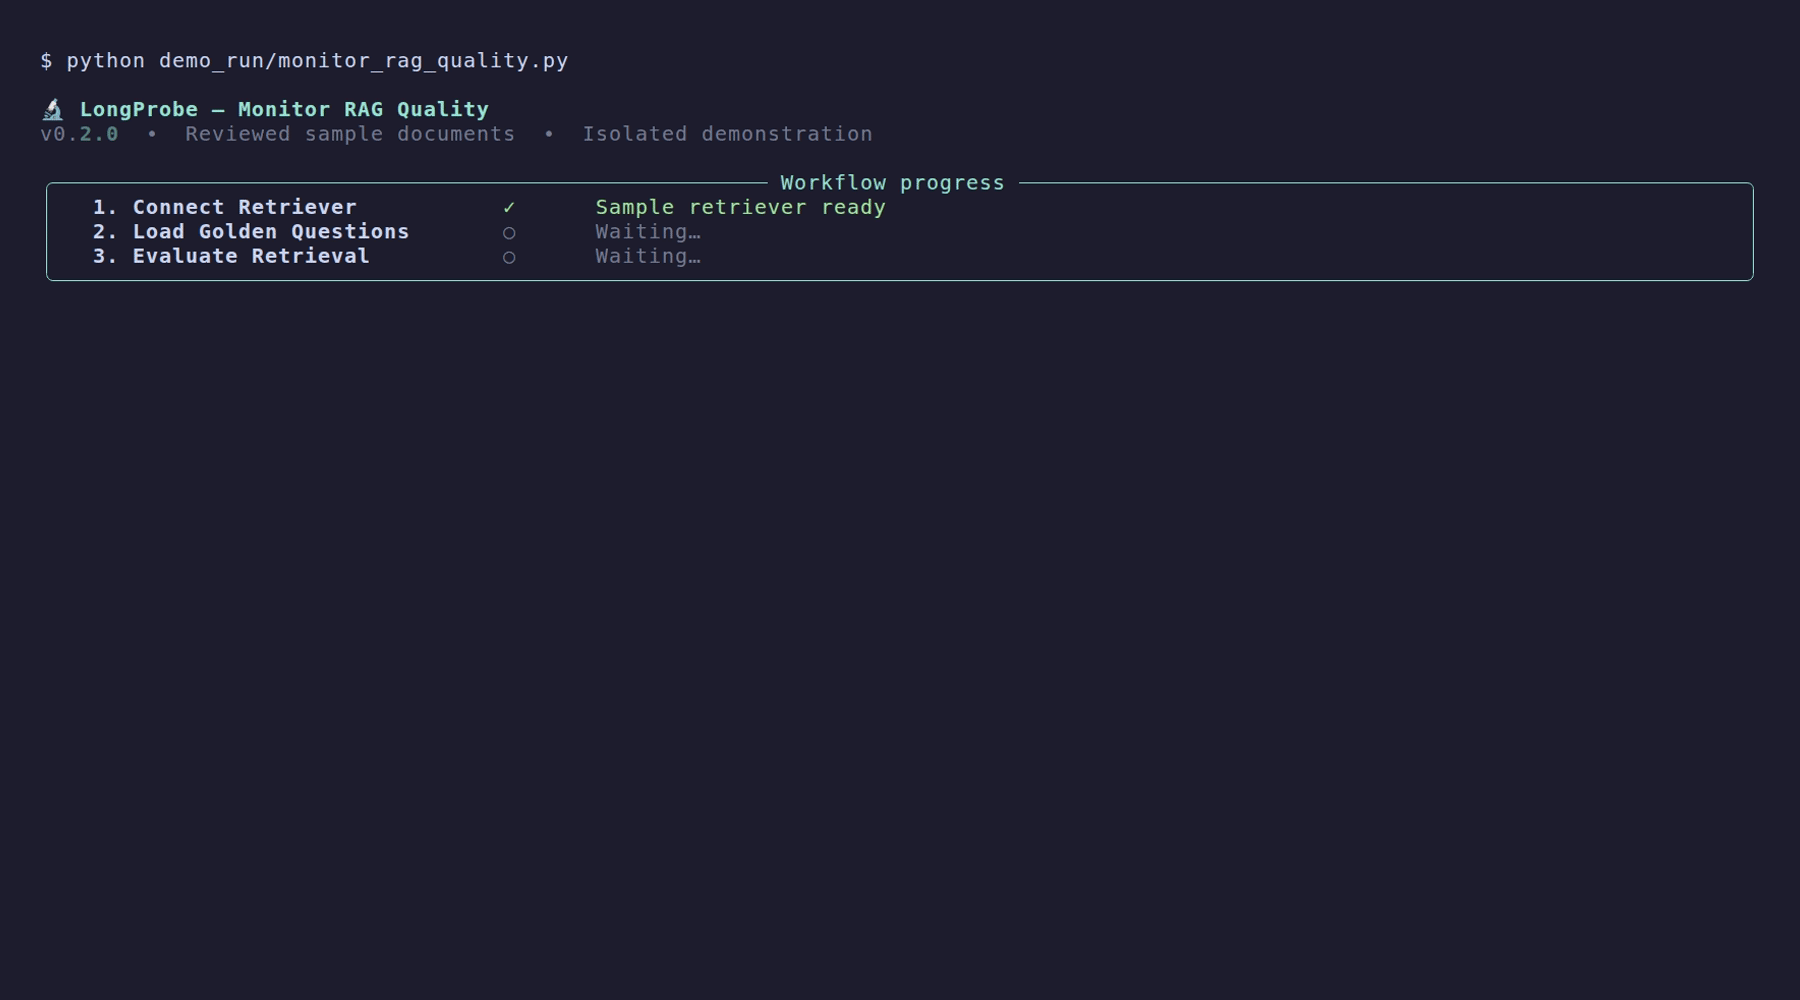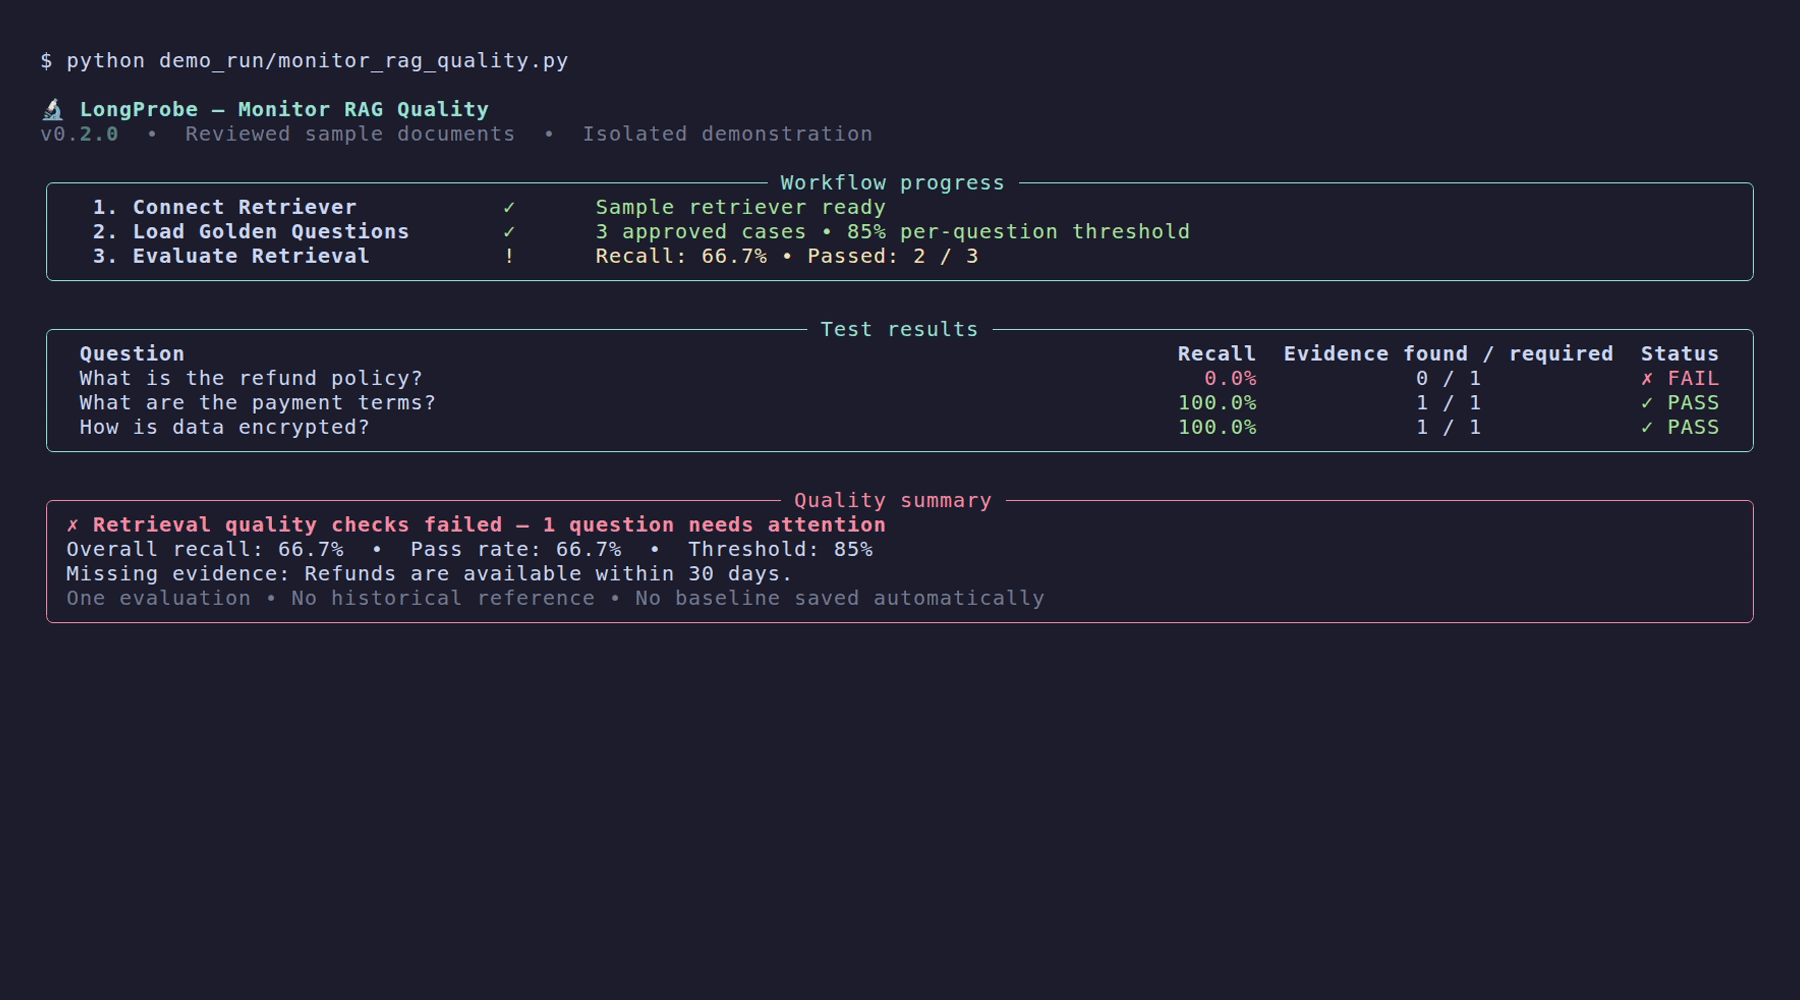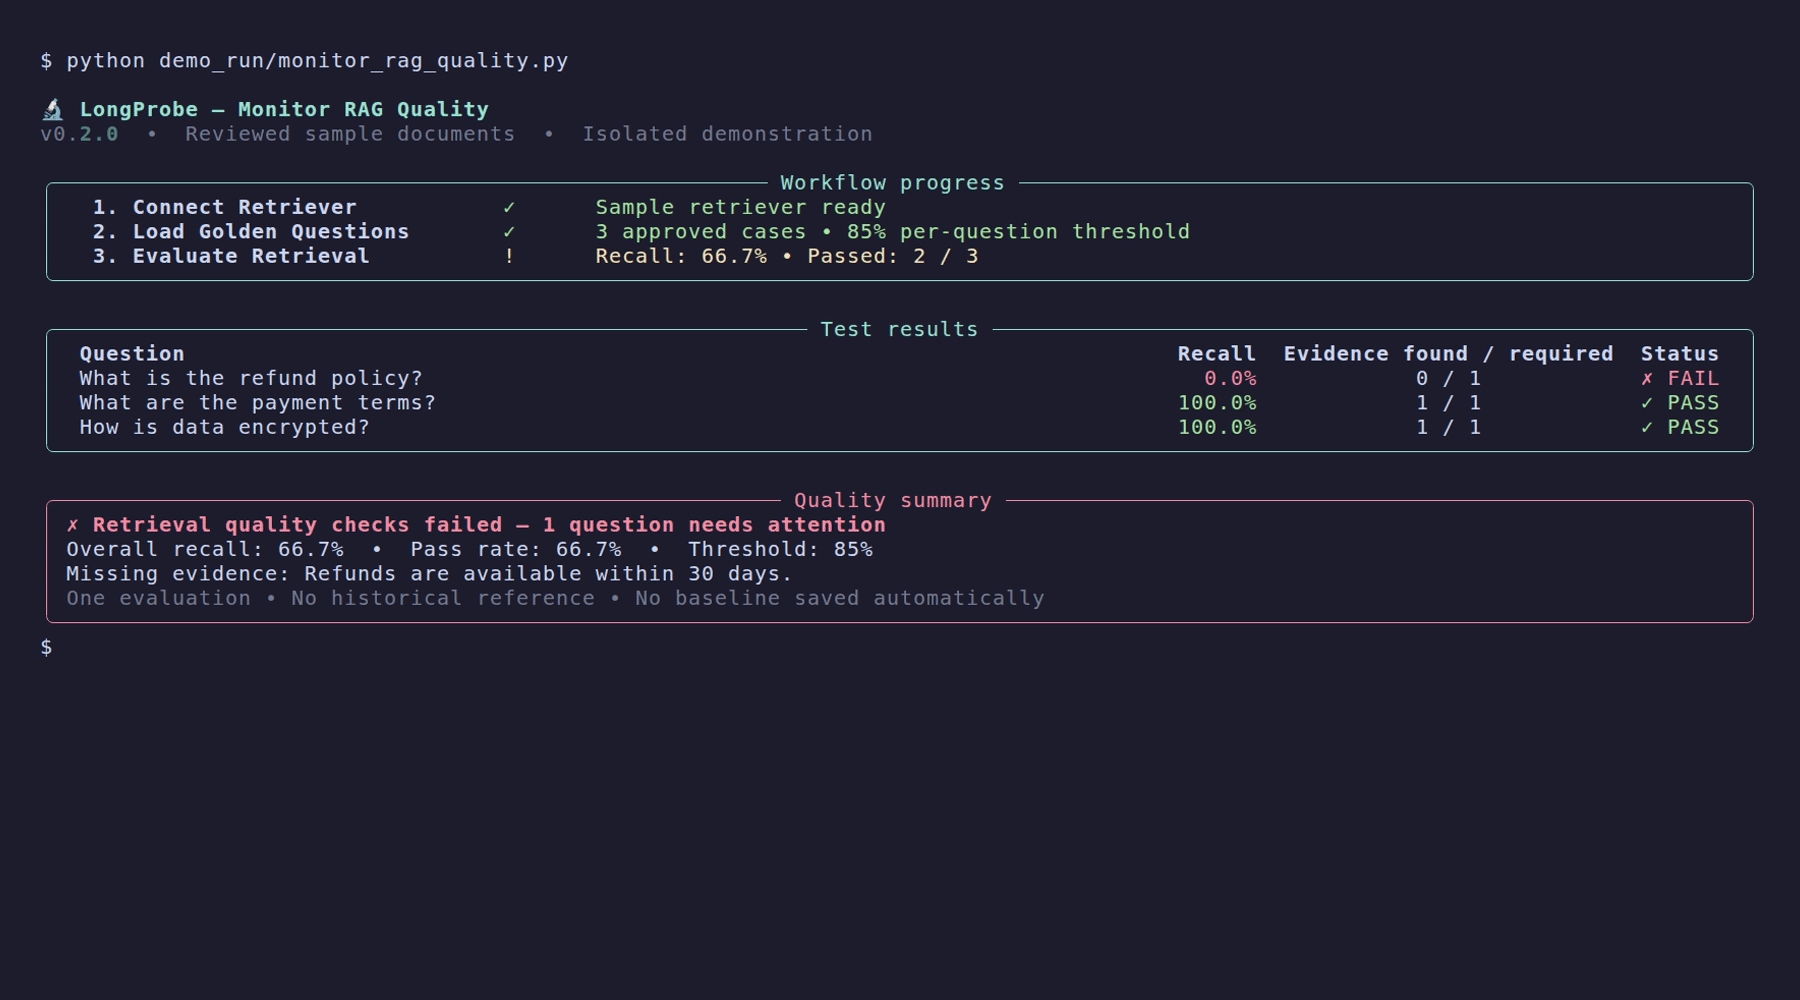
Monitor RAG Quality
Inspect recall percentages, evidence found / required, and quality results: two passing questions and one deliberate failure.
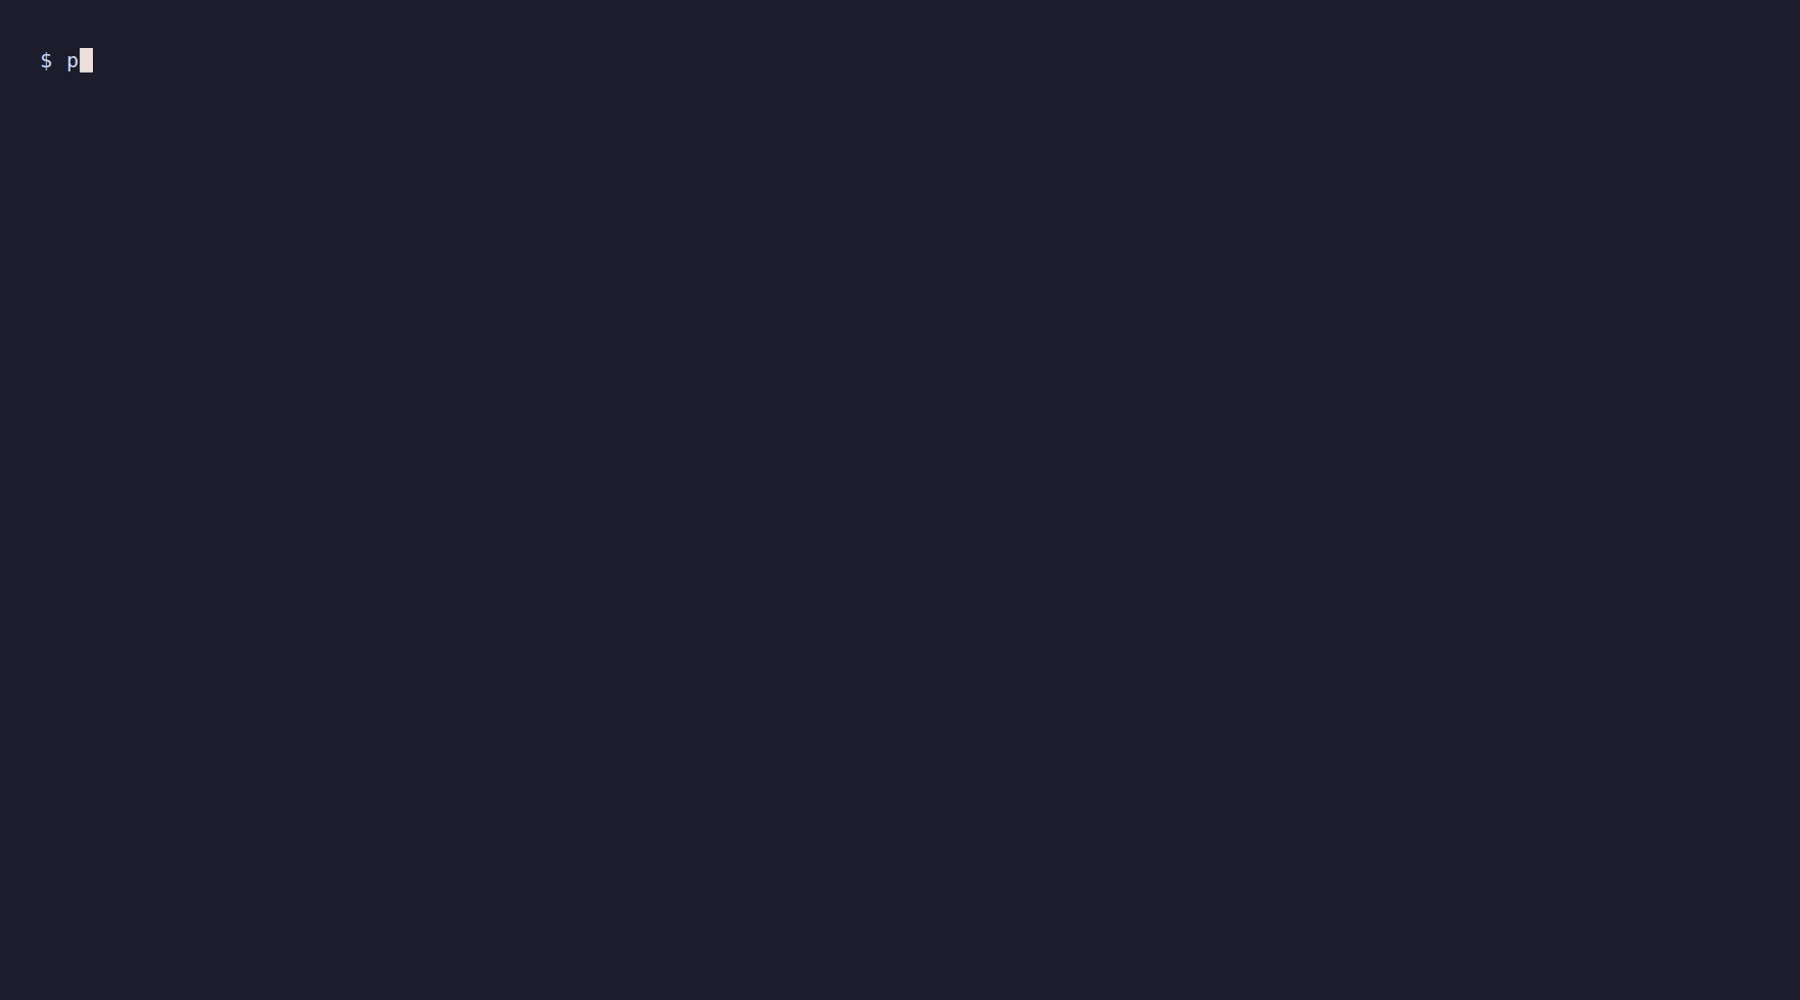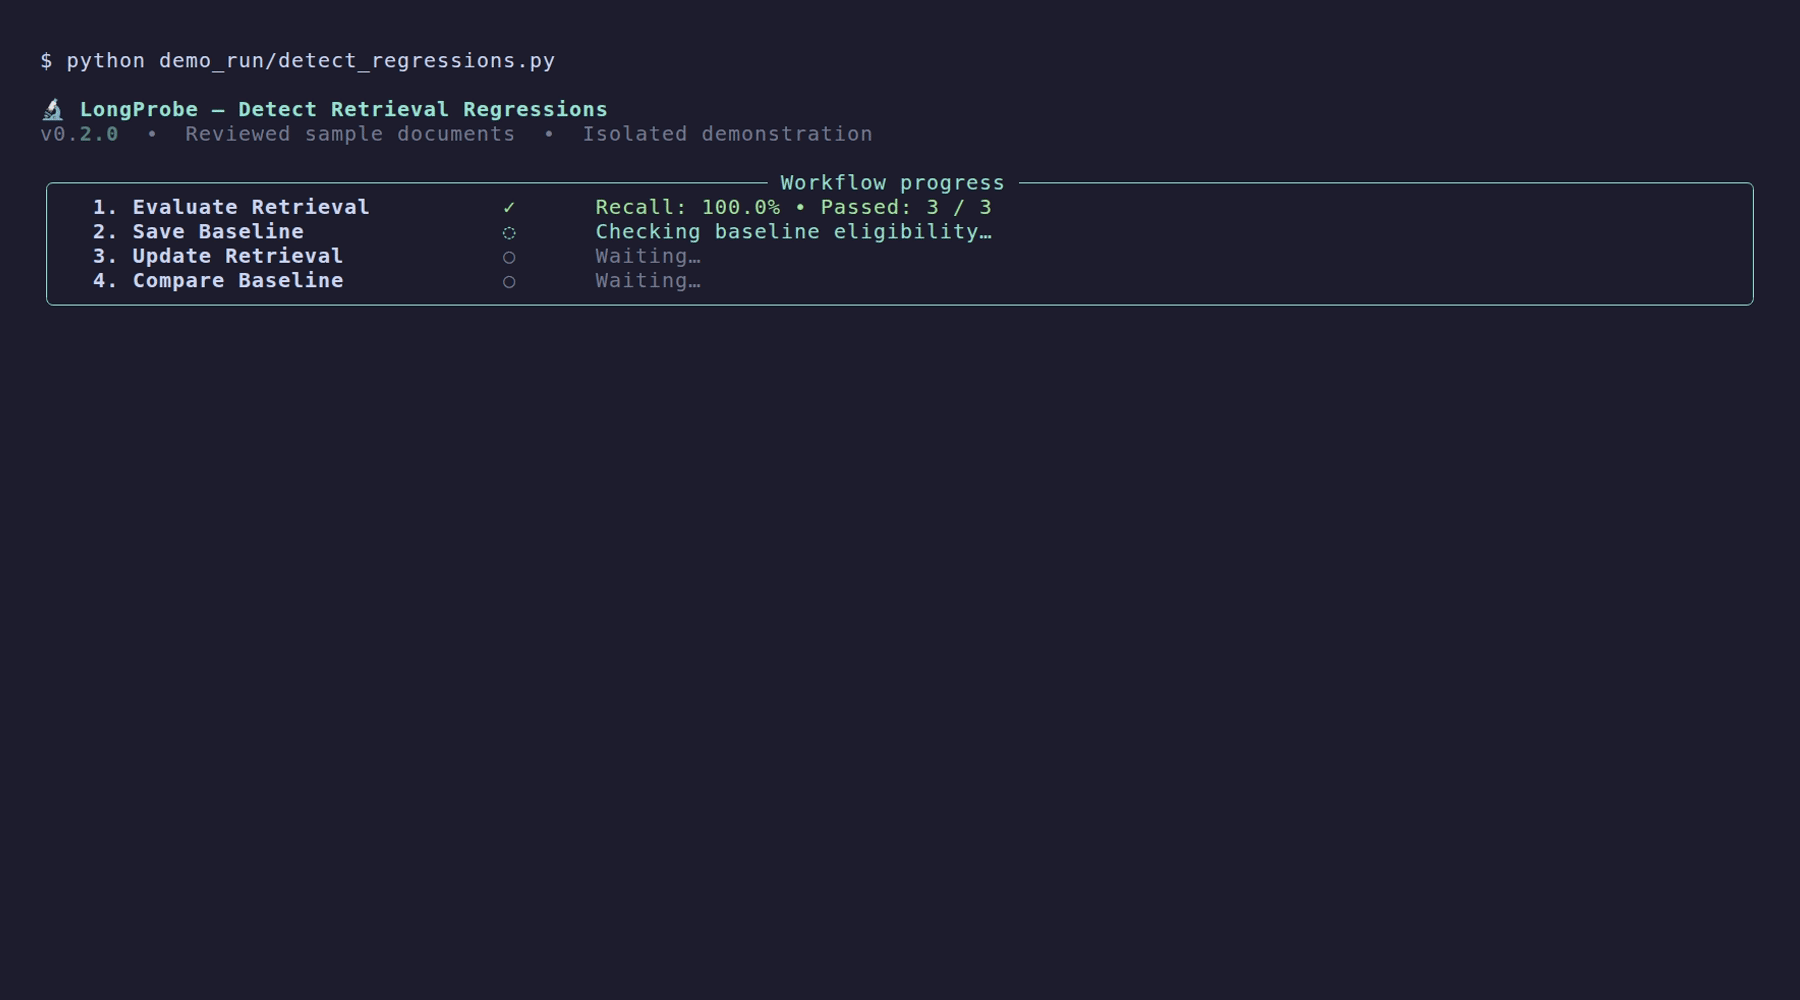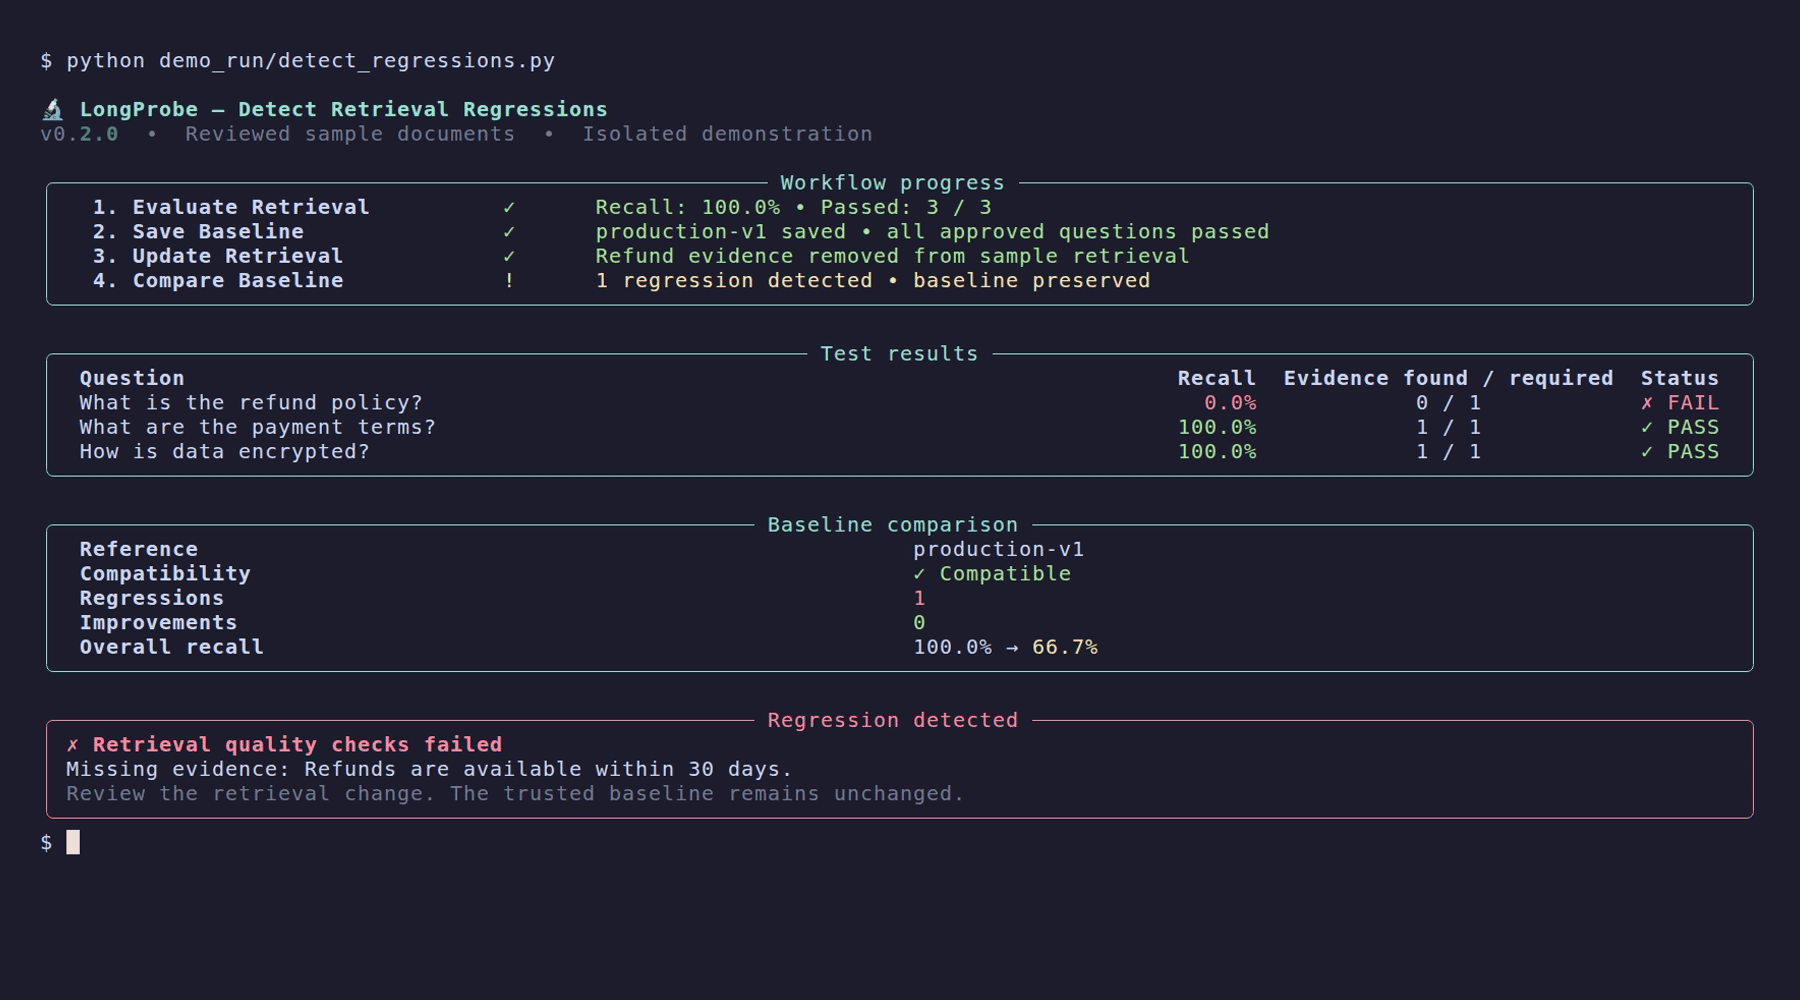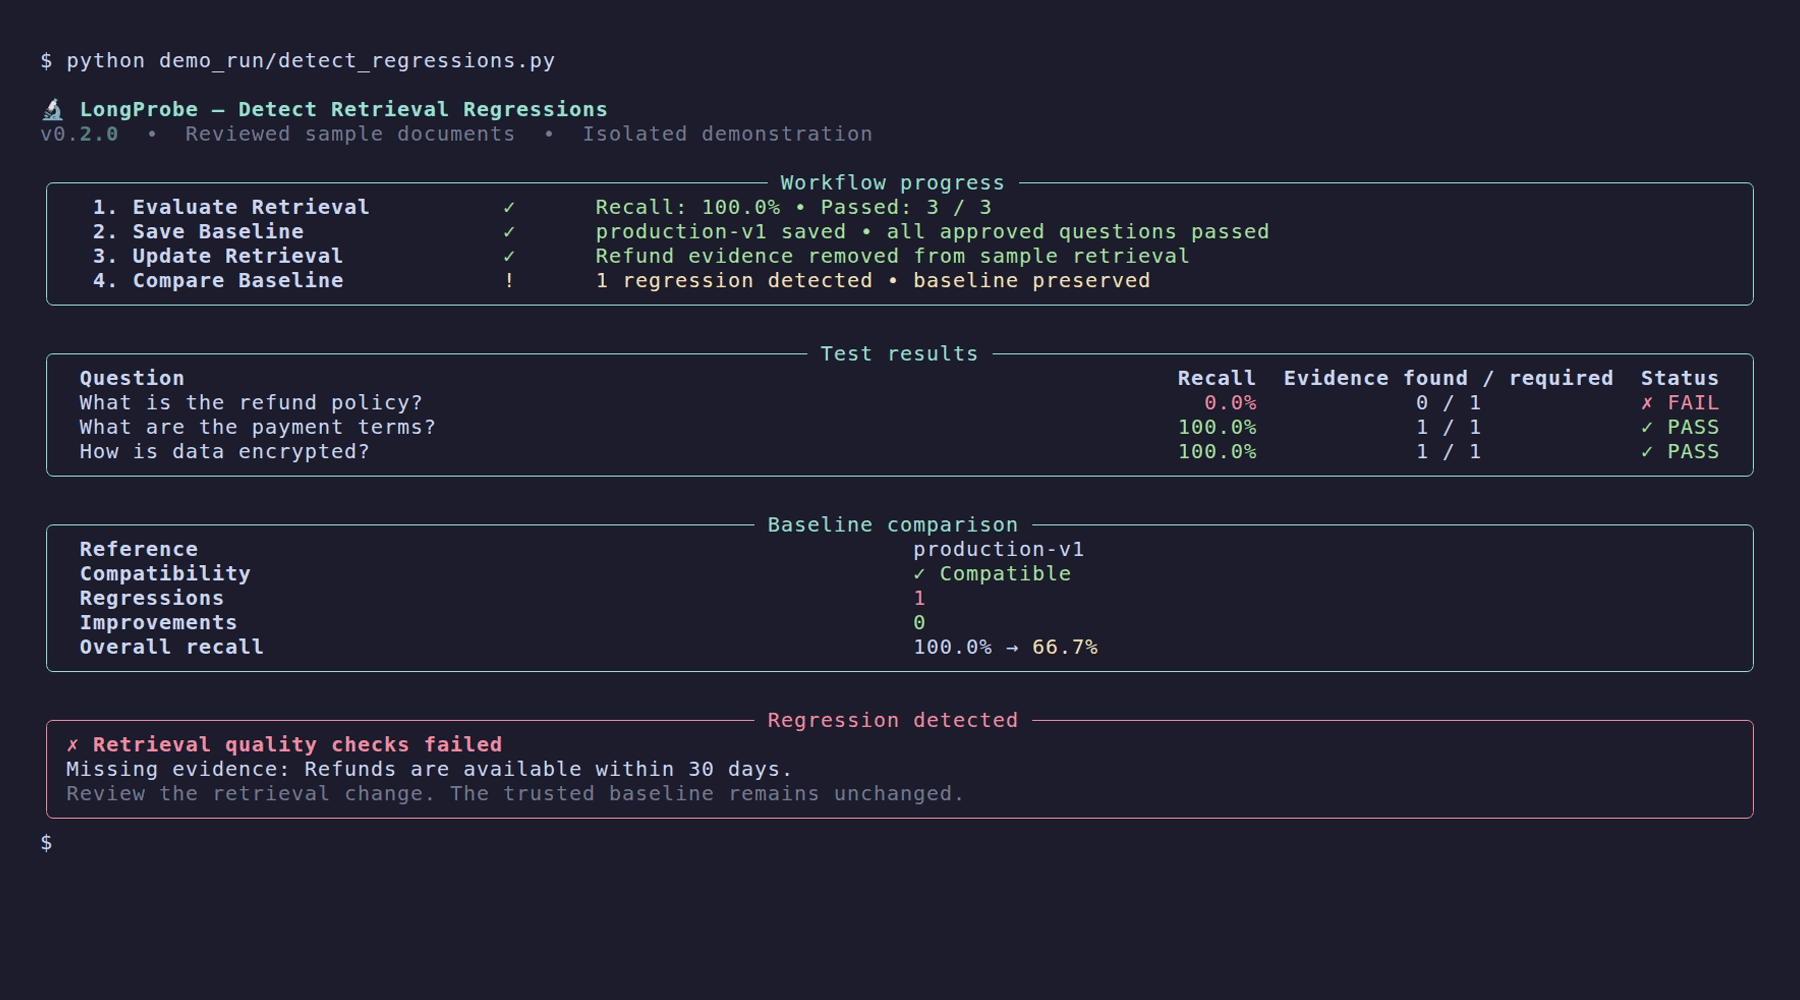
Detect Regressions
Compare against an explicitly selected baseline, check compatibility, and identify lost evidence and regression counts.
Why LongProbe?
Every RAG developer faces the same silent killer: you refactor chunking strategy, upgrade LangChain, or add a new document — and your retrieval silently degrades. DeepEval and RAGChecker are heavyweight evaluation frameworks meant for batch analysis, not fast regression checks in a dev loop.
LongProbe gives you instant feedback:
- ⚡ Sub-second checks on small golden sets
- 🔍 Exact diffs showing which chunks were lost/gained
- 📊 Recall scores with per-question breakdown
- 💾 Baseline tracking to catch regressions over time
- 🧪 pytest integration for existing test suites
- 🔌 Pluggable adapters for any vector store
Part of the Long Suite
LongProbe is part of the EnDevSols Long Suite of RAG tools:
- LongParser - Document ingestion and chunking
- LongTrainer - RAG chatbot framework
- LongTracer - Hallucination detection
- LongProbe - Retrieval regression testing ← You are here
Together they cover the full RAG pipeline from ingestion to production monitoring.
Features
- ⚡ Sub-second checks on small golden sets
- 📋 Golden Questions + Required Chunks defined in simple YAML
- 🔍 Three match modes: exact ID, text substring, and lexical cosine similarity (
semanticmode) - 📊 Recall Score with per-question breakdown
- 🔄 Regression diff: exactly which chunks were lost/gained
- 💾 SQLite baseline store: explicitly save references and compare compatible runs
- 🧪 pytest plugin: integrate into existing test suites
- 🔌 Pluggable adapters: LangChain, LlamaIndex, Chroma, Pinecone, Qdrant
- 🖥️ Beautiful CLI with Rich tables, JSON, and GitHub Actions output
- 👀 Watch mode: auto re-run when the golden file changes
- 🏗️ CI/CD ready: fails pipeline on regression
Quick Start
Installation
Requires Python 3.11 or newer. The package-index commands below install a published version. To use this v0.2.0 checkout, run pip install -e . from the directory containing pyproject.toml, or install its locally built wheel. See installation.
# Install with UV (recommended)
uv pip install longprobe

# Install with pip
pip install longprobe

# Install with optional dependencies
uv pip install "longprobe[chroma]"      # ChromaDB support
uv pip install "longprobe[openai]"      # Optional OpenAI SDK
uv pip install "longprobe[all]"         # Everything
Initialize
longprobe init
This creates:
.longprobe/— directory for baseline storagegoldens.yaml— example golden questionslongprobe.yaml— configuration file
The initial content is copied from fixed templates in CLI source. It does not read your documents or embeddings. Replace example questions with verified cases, or use capture/generate --auto-capture and review drafts with edit.
Configuration errors and zero-question evaluations fail explicitly. Existing invalid golden files are preserved rather than replaced during generation. See the working local HTTP quick start and v0.2.0 migration notes.
Define Golden Questions
Edit goldens.yaml with reviewed test cases. Omitted status defaults to approved; use status: draft for unverified candidates. Drafts are excluded by default. See the golden-question review workflow.
name: "my-rag-golden-set"
version: "1.0"

questions:
  - id: "q1"
    question: "What is the termination clause?"
    match_mode: "id"            # exact chunk ID match
    required_chunks:
      - "contracts_chunk_42"
      - "contracts_chunk_43"
    top_k: 5
    tags: ["contracts", "critical"]

  - id: "q2"
    question: "What are the payment terms?"
    match_mode: "text"          # substring match
    required_chunks:
      - "net 30 days from invoice"
    top_k: 5

  - id: "q3"
    question: "Who can sign contracts?"
    match_mode: "semantic"      # word-frequency similarity
    semantic_threshold: 0.80
    required_chunks:
      - "The following officers are authorized to sign"
    top_k: 10
Configure Your Retriever
Edit longprobe.yaml:
retriever:
  type: "chroma"
  persist_directory: "./chroma_db"
  collection: "my_documents"

scoring:
  recall_threshold: 0.8
  fail_on_regression: true

baseline:
  db_path: ".longprobe/baselines.db"
  auto_compare: true
  quality_gate: all_questions
Run Checks
# Run against live vector store
longprobe check --goldens goldens.yaml

# Override settings
longprobe check --threshold 0.9 --top-k 10

# After saving v1.0, require that reference
longprobe check --baseline v1.0

# Inspect current quality without a historical comparison
longprobe check --no-compare

# JSON output for automation
longprobe check --output json

# GitHub Actions annotations
longprobe check --output github
CLI Reference
Core Commands
| Command | Description |
|---|---|
longprobe init |
Create starter configuration files |
longprobe check |
Run probes against the golden set |
longprobe diff |
Compare current results against baseline |
longprobe baseline save |
Fresh approved-only evaluation and policy-gated baseline promotion |
longprobe report PATH |
Render a saved JSON report without retrieval |
longprobe baseline list |
List all saved baselines |
longprobe watch |
Watch golden file and re-run on changes |
longprobe generate |
Auto-generate Golden Questions from documents |
longprobe capture |
Capture candidate evidence from your retriever |
longprobe edit |
Review and approve draft questions |
Examples
# Initialize project
longprobe init

# Run checks with custom config
longprobe check -g goldens.yaml -c longprobe.yaml

# Save baseline for comparison
longprobe baseline save --label v1.0

# Compare against baseline
longprobe diff --baseline v1.0

# Watch mode for development
longprobe watch --interval 2

# Generate questions from documents
longprobe generate ./docs --auto-capture
longprobe edit
Python API
Basic Usage
from longprobe import LongProbe
from longprobe.adapters import create_adapter

# Create adapter for your vector store
adapter = create_adapter(
    "chroma",
    collection_name="my_documents",
    persist_directory="./chroma_db"
)

# Create and run probe
probe = LongProbe(
    adapter=adapter,
    goldens_path="goldens.yaml",
    config_path="longprobe.yaml"
)
report = probe.run()

print(f"Overall Recall: {report.overall_recall:.2%}")
print(f"Pass Rate: {report.pass_rate:.2%}")
Baseline Management
from longprobe import LongProbe
from longprobe.adapters import create_adapter

adapter = create_adapter("chroma", collection_name="docs", persist_directory="./db")
probe = LongProbe(adapter=adapter, goldens_path="goldens.yaml")

# Run and save baseline
report = probe.run()
probe.save_baseline(label="v1.0")

# After making changes, evaluate against the explicitly selected reference.
report2 = probe.run(baseline_label="v1.0")
diff = report2.comparison
print(f"Regressions: {len(diff['regressions'])}")
print(f"Improvements: {len(diff['improvements'])}")
assert report2.quality["passed"], report2.quality["reasons"]
With LangChain
from longprobe import LongProbe
from longprobe.adapters import LangChainRetrieverAdapter

# Wrap your existing LangChain retriever
adapter = LangChainRetrieverAdapter(your_langchain_retriever)
probe = LongProbe(adapter=adapter, goldens_path="goldens.yaml")
report = probe.run()

assert report.quality["passed"], report.quality["reasons"]
With LlamaIndex
from longprobe import LongProbe
from longprobe.adapters import LlamaIndexRetrieverAdapter

adapter = LlamaIndexRetrieverAdapter(your_llamaindex_retriever)
probe = LongProbe(adapter=adapter, goldens_path="goldens.yaml")
report = probe.run()
Pytest Integration
Configuration
Configure the retriever, scoring, and baseline settings in longprobe.yaml. The installed plugin supplies longprobe_report, which evaluates once per pytest session and shares the result across tests.
pytest --longprobe-config tests/longprobe.yaml --longprobe-goldens tests/goldens.yaml
Writing Tests
def test_retrieval_quality(longprobe_report):
    assert longprobe_report.quality["passed"], longprobe_report.quality["reasons"]
Alternatively, use pytest --longprobe-fail-threshold 0.85 to enforce quality automatically, even when tests do not request the report. Explicit per-question thresholds take precedence over that global threshold. Without an assertion or enforcement option, requesting a report alone does not enforce passing quality.
Retriever Adapters
LongProbe supports multiple vector stores and retrieval frameworks:
| Adapter | Type | Configuration |
|---|---|---|
| ChromaDB | Direct | type: chroma |
| Pinecone | Direct | type: pinecone |
| Qdrant | Direct | type: qdrant |
| HTTP API | Direct | type: http |
| LangChain | Programmatic | LangChainRetrieverAdapter |
| LlamaIndex | Programmatic | LlamaIndexRetrieverAdapter |
ChromaDB Example
retriever:
  type: chroma
  collection: my_collection
  persist_directory: ./chroma_db
HTTP API Example
retriever:
  type: http
  http:
    url: "http://localhost:8000/api/retrieve"
    method: "POST"
    body_template: '{"query": "{question}"}'
    response_mapping:
      results_path: "data.chunks"
      text_field: "content"
GitHub Actions
name: RAG Regression Check

on: [push, pull_request]

jobs:
  rag-probe:
    runs-on: ubuntu-latest
    steps:
      - uses: actions/checkout@v4
      - uses: astral-sh/setup-uv@v4
      - run: uv pip install --system "longprobe[chroma]==0.2.0"
      - name: Run RAG regression check
        run: longprobe check --goldens goldens.yaml --output github
Match Modes
ID Match (match_mode: "id")
Exact string match on chunk/document IDs. Best when you control the IDs in your vector store.
Text Match (match_mode: "text")
Case-insensitive substring matching. Checks if the required text appears anywhere in the retrieved documents.
Semantic Match (match_mode: "semantic")
Word-frequency cosine similarity. Measures lexical overlap; it does not use neural embeddings or guarantee matching paraphrases.
Current limitations
Normal checks pass text directly to the retriever; embedder settings are not wired into this path. Pinecone/Qdrant need an embedding-aware custom adapter or application endpoint. Semantic matching uses word frequencies, not neural embeddings. CLI/Python baseline promotion now defaults to every evaluated question passing. Legacy references remain readable but require reviewed rebaselining for strict comparison. JSON is machine-readable, and the pytest plugin supports configured adapters and a shared report fixture. Explain does not add rank/distance deltas.
Development
# Install for development
git clone https://github.com/ENDEVSOLS/LongProbe.git
cd LongProbe
uv sync --dev

# Run tests
uv run pytest tests/unit/ -v
uv run pytest tests/ -v --run-integration

# Lint and format
uv run ruff check src/
uv run ruff format src/
How It Works
Reviewed golden questions
            ↓
     Retriever adapter
            ↓
       Recall scoring
            ↓
    Baseline comparison
            ↓
  Quality verdict + report
- Define your Golden Questions + Required Fact Chunks in YAML
- Configure your existing retriever; it manages text-to-vector conversion where supported
- Retrieve from your live vector store using the pluggable adapter
- Score each question by checking if required chunks appear in Top-K results
- Compare against saved baselines to detect regressions
- Report a Recall Score, diff of lost chunks, and optionally fail CI/CD
Contributing
We welcome contributions! Please see CONTRIBUTING.md for guidelines.
Security
For security issues, please see SECURITY.md.
License
MIT License — see LICENSE for details.
1 maintainer

Metadata
1 maintainer
Release files for longprobe 0.2.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| longprobe-0.2.0.tar.gz | 130.9 kB | Without provenance | Details for longprobe-0.2.0.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| longprobe-0.2.0-py3-none-any.whl | Python 3 | none | any | Details for longprobe-0.2.0-py3-none-any.whl |
Total release size: 210.0 kB
Release files / longprobe-0.2.0.tar.gz
| Download URL | longprobe-0.2.0.tar.gz |
|---|---|
| Size | 130.9 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
485b4245a42972ea6e10fd82dca2d68badf00cb0e966bf83ecd74800f4ff21e7
|
|
BLAKE2b-256 checksum How to use checksums |
96dd833d8a6963e1cf07fd8056de8e24243a0e7c392e55751ea695d1fa3a6ad7
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
uv/0.13.5 {"installer":{"name":"uv","version":"0.13.5","subcommand":["publish"]},"python":null,"implementation":{"name":null,"version":null},"distro":{"name":"Ubuntu","version":"24.04","id":"noble","libc":null},"system":{"name":null,"release":null},"cpu":null,"openssl_version":null,"setuptools_version":null,"rustc_version":null,"ci":null}
|
Release files / longprobe-0.2.0-py3-none-any.whl
| Download URL | longprobe-0.2.0-py3-none-any.whl |
|---|---|
| Size | 79.1 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
d910ed37ecb4a842b0aeb284ef8fe3144bf24f082aaf46ad7fa8a8effae1beba
|
|
BLAKE2b-256 checksum How to use checksums |
37880bdd2706d57d95a63f21e0d9a4cf6f47ebd6ec824bf3fe324eff4190878a
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
uv/0.13.5 {"installer":{"name":"uv","version":"0.13.5","subcommand":["publish"]},"python":null,"implementation":{"name":null,"version":null},"distro":{"name":"Ubuntu","version":"24.04","id":"noble","libc":null},"system":{"name":null,"release":null},"cpu":null,"openssl_version":null,"setuptools_version":null,"rustc_version":null,"ci":null}
|
Security for longprobe 0.2.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














