
LongTrainer 1.4.0 — Production-Ready RAG Framework
Multi-tenant bots, streaming, tools, and persistent memory — all batteries included.



Documentation • Quick Start • Features • Migration from 0.3.4
Development status: The
1.4.0agent-type features are implemented in this checkout and locally verified. Package version metadata is aligned to1.4.0; this release has not been published. Use the source-install instructions below for the new interfaces.
What is LongTrainer?
LongTrainer is a production-ready RAG framework that turns your documents into intelligent, multi-tenant chatbots — with 5 lines of code.
Built on top of LangChain, LongTrainer handles the hard parts that every production RAG system needs: multi-bot isolation, persistent MongoDB memory, FAISS vector search, streaming responses, custom tool calling, chat encryption, and vision support — so you don't have to wire them together yourself.
Why LongTrainer over raw LangChain / LlamaIndex?
| Problem | LangChain / LlamaIndex | LongTrainer |
|---|---|---|
| Multi-bot management | DIY — manage state per bot | Built-in: initialize_bot_id() → isolated bots |
| Persistent chat memory | Wire MongoDB/Redis yourself | Built-in: MongoDB-backed, encrypted, restorable |
| Document ingestion | Assemble loaders + splitters | One-liner: add_document_from_path(path, bot_id) |
| Streaming responses | Implement astream yourself |
get_response(stream=True) yields chunks |
| Custom tool calling | Define tools, build agent | add_tool(my_tool) — plug and play |
| Web search augmentation | Find and integrate search | Built-in toggle: web_search=True |
| Vision chat | Complex multi-modal setup | get_vision_response() — pass images |
| Self-improving from chats | Not a concept | train_chats() feeds Q&A back into KB |
| Encryption at rest | DIY | encrypt_chats=True — Fernet out of the box |
Installation
pip install longtrainer
With legacy agent/tool-calling support (optional):
pip install longtrainer[agent]
With observability & hallucination detection (optional):
pip install longtrainer[tracer]
Source installation for 1.4.0 release preparation
From the Long-Trainer/ checkout, install the extra for the purpose you need:
pip install -e '.[research,api,cli]'
# Alternatives: '.[coding]', '.[financial]', or '.' for customer support/RAG.
Research and coding require TAVILY_API_KEY. All agent purposes require a tool-calling model; configure its credentials and a running MongoDB instance before creating bots. Default OpenAI models also require OPENAI_API_KEY. The [agent] extra installs LangGraph, but does not install every purpose's tools.
System Dependencies
Linux (Ubuntu/Debian)
sudo apt install libmagic-dev poppler-utils tesseract-ocr qpdf libreoffice pandoc
macOS
brew install libmagic poppler tesseract qpdf libreoffice pandoc
Quick Start 🚀
LongTrainer 1.4.0 requires Python 3.11 or newer. Python 3.12 is recommended for development. Upgrade Python 3.10 environments before installing this version.
🎬 Complete Workflow Demo
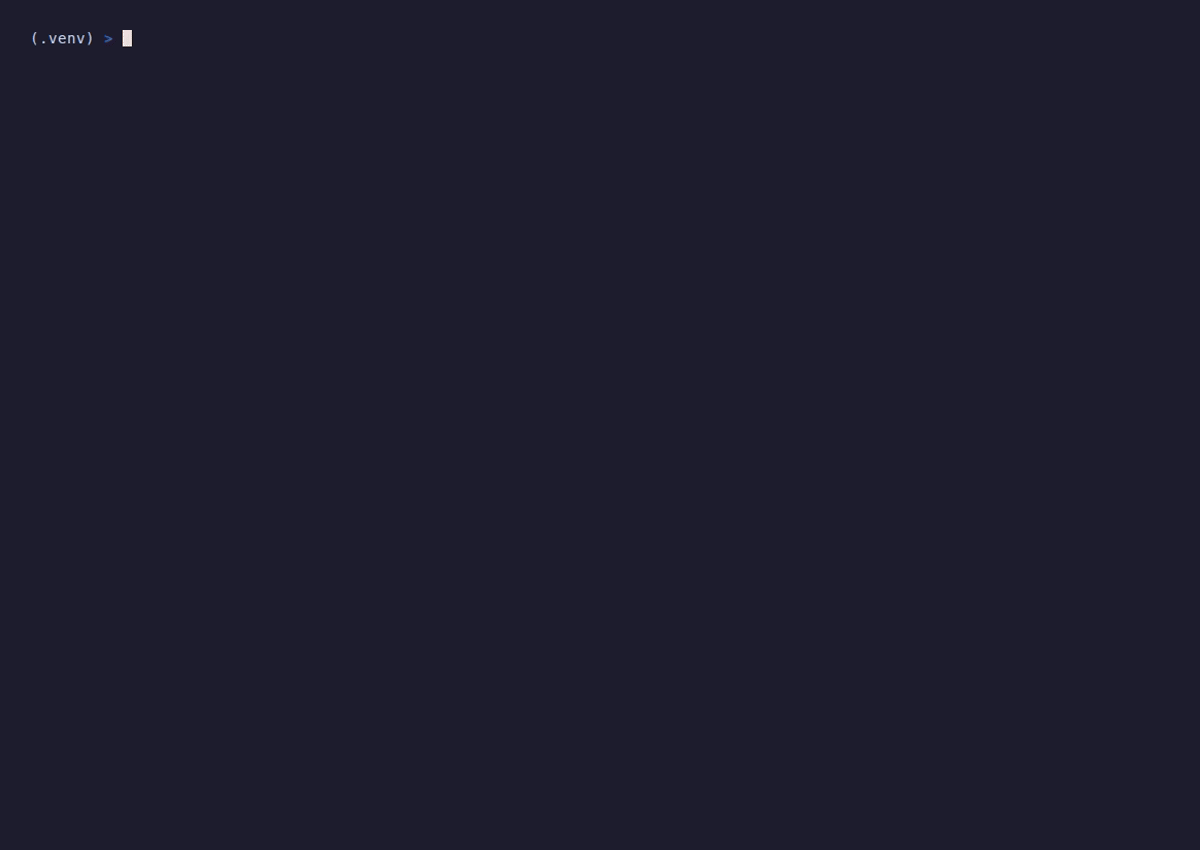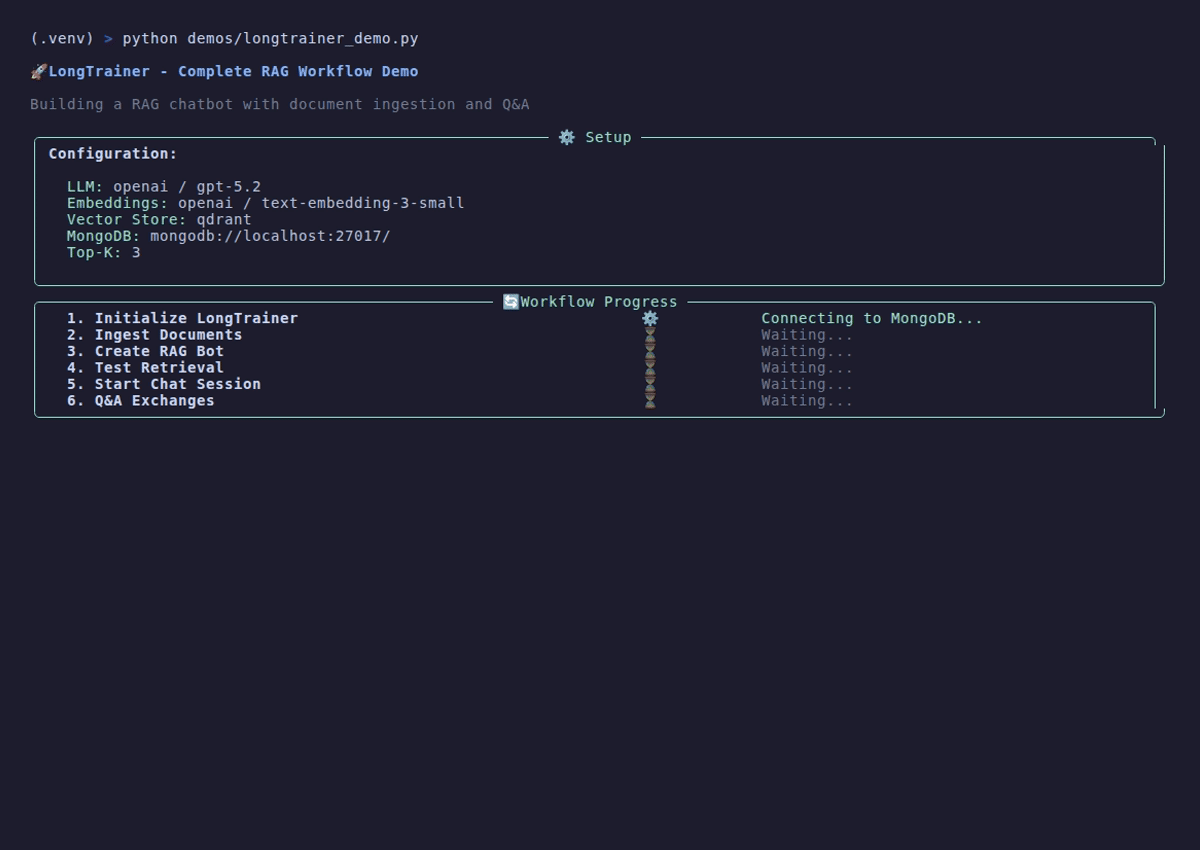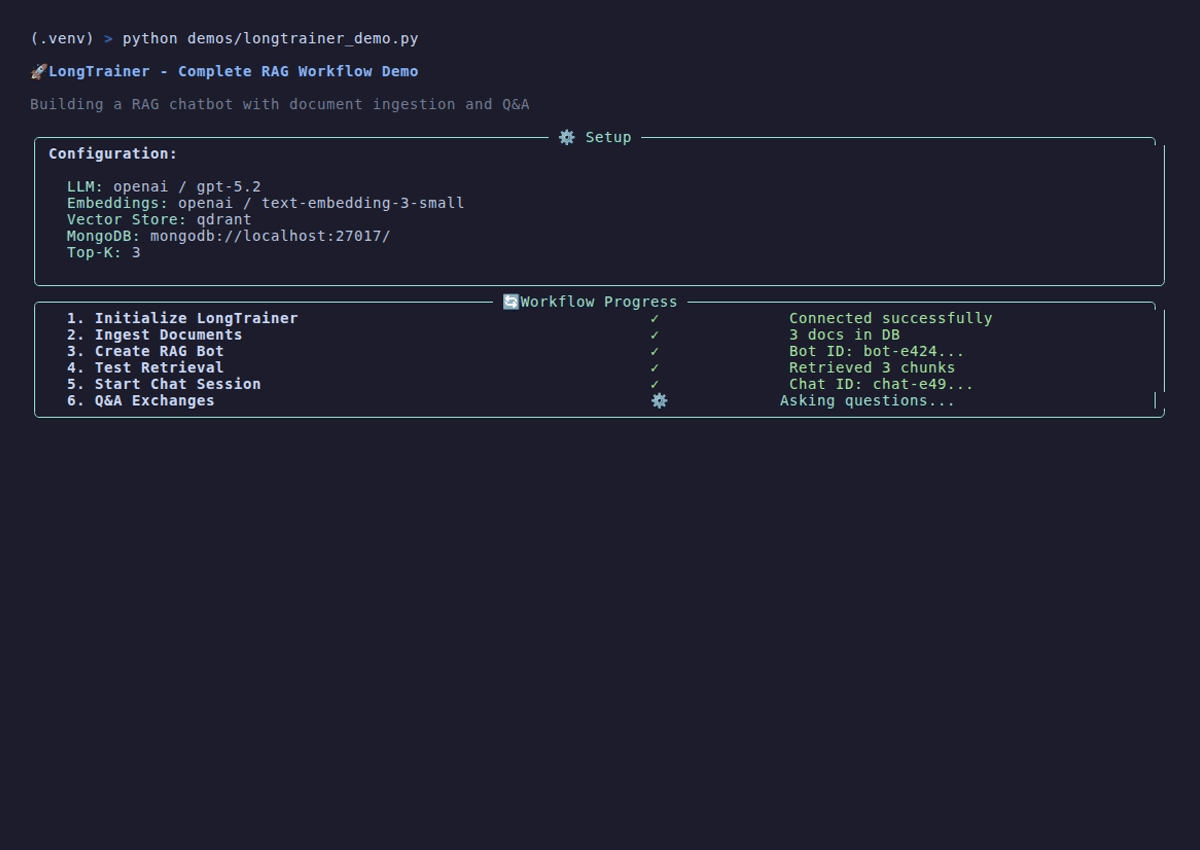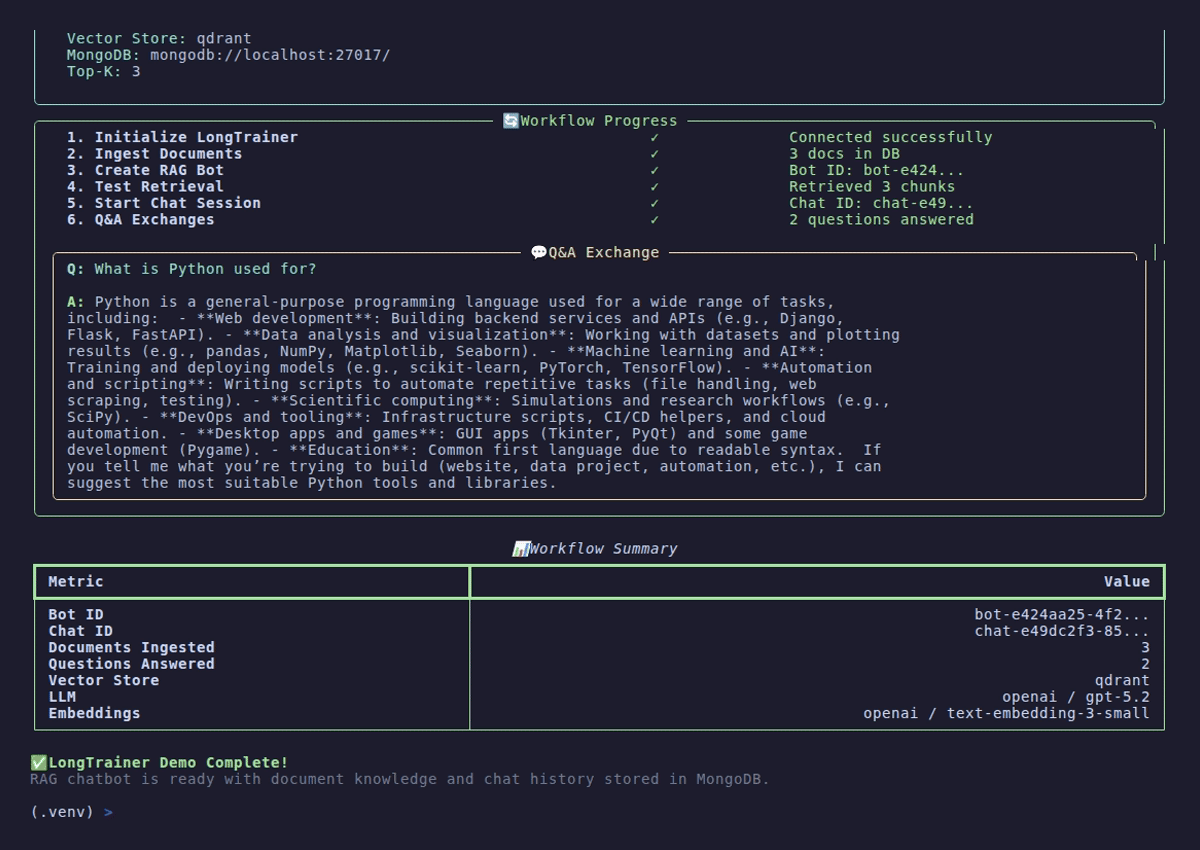
Full RAG workflow: initialize → create bot → ingest documents → vector search → Q&A — all with live progress tracking. Run it yourself:
python demos/longtrainer_demo.py
1. Zero-Code CLI & API Server
# 1. Initialize a new project and generate longtrainer.yaml
longtrainer init

# 2. Create a new bot
longtrainer bot create --prompt "You are a helpful assistant."

# 3. Add a document (PDF, link, etc.)
longtrainer add-doc <bot_id> /path/to/document.pdf

# 4. Start chatting!
longtrainer chat <bot_id>
FastAPI REST Server
Install longtrainer[api,cli] (or pip install -e '.[api,cli]' from this checkout), then start the API server:
longtrainer serve
This starts a FastAPI server on http://localhost:8000 with endpoints including:
/health/bots(CRUD)/bots/{id}/documents/path(Ingest files)/bots/{id}/chats/{chat_id}(Chat and Streaming)
Visit http://localhost:8000/docs to see the auto-generated Swagger UI.
2. Python SDK — Default RAG Mode
from longtrainer.trainer import LongTrainer
import os

os.environ["OPENAI_API_KEY"] = "sk-..."

# Initialize
trainer = LongTrainer(mongo_endpoint="mongodb://localhost:27017/")
bot_id = trainer.initialize_bot_id()

# Add documents (PDF, DOCX, CSV, HTML, MD, TXT, URLs, YouTube, Wikipedia)
trainer.add_document_from_path("path/to/your/data.pdf", bot_id)

# Create bot and start chatting
trainer.create_bot(bot_id)
chat_id = trainer.new_chat(bot_id)

# Get response
answer, sources = trainer.get_response("What is this document about?", bot_id, chat_id)
print(answer)
Streaming Responses
# Stream tokens in real-time
for chunk in trainer.get_response("Summarize the key points", bot_id, chat_id, stream=True):
    print(chunk, end="", flush=True)
Structured JSON Responses
For RAG bots, pass a JSON Schema to validate the complete response:
schema = {
    "type": "object",
    "properties": {"answer": {"type": "string"}},
    "required": ["answer"],
}
result, sources = trainer.get_response("Summarize the document", bot_id, chat_id, schema=schema)
print(result["status"], result["data"])
The dictionary contains status, data, raw_llm_output, and error. Invalid JSON/schema output is retried once; final validation failure returns partial_success with the last raw output. Structured responses require a complete response, so do not combine them with streaming.
Async Streaming
async for chunk in trainer.aget_response("Explain the methodology", bot_id, chat_id):
    print(chunk, end="", flush=True)
3. Named Agent Types — 1.4.0
Choose a purpose to select its default prompt, tools and execution mode:
from longtrainer import LongTrainer, AgentTypeRegistry

trainer = LongTrainer(mongo_endpoint="mongodb://localhost:27017/")
bot_id = trainer.initialize_bot_id()
trainer.create_bot(bot_id, agent_type="research")
chat_id = trainer.new_chat(bot_id)
answer, sources = trainer.get_response("Compare the available research on this topic", bot_id, chat_id)
print(answer)
print(AgentTypeRegistry.names())
| Type | Runtime | Default capabilities | Source installation |
|---|---|---|---|
research |
Agent | Tavily search, Wikipedia, arXiv; cross-checking and citations | pip install -e '.[research]' |
coding |
Agent | Python REPL and Tavily search; ordered work, testing and error recovery | pip install -e '.[coding]' |
financial |
Agent | Yahoo Finance News and Python REPL; sourced figures, timestamps and a disclaimer | pip install -e '.[financial]' |
customer_support |
RAG | Knowledge-base retrieval, source identifiers and escalation when unsupported | pip install -e . |
Financial tools provide news and calculations, not a market-price feed. Coding and financial Python tools execute in the application process with its permissions; the library does not sandbox their execution. Customer support rejects web/upload augmentation and vision responses, and instructs the model to cite supplied documents. Model adherence is not independently verified. SQL is deferred and is not a registered type.
Overrides and persistence
# A supplied purpose determines mode. An explicit prompt replaces its default.
trainer.create_bot(bot_id, agent_type="research", tools=["wikipedia"],
                   prompt_template="Research carefully and cite your sources.")

# An explicit empty list disables default tools.
trainer.create_bot(bot_id, agent_type="coding", tools=[])
tools=None uses purpose defaults; an explicit list replaces them. Named bots exclude implicit global and previous per-bot tools. Missing required tools, dependencies or keys fail visibly. Calls without agent_type retain legacy RAG/agent behavior.
The purpose, effective prompt/mode and string tool identifiers survive load_bot() and internal ingestion/chat-training rebuilds. Tool objects and credentials are not serialized; re-register custom tool objects after reload. Application-defined registry types must also be registered again before loading their records. A direct create_bot(bot_id) keeps legacy creation semantics rather than inferring a stored purpose.
CLI
After installing the required extra and configuring infrastructure with longtrainer init:
# Initialize and build a new research bot; prints its ID.
longtrainer build --agent-type research

# Build an existing bot or create a new support bot.
longtrainer build BOT_ID --agent-type coding --tools ""
longtrainer bot create --agent-type customer_support
A plain longtrainer build BOT_ID preserves stored named configuration. --tools "" explicitly selects no tools. Existing bot create, --agent, --tools, and --prompt options remain available. YAML contains infrastructure settings only; select per-bot purpose, prompt and tools through explicit CLI/API/Python arguments.
HTTP API
After initializing an ID with POST /bots, use the existing build route:
curl -X POST http://localhost:8000/bots/BOT_ID/build \
  -H 'Content-Type: application/json' \
  -d '{"agent_type":"research","tools":["wikipedia"]}'
The optional agent_type field selects a purpose. Unknown names return HTTP 400 listing supported types. Omit tools or use null for defaults; use [] for no tools. Explicit prompt_template overrides the default. Existing payloads and response shapes remain supported.
See the Named Agent Types guide for full configuration and restoration rules.
Dynamic Tools in Legacy Agent Mode
The legacy path accepts identifiers supported by the existing LangChain community loader:
# bot_id must have been initialized first; install the tool dependencies.
trainer.create_bot(bot_id, agent_mode=True, tools=["wikipedia", "arxiv"])
Loader identifiers differ from runtime tool names and class names. The named-purpose path additionally adapts tavily, python_repl, and yahoo_finance_news through the existing factories. Use add_tool() for custom tool objects as shown below.
Agent Mode — With Custom Tools
from longtrainer.tools import web_search
from langchain_core.tools import tool

# Add built-in web search tool
trainer.add_tool(web_search, bot_id)

# Add your own custom tool
@tool
def multiply(left: float, right: float) -> float:
    """Multiply two numbers."""
    return left * right

trainer.add_tool(multiply, bot_id)

# Create bot in agent mode
trainer.create_bot(bot_id, agent_mode=True)
chat_id = trainer.new_chat(bot_id)

response, _ = trainer.get_response("What is 42 * 17?", bot_id, chat_id)
print(response)
Vision Chat
vision_id = trainer.new_vision_chat(bot_id)
response, sources = trainer.get_vision_response(
    "Describe what you see in this image",
    image_paths=["photo.jpg"],
    bot_id=bot_id,
    vision_chat_id=vision_id,
)
print(response)
Per-Bot Customization
from langchain_openai import ChatOpenAI, OpenAIEmbeddings

# Each bot can have its own LLM, embeddings, and retrieval config
trainer.create_bot(
    bot_id,
    llm=ChatOpenAI(model="gpt-4o-mini", temperature=0.2),
    embedding_model=OpenAIEmbeddings(model="text-embedding-3-small"),
    num_k=5,                    # retrieve 5 docs per query
    prompt_template="You are a helpful legal assistant. {context}",
    agent_mode=True,            # enable tool calling
    tools=[web_search],
)
Features ✨
Core
- ✅ Named Purposes (1.4.0 checkout): Research, coding, financial news and document-grounded customer support
- ✅ Structured JSON Responses: Schema validation with one retry; existing dictionary response contract
- ✅ Dual Mode: RAG (LCEL chain) for simple Q&A, Agent (LangGraph) for tool calling
- ✅ Streaming Responses: Sync and async streaming out of the box
- ✅ Custom Tool Calling: Add any LangChain
@tool— web search, document reader, or your own - ✅ Multi-Bot Management: Isolated bots with independent sessions, data, and configs
- ✅ Persistent Memory: MongoDB-backed chat history, fully restorable
- ✅ Chat Encryption: Fernet encryption for stored conversations
- ✅ Observability & Tracing: Native integration with LongTracer for logging spans and hallucination detection (
pip install longtrainer[tracer])
Document Ingestion
- ✅ Standard Formats: PDF, DOCX, CSV, HTML, Markdown, TXT
- ✅ Web & Crawling:
add_document_from_link(),add_document_from_query(),add_document_from_crawl() - ✅ Cloud & Enterprise: S3 (
add_document_from_aws_s3), Google Drive (add_document_from_google_drive), Confluence (add_document_from_confluence) - ✅ Structured Data: Local Directory (
add_document_from_directory), JSON & JQ (add_document_from_json), GitHub Repo (add_document_from_github) - ✅ Dynamic Integrations: Inject ANY LangChain document loader class dynamically via
add_document_from_dynamic_loader()
RAG Pipeline & Vector DBs
- ✅ Vector Databases: FAISS, Pinecone, Chroma, Qdrant, PGVector, MongoDB Atlas, Milvus, Elasticsearch, Weaviate
- ✅ Multi-Query Ensemble Retrieval: Generates alternative queries for better recall
- ✅ Self-Improving Memory:
train_chats()feeds past Q&A back into the knowledge base
Customization
- ✅ Per-bot LLM — use different models for different bots
- ✅ Per-bot Embeddings — custom embedding models per bot
- ✅ Per-bot Retrieval Config — custom
num_k,chunk_size,chunk_overlap - ✅ Custom Prompt Templates — full control over system prompts
- ✅ Vision Chat — GPT-4 Vision support with image understanding
Works with All LangChain-Compatible LLMs
- ✅ OpenAI (default)
- ✅ Anthropic
- ✅ Google VertexAI / Gemini
- ✅ AWS Bedrock
- ✅ HuggingFace
- ✅ Groq
- ✅ Together AI
- ✅ Ollama (local models)
- ✅ Any
BaseChatModelimplementation
API Reference
LongTrainer — Main Class
trainer = LongTrainer(
    mongo_endpoint="mongodb://localhost:27017/",
    llm=None,                # default: ChatOpenAI(model="gpt-4o-2024-08-06")
    embedding_model=None,    # default: OpenAIEmbeddings()
    prompt_template=None,    # custom system prompt
    max_token_limit=32000,   # conversation memory limit
    num_k=3,                 # docs to retrieve per query
    chunk_size=2048,         # text splitter chunk size
    chunk_overlap=200,       # text splitter overlap
    ensemble=False,          # enable multi-query ensemble retrieval
    encrypt_chats=False,     # enable Fernet encryption
    encryption_key=None,     # custom encryption key (auto-generated if None)
    enable_tracer=False,     # enable LongTracer observability
    tracer_backend="mongo",    # tracer backend ('mongo', 'sqlite', 'memory')
    tracer_verify=True,      # run CitationVerifier (hallucination detection)
    tracer_verbose=False,    # print tracer spans to console
    tracer_threshold=0.5,    # confidence threshold for tracer (0-1)
)
Key Methods
| Method | Description |
|---|---|
initialize_bot_id() |
Create a new bot, returns bot_id |
create_bot(bot_id, ..., agent_type=None) |
Build a bot with optional purpose selection |
AgentTypeRegistry.names() |
List supported registered purposes |
load_bot(bot_id) |
Restore an existing bot from MongoDB + FAISS |
new_chat(bot_id) |
Start a new chat session, returns chat_id |
get_response(query, bot_id, chat_id, stream=False, schema=None) |
Get a response, stream, or schema-validated dictionary |
aget_response(query, bot_id, chat_id) |
Async streaming response |
add_document_from_path(path, bot_id) |
Ingest a file |
add_document_from_link(links, bot_id) |
Ingest URLs / YouTube links |
add_tool(tool, bot_id) |
Register a tool for a bot |
remove_tool(tool_name, bot_id) |
Remove a tool |
list_tools(bot_id) |
List registered tools |
train_chats(bot_id) |
Self-improve from chat history |
new_vision_chat(bot_id) |
Start a vision chat session |
get_vision_response(query, images, bot_id, vision_id) |
Vision response |
Development Checks
From the checkout, install test dependencies and the document parser asset:
pip install -e '.[agent,dev,cli,api,integration]'
python -m pip install 'spacy>=3.8,<3.9' 'https://github.com/explosion/spacy-models/releases/download/en_core_web_sm-3.8.0/en_core_web_sm-3.8.0-py3-none-any.whl'
pytest tests/ -v -ra
ruff check .
The default suite skips the MongoDB integration test. To include it, point to a dedicated test service:
LONGTRAINER_TEST_MONGO_URI='mongodb://localhost:27017/?serverSelectionTimeoutMS=5000' \
  pytest tests/ -v -ra --run-integration
Build documentation into a temporary directory:
pip install mkdocs mkdocs-material
mkdocs build --strict --config-file docs/mkdocs.yml --site-dir /tmp/longtrainer-docs
To publish docs from your repository, open Settings → Pages and select
GitHub Actions under Build and deployment → Source. This one-time setup
is required for each repository, including forks; the workflow's GITHUB_TOKEN
cannot enable Pages. Without it, deployment can fail with
Failed to create deployment (status: 404) even when the docs build succeeds.
After enabling Pages, push or merge the updated workflow into master to start
a new deployment, or run Actions → Deploy Docs → Run workflow on master.
Rerunning an older failed run uses its original workflow, so it will not pick up
workflow fixes. Each attempt of the updated workflow uses a unique artifact name
to avoid duplicate github-pages artifacts on reruns. Later changes to docs/
deploy automatically.
Local verification recorded 142 passing tests with MongoDB integration on Python 3.12; Python 3.10/3.11 each passed 141 offline tests, with the service test skipped. Fresh base and individual purpose installs, real tool construction and strict docs builds passed. Remote CI, human review and release publication remain pending. These checks use local fake models and do not verify live external search/finance services. See Phase C verification and Phase D verification.
Migration from 0.3.4
LongTrainer 1.0.0 is a major upgrade with breaking changes:
| 0.3.4 | 1.0.0 |
|---|---|
ConversationalRetrievalChain |
LCEL chain (RAGBot) or LangGraph agent (AgentBot) |
requirements.txt + setup.py |
pyproject.toml (UV/pip compatible) |
| No streaming | stream=True or aget_response() |
| No tool calling | add_tool() + agent_mode=True |
langchain.memory |
langchain_core.chat_history |
| Fixed LLM for all bots | Per-bot LLM, embeddings, and config |
Upgrade path:
pip install --upgrade longtrainer
The core API (initialize_bot_id, create_bot, new_chat, get_response) remains the same — existing code should work with minimal changes. The main difference is get_response() now returns (answer, sources) instead of (answer, sources, web_sources).
Part of the Long Suite
LongTrainer is part of the Long Suite — a collection of tools for building, testing, and monitoring production RAG systems.
| Project | Description |
|---|---|
| LongParser | Document ingestion and chunking |
| LongTrainer | RAG chatbot framework (you are here) |
| LongTracer | Hallucination detection and tracing |
| LongProbe | Retrieval regression testing |
Citation
@misc{longtrainer,
  author = {Endevsols},
  title = {LongTrainer: Production-Ready RAG Framework},
  year = {2024},
  publisher = {GitHub},
  journal = {GitHub repository},
  howpublished = {\url{https://github.com/ENDEVSOLS/Long-Trainer}},
}
License
Contributing
We welcome contributions! See CONTRIBUTING.md for guidelines.
1 maintainer

Metadata
1 maintainer
Release files for longtrainer 1.4.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| longtrainer-1.4.0.tar.gz | 1.6 MB | Without provenance | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| longtrainer-1.4.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 1.6 MB
Release files / longtrainer-1.4.0.tar.gz
| Download URL | longtrainer-1.4.0.tar.gz |
|---|---|
| Size | 1.6 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
1c2d45c6adb1f6d730ab382235fdd50907d1980b5d79145e762d8dfb49cd938c
|
|
BLAKE2b-256 checksum How to use checksums |
96afbe22cd4c42693a7ebb78d817ef68ecc0e26f351ed49f511fd1d6c087f3cd
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
uv/0.9.26 {"installer":{"name":"uv","version":"0.9.26","subcommand":["publish"]},"python":null,"implementation":{"name":null,"version":null},"distro":{"name":"Ubuntu","version":"24.04","id":"noble","libc":null},"system":{"name":null,"release":null},"cpu":null,"openssl_version":null,"setuptools_version":null,"rustc_version":null,"ci":null}
|
Release files / longtrainer-1.4.0-py3-none-any.whl
| Download URL | longtrainer-1.4.0-py3-none-any.whl |
|---|---|
| Size | 74.2 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
7eb7f9e40608dcd6f0ec823e7e295351689a8356b6376477cfc36f6692eec8d6
|
|
BLAKE2b-256 checksum How to use checksums |
e8e8d582fc6e40470d3242f275e9586621fc8cd8208450197cdd40430bfca2a0
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
uv/0.9.26 {"installer":{"name":"uv","version":"0.9.26","subcommand":["publish"]},"python":null,"implementation":{"name":null,"version":null},"distro":{"name":"Ubuntu","version":"24.04","id":"noble","libc":null},"system":{"name":null,"release":null},"cpu":null,"openssl_version":null,"setuptools_version":null,"rustc_version":null,"ci":null}
|
Security for longtrainer 1.4.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














