
LoopBrake
Brakes for stuck AI agents.
Stop agent runs that are going in circles, with a guaranteed limit on how often a good run gets stopped.



The problem
AI agents get stuck. They run the same command again and again, re-read the same file, or hit the same error, and they keep spending tokens until a step or budget limit finally stops them.
The usual fixes are blunt: a fixed step limit, or a rule like "stop after the same action 3 times". Set them tight and you kill runs that would have succeeded. Set them loose and you pay for every loop.
The idea
LoopBrake watches a run one step at a time and gives each step a stuck score. When the score crosses a stop line, it stops the run and says why.
The stop line is not guessed. It is set from your own past successful runs, so that at most a chosen share of good runs, for example 5 in 100, would ever cross it. That is a statistical guarantee (split-conformal calibration), not a tuned target.
In v1 the stuck score is simply how long the run has gone on. Two experiments (below) tested smarter scores, and neither beat it on agents they were not tuned on. The stuck signals (repeats, nothing new, same error again) still run, but only to explain why a stopped run looked stuck.
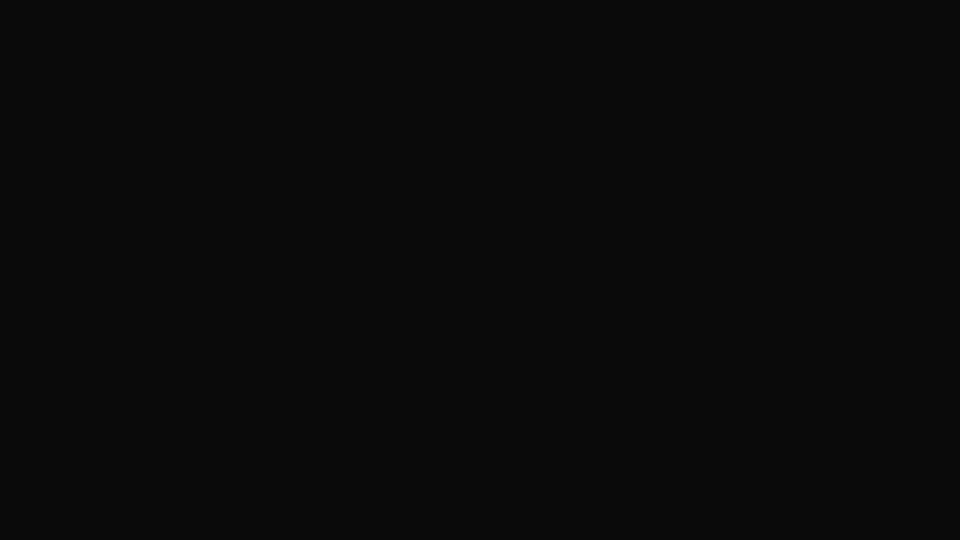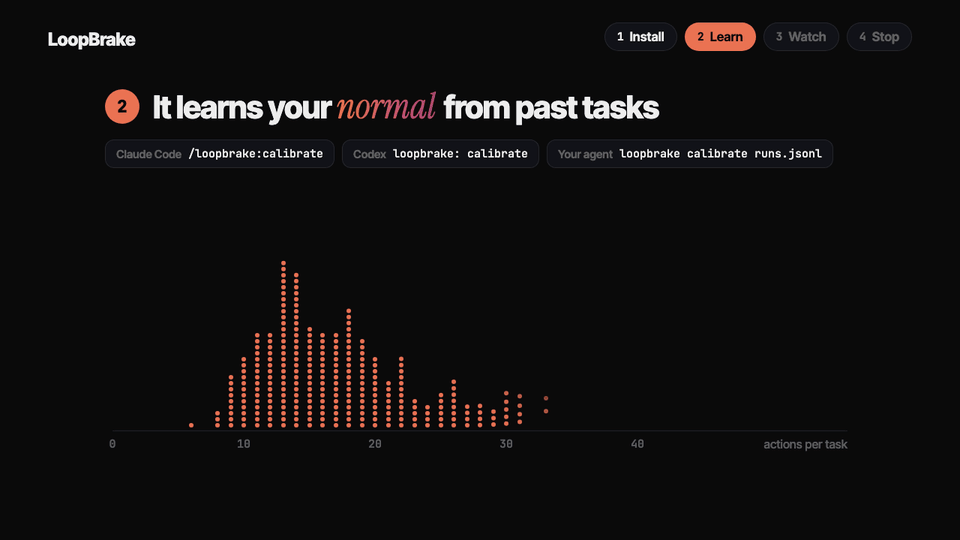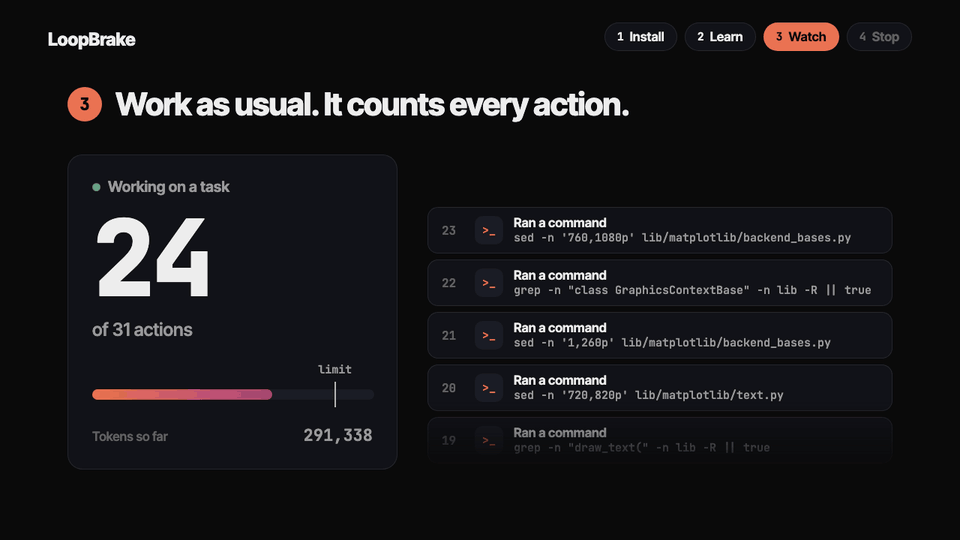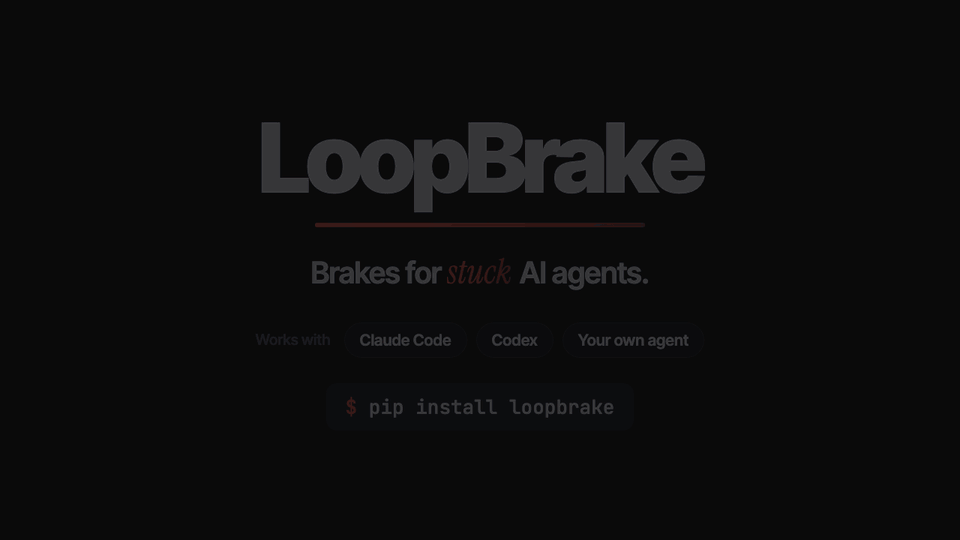
Every command and number here is real: a public SWE-bench run (GPT-5-mini) replayed through
LoopBrake. Its limit was learned with loopbrake calibrate from every finished public run of that
agent, so it is higher than in the example below, which learned from 20.
What a stop looks like
A real run from the public SWE-bench data (GPT-5-mini), replayed through LoopBrake. The agent kept searching the same files for a function and found nothing new:
swe-gpt5mini · matplotlib__matplotlib-25775 · stopped at step 27 of 72 · saved 2,023,115 tokens (84%)
Reason: repeating in 5 of last 5 steps (similar to step 19); nothing new in 2 of last 5 steps (0 of 21 output lines new)

  23  sed -n '760,1080p' lib/matplotlib/backend_bases.py
  24  grep -n "def set_antialiased" -n lib/matplotlib/backend_bases.py || true
  25  sed -n '892,932p' lib/matplotlib/backend_bases.py
  26  sed -n '1,220p' lib/matplotlib/patches.py
  27  grep -n "set_antialiased" -n lib -R || true
More in eval/results/kill-stories.md.
Use it
Install. pip install loopbrake, or uv add loopbrake (PyPI).
No other packages are needed.
1. Wrap your agent. Name what you watch, wrap each tool your agent can call, and run each job inside a task:
import loopbrake

brake = loopbrake.watch("my-agent")

@brake.tool
def search(query):                 # one of your agent's tools
    return f"results for {query}"

with brake.task():                 # one job for your agent
    search("flights to Lisbon")    # your agent calls its tools as usual
Every tool call counts as one action, by itself. Until a limit is set, LoopBrake only watches and
records. Tools can be normal or async (use async with brake.task():).
2. Set the limit, once LoopBrake has watched at least 19 good tasks (a task is good when it ended normally and wasn't stopped):
loopbrake calibrate --project my-agent
No file needed: it learns from the tasks it watched under that name. (Runs saved elsewhere work too:
loopbrake calibrate my_runs.jsonl --project my-agent.)
3. When a task goes past the limit, the next tool call doesn't run. It raises loopbrake.Stopped,
whose message says why in plain words, and so does every later tool call in that task. Let it end the
task, or catch it and tell your user.
Logs. LoopBrake also writes to your app's logs, through Python's logging (the loopbrake
logger): a WARNING with the reason when it stops a task, and an INFO line when a task ends. It stays
silent until your app turns logging on, for example with logging.basicConfig(level=logging.INFO).
Teams of agents. Use one watcher for the whole job, or one per agent:
import loopbrake

# One limit for the whole job: every agent's tools use the same watcher.
team = loopbrake.watch("support-bot")
lookup = team.tool(lambda q: f"results for {q}", name="lookup")
with team.task():
    lookup("refund policy")

# One limit per agent: the researcher's work is its own task, and never counts for the desk.
desk, researcher = loopbrake.watch("desk"), loopbrake.watch("researcher")

@researcher.tool
def find(q):
    return f"results for {q}"

@desk.tool
def ask_researcher(q):
    with researcher.task():
        return find(q)

with desk.task():
    ask_researcher("refund policy")
Tasks running at the same time (threads or async) keep separate counts. The
demo is a bookshop run by two agents, each
with its own limit.
4. See how it's doing.
loopbrake status --project my-agent        # tasks watched, stops, and stops you marked as mistakes
loopbrake feedback last --mistaken         # the last stop was wrong: the limit can only go up
loopbrake dashboard                        # every task, and why any was stopped
Full control. To report each action yourself, use loopbrake.start() and brake.step():
import loopbrake

with loopbrake.start(project="my-agent") as brake:
    decision = brake.step("search flights to Lisbon", "3 results")
    if decision.stop:
        print(decision.reason)
Claude's agent toolkit: pip install "loopbrake[agent-sdk]", then
ClaudeAgentOptions(hooks=loopbrake.agent_sdk.hooks(project="my-agent")).
Everything stays on your machine, in ~/.loopbrake. LoopBrake never uses the network unless you turn
on export (see "Send to your observability tools" below). If something inside it fails, it switches
to watching only. It never crashes or stops your agent because of its own problem.
Use it with Claude Code
Install the plugin. It needs Claude Code 2.1.281 or later and uv.
/plugin marketplace add SahilSelokar/LoopBrake
/plugin install loopbrake@loopbrake
Set it up for the project you are in. LoopBrake looks at how many tool calls your past successful tasks in this project needed, and picks a limit:
/loopbrake:calibrate
LoopBrake is set up for this project.
It will stop a task that goes past <limit> tool calls. That limit comes from your <n> past
successful tasks here: fewer than 1 in 20 good tasks should go past it.
A task is everything Claude does for one message you send. Tool calls made by subagents don't count. From then on, when a task goes past the limit, Claude stops and tells you why:
LoopBrake stopped this task after <limit + 1> tool calls. Based on your <n> past successful tasks
in this project, good tasks almost never need more than <limit> (fewer than 1 in 20 do). This one
also looks stuck: its last few tool calls repeat each other. If it wasn't stuck, run
/loopbrake:mistake, then tell Claude to continue.
| Command | What it does |
|---|---|
/loopbrake:calibrate |
Sets the limit from this project's past tasks (run it again any time) |
/loopbrake:status |
Shows the limit, how many tasks it saw and stopped, and the stops you marked as mistakes |
/loopbrake:mistake |
Tells LoopBrake its last stop was wrong. The next calibration counts that task as a long good one, so the limit can only go up. |
/loopbrake:exclude |
Leaves your last finished task out of future calibration (for example, a task that went badly) |
/loopbrake:dashboard |
Opens the dashboard (below) in your browser; it keeps running in the background. /loopbrake:dashboard stop stops it. |
See the count while you work (optional; plugins can't add a status line themselves). Add this to
~/.claude/settings.json to see LoopBrake: <calls> of <limit> tool calls at the bottom of Claude Code:
"statusLine": {"type": "command", "command": "uvx --offline loopbrake statusline"}
What the promise means here. Each project gets its own limit. On average, fewer than 1 in 20 of
your good tasks will be stopped (5%), as long as your future tasks are like your past ones: the same
kind of work, done the same way. When your work changes, run /loopbrake:calibrate again.
No uv? Install loopbrake==0.5.0 with pip, then set LOOPBRAKE_CMD to its full path, quoted,
in the environment Claude Code starts from: export LOOPBRAKE_CMD="'$(which loopbrake)'".
Troubleshooting. If /loopbrake:status says "No tasks recorded here yet" after you have worked in the
project, the hooks are not running. Start Claude Code with claude --debug and look for loopbrake
hook errors, and check that uv is on the PATH Claude Code sees. The plugin never blocks Claude
because of its own problem; it just stops recording.
Use it with Codex
Install the plugin for OpenAI's Codex CLI. It needs a recent Codex CLI and uv.
codex plugin marketplace add SahilSelokar/LoopBrake
codex plugin add loopbrake@loopbrake
Then open Codex and type /hooks to trust LoopBrake's hooks. Codex runs a plugin's hooks only
after you trust them, and until then it skips them without a word. If loopbrake: status gets an
ordinary reply from Codex instead of LoopBrake's status, the hooks aren't trusted yet.
Set it up for the project you are in by sending this as your whole message:
loopbrake: calibrate
Codex has no slash commands for plugins, and its sandbox keeps commands from writing LoopBrake's files, so LoopBrake's commands are messages that its hook answers:
| Message | What it does |
|---|---|
loopbrake: calibrate |
Sets the limit from this project's past Codex tasks (send it again any time) |
loopbrake: status |
Shows the limit, how many tasks it saw and stopped, and the stops you marked as mistakes |
loopbrake: mistake |
Tells LoopBrake its last stop was wrong; the limit can only go up |
loopbrake: exclude |
Leaves your last finished task out of future limits |
loopbrake: dashboard |
Opens the dashboard (below); loopbrake: dashboard stop stops it |
loopbrake: help |
Lists these |
What a stop looks like. When a task goes past the limit, the tool call that crossed it gets LoopBrake's reason instead of its result, and every later tool call in that task is refused, even ones Codex had already lined up in parallel. Codex then ends the task and relays the reason, in the same words as in Claude Code.
How it differs from Claude Code: Codex and Claude Code tasks in the same folder get separate limits; Codex reports no tool-call durations, so the dashboard shows none for Codex; and Codex tasks don't nest inside a Codex trace when exported.
How this was checked. On Codex CLI 0.160.0 running a local model, without an OpenAI account: installing, the stop, the refused calls, the commands, and learning the limit from Codex's own history. Two things weren't: how a GPT model behaves after a refused call (it may try a few more before it ends the task; refused calls never run), and Codex's helper agents, whose calls LoopBrake is built never to count. If either surprises you, please open an issue.
See what it did: the dashboard
In Claude Code, run /loopbrake:dashboard; in Codex, send loopbrake: dashboard. In a terminal:
loopbrake dashboard
This opens a page in your browser, written so that anyone can follow it, coder or not. It updates while your agent works, and it comes in a light and a dark theme that follow your computer's setting. Each thing your agent does (a tool call) is called an action.
- Home: one sentence on how things are going, each task working now with its progress toward the limit, recent stops with the reason in a few words, your projects, and stops per day.
- Tasks: every task, filterable by status and project, and searchable.
- A task: why it stopped, as a picture of your past tasks next to the limit; what it kept doing ("Ran the same command 6 times"); its actions over time (point at the chart to read each one); and every action in plain words ("Ran a command", "Read a file"). On a stopped task, "It wasn't stuck"; on a finished one, "Leave out of future limits". Each asks before it changes anything.
- A project, shown by its folder name: its limit and what that promises, the past tasks it came from, and, for Claude Code projects, "Set the limit again".
- Settings: the theme, sending to your tools (next section), how LoopBrake works, and what each word means. A "?" next to each idea explains it in one line.
Options: --port N for a fixed port, --no-open to skip opening the browser, --days D to read
only the last D days, --background to keep it running and get your terminal back (running it again
reopens the same one), and --stop to stop it.
Only your computer can open it. The server listens on 127.0.0.1 only. Each start prints an address with a new secret key; the page swaps it for a cookie, and every request needs it. Requests from other sites are refused, and the page loads nothing from the internet.
Send to your observability tools
LoopBrake can send each finished task to Datadog, Grafana, Honeycomb, Langfuse, Jaeger or any OpenTelemetry Collector, as OpenTelemetry traces and counters (OTLP over HTTP, as JSON). It is off until you turn it on, in the environment your agent runs in:
export LOOPBRAKE_EXPORT=otlp
export OTEL_EXPORTER_OTLP_ENDPOINT=http://localhost:4318
What is sent. One trace per task: the task, each tool call inside it, and the stop with a short
reason code. Plus four counters: tasks, stops, stops marked as mistakes, and tokens (when the agent
reports them). Commands, project names and the stop explanation are not sent unless you also set
LOOPBRAKE_EXPORT_CONTENT=1; without it, a project is named by a short hash. Only tasks that start
while export is on are ever sent.
It never slows your agent. Each task is sent in the background after it ends, or right after
LoopBrake stops it. If the tool can't be reached, the task waits and goes with the next send.
loopbrake export --test sends one test span, and loopbrake export --pending sends now. The
dashboard's Export screen shows the last result.
With Claude Code's own tracing on, LoopBrake's task shows up inside Claude Code's trace.
| Tool | Settings |
|---|---|
| OpenTelemetry Collector | OTEL_EXPORTER_OTLP_ENDPOINT=http://localhost:4318 |
| Datadog | OTEL_EXPORTER_OTLP_ENDPOINT=https://otlp.datadoghq.com (or your site's), OTEL_EXPORTER_OTLP_HEADERS=dd-api-key=<key> |
| Grafana Cloud | your stack's OTLP endpoint, OTEL_EXPORTER_OTLP_HEADERS=Authorization=Basic%20<base64 of instance:token>, OTEL_EXPORTER_OTLP_METRICS_TEMPORALITY_PREFERENCE=cumulative |
| Honeycomb | OTEL_EXPORTER_OTLP_ENDPOINT=https://api.honeycomb.io, OTEL_EXPORTER_OTLP_HEADERS=x-honeycomb-team=<key> |
| Langfuse | OTEL_EXPORTER_OTLP_ENDPOINT=https://cloud.langfuse.com/api/public/otel, OTEL_EXPORTER_OTLP_HEADERS=Authorization=Basic%20<base64 of public key:secret key>, OTEL_EXPORTER_OTLP_METRICS_ENDPOINT=none (traces only) |
| Jaeger | OTEL_EXPORTER_OTLP_ENDPOINT=http://localhost:4318, OTEL_EXPORTER_OTLP_METRICS_ENDPOINT=none (traces only) |
| Phoenix, and other tools that only take protobuf | send to an OpenTelemetry Collector, which forwards to them |
Counters are sent as changes since the last send (delta), which is what Datadog needs. Grafana needs running totals, hence its cumulative setting.
How this was checked. Each tool's settings were checked against its published intake rules, by small stand-ins in the tests, and against a real OpenTelemetry Collector and Jaeger. Not against live accounts. If a live service disagrees, please open an issue.
Phase 1 results
Before building the product, we tested the idea offline. We replayed 2,979 recorded runs from six agent groups, on coding tasks (SWE-bench Verified) and customer-service tasks (τ-bench).
| Finding | Result |
|---|---|
| The guarantee held: good runs stopped by the chosen method, on every test group | at most 4.9% (limit 5%) |
| The naive rule "stop at 20 steps or 3 repeats" stops good runs | 99.3% (Devstral), 29.1% (GPT-5-mini) |
| Tokens saved by a calibrated step limit (GPT-5-mini, 100 past runs) | 11.2% |
| Tokens saved by the stuck signals (same setting) | 12.9% |
| Extra saving from stuck signals over the step limit, with 95% interval | SWE-bench +1.5% [−9.7%, +13.2%] τ-bench +0.9% [−3.1%, +5.0%] |
Verdict: NO-GO. The cheap stuck signals do not clearly beat a calibrated step limit. Following the plan set in advance, a second experiment tested a progress judge (below). For comparison, FailFast, a trained monitor, reports 14.6–20.4% saved at 5% of good runs stopped. Its threshold was set on the same data it reports on, though, so that 5% is a target, not a guarantee.
Full report: eval/results/results.md
Progress judge: also NO-GO
Counting repeats is not the same as understanding a step, so the second experiment asked a fast
hosted decision model, Jev (jev-1.13.0), about every step: did this
move the agent closer to finishing? and what kind of step was it? Savings are counted net:
every token the judge reads is subtracted. The method was chosen on one agent and committed
(0827ece) before any other agent was judged.
| Dataset | Extra net saving over the step limit, with 95% interval |
|---|---|
| SWE-bench (GPT-5-mini) | −6.3% [−18.9%, +1.9%] |
| τ-bench (4 groups) | −4.2% [−8.2%, −1.5%] |
What we learned:
- A threshold tuned on one agent did not travel. The chosen method asked the judge only when the cheap score passed a level set on Devstral's long runs. On the other agents that level was almost never reached (0–0.3% of steps), so the method rarely stopped anything.
- A judge on every step is expensive. On short customer-service tasks it used about as many tokens as the agent itself.
- Even ignoring its cost, the judge did not spot stuck runs better than counting steps: for example 7.3% vs 9.3% of tokens saved on GPT-5-mini.
- The guarantee held on every group. The whole experiment took 73,812 judgments, for about $3.91.
Full report: eval/results/judge/results.md
How the results are kept honest
- Chosen in advance. The method was picked using one agent's runs and committed before any
test runs were scored (commits
8b8eaf3and, for the judge,0827ece). - Mistakes stay visible. The first results were committed exactly as they came out, including a
flaw in how runs were split (
e655b96). The fix is a separate, documented commit (76e8cdc), with before-and-after numbers in CORRECTIONS.md. - Tested on unseen runs. The stop line is always checked on runs it was not set from.
- Reproducible. Every number above comes from
eval/results/and comes out identical on every run.
How the guarantee works
- Each step gets a stuck score. A run's score is the highest score it reaches.
- Take n past successful runs and sort their scores. The stop line is the k-th smallest score, where k = ⌈(n + 1)(1 − α)⌉ and α is the share of good runs you accept losing (for example 5%).
- A new successful run then crosses the stop line with probability at most α.
With α = 5%, LoopBrake needs at least 19 past successful runs. With fewer, it only watches and never stops anything.
The guarantee holds when new runs look like the past ones (same agent, same kind of tasks), and when the past runs come from different tasks. We learned the second condition the hard way: see CORRECTIONS.md.
Reproduce
Requires uv and Python 3.11+.
git clone https://github.com/SahilSelokar/LoopBrake && cd LoopBrake
uv run pytest                        # the test suite
uv run python eval/fetch.py          # one-time download, about 450 MB, into ~/.loopbrake/data
uv run python eval/run.py --final    # about 1 minute; writes eval/results/
The progress judge needs a Typesafe API key in TYPESAFE_API_KEY (or in
~/.loopbrake/typesafe_key). Judging every public step costs about $4:
uv run python eval/tasks.py                              # task texts for the judge
uv run python eval/judge.py --group swe-devstral         # one group at a time; resumable
uv run python eval/judge_eval.py --final                 # reads stored answers only; writes eval/results/judge/
Repository layout
src/loopbrake/   the package: brake, stop-line rule, run readers, Claude Code hooks, dashboard and export
                 (standard library only)
plugin/          the Claude Code plugin: hooks, slash commands and the launcher; .claude-plugin/ is the marketplace
codex-plugin/    the Codex plugin: hooks and the same launcher; .agents/plugins/ is its marketplace
eval/            the experiments: fetch.py downloads the data, run.py replays runs, judge.py asks the
                 progress judge, judge_eval.py scores its answers; results/ holds the published numbers
specs/           design: constitution, roadmap, and the spec, plan, research and tasks of each experiment
tests/           tests, including a check of the guarantee on simulated data
liveness.py      the original naive rule, kept as the baseline
Roadmap
| Phase | What | Status |
|---|---|---|
| 1 | Experiment: does it work on real runs? | Done: NO-GO for cheap signals |
| 1b | Progress judge: a hosted decision model judges whether each step moved the run forward | Done: NO-GO |
| 2 | Python package: pip install loopbrake; a stop line on run length, with a guarantee and a readable reason |
Done: v0.1.0 on PyPI |
| 3 | Claude Code plugin: stop stuck turns live, calibrated on your own history | Done: v0.2.1 |
| 4 | Observability: live dashboard, plus export to Datadog, Grafana and others via OpenTelemetry | Done: v0.3.0 |
| 4b | Codex CLI plugin: the same live stops for OpenAI's Codex | Done: v0.4.0 |
| 4c | Your own agents, simply: wrap the tools, mark each task, one brake per agent | Done: v0.5.0 |
| 5 | Launch: a demo agent, the public release and a video | Planned |
The full plan is in specs/roadmap.md.
Status
v0.5.0 is on PyPI (pip install loopbrake), with plugins for Claude Code and Codex CLI in this
repository. The stop rule is a stop line on run length, set from your own past successful runs, with
a guaranteed limit on stopping good runs. v0.5.0 makes it simple in your own agents: wrap the tools,
mark each task, and give each agent in a team its own brake. Next: the launch, and integrations with
agent frameworks (help wanted).
License
MIT. One test fixture is a trimmed τ-bench run, used under τ-bench's own MIT license (see tests/fixtures/NOTICE.md).
1 maintainer

Metadata
1 maintainer
Release files for loopbrake 0.5.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| loopbrake-0.5.0.tar.gz | 196.4 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| loopbrake-0.5.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 401.2 kB
Release files / loopbrake-0.5.0.tar.gz
| Download URL | loopbrake-0.5.0.tar.gz |
|---|---|
| Size | 196.4 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
5585a6a995f78d83d0f8470df71915706e57341aaee9e9377d78b8c1bea06b39
|
|
BLAKE2b-256 checksum How to use checksums |
28e01d2726747a020a8a687fda2757935eab2a32856ca6d78ad512007fcae094
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
uv/0.12.22 {"installer":{"name":"uv","version":"0.12.22","subcommand":["publish"]},"python":null,"implementation":{"name":null,"version":null},"distro":{"name":"Ubuntu","version":"24.04","id":"noble","libc":null},"system":{"name":null,"release":null},"cpu":null,"openssl_version":null,"setuptools_version":null,"rustc_version":null,"ci":true}
|
Release files / loopbrake-0.5.0-py3-none-any.whl
| Download URL | loopbrake-0.5.0-py3-none-any.whl |
|---|---|
| Size | 204.8 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
39dc843dfbeebf4ee24f31903c9b1a4e40458618951bf993e53de5b426e459d0
|
|
BLAKE2b-256 checksum How to use checksums |
ce98b87255c34340e67e72da567d9e0c3960430b4aeaec88e3d32924b1218485
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
uv/0.12.22 {"installer":{"name":"uv","version":"0.12.22","subcommand":["publish"]},"python":null,"implementation":{"name":null,"version":null},"distro":{"name":"Ubuntu","version":"24.04","id":"noble","libc":null},"system":{"name":null,"release":null},"cpu":null,"openssl_version":null,"setuptools_version":null,"rustc_version":null,"ci":true}
|














