
lyNNX: Deep RL in Flax NNX


lyNNX is still experimental. Expect breaking changes!
lyNNX is a repository of deep reinforcement learning (deep RL) algorithms and environments, written completely in JAX + Flax NNX for end-to-end GPU-accelerated training.
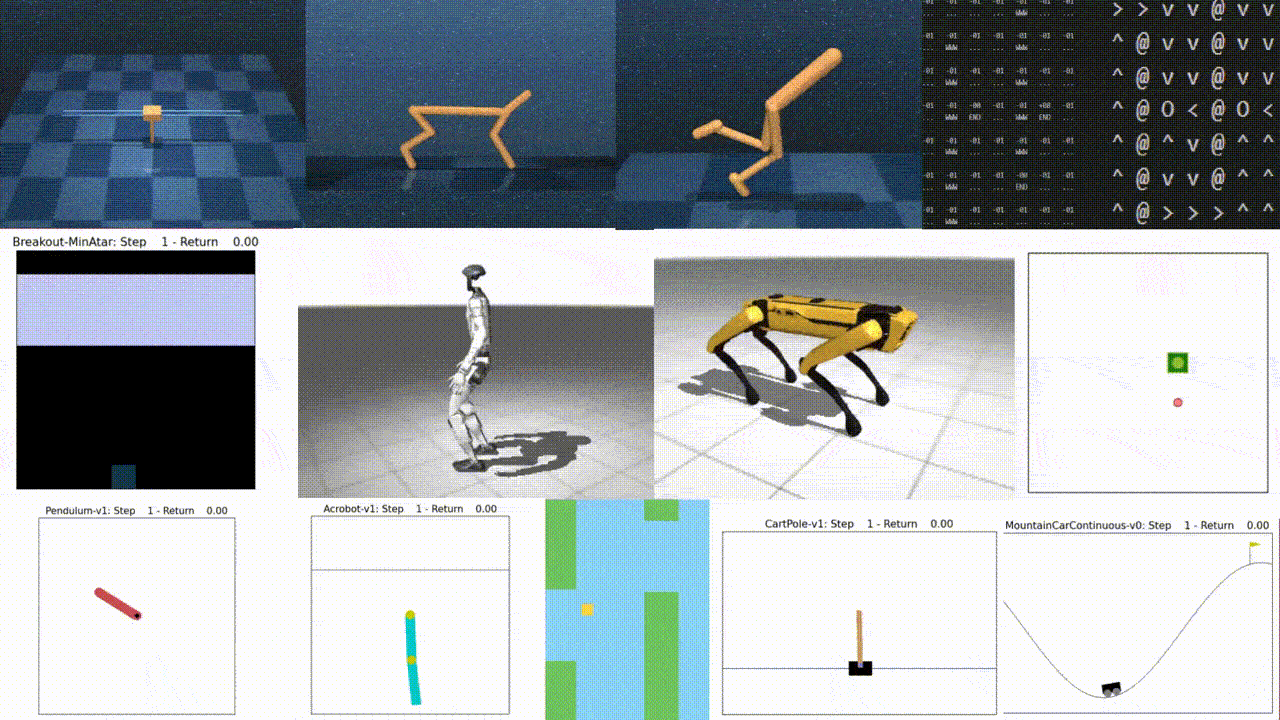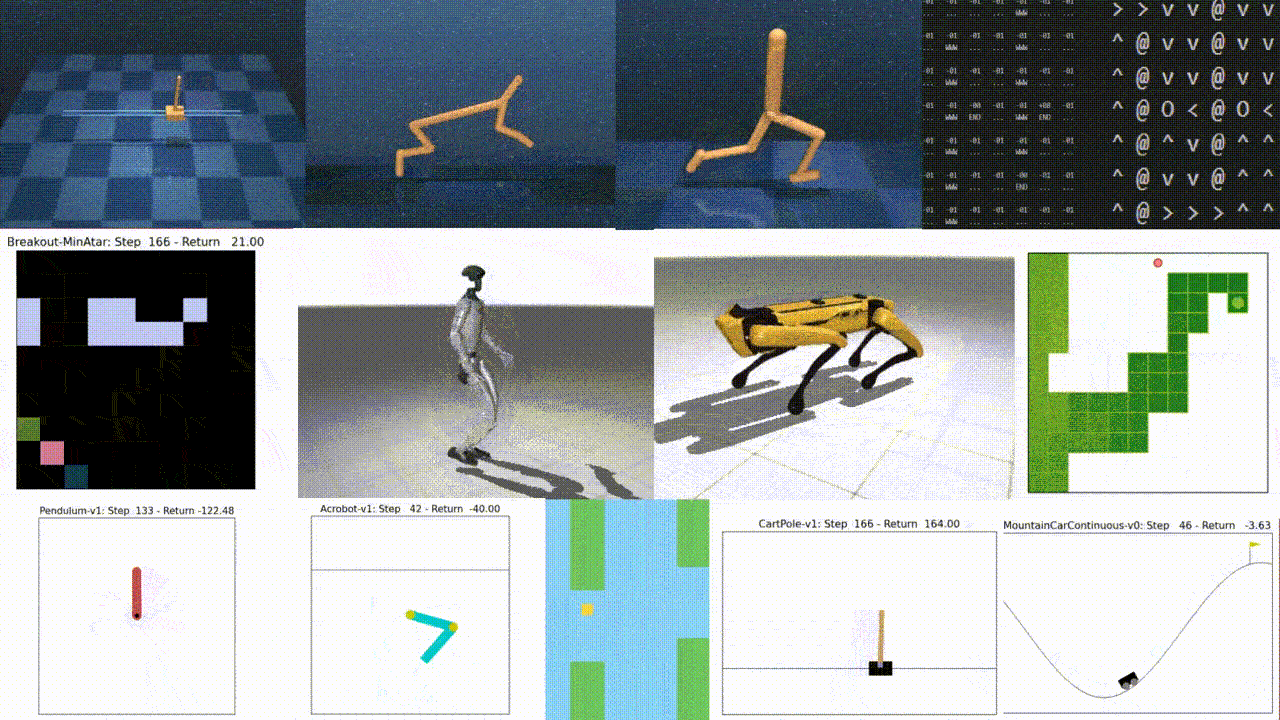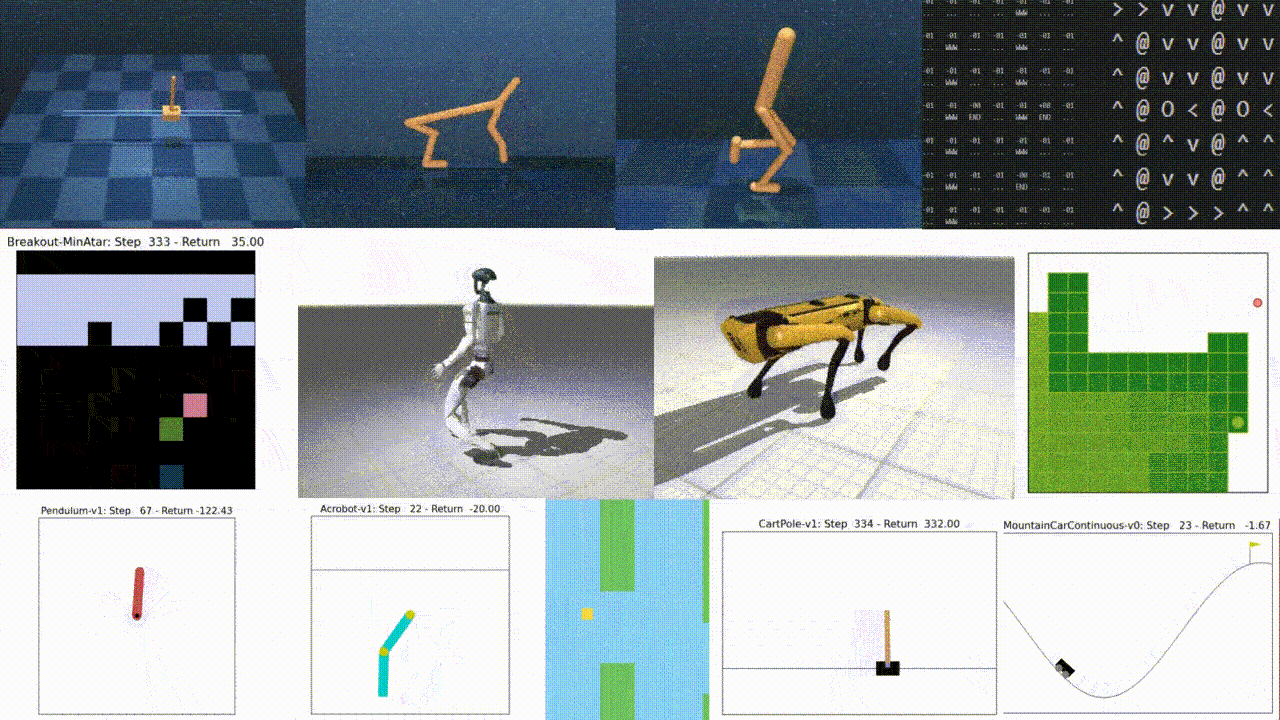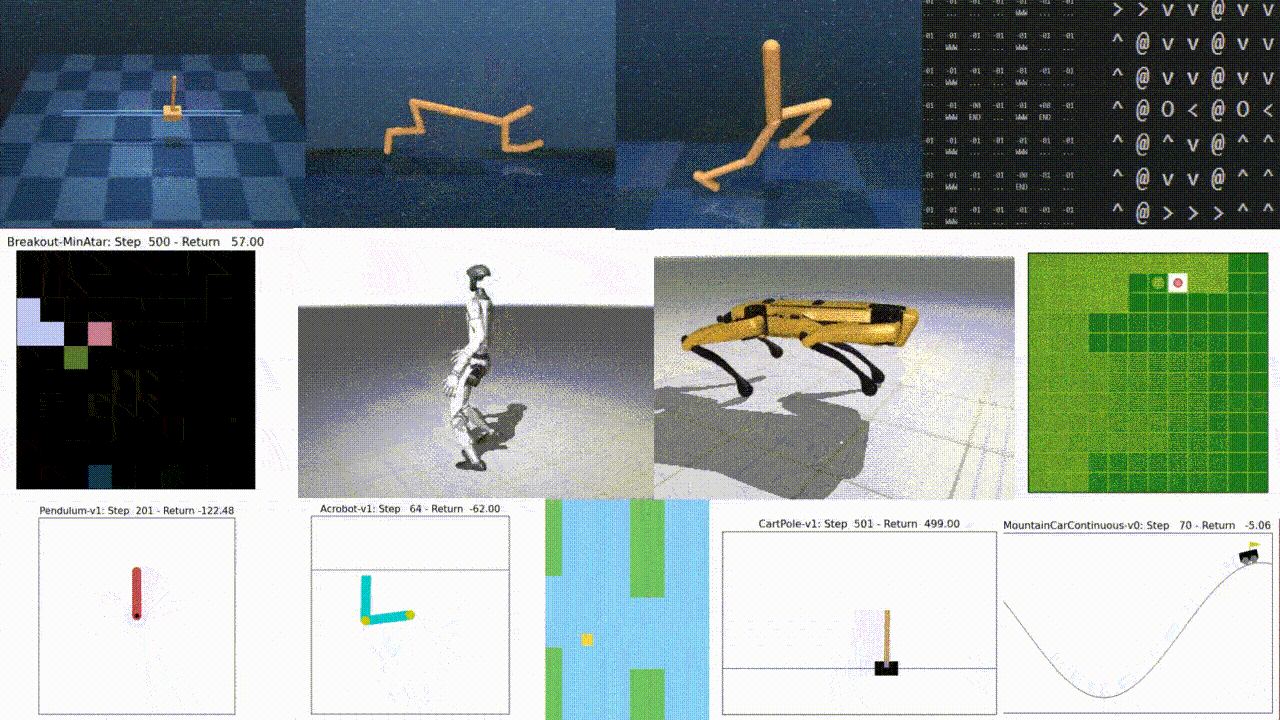
Train any environment, instantly. Algorithms are designed to support, whenever possible, any observation space and any action space — whether discrete, continuous, or a mix of both. Wrappers allow plug-and-play use with popular existing JAX RL environment libraries: Gymnax, Jumanji, Brax, Mujoco Playground, etc.
Full customizability, without editing source code. Pass your own hyperparameters, network architectures/user-defined classes, optimizers, etc. Customize environments with the many built-in wrappers or create your own. Turn any (non-structural) hyperparameter into a schedule based on training progress.
Rollout, evaluate, or visualize your agent in a single function call. Utility functions are included to simplify common use cases, allowing you to focus on what matters:
timesteps, final_states, final_infos = rollout(rngs, VmapWrapper(env), actor, iters=32, env_batch_dims=256)
returns, lengths = evaluate_episodes(rngs, env, actor, episodes=256, n_envs=256, eps_steps_limit=1000)
visualize_pygame(rngs, env, actor)
Modern, Pythonic API with Flax NNX. Use JAX transformations directly on native Python objects, keeping the traditional mutability and reference semantics. This simplifies state management, and brings the interface more in line with more conventional PyTorch paradigms. Why Flax NNX?
JIT-compile the entire training loop. Code is written 100% in JAX for massive parallelization on the GPU. All memory buffers are kept completely on device, eliminating host-device transfer bottlenecks. Run experiments at 100k+ steps per second, allowing for rapid iteration and troubleshooting.
Features Implemented
Algorithms include:
- Tabular Q-Learning, w/ rounding or linear interpolation for continuous observations
- Deep Q-Learning (DQN), w/ Double DQN add-on
- Advantage Actor-Critic (A2C)
- Proximal Policy Optimization (PPO), w/ action clipping or tanh-based squashing
- Twin Delayed Deep Deterministic Policy Gradient (TD3)
- Soft Actor-Critic (SAC), w/ automatic entropy adjustment
Environments include:
- Gridworld: place walls and endpoints, set tile rewards; visualize Q table as arrows.
- Flappy Bird: includes a fully JIT-compilable renderer written in JAX, allowing for end-to-end GPU-accelerated training with image observations.
- More to come! WIP 2D Soccer environment (image observations, can be MARL).
Getting Started
It is highly recommended to check out the tutorial notebook for a more complete guide.
Additionally, check out examples/experiements for sample scripts.
The rest of this section will act as an abridged summary.
Installation
Prerequisites: Python 3.12 or later.
Install JAX. Installation details vary between accelerator devices; see https://docs.jax.dev/en/latest/installation.html. For CUDA 12:
pip install -U jax[cuda12]
Install lyNNX from PyPI:
pip install lynnx
To use lyNNX with external environment libraries, install them using:
pip install lynnx[gymnax,jumanji,playground,viz]
Basic Usage
Run a sample experiment script (see examples/experiements):
python examples/experiments/dqn_cartpole_gymnax/dqn_cartpole_gymnax.py
Or, write your own script:
from flax import nnx

from lynnx.algos import dqn
from lynnx.envs.wrappers import VmapWrapper
from lynnx.envs.utils import evaluate_episodes

from lynnx.envs.gymnax import GymnaxWrapper
import gymnax

gymnax_env, gymnax_env_params = gymnax.make("CartPole-v1")
env = GymnaxWrapper(gymnax_env, gymnax_env_params)

algo = dqn.DQN(VmapWrapper(env), hyperparameters=dqn.Hyperparameters())
train = nnx.jit(algo.train, static_argnames=('steps',), donate_argnames=('training_state'))

rngs = nnx.Rngs(0, env=1, actions=2, params=3, optimize_samples=4)
training_state = algo.init_training_state(rngs, prefill_steps=5000)
training_state, metrics = train(rngs, training_state, steps=100_000)

actor = algo.make_actor(training_state.networks, epsilon=0)
evaluate = nnx.jit(evaluate_episodes, static_argnames=('env', 'episodes', 'n_envs'))

returns, lengths = evaluate(rngs, VmapWrapper(env), actor, episodes=256, n_envs=256)
print(f"Episode Return: mean={jnp.mean(returns)} std={jnp.std(returns, ddof=1)}")
print(f"Episode Length: mean={jnp.mean(lengths)} std={jnp.std(lengths, ddof=1)}")
Roadmap
Short-term plans include:
- Add better logging utilities and support for Weights & Biases.
- Properly benchmark performance/speed and compare with other libraries.
- Refine the environment API to be more flexible. Specifically, we should support states that persist throughout the entire training process, allowing for curriculum learning and reducing compile times for reset states caching.
- Support multi-device training with the Anakin Podracer architecture.
- Add more DQN add-ons: n-step returns, dueling networks, NoisyNets
- Add support for discrete action spaces in SAC.
- Integrate existing 2D Soccer environment (image observations, can be MARL).
Possible mid-to-long term features include:
- Prioritized experience replay (PER). This affects all off-policy algorihms: DQN, TD3, and SAC.
- QR-DQN, completing all of the Rainbow DQN enchancements.
- Support for CPU-based environments using the Sebulba Podracer architecture.
- More algorithms! Model-based algorithms: Dreamer-v3, MuZero.
1 maintainer

Metadata
1 maintainer
Release files for lynnx 0.0.1.post1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| lynnx-0.0.1.post1.tar.gz | 76.9 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| lynnx-0.0.1.post1-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 170.3 kB
Release files / lynnx-0.0.1.post1.tar.gz
| Download URL | lynnx-0.0.1.post1.tar.gz |
|---|---|
| Size | 76.9 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
2131f60ce669f76c99513a1631ecfea25cd9850878517f7e750f20c2926cc5b9
|
|
BLAKE2b-256 checksum How to use checksums |
d429b0022cab91ffff76ffb5787abd899bce3ff51b172a855c35ae5de8134bbb
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.13.13
|
Release files / lynnx-0.0.1.post1-py3-none-any.whl
| Download URL | lynnx-0.0.1.post1-py3-none-any.whl |
|---|---|
| Size | 93.4 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
4a8e063e49bef883657fc2a013188cfa1b606bc1297a68fe35142f4e3991bb0a
|
|
BLAKE2b-256 checksum How to use checksums |
c884a447ad0f1f995f645ed31c379c9a55a208c1dc14e553696ef57c80d38d39
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.13.13
|














