
Maintainability Agent
A deterministic, offline maintainability audit whose output is a bounded work order for an AI coding agent — a copy-paste prompt, per finding, that says fix exactly these and refactor nothing else. Chat-primary; CLI for CI. Version 3.6.1.
Languages parsed: Python, Java, C, C++, C#, Go, Rust, PHP, Ruby, Swift, COBOL, Fortran (free-form and fixed-form), and the JS/TS/HTML family — each by a scanner written for it, and measured with that language's own reading of what a branch is, checked construct-by-construct against an independent implementation. What that means per language.
pip install maintainability-agent          # CLI + library
pip install "maintainability-agent[mcp]"   # optional local MCP server for chat / IDE hosts
cp -r skills/maintainability-agent ~/.claude/skills/   # Claude Code slash command
Install the analyzer pool too, or you get the built-in tier. This tool
prefers established analyzers and falls back to its own detectors when none is
present. The fallback is honest — the report says Estimate source: built-in detectors and the coverage section names what nothing examined — but it is a
weaker reading than the tool is capable of, and a first run without these is
the commonest reason it looks thin.
pip install cohesion complexipy flake8 fortitude-lint interrogate lizard \
  multimetric mypy pydocstyle pylint radon ruff vulture
npm install -g jscpd eslint            # duplication + JavaScript/TypeScript
brew install pmd checkstyle spotbugs   # JVM languages, optional
Unpinned on purpose: this is the exact set CI installs and calibrates against,
and test_the_readme_names_the_analyzer_pool_ci_installs fails if the two ever
disagree. Nothing here is required — the audit runs without any of it and tells
you what it could not measure.
One command to a work order. A config file is the whole setup — with one present, nothing is asked and nothing is written into your tree:
curl -O https://raw.githubusercontent.com/marshallguillory86/maintainability-agent/main/maintainability-audit.example.json
maintainability-audit --config maintainability-audit.example.json \
  --output report.md --prompt-output prompt.md
prompt.md is the bounded work order: the findings worth fixing, in order,
each with its location, why it matters and the command that verifies it — and
the standing rule that nothing else gets refactored. Paste it into your agent.
report.md is the evidence behind it. The prompt is the product.
Want to see the output before pointing it at your own code?
examples/demo is a two-module order system with real
problems in it — an overgrown pricing function, a money path nothing tests, and
a block duplicated between billing and invoicing. Four items, three finding
classes, a copy-paste prompt each, and it reads in under a minute. The work
order it produces is checked in at
expected-prompt.md.
Without --config, an interactive run asks the first-run questions instead —
analyzer pool, depth, licence policy, whether to run your suite — because those
are choices this tool will not make on your behalf.
Executive summary
Agents write code faster than anyone can review it. Not measurably worse code — this project tested that claim about itself and retracted it — just more, arriving faster than trust can accumulate. Linters and quality dashboards catch some of the resulting slop. None of them ship the one thing that actually closes the loop: a bounded prompt back to the agent, scoped to the findings, that forbids unbounded rewrites.
That prompt is the product. Everything else — the scanner, the ISO/IEC 25010-inspired 0–5 score, the analyzer pool, the semantic and economic signals — exists to aim it. Remove the prompt and what's left is a worse version of tools that already ship.
What 1.0 guarantees:
- Deterministic and local. Same tree, config, pinned analyzer versions and history in → same evidence, findings and score out. The analysis performs no network access and invokes no LLM, and this agent does not transmit your source. Every report states what it examined and produced — files, declarations, findings, bounded work items — all computed with no model call: work a metered agent never has to do. Third-party analyzers it may spawn (eslint, jscpd, lizard) are not network-sandboxed — this process does not police whether they phone home; install them for an air-gapped run.
- One uniform rubric, readable in source, applied to every repository — so "better" and "worse" are not an argument. Calibrated against a query-selected corpus of mature open-source projects; the corpus median earns a B, and A+ is gated, not averaged.
- Honest about evidence. A score is withheld when too little was examined
to support one — a
--changed-onlydiff is not a repository grade, and a shallow clone is not an A. Every reported value names what measured it. - The complete work order is the report; chat/CLI is a bounded UI. The HTML/Markdown report carries the entire backlog with a deterministic copy-paste prompt for each item. The chat surface stays a tight summary so a host's payload cap can never truncate the prompt.
- One setup, three transports. Chat, MCP, and an interactive CLI TTY ask the same first-run questions. A surface that asks a subset is a bug.
Governing intent lives in docs/product-intent.md — that document is authoritative, and this README defers to it wherever the two differ.
Why this exists
The ratio of code-written to code-reviewed has collapsed, and the same speed is the way out: an agent pointed at specific, deterministic findings can fix them at the rate they appear. The loop is measure with no model involved, score against one uniform standard, emit a prompt scoped to those findings only, and hand it over. Step three is the product.
Who does the checking matters as much as what it checks. An author is never the independent check on their own work, so a platform that generates code and grades it is producing a self-assessment. This writes nothing and runs no model, which is what lets its verdict count as evidence. Since 2.1.0 the work order is itself checked — scope conformance, a dimension ratchet, and an attestation record — and those checks read a diff's shape, never whether it works.
The full argument, including what this deliberately does not compete on: why this exists and philosophy.
Install
python3 -m pip install maintainability-agent
maintainability-agent --root . --config maintainability-agent.json
Or run from a source checkout without installing:
python3 -m maintainability_audit --root . --config maintainability-agent.json
For an editable dev install and the full local-verification sequence, see CONTRIBUTING.md. Upgrading from 0.x? The scale and the evidence model changed on the way to 1.0 — see docs/migration-1.0.md.
Primary Surface: Chat / MCP
Drive the local MCP process from an IDE assistant or chat host. Call
audit_repository; unset action never audits. An unconfigured repository
(no repository maintainability-agent.json and no user config) returns
setup_needed and audit_ran: false — structured setup choices for analyzer
policy, history consent, economics, test-suite execution, and presentation, and
no report. A configured repository returns choice_needed (run or
reconfigure), also without a report. Answering setup does not start an audit.
action="run" returns the report and its bounded remediation prompt to the
conversation. record_history=None follows the persisted first-run consent and
always appends to an existing history; an explicit true or false wins.
python3 -m pip install "maintainability-agent[mcp]"
maintainability-agent mcp --allow-root /absolute/path/to/repository
Presentation is exactly three choices — chat, a Markdown file, or a single-file HTML report. Where to save is asked only after a file format is chosen, and no report file is written without that choice. See chat workflow help and IDE and agent integration.
Automation / CI: CLI
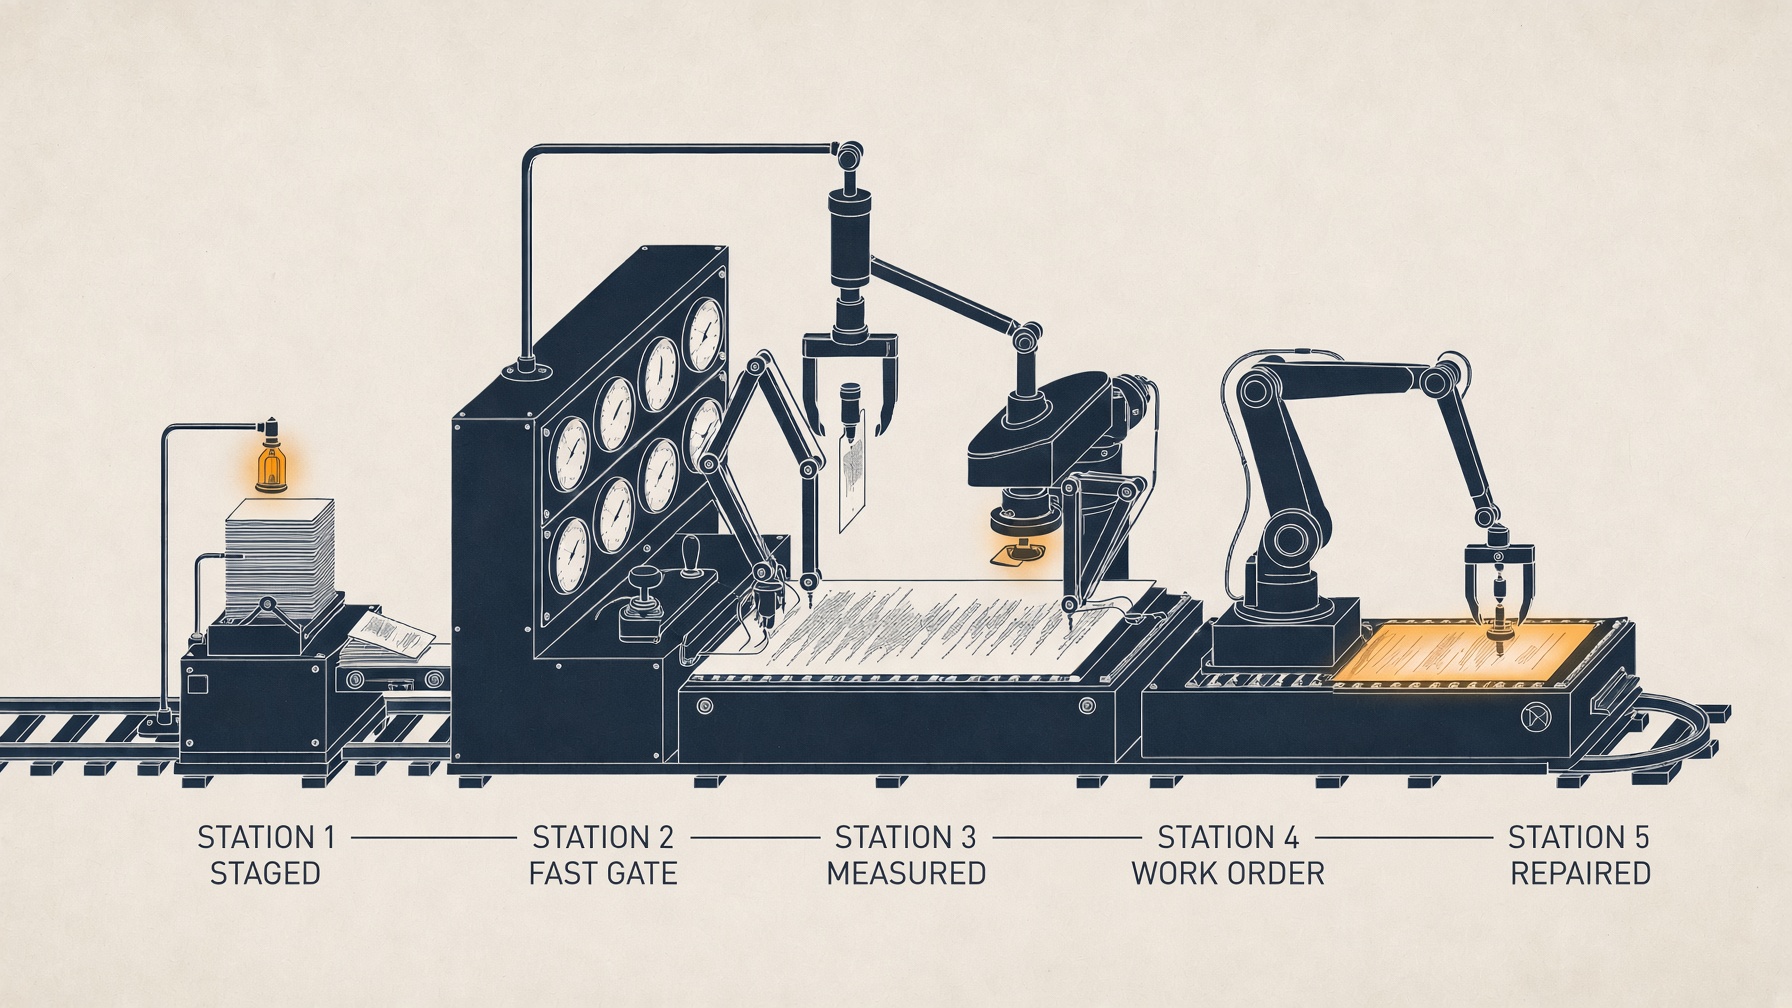
Use the CLI for scripts, repeatable automation, and CI gates. Copy the example
config to your repo root as maintainability-agent.json, then:
maintainability-agent \
  --config maintainability-agent.json \
  --fail-on-gate \
  --output maintainability-report.md \
  --prompt-output maintainability-remediation-prompt.md \
  --comment-output maintainability-pr-comment.md \
  --sarif-output maintainability.sarif
--fail-on-gate fails CI on hard gates only (a missing README, an undocumented
test command, a breached threshold) — never on a letter grade, and never on a
withheld estimate. For PR work, add --changed-only main...HEAD to audit the
diff; on a change too small to support a rate, the estimate and grade are
withheld and the scope is named as the reason.
Checking that the agent did the work
The work order tells an agent to fix exactly these findings and refactor nothing else. Four flags check that the diff obeyed it — reading its shape, never whether it works:
maintainability-agent \
  --config maintainability-agent.json \
  --conformance main...HEAD \
  --fail-on-out-of-scope \
  --fail-on-regression \
  --attestation-output maintainability-attestation.md
--conformance answers two questions separately — did the diff stay in
scope, and did it silence nothing — because a change can obey the work
order and still add a # noqa to a finding inside it. --fail-on-out-of-scope
turns that into a CI failure. --fail-on-regression ratchets the dimension
scores against history, with three outcomes rather than two: held, regressed,
and not comparable, because two scans taken under different calibration
cannot be differenced. --attestation-output composes them into one per-change
record, reproducible and not signed — a check nobody ran renders as not
asked, never as passed.
Each flag in full, including --transformation:
docs/cli.md. Why this was the hole under the product's central
claim: the roadmap.
During the loop, not only after it
The gate above runs once the work is done. Two flags run while it is still in the author's hands, and neither produces a score — a diff and a single file both lack the population a rate needs.
maintainability-agent --check src/thing.py < proposed.py   # while writing
maintainability-agent --install-precommit-hook             # before committing
--check PATH answers about content on stdin. No repository, no git, no
scan; PATH names the content and is never opened. Pass file content, not a
diff — a piped diff is refused in every language, by its format rather
than by a parser, and says so rather than reading as clean; so does a
language with no scanner. Beyond that, only Python's content is parsed:
a brace language's invalid source is not detected, because zero
declarations is not evidence of a parse failure and marking valid files
unparsed would be worse than the silence. In text it is silent while you have room
and speaks once a declaration nears its limit — on any budget it can be
failed on, length or cyclomatic or cognitive, not length alone.
--format json carries the remaining budget for every declaration whether
or not it is close, per budget rather than as one number.
--staged scans the git index. Stage half a file with git add -p, keep
typing, and what gets measured is what the commit will actually contain —
reading the working tree is the classic pre-commit bug. It applies no
repository gates, runs nothing, writes nothing, and costs 0.17s here against
the full audit's 266; a hook slower than the author's patience is one they
uninstall. --install-precommit-hook refuses to replace a hook it did not
write and honours core.hooksPath. It pins the interpreter that installed it by
absolute path, so re-run it if that virtualenv moves.
Both exit 1 on a breach and 0 silently, and both take --format json.
What it analyzes
The deterministic scanner reads code from your repo (no LLM calls) and produces signals on:
- largest files (configurable warn/fail thresholds)
- function size and complexity — exact ranges for Python via
ast, and bounded ranges for every other parsed language, each measured with that language's own reading of what a branch is (Language support is the list, so this sentence cannot drift out of step with it) — plus cognitive complexity (nesting-weighted reading cost) - class size, against its own budget (
max_class_lines) - duplicate blocks, and near-duplicate declarations compared structurally so renaming can't hide a copy, each paired with the original to reuse
- unreferenced private declarations (debris nothing can reach)
- competing libraries for one concern (two HTTP clients, two validators)
- configurable risk patterns (
eval(,exec(, TODO/FIXME, custom regex) - expected files / commands / clean-worktree (opt-in hard gates)
- TypeScript semantic facts from a recorded analysis or an
already-installed
tsc, including workspace projects (ADR 003) - test effectiveness from an opted-in suite run and parsed coverage (Class 5, default off — the one place the agent may execute the tree)
- an ISO/IEC 25010-inspired 0–5 estimate per category, and a verified grade — or a disclosed withholding when the evidence is thin.
The analyzer is intentionally conservative and under-reports rather than
over-reports: an unrecognized declaration costs one missed finding, never a
cascade of false ones. Pair it with native tools (ESLint, Ruff, Radon, Semgrep,
SonarQube, Qlty) rather than replacing them — their SARIF folds in via
--sarif-input. Accuracy and limits: docs/language-support.md.
Language support
Be clear-eyed: the tool does not support every language equally, and on an unrecognized language it under-reports rather than fails. Coverage has two layers.
Fourteen languages are parsed as of 2.11.0: Python (1.0), Java (1.0), C (1.1), C++ (1.2), C# (1.3), Fortran (free-form 1.4, fixed-form 1.6), Swift (2.4), COBOL (2.7), Go (2.11), Rust (2.11), PHP (2.11), Ruby (2.11), the JS/TS family, and HTML. Each has a scanner written for it and a documented list of what it misses — a language is claimed only when both exist.
Built-in scanner (always on, no dependencies) — reads function/class declarations, sizes and complexity for a fixed set of languages, and only these:
| Language | How it's measured | Fidelity |
|---|---|---|
Python (.py) |
ast — exact end_lineno |
Exact |
Java (.java) |
dedicated brace-bounded scanner | Bounded; under-reports some constructs |
C (.c, .h) |
dedicated brace-bounded scanner — functions, struct/enum/union |
Bounded; prototypes and macros are not declarations |
C++ (.cpp, .hpp, .cc, .cxx, .hh) |
dedicated brace-bounded scanner — functions, class members, namespaces, templates | Bounded; bodyless declarations are not definitions |
C# (.cs) |
dedicated brace-bounded scanner — methods, constructors, class/interface/struct/record/enum |
Bounded; properties are not declarations |
Swift (.swift) |
dedicated brace-bounded scanner — functions, initialisers, subscripts, class/struct/enum/protocol/actor |
Bounded; extension members carry their type, protocol requirements and computed properties are not declarations |
Go (.go) |
dedicated brace-bounded scanner — functions, methods, type/struct/interface |
Bounded; methods carry their receiver type, interface methods are requirements, function literals inside a body are not seen |
Rust (.rs) |
dedicated brace-bounded scanner — functions, impl and trait members, struct/enum/trait/union |
Bounded; methods carry the type their impl names, trait requirements mint nothing, closures and macro bodies are not read |
PHP (.php, .phtml) |
dedicated brace-bounded scanner — functions, methods, class/interface/trait/enum; markup outside <?php is blanked |
Bounded; methods carry their class, bodyless members mint nothing, heredoc bodies are not masked |
Ruby (.rb, .rake, .gemspec) |
dedicated scanner — methods, classes and modules bounded by end, counted by openers |
Bounded by depth; methods carry their class, blocks and modifier forms discounted, metaprogrammed methods are not seen |
COBOL (.cbl, .cob, .cpy, and .CBL/.COB/.CPY) |
dedicated scanner — PROCEDURE DIVISION paragraphs, bounded by the start of whatever follows; fixed-form card columns read where the layout carries them | Bounded by the next header; level numbers and container programs/sections are not declarations |
Fortran, free-form (.f90, .f95, .f03, .f08, .F90, .F95, .F03, .F08, .pf) |
dedicated keyword-bounded scanner — modules, subroutines, functions, derived types | Bounded by end; measured with Fortran's own branch and nesting reading |
Fortran, fixed-form (.f, .for, .ftn, .F, .FOR, .FTN) |
the same scanner over card-column source; continuations joined, labelled DO loops understood |
Bounded by end or by the loop's label |
JS / TS / JSX / TSX (.js, .jsx, .mjs, .cjs, .ts, .tsx) |
brace/paren depth over a masked copy | Bounded by the declaration's own braces |
HTML (.html) |
same brace scanner (inline <script>) |
Bounded |
| TypeScript (semantic) | a recorded analysis or a locally-installed tsc, workspace projects included |
Type-level facts; unknown when no checker is present |
Any language not in that table — Kotlin, Scala, Elixir, Zig, and the rest — is not parsed for declarations by the built-in scanner. Its files still count toward repo size, but the built-ins produce no function-size, complexity, duplication or dead-code findings for them, and the estimate leans on whatever evidence is available — which is why the report discloses its evidence tier and can withhold the grade.
So: first-class today is Python (and TypeScript for semantics); every other parsed language is bounded-but-real; anything outside the table is only as covered as the analyzer you point at it. Per-language accuracy and limits: docs/language-support.md. Which analyzer covers which language, how the opt-in pool extends coverage past the built-in set, and why COBOL's external tier is empty: docs/adapters.md.
What it produces
Any combination of: maintainability-report.md (or a single-file HTML report),
maintainability-remediation-prompt.md (the bounded prompt),
maintainability-pr-comment.md, maintainability.sarif (2.1.0, for GitHub
Code Scanning), maintainability-baseline.json (for --fail-on-new
incremental adoption), and per-tool agent instruction files
(AGENTS.md, CLAUDE.md, Cursor/Copilot/Windsurf rules) via
--init-agent-standards.
The report is the complete work order. The HTML and Markdown reports carry the whole backlog — every finding with a self-contained, deterministic copy-paste prompt telling the agent to fix only the listed items, keep the patch small, preserve architecture and behavior, add tests where behavior changes, and report false positives instead of rewriting blindly. Chat and CLI render a bounded view — a summary plus the top items and a pointer to the report — so a payload cap can never truncate the prompt.
Scoring standard
One rubric, applied uniformly, published in full at docs/standard.md: the aspects, their weights, the calibration method, and the reference corpus. A score is withheld rather than guessed when the evidence does not support one, and the report says which tier the evidence came from.
Self-audit
The tool runs against this codebase in CI, and the report is checked in at docs/self-audit.md, stamped with the exact source commit it was generated against — a provenance record, not a claim about HEAD.
| Metric | Value |
|---|---|
| Maintainability estimate | 4.5 / 5 |
| Verified grade | B |
| Files scanned | 511 |
| Hard gate failures | 0 |
A B, and the report says why: the grade is verified against the evidence floor of 4.2 rather than the 4.5 point estimate, because an unmeasured aspect prices at 0 when a grade has to be defended. Every threshold gate is opted on for this repository's own CI, so drifting below the bar fails the build rather than the README.
The tool reports warn-band declarations here and they are not treated as defects — see what counts as a defect. Restyling this codebase to raise its own grade is explicitly not work: a tool that games its own metric has broken the only promise that matters.
Platform support
POSIX. Windows is not claimed, for a measured reason. A windows-latest probe
found most failures in three POSIX-only calls: os.fchmod, os.O_DIRECTORY and
os.O_NONBLOCK. The third arrived with the one-handle operator read (D130/D131)
and is now the dominant failure in the probe, which is why the count moved. The
bounded, symlink-refusing write works through a file descriptor, so a validated
path cannot be swapped for a symlink before the write lands — Windows has no
equivalent and the portable rewrite is the hole. An unsupported platform never
buys green by weakening the supported ones.
Invokable skill / slash command
This repo ships a portable skill under
skills/maintainability-agent/, so
/maintainability-agent is one keystroke away in Claude Code, Codex and
Copilot Chat:
maintainability-agent --install-skill # writes ~/.claude/skills
Re-run it after every upgrade — a drifted skill teaches agents a dead workflow,
so a differing installed copy is refused with the list of differences. Per-host
install destinations, and --init-agent-standards for always-on guidance
instead of an invokable skill:
docs/ide-agent-integration.md.
GitHub Action
This repo ships action.yml, usable as a composite action:
- uses: marshallguillory86/maintainability-agent@v1.0.0
  with:
    config: maintainability-agent.json
    changed-only: main...HEAD
    fail-on-gate: "true"
Or copy .github/workflows/maintainability.yml into the target repo. For repos
not on GitHub Actions, examples/local-ci.sh enforces coverage and writes
coverage.xml.
Documentation
Start with the documentation index, which states each document's genre and what it is allowed to assert.
Governing — Product intent (authoritative: promises, and what it must never claim) · Architecture (layers, enforced invariants, known debt) · Philosophy (why AI-specific: volume, not pathology) · Decision register including ADR 001 (evidence and verification).
Reference — Maintainability standard · Studies and measured results · Report contract · CLI reference · Config schema · Language support · Analyzer adapters · IDE and agent integration · Chat workflow help · PR and baseline workflows · Roadmap · Changelog.
Running tests
PYTHONPATH=src python3 -m pytest
The full local verification that matches CI — ruff, pip-audit, the 92% coverage gate, and the self-audit — is in CONTRIBUTING.md.
Get in touch
- Bugs / features / questions — open a GitHub Issue.
- Discussion — the Discussions tab.
- Security — see
SECURITY.mdand the private advisory flow. Do not post vulnerabilities in public issues.
Support this work
This is a single-maintainer, MIT-licensed project — free to use, and built on a lot of unpaid hours. If it saves you or your team time, please consider sponsoring its continued development:
Sponsorship is optional and never gates a feature, a fix, or support — the whole tool stays free and open. It just helps keep the work going.
Acknowledgements
- Miles Parker — identified the friction-signal gap: that the "this keeps fighting me" signal a maintainer accumulates over months is exactly the evidence an LLM cannot hold across sessions, and that a tool positioned between the two should carry it. A contribution of insight rather than code, and it changed what this project is for.
License
MIT
1 maintainer

Download files
Download the file for your platform. If you're not sure which to choose, learn more about installing packages.
Source Distribution
Built Distribution
Filter files by name, interpreter, ABI, and platform.
If you're not sure about the file name format, learn more about wheel file names.
Copy a direct link to the current filters
File details
Details for the file maintainability_agent-3.6.1.tar.gz.
File metadata
- Download URL: maintainability_agent-3.6.1.tar.gz
- Upload date:
- Size: 1.2 MB
- Tags: Source
- Uploaded using Trusted Publishing? Yes
- Uploaded via:
twine/7.0.0 CPython/3.13.14
File hashes
| Algorithm | Hash digest | |
|---|---|---|
| SHA256 |
edc3445d5ef012dd8d01adf69cd36388c70d09ea4f90e7de929160786c657238
|
|
| MD5 |
4ff6553d6d4465e4b16de33e537e41f6
|
|
| BLAKE2b-256 |
e728f7ad240e1bd9b67735a966750fec5824a9358cd94c25b73a9006d5b90c3b
|
Provenance
The following attestation bundles were made for maintainability_agent-3.6.1.tar.gz:
Publisher:
release.yml on marshallguillory86/maintainability-agent
-
Statement:
-
Statement type:
https://in-toto.io/Statement/v1 -
Predicate type:
https://docs.pypi.org/attestations/publish/v1 -
Subject name:
maintainability_agent-3.6.1.tar.gz -
Subject digest:
edc3445d5ef012dd8d01adf69cd36388c70d09ea4f90e7de929160786c657238 - Sigstore transparency entry: 2820984180
- Sigstore integration time:
-
Permalink:
marshallguillory86/maintainability-agent@77de21cd8568451c65370c40fafb870c596894d7 -
Branch / Tag:
refs/tags/v3.6.1 - Owner: https://github.com/marshallguillory86
-
Access:
public
-
Token Issuer:
https://token.actions.githubusercontent.com -
Runner Environment:
github-hosted -
Publication workflow:
release.yml@77de21cd8568451c65370c40fafb870c596894d7 -
Trigger Event:
push
-
Statement type:
File details
Details for the file maintainability_agent-3.6.1-py3-none-any.whl.
File metadata
- Download URL: maintainability_agent-3.6.1-py3-none-any.whl
- Upload date:
- Size: 614.4 kB
- Tags: Python 3
- Uploaded using Trusted Publishing? Yes
- Uploaded via:
twine/7.0.0 CPython/3.13.14
File hashes
| Algorithm | Hash digest | |
|---|---|---|
| SHA256 |
b0e2bcc6e7131975e50d2411fc68358344a57bcde4da7e4e065e68347c0339b2
|
|
| MD5 |
81f04bd6ee6fc06bc0d77b3b69c8c1d2
|
|
| BLAKE2b-256 |
79aafe6b964b591feb10a6aaede592e6971ca705a5682b529b96944e38cc1f65
|
Provenance
The following attestation bundles were made for maintainability_agent-3.6.1-py3-none-any.whl:
Publisher:
release.yml on marshallguillory86/maintainability-agent
-
Statement:
-
Statement type:
https://in-toto.io/Statement/v1 -
Predicate type:
https://docs.pypi.org/attestations/publish/v1 -
Subject name:
maintainability_agent-3.6.1-py3-none-any.whl -
Subject digest:
b0e2bcc6e7131975e50d2411fc68358344a57bcde4da7e4e065e68347c0339b2 - Sigstore transparency entry: 2820984392
- Sigstore integration time:
-
Permalink:
marshallguillory86/maintainability-agent@77de21cd8568451c65370c40fafb870c596894d7 -
Branch / Tag:
refs/tags/v3.6.1 - Owner: https://github.com/marshallguillory86
-
Access:
public
-
Token Issuer:
https://token.actions.githubusercontent.com -
Runner Environment:
github-hosted -
Publication workflow:
release.yml@77de21cd8568451c65370c40fafb870c596894d7 -
Trigger Event:
push
-
Statement type:














