
makystats
Econometrics toolkit for Python — ARMA (constant variance), ARMA–GARCH (MLE), VAR (native OLS), VECM / Johansen, and ARDL (bounds test, ECM, forecasts).
| Install | pip install makystats |
| Python | >= 3.9 (tested up to 3.14) |
| License | MIT |
| Version | 0.1.3 |
Documentation: Online user guide (EN/FR).
Full technical guides (also shipped inside the installed package): ARMA, ARMA–GARCH, VAR, VECM, ARDL.
Version française : README.fr.md.
Contact
- Author: ANDRIANITOVIANA Lauret Boris
- E-mail: boris.andrianitoviana@gmail.com
Features
ARMA (makystats.arma)
- Homoskedastic ARMA / AR / ARX / HAR (MLE) — same mean API as
arma_garch, no GARCH dynamics - Deterministics
trend=n/c/t/ct; order selection viaselect_arma_order - Use when only the mean equation is needed; switch to
arma_garchfor conditional volatility / VaR
Volatility (makystats.armagarch)
- Joint MLE of mean (ARMA / ARX / HAR) and variance (GARCH, GJR/TARCH, EGARCH, APARCH, FIGARCH)
- Innovations: normal, Student-t, Hansen skew-t, GED
- Deterministic terms in the mean:
trend=n/c/t/ct(constant and/or linear trend) - Unconstrained BFGS on a reparameterised space; OPG standard errors by default
- Fluent API in the spirit of arch
VAR (makystats.var_model)
- Native OLS VAR in levels; deterministics
n/c/t/ct/ctt - Order selection (
select_var_order), IRF, FEVD, Granger, JB, whiteness, diagnostics forecast(..., variables=...)subset of series (default: all)
Cointegration (makystats.vecm)
- Johansen reduced-rank regression and rank tests
- Eight deterministic cases, including JHJ dual constant/trend (
3a,4a,5a) - MacKinnon–Haug–Michelis (1999) continuous p-values and critical values
- Native multi-step forecasts (
variables=filter), IRF, FEVD, diagnostics
Installation
pip install makystats
pip install "makystats[numba]"   # optional JIT for the GARCH filter
pip install "makystats[plot]"    # matplotlib (diagnostics & forecast plots)
From a source checkout:
pip install -e ".[numba,plot,test]"
Online documentation
User-facing pages (EN/FR): https://Lauret-Boris.github.io/makystats/
Built from the website/ folder (GitHub Pages). The repository docs/ folder holds formula images for this README and is not the Pages root.
Documentation on this page
Table of contents:
| Section | Content |
|---|---|
| Quick start — VAR | Order selection, fit, IRF, forecast |
| Quick start — VECM | Rank test, estimation, forecast |
| VECM reference | Parameters, API, JHJ, forecasts, diagnostics |
| Quick start — ARMA | Homoskedastic ARMA |
| Quick start — ARDL | Bounds test, ECM, forecasts |
| Quick start — ARMA–GARCH | Fit, order selection |
| §1–§8 | Full ARMA–GARCH technical guide |
After install, extended markdown guides are also shipped inside the package:
python -c "import makystats.vecm, pathlib; print(pathlib.Path(makystats.vecm.__file__).parent / 'DOCUMENTATION.md')"
python -c "import makystats.armagarch, pathlib; print(pathlib.Path(makystats.armagarch.__file__).parent / 'DOCUMENTATION.md')"
In-process help: help(VAR), help(VECM), help(ardl), help(arma), help(arma_garch), help(select_var_order), help(select_coint_rank), help(select_ardl_order).
Quick start — ARMA
Homoskedastic ARMA / ARIMA / SARIMA (constant variance). Time index of y is preserved.
from makystats import arma, arima, sarima, select_arma_order

res = arma(y, mean='ARMA', ar=1, ma=1, trend='c').fit()
print(res.params['AR(1)'], res.bse, res.pvalues)
print(res.cov_params())
print(res.arroots, res.maroots)          # |root| > 1 preferred
res.test_normality()
res.test_serial_correlation(10)
print(res.forecast(steps=5, conf_int=True))

# ARIMA (d=1) and SARIMA
res = arima(prices, order=(1, 1, 1), trend='c').fit()
res = arma(ylog, mean='ARMA', ar=0, ma=1, d=1,
           seasonal_order=(0, 1, 1, 12), trend='n').fit()

tab = select_arma_order(y, p_range=range(0, 4), q_range=range(0, 3), criterion='bic')
tab = select_arma_order(ylog, d=1, seasonal_order=(0, 1, 1, 12),
                        p_range=range(0, 3), q_range=range(0, 2))
For conditional volatility, VaR, or GARCH-M, use arma_garch instead.
Details: makystats/arma/README.md.
Quick start — VAR
from makystats import VAR, select_var_order

order = select_var_order(data, maxlags=4, det='c', criterion='bic')
res = VAR(data, k_ar=order.best, det='c').fit()
res.summary()
print(res.forecast(5))
print(res.forecast(5, variables='DTS'))          # one series
print(res.forecast(5, conf_int=True, variables=['DTS', 'FMG']))
res.irf(10).plot()
res.fevd(10).to_wide()['DTS']
res.plot_diagnostics()
Quick start — VECM
from makystats import VECM, select_coint_rank, select_var_order
from makystats.vecm import summarize_johansen, information_criteria_table

# data: DataFrame or ndarray (T x n) in LEVELS
p = select_var_order(data, maxlags=4, criterion='bic').best
k = p - 1   # k_ar_diff = VAR order - 1 (may be 0)

summarize_johansen(data, k_ar_diff=k, signif=0.05)          # all 5 test cases (CV-based rank)
rank = select_coint_rank(data, k_ar_diff=k, test_case='3') # MHM p-values
rank.summary()

model = VECM(data, k_ar_diff=k, coint_rank=max(rank.rank, 1), det_case='3a').fit()
model.summary()

# Native forecast + confidence intervals (optional variable filter)
print(model.forecast(steps=8, conf_int=True, method='analytic'))
print(model.forecast(steps=8, conf_int=True, method='bootstrap',
                     sim_reps=1000, seed=1, variables='DTS'))
model.plot_forecast(steps=8, method='bootstrap', sim_reps=1000, variables='DTS')
model.fitted_values(level=True)    # levels
model.fitted_values(level=False)   # differences
model.irf(10).plot()
model.plot_diagnostics()

information_criteria_table(data, k_ar_diff=k)  # optional AIC/BIC by rank & case
VECM reference
Parameters (makystats API — not statsmodels names)
| Parameter | Values | Role |
|---|---|---|
test_case |
'1' … '5' |
Deterministic specification of the rank test |
det_case |
'1', '2', '3a', '3b', '4a', '4b', '5a', '5b' |
Deterministic specification of VECM estimation (default '3a') |
k_ar_diff |
int | Lags in differences (= VAR order in levels − 1) |
coint_rank |
int | Cointegration rank r |
test_case |
Meaning |
|---|---|
'1' |
No deterministic terms |
'2' |
Restricted constant (inside cointegration) |
'3' |
Unrestricted constant |
'4' |
Unrestricted constant + restricted trend |
'5' |
Unrestricted constant and trend |
det_case |
Meaning |
|---|---|
'3a' / '4a' / '5a' |
JHJ dual deterministic terms (Johansen–Hendry–Juselius) |
'3b' / '4b' / '5b' |
Classical single-term counterparts |
Rank: p-values vs critical values
| Function | Selection rule |
|---|---|
select_coint_rank |
Continuous MHM p-values |
summarize_johansen |
Tabulated MHM critical values |
Near the boundary the displayed ranks may differ by one unit.
Imports
from makystats import VECM, select_coint_rank

from makystats.vecm import (
    VECMModel, JohansenTest, vecm, VECM,
    select_coint_rank, summarize_johansen,
    information_criteria_table, mhm_pvalue, mhm_critical,
)
At the package root only VECM is exported (not vecm), so the submodule makystats.vecm stays importable.
Forecasts and confidence intervals
Point forecasts use the makystats recursion (including JHJ deterministics).
Intervals (conf_int=True) support three methods — parameters held fixed (innovation uncertainty only):
method |
Construction |
|---|---|
'analytic' (default) |
Lütkepohl MSE via MA representation + normal quantiles |
'bootstrap' |
Resample residual rows (preserves contemporaneous correlation); empirical percentiles |
'gaussian' |
Draws from N(0, Σ_u); empirical percentiles |
Aliases: 'simulation' → bootstrap; 'mc' / 'normal' → gaussian.
Analytic MSE at horizon h (levels VAR equivalent, Lütkepohl):
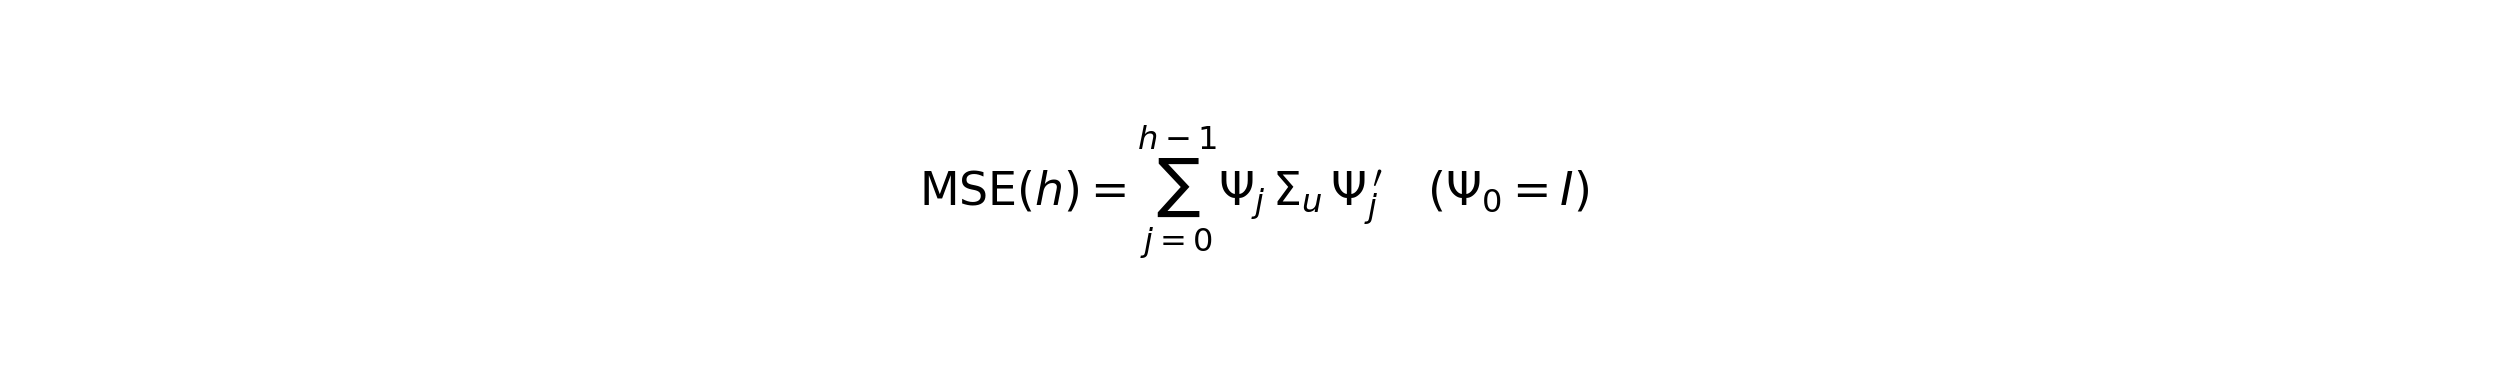
Diagnostics, IRF and FEVD
irf, fevd, test_whiteness, test_normality, Granger causality, and plot_diagnostics are native (same design as makystats.VAR, via the levels VAR equivalent and reduced-rank residuals). Granger uses an F-test on the levels VAR (may differ numerically from statsmodels’ VECM Wald form). Forecast tools support variables= to return a subset of series (default: all).
JHJ estimation sketch
- Classical reduced-rank → estimates of α, β, Γ
- Orthogonalise cointegration residuals on dual deterministic regressors
- Re-estimate short-run equation with detrended ECT → outside deterministics and all SEs refreshed; α and Γ unchanged
Quick start — ARDL
Native OLS ARDL with Pesaran bounds test, long-run multipliers, ECM, and conditional forecasts.
from makystats import ardl, select_ardl_order
import numpy as np

res = ardl(y, x=x, lags=2, order=2, case=3).fit(verbose=False)

res.summary()            # ARDL + residual diagnostics
res.summary_uecm()       # UECM + long-run table
res.summary_ecm()        # error-correction term α
res.summary_bounds()     # Pesaran / Narayan critical values

print(res.params, res.bse, res.pvalues)
print(res.cov_params())
print(res.diagnostic_summary())   # JB + Ljung-Box + ARCH-LM

print(res.bounds["f_stat"])
print(res.long_run_table)
df_lr = res.long_run_fitted()    # y, fitted_lr, ect
res.plot_long_run_fitted()

# Order selection (homogeneous or per-variable maxorder)
tab = select_ardl_order(y, x=x, maxlag=4, maxorder=2, case=3, ic="bic", verbose=False)
# tab = select_ardl_order(y, x=x, maxlag=3, maxorder={"R": 2, "oil": 1}, case=3)
tab.best_model.summary_bounds()

# Fixed regressors (outside the cointegrating relation)
# res = ardl(y, x=x, lags=2, order=2, case=3, fixed=z).fit(verbose=False)

# Restricted ECM then forecast (levels)
res.restrict_ecm(pvalue=0.10, keep_levels=True)
exog_f = np.full((8, x.shape[1] if hasattr(x, "shape") else 1), 0.0)  # scenario for x
print(res.forecast(steps=8, exog_future=exog_f, conf_int=True))
print(res.forecast_ecm(steps=8, exog_future=exog_f, restricted=True, level=True, conf_int=True))
case=1…5 follows the PSS specification (None / Rest. Constant / Constant / Rest. Trend / Trend).
See makystats/ardl/README.md and DOCUMENTATION.md.
Quick start — ARMA–GARCH
from makystats import arma_garch, select_order, ARMAGarch

res = arma_garch(y, mean='AR', ar=1, ma=1, vol='GARCH', trend='c').fit()
print(res.coef_table)
res.plot_diagnostics()

# lag selection helper
order = select_order(y, max_ar=3, max_ma=3, vol='GARCH')
The sections below are the full technical documentation of the volatility submodule.
1. Statistical model
1.1 Mean equation
For observations y_t, t = 1, …, n:
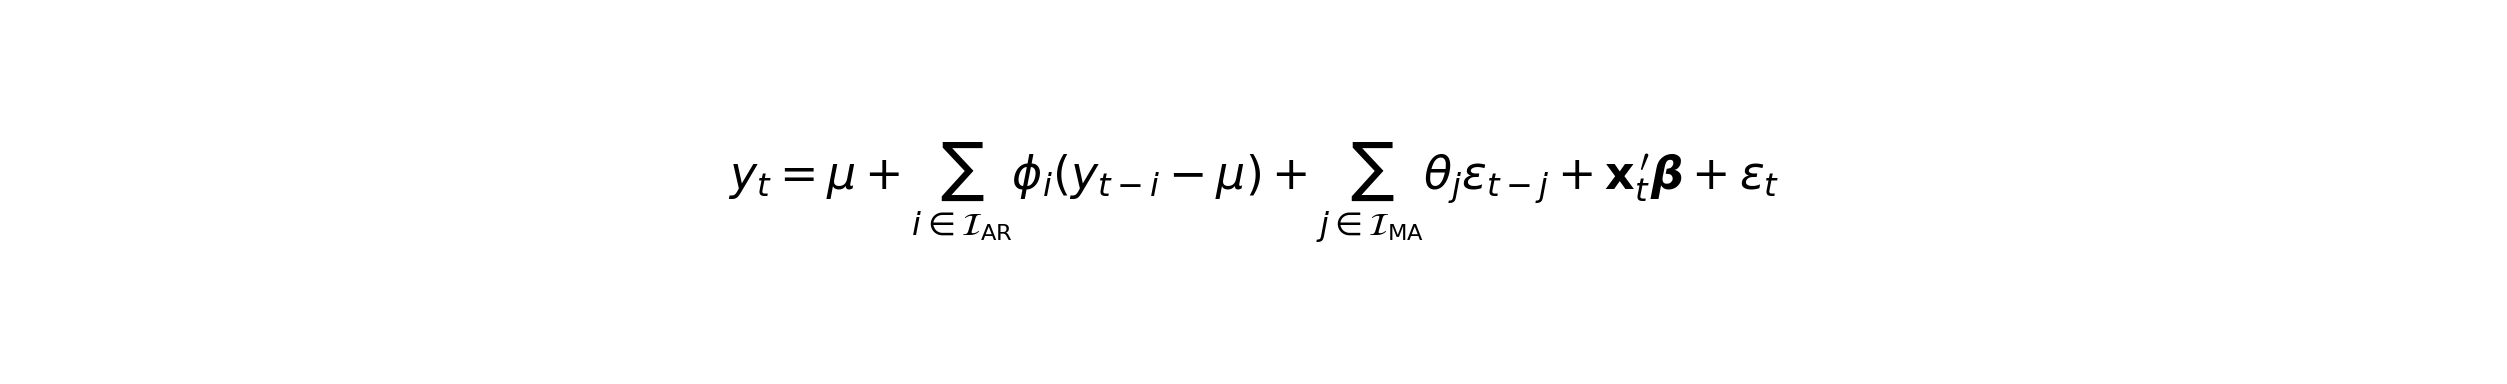
- Index sets I_AR, I_MA may be consecutive {1, …, p} or sparse (e.g. {5} only).
- ARX: AR terms + exogenous x_t, no MA.
- ARMAX: AR + MA + x_t.
- GARCH-M (ARCH-M):
in_mean='sigma'|'var'|'log'— λ·f(σ_t) in the mean ('var'= variance form); coefficient labelarchm. Also onselect_order(..., in_mean=). Careful if σ² is nearly flat (const ↔ λ). - Post-fit without re-passing y/x:
forecast(),var(),results_frame(), … reuse series fromfit(); futurexdefaults to last row. - VaR / ES:
var()/expected_shortfall()withaggregation="marginal"(quantile of y_{T+h}, default) or"cumulative"(Monte Carlo sum over h days;n_sims,seed). In-sample 1-step only:var_series()→var_fitted_,var_backtest()(Kupiec),plot_var(..., window=, style=). Methods: parametric or FHS. - Exogenous names: pass
xas aDataFramesocoef_tableuses column names; with anndarray, usefit(..., x_names=[...]). - LS: intercept + x_t only.
- HAR / HARX (Corsi-style): regressors are causal rolling means of y at user horizons (default 1, 5, 22); estimation proceeds as LS + GARCH on the residual scale.
Deterministic terms (trend). Independently of mean, set:
trend |
Constant | Linear trend τ_t = 1…T | coef_table labels |
|---|---|---|---|
'n' |
no | no | — |
'c' (default) |
yes | no | const |
't' |
no | yes | trend |
'ct' |
yes | yes | const, trend |
Mean path: μ_t = c + δ·τ_t. The AR applies to (y_t − μ_t).
mean='Zero' means no constant (AR/MA via ar=/ma= remain allowed); with default trend='c' it becomes trend='n'.
mean='Zero' + trend='ct' is rejected; trend='t' is allowed.
Centring. When center=True (default) and a constant is present without a trend, y is demeaned for numerical conditioning; the intercept is restored on the original scale after convergence. Centring is turned off automatically when trend is 't' or 'ct'.
1.2 Conditional variance
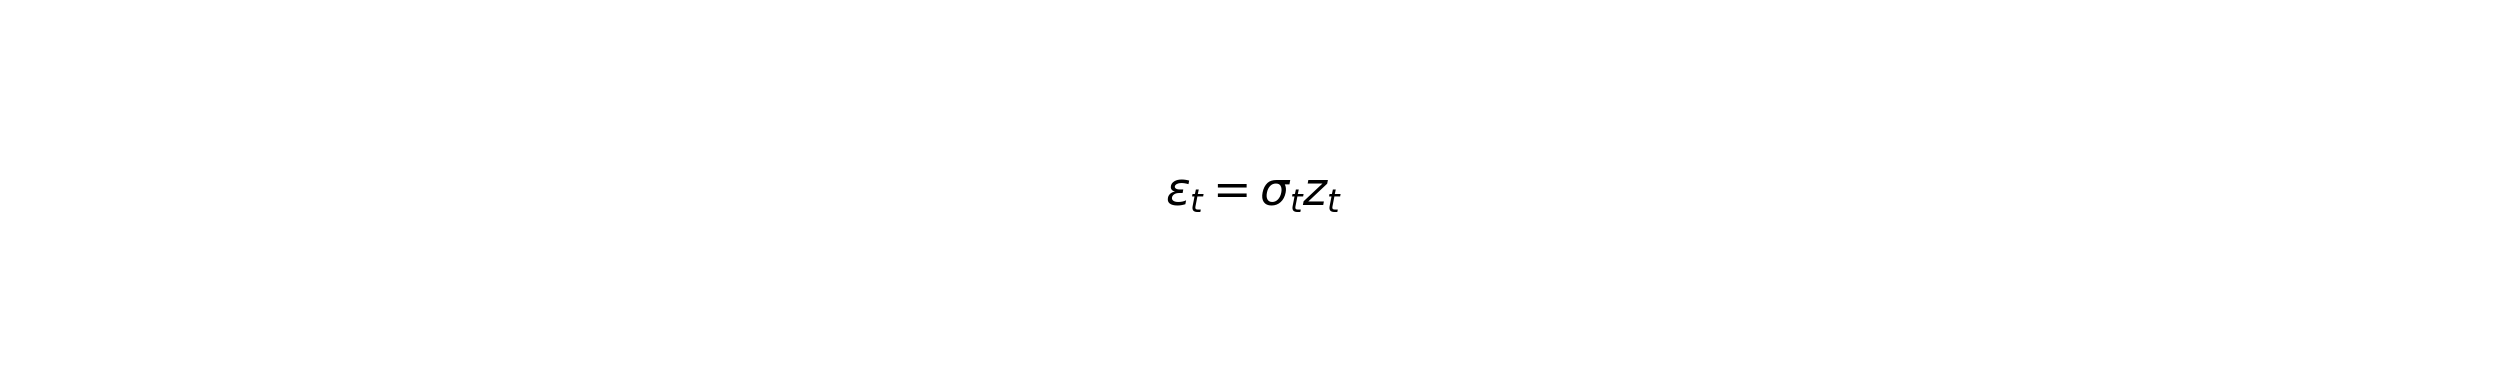
with z_t i.i.d. under the chosen distribution (mean 0, variance 1 after standardisation where required).
GARCH(r, s)
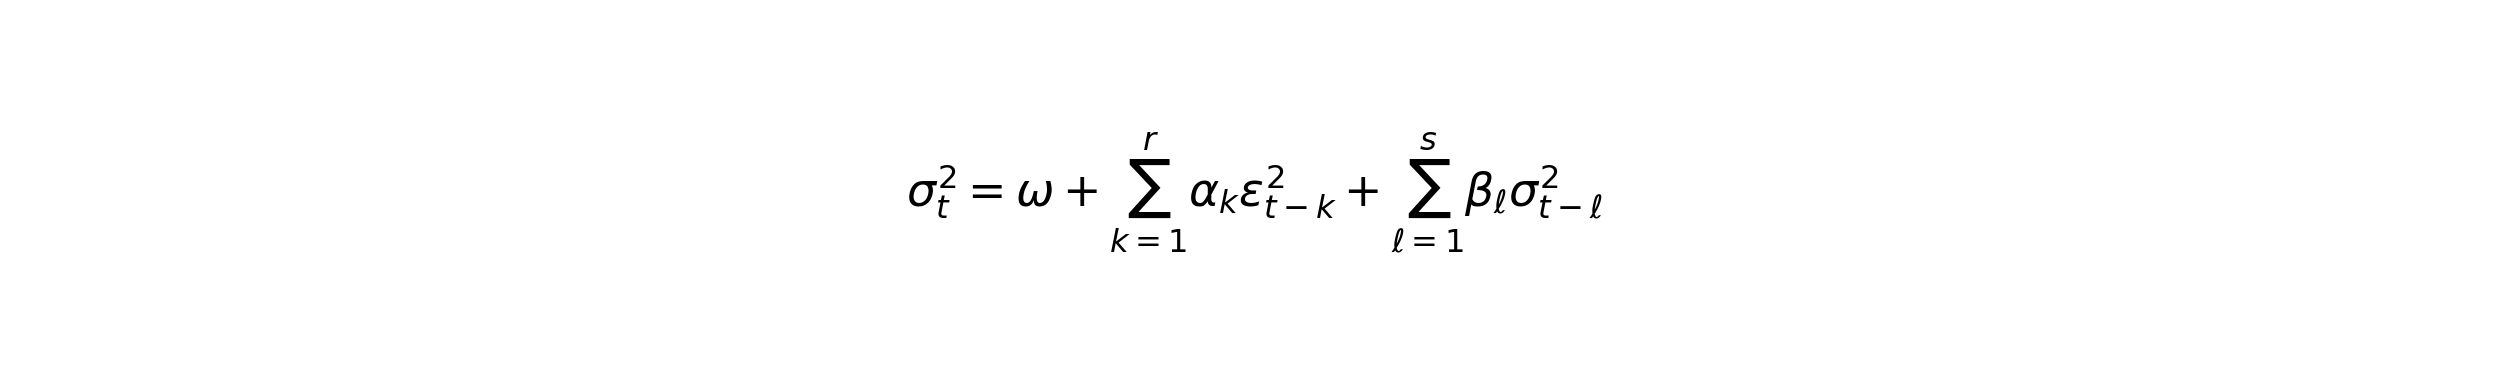
ARCH — GARCH with s = 0.
GJR / TARCH — GARCH plus the asymmetry term
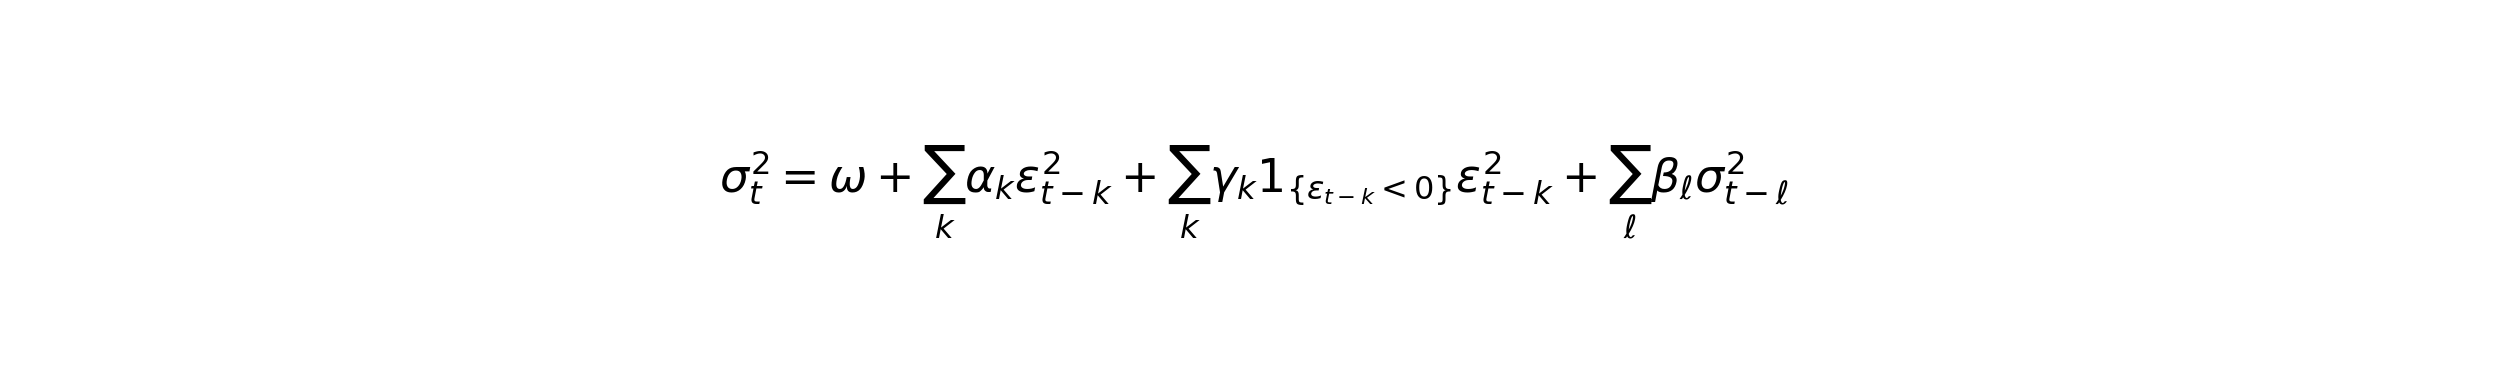
EGARCH (Nelson 1991)
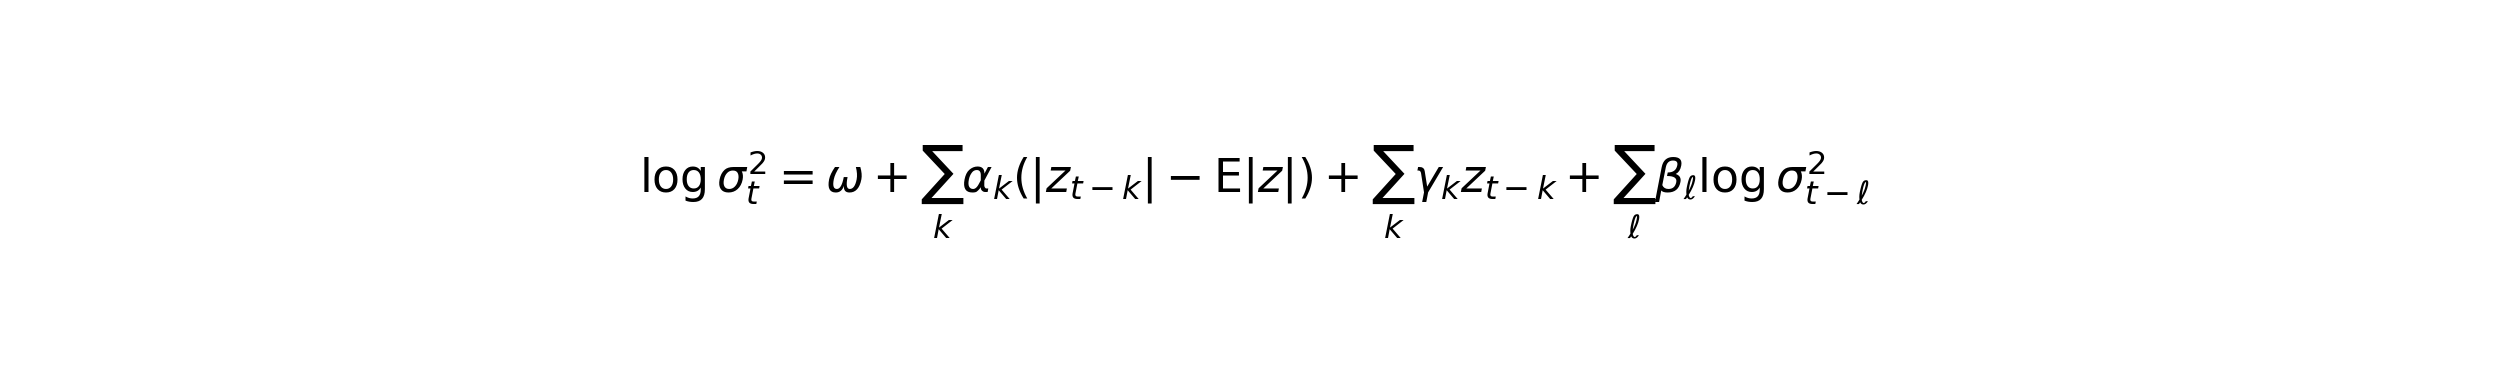
APARCH (Ding–Granger–Engle)
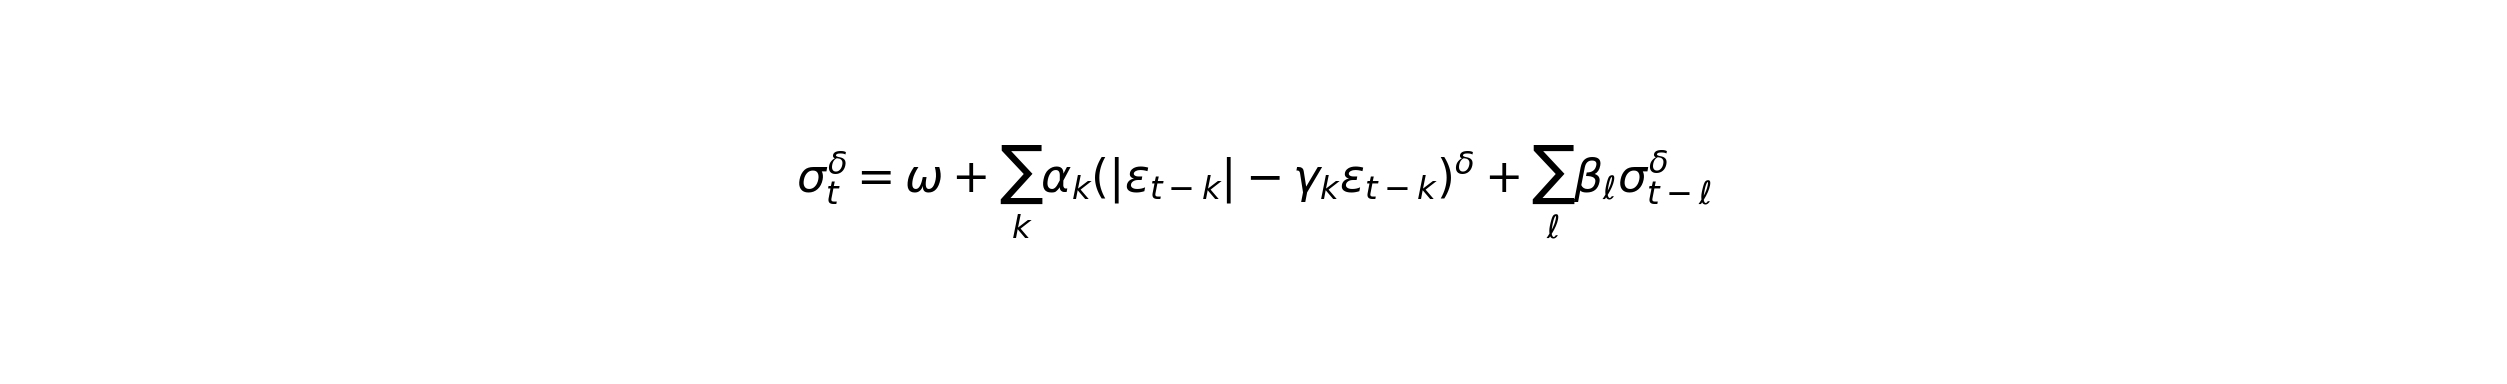
FIGARCH(p, d, q) (Baillie–Bollerslev–Mikkelsen)
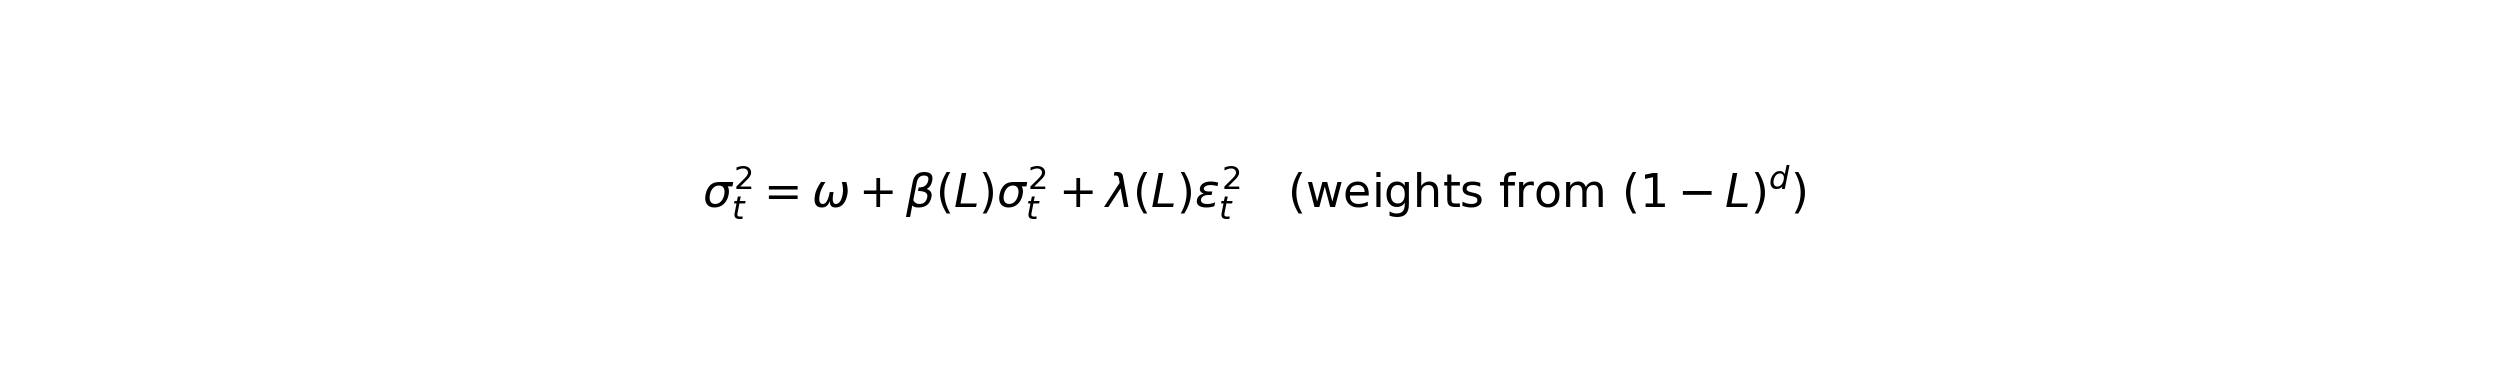
(truncated lag polynomial for the fractional weights; default truncation 1000)
EGARCH display forms. Internally the filter uses the centred Nelson specification (magnitude term |z| − E|z|). Setting egarch_form='raw' shifts the reported intercept only:
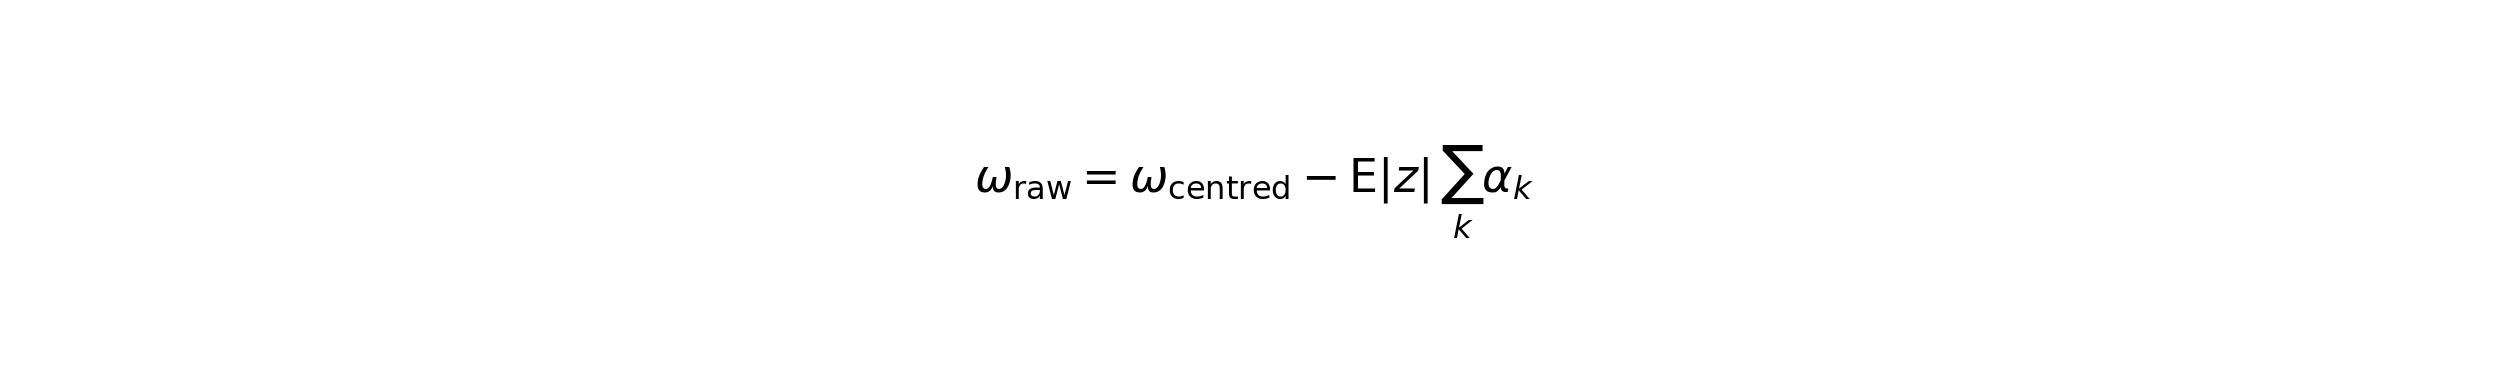
so that the printed equation matches the non-centred writing
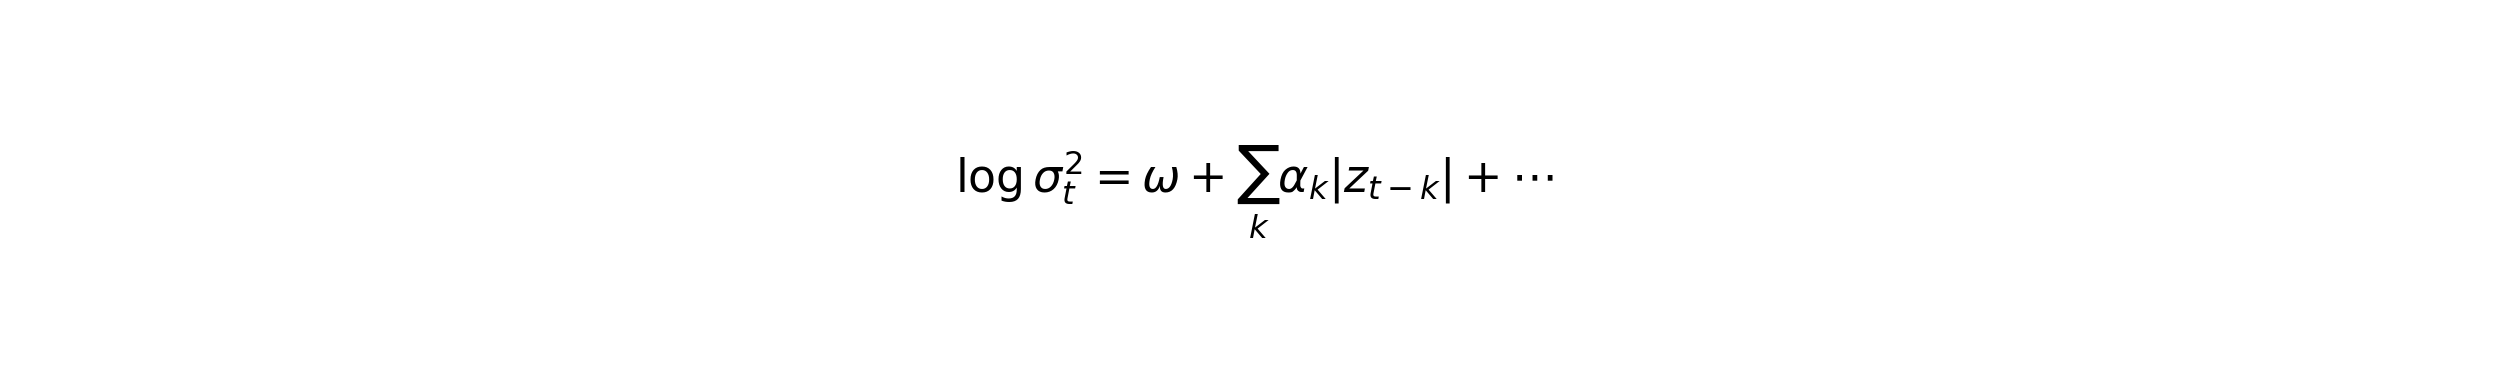
Likelihood and other coefficients are unchanged.
Sign restrictions. For multi-lag GARCH, individual α_k, β_ℓ are not forced positive (only ω > 0 via exp); negative coefficients remain admissible provided σ_t² stays positive in the filter (clamped only for numerical safety). This matches unrestricted ML practice when higher-order lag polynomials are used. GJR γ is free; APARCH γ is mapped to (−1, 1) via tanh; FIGARCH d is soft-bounded for stability.
1.3 Innovation distributions
Standardised residuals z_t = ε_t / σ_t contribute to the log-likelihood as follows (up to constants independent of parameters).
normal
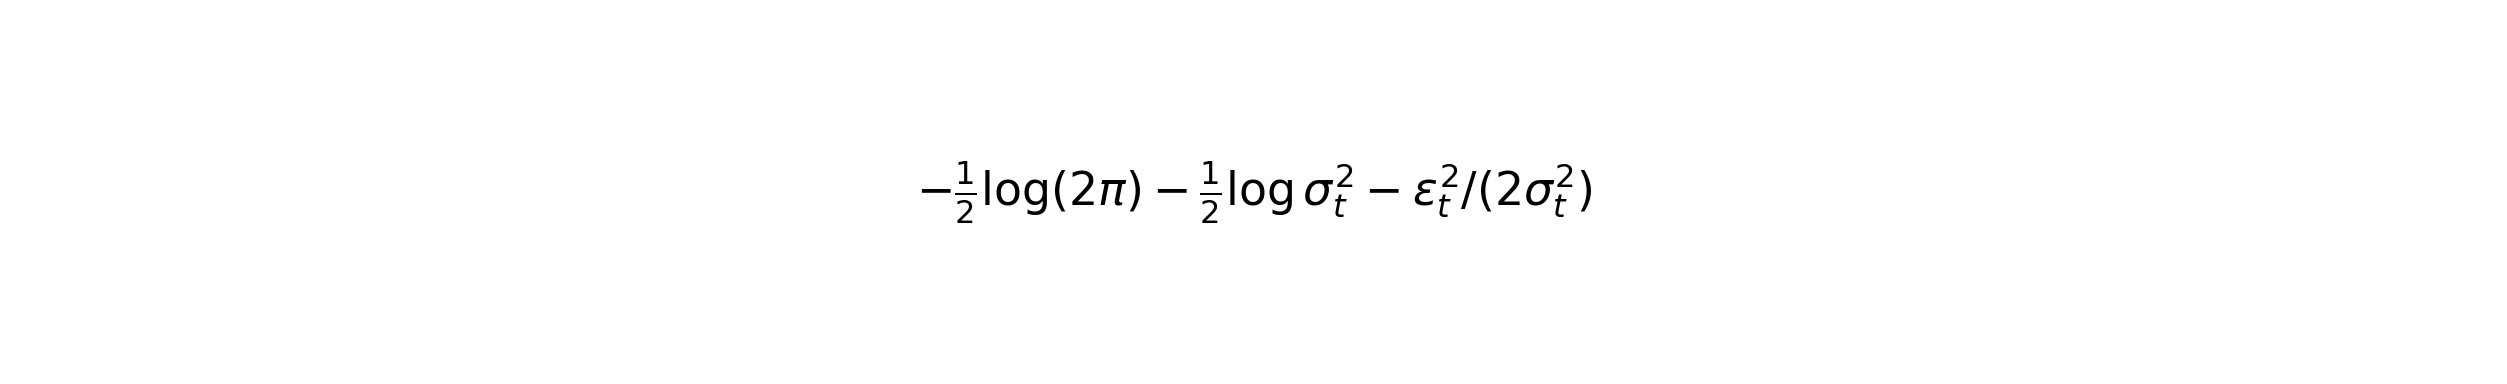
Student-t — form with ν > 2, scaled so that Var(z) = 1.
skew-t (Hansen 1994) — ν > 2, skewness λ ∈ (−1, 1).
GED — shape ν > 0; ν = 2 recovers the Gaussian.
Shape parameters are reparameterised so that BFGS stays in an open unconstrained domain, e.g.
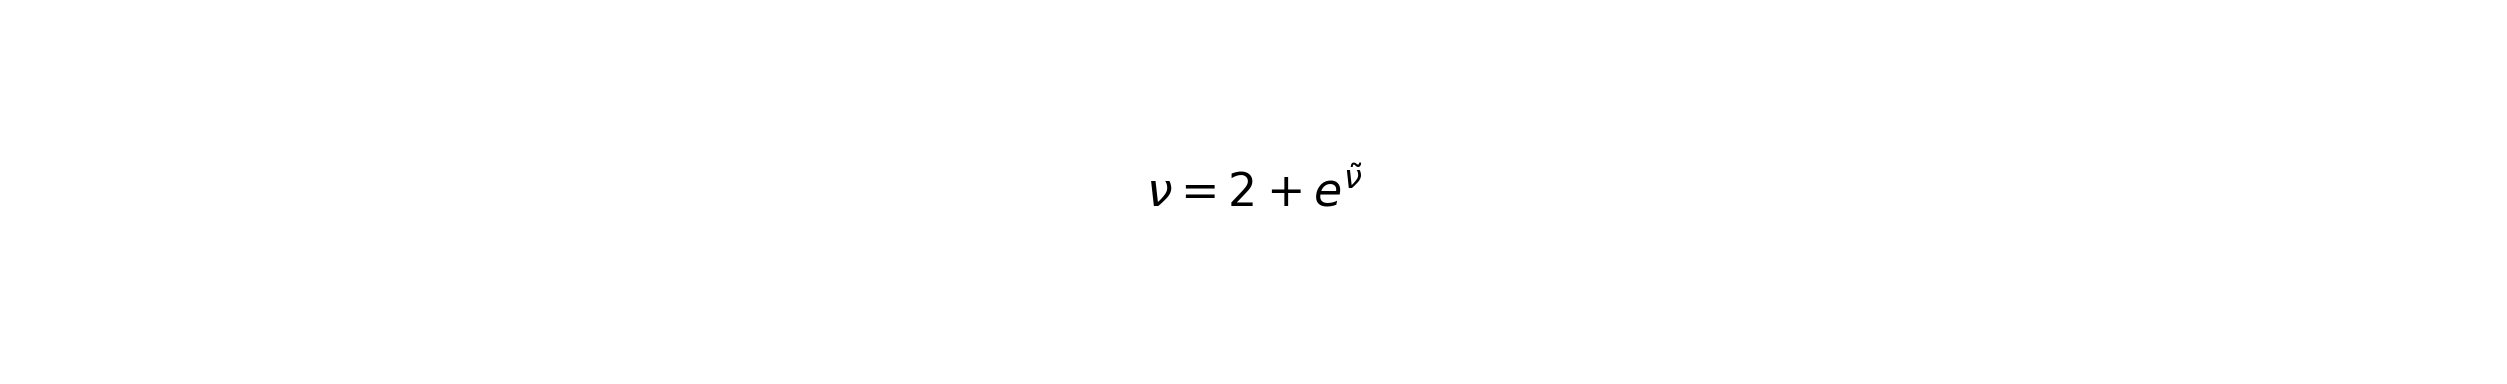
for the t law.
2. Likelihood construction and sample handling
2.1 Log-likelihood
The objective maximised is the conditional Gaussian / t / skew-t / GED log-likelihood
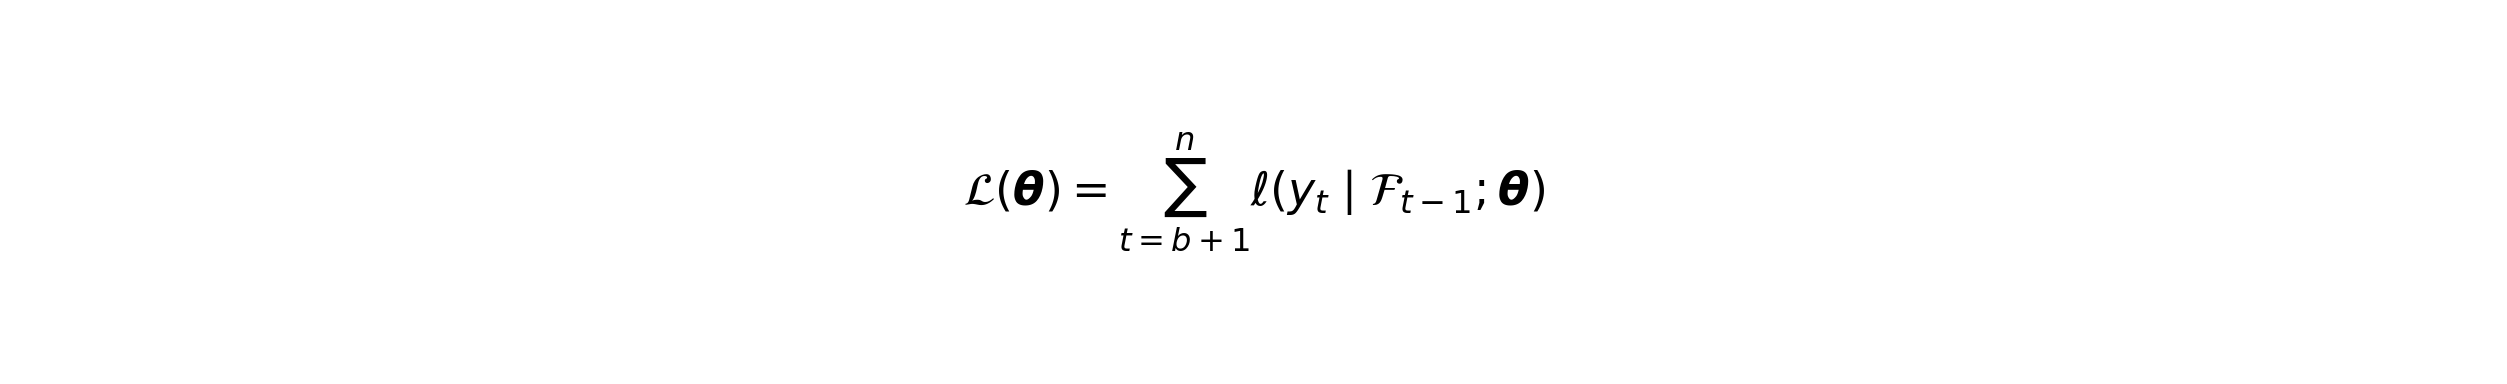
where b is the burn-in (see below) and ℓ uses ε_t(θ) and σ_t²(θ) from the joint filter.
2.2 Burn-in and adjust_sample
| Flag | Behaviour |
|---|---|
adjust_sample=True (default) |
b = max(AR lags, MA lags, hold_back). The first b observations initialise lags; they do not enter L. Same idea as “sample adjusted” in classical ARMA practice. |
adjust_sample=False |
b = 0. All n terms enter L; pre-sample AR/MA/variance states are filled by backcast. Appropriate when the reference sample is 1…n with no adjustment. |
HAR forces at least b = max(horizons) when adjust_sample=True, because early rolling means are incomplete.
2.3 MA pre-sample (Bjørnstad-type / reverse recursion)
When MA terms are present, pre-sample innovations are not set to zero. The implementation:
- Builds AR-only residuals u_t on the estimation window.
- Runs a backward recursion to obtain a Bjørn–Johansen-style backcast path e^{bc}_t.
- Extends that path before the sample (zero driving noise) to form pre-sample MA states e^{ps}.
- Runs the forward ARMA recursion using e^{ps} for lags that fall before the burn index.
This avoids the bias of zero-innovation start-up for pure MA or ARMA models and is material for likelihood levels on short effective samples.
2.4 Variance backcast
Pre-sample conditional variance uses exponential smoothing of squared residuals (parameter λ = backcast, default 0.7):
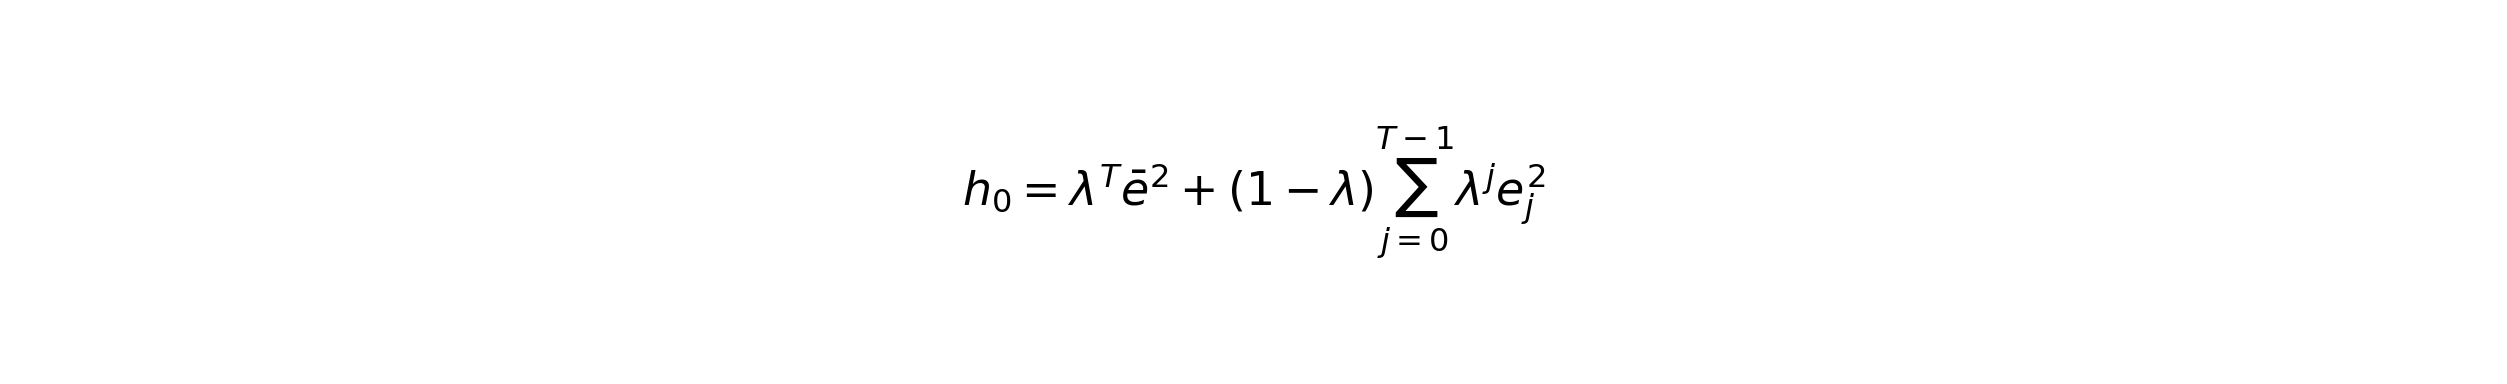
with j = 0 the oldest residual in the estimation window (weights decay toward the present). λ = 1 collapses to h_0 = ē². Inside the filter, both lagged ε² and lagged σ² that fall in the burn region are replaced by h_0 (GARCH-family recursions).
For GARCH-type models, h_0 is also recomputed from current residuals inside each likelihood evaluation so that the backcast stays consistent with the current mean parameters.
3. Optimisation strategy
3.1 Unconstrained BFGS + reparameterisation
Parameters θ live in an unconstrained space; a smooth map θ ↦ ψ yields the economic coefficients ψ (AR, MA, variance, shape):
| Block | Map (illustrative) |
|---|---|
| AR / MA coefficients | stationarity-friendly box (see image) |
| ω (GARCH family) | see image |
| α, β (multi-lag GARCH) | free (signed); filter clamps σ_t² > 0 |
| EGARCH β | positive, scaled to keep persistence < 1 |
| APARCH γ | tanh into (−1, 1) |
| FIGARCH d | soft map into a stable interval |
| t degrees of freedom | see image |
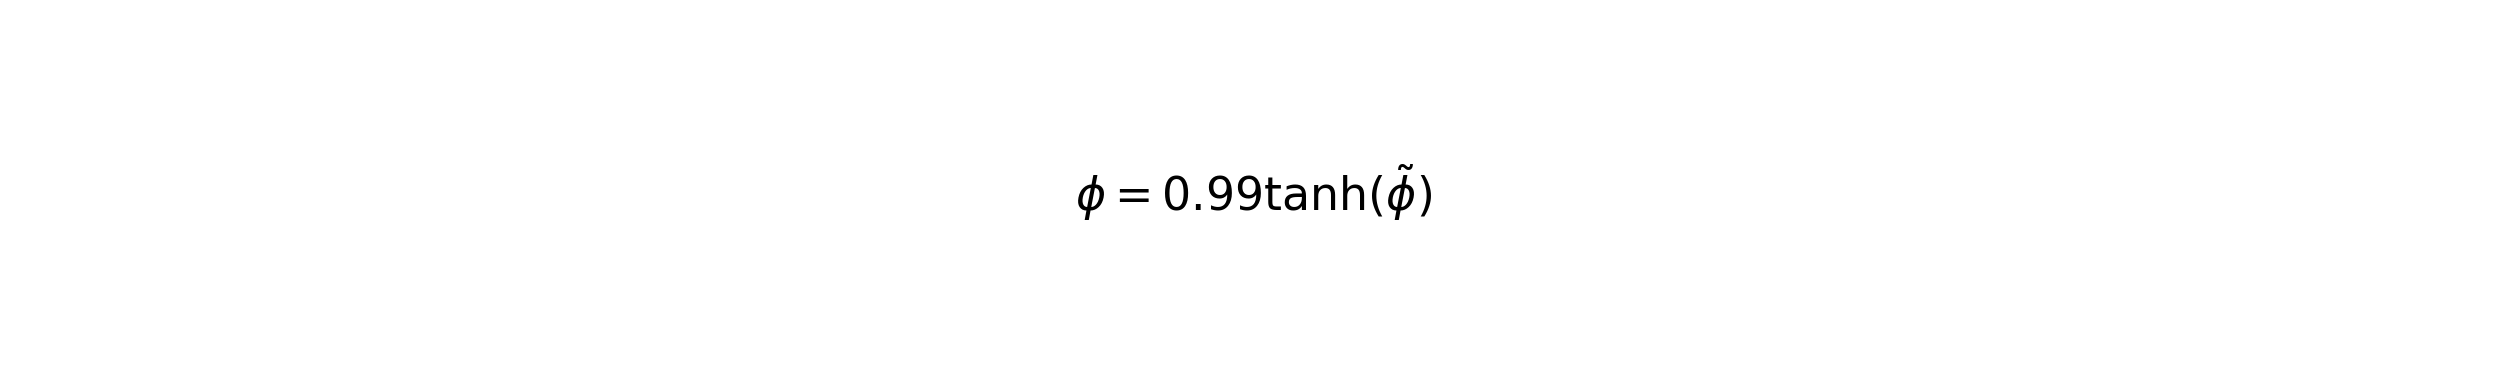
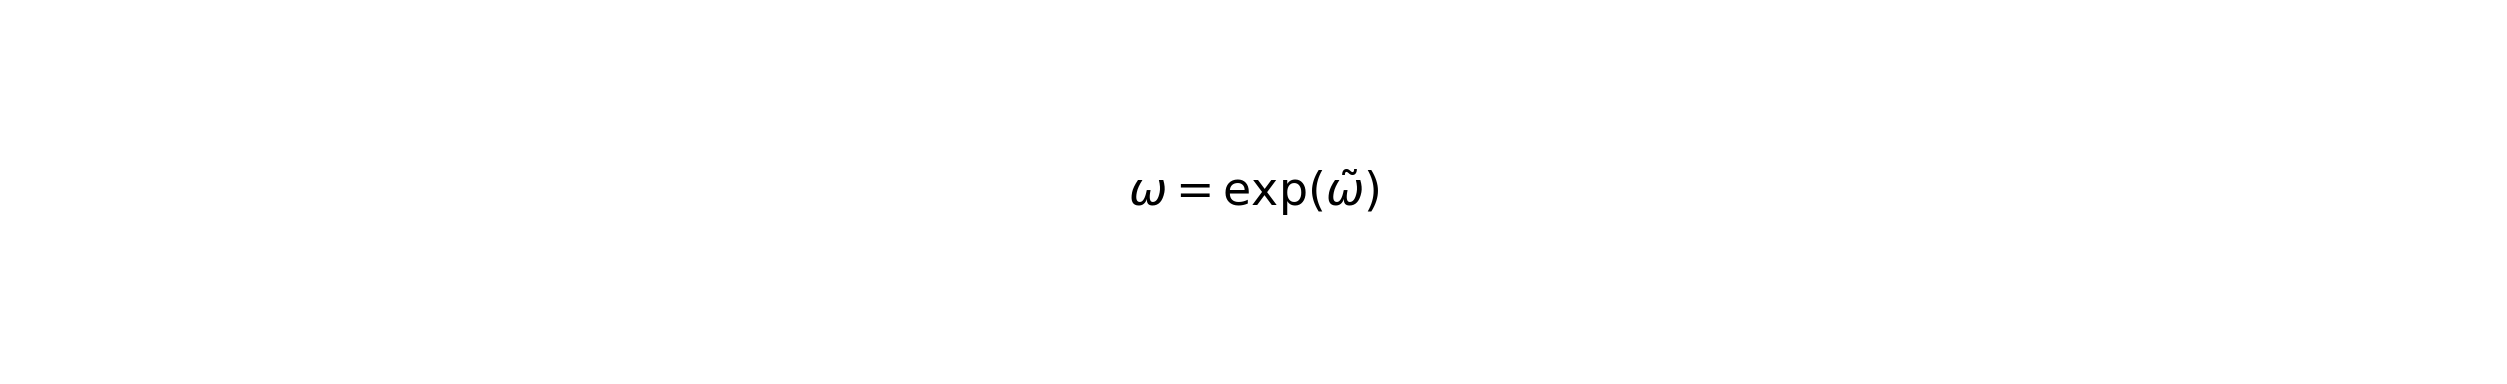
No inequality constraints are passed to SciPy; BFGS (with finite-difference gradient) operates on θ only. Arguments of exp are clipped to avoid overflow during exploratory steps.
Polish step. If the first BFGS run does not report success (common with numerical gradients: “precision loss”), a second BFGS run restarts from the current point.
3.2 Starting values
- Dense ARMA: preliminary ARIMA (statsmodels) when lags are 1…p, 1…q.
- Sparse AR/MA: neutral defaults / method-of-moments style starts.
- Variance: small α, moderate β, ω scaled to residual variance (APARCH uses ω proportional to σ̂^δ).
3.3 Standard errors
Default OPG / BHHH (outer product of gradients):
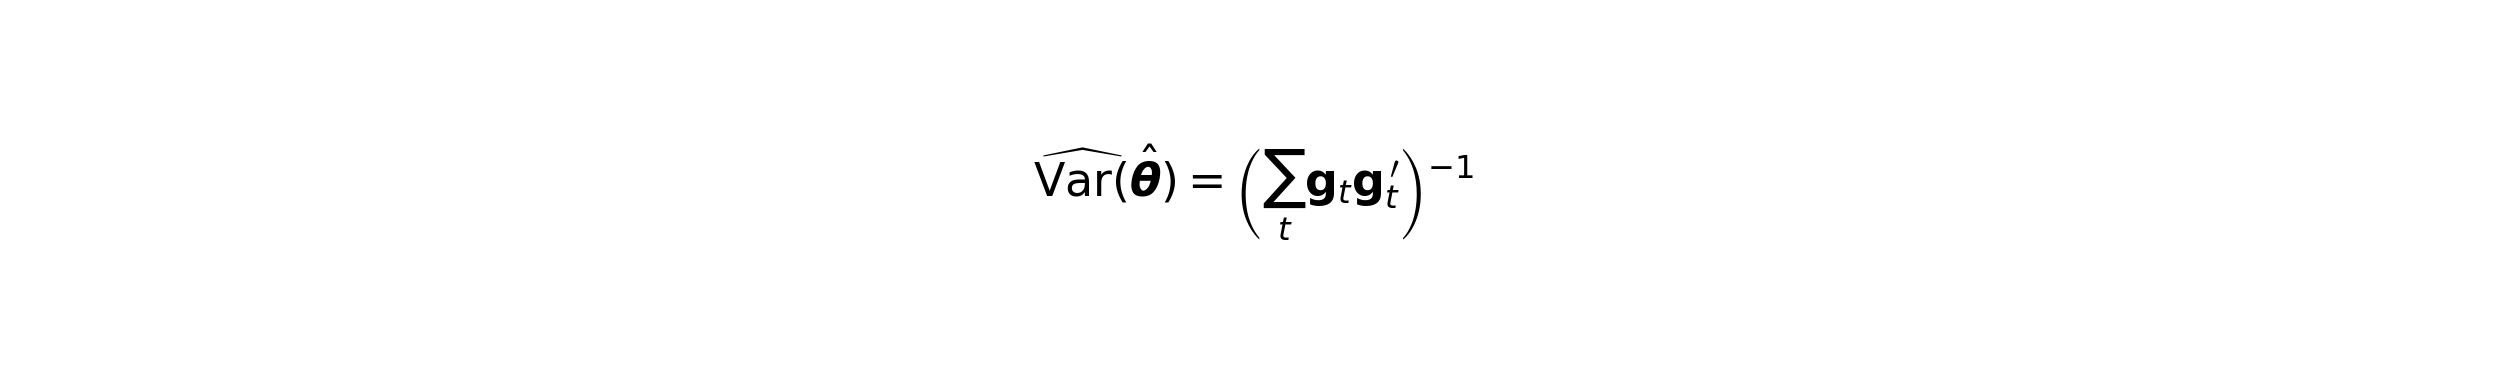
with g_t = ∂ℓ_t / ∂θ evaluated numerically at the MLE (mapped to the economic parameter scale for reporting). Alternative: cov_type='hessian' (numerical Hessian of the concentrated objective).
4. Post-estimation
4.1 Output series (length n)
| Attribute | Content |
|---|---|
residuals |
ε̂_t |
std_resid |
ε̂_t / σ̂_t |
conditional_vol |
σ̂_t |
fitted_values |
y_t − ε̂_t (one-step mean prediction) |
coef_table |
coefficients, SE, z, p-values, 95% CI |
4.2 Diagnostics
plot_diagnostics(): 2×3 figure — residual path, histogram + N(0,1) + KDE, normal QQ plot, ACF of z_t, ACF of z_t², conditional volatility path.
4.3 Forecasts
forecast(y, h, threshold=0.0, x=None) returns a DataFrame with columns mean, variance, vol, p_up for horizons 1…h:
- Mean: multi-step ARMA recursion; future shocks set to zero (minimum MSE under symmetric loss).
- Variance: recurse the chosen variance equation with ε_{T+k}² replaced by σ_{T+k}² for k ≥ 1 where needed.
p_up= P(y_{T+h} > threshold) under the fitted innovation law (normal / t CDF; GED / skew-t use consistent approximations).- Exogenous forecasts require future x (
xwith h rows); if omitted, the exogenous contribution is set to zero.
4.4 Order selection (select_order)
Grid search over AR/MA orders with information criteria (AIC / BIC).
Limitation: the grid uses dense orders 0, 1, …. Sparse specifications such as ma=[5] must be estimated directly.
5. Numerical and implementation notes
- Single filter path. Residuals and σ_t² are produced by one combined ARMA + variance recursion per likelihood evaluation.
- Clamping. σ_t² is kept in a large positive range to prevent log-domain NaNs; this is a numerical guard, not an economic constraint.
- Numba (optional).
pip install "makystats[numba]"can accelerate the filter on long series. - Missing data. Series should be cleaned before estimation; the backend expects a contiguous numeric sample.
- Persistence. Reported persistence is Σα + Σβ (GARCH), Σα + (1/2)Σγ + Σβ (GJR), or the analogous EGARCH / APARCH summaries.
6. API sketch
from makystats import arma_garch, select_order, ARMAGarch

res = arma_garch(
    y,
    mean='ARMA',      # 'Zero', 'Constant', 'AR', 'ARMA', 'ARX', 'ARMAX', 'HAR', 'HARX', 'LS'
    ar=1, ma=1,
    vol='GARCH',      # 'GARCH', 'GJR', 'TARCH', 'EGARCH', 'APARCH', 'FIGARCH'
    dist='normal',    # 'normal', 't', 'skewt', 'ged'
    adjust_sample=True,
).fit()

print(res.coef_table)
print(res.llf, res.aic, res.bic)
res.plot_diagnostics()
fc = res.forecast(y, h=10)
In-process documentation: help(arma_garch), help(ARMAGarch.fit), help(select_order).
7. Package layout and tests
makystats/
  __init__.py           # public exports
  armagarch/            # ARMA–GARCH family (MLE)
    __init__.py
    core.py
    README.md
    DOCUMENTATION.md
  vecm/                 # VECM / Johansen cointegration
    __init__.py
    core.py
    vecm_model.py
    mhm_tables.npz
    README.md
    DOCUMENTATION.md
python -m pytest tests/ -q
8. References (methods implemented)
- Bollerslev, T. (1986), Generalized autoregressive conditional heteroskedasticity, Journal of Econometrics.
- Glosten, L., Jagannathan, R., Runkle, D. (1993), On the relation between the expected value and the volatility of the nominal excess return on stocks, Journal of Finance (GJR).
- Nelson, D. (1991), Conditional heteroskedasticity in asset returns: a new approach, Econometrica (EGARCH).
- Ding, Z., Granger, C., Engle, R. (1993), A long memory property of stock market returns and a new model, Journal of Empirical Finance (APARCH).
- Baillie, R., Bollerslev, T., Mikkelsen, H. (1996), Fractionally integrated generalized autoregressive conditional heteroskedasticity, Journal of Econometrics (FIGARCH).
- Hansen, B. (1994), Autoregressive conditional density estimation, International Economic Review (skew-t).
- Corsi, F. (2009), A simple approximate long-memory model of realized volatility, Journal of Financial Econometrics (HAR).
- Berndt, E., Hall, B., Hall, R., Hausman, J. (1974), Estimation and inference in nonlinear structural models, Annals of Economic and Social Measurement (BHHH / OPG).
- Johansen, S. (1995), Likelihood-Based Inference in Cointegrated Vector Autoregressive Models.
- MacKinnon, J. G., Haug, A. A., & Michelis, L. (1999), Numerical distribution functions of likelihood ratio tests for cointegration, Journal of Applied Econometrics.
- Lütkepohl, H. (2005), New Introduction to Multiple Time Series Analysis.
License
MIT. Version 0.1.3.
1 maintainer

Metadata
1 maintainer
Release files for makystats 0.1.3
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| makystats-0.1.3.tar.gz | 2.4 MB | Without provenance | Details for makystats-0.1.3.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| makystats-0.1.3-py3-none-any.whl | Python 3 | none | any | Details for makystats-0.1.3-py3-none-any.whl |
Total release size: 3.3 MB
Release files / makystats-0.1.3.tar.gz
| Download URL | makystats-0.1.3.tar.gz |
|---|---|
| Size | 2.4 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
5d9ba407c7d2e95a0118c765a3072be6919ec24f0bac2ee4a65b01074601ef93
|
|
BLAKE2b-256 checksum How to use checksums |
4855238f505d392726757fdab42013fbd2e9da8afae8ad2d5a4fa5d1080e6841
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.15.0
|
Release files / makystats-0.1.3-py3-none-any.whl
| Download URL | makystats-0.1.3-py3-none-any.whl |
|---|---|
| Size | 963.1 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
29449cef5fec4b2f39c9cc64e77580276787ec4c8c2ba5a44b3b0a5e9f3d52c4
|
|
BLAKE2b-256 checksum How to use checksums |
81169238422e5a916f4449bc8e933c3d4c393f63e772beecdaca753cbd7555fc
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.15.0
|
Security for makystats 0.1.3
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














