

manimvox
Explainer videos made by your AI agent. Ask Claude Code, Codex, Cursor or Gemini CLI for "an explainer video of" a paper, a codebase, an idea or a pull request. manimvox gives the agent what it needs to research the topic, write a cited script, animate it with Manim, narrate it with a text-to-speech voice, and check the result before it ships. You direct; the agent does the work.





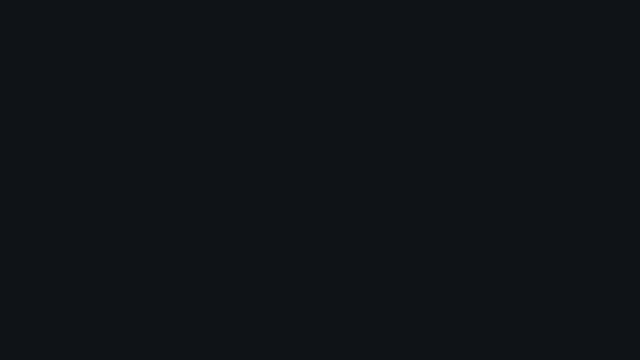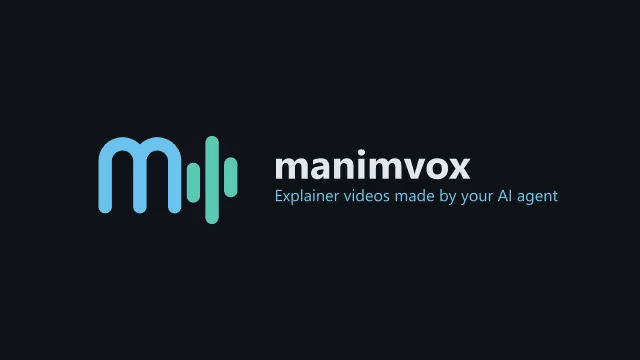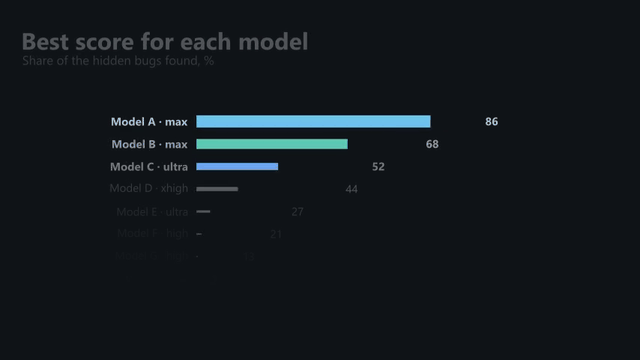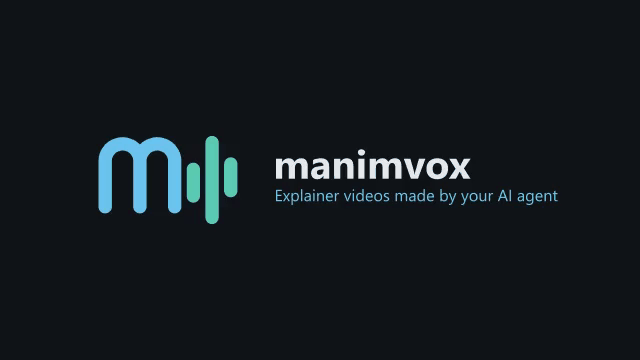
Made with manimvox: four of its blocks. Finished videos made by AI agents are in the gallery, and how agents and voices compare is in the benchmarks. Documentation: laplacianai.github.io/manimvox.
How it works
- Install manimvox and its skills into the coding agent you use (below).
- Ask for a video: "make an explainer video of this paper", "explain hash maps", "turn this repo into a playlist", "walk through PR #42".
- The agent follows a workflow for that kind of video. It gathers sources with your permission, writes every claim into
FACTS.mdwith its source, writes the script, and builds the episodes from manimvox's components and blocks. - It checks its own work. It drafts, reads the contact sheets and the layout check, fixes what's wrong, and renders the final MP4 with subtitles only when every check passes.
The agent makes the video by writing code, a Python file per episode, not by calling a long list of tools. Studies by Anthropic, Cloudflare and the CodeAct authors found that agents work better and more efficiently that way; How it works has the details.
The agent asks before it installs anything, downloads a model, fetches from the web or uses an online voice. Everything it uses is a normal Python library and command line, so you can also write episodes by hand.
Features
-
Made for AI agents. Eleven agent skills cover four workflows (a document, a concept, a codebase playlist, a pull request), and every command is also a typed tool for Python agent frameworks. It never prompts without a terminal, its errors are one line, and downloads need
--yes. -
One episode file in, one finished MP4 out. It comes with subtitles (
.srt), and narration and picture stay in step. -
Ten voice engines behind one interface. Kokoro is the default, and it runs offline with no key. Piper, macOS
say, edge-tts, OpenAI, ElevenLabs, Sarvam AI and Gnani.ai (for Indian languages), and the XTTS-v2 and F5-TTS voice cloners are also supported. -
Checks that gate a render:
- text contrast against the background (WCAG 2.1);
- text off the safe stage or overlapping;
- silent narration lines;
- contact sheets for a quick look.
Every failed check exits non-zero.
-
3D when depth is the idea:
Episode3Dadds Manim's tilting, orbiting camera to an episode, with the header and progress bar kept flat on screen. -
3D models from files: a glTF (Blender's export), OBJ or STL model drawn by Manim so its camera orbits it and parts can be picked out (the
mesh-modelblock), or rendered with real lighting and animations as a clip (from_model). -
A theme per video: colours and fonts come from the project's
series.json, never from a fixed preset. -
Cross-platform: macOS, Linux and Windows, with no system ffmpeg (audio and video are decoded with PyAV).
Requirements
- Python 3.11 or newer, and uv or pip
- System libraries for Manim's text rendering:
| OS | Command |
|---|---|
| macOS | brew install cairo pkg-config |
| Debian / Ubuntu | sudo apt install libcairo2-dev libpango1.0-dev pkg-config python3-dev |
| Windows | nothing extra (wheels are provided) |
Installation
Install it from PyPI, with the default Kokoro voice, using either uv or pip:
uv tool install "manimvox[kokoro]"     # with uv: its own environment, on your PATH
pip install "manimvox[kokoro]"         # with pip: best inside a virtual environment
manimvox doctor
manimvox doctor checks the system libraries, fonts and voice engines, and names the command that fixes anything missing. The first run can take a few minutes while Pango builds its font cache.
Add more voices by installing again with the extras you want, keeping kokoro:
uv tool install --force "manimvox[kokoro,piper]"     # with uv
pip install "manimvox[kokoro,piper]"                 # with pip
The development version installs from GitHub: uv tool install "manimvox[kokoro] @ git+https://github.com/LaplacianAI/manimvox", or the same with pip install.
| Extra | Adds |
|---|---|
kokoro |
Kokoro (default voice) |
piper |
Piper |
edge |
edge-tts |
cloud |
OpenAI, ElevenLabs, Sarvam AI and Gnani.ai (standard library; needs an API key) |
xtts |
XTTS-v2 voice cloning (installs PyTorch) |
f5 |
F5-TTS voice cloning (installs PyTorch) |
matplotlib |
Matplotlib charts as scenes (manimvox.scenes) |
plotly |
Plotly charts as scenes (Kaleido needs Chrome on the machine) |
trimesh |
3D model files for the mesh-model block |
pyvista |
3D models and scans rendered with lighting as clips (from_model, from_pyvista; needs OpenGL 3.2: a graphics driver, or on a Linux server sudo apt install libegl1 libosmesa6, or on a Windows server Mesa's opengl32.dll) |
agno, langchain, pydantic-ai, openai-agents, crewai, llamaindex, haystack, google-adk |
Tools for that agent framework (see Use it from a Python agent framework) |
Make a video with your coding agent
manimvox ships eleven agent skills, so your coding agent can plan, write, render and check a video for you. Install them into the agents you use:
npx skills add LaplacianAI/manimvox                      # detects your agents and lets you pick
npx skills add LaplacianAI/manimvox -g -y                # your detected agents, for all projects, no prompts
npx skills add LaplacianAI/manimvox -a claude-code -a codex -y
Without Node.js, manimvox installs the same skills itself:
manimvox skills install                  # pick agents; add --agent ID (repeatable) to name them
manimvox skills install --global --yes   # every project, no questions
manimvox skills check                    # are the installed skills current?
manimvox skills update
manimvox skills remove
Other flags: --project (the default) installs in the current project, --copy copies the skills instead of linking them, and --native skips npx even when it is present. Without a terminal, install and remove need --yes (with --agent ID to choose agents), npx or not. An npx in the current folder is ignored. Only the eleven manimvox skills are ever touched.
npx skills add LaplacianAI/manimvox fetches from GitHub, so it installs whatever is on the default branch. manimvox skills install installs the skills that match your installed manimvox version.
Agent-specific routes:
- Claude Code:
claude plugin marketplace add LaplacianAI/manimvox, thenclaude plugin install manimvox@manimvox. - Gemini CLI:
gemini extensions install https://github.com/LaplacianAI/manimvox. - Codex and Cursor: the plugin manifests in the repository root (
.codex-plugin/,.cursor-plugin/) point atskills/.
Then ask your agent: "make an explainer video of <paper / repo / idea / PR>".
| Skill | What it does |
|---|---|
manimvox |
Picks the workflow for your request and checks the setup |
manimvox-core |
The authoring contract for episodes: structure, timing, safe stage, components |
manimvox-animation |
Motion patterns: carry-overs, reveals, tables, graphs, zooms, sequence diagrams |
manimvox-creative |
Theme, story and narration, and the facts discipline |
manimvox-voice |
Choosing and preparing the voice: engines, licences, pronunciation, cloning consent |
manimvox-cli |
The command line and how to read its output |
manimvox-blocks |
Ready-made charts and diagrams to copy into a project, and how to write one |
manimvox-paper |
One document into an explainer video of about 5 to 8 minutes (shorter on request), every claim traced to the source |
manimvox-playlist |
A codebase or spec into a beginner-to-advanced playlist, with page and zips |
manimvox-concept |
An idea with no source document into a 3Blue1Brown-style video |
manimvox-pr |
A pull request into a 1-3 minute walkthrough |
Write an episode by hand
manimvox new demo --series "Vectors, Explained" --tagline "What a vector really is"
cd demo
This creates:
demo/
  series.json   series name, voice, speed, loudness, pronunciations, theme, episode list
  FACTS.md      every claim the video makes, with its source
  SERIES.md     the outline every episode is written against
  episodes/     one Python file per episode
  out/          finished videos and subtitles
  research/     source material
Write episodes/ep01_vectors.py:
from manimvox.kit import *

class Ep01(Episode):
    EP = 1
    TITLE = "What is a vector?"
    TAGLINE = "An arrow, a list of numbers, and why they are the same thing"
    NCHAP = 1

    def build(self):
        self.intro("A vector is an arrow with a length and a direction.")
        self.chapter("Arrows", "Start with an arrow from the origin.")
        v = arrow(ORIGIN, RIGHT * 3 + UP * 2, color=ACCENT, label="v")
        self.say("This arrow goes three right and two up.", Create(v))
        self.outro(["A vector has a length and a direction"], "That is all a vector is.")
Register it in series.json:
"episodes": [{"n": 1, "stem": "ep01_vectors", "cls": "Ep01", "title": "What is a vector?"}]
Then draft, look, and render:
manimvox draft ep01          # 480p, no voice: contact sheets in sheets/ep01_vectors/ and a layout report
manimvox render ep01 --yes   # 1080p with the voice; --yes allows the one-time 354 MB Kokoro download
The result is out/ep01_vectors.mp4 and out/ep01_vectors.srt. The render finishes with audio check: ok or exits 1.
Use it from a Python agent framework
An agent built on a Python framework has no shell, so manimvox also ships its commands as tools (manimvox.tools) and adapters for eight frameworks. Install the extra for yours, next to a voice:
pip install "manimvox[kokoro,agno]"
pip install "manimvox[kokoro,langchain]"
pip install "manimvox[kokoro,pydantic-ai]"
pip install "manimvox[kokoro,openai-agents]"
pip install "manimvox[kokoro,crewai]"
pip install "manimvox[kokoro,llamaindex]"
pip install "manimvox[kokoro,haystack]"
pip install "manimvox[kokoro,google-adk]"
Install one, in the environment your agent runs in. Each tool builder (manimvox_tools, ManimvoxTools, manimvox_toolset) takes the project folder, such as hash-maps, and pins the tools to it.
Agno (set AGNO_TELEMETRY=false if you do not want Agno to send usage telemetry) loads the skills itself and takes the tools as a toolkit:
import manimvox
from agno.agent import Agent
from agno.skills import LocalSkills, Skills
from manimvox.integrations.agno import ManimvoxTools

agent = Agent(
    model=...,
    skills=Skills(loaders=[LocalSkills(str(manimvox.skills_path()))]),
    tools=[ManimvoxTools("hash-maps")],
)
LangChain Deep Agents:
from deepagents import create_deep_agent
from manimvox.integrations.langchain import deep_agent_kwargs

agent = create_deep_agent(model=..., **deep_agent_kwargs("hash-maps"))
Pydantic AI:
from pydantic_ai import Agent
from manimvox.integrations.common import manimvox_instructions
from manimvox.integrations.pydantic_ai import manimvox_toolset

agent = Agent(..., toolsets=[manimvox_toolset("hash-maps")], instructions=manimvox_instructions())
OpenAI Agents SDK:
from agents import Agent
from manimvox.integrations.openai_agents import manimvox_instructions, manimvox_tools

agent = Agent(name="manimvox", instructions=manimvox_instructions(), tools=manimvox_tools("hash-maps"))
CrewAI:
import manimvox
from crewai import Agent
from manimvox.integrations.crewai import manimvox_tools

agent = Agent(..., tools=manimvox_tools("hash-maps"), skills=[manimvox.skills_path()])
LlamaIndex:
from llama_index.core.agent.workflow import FunctionAgent
from manimvox.integrations.llamaindex import manimvox_instructions, manimvox_tools

agent = FunctionAgent(tools=manimvox_tools("hash-maps"), llm=..., system_prompt=manimvox_instructions())
Haystack (set HAYSTACK_TELEMETRY_ENABLED=False if you do not want Haystack to send usage telemetry):
from haystack.components.agents import Agent
from manimvox.integrations.haystack import manimvox_skills, manimvox_tools

agent = Agent(chat_generator=..., tools=[*manimvox_tools("hash-maps"), manimvox_skills()])
Google ADK:
from google.adk.agents import LlmAgent
from manimvox.integrations.google_adk import manimvox_skill_toolset, manimvox_tools

agent = LlmAgent(..., tools=[*manimvox_tools("hash-maps"), manimvox_skill_toolset()])
Security. Each adapter pins the tools to the one project folder it was built with, so the model cannot name another folder. But an episode is Python, and render runs it with your permissions. Run an agent in a container or VM when the model or its input is untrusted.
CrewAI cannot share an environment with the OpenAI Agents SDK (they need different major versions of openai) or with the f5 voice extra (CrewAI needs rich>=14.2, F5-TTS needs rich<14). Install them separately. CrewAI also needs Python below 3.14, and sends usage telemetry unless you set CREWAI_DISABLE_TELEMETRY=true.
Other frameworks:
- Frameworks that read
SKILL.mdfolders takemanimvox.skills_path(): Microsoft Agent Framework (SkillsProvider.from_paths) and AG2 (SkillsToolkit). - Any framework can register
manimvox.integrations.common.json_tools(folder)andfile_tools(folder)as plain functions. pydantic-ai-harness[skills]and the OpenAI SDK's sandboxSkillsare native alternatives toread_skill.
Notes:
- Tell the agent which folder the project is in.
project_note(folder)writes that line for the instructions. - A render takes minutes and a video takes many tool calls, so raise the framework's turn or request limit; the examples show how.
- The plain functions,
json_tools()andfile_tools()with no folder, are unbound. Pass the folder,json_tools(folder)andfile_tools(folder), whenever a model is calling them.
A runnable script for each framework is in examples/agents/.
Usage
| Command | What it does |
|---|---|
manimvox new DIR --series NAME [--tagline T] [--voice E:V] |
Create a project folder |
manimvox draft EP [--every SECONDS] |
Fast 480p render without voice; writes contact sheets and runs the layout check |
manimvox render EP [--voice E:V] [--yes] |
1080p render with narration, then the audio check |
manimvox check theme |
Contrast, fonts and theme source |
manimvox check layout EP |
Text off the stage or overlapping, from the last draft |
manimvox check audio EP |
Every narration line is audible in the final video |
manimvox voices [ENGINE] |
Engines with status and licence, or the voices of one engine |
manimvox voices --prepare ENGINE[:VOICE] [--yes] |
Download and check a voice ahead of a render |
manimvox add [BLOCK ...] [--list] [--force] |
Copy a scene block into the project's blocks/ folder |
manimvox join [EP ...] [-o OUT.mp4] [--no-cards] |
Join rendered episodes into one video with a title card (each episode keeps its own end card) |
manimvox doctor |
System libraries, fonts and voice engines |
EP can be written ep01, 1, or the episode's file stem. Commands exit non-zero on any failed check. Without a terminal, manimvox never prompts: pass --yes (or set MANIMVOX_ASSUME_YES=1) to allow downloads.
Writing episodes
An episode is a class that subclasses Episode and implements build(). from manimvox.kit import * brings in Manim plus:
-
Structure:
intro(narration): title card, which then becomes the persistent header.chapter(title, narration): chapter card, which also advances the progress bar.clear(): removes everything from the stage.outro(recap, narration, next_title=None): recap list and a pointer to the next episode.
-
Narration:
say(text, *animations): plays the animations at the start of the line.steps(text, [animations]): spreads the animations across the line.with self.narrate(text):for full control.
Pass
tts="..."when the spoken words should differ from the subtitle. -
Components:
- text:
T(one line),P(wrapped paragraph),heading,note; - shapes and cards:
box,card,node,chip,stat; - connections:
arrow,flow,gnode,gedge,lifeline,message; - content:
bullets,table,code; - icons:
icon_*.
- text:
-
3D: subclass
Episode3Dinstead ofEpisodeto tilt and turn the camera (move_camera,begin_ambient_camera_rotation).pin(*mobs)keeps a label flat on screen, andcamera_home()turns back to the flat view. Title, chapter and recap cards are always drawn flat. -
Theme colours:
BG PANEL LINE INK MUTED ACCENT OK WARN ERROR BLUE ORANGE VIOLET PINK TEAL, plus any colour named in the theme (written in capitals).
Keep content inside the safe stage: x from −6.6 to 6.6, y from −3.45 to 3.15. The header and the progress bar sit outside it.
Blocks, charts and finishing
Blocks
A block is a ready-made scene component, copied into your project so you own it.
manimvox add --list          # every block, with what it draws
manimvox add bar-ranking     # writes blocks/bar_ranking.py and prints the import line
from blocks.bar_ranking import bar_ranking, grow, value_x
The eleven blocks: venn, bar-ranking, line-by-level, log-scatter, bug-grid, token-panel, request-flow, sequence-diagram, code-diff, surface-plot (a 3D surface) and mesh-model (a 3D model from a file), the last two for an Episode3D. manimvox add never replaces a block already in the project; --force does.
Charts
manimvox.scenes turns frames from Pillow, Cairo, Matplotlib, Plotly or a 3D model into a clip you place and play like any mobject, in the theme's colours.
import matplotlib.pyplot as plt
from manimvox.scenes import from_matplotlib, mpl_style
with plt.rc_context(mpl_style()):
    fig, ax = plt.subplots(figsize=(9.6, 5.4)); ax.plot([1, 2, 3], [2, 5, 3])
clip = from_matplotlib(fig)   # then clip.move_to(...), self.add(clip), self.play(clip.play(), ...)
Install the matplotlib or plotly extra for them (see the extras table). Plotly exports through Kaleido, which needs Chrome; manimvox never downloads it for you.
Finishing
series.json may hold a post object that manimvox render applies after the audio check:
"post": {"music": "music/bed.mp3", "music_db": -16, "duck_db": -12, "captions": "burn", "end_card": ["Sources: FACTS.md"], "card_seconds": 3}
music is a file you provide; it loops under the narration and dips by duck_db while someone speaks. captions is "srt" (default) or "burn". end_card is up to 4 lines. manimvox join then makes one video of the rendered episodes: a title card, then each episode with its own end card.
Configuration
series.json
{
  "manimvox": "0.3.0",
  "series": "Vectors, Explained",
  "tagline": "What a vector really is",
  "voice": "kokoro:af_heart",
  "speed": 1.0,
  "loudness": -16,
  "pron": [["\\bNumPy\\b", "num pie"]],
  "theme": { "source": "..." },
  "episodes": [{ "n": 1, "stem": "ep01_vectors", "cls": "Ep01", "title": "What is a vector?" }]
}
loudness is the level every narration line is brought to, in LUFS (−40 to −5; default −16, a common level for speech online). Voices return audio at very different levels, so without it, changing the voice changes the volume. Each line is measured as ITU-R BS.1770 integrated loudness, brought to the target, and kept under −1.5 dBTP. null keeps each voice's own level. The line as the voice returned it stays cached, so a new target never pays for synthesis again.
pron holds pairs of regex and spoken form, applied to what the voice says and never to the subtitles. Common terms such as API, JSON and SQL are already handled.
Themes
Choose a theme for each video from its subject: the product's brand, the paper's figures, or the house style of the channel being emulated. Roles left out fall back to a neutral dark theme, and check theme lists them. Here is an example in the spirit of 3Blue1Brown:
"theme": {
  "source": "in the spirit of 3Blue1Brown: near-black stage, Manim's blue, yellow, green and red",
  "bg": "#0E1113", "panel": "#1A1F24", "panel2": "#252B31", "line": "#3A434B",
  "ink": "#ECECEC", "muted": "#A3ABB2", "accent": "#58C4DD",
  "ok": "#83C167", "warn": "#FFFF00", "error": "#FC6255",
  "blue": "#58C4DD", "orange": "#FF862F", "violet": "#9A72AC", "pink": "#D147BD", "teal": "#5CD0B3",
  "named": { "vector_i": "#83C167", "vector_j": "#FC6255" }
}
What check theme requires:
- Contrast: text roles (
ink muted accent ok warn error) have at least 4.5:1 contrast onbgandpanel; hues and named colours have at least 3:1 onbg. - Fonts: every font can be loaded.
- Source:
sourcesays where the theme came from.
Optional keys:
fontandmono(defaults per OS);font_files(bundled font files);mark_svg(a logo drawn on the title card).
Environment variables
| Variable | Purpose |
|---|---|
MANIMVOX_VOICE |
Voice used when neither --voice nor series.json sets one |
MANIMVOX_CACHE |
Where models and voices are stored. Default: %LOCALAPPDATA%\manimvox on Windows, $XDG_CACHE_HOME/manimvox or ~/.cache/manimvox elsewhere |
MANIMVOX_ASSUME_YES |
1 answers yes to download and licence prompts |
OPENAI_API_KEY, ELEVENLABS_API_KEY, SARVAM_API_KEY, GNANI_API_KEY |
Keys for the online engines |
Voices
A voice is written engine:voice, and the default is kokoro:af_heart. It is chosen by --voice first, then series.json, then MANIMVOX_VOICE. If a voice is missing, not installed or lacks its key, the render stops with a one-line reason; manimvox never switches voice silently.
| Engine | Voice example | Install | Runs | Licence |
|---|---|---|---|---|
| Kokoro (default) | kokoro:af_heart |
kokoro |
offline, 354 MB model | Apache-2.0 weights, MIT runtime |
| Piper | piper:en_US-libritts_r-medium |
piper |
offline, ~80 MB per voice | GPL-3.0 package; each voice's licence is saved beside it as <voice>.MODEL_CARD (CC BY 4.0 for the default) |
| macOS say | say:Samantha |
built in, macOS only | offline | macOS licence: personal, non-commercial voice output |
| edge-tts | edge:en-US-AriaNeural |
edge |
online, no key; text goes to Microsoft | LGPL-3.0 package; Microsoft service terms |
| OpenAI | openai:alloy, openai:tts-1-hd/onyx |
cloud + OPENAI_API_KEY |
online, paid | OpenAI terms; disclose that the voice is AI-generated |
| ElevenLabs | elevenlabs:<voice id> |
cloud + ELEVENLABS_API_KEY |
online, paid or free tier | ElevenLabs terms; the free tier requires attribution |
| Sarvam AI | sarvam:shubh, sarvam:anushka@hi-IN |
cloud + SARVAM_API_KEY |
online, paid; 11 Indian languages | Sarvam AI terms |
| Gnani.ai | gnani:Kaveri, gnani:Shivani@ta-IN |
cloud + GNANI_API_KEY |
online, paid; 10 Indian languages and Hinglish | Gnani.ai terms |
| XTTS-v2 | xtts:clone=voice.wav |
xtts |
offline, ~1.9 GB + PyTorch | non-commercial (Coqui Public Model License) |
| F5-TTS | f5:clone=voice.wav with voice.txt |
f5 |
offline, ~1.3 GB + PyTorch | non-commercial weights (CC-BY-NC) |
Notes on particular engines:
- Voice cloning: the engines clone from a 6–30 second recording of the speaker. F5-TTS also needs a transcript of that recording:
voice.txt, besidevoice.wav, holding exactly what is said in it. - Paths:
clone=recordings and local Piper.onnxvoices are resolved from the project root. - Indian languages: Sarvam AI and Gnani.ai voices are written
[model/]voice[@language]. With no model, the one that has the voice is used. With no language, Sarvam usesen-INand Gnani detects it. For example,sarvam:bulbul:v4-flash/simran_en_customerorgnani:timbre-v3.0/Avinash@hi-IN.manimvox voices sarvamandmanimvox voices gnanilist the voices and languages. Sarvam takes speed 0.5 to 2.0 (0.3 to 3.0 onbulbul:v2), and Gnani takes 0.85 to 1.15. - Even loudness: every voice is levelled to the same loudness (
loudnessinseries.json, −16 LUFS by default), so switching voices doesn't change the volume. - Online engines receive only the narration text.
manimvox voices edgeandmanimvox voices elevenlabsgo online to list their voices. - Downloads happen only after you confirm (or pass
--yes). Kokoro and Piper files are verified by hash.
Licences were summarised on 2026-10-16 and have not been legally reviewed. Verify them upstream before any commercial use.
Development
git clone https://github.com/LaplacianAI/manimvox && cd manimvox
uv sync --extra dev --extra kokoro
uv run pytest            # about 30 s; offline, no heavy extras needed
uv run ruff check src tests
Tests that need real engines are opt-in:
uv run pytest -m kokoroneeds the Kokoro model in the cache.uv run pytest -m piperneedsuv sync --extra piperand network access once.
Tests that render with Manim are marked slow.
src/manimvox/
  cli.py            the manimvox command
  tools.py          typed tools mirroring the CLI, for agents with no shell
  integrations/     adapters for eight agent frameworks
  project.py        series.json loading and validation
  scaffold.py       manimvox new
  skills.py         finds the bundled agent skills
  skills_admin.py   manimvox skills install|check|update|remove
  playlist.py       manimvox index and package
  runner.py         runs Manim in a subprocess
  kit/              Episode, components, theme, text (what episodes import)
  scenes/           clips from Pillow, Cairo, Matplotlib and Plotly
  post/             music bed, captions, cards, join
  blocks.py         block registry, manimvox add, the preview tool
  checks/           theme, layout, audio, contact sheets
  voice/            the voice interface, cache, downloads, HTTP, audio conversion
  voice/engines/    one module per text-to-speech engine
examples/agents/   one script per framework
skills/             the eleven agent skills (bundled into the wheel)
.claude-plugin/     Claude Code plugin and marketplace manifests
.codex-plugin/      Codex plugin manifest
.cursor-plugin/     Cursor plugin manifest
gemini-extension.json, plugin.json   Gemini CLI and agent-plugins manifests
tests/
Roadmap
What comes next, release by release: ROADMAP.md.
Contributing
Contributions are welcome, from people and from their agents: read CONTRIBUTING.md to get set up, and AGENTS.md if an agent is doing the work. Everyone taking part follows the Code of Conduct. Report a vulnerability privately as SECURITY.md describes; for help, see SUPPORT.md. Changes are listed in the changelog.
License
MIT. Voice engines and models carry their own licences; see Voices.
1 maintainer

Metadata
1 maintainer
Release files for manimvox 0.3.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| manimvox-0.3.0.tar.gz | 3.4 MB | With provenance | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| manimvox-0.3.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 4.4 MB
Release files / manimvox-0.3.0.tar.gz
| Download URL | manimvox-0.3.0.tar.gz |
|---|---|
| Size | 3.4 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
77db758ba91e452c0ec0eef13509c9c2732b5ae2e67b562c2f9586c7d25111d9
|
|
BLAKE2b-256 checksum How to use checksums |
f2cfc30194c338517335c28aaa54aa4edd3e4efd660b8fbb287474ce5dfd0f76
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 23, 2026.
Transparency logRelease files / manimvox-0.3.0-py3-none-any.whl
| Download URL | manimvox-0.3.0-py3-none-any.whl |
|---|---|
| Size | 959.8 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
5171fab197a128f2cbbf5d646debd89c5d3bcb276813e289bb5bfde359977ba5
|
|
BLAKE2b-256 checksum How to use checksums |
49fb7b08fd9cdc32b2cd7859a60f7f7ea9f25bc954b53e605263c1d3a3858ca8
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 23, 2026.
Transparency logSecurity for manimvox 0.3.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
All 2 files in this release have been uploaded with provenance metadata.
Attestation for manimvox-0.3.0.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 23, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














