
manyhands
Run several local OCR models over the same handwritten page and show a human exactly which words they disagree on.
A single vision model transcribing a parish register gives you a wall of confident text. Some of it is wrong, and nothing in the output tells you where. manyhands runs the page through several different models, aligns what they produced, and highlights every word they did not all agree on. You read the highlights instead of proofreading the page.
Everything runs locally. No API keys, no uploads, no model weights in this package.
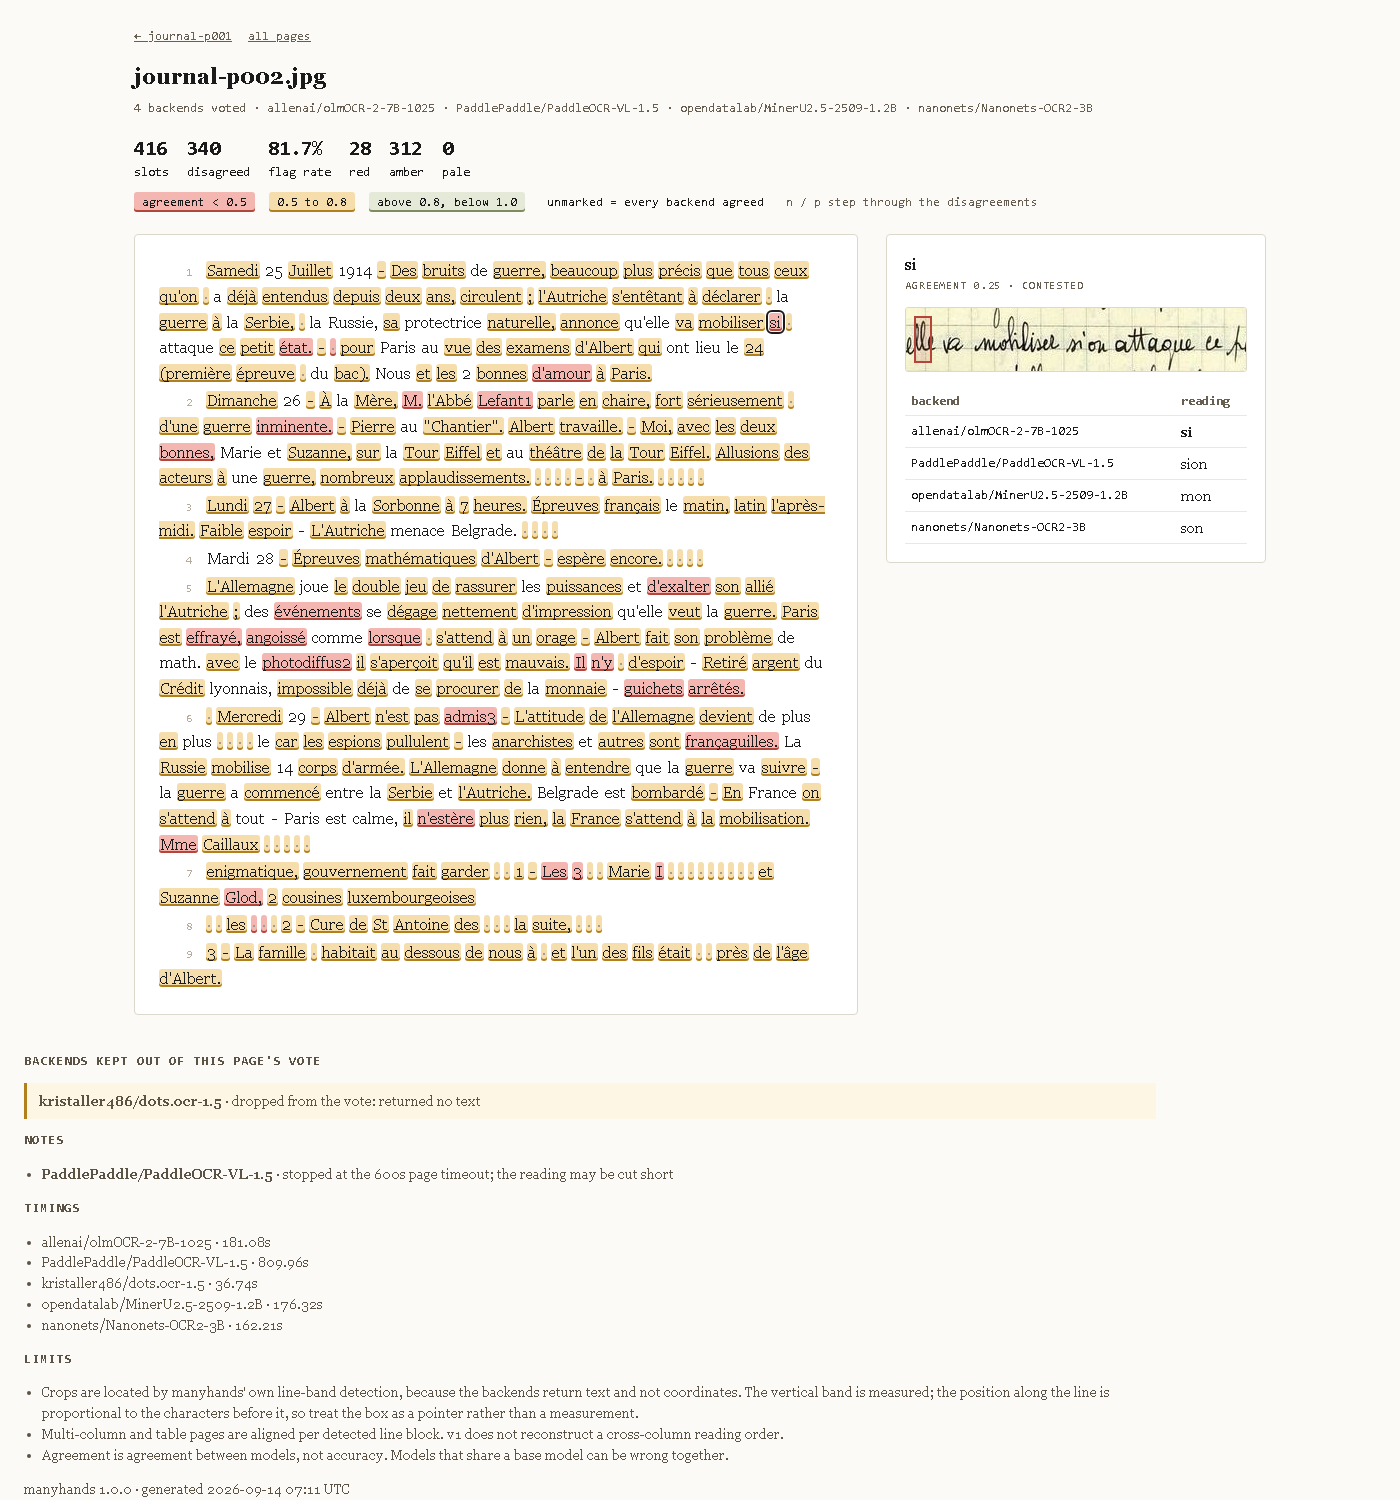
Page two of the sample diary. si is highlighted red because the four models read it as si,
sion, mon and son. The panel shows the line it came from so you can settle it yourself.
What you get per page
manyhands-out/
  index.html
  journal-p001/
    consensus.txt     the majority reading, one line per aligned line
    agreement.json    every slot, its vote counts, its agreement ratio, its bbox
    report.html       the consensus with disagreements highlighted, self-contained
report.html opens in a browser with no server and no network. Click a highlighted word
and a panel shows the cropped region of the page image alongside one row per model. n and
p step through the disagreements without touching the mouse, and each report links to the
pages either side of it and back to index.html.
Install
pip install manyhands
That gives you the CLI and the alignment, voting and reporting code. It does not pull torch, because the right torch build depends on your CUDA version. To actually run models:
pip install torch --index-url https://download.pytorch.org/whl/cu128   # or your CUDA build
pip install 'manyhands[hf]'
Model weights download from Hugging Face on first use, into the normal HF_HOME cache.
The five default weight sets are 34 GB together: 16.6, 7.5, 6.1, 2.3 and 1.9. On Windows
without developer mode the cache keeps two copies of each file, so budget double that.
dots.ocr-1.5 is the exception. churro-ocr fetches it with snapshot_download(local_dir=...)
into ~/.cache/churro-ocr/hf/DotsOCR_1_5/, so it ignores HF_HOME and lands on the system
drive whatever you set. That was 5.7 GB here.
Python 3.12 or newer.
Usage
manyhands run <folder>                  transcribe every page and write the reports
manyhands confirm <page>                record the readings you accept
manyhands eval <dataset-dir>            score the flags against ALTO/PAGE-XML ground truth
run
manyhands run scans/parish-register
Walks the folder for .png .jpg .jpeg .tif .tiff .bmp .webp and PDFs, rasterising PDF
pages at 300 dpi into .manyhands/pdf-pages. Each model is loaded once, run over the whole
folder, then released, because the default five do not fit in 24 GB together.
The two sample pages in this repo, run with the default five:
$ manyhands run tests/data/pages
  allenai/olmOCR-2-7B-1025 · journal-p001.jpg: 11 tokens (119.2s)
  allenai/olmOCR-2-7B-1025 · journal-p002.jpg: 365 tokens (181.1s)
  PaddlePaddle/PaddleOCR-VL-1.5 · journal-p001.jpg: 11 tokens (37.0s)
  PaddlePaddle/PaddleOCR-VL-1.5 · journal-p002.jpg: 288 tokens (810.0s)
  kristaller486/dots.ocr-1.5 · journal-p001.jpg: 0 tokens (63.0s)
  kristaller486/dots.ocr-1.5 · journal-p002.jpg: 0 tokens (36.7s)
  opendatalab/MinerU2.5-2509-1.2B · journal-p001.jpg: 11 tokens (47.2s)
  opendatalab/MinerU2.5-2509-1.2B · journal-p002.jpg: 343 tokens (176.3s)
  nanonets/Nanonets-OCR2-3B · journal-p001.jpg: 11 tokens (47.6s)
  nanonets/Nanonets-OCR2-3B · journal-p002.jpg: 365 tokens (162.2s)
  journal-p001.jpg: 0/11 flagged (0%)
    kristaller486/dots.ocr-1.5: dropped from the vote: returned no text
  journal-p002.jpg: 340/416 flagged (82%)
    kristaller486/dots.ocr-1.5: dropped from the vote: returned no text

2 pages, 340 of 427 slots flagged (79.6%)
reports: tests\data\pages\manyhands-out\index.html
82% on page two is not a bug, it is the answer. That page is dense 1914 French cursive, and
two of the four surviving models cannot read it: against Samedi 25 Juillet 1914 they return
Lamedi and Jameedi, against bruits they return briro and bulto. Page one is a sparse
title page where the survivors agree on all eleven words, so nothing is highlighted. A high
flag rate means the ensemble is out of its depth on that hand, which is worth knowing before
you trust any single one of them on it.
Useful options:
| option | what it does |
|---|---|
--models N |
use the first N of the five defaults. Fewer models is faster, but flags more and reads worse, measured under eval below |
--backends a,b,c |
pick models by Hugging Face id, by alias, or by cached folder name |
--out DIR |
write reports somewhere other than <folder>/manyhands-out |
--page-timeout S |
stop a model after S seconds on one page and keep what it read. Default 600 |
--no-cache |
re-transcribe pages that are already in the cache |
--no-glossary |
ignore confirmed readings for this run |
--json FILE |
write a folder-level summary: slots, flags and the report path per page |
Every transcript is cached under <folder>/.manyhands/transcripts/<model>/ as it lands,
and a page already in the cache is not read again. A run killed on page 80 of 200 picks up
at page 80. Re-running after a confirm costs no GPU time at all.
confirm
manyhands confirm scans/parish-register/manyhands-out/journal-p001
Walks the flagged slots one at a time and asks which reading is right. You can type a
number to accept one of the offered readings, type your own, press Enter to skip, or q
to stop. For scripting, --slot 42 --reading Fenwick does one slot without prompting.
Decisions go into .manyhands/glossary.json, filed under the set of competing readings
rather than under a page and a slot. Confirming Fenwick over Renwick once settles every
later page where the same models produce the same argument.
confirm writes the glossary and nothing else. Run manyhands run <folder> again to rebuild
the reports with the confirmed readings applied and ticked. That second run reads every
transcript from the cache, so it costs no GPU time.
eval
manyhands eval datasets/celestine-doniau-danest/data --per-page
Expects each page image next to an ALTO or PAGE-XML file with the same stem, which is how HTR-United datasets ship. It answers the only question that matters for this tool: if a human reads only the highlighted words, how many of the real errors do they see, and how much do they have to read to see them.
It takes the same --models, --backends, --page-timeout and --no-cache options as
run, plus:
| option | what it does |
|---|---|
--per-page |
print a row per page as well as the totals |
--limit N |
score only the first N pages |
--out DIR |
also write the page reports and an index there |
--json FILE |
write the scores as JSON |
--target-capture F |
the capture the [met] line is judged against, default 0.70 |
--target-flag F |
the flag rate the [met] line is judged against, default 0.20 |
Two datasets, both published through HTR-United, both scored with the default five models on an RTX 4090. Neither is bundled here; clone dataset-celestine-doniau-danest and tapuscorpus if you want to reproduce these. The model loading and per-page progress lines are cut from the blocks, everything else is what the command printed.
1914 French cursive, four pages
$ manyhands eval datasets/celestine-doniau-danest/data --per-page
  10c3fa40-d683-4703-8bc4-94b48936ce85.jpg: capture 88%, flag 91%, CER 15.0%
  7f841dee-0d18-4eef-9966-f13cc9f4589c.jpg: capture 87%, flag 79%, CER 12.3%
  9ee628b4-e868-4236-a2bf-cd563acda597.jpg: capture 81%, flag 76%, CER 12.1%
  e1c22fc0-d84b-4d17-96fb-e3269b4d048d.jpg: capture 0%, flag 40%, CER 8.3%

page                                slots  flagged   flag%  capture%    CER%
----------------------------------------------------------------------------
10c3fa40-d683-4703-8bc4-94b48936c     690      627   90.9%     87.8%   15.0%
7f841dee-0d18-4eef-9966-f13cc9f45     402      316   78.6%     86.7%   12.3%
9ee628b4-e868-4236-a2bf-cd563acda     669      511   76.4%     81.1%   12.1%
e1c22fc0-d84b-4d17-96fb-e3269b4d0      15        6   40.0%      0.0%    8.3%

pages scored          4
slots                 1776
flagged slots         1460

error-capture rate    84.8%  (1105 of 1303 wrong characters sit in a flagged word)
flag rate             82.2%  (1460 of 1776 words highlighted for review)
consensus CER         13.2%

target                capture >= 70%, flag rate < 20%  [not met]
20th-century French typescript, four pages
Four pages of Franz Toussaint's Le Jardin des Caresses out of tapuscorpus, copied into one folder. tapuscorpus is much larger. Four pages is what 80 minutes of GPU time buys.
$ manyhands eval datasets/tapus-jardin --per-page
  16_7e494_default.jpg: capture 99%, flag 75%, CER 1311.1%
  18_9f102_default.jpg: capture 61%, flag 22%, CER 12.9%
  20_21abf_default.jpg: capture 54%, flag 25%, CER 23.2%
  22_c266f_default.jpg: capture 42%, flag 20%, CER 33.3%

page                                slots  flagged   flag%  capture%    CER%
----------------------------------------------------------------------------
16_7e494_default.jpg                   20       15   75.0%     99.1% 1311.1%
18_9f102_default.jpg                  129       28   21.7%     61.4%   12.9%
20_21abf_default.jpg                  129       32   24.8%     54.4%   23.2%
22_c266f_default.jpg                  177       35   19.8%     41.9%   33.3%

pages scored          4
slots                 455
flagged slots         110

error-capture rate    79.3%  (1243 of 1568 wrong characters sit in a flagged word)
flag rate             24.2%  (110 of 455 words highlighted for review)
consensus CER         63.9%

target                capture >= 70%, flag rate < 20%  [not met]
Read that honestly
The bar is catching at least 70% of the wrong characters while highlighting under 20% of the words. Neither dataset clears it, and they miss in opposite directions.
On the cursive the consensus is wrong about one character in eight, and the models disagree about four words in five. Capture is genuinely 85%: re-read only the highlighted words and you see five errors in six. But at an 82% flag rate you are re-reading nearly the whole page. On a hand this hard manyhands orders your attention, it does not save you the reading. The fourth page scoring 0% capture is fifteen words long with six wrong characters in them, which is sample size, not signal.
The typescript inverts it. Flag rate falls to about a fifth of the words, which is the number you want, and capture falls with it. Ignore the title page, discussed next, and the other three come to 48.0% capture (292 of 608 wrong characters) at a 21.8% flag rate, over a 24.8% CER. Half the errors are in words all five models agreed on, because on clean print the models are good enough to make the same mistakes. Agreement is evidence only when the voters are independent, and easy material makes them less so.
16_7e494_default.jpg and its 1311% CER is a ground-truth coverage artefact, not a transcription
failure. That page is a title page. The ALTO transcribes the seven-line title block and nothing
else, 72 characters, while the models read the whole page: the margin numbers 85 89 97 164 53
and a long decorative rule of dashes. So 1013 consensus characters are scored against 72 of truth
and almost everything counts as an error. Those 960 characters are 61% of the dataset's error
total, and since they sit in flagged words they are what lifts the headline capture to 79.3%.
Quote the per-page rows, not that number.
Fewer models is worse on both axes except capture. The same cursive dataset with three backends instead of five:
$ manyhands eval datasets/celestine-doniau-danest/data --per-page --backends olmocr,paddle,mineru
  10c3fa40-d683-4703-8bc4-94b48936ce85.jpg: capture 92%, flag 91%, CER 17.4%
  7f841dee-0d18-4eef-9966-f13cc9f4589c.jpg: capture 90%, flag 77%, CER 15.6%
  9ee628b4-e868-4236-a2bf-cd563acda597.jpg: capture 90%, flag 96%, CER 16.0%
  e1c22fc0-d84b-4d17-96fb-e3269b4d048d.jpg: capture 0%, flag 40%, CER 8.3%

page                                slots  flagged   flag%  capture%    CER%
----------------------------------------------------------------------------
10c3fa40-d683-4703-8bc4-94b48936c     684      620   90.6%     92.2%   17.4%
7f841dee-0d18-4eef-9966-f13cc9f45     387      299   77.3%     89.9%   15.6%
9ee628b4-e868-4236-a2bf-cd563acda    1835     1765   96.2%     90.0%   16.0%
e1c22fc0-d84b-4d17-96fb-e3269b4d0      15        6   40.0%      0.0%    8.3%

pages scored          4
slots                 2921
flagged slots         2690

error-capture rate    90.5%  (1465 of 1618 wrong characters sit in a flagged word)
flag rate             92.1%  (2690 of 2921 words highlighted for review)
consensus CER         16.4%

target                capture >= 70%, flag rate < 20%  [not met]
| backends | capture | flag rate | consensus CER |
|---|---|---|---|
| olmOCR-2, PaddleOCR-VL, MinerU2.5 | 90.5% | 92.1% | 16.4% |
| the default five | 84.8% | 82.2% | 13.2% |
Capture rises because the flags cover nearly everything, which is not a win. The transcript gets
worse and there is more of the page to re-read. Page 9ee628b4 shows where the extra 1166 slots
come from: MinerU2.5 returns 1725 tokens for that page against about 600 from every other model,
and with only three voters that run of repeated text survives into the consensus.
So: run it when the material is hard enough that models disagree usefully and your alternative is reading every word yourself. On clean print, a single good model plus a spellchecker will cost you a lot less.
How it works
Transcribe. Each backend returns the page as whatever it likes: markdown with tables,
HTML-ish layout markup, XML line elements, or a bare block of text. backends.py flattens
all of it to display lines so the aligner sees one grammar.
Align. align.py does anchor-based progressive multiple alignment, ROVER style. Tokens
whose normalised key occurs exactly once in every stream are certain matches, so they become
single-token columns and cut the page into independent gaps. Each gap is aligned the same
way recursively, because a key that was ambiguous over a whole page is usually unique inside
a twenty-token gap. When a gap has no anchors left it falls back to pairwise alignment
against the longest stream, which is where null tokens appear.
Vote. vote.py groups each column's readings by normalised key, takes the majority, and
records the agreement ratio. A tie goes to a reading the glossary already confirms, and
otherwise to the best-ranked backend holding it. The winner is marked contested in
agreement.json.
Locate. The models return text, not coordinates. layout.py finds the line bands itself:
Otsu threshold, a horizontal ink projection, a dense core per line grown out over its
ascenders and descenders, and the scanner's dark frame trimmed off first so it does not own
the profile. A document VLM returns a paragraph per entry rather than a line per line, so the
page is then treated as a ribbon: bands are handed to consensus lines in proportion to their
character count, and words are laid along the bands their line covers. The vertical band is
measured. The position along it is an estimate, which is why the report shows the whole line
crop with the slot boxed rather than a tight crop.
Worked example
Five models read a line of a parish register. Four return Fenwick and one returns
Renwick:
| model | reading |
|---|---|
| olmOCR-2 | Buried this day John Fenwick of the parish |
| PaddleOCR-VL | Buried this day John Fenwick of the parish |
| dots.ocr | Buried this day John Fenwick of the parish |
| MinerU2.5 | Buried this day John Fenwick of the parish |
| Nanonets-OCR2 | Buried this day John Renwick of the parish |
The consensus is Fenwick, agreement 0.8, drawn amber. Clicking it lists all five readings
next to the crop of that line.
Split the vote two ways and it gets more interesting. Two models read Fenwick, two read
Fenwich, one reads Renwick: agreement drops to 0.4, the word goes red, and the slot is
marked "contested": true because the plurality reading did not win outright.
Bands
| agreement | colour | meaning |
|---|---|---|
| 1.0 | none | every model read the same word |
| above 0.8 | pale | one dissenter in a large ensemble |
| 0.5 to 0.8 | amber | four of five, or three of four |
| below 0.5 | red | no reading held a majority |
Four models out of five is 0.8 and reads as amber, so the top of the amber band is inclusive.
Configuration
Default ensemble, in rank order. Rank breaks a tie the glossary does not.
| alias | model | params | weights |
|---|---|---|---|
olmocr |
allenai/olmOCR-2-7B-1025 |
7B | 16.6 GB |
paddle |
PaddlePaddle/PaddleOCR-VL-1.5 |
0.9B | 1.9 GB |
dots |
kristaller486/dots.ocr-1.5 |
3B | 6.1 GB |
mineru |
opendatalab/MinerU2.5-2509-1.2B |
1.2B | 2.3 GB |
nanonets |
nanonets/Nanonets-OCR2-3B |
3B | 7.5 GB |
dots.ocr-1.5 contributed nothing to any page reported here, in two different ways. On the two
sample pages it returns no text: no error, no timeout, zero tokens after 63s and 37s. On all
eight eval pages, cursive and typescript alike, it dies with CUDA out of memory. Tried to allocate 27.76 GiB on a 24 GB card. It asks for the whole page at native resolution, so what
kills it is scan size rather than the hand. It is still in the default five because it is a
capable model on smaller images and on a bigger card, and because ten pages from two documents
is thin evidence for editing a default. If it does this to you, the footer will say so and it
will stop being tried after the third page. Drop it outright with --backends if you would
rather not pay for those three.
Other aliases that resolve to models churro-ocr knows: olmocr-fp8, dots-mocr, chandra,
deepseek, glm, infinity, lfm, churro. Any Hugging Face id works too.
stanford-oval/churro-3B is opt-in and prints a notice when you use it. Its weights are
under the Qwen-research licence, not a permissive open-source licence, so it is not in the
default five. Check the terms before you use its output.
Diversity comes only from using different models. Four of the five default churro-ocr
profiles resolve to do_sample: False and olmOCR-2 to temperature: 0.1, so sampling one
model five times would return one answer five times. There is deliberately no temperature
path.
Performance
Measured on an RTX 4090 (24 GB), CUDA 12.8, weights already in the cache. The two sample pages with the default five took 28 minutes end to end, 12:16:08 to 12:44:15:
| page | five models | what dominates it |
|---|---|---|
journal-p001.jpg, a sparse title page, 11 words |
5m 14s | loading five sets of weights |
journal-p002.jpg, dense cursive, ~400 words |
22m 46s | PaddleOCR-VL alone, 810s of it |
The eight eval pages above ran the same five models. Excluding a nearly blank page that took 90 seconds, they ranged from 12 to 41 minutes each, median 15.6 minutes.
PaddleOCR-VL is usually more than half of that on its own. Over the seven dense eval pages it
spent 484s, 601s, 618s, 628s, 632s, 668s and 869s, against 42s to 418s for olmOCR-2 on the same
pages. Dropping it with --backends roughly halves the wall clock and costs you one vote.
manyhands runs one model over the whole folder, frees its weights, then loads the next, because five 3B to 7B models do not fit in 24 GB at once. So a two-page folder pays for five weight loads and a two-hundred-page folder also pays for five. Small folders carry a load tax that large ones amortise away, which is why the sparse title page above cost five minutes.
Budget this for a folder overnight, not for someone waiting at a terminal. Transcripts are
cached under .manyhands/transcripts, so re-running to rebuild the reports after confirm
costs no GPU time. None of these numbers include the 34 GB of first-use weight downloads
described under Install.
When a model misbehaves
The failure modes are not hypothetical, so each one has a defined behaviour.
A model crashes or will not download. That page records the failure, the rest of the ensemble votes without it, and the report footer says which model dropped out and why. A model that fails to load is not retried on later pages, and neither is one that fails three pages in a row. Running out of VRAM on an archive scan can cost ten minutes before it raises, so a backend that cannot handle your pages is not allowed to charge you for every one of them.
A model loops. Document VLMs fail by latching onto a phrase and emitting it until they run out of tokens. A transcript more than half covered by an immediately repeated n-gram is dropped from the vote and named in the footer.
A model runs long. After --page-timeout seconds of generation the model is stopped and
whatever it produced is kept, with a note on the transcript. Default 600 seconds. Not every
backend honours it. The deadline goes in as a transformers stopping criterion, and some churro
profiles reach generate by a path that never consults one, so the footer says which of the
two happened rather than claiming a stop that never came.
A model reads a different page. A transcript over 3x the page's median token count, or under a third of it, is dropped from the vote. Overshooting means it invented most of what it returned, undershooting means it stopped partway down the page, and either way the rest of its "reading" is silence rather than disagreement.
A model reads nothing. A backend that returns no text at all, on a page the others read
fine, is dropped exactly like one that crashed. Counting its silence as a dissenting vote
would flag every word on the page. dots.ocr-1.5 does this on both sample pages.
Too few models left. Below three usable voters the outlier rules are suspended, everyone is kept, and the notes say so. Dropping a model when only two are left is not a vote.
A blank page. If every model reads the page as empty, the consensus is empty and the page
is flagged blank. It does not emit whatever one model hallucinated.
Every model failed. manyhands run exits 3 rather than reporting a clean page with zero
flags.
One model listed twice. --backends olmocr,allenai/olmOCR-2-7B-1025 names one model two
ways. It votes once, and the run says so on stderr. A model cannot corroborate itself, and
counting it twice would report a lone reading as agreed.
Limitations
- Agreement is agreement, not accuracy. Models that share a base model can be confidently wrong together. An unflagged word is one nobody disagreed about, which is not the same as a word that is right. The eval numbers above are the honest measure of this.
- Case and edge punctuation are not disagreements. One model reading
JOURNALand anotherJournal,are grouped as the same word, because otherwise a page the models agree on perfectly lights up red. Letters and diacritics are never folded, since those are exactly the differences a palaeographer needs to see. Long s, ligatures and typographic quotes are folded. - Bounding boxes are estimates. The line band is measured from the ink. Which band a word lands on, and where along it, is proportional to character counts, so a model that dropped half a page drags its neighbours' boxes with it. Treat the box as a pointer at the line, not a measurement of the word.
- Multi-column and table pages are aligned per detected line block. v1 does not reconstruct a cross-column reading order, so a two-column page produces bands spanning both columns and the alignment will fight the reading order.
- No training, no cloud, no GUI. By design. See the non-goals below.
Prior art
Cross-model confidence voting in OCR is not new. Calamari-OCR has shipped voting across an ensemble of models for years, and it is the reference implementation for this idea in the HTR world. If you have segmented line images and can train your own models, use Calamari.
manyhands differs in three ways.
It votes across heterogeneous third-party document VLMs with different output grammars, rather than across a cross-fold ensemble of one architecture you trained yourself. Getting five different models' markdown, XML and layout markup into one comparable token stream is most of the work.
It works on whole page scans with no ground truth and no line segmentation, rather than on pre-segmented line images.
Most of all, it spends the disagreement on the human rather than on the transcript. Calamari uses the vote to produce one better line. manyhands shows you the vote, per word, next to the image, because on historical material the value of knowing a word is uncertain is higher than the value of a marginally better guess at it.
If you run it on your own material
The eval numbers above come from eight pages: four of one 1914 French diary and four of one
20th-century French typescript. Two hands is not a corpus. Whether an ensemble catches errors
on your hand is an empirical question, and the answer changes with the script, the century and
the language. If you have an HTR-United dataset, or any folder of pages with ALTO or PAGE-XML
beside them, manyhands eval on it is one command.
Open an issue with the error-capture and flag rates you got, the hand, and the backends you
used. Numbers from other people's material are the most useful thing this project can
receive right now, and the ones that hold up go in this README.
Status
1.0.0, and the trove classifier still says Beta, which is the honest pair. Everything documented here runs and is covered by tests. What is thin is the evidence: eight scored pages from two documents, one hand each, on one GPU. Nothing here has met a hand it was not developed against.
Distribution plan, such as it is. PyPI first, because every other step needs an install command that works. Then one write-up in r/LocalLLaMA led with the numbers above, the 48.0% capture on typescript included, since a post that only quotes 79.3% would be the exact overclaim this tool exists to argue against.
Non-goals
No model training or fine-tuning. No cloud or API backends. No layout editor. No translation. No GUI app. No hosted service. No model weights shipped in this package.
Development
git clone https://github.com/Booyaka101/manyhands
cd manyhands
python -m venv .venv && .venv/Scripts/activate    # or source .venv/bin/activate
pip install -e '.[dev]'
pytest
ruff check .
backends.py carries one upstream workaround. Four of churro-ocr 0.3.0's preset backends,
two of them in the default five, combine @dataclass(slots=True) with a zero-argument
super(), which raises TypeError before any weights load. repair_preset_super() patches
the stale __class__ cell at load time. It only matters on Python 3.12: 3.13 repoints the cell
itself when the slotted dataclass is rebuilt, so on 3.13 the function finds nothing to do and
the presets work unpatched. The draft issue is in
docs/churro-issue.md,
and the workaround comes out when a churro-ocr release carries the fix.
The test suite runs without a GPU and without torch, on Linux and Windows, on 3.12 and 3.13.
.github/workflows/ci.yml runs ruff and pytest over that matrix. The integration tests drive the whole
pipeline from committed transcript fixtures under tests/data/pages/.manyhands/transcripts/,
which are real output from three of the default models, frozen. Those fixtures are test-only;
nothing in the shipped package reads them.
Licence
MIT. See LICENSE.
The two sample pages under tests/data/pages/ come from the
Célestine Doniau-Danest journal
dataset, CC-BY-4.0. The eval numbers above also use
tapuscorpus, CC-BY-4.0, which is not bundled here.
Both are published through HTR-United. Model weights are downloaded from Hugging Face and carry
their own licences.
1 maintainer

Release files for manyhands 1.0.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| manyhands-1.0.0.tar.gz | 1.1 MB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| manyhands-1.0.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 1.2 MB
Release files / manyhands-1.0.0.tar.gz
| Download URL | manyhands-1.0.0.tar.gz |
|---|---|
| Size | 1.1 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
af185a8cf699b039141e86fa866e4e6a7853f4af35b0a1d1cf77b0f327b23323
|
|
BLAKE2b-256 checksum How to use checksums |
d147c3096559d969c4d415707ed896e35ef6679e935cac82f773aa0af130c123
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.12.10
|
Release files / manyhands-1.0.0-py3-none-any.whl
| Download URL | manyhands-1.0.0-py3-none-any.whl |
|---|---|
| Size | 61.6 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
ee2f3ddd0776eb1faa4e7d870e220dee792d128e06edd07bae34c448711bc7d1
|
|
BLAKE2b-256 checksum How to use checksums |
8a563b2a20234397c82cf7c2086fdd3cb1746bc76ec0df6dda190a87db054434
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.12.10
|













