
MassSpecGym: A benchmark for the discovery and identification of molecules




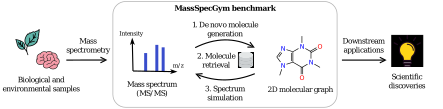
MassSpecGym provides three challenges for benchmarking the discovery and identification of new molecules from MS/MS spectra:
- 💥 De novo molecule generation (MS/MS spectrum → molecular structure)
- ✨ Bonus chemical formulae challenge (MS/MS spectrum + chemical formula → molecular structure)
- 💥 Molecule retrieval (MS/MS spectrum → ranked list of candidate molecular structures)
- ✨ Bonus chemical formulae challenge (MS/MS spectrum → ranked list of candidate molecular structures with ground-truth chemical formulae)
- 💥 Spectrum simulation (molecular structure → MS/MS spectrum)
- ✨ Bonus chemical formulae challenge (molecular structure → MS/MS spectrum; evaluated on the retrieval of molecular structures with ground-truth chemical formulae)
The provided challenges abstract the process of scientific discovery from biological and environmental samples into well-defined machine learning problems with pre-defined datasets, data splits, and evaluation metrics.
📚 Please see more details in our NeurIPS 2024 Spotlight paper.
📦 Installation
Installation is available via pip:
pip install massspecgym
If you use conda, we recommend creating and activating a new environment before installing MassSpecGym:
conda create -n massspecgym python==3.11
conda activate massspecgym
If you are planning to run Jupyter notebooks provided in the repository or contribute to the project, we recommend installing the optional dependencies:
pip install massspecgym[notebooks, dev]
🍩 Getting started with MassSpecGym

MassSpecGym’s infrastructure consists of predefined components that serve as building blocks for the implementation and evaluation of new models.
First of all, the MassSpecGym dataset is available as a Hugging Face dataset and can be downloaded within the code into a pandas DataFrame as follows.
from massspecgym.utils import load_massspecgym
df = load_massspecgym()
Second, MassSpecGym provides a set of transforms for spectra and molecules, which can be used to preprocess data for machine learning models. These transforms can be used in conjunction with the MassSpecDataset class (or its subclasses), resulting in a PyTorch Dataset object that implicitly applies the specified transforms to each data point. Note that MassSpecDataset also automatically downloads the dataset from the Hugging Face repository as needed.
from massspecgym.data import MassSpecDataset
from massspecgym.transforms import SpecTokenizer, MolFingerprinter

dataset = MassSpecDataset(
    spec_transform=SpecTokenizer(n_peaks=60),
    mol_transform=MolFingerprinter(),
)
Third, MassSpecGym provides a MassSpecDataModule, a PyTorch Lightning LightningDataModule that automatically handles data splitting into training, validation, and testing folds, as well as loading data into batches.
from massspecgym.data import MassSpecDataModule

data_module = MassSpecDataModule(
    dataset=dataset,
    batch_size=32
)
Finally, MassSpecGym defines evaluation metrics by implementing abstract subclasses of LightningModule for each of the MassSpecGym challenges: DeNovoMassSpecGymModel, RetrievalMassSpecGymModel, and SimulationMassSpecGymModel. To implement a custom model, you should inherit from the appropriate abstract class and implement the forward and step methods. This procedure is described in the next section. If you looking for more examples, please see the massspecgym/models folder.
🚀 Train and evaluate your model
MassSpecGym allows you to implement, train, validate, and test your model with a few lines of code. Built on top of PyTorch Lightning, MassSpecGym abstracts data preparation and splitting while eliminating boilerplate code for training and evaluation loops. To train and evaluate your model, you only need to implement your custom architecture and prediction logic.
Below is an example of how to implement a simple model based on DeepSets for the molecule retrieval task. The model is trained to predict the fingerprint of a molecule from its spectrum and then retrieves the most similar molecules from a set of candidates based on fingerprint similarity. For more examples, please see notebooks/demo.ipynb.
- Import necessary modules:
import torch
import torch.nn as nn
import pytorch_lightning as pl
from pytorch_lightning import Trainer

from massspecgym.data import RetrievalDataset, MassSpecDataModule
from massspecgym.data.transforms import SpecTokenizer, MolFingerprinter
from massspecgym.models.base import Stage
from massspecgym.models.retrieval.base import RetrievalMassSpecGymModel
- Implement your model:
class MyDeepSetsRetrievalModel(RetrievalMassSpecGymModel):
    def __init__(
        self,
        hidden_channels: int = 128,
        out_channels: int = 4096,  # fingerprint size
        *args,
        **kwargs
    ):
        """Implement your architecture."""
        super().__init__(*args, **kwargs)

        self.phi = nn.Sequential(
            nn.Linear(2, hidden_channels),
            nn.ReLU(),
            nn.Linear(hidden_channels, hidden_channels),
            nn.ReLU(),
        )
        self.rho = nn.Sequential(
            nn.Linear(hidden_channels, hidden_channels),
            nn.ReLU(),
            nn.Linear(hidden_channels, out_channels),
            nn.Sigmoid()
        )

    def forward(self, x: torch.Tensor) -> torch.Tensor:
        """Implement your prediction logic."""
        x = self.phi(x)
        x = x.sum(dim=-2)  # sum over peaks
        x = self.rho(x)
        return x

    def step(
        self, batch: dict, stage: Stage
    ) -> tuple[torch.Tensor, torch.Tensor]:
        """Implement your custom logic of using predictions for training and inference."""
        # Unpack inputs
        x = batch["spec"]  # input spectra
        fp_true = batch["mol"]  # true fingerprints
        cands = batch["candidates"]  # candidate fingerprints concatenated for a batch
        batch_ptr = batch["batch_ptr"]  # number of candidates per sample in a batch

        # Predict fingerprint
        fp_pred = self.forward(x)

        # Calculate loss
        loss = nn.functional.mse_loss(fp_true, fp_pred)

        # Calculate final similarity scores between predicted fingerprints and retrieval candidates
        fp_pred_repeated = fp_pred.repeat_interleave(batch_ptr, dim=0)
        scores = nn.functional.cosine_similarity(fp_pred_repeated, cands)

        return dict(loss=loss, scores=scores)
- Train and validate your model:
# Init hyperparameters
n_peaks = 60
fp_size = 4096
batch_size = 32

# Load dataset
dataset = RetrievalDataset(
    spec_transform=SpecTokenizer(n_peaks=n_peaks),
    mol_transform=MolFingerprinter(fp_size=fp_size),
)

# Init data module
data_module = MassSpecDataModule(
    dataset=dataset,
    batch_size=batch_size,
    num_workers=4
)

# Init model
model = MyDeepSetsRetrievalModel(out_channels=fp_size)

# Init trainer
trainer = Trainer(accelerator="cpu", devices=1, max_epochs=5)

# Train
trainer.fit(model, datamodule=data_module)
- Test your model:
# Test
trainer.test(model, datamodule=data_module)
🏅 Submit your results to the leaderboard
The MassSpecGym leaderboard is available on the Papers with Code website. To submit your results, please see the following tutorial.
🔗 References
If you use MassSpecGym in your work, please cite the following paper:
@article{bushuiev2024massspecgym,
      title={MassSpecGym: A benchmark for the discovery and identification of molecules},
      author={Roman Bushuiev and Anton Bushuiev and Niek F. de Jonge and Adamo Young and Fleming Kretschmer and Raman Samusevich and Janne Heirman and Fei Wang and Luke Zhang and Kai Dührkop and Marcus Ludwig and Nils A. Haupt and Apurva Kalia and Corinna Brungs and Robin Schmid and Russell Greiner and Bo Wang and David S. Wishart and Li-Ping Liu and Juho Rousu and Wout Bittremieux and Hannes Rost and Tytus D. Mak and Soha Hassoun and Florian Huber and Justin J. J. van der Hooft and Michael A. Stravs and Sebastian Böcker and Josef Sivic and Tomáš Pluskal},
      year={2024},
      eprint={2410.23326},
      url={https://arxiv.org/abs/2410.23326},
      doi={10.48550/arXiv.2410.23326}
}
1 maintainer

Metadata
1 maintainer
Release files for massspecgym 1.3.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| massspecgym-1.3.1.tar.gz | 89.2 kB | Without provenance | Details for massspecgym-1.3.1.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| massspecgym-1.3.1-py3-none-any.whl | Python 3 | none | any | Details for massspecgym-1.3.1-py3-none-any.whl |
Total release size: 183.3 kB
Release files / massspecgym-1.3.1.tar.gz
| Download URL | massspecgym-1.3.1.tar.gz |
|---|---|
| Size | 89.2 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
cf63a77bba36505572286cbbc4ac7e56f2606b890e051050d7034baf8320dc84
|
|
BLAKE2b-256 checksum How to use checksums |
3688577fd8dd5a4135d115d7e74588911a3c83d752778b39ea48166d305491b0
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/5.1.1 CPython/3.11.9
|
Release files / massspecgym-1.3.1-py3-none-any.whl
| Download URL | massspecgym-1.3.1-py3-none-any.whl |
|---|---|
| Size | 94.1 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
5ce66520b8a968415e81ce0b45e4f8e3f9cdf4d18d31bfb2e0f0038e7d0e8ae0
|
|
BLAKE2b-256 checksum How to use checksums |
e51094d6c81d357d0e33e11fa37f63952ef213f2fd4c0c6665f35957823995c9
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/5.1.1 CPython/3.11.9
|
Security for massspecgym 1.3.1
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














