
mcp-memory-service
Persistent Shared Memory for AI Agent Pipelines
Open-source memory backend for AI agents — REST API, MCP, OAuth, CLI, dashboard. One self-hosted service, every transport. Agents store decisions, share causal knowledge graphs, and retrieve context in 5ms — without cloud lock-in or API costs.
Works with LangGraph · CrewAI · AutoGen · any HTTP client · Claude Desktop · OpenCode


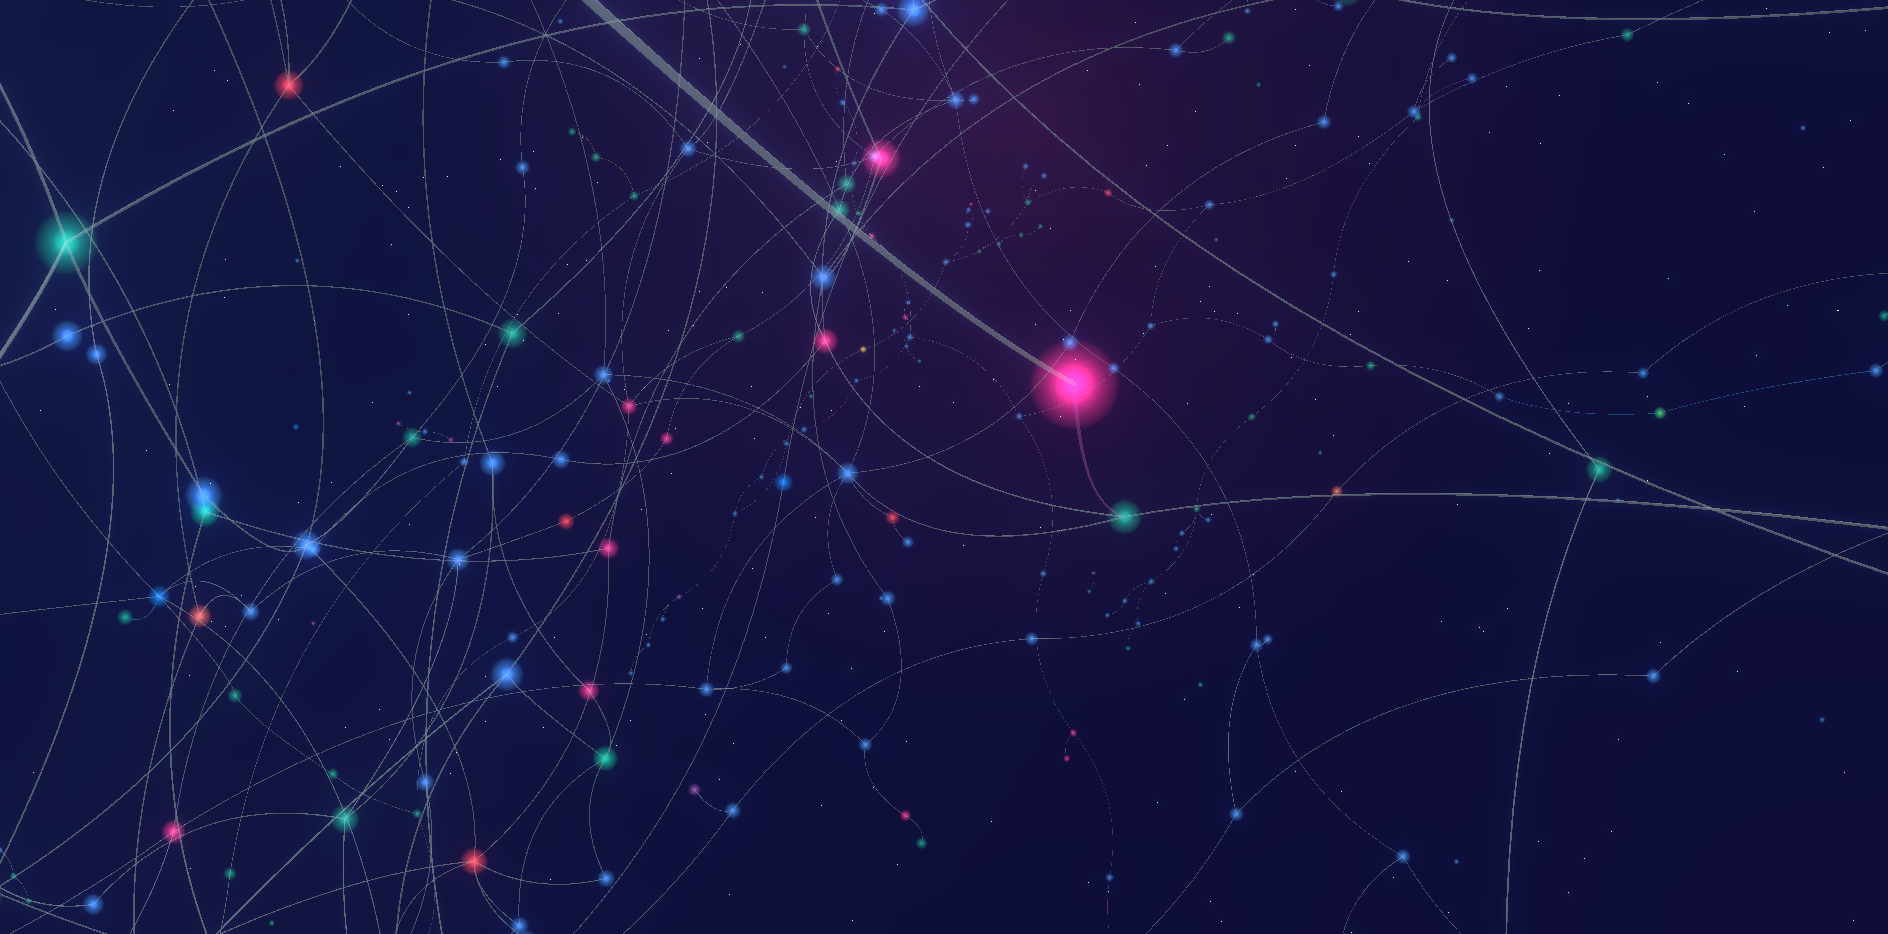
▶ The 3D knowledge graph in motion — every memory a glowing node, every relationship a curved edge.
Why Agents Need This
Your AI assistant forgets everything when you start a new chat. You spend 10 minutes re-explaining your architecture. Again. MCP Memory Service captures project context, architecture decisions, and code patterns automatically — new sessions start with everything already known.
| Without mcp-memory-service | With mcp-memory-service |
|---|---|
| Each agent run starts from zero | Agents retrieve prior decisions in 5ms |
| Memory is local to one graph/run | Memory is shared across all agents and runs |
| You manage Redis + Pinecone + glue code | One self-hosted service, zero cloud cost |
| No causal relationships between facts | Knowledge graph with typed edges (causes, fixes, contradicts) |
| Context window limits create amnesia | Autonomous consolidation compresses old memories |
Key capabilities for agent pipelines:
- Framework-agnostic REST API — no MCP client library needed; the live endpoint list is at
/api/docs - Knowledge graph — agents share causal chains, not just facts
X-Agent-IDheader — auto-tag memories by agent identity for scoped retrievalconversation_id— bypass deduplication for incremental conversation storage- SSE events — real-time notifications when any agent stores or deletes a memory
- Embeddings run locally via ONNX — memory never leaves your infrastructure
🚀 Get Started in 60 Seconds
Not sure which setup fits? The Setup Guide walks you to the right path in under a minute.
1. Install:
pip install mcp-memory-service
2. Configure your AI client:
Claude Desktop
Add to your config file:
- macOS:
~/Library/Application Support/Claude/claude_desktop_config.json - Windows:
%APPDATA%\Claude\claude_desktop_config.json - Linux:
~/.config/Claude/claude_desktop_config.json
{
  "mcpServers": {
    "memory": {
      "command": "memory",
      "args": ["server"]
    }
  }
}
Restart Claude Desktop. Your AI now remembers everything across sessions.
Claude Code
claude mcp add memory -- memory server
Restart Claude Code. Memory tools will appear automatically.
Agent pipelines (REST API — LangGraph, CrewAI, AutoGen, any HTTP client)
MCP_ALLOW_ANONYMOUS_ACCESS=true memory server --http
# REST API running at http://localhost:8000
Store a memory with POST /api/memories, search with POST /api/search, retrieve by tag
with POST /api/search/by-tag. Send X-Agent-ID: <id> on a store request and the server
tags the memory agent:<id>, which a tag search then scopes retrieval by.
Worked examples per framework, the tag conventions and the async patterns: docs/agents/
OpenCode
MCP_ALLOW_ANONYMOUS_ACCESS=true memory server --http
The plugin ships as repository files for the local plugin directory, so clone the
repository once even if you installed from PyPI. Install steps, the /memory slash
command and the endpoint override:
opencode/README.md
Codex (automatic memory hooks)
Start the Memory Service HTTP API, then install the hooks from this repository:
python3 codex/install_hooks.py
Restart Codex and review the hooks with /hooks. They retrieve project context,
capture new learnings, and checkpoint outcomes before compaction and at session end.
See Codex hook setup for prerequisites, authentication, and project-local installation.
claude.ai and ChatGPT (browser — Remote MCP)
Remote MCP puts persistent memory in the browser on any device, no desktop app required: OAuth 2.0 over HTTPS, self-hosted or cloud-hosted. Both claude.ai and ChatGPT (Developer Mode) connect to the same endpoint.
Cloudflare Tunnel quick start, Let's Encrypt, nginx, Caddy and Docker production setups: Remote MCP Setup · 5-minute tutorial
Advanced: custom backends and team setup
git clone https://github.com/doobidoo/mcp-memory-service.git
cd mcp-memory-service
python scripts/installation/install.py
Choose from SQLite (local, fast, single-user), Cloudflare (cloud, multi-device
sync), Hybrid (5ms local reads with background cloud sync — recommended for
production) or Milvus (dedicated vector DB: Lite file, self-hosted, or Zilliz Cloud).
For self-hosted team setups, the Hybrid backend can sync to another HTTP MCP Memory Service
instead of Cloudflare using MCP_HYBRID_SECONDARY_BACKEND=http.
For long-lived services, prefer Docker Milvus or Zilliz Cloud over Milvus Lite — why.
⚡ Works With Your Favorite AI Tools
- Agent frameworks (REST): LangGraph · CrewAI · AutoGen · OpenClaw/Nanobot · any HTTP client
- CLI and terminal (MCP): Claude Code · Gemini CLI · OpenCode · Codex CLI · Goose · Aider · Amp
- Desktop and IDE (MCP): Claude Desktop · VS Code · Cursor · Windsurf · Raycast · JetBrains · Zed
- Chat (MCP): ChatGPT (Developer Mode) · claude.ai (Remote MCP over HTTPS)
Full list, plus clients without OAuth such as Home Assistant: docs/integrations.md
✨ Features
Store and retrieve context
- 🧠 Persistent memory — Keep decisions, notes, and project context across sessions and agents.
- 🔍 Semantic and keyword search — Combine vector search with BM25; use
mode="ranked"to weigh recency, access frequency, and quality. An optional fallback cascade tries exact and tag matching when semantic results are sparse. - 🏷️ Scoped retrieval — Filter by tags with AND/OR matching, natural-language time
ranges, and store partitions (
default,docs, orallfor cross-store search). - 📝 Optional search summaries — Request
summarize=truefor query-aware summaries with validated source references. RequiresMCP_SEARCH_SUMMARIZE_ENABLED=trueand a configured LLM provider; unavailable summaries fall back to raw results. Search API and examples - 📄 Document ingestion — Import PDF, text, and Markdown with chunking for retrieval. Additional formats such as DOCX and PPTX require optional parsing tools. Document ingestion guide
Capture and maintain knowledge
- ⚡ Automatic session capture — Configurable Claude Code hooks retrieve context and
save session learnings; the local
memory_harvesttool extracts decisions, bugs, conventions, and lessons from transcripts. Hooks setup · Harvest configuration - 💡 Autonomous consolidation — Schedule clustering, compression, association discovery, and controlled forgetting. Insight cards surface patterns, trends, and knowledge gaps. Consolidation guide
- 💭 Beliefs and contradiction handling — Derive confidence-scored beliefs from observations. Heuristic contradiction detection can mark older memories as superseded, hiding them from default retrieval while retaining them for explicit lookup.
- 🤖 Agent bootstrap profiles —
get_bootstrap_profileassembles behavioral context for a new agent within a token budget, with optional task-aware retrieval. RequiresMCP_BOOTSTRAP_ENABLED=true; profiles are not isolated by project. - 🧬 Knowledge graph and entities — Explore typed causal relationships in the interactive graph. 🔗 Entity extraction links @mentions, #tags, URLs, and file paths to a queryable entity graph. Knowledge graph guide
- 🏠 Quality scoring — Use your own OpenAI-compatible endpoint, including Ollama, LiteLLM, or vLLM. Configuration guide
Run locally and share across devices
- 🔒 Local-first storage — Local ONNX embeddings and SQLite storage keep core memory operations on your infrastructure. Optional LLM features use the providers you configure.
- ☁️ Cloud or self-hosted sync — Use Cloudflare or another MCP Memory Service instance as a Hybrid secondary. Separately enabled delta-sync exchanges changes between hosts; it is off by default. Self-hosted sync guide
- 📦 Import, export, and migration — Move memories through JSON import/export, including conversion of mem0 exports. Import/export tools · mem0 migration guide
- 💾 Database backups — Configure scheduled backups or trigger one manually through
the HTTP API. Inspect backup status and available snapshots through the backup endpoints
in the live API reference at
/api/docs. - 📊 Web dashboard — Search, browse, visualize, and manage memories at
http://localhost:8000.
The dashboard has eight tabs — Dashboard, Search, Browse, Documents, Manage, Analytics, Quality, API Docs. Two-minute walkthrough on YouTube · Web Dashboard Guide
How it compares to Mem0, Zep and the MCP-native alternatives, benchmark results, and deployments people run in production: mcpmemory.services
🛠️ Configuration Highlights
memory launch                  # Start HTTP server in background (127.0.0.1:8000)
memory launch --port 8192      # Custom port
memory info                    # Status and health
memory logs --lines 50         # Recent logs
memory stop                    # Stop server
These commands are optimized for fast startup and avoid loading heavy ML dependencies unless needed.
⚠️ Security note: the server binds to
127.0.0.1(localhost only) by default.--host 0.0.0.0/MCP_HTTP_HOST=0.0.0.0exposes the API to your network — do that only in trusted environments with authentication and firewall rules, or behind TLS termination or a VPN overlay.
Backends, embedding models, quality scoring and every environment variable: Configuration Guide
📚 Documentation
- Setup Guide – Decision tree and step-by-step paths
- Agent Integration Guides – LangGraph, CrewAI, AutoGen, HTTP generic
- Remote MCP Setup – claude.ai and ChatGPT via HTTPS + OAuth
- Configuration Guide – Backend options and customization
- Architecture Overview – How it works under the hood
- Knowledge Graph Dashboard – Interactive graph visualization
- Benchmarks – LongMemEval, DevBench, LoCoMo, with run commands
- Migration Guide – Upgrading between major versions
- Troubleshooting – Common issues and solutions
- Wiki – Long-form guides and API reference
- Full documentation index – Everything else
Also listed on Glama and Spark.
📦 Releases
Every release, with upgrade notes: CHANGELOG.md · GitHub Releases · archived history
🤝 Contributing
We welcome contributions! See CONTRIBUTING.md for guidelines and SECURITY.md for reporting a vulnerability.
Releases, good first issues and new Discussions are announced on our Discord server, which is also the place for informal chat. Claiming an issue, decisions and reviews stay on GitHub.
Who authors this project, who holds copyright, and what every change passes before
it reaches main: AUTHORSHIP.md.
Quick Development Setup:
git clone https://github.com/doobidoo/mcp-memory-service.git
cd mcp-memory-service
pip install -e .  # Editable install
pytest tests/      # Run test suite
Supporting the Project
MCP Memory Service is maintained by one person. If it saves you or your company time, you can support its development via Ko-fi, Buy Me a Coffee or PayPal: SPONSORS.md.
1 maintainer

Metadata
1 maintainer
Release files for mcp-memory-service-lite 12.2.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| mcp_memory_service_lite-12.2.0.tar.gz | 43.6 MB | Without provenance | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| mcp_memory_service_lite-12.2.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 45.0 MB
Release files / mcp_memory_service_lite-12.2.0.tar.gz
| Download URL | mcp_memory_service_lite-12.2.0.tar.gz |
|---|---|
| Size | 43.6 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
4f207c04fcae3cd83487bcc988d6022864af7accff2e41b61fbe52ae264ada39
|
|
BLAKE2b-256 checksum How to use checksums |
93a0894bd1edef0247b8fbea5a81f2b1c5a5ba48c77a36e879494369ec00a5cd
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.12.3
|
Release files / mcp_memory_service_lite-12.2.0-py3-none-any.whl
| Download URL | mcp_memory_service_lite-12.2.0-py3-none-any.whl |
|---|---|
| Size | 1.4 MB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
4a6696dc050eb591d46febb975dc9f588d3e51838883df1d5999e1b21be400ee
|
|
BLAKE2b-256 checksum How to use checksums |
45c709da41ea95c880b74f8d57671a0d7a9ce2e2eba027047d7da720320c18d0
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.12.3
|
Security for mcp-memory-service-lite 12.2.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.














