
MCUNet: Tiny Deep Learning on IoT Devices
website | paper | demo
News
- (2022/06) We refactor the MCUNet repo as a standalone repo (previous repo: https://github.com/mit-han-lab/tinyml)
- (2021/10) Checkout our new paper MCUNetV2: https://arxiv.org/abs/2110.15352 !
- Our projects are covered by: MIT News, WIRED, Morning Brew, Stacey on IoT, Analytics Insight, Techable, etc.
Overview
Microcontrollers are low-cost, low-power hardware. They are widely deployed and have wide applications.

But the tight memory budget (50,000x smaller than GPUs) makes deep learning deployment difficult.

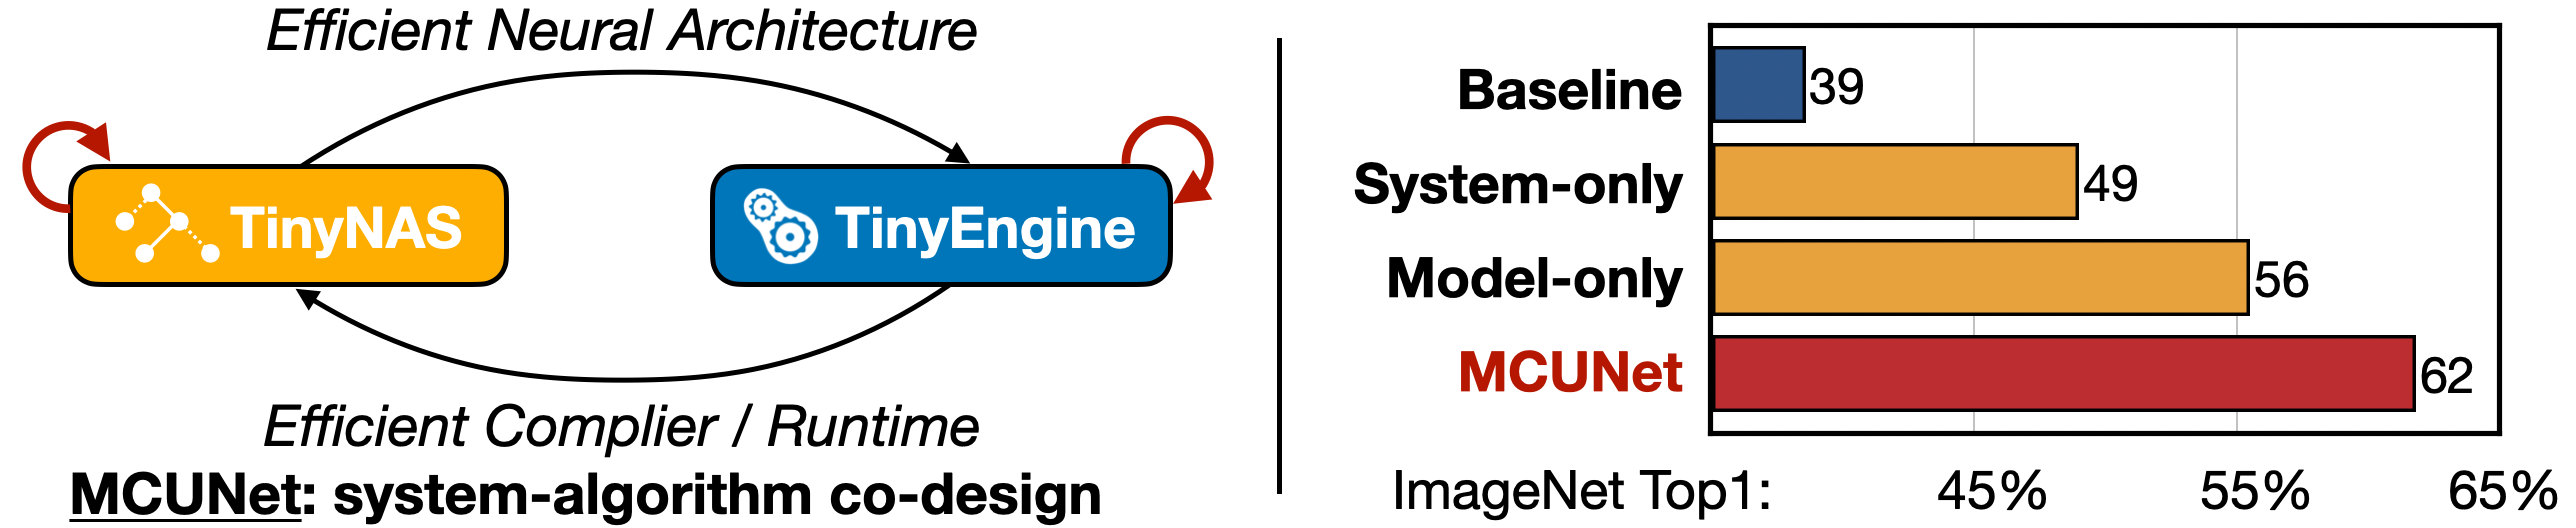
MCUNet is a system-algorithm co-design framework for tiny deep learning on microcontrollers. It consists of TinyNAS and TinyEngine. They are co-designed to fit the tight memory budgets.
With system-algorithm co-design, we can significantly improve the deep learning performance on the same tiny memory budget.
Our TinyEngine inference engine could be a useful infrastructure for MCU-based AI applications. It significantly improves the inference speed and reduces the memory usage compared to existing libraries like TF-Lite Micro, CMSIS-NN, MicroTVM, etc. It improves the inference speed by 1.5-3x, and reduces the peak memory by 2.7-4.8x.

Model Zoo
Usage
You can build the pre-trained PyTorch fp32 model or the int8 quantized model in TF-Lite format.
from mcunet.model_zoo import net_id_list, build_model, download_tflite
print(net_id_list)  # the list of models in the model zoo

# pytorch fp32 model
model, image_size, description = build_model(net_id="mcunet-320kb-in", pretrained=True)  # you can replace net_id with any other option from net_id_list

# download tflite file to tflite_path
tflite_path = download_tflite(net_id="mcunet-320kb-in")
Evaluate
To evaluate the accuracy of PyTorch fp32 models, run:
python eval_torch.py --net_id mcunet-320kb-in --dataset {imagenet/vww} --data-dir PATH/TO/DATA/val
To evaluate the accuracy of TF-Lite int8 models, run:
python eval_tflite.py --net_id mcunet-320kb-in --dataset {imagenet/vww} --data-dir PATH/TO/DATA/val
Model List
- Note that all the latency, SRAM, and Flash usage are profiled with TinyEngine.
- Here we only provide the
int8quantized modes.int4quantized models (as shown in the paper) can further push the accuracy-memory trade-off, but lacking a general format support. - For accuracy (top1, top-5), we report the accuracy of
fp32/int8models respectively
The ImageNet model list:
| net_id | MACs | #Params | SRAM | Flash | Top-1 (fp32/int8) |
Top-5 (fp32/int8) |
|---|---|---|---|---|---|---|
| # baseline models | ||||||
| mbv2-320kb-in | 23.5M | 0.75M | 308kB | 862kB | 49.7%/49.0% | 74.6%/73.8% |
| proxyless-320kb-in | 38.3M | 0.75M | 292kB | 892kB | 57.0%/56.2% | 80.2%/79.7% |
| # mcunet models | ||||||
| mcunet-10fps-in | 6.4M | 0.75M | 266kB | 889kB | 41.5%/40.4% | 66.3%/65.2% |
| mcunet-5fps-in | 12.8M | 0.64M | 307kB | 992kB | 51.5%/49.9% | 75.5%/74.1% |
| mcunet-256kb-in | 67.3M | 0.73M | 242kB | 878kB | 60.9%/60.3% | 83.3%/82.6% |
| mcunet-320kb-in | 81.8M | 0.74M | 293kB | 897kB | 62.2%/61.8% | 84.5%/84.2% |
| mcunet-512kb-in | 125.9M | 1.73M | 456kB | 1876kB | 68.4%/68.0% | 88.4%/88.1% |
The VWW model list:
Note that the VWW dataset might be hard to prepare. You can download our pre-built minival set from here, around 380MB.
| net_id | MACs | #Params | SRAM | Flash | Top-1 (fp32/int8) |
|---|---|---|---|---|---|
| mcunet-10fps-vww | 6.0M | 0.37M | 146kB | 617kB | 87.4%/87.3% |
| mcunet-5fps-vww | 11.6M | 0.43M | 162kB | 689kB | 88.9%/88.9% |
| mcunet-320kb-vww | 55.8M | 0.64M | 311kB | 897kB | 91.7%/91.8% |
For TF-Lite int8 models we do not use quantization-aware training (QAT), so some results is slightly lower than paper numbers.
Requirement
-
Python 3.6+
-
PyTorch 1.4.0+
-
Tensorflow 1.15 (if you want to test TF-Lite models; CPU support only)
Acknowledgement
We thank MIT Satori cluster for providing the computation resource. We thank MIT-IBM Watson AI Lab, SONY, Qualcomm, NSF CAREER Award #1943349 and NSF RAPID Award #2027266 for supporting this research.
Citation
If you find the project helpful, please consider citing our paper:
@article{lin2020mcunet,
  title={Mcunet: Tiny deep learning on iot devices},
  author={Lin, Ji and Chen, Wei-Ming and Lin, Yujun and Gan, Chuang and Han, Song},
  journal={Advances in Neural Information Processing Systems},
  volume={33},
  year={2020}
}

@inproceedings{
  lin2021mcunetv2,
  title={MCUNetV2: Memory-Efficient Patch-based Inference for Tiny Deep Learning},
  author={Lin, Ji and Chen, Wei-Ming and Cai, Han and Gan, Chuang and Han, Song},
  booktitle={Annual Conference on Neural Information Processing Systems (NeurIPS)},
  year={2021}
}
Related Projects
TinyTL: Reduce Memory, Not Parameters for Efficient On-Device Learning (NeurIPS'20)
Once for All: Train One Network and Specialize it for Efficient Deployment (ICLR'20)
ProxylessNAS: Direct Neural Architecture Search on Target Task and Hardware (ICLR'19)
AutoML for Architecting Efficient and Specialized Neural Networks (IEEE Micro)
AMC: AutoML for Model Compression and Acceleration on Mobile Devices (ECCV'18)
HAQ: Hardware-Aware Automated Quantization (CVPR'19, oral)
1 maintainer

Metadata
1 maintainer
Release files for mcunet 0.1.1.post202206152022
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| mcunet-0.1.1.post202206152022-py3-none-any.whl | Python 3 | none | any | Details |
Release files / mcunet-0.1.1.post202206152022-py3-none-any.whl
| Download URL | mcunet-0.1.1.post202206152022-py3-none-any.whl |
|---|---|
| Size | 38.9 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
af640621d108dc42496cd9a25b86573598c882089a38fb67d09b85eeb375b6d8
|
|
BLAKE2b-256 checksum How to use checksums |
746fb1c1bb2b0b6628627c43ce767ef82e35a862f1aab60b9edd3e3c6ea72b5c
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/4.0.1 CPython/3.7.13
|
Security for mcunet 0.1.1.post202206152022
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














