
memdex
Shared, token-saving memory for AI coding agents.
One SQLite file. Zero dependencies. Any MCP client. Claude Code, Codex, Cursor and DeepSeek can all remember the same things — and talk to each other.


Quick start · How it works · Tools · CLI · Configuration · Comparison · FAQ · 한국어
Every new agent session starts from nothing. It re-reads the same 3,000-token files, re-runs the same searches and re-discovers the same pitfalls — and you pay for every token of it. When several agents work on one machine, they can't see what the others learned, or that another one is editing the same file right now.
memdex is a small MCP server that fixes both:
- A file summary written once stays valid until the file's content changes. Summaries are keyed to the sha256 of the content, not the path. The next session — or the next agent — gets a 100-token summary instead of the 3,000-token file, and is told the moment it goes stale.
- Notes know when they rot. Decisions, pitfalls and handoffs cite the files they're based on; when those files change, the note is flagged.
- Agents coordinate.
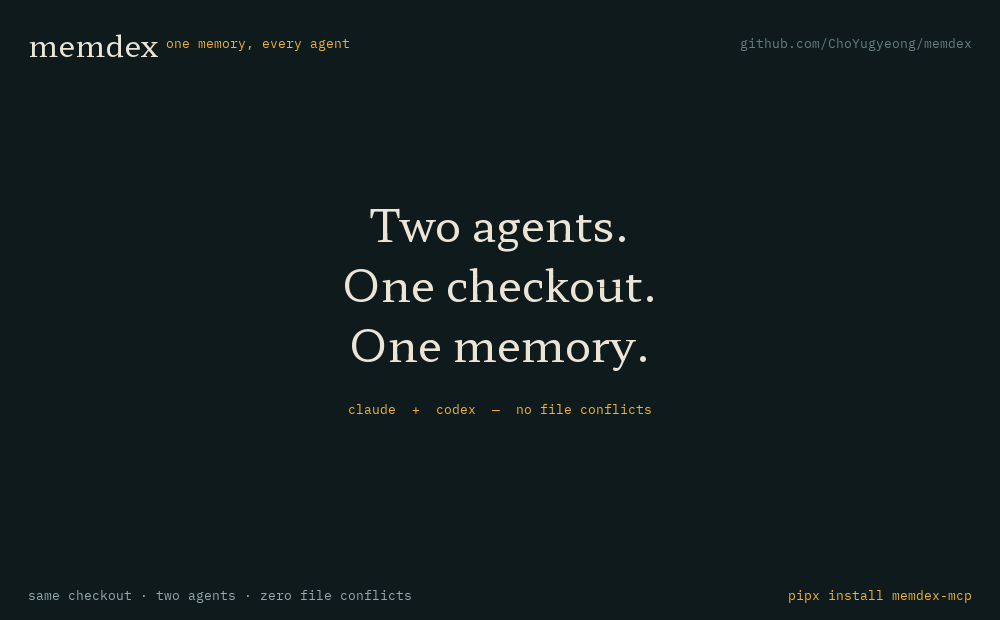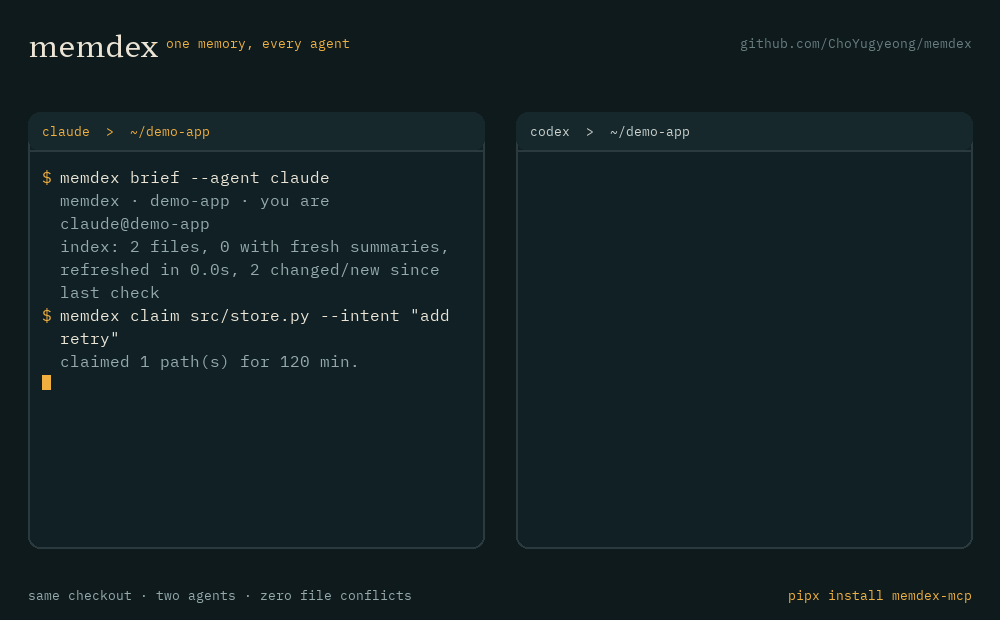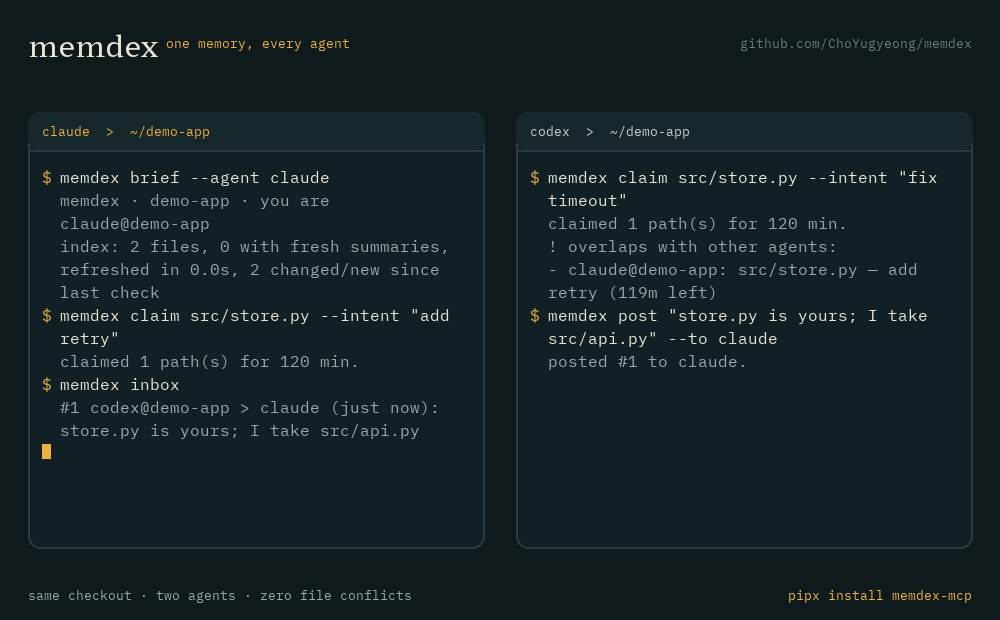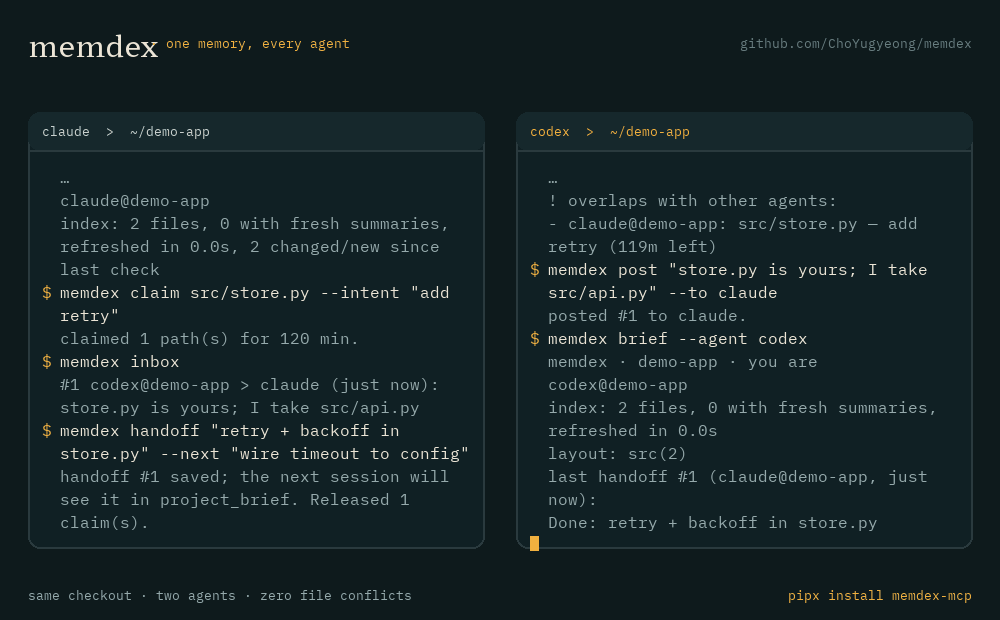
claimwhat you're editing,postto other agents, read yourinbox, leave ahandofffor whoever comes next. All worktrees of a repository share one memory.
$ memdex file src/store.py
src/store.py · python · 444 lines · sha 3adeaf13
summary (claude@memdex, 2h ago, matches current content):
SQLite store. Tables: files, summaries (keyed by sha), symbols, notes, messages, claims, fts.
index() skips files whose stat is unchanged. search() fuses FTS5 and embeddings with RRF.
outline: class Store:53; method Store.index:101; method Store.search:280; …
That response is 1.5 KB. The file is 22 KB. Nothing was sent to any model to produce it.
Listed in the official MCP Registry as
io.github.ChoYugyeong/memdex and on PyPI as memdex-mcp.
On a real 66-file site repo, memdex bench measures 154,105 tokens to read every file versus 3,471 tokens
of outlines — 98% smaller, before an agent saves a single summary. Run memdex bench in your own checkout;
the token count is chars / 4, an estimate, and the ratio is the point.
Quick start
pipx install memdex-mcp # PyPI name is memdex-mcp; the command is `memdex`
Claude Code (user scope, every project):
claude mcp add memdex --scope user -e MEMDEX_AGENT=claude -- memdex serve
Any other MCP client — Claude Desktop, Cursor, Codex, Windsurf, DeepSeek harness, …:
{ "mcpServers": { "memdex": { "command": "memdex", "args": ["serve"], "env": { "MEMDEX_AGENT": "codex" } } } }
Give each agent its own MEMDEX_AGENT name; its id becomes name@checkout (e.g. claude@myrepo-wt).
memdex config --agent <name> prints the snippets above, plus an optional Claude Code SessionStart hook
that injects the project brief automatically.
That's it. The server sends its own usage instructions in the MCP initialize response, so agents know
the workflow (brief → file_summary before reading → remember → handoff) without extra prompting.
How it works
          agents (Claude Code, Codex, Cursor, DeepSeek, …)
               │ MCP stdio        │ CLI
               ▼                  ▼
        ┌──────────────── memdex ────────────────┐
        │ project_brief · file_summary · where_is │
        │ read_snippet · search · remember        │
        │ handoff · post/inbox · claim            │
        ├─────────────────────────────────────────┤
        │ incremental index   outlines + symbols  │   only files whose size/mtime
        │ (stat → sha256)     (regex/ast, no LLM) │   moved are re-read
        ├─────────────────────────────────────────┤
        │ summaries keyed by sha256               │   valid until content changes
        │ notes with file refs → stale flags      │
        │ messages, cursors, claims (expiring)    │
        ├─────────────────────────────────────────┤
        │ SQLite WAL · FTS5 trigram · vectors     │   ~/.memdex/memdex.db
        └─────────────────────────────────────────┘
| What it does | Borrowed from | |
|---|---|---|
| Content-hash summary cache | A summary is stored under the file's sha256. Same content in another worktree or branch shares it; changed content gets "no summary yet, here is the old one and the outline". | content-addressed storage |
| Incremental index | git ls-files (honours .gitignore), then only files whose size or mtime moved are read. An 800-file repo re-indexes in ~0.2 s. |
Everything's USN-journal approach |
| Outlines + symbol map | Docstring/comment head plus classes, functions and line numbers for 30+ languages (Python via ast, the rest via per-language regexes — no tree-sitter, no parser install). where_is replaces repeated grepping. |
Serena / repo maps |
| Bounded reads | read_snippet returns ~256 tokens around a match or a line instead of the whole file. |
Kensaku |
| Rot-aware notes | remember links a note to files; search and project_brief show "⚠ changed since" when they move. Notes are append-only (supersedes), so concurrent writers never clobber each other. |
Basic Memory, mem0 |
| Agent coordination | claim with expiry and overlap warnings; post/inbox with per-agent cursors; handoff as the first thing the next session sees. |
— |
| Hybrid search | FTS5 trigram (works for Korean, Japanese and Chinese; 2-character terms fall back to LIKE) fused with optional local embeddings via reciprocal rank fusion. | claude-context |
| Whole-machine content | If Kensaku is installed, search also returns full-text, OCR and semantic hits from PDFs, Office files and screenshots. |
Kensaku |
Supported outline languages: Python, JavaScript/TypeScript, Vue, Svelte, Go, Rust, Java, Kotlin, Scala, C#, Swift, Dart, C, C++, Ruby, PHP, Lua, GDScript, Elixir, Clojure, Zig, Julia, R, Haskell, Groovy, Protobuf, GraphQL, SQL, shell, PowerShell, Markdown.
Tools
| Tool | When | What you get |
|---|---|---|
project_brief |
Start of session | Last handoff, pitfalls, decisions, todos, unread messages, who is editing what. Refreshes the index. |
file_summary |
Before reading a file | Cached summary if the content is unchanged, otherwise the old summary (marked stale) and a free outline. |
file_summary_save |
After reading a file | Stores 2–6 lines for everyone, keyed to the content hash. |
where_is |
"Where is X defined?" | path:line kind name matches. |
read_snippet |
Reading one part of a file | A bounded slice around query or line. |
search |
Before exploring from scratch | Notes, handoffs and summaries; keyword + semantic; Kensaku hits when available. |
remember / note |
Something non-obvious | Save / read / archive a note, decision, pitfall or todo, optionally linked to files. |
handoff |
End of session | Done / next / decisions / pitfalls; releases your claims. |
post / inbox |
Talking to other agents | Broadcast or to: "deepseek"; inbox marks read unless peek. |
claim |
Before editing | Announce paths for N minutes; warns about other agents' overlapping claims. |
The 12 tool schemas cost about 1,000 tokens per request. Responses are short plain text — every byte is a token.
CLI
Everything the tools do is also a command, for shell-only agents, hooks and humans:
memdex brief --agent codex              # start of session
memdex file src/store.py                # cached summary + outline
memdex file src/store.py --summary "…"  # save a summary
memdex snippet src/store.py --query "def index"
memdex where_is index                   # where a symbol is defined
memdex search "locked"
memdex remember pitfall "WAL mode needed" --body "…" --files src/store.py
memdex claim src/store.py --intent "refactor"
memdex post "store.py is mine for an hour" --to claude
memdex inbox
memdex note 7 --archive                 # read a note, or archive it
memdex handoff "Done X" --next "Y" --pitfalls "Z"
memdex index                            # refresh the index for the current project
memdex export --out notes/              # notes as Markdown, one file each
memdex stats
memdex bench                            # what the outlines save on this repo
memdex prune --dry-run                  # drop index rows of deleted projects
memdex doctor                           # database, schema, project index, optional integrations
Measure it on your repo
The first thing anyone asks is "how much does this actually save?". Run it yourself:
cd your-repo && memdex bench
your-repo: 812 files · 3.4 MB indexed in 0.21s (812 changed)
reading every file whole: ~871,000 tokens
outline instead:          ~96,120 tokens  (89% smaller; 640 files have symbols)
biggest wins (file → outline):
  src/generated/api.ts                            144.0 KB →    1.6 KB  ( 99% smaller)
  src/store.ts                                     22.2 KB →    1.0 KB  ( 95% smaller)
--json prints the same numbers for scripts. Tokens are estimated as chars / 4; the ratio is the point,
not the absolute number — and file_summary gets smaller still once agents save real 2–6 line summaries.
Maintenance
One SQLite file is shared by every project on the machine, so it grows. memdex prune drops index rows for
project directories that no longer exist, then VACUUMs:
memdex prune --dry-run     # report only
memdex prune               # drop stale file index, VACUUM
memdex prune --all         # also notes/messages/claims of missing projects (destructive)
Configuration
| Variable | Default | Meaning |
|---|---|---|
MEMDEX_AGENT |
agent (or the MCP client's name) |
Who this agent is. Shown on notes, messages and claims. |
MEMDEX_HOME |
~/.memdex |
Where memdex.db lives. Nothing is ever written inside a repository. |
MEMDEX_PROJECT |
current directory | Project root, when the server is not started inside it. |
MEMDEX_EMBED |
off | ollama:<model> turns on semantic search, e.g. ollama:bge-m3 (multilingual). |
MEMDEX_OLLAMA_URL |
http://localhost:11434 |
Ollama endpoint. Unreachable → silent fallback to keyword search. |
MEMDEX_KENSAKU |
kensaku-cli on PATH |
Path to Kensaku's CLI, or off. |
What is never read: files that look like secrets (.env*, *.pem, *.key, *secret*, *credential*,
.npmrc, …), binaries, lockfiles, files over 512 KB and anything git ignores.
Project identity: the git common directory. All worktrees of a repository share notes, messages and claims; each worktree keeps its own file index.
Limits (read this before adopting it)
memdex is honest about what it is not:
- The bench baseline is generous.
memdex benchcompares "read every file whole" with "take the outline". A real agent greps and reads slices, so your actual saving is smaller than 98%. The win that does hold is that nobody re-discovers the same file, symbol or pitfall twice. - Nothing is shared between machines. One SQLite file, local only. There is no team sync, no cloud, no SSO — by design, but it does mean it cannot replace a team knowledge base.
- It coordinates, it does not lock.
claimwarns about overlapping edits; it cannot stop two agents writing the same file. Git is still the source of truth. - A tiny repo may not need it. Under ~20 files, a hand-written
AGENTS.mdis cheaper than any tool. - It is young. One maintainer, schema v1, no migration history yet (the version is tracked in
PRAGMA user_version, and a newer database is refused rather than silently corrupted). - Outlines are regex-level, not semantic. Python uses
ast; everything else is per-language regexes. Expect good results on normal code and occasional misses in exotic syntax.where_isstill falls back to substring search.
How it compares
memdex is deliberately small. These tools are good at things memdex doesn't try to do, and several of them inspired it.
| Focus | Dependencies | Relationship | |
|---|---|---|---|
| memdex | Cross-session, cross-agent memory: content-hash summaries, rot-aware notes, coordination | none | — |
| Serena | Precise symbol navigation and editing through language servers | LSP servers per language | Use both: Serena for editing, memdex for memory. memdex's where_is is a regex-level stand-in. |
| Basic Memory | Markdown knowledge base with a graph of notes | Python packages, Markdown files in your project | memdex keeps notes out of the repo and ties them to file hashes. |
| mem0 | Memory layer for LLM apps, hosted or self-hosted | vector DB / LLM | memdex is local-only and aimed at coding agents on one machine. |
| claude-context | Vector search over a codebase | Milvus/Zilliz, embedding API | memdex searches notes and summaries; code search stays keyword + symbols, optionally embeddings via Ollama. |
| Kensaku | Desktop search: file names, PDF/Office text, OCR, semantic, for humans and agents | Rust desktop app | Complementary: memdex bridges to it for whole-machine content search. |
FAQ
Does anything leave my machine? No. SQLite file, local subprocesses, optional local Ollama. No telemetry.
Who writes the summaries? The agents, when they read a file that has no fresh summary. The server's
instructions ask for 2–6 lines. You can also write them: memdex file path --summary "…".
What if two agents edit the same file? claim warns, it doesn't lock. memdex coordinates; it doesn't
replace git.
How much context does it cost? About 1,000 tokens of tool schemas per request, a few hundred for
project_brief (hard-capped at 4,000 chars; memdex brief --max-chars 0 shows everything).
It pays for itself the first time a file isn't re-read.
Something is broken — what do I run? memdex doctor. It reports the database path, size, schema version,
whether it is writable, whether the current project is indexed, and which optional integrations are on.
Can I see or edit the memory? memdex export writes every note as a Markdown file. The database is plain
SQLite. Delete ~/.memdex to start over.
Why not just a vector database? Exact names beat embeddings for code; embeddings help for fuzzy recollection of notes. memdex does keyword + symbols by default and adds vectors only when you turn them on.
Brand
The identity is Ledger Ribbon: a bookmark left in the file, set in Hahmlet, on the night ledger's ink with one amber rule.
- Logo:
logo.svg· dark ground:logo-on-dark.svg· symbol:symbol.svg - Colour: Ledger Ink
#0e1a1c· Lamp Amber#f0b03f· Bone#ece5d6 - Type: Hahmlet (display) · Gothic A1 (text) · Nanum Gothic Coding (mono) — all OFL 1.1
- Tokens:
tokens.css· guidelines:memdex-guidelines.pdf(13 pages) · notes indocs/brand/
Contributing
git clone https://github.com/ChoYugyeong/memdex && cd memdex
pip install -e .
python -m unittest discover tests     # 100 tests, ~9 s, spawns real processes for the concurrency suite
Ground rules are short: no runtime dependencies, keep tool descriptions terse (they are tokens on every request), and every outline regex captures the symbol name in group 1. See CONTRIBUTING.md.
memdex was built by Claude Code and DeepSeek working on the same checkout — coordinated through memdex itself.
License
1 maintainer

Metadata
1 maintainer
Release files for memdex-mcp 0.2.5
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| memdex_mcp-0.2.5.tar.gz | 60.8 kB | With provenance | Details for memdex_mcp-0.2.5.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| memdex_mcp-0.2.5-py3-none-any.whl | Python 3 | none | any | Details for memdex_mcp-0.2.5-py3-none-any.whl |
Total release size: 104.4 kB
Release files / memdex_mcp-0.2.5.tar.gz
| Download URL | memdex_mcp-0.2.5.tar.gz |
|---|---|
| Size | 60.8 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
8dbf78ead6836f26987e9336ab100562d02c0988cdb6063bd6287c834489ccf1
|
|
BLAKE2b-256 checksum How to use checksums |
7cc224dd734618a89f9c456407305e30375bb9aeb3419e659692557c8405e103
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 1, 2026.
Transparency logRelease files / memdex_mcp-0.2.5-py3-none-any.whl
| Download URL | memdex_mcp-0.2.5-py3-none-any.whl |
|---|---|
| Size | 43.6 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
32745e596e6115a7256a439e804152b1aefce23d034aa6a73ebed53048bb1040
|
|
BLAKE2b-256 checksum How to use checksums |
d518eda58b88153cb30052fbd061c05b3d45a8eab6c3b9728b245754d26535d8
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 1, 2026.
Transparency logSecurity for memdex-mcp 0.2.5
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
All 2 files in this release have been uploaded with provenance metadata.
Attestation for memdex_mcp-0.2.5.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 1, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.

















