
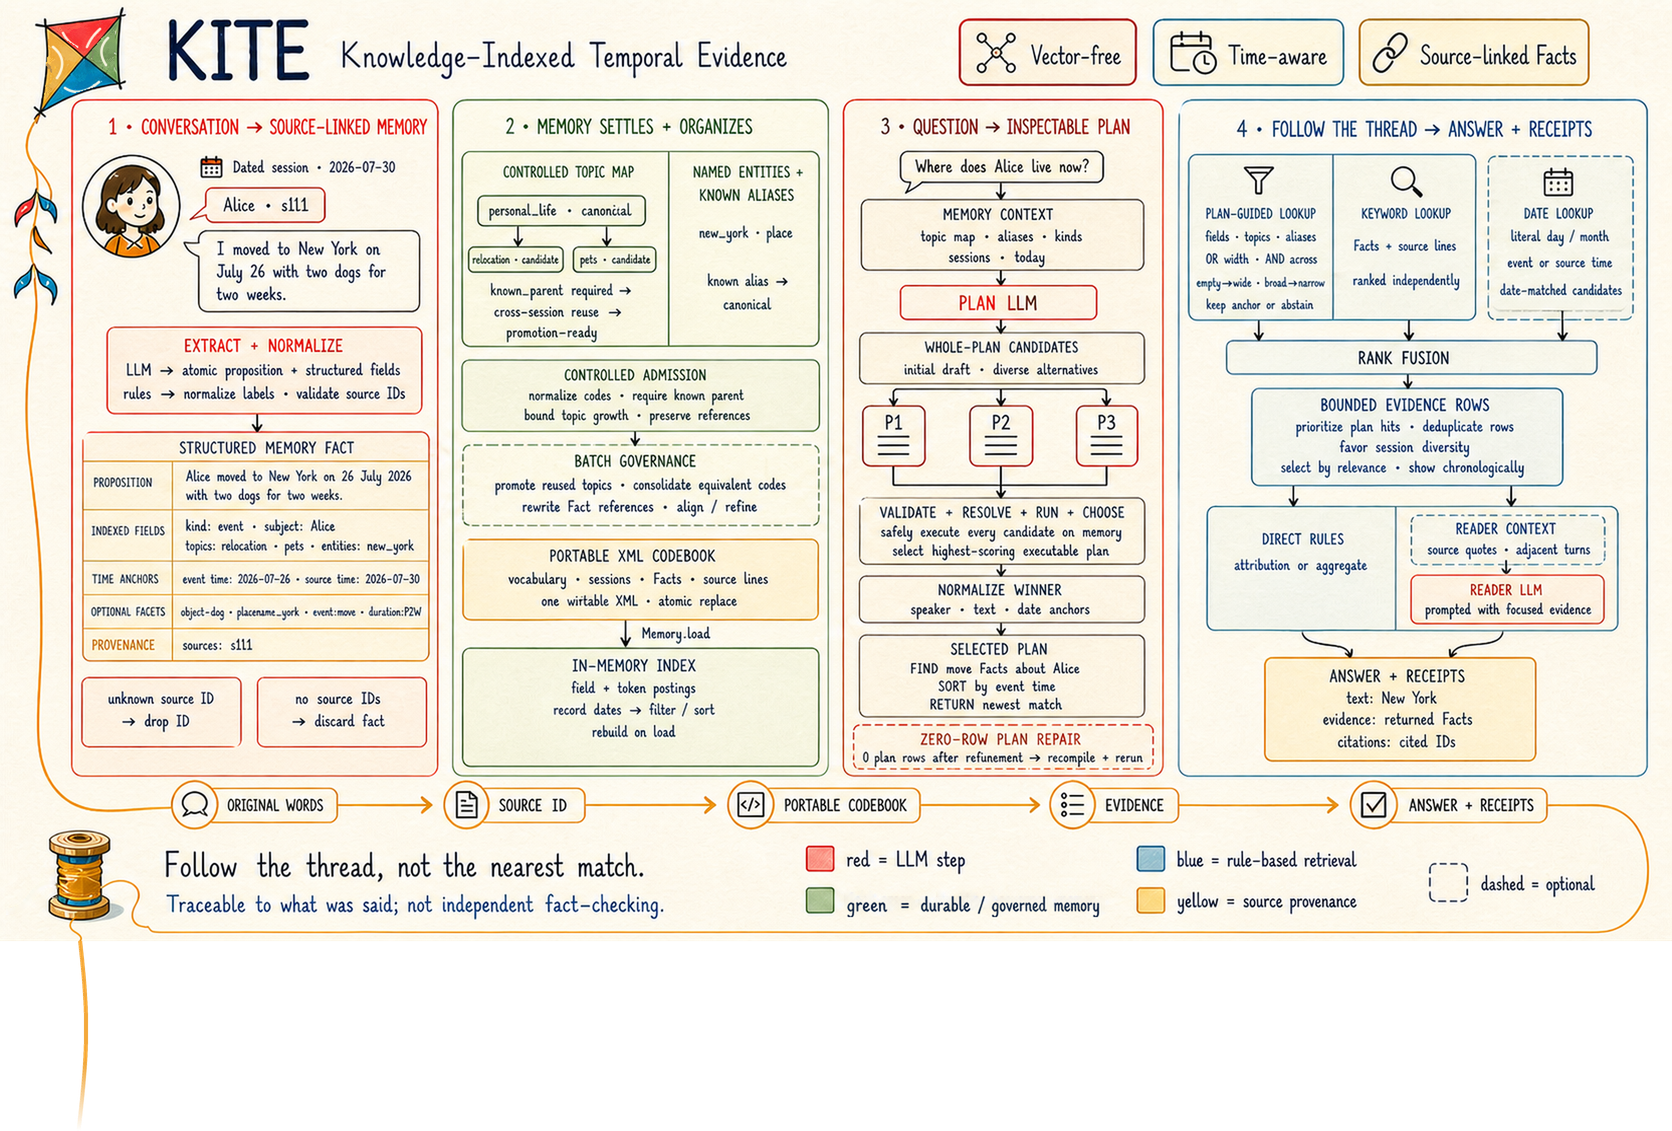
Follow the thread, not the nearest match.
KITE by Memoket turns conversations into structured, source-backed facts, then answers questions with the exact moment they came from attached.

💡 Why KITE by Memoket
Most AI memory turns every sentence into a cloud of numbers and hands back whatever lands closest to your question. It always returns something, even when the answer was never there, and it cannot show you why.
KITE by Memoket reads what a question means, not how it sounds.
"Who's the decision-maker on the Henderson account now?"
Nothing in memory says decision-maker:
- March. Marcus: "I'll sign off on Henderson."
- June. The new VP of Ops: "Dana owns Henderson from here."
Both were filed under the same topic when they were written. Then now sorts them by date. Similarity has no notion of now: nearest-match memory rates March just as relevant and answers "Marcus", with nothing to tell you it is wrong. KITE answers "Dana", with the June line attached.
| Nearest-match memory | 🪁 KITE by Memoket | |
|---|---|---|
| Finds | whatever sounds like the question | the facts that answer it |
| When it was never said | returns something anyway | comes back empty, and says so |
| Why this answer? | a similarity score | a readable plan, with who said it and when |
| Runtime stack | embeddings · vector DB · rerankers | one portable, topic-indexed file |
| Ask again tomorrow | depends on the index that day | the same plan walks the same steps |
⚙️ How It Works
The whole idea in one line: conversations settle into facts under topics, and a question finds its topic and pulls that topic's memories, receipts included.
1 · Message → Fact
A user says, "I moved to Tokyo on July 26." KITE by Memoket extracts what happened and files it under its topics, keeping the original message as evidence:
<fact t="2026-07-26" kind="event" who="user"
      place="tokyo" event="move" src="chat1L1">
  The user moved to Tokyo on 26 July 2026.
</fact>
<line id="chat1L1" who="user">I moved to Tokyo on July 26.</line>
2 · Question → Plan
When the agent asks "Where does the user live now?", KITE by Memoket compiles the question into a plan you can read, validate, and cache:
{
  "select": "facts",
  "where": {"who": ["user"], "event": ["move"]},
  "pipe": [
    {"op": "sort", "key": "t", "desc": true},
    {"op": "head", "n": 1}
  ]
}
3 · Plan → Execution
The executor runs the plan over the topic index. Keywords and associations come first, then conditions filter down to the one moment that answers the question:
SEARCH facts
FILTER who = "user" AND event = "move"
SORT BY event_time DESC
TAKE 1
The same validated plan always follows the same steps over the same memory, with no embeddings and no vector database anywhere.
4 · Evidence → Answer
Answer: Tokyo
Source: chat1L1, "I moved to Tokyo on July 26."
Key Features
🚫 No vector stackNo embeddings, no vector database, no layers to embed, sort, and re-rank every result. |
🗂️ Structured factsConversations crystallize into typed, dated, topic-indexed memory you can open and read. |
🔍 Inspectable queriesEvery question becomes a symbolic plan, revealing exactly how each answer was matched. |
🕐 Time-aware retrievalPeople, events, dates, and updates handled directly, so "now" means now. |
🧾 Shows its workEvidence links straight back to the moment it came from: who said it, when, and the actual words. |
🤷 Knows what it doesn't knowWhen something was never said, the search comes back genuinely empty, and KITE says so. |
🚀 Quick Start
1. Install and configure
python -m pip install memoket-kite
export OPENAI_API_KEY="sk-..."
mkdir -p artifacts
curl -fsSL \
  https://raw.githubusercontent.com/memoket/memoket-kite/main/examples/data/demo_codebook.xml \
  -o artifacts/quickstart.xml
Using another OpenAI-compatible provider? Set OPENAI_BASE_URL as well.
2. Remember
Turn a conversation into structured, source-backed facts:
from memoket_kite import Memory

memory = Memory.load("artifacts/quickstart.xml")
memory.remember(
    [{"role": "user", "content": "I moved to Tokyo."}],
    session_id="session_1",
)
3. Recall
Compile a question into a plan and retrieve matching facts, each carrying its sources:
from memoket_kite import Memory

memory = Memory.load("artifacts/quickstart.xml")

for fact in memory.recall("Where did the user move?"):
    print(fact.content)
    print(fact.sources)
4. Answer
Generate an answer from the retrieved evidence and keep the receipts:
from memoket_kite import Memory

memory = Memory.load("artifacts/quickstart.xml")

result = memory.answer_with_evidence("Where did the user move?")
print(result.text)  # "The user moved to Tokyo."
for fact in result.evidence:
    print(fact.content, fact.sources)  # the moments the answer stands on

print(memory.answer("Where did the user move?"))  # just the text
Full reference in docs/api.md;
more runnable examples in
examples/.
📊 Benchmark Results
KITE by Memoket posts the top overall score on both public long-conversation memory benchmarks. It is the only system up there that uses no vectors, and it reads less context than any capable rival.
| Benchmark | Overall Accuracy | Avg. Reader Context |
|---|---|---|
| LoCoMo | 🥇 93.51% | 1.51k tokens |
| LongMemEval-S | 🥇 85.60% | 1.65k tokens |
All systems are evaluated under one shared protocol, with gpt-4.1-mini as the
common reader and judge; the exact rubrics are in the
LoCoMo protocol
and
LongMemEval protocol.
Reader context is the mean per-question evidence budget: what the reader actually
gets to see, measured by the same ledger on every question.
Each figure comes from a reference run under the default configuration, with
gpt-4.1-mini reading and judging and no ablation flags set. The reproduction
contract pins the dataset revisions, protocols, model IDs, expected row counts,
and reported scores. The provided scripts rebuild the evaluation locally from
the official datasets with a configured compatible LLM endpoint.
How a local run is recorded
Every rebuilt run writes a local manifest naming the exact commit, corpus
digest, tokenizer, and plan-cache digest it used. Judging records the answers,
verdicts, and score in a second manifest keyed to the first. A completed run can
validate that seal and recompute its metrics offline; the reference verifier
also checks the manifest-declared paths, counts, and reported aggregate. Details
are in the
benchmark guide
and
reproducibility notes;
the benchmark corpora keep their own licences, spelled out in
LICENSE-DATA.md.
🔗 Integrations
KITE by Memoket is a plain Python library: three calls take you from a raw conversation to a cited answer. Integrations across the agent ecosystem (Claude Code, Codex, Cursor, OpenCode, and more) are next on the roadmap.
Want yours first? Tell us on Discord.
✨ Experience KITE with Memoket
The memory you just read about ships today. KITE is the algorithm inside every Memoket: the same topic-filed facts, the same line back to the source, running on your own device. Ask it "didn't this client say their fiscal year ends in March?" months later, and it surfaces the exact moment: who said it, when, and in their words.
Memoket captures memories; KITE is the memory itself.
See more of Memoket in action →
🤝 Community
- 💬 Discord for questions, ideas, and integration requests
- 🐛 Issues for bugs and feature requests
- 🔧 Contributing guide · 🔒 Security policy
📖 Citation
A technical report is in preparation; BibTeX will land here with the arXiv release. Until then, please cite this repository.
📄 License
KITE by Memoket is released under the Apache License 2.0.
Like its name, KITE by Memoket stays light enough to fly, always on a line back to the truth. 🪁
1 maintainer

Metadata
1 maintainer
Release files for memoket-kite 0.1.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| memoket_kite-0.1.0.tar.gz | 103.6 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| memoket_kite-0.1.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 214.2 kB
Release files / memoket_kite-0.1.0.tar.gz
| Download URL | memoket_kite-0.1.0.tar.gz |
|---|---|
| Size | 103.6 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
55ed763cf9e038d334fc28da82d2796db559c9010da9152ed97b852cc1facddf
|
|
BLAKE2b-256 checksum How to use checksums |
7528ba3f0ac4325666c83c36144da322eb3c6b1b687f9c9f2338e3096f9bc197
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Aug 13, 2026.
Transparency logRelease files / memoket_kite-0.1.0-py3-none-any.whl
| Download URL | memoket_kite-0.1.0-py3-none-any.whl |
|---|---|
| Size | 110.6 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
61019a550a59f613110e8d884464394f01ecbc275f6cc001a8e75acf1d48da61
|
|
BLAKE2b-256 checksum How to use checksums |
22437e7ef78a715f7e8d5e5b86c86e49a53e5a03d2fd39d4a66d460638bd4252
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Aug 13, 2026.
Transparency log












