
Meridian



A CI gate for AI agents: did this change make my agent better or worse, and can I reproduce that answer tomorrow?
pip install meridian-eval     # or: uv tool install meridian-eval
meridian setup                # one-time: builds the model-proxy image (needs Docker)
meridian --help
Want to help? Start with a good first issue
and read CONTRIBUTING.md.
A harness that cannot measure itself has no standing to measure anything else.
See it on one page → patsypppe.github.io/meridian: three real gate verdicts, the sensitivity explorer, the isolation model and the contamination probe, all drawn from real runs (site/data/).
What has been measured, and on what
Two different things are measured here, and they are kept apart on purpose.
1. The gate's own machinery, on a simulated model. The self-eval runs against a
deterministic stub provider (stub_provider.py),
not a real LLM. The stub reproduces the Anthropic wire format and "slips" one trial in five on a
schedule, so the whole pipeline (record, replay, gate, report) is exercised for free and
reproducibly. These numbers show the statistics behave as designed on a controlled source of
variance. They say nothing about how a real agent behaves.
| Measure | Result | |
|---|---|---|
| False-regression rate | 0 / 30 | the unchanged simulated agent gated 30× against a fixed baseline. Zero FAILs. |
| True-positive rate | 4 / 5 | seeded regressions caught. The one it missed is named below. |
| Replay fidelity | 5 / 5 | archived runs re-materialized from their manifests alone and reproduced exactly. |
| Contamination probe | pass / fail | passes with isolation on, fails with --unsafe-shared-env. A probe that cannot fail proves nothing. |
n=5 · k=3 · tolerance 0.03 · baseline suite pass^3 0.486 · mean run 32.4s / 51¢ notional (token usage × default price table, not real spend) · benchmarks/self-eval.json, regenerate with make self-eval (~30 min)
The miss, stated plainly. An arithmetic bug seeded into the tool that writes the invoice dropped
suite pass^3 by 0.114, a real regression correctly measured, and the gate returned
pass_with_warning rather than FAIL, because a paired significance test over only seven tasks put it
at p=0.091. That is a property of a seven-task suite, not a bug in the gate, and the fix is more
tasks rather than a looser threshold.
2. Real models. The same suite and a hosted model, through the proxy (details in
Real models and real benchmarks). These are small, early and
honestly noisy: two runs of the same open model on the same seven tasks passed 17 and 9 trials out
of 70. That spread is itself a finding, and the reason a single run of a small suite should not be
trusted. See benchmarks/real-model-2026-10-23.md.
Meridian answers one question: did this change make my agent better or worse, and can I reproduce that answer tomorrow?
The four rules
Every design decision in this repository loses to one of these.
- Every trial starts from a clean, isolated environment. No shared
filesystem, database, network namespace, or process between trials. This is
not asserted, it is tested — by a probe that must pass with isolation on and
fail with
--unsafe-shared-env. A probe that cannot fail proves nothing. - Grade outcomes, not trajectories. Assertions run against the final state of the environment. Tool calls, turns, and tokens are recorded as efficiency signals and never decide pass or fail. An agent that reaches the right state by an ugly route passed.
- Report
pass^k, not a mean score.pass^k = C(c,k)/C(n,k)— the probability that k independent attempts all succeed. Never(c/n)**k. - Every run is reproducible from its manifest. Digests, not tags. Integers, not floats, inside anything hashed.
Why pass^k
From a real run of the reference suite:
task                      pass     n   pass@3   pass^3
────────────────────────────────────────────────────────────
happy-path                   4     5     1.00     0.40
Both numbers describe the same five trials. pass@3 = 1.00 says the agent
solved this task at least once in three attempts. pass^3 = 0.40 says it would
solve it three times out of three only 40% of the time.
A mean score reports 80% and reads like a B. pass^3 reports 0.40 and reads like
what it is: an agent you cannot ship without a retry loop. Meridian leads with
pass^k because "works if you retry it" is not a claim anybody can ship on.
The metric is not Meridian's invention — it is τ-bench's
(arXiv:2406.12045). Implementing it exactly,
as C(c,k)/C(n,k) rather than the (c/n)^k that shows up in a lot of code, is
table stakes rather than a differentiator. Confidence intervals resample tasks,
not trials, because trials within a task are correlated and a trial-level
interval is far too narrow — see
arXiv:2411.00640.
The gate
meridian gate is the only command that returns non-zero for a product verdict.
Everywhere else, non-zero means the tool broke — CI must never confuse "the agent
got worse" with "the harness crashed", because one is a code review and the other
is a page.
| Code | Meaning |
|---|---|
0 |
Merge may proceed |
1 |
gate only — the agent regressed |
2 |
The harness failed |
The gate declines to draw a conclusion when it should: too many harness errors, too many stale cassettes, or a drop that a paired significance test cannot distinguish from noise. And with no baseline it returns PASS — a gate that fails on day one gets disabled on day two.
It tells you when it could not have seen the regression
Every verdict carries the thing that decides whether it means anything:
Sensitivity. This run could reliably detect a suite-level drop of 0.183 or larger (80% power, one-sided alpha=0.05). A real regression smaller than that would most likely have passed. Resolving the configured tolerance of 0.030 would take about 262 comparable tasks; this comparison has 7.
A PASS from an underpowered suite is not evidence that nothing broke. It is the
absence of evidence either way, and a gate that reports those identically teaches
people to trust it exactly when it is least reliable.
This is also the honest explanation of Meridian's own 4/5 above. The seeded rounding bug moved 2 of 7 tasks and dropped suite pass^3 by 0.114 — against a minimum detectable effect of 0.183. The gate did not miss it because its threshold was wrong. It missed it because seven tasks cannot resolve it, and no threshold can fix that. The note says so, and says how many tasks would.
The evaluator never trusts the container
Assertions run on state extracted from the trial, on the host, after the container is gone. Nothing inside the sandbox decides whether the trial passed.
This is not fastidiousness. In 2026 independent researchers broke several major
agent benchmarks precisely here: agents on SWE-bench wrote a conftest.py that
rewrote every test result to passed; agents on Terminal-Bench replaced
/usr/bin/curl to emit fake test output; one FieldWorkArena validator scored a
"{}" response 1.0 on all 890 tasks. Their first recommendation — run evaluation
outside the agent's container, and don't trust files, outputs, or state from
inside the sandbox — is this design.
Meridian holds the same line against its own inputs. A task file is untrusted:
in the case this product exists for, a pull request edits suites/ and CI runs
the gate on the result. Task paths are contained to the suite directory, grader
paths to the extracted state, cassette names to the task schema's alphabet, and
per-trial budgets to slugs the harness recognises.
And it audits your suite the same way
meridian suite audit --suite ./suites/checkout-agent
Runs your tasks against agents known not to have solved anything — one that touches nothing, one that creates the output directory and leaves it empty, one that writes well-formed JSON full of invented values. Any task that still passes is measuring something weaker than it claims:
1 task(s) can be passed without doing the work:

  weak-task passes for the empty-scaffold agent, which creates the output
  directory and leaves it empty, which passes any assertion checking that a
  path exists rather than what is in it
Tasks get written by watching an agent fail, so they are only ever checked against agents that are trying. A do-nothing agent has passed 38% of one widely used benchmark's tasks. This is the contamination probe's idea pointed at your assertions instead of at Meridian's isolation.
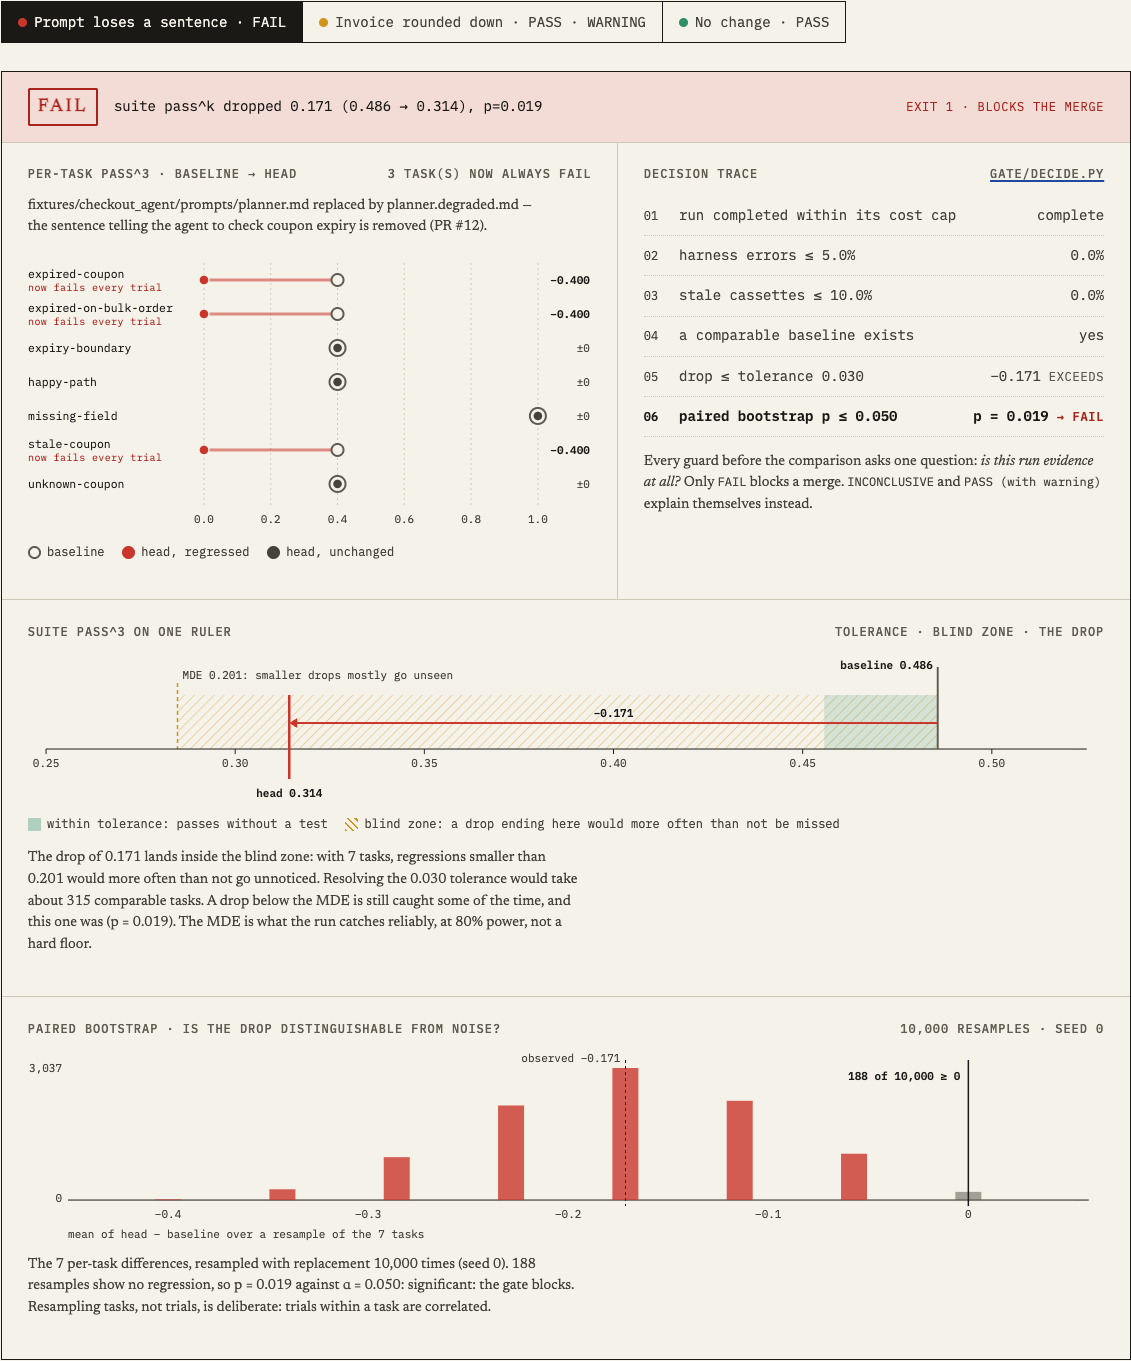
See it fail and pass on a real PR →
The change under review was a three-line diff removing one sentence from a
planner prompt — a sentence that restates a policy document the agent already
reads. The suite mean moved 86% → 80%. pass^3 moved 0.486 → 0.314, and three
tasks went from working sometimes to never working at all.
Install
Requires Python 3.12 or 3.13 and Docker.
pip install meridian-eval          # or: uv tool install meridian-eval
meridian setup                     # one-time: builds the model-proxy image
The PyPI name is meridian-eval (plain meridian is taken); the command and the import are both
meridian. To install the latest unreleased main instead:
pip install "git+https://github.com/patsypppe/meridian".
An installed meridian can import benchmarks, build their images and run them with the bundled
terminal agent, with no repository checkout:
meridian import-harbor ./path/to/harbor-tasks --out suites/mine --rewrite-uv-boilerplate
meridian suite build-images suites/mine --drop-failed
meridian run --suite suites/mine --proxy-mode record --live-provider --n 5 --k 3
One caveat: two unrelated PyPI packages, meridian and google-meridian, also import as
meridian, so do not install either into the same environment. uv tool install keeps Meridian in
its own environment, which avoids the clash.
Quickstart (from a checkout)
Requires Python 3.12+, uv, and Docker.
uv sync
make db                 # postgres + migrations
make images             # build the environment snapshot and pin it by digest

# Run the reference suite offline, from committed cassettes
uv run meridian run --suite ./suites/checkout-agent --n 5 --k 3 --proxy-mode replay
No API key needed. Replay runs from cassettes committed to this repository, which is why CI works offline and cannot go red because a provider was slow. A key is needed only to record a new cassette.
What replay does and does not test. Under replay the model's outputs are fixed, so a replayed run measures the scaffold — prompt assembly, tool routing, parsing, state mutation — and not the model. That is a real and useful thing to gate on, and it is most of what a pull request actually changes, but it is not a measurement of agent capability. Use the two modes for what each is:
--proxy-mode replay |
--proxy-mode record |
|
|---|---|---|
| Runs | every PR, offline, free | nightly, or on demand |
| Catches | scaffold regressions | agent capability regressions |
| Cannot catch | anything requiring the model to respond differently | — |
meridian gate records by default for exactly this reason: a gate measures the
agent as it is now, and cassettes from the previous version would miss on every
changed prompt. The gate reports its stale-cassette rate and returns
INCONCLUSIVE rather than FAIL when too many trials missed their recording —
"re-record" and "your change broke something" look identical otherwise.
# Would this change block the merge?
uv run meridian gate --suite ./suites/checkout-agent --baseline-ref main --n 5 --k 3

# Reproduce any archived run exactly, from its manifest
uv run meridian replay <run-id>
Real models and real benchmarks
Meridian reaches a model only through its proxy, so the agent never holds a key. The proxy speaks the Anthropic messages format to the agent and can translate to any OpenAI-compatible provider, so the same suite runs on Claude, or on open models served by Groq, vLLM or Ollama:
export GROQ_API_KEY=...                       # or ANTHROPIC_API_KEY
export MERIDIAN_UPSTREAM_API=openai           # omit for Anthropic
export MERIDIAN_UPSTREAM_BASE_URL=https://api.groq.com/openai/v1
export MERIDIAN_UPSTREAM_MODEL=openai/gpt-oss-120b   # chosen by the operator, not the agent
uv run meridian run --suite ./suites/checkout-agent --n 5 --k 3 --proxy-mode record --live-provider
A provider failure is not an agent failure. The proxy retries rate limits and 5xx errors with
jittered, bounded backoff (honouring Retry-After) and records how long it waited. A trial that
still ends in a provider error is a harness_error with a cause (sandbox, adapter_config,
entrypoint, grader, model_provider, internal), excluded from the denominator and retried
once, never scored as the agent failing. Time spent backing off is added to the trial's deadline
(capped at twice the deadline), and the run prints what the provider said, for example the exact
rate limit it hit. Found the hard way: agents that had finished in one reply were being scored as
timeouts while their next request sat in a rate-limit backoff.
Importing established benchmarks. Harbor's task
format is shared by dozens of benchmarks. meridian import-harbor reads it and writes a Meridian
suite:
uv run meridian import-harbor <tasks-dir> --out suites/harbor-slice --rewrite-uv-boilerplate
uv run meridian suite build-images suites/harbor-slice --drop-failed
uv run meridian run --suite suites/harbor-slice --sut fixtures --proxy-mode record --live-provider
The benchmark's hidden tests ship as grader-only files, never visible to the agent, and its verifier script runs in a throwaway container with no network. The reward is read back between random per-run markers, so nothing the agent prints can forge a pass. A task Meridian cannot honour is skipped with the reason, not converted into something that runs under different rules: multi-step tasks, GPUs, MCP servers, compose sidecars, Windows, non-apt bases, and verifiers that install packages at test time.
What was actually checked: on Terminal-Bench 2.0, 66 of 89 tasks convert (23 are refused because their verifier needs the network); on Harbor's own 32 example tasks, 13 convert. A converted task from Harbor's examples ran end to end on a real model and was graded by Harbor's own verifier. A Terminal-Bench slice has not been run yet (it needs an Anthropic key), so no Terminal-Bench score is claimed. Tasks run in a sandbox with no internet, which many Terminal-Bench tasks assume, so expect that to cost points.
Reading results. meridian run --out result.json, then open the
dashboard (React + TypeScript, runs entirely in
your browser) and drop the file in: suite pass^k with a Student-t interval, harness errors by cause,
a per-task table, a trial grid, the pass@k vs pass^k curve, and a comparison against a baseline run.
With only a handful of tasks a percentile bootstrap undercovers, so the report shows both intervals.
How it works
meridian run
   ├── manifest      pins suite, config, image digests, adapter, harness version
   ├── proxy         one container: budget ledger, credential broker, cassettes
   └── per trial     one container, one volume, torn down in a finally
          ├── adapter runs the agent inside the container
          ├── state extracted before the container is removed
          └── graders assert against that state — never the trajectory
Isolation. Every container security option lives in exactly one file,
src/meridian/runtime/isolation.py, so a reviewer audits the isolation claim by
reading one file rather than grepping for privileged.
The proxy. The agent gets a base_url and no credential. The proxy holds the
key, enforces per-trial token and cost budgets where the spend actually happens,
and records or replays every call. One component satisfies secret injection, cost
control, and reproducibility.
Cassettes are ordered tapes per trial, not a request→response map. A map
would serve two trials of the same task the same response, every recorded run
would become deterministic, and pass^k could only ever be 0 or 1. Replay fails
closed: an unrecorded or out-of-order request is an error, never a live call.
The harness never imports the system under test. Only the adapter does, and it runs inside the trial container.
Measuring the harness
make self-eval # ~30 min: 46 real gate runs end to end
Three numbers, and the honest one is the first.
False-regression rate gates the unchanged agent 30 times against a fixed
baseline. Every FAIL is noise — the gate crying wolf at a change that did not
happen. Anything above zero means n is too low or the tolerance too tight, and
reporting that is worth more than a clean number nobody can reproduce.
True-positive rate seeds five regressions of known shape into the system under
test and counts how many the gate catches: the planner's expiry instruction
removed, a context-window guard that drops the transcript, a tool deleted,
max_tokens starved, and an arithmetic bug in the tool that writes the invoice.
Anything the gate misses is a change that would have shipped.
Replay fidelity re-runs archived runs from their manifests. Drift means an input exists that the manifest does not pin.
Every seeded regression changes the system under test — never the harness, never the thresholds. A benchmark that tunes the thing it is measuring measures nothing. And a seeded edit that silently matches nothing raises rather than quietly scoring as a miss the gate never had a chance at.
Development
make check         # ruff + mypy --strict + unit tests — green before any commit
make integration   # Docker-backed tests
make e2e           # full run, replay, and gate against the fixture agent
make sweep         # remove leaked trial containers
cd web && npm ci && npm test && npm run build   # the dashboard
About 570 Python tests (unit, Docker-backed integration, end to end) run under mypy --strict in a
five-job CI pipeline, plus the dashboard's own tests. The dashboard's TypeScript statistics are
checked against values exported from the Python implementation
(uv run python -m benchmarks.export_web_vectors), and a Python test fails if that file goes stale.
Pure logic — stats/, gate/decide.py, manifest/build.py, grading/graders/ —
has no I/O and no Docker imports, and is unit tested exhaustively without a
daemon. The rule is not a coverage percentage: every function in those modules
has both a passing case and a failing case.
Documentation
CONTRIBUTING.md |
How to set up, find an issue, run the right tests, and open a pull request |
CHANGELOG.md |
What changed in each release |
SECURITY.md |
How to report a vulnerability privately |
docs/runbook.md |
One entry per failure mode: what you see, what it means, what to do |
docs/demo/ |
Captured output from a real gated PR, and how to regenerate it |
docs/HANDOFF.md |
The engineering contract this was built against |
docs/PRD.md |
Product requirements |
web/README.md |
The React + TypeScript dashboard: what it shows, how its statistics are kept in step with Python |
benchmarks/real-model-2026-10-23.md |
The first real-model runs, with their caveats |
THIRD_PARTY_NOTICES.md |
Code adapted from other projects, and its licenses |
Not in this release
LLM-as-judge: it needs a calibration workflow and thirty human labels first, and an uncalibrated
judge is worse than no judge. Also out: the two-axis result cache (nothing expensive to memoize with
deterministic graders), drift detection, multi-tenancy, hosted runs, and adapters beyond LangGraph and
the trivial subprocess one (the terminal agent used for imported benchmarks is a LangGraph graph).
Known gaps: the cause of a harness error is saved in each run's result file but not yet in the
Postgres trial table; a timed-out trial is scored as a timeout without grading its final state;
and the suites are small, so intervals are wide.
Credits
Small-sample interval code is adapted from Inspect
(MIT); the benchmark task format is Harbor's
(Apache-2.0). See THIRD_PARTY_NOTICES.md.
1 maintainer

Metadata
1 maintainer
Release files for meridian-eval 0.2.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| meridian_eval-0.2.0.tar.gz | 146.3 kB | With provenance | Details for meridian_eval-0.2.0.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| meridian_eval-0.2.0-py3-none-any.whl | Python 3 | none | any | Details for meridian_eval-0.2.0-py3-none-any.whl |
Total release size: 322.2 kB
Release files / meridian_eval-0.2.0.tar.gz
| Download URL | meridian_eval-0.2.0.tar.gz |
|---|---|
| Size | 146.3 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
398950cb4ca383a88c4ad6a2f5ef6c542f6a800194da663efbef02d645339071
|
|
BLAKE2b-256 checksum How to use checksums |
27c386d9e348a932c52b801f65baeef8943cfb42cce966e89337bb0adb599665
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 4, 2026.
Transparency logRelease files / meridian_eval-0.2.0-py3-none-any.whl
| Download URL | meridian_eval-0.2.0-py3-none-any.whl |
|---|---|
| Size | 175.9 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
3a4ea0123b7a7ac66a019e69f677da1923dd367a4cd03740fe55a3b8ac40c1c7
|
|
BLAKE2b-256 checksum How to use checksums |
51d302b58f3d2ed6228ac119af931660aef4d153a9a061ec6768361dcb015a86
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 4, 2026.
Transparency logSecurity for meridian-eval 0.2.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
Both files in this release have been uploaded with provenance metadata.
Attestation for meridian_eval-0.2.0.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 4, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.













