
Meta tags parser


Fast, modern, pure Python meta tag parser and snippet creator with full support for type annotations.
The base package ships with py.typed and provides structured output. No jelly dicts — only typed structures!
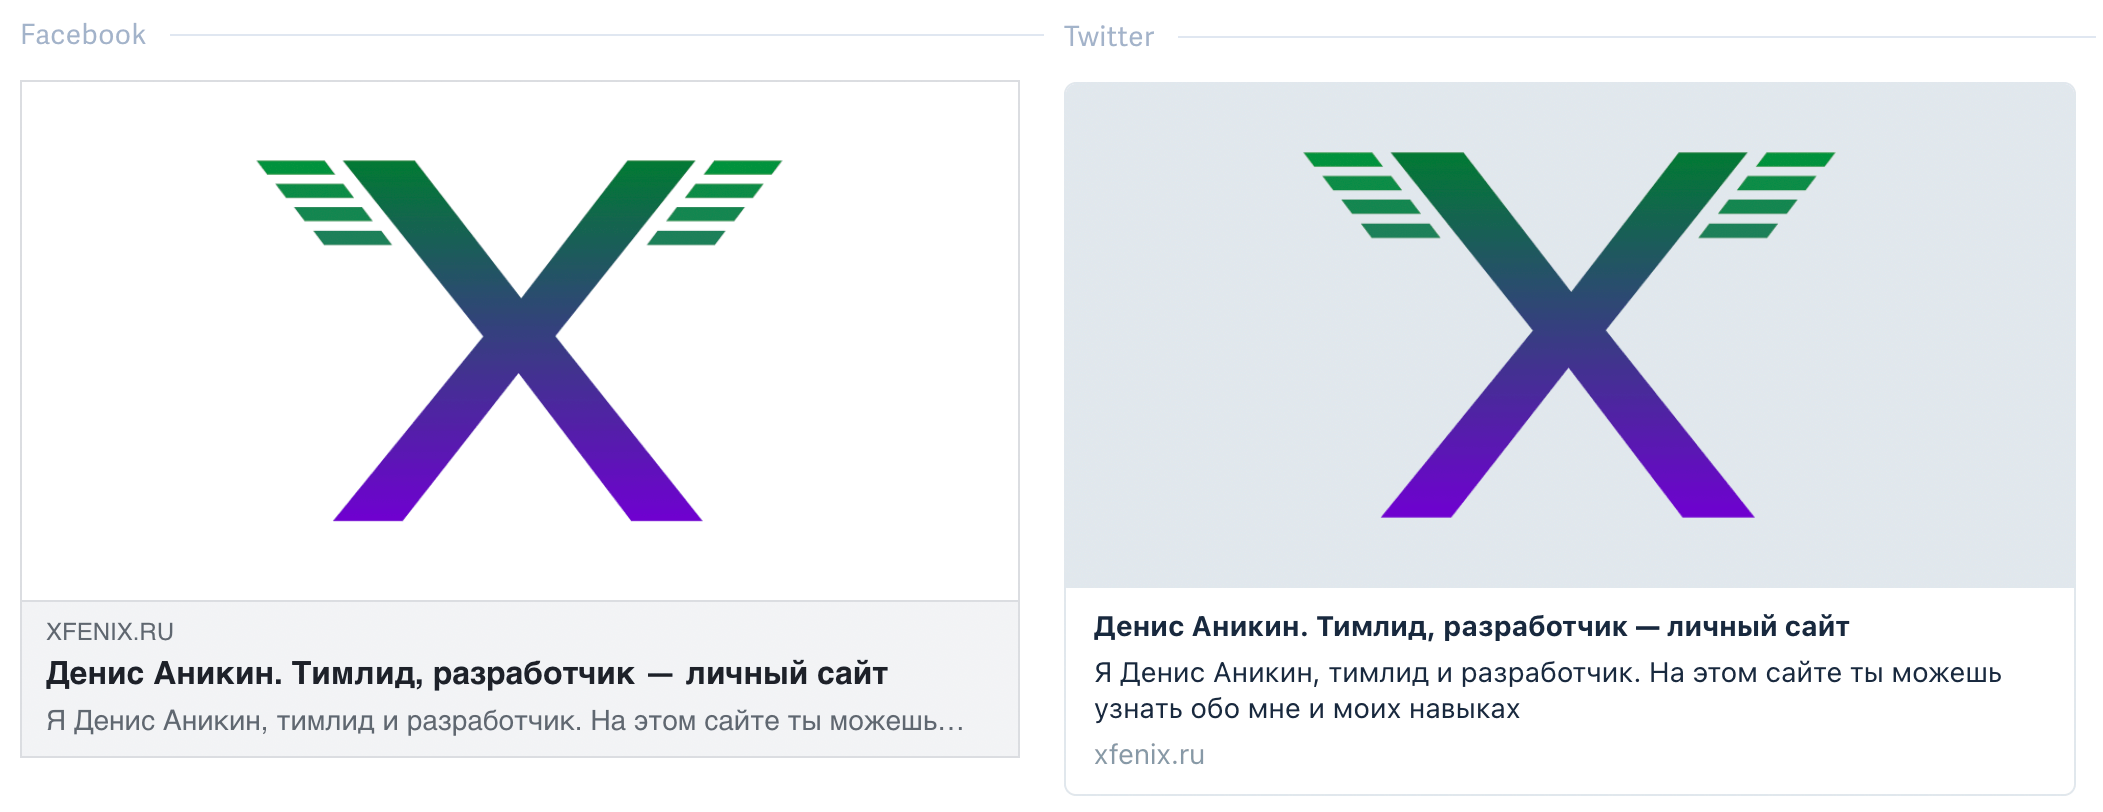
If you want to see what social media snippets look like, check the example:
Requirements
- Python 3.9+
- HTTPX
- selectolax
Install
pip install meta-tags-parser
Usage
TL;DR
-
Parse meta tags from a source:
from meta_tags_parser import parse_meta_tags_from_source, structs


desired_result: structs.TagsGroup = parse_meta_tags_from_source("""... html source ...""")
# desired_result is what you want
-
Parse meta tags from a URL:
from meta_tags_parser import parse_tags_from_url, parse_tags_from_url_async, structs


desired_result: structs.TagsGroup = parse_tags_from_url("https://xfenix.ru")
# and async variant
desired_result: structs.TagsGroup = await parse_tags_from_url_async("https://xfenix.ru")
# desired_result is what you want in both cases
-
Parse a social media snippet from a source:
from meta_tags_parser import parse_snippets_from_source, structs


snippet_obj: structs.SnippetGroup = parse_snippets_from_source("""... html source ...""")
# snippet_obj is what you want
# access like snippet_obj.open_graph.title, ...
-
Parse a social media snippet from a URL:
from meta_tags_parser import parse_snippets_from_url, parse_snippets_from_url_async, structs


snippet_obj: structs.SnippetGroup = parse_snippets_from_url("https://xfenix.ru")
# and async variant
snippet_obj: structs.SnippetGroup = await parse_snippets_from_url_async("https://xfenix.ru")
# snippet_obj is what you want
# access like snippet_obj.open_graph.title, ...
Huge note: the *_from_url functions are provided only for convenience and are very error-prone, so any reconnection or error handling is entirely up to you.
I also avoid adding heavy dependencies to ensure robust connections, since most users don't expect that from this library. If you really need that, contact me.
Basic snippet parsing
Let's say you want to extract a snippet for Twitter from an HTML page:
from meta_tags_parser import parse_snippets_from_source, structs


my_result: structs.SnippetGroup = parse_snippets_from_source("""
    <meta property="og:card" content="summary_large_image">
    <meta property="og:url" content="https://github.com/">
    <meta property="og:title" content="Hello, my friend">
    <meta property="og:description" content="Content here, yehehe">
    <meta property="twitter:card" content="summary_large_image">
    <meta property="twitter:url" content="https://github.com/">
    <meta property="twitter:title" content="Hello, my friend">
    <meta property="twitter:description" content="Content here, yehehe">
""")

print(my_result)
# What will be printed:
"""
SnippetGroup(
    open_graph=SocialMediaSnippet(
        title='Hello, my friend',
        description='Content here, yehehe',
        image='',
        url='https://github.com/'
    ),
    twitter=SocialMediaSnippet(
        title='Hello, my friend',
        description='Content here, yehehe',
        image='',
        url='https://github.com/'
    )
)
"""
# You can access attributes like this
my_result.open_graph.title
my_result.twitter.image
# All fields are required and will always be available, even if they contain no data
# So you don't need to worry about attribute existence (though you may need to check their values)
Basic meta tag parsing
The main function is parse_meta_tags_from_source. Use it like this:
from meta_tags_parser import parse_meta_tags_from_source, structs


my_result: structs.TagsGroup = parse_meta_tags_from_source("""... html source ...""")
print(my_result)

# What will be printed:
"""
structs.TagsGroup(
    title="...",
    twitter=[
        structs.OneMetaTag(
            name="title", value="Hello",
            ...
        )
    ],
    open_graph=[
        structs.OneMetaTag(
            name="title", value="Hello",
            ...
        )
    ],
    basic=[
        structs.OneMetaTag(
            name="title", value="Hello",
            ...
        )
    ],
    other=[
        structs.OneMetaTag(
            name="article:name", value="Hello",
            ...
        )
    ]
)
"""
As you can see from this example, we don't use any jelly dicts—only structured dataclasses. Let's see another example:
from meta_tags_parser import parse_meta_tags_from_source, structs


my_result: structs.TagsGroup = parse_meta_tags_from_source("""
    <meta property="twitter:card" content="summary_large_image">
    <meta property="twitter:url" content="https://github.com/">
    <meta property="twitter:title" content="Hello, my friend">
    <meta property="twitter:description" content="Content here, yehehe">
""")

print(my_result)
# What will be printed:
"""
TagsGroup(
    title='',
    basic=[],
    open_graph=[],
    twitter=[
        OneMetaTag(name='card', value='summary_large_image'),
        OneMetaTag(name='url', value='https://github.com/'),
        OneMetaTag(name='title', value='Hello, my friend'),
        OneMetaTag(name='description', value='Content here, yehehe')
    ],
    other=[]
)
"""

for one_tag in my_result.twitter:
    if one_tag.name == "title":
        print(one_tag.value)
# What will be printed:
"""
Hello, my friend
"""
Improving speed
You can specify exactly what to parse:
from meta_tags_parser import parse_meta_tags_from_source, structs


result: structs.TagsGroup = parse_meta_tags_from_source("""... source ...""",
    what_to_parse=(WhatToParse.TITLE, WhatToParse.BASIC, WhatToParse.OPEN_GRAPH, WhatToParse.TWITTER, WhatToParse.OTHER)
)
Reducing this tuple of parsing requirements may increase overall parsing speed.
Important notes
- Any name in a meta tag (name or property attribute) is lowercased
og:andtwitter:prefixes are stripped from the original attributes, and the dataclass structures carry this information.- HTML is parsed with selectolax's
LexborHTMLParser. It is fast and tolerant but does not emulate a browser, so extremely malformed markup or tags generated by JavaScript may not be handled. If the parser encounters a meta tag with propertyog:name, it will appear in themy_result.open_graphlist
- The page title (e.g.,
<title>Something</title>) is available as the stringmy_result.title(you'll receiveSomething) - "Standard" tags like
titleanddescription(see the full list in ./meta_tags_parser/structs.py in theBASIC_META_TAGSconstant) are available as a list inmy_result.basic - Other tags are available as a list in
my_result.other, and their names are preserved, unlike theog:/twitter:behavior - For structured snippets, use the
parse_snippets_from_sourcefunction
Changelog
See the release page at https://github.com/xfenix/meta-tags-parser/releases/.
1 maintainer

Metadata
1 maintainer
Release files for meta-tags-parser 2.0.2
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| meta_tags_parser-2.0.2.tar.gz | 522.9 kB | Without provenance | Details for meta_tags_parser-2.0.2.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| meta_tags_parser-2.0.2-py3-none-any.whl | Python 3 | none | any | Details for meta_tags_parser-2.0.2-py3-none-any.whl |
Total release size: 533.3 kB
Security for meta-tags-parser 2.0.2
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














