
MetaRAG is an open-source engine that takes the guesswork out of RAG pipeline design. Instead of manually tuning chunking strategies, retrieval backends, and rerankers — MetaRAG benchmarks them all and routes every query to the configuration that actually performs best on your data.
Think of it as AutoML, but for RAG.
📌 Table of Contents
- Why MetaRAG
- Architecture
- Components
- Quickstart
- Pipeline Selection
- Evaluation
- Supported Models
- Roadmap
- Routing in Practice
- Future Scope
- Project Structure
- Contributing
- Full Documentation — installation, quickstart, architecture, and the complete API references
🤔 Why MetaRAG
Every team building a RAG system faces the same unsolved problem:
Which chunking strategy should I use?
Which retrieval method works best for my documents?
How do I know if my pipeline is actually good?
What happens when a different query type breaks everything?
Current tools make you answer these questions manually — every time, for every project.
| Tool | Build RAG | Evaluate | Compare | Auto-Select | Learn |
|---|---|---|---|---|---|
| LangChain | ✅ | ❌ | ❌ | ❌ | ❌ |
| LlamaIndex | ✅ | ❌ | ❌ | ❌ | ❌ |
| RAGAS | ❌ | ✅ | ❌ | ❌ | ❌ |
| MetaRAG | ✅ | ✅ | ✅ | ✅ | ✅ |
MetaRAG owns the entire RAG workflow — from raw documents to evaluated, auto-selected, continuously improving answers. No LangChain dependency in the core — the retrieval and chunking logic is hand-built on top of numpy, pandas, and rank-bm25 only.
🏗 Architecture
                        ┌─────────────────────────────────────────┐
                        │              USER INTERFACE              │
                        │   MetaRAG(docs, embeddings, generator)   │
                        │            .fit()  .ask()                │
                        └─────────────────┬─────────────────────────┘
                                          │
                 ┌────────────────────────▼────────────────────────┐
                 │                    METARAG CORE                  │
                 │                                                  │
                 │   ┌──────────┐    ┌──────────┐   ┌───────────┐   │
    Documents ──►│   │  Loader  │───►│ Chunker  │──►│ Embeddings│   │
                 │   └──────────┘    └──────────┘   └─────┬─────┘   │
                 │                                        │         │
                 │                              ┌─────────▼──────┐  │
                 │                              │  Vector Database│ │
                 │                              │ InMemory│Chroma │ │
                 │                              │      │ FAISS   │ │
                 │                              └─────────┬──────┘  │
                 │                                        │         │
                 │                              ┌─────────▼──────┐  │
                 │                              │   Retrievers   │  │
                 │                              │ BM25 │ Dense   │  │
                 │                              │ Hybrid │ MMR   │  │
                 │                              └─────────┬──────┘  │
                 │                                        │         │
    Query ──────►│   ┌──────────┐               ┌────────▼──────┐  │
                 │   │  Router  │──────────────► │   Pipelines  │   │
                 │   │ (cold-   │               │Straight│MQuery│   │
                 │   │  start → │               │Reranked│Full  │   │
                 │   │  learned)│               └────────┬──────┘   │
                 │   └────▲─────┘                        │          │
                 │        │                     ┌────────▼──────┐   │
                 │        │                     │   Evaluator   │   │
                 │        │                     │  (5 metrics)  │   │
                 │        │                     └────────┬──────┘   │
                 │        │                              │          │
                 │        └────────── benchmark() ───────┘          │
                 │              trains router from win-rates        │
                 └───────────────────────────────────────┬──────────┘
                                                          │
                                                    ┌─────▼──────┐
                                                    │   Answer   │
                                                    │text│score  │
                                                    │pipeline│ms │
                                                    └────────────┘
🧩 Components
Every stage below is swappable — full options, defaults, and signatures live in docs/api.md.
from metarag import DocumentLoader, Chunker, InMemoryVectorDB, HybridRetriever, OllamaGenerator, Evaluator, Router

docs      = DocumentLoader("./data").load()                          # PDF, DOCX, HTML, CSV, JSON, MD, TXT
chunks    = Chunker(strategy="recursive").chunk_documents(docs)      # 6 strategies
db        = InMemoryVectorDB()                                       # or ChromaVectorDB / FAISSVectorDB
retriever = HybridRetriever(chunks, embeddings, db, alpha=0.5)        # or BM25 / Dense / MMR
generator = OllamaGenerator(model="mistral")                          # or bring your own .generate(prompt)
evaluator = Evaluator(embedding_model=embeddings, preset="balanced")  # 5 metrics, zero LLM calls
router    = Router()                                                  # cold-start rules → win-rate thresholds
fit() wires all of this together automatically and builds five pipelines — straight, multiquery, hyde, reranked, full — inspectable via rag.pipeline_graph().
⚡ Quickstart
Installation
pip install metarag-sdk
Optional components install on top as needed — see docs/installation.md for the full list ([pdf], [chroma], [faiss], [nltk], [rerank], [ollama], or [all]).
Setup Ollama (free, local — optional)
# install from ollama.com, then pull models
ollama pull mistral             # generation
ollama pull nomic-embed-text    # embeddings
Build and Ask
from metarag import MetaRAG, CachedEmbeddings, OllamaGenerator

embeddings = CachedEmbeddings(...)

rag = MetaRAG(
    docs="./data",
    embeddings=embeddings,
    generator=OllamaGenerator(model="mistral"),
)

rag.fit()
Example output
Files Loaded        : 8
Documents Extracted : 101
Chunks Generated     : 333
Vector Index Built
Pipelines Built      : 7
answer = rag.ask("What is the main topic of this document?")
print(answer.text)
Benchmark Every Pipeline
queries = [
    "Summarize the document.",
    "What are the key findings?",
    "List important numbers.",
]

results = rag.benchmark(queries, retrieval_only=True)
Example output
Benchmark Rows      : 595
Benchmark CSV Saved
Router Thresholds Saved
rag.leaderboard()
rag.dashboard()
rag.report()
Example output
=========================================================================================
PIPELINE       PREC   COVER  REDUND  SCORE    LATENCY
=========================================================================================
reranked        0.84   0.79   0.12    0.84      1240ms
multiquery      0.81   0.76   0.15    0.82       890ms
hybrid          0.74   0.71   0.18    0.76       340ms
mmr             0.71   0.69   0.09    0.73       290ms
dense           0.69   0.65   0.21    0.68       230ms
bm25            0.63   0.60   0.24    0.61       120ms
straight        0.60   0.58   0.26    0.58       110ms
=========================================================================================

🏆 Best pipeline: reranked (score=0.84)
🔀 Router would pick: reranked
rag.save()
🔁 Pipeline Selection
MetaRAG does not commit to one pipeline. Every query gets routed to whichever configuration actually performs best on your data.
User asks a question
        │
        ▼
Router extracts features
  (corpus profile + query profile + one cheap probe retrieval)
        │
        ▼
   ┌────────────────────────────────────────┐
   │  Trained?                               │
   │   NO  → cold-start rule-based routing    │
   │   YES → win-rate-driven learned routing  │
   └────────────────────────────────────────┘
        │
        ▼
  Selected pipeline retrieves chunks
        │
        ▼
  Generator produces Answer
        │
        ▼
  Evaluator scores it (composite)
        │
        ▼
  benchmark() → train() feeds the router real win-rate evidence over time
📐 Evaluation
MetaRAG uses a single fast, zero-LLM-call evaluation tier by default — every metric is either embedding cosine similarity or lexical overlap, so it costs milliseconds regardless of which embedding model you're using.
Faithfulness   →  cosine(answer, retrieved context) — is it grounded?
Relevancy      →  cosine(query, answer) — does it address the question?
Precision      →  cosine(query, each chunk) — max / avg / std
Coverage       →  query-term overlap inside the retrieved chunks
Redundancy     →  avg pairwise chunk similarity (lower is better)
Composite      →  preset-weighted combination — drives the router
Three built-in presets weight these differently:
| Preset | Best for |
|---|---|
balanced |
General RAG, internal docs |
precision |
Security logs, anomaly detection — penalizes redundancy and latency harder |
recall |
Research and summarization — weights coverage highest |
No OpenAI. No cloud API. Runs entirely on your own embedding model.
🤖 Supported Models
MetaRAG doesn't hardcode any specific model — any object satisfying EmbeddingInterface (.embed_query() / .embed_documents()) or GeneratorInterface (.generate()) works. These are the options most commonly used in testing:
Embeddings
| Model | Provider | Cost |
|---|---|---|
nomic-embed-text |
Ollama (local) | Free |
all-MiniLM-L6-v2 |
HuggingFace | Free |
BAAI/bge-small-en |
HuggingFace | Free |
text-embedding-3-small |
OpenAI | Paid |
Generation
| Model | Provider | Cost |
|---|---|---|
mistral |
Ollama (local) | Free |
llama3 |
Ollama (local) | Free |
llama3-8b-8192 |
Groq API | Free tier |
gpt-4o-mini |
OpenAI | Paid |
CachedEmbeddings wraps any embedding model with a local disk cache automatically — repeat runs against the same corpus skip re-embedding entirely.
🗺 Roadmap
v0.1 — Foundation ✅
- Document loader — PDF, HTML, DOCX, CSV, JSON, Markdown
- 6 chunking strategies with a unified interface
- Vector database — InMemory, Chroma, FAISS
- 4 retrieval strategies — BM25, Dense, Hybrid, hand-coded MMR
- Pipeline composition — MultiQuery, Reranker, Full
- 5-metric evaluator with preset weighting
v0.2 — Intelligence ✅
-
MetaRAGtop-level class —fit(),ask(),benchmark(),leaderboard() - Backend-agnostic core — LangChain removed, hard deps reduced to
numpy/pandas/rank-bm25 - Corpus / Query / Probe profilers feeding a merged router feature dict
- Trained router — cold-start rules → win-rate-driven learned thresholds
-
benchmark()— per-query winners across every built pipeline
v0.3 — Toolkit & Observability (current)
- Observability suite —
pipeline_graph(),dashboard(),report(),inspect(),trace() - Router persistence —
save()/load()/update_router_thresholds() -
defaults.pysingle-source-of-truth config, with sweep-ready list values -
SklearnRouterAdapter— plug in any.predict()-style model as the router - Comprehensive test suite
-
pip install metarag-sdk— packaged release -
RAGTuner— automated hyperparameter sweep acrossDEFAULTSlist values - CLI —
metarag fit ./data,metarag ask "question" - Experiment-tracking view — compare runs beyond raw
benchmark.csv
📊 Routing in Practice
Example Routing Results
| Query | Selected Pipeline | Composite Score | Latency |
|---|---|---|---|
Where is build_prompt() defined? |
MMR | 0.535 | 9.03 s |
| BM25 scoring formula | Dense | 0.623 | 8.16 s |
| Design an end-to-end RAG pipeline | BM25 | 0.562 | 8.61 s |
| Chunking → Embeddings → Retrieval → Hallucinations | MMR | 0.600 | 9.06 s |
| How do I make search better? | Dense | 0.548 | 30.56 s |
| Database migration causing duplicate answers | BM25 | 0.449 | 7.31 s |
These results were produced automatically by MetaRAG's learned router without manually specifying a retrieval strategy.
Example Router Decisions
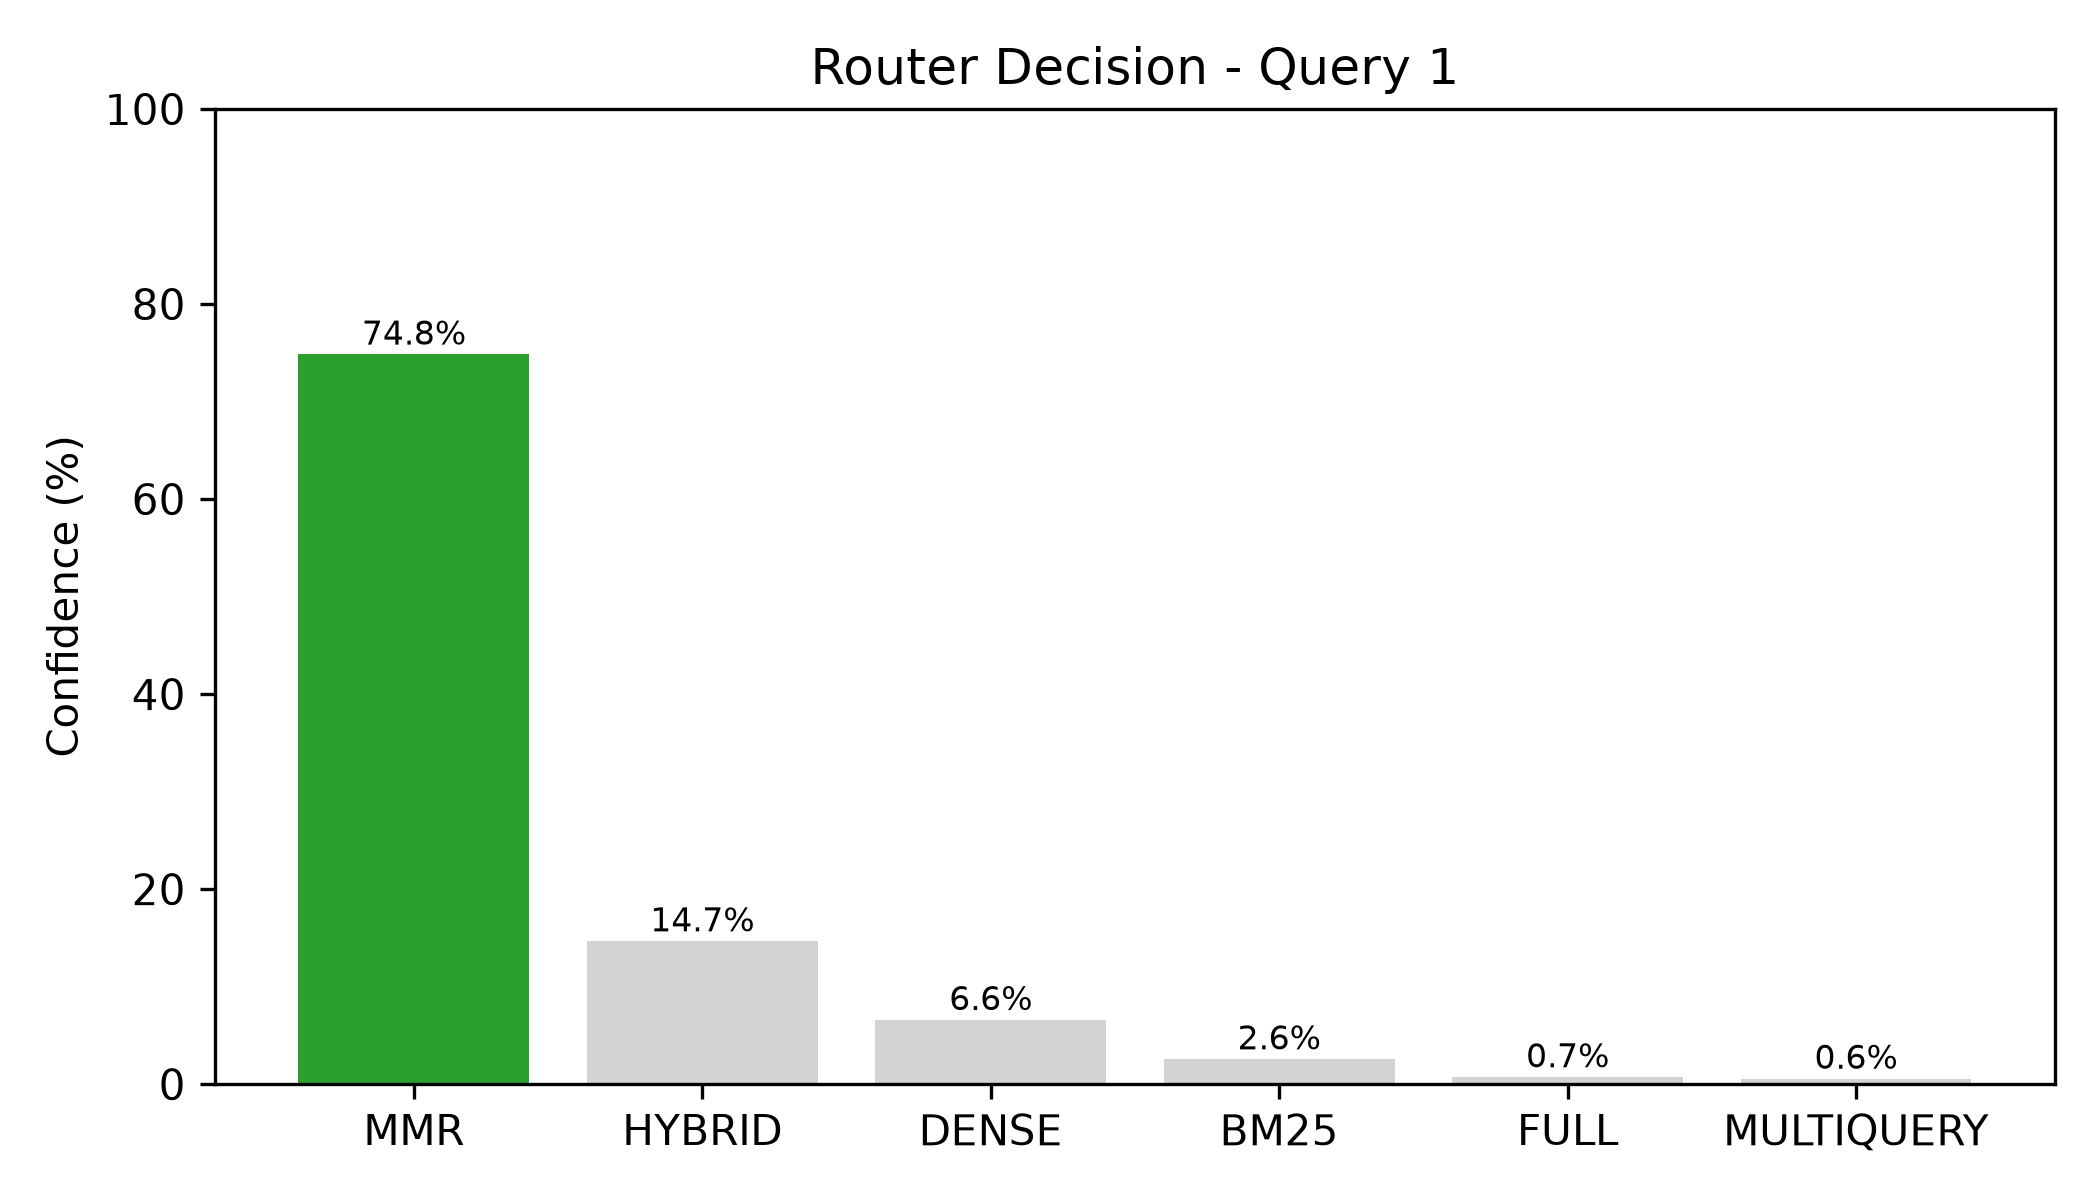
The learned router predicts a probability distribution over all available retrieval pipelines before execution.
| Query | Router Confidence |
|---|---|
Where is build_prompt() defined? (MMR Selected) |
 |
| BM25 scoring formula (Dense Selected) | 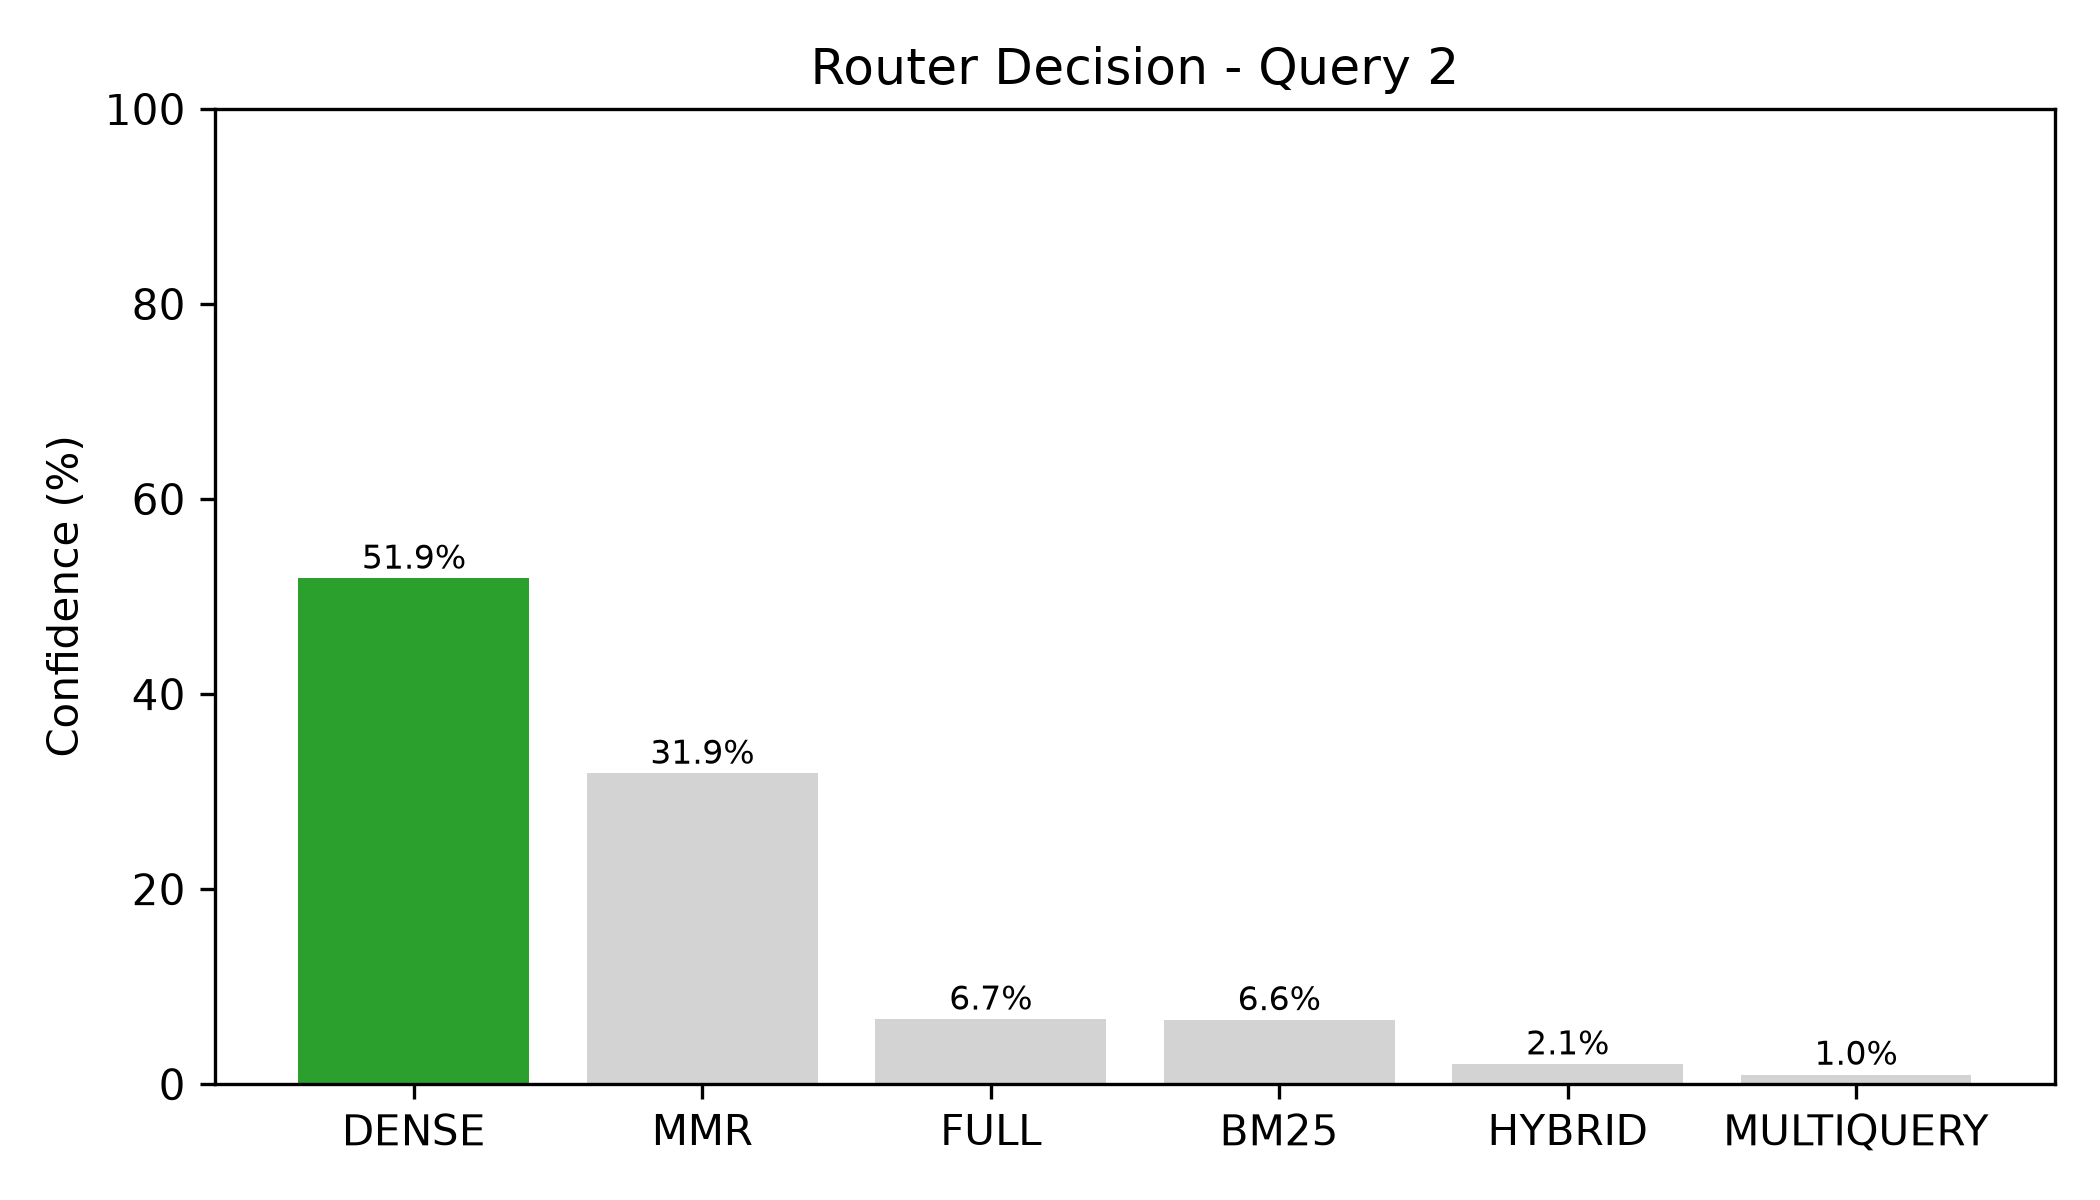 |
| Design an end-to-end RAG pipeline (BM25 Selected) | 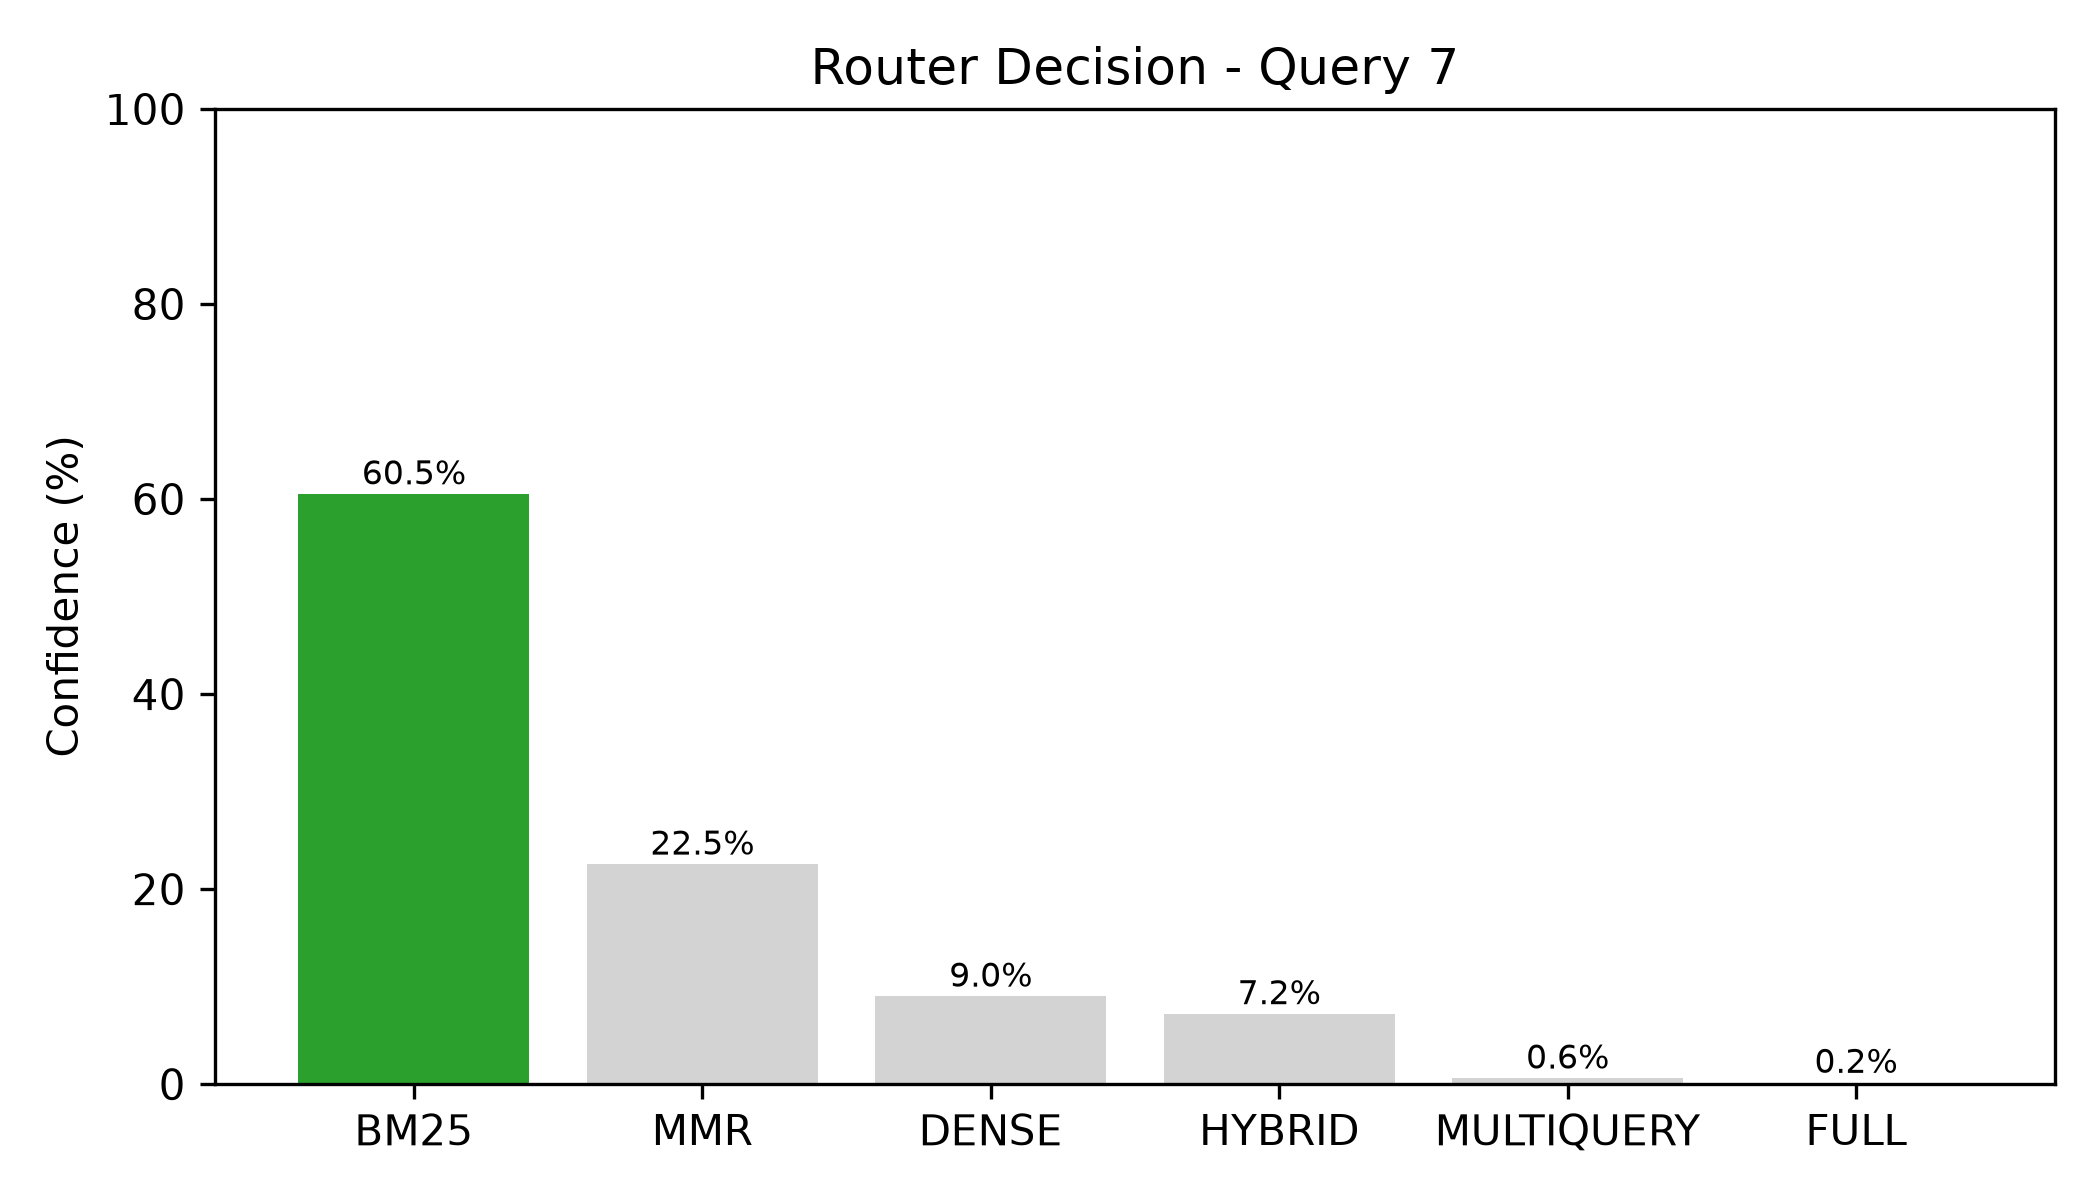 |
Each graph represents the router's confidence distribution across every available pipeline, making routing decisions transparent and explainable.
Lazy Pipeline Loading
Pipelines are instantiated only when selected.
Loaded Pipelines
----------------
['bm25', 'dense', 'mmr']
Unused pipelines are never initialized, reducing startup overhead and memory usage while preserving completely dynamic routing.
Pipeline Usage During Evaluation
Across the evaluation suite, MetaRAG automatically distributed queries across multiple retrieval strategies instead of relying on a single fixed pipeline.

This behavior emerges entirely from the learned router and requires no manual pipeline selection.
Why Routing Matters
Instead of forcing every query through the same retrieval pipeline, MetaRAG adapts retrieval strategy to the characteristics of each incoming query.
✔ Query-aware pipeline selection
✔ Explainable routing probabilities
✔ Dynamic lazy pipeline initialization
✔ Pluggable routing engines (Rule-based or Machine Learning)
✔ Automatic benchmarking and evaluation
✔ Framework-first architecture with interchangeable retrieval components
🔭 Future Scope
🤖 Agentic Workflow (v1.0)
MetaRAG will support agentic execution — where the system can loop, retry with a different pipeline if confidence is low, and handle multi-hop questions that require multiple retrieval steps.
query → retrieve → evaluate
                      │
               score < 0.6?
                      │
              retry with different pipeline
                      │
               score >= 0.6?
                      │
                return answer
This turns MetaRAG from a pipeline selector into a self-correcting retrieval agent.
🌐 REST API (v1.5)
A FastAPI layer that exposes MetaRAG over HTTP — enabling any platform or language to use it.
POST /upload       # index a document set
POST /ask          # get an answer
GET  /leaderboard  # pipeline scores
GET  /history       # query history
Designed for organisations that cannot install Python directly — they just call the API.
🏢 Platform Integrations (v2.0)
Native integrations with where organisations actually work:
MetaRAG for Notion       →  query your Notion workspace
MetaRAG for Confluence   →  search your team's knowledge base
MetaRAG for SharePoint   →  enterprise document intelligence
MetaRAG for Slack        →  answer questions from channel history
🧠 Continuous Learning (v2.5)
A full training pipeline that learns from real usage:
Every ask() + score  →  training data
Periodic retraining   →  smarter router
Domain adaptation     →  legal, medical, code — tuned per org
Human feedback loop    →  thumbs up/down improves quality
The router goes from cold-start rules → win-rate thresholds → sklearn classifier → fine-tuned model, automatically, as data accumulates.
☁️ MetaRAG Cloud (v3.0)
A hosted layer for organisations that don't want to manage infrastructure — upload documents, ask questions via a chat interface, see the pipeline leaderboard, no terminal or Python setup required.
📁 Project Structure
metarag/
│
├── metarag.py            High-level framework — MetaRAG class
├── defaults.py           Shared, single-source-of-truth configuration
│
├── core/
│   ├── loader.py
│   ├── chunking.py
│   ├── embeddings.py
│   ├── vector_db.py
│   └── retriever.py
│
├── pipelines/
│   ├── generator.py
│   └── pipeline.py
│
├── Evaluator/
│   ├── evaluator.py
│   ├── scorer.py
│   └── metrics.py
│
├── router/
│   ├── router.py
│   ├── router_interface.py
│   ├── query_profiler.py
│   ├── corpus_profiler.py
│   └── probe_profiler.py
│
├── examples/
│   ├── loader_demo.py
│   ├── chunker_demo.py
│   ├── embeddings_demo.py
│   ├── retriever_demo.py
│   ├── vector_db_demo.py
│   ├── pipeline_demo.py
│   └── metarag_demo.py
│
├── tests/
│
├── docs/
│   ├── index.md
│   ├── installation.md
│   ├── quickstart.md
│   ├── architecture.md
│   ├── api.md
│   ├── contracts.md
│   ├── data_types.md
│   └── examples.md
│
├── assets/
├── README.md
├── LICENSE
├── pyproject.toml
└── requirements-dev.txt
🤝 Contributing
MetaRAG is in active development. Contributions welcome in any of these areas:
- New retrieval strategies
- New chunking strategies
- New evaluation metrics
RAGTuner— hyperparameter sweep implementation- CLI tool
- Integration connectors (Notion, Confluence, Slack)
- Documentation and examples
git clone https://github.com/AnkitKumarxcodes/metarag-sdk.git
cd metarag-sdk

python -m venv .venv
source .venv/bin/activate      # Windows: .venv\Scripts\activate

pip install -e .
pip install -r requirements-dev.txt
Run the test suite before opening a PR:
pytest
📄 License
MIT License — free to use, modify, and distribute.
Built with the belief that RAG quality should be automatic, measurable, and continuously improving.
⭐ Star this repo if MetaRAG saves you time
1 maintainer

Metadata
1 maintainer
Release files for metarag-sdk 0.3.9
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| metarag_sdk-0.3.9.tar.gz | 350.4 kB | Without provenance | Details for metarag_sdk-0.3.9.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| metarag_sdk-0.3.9-py3-none-any.whl | Python 3 | none | any | Details for metarag_sdk-0.3.9-py3-none-any.whl |
Total release size: 411.8 kB
Release files / metarag_sdk-0.3.9.tar.gz
| Download URL | metarag_sdk-0.3.9.tar.gz |
|---|---|
| Size | 350.4 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
4ec3b0708433e9ffa62a6fe4a766c2d8c2680e0262d4cc1e3ab10130ce222f27
|
|
BLAKE2b-256 checksum How to use checksums |
6708ca12f73b7d9e65f46589ca4b4d02a76375ed57438d4fbb2556222bf30122
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.2.0 CPython/3.11.1
|
Release files / metarag_sdk-0.3.9-py3-none-any.whl
| Download URL | metarag_sdk-0.3.9-py3-none-any.whl |
|---|---|
| Size | 61.4 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
2c39241bb243599498587bcc14935e4cf02f9bda2fb18d0b773f7c73969aafda
|
|
BLAKE2b-256 checksum How to use checksums |
1caec1825162d17f9c767f384cf2eb0bf053803d4f6329e478565f1d7277173d
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.2.0 CPython/3.11.1
|
Security for metarag-sdk 0.3.9
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














