
مِسار — Misar
Adaptive $O(n)$ Context-Aware Arabic NLP Preprocessing Router for Transformer Language Models
الموجّه اللغوي التكيفي لتعزيز كفاءة ودقة معالجة اللغة العربية في نماذج الذكاء الاصطناعي



Architecture • Benchmarks • Installation • Quick Start • CLI & Workbench • Citation • النسخة العربية
Why Misar?
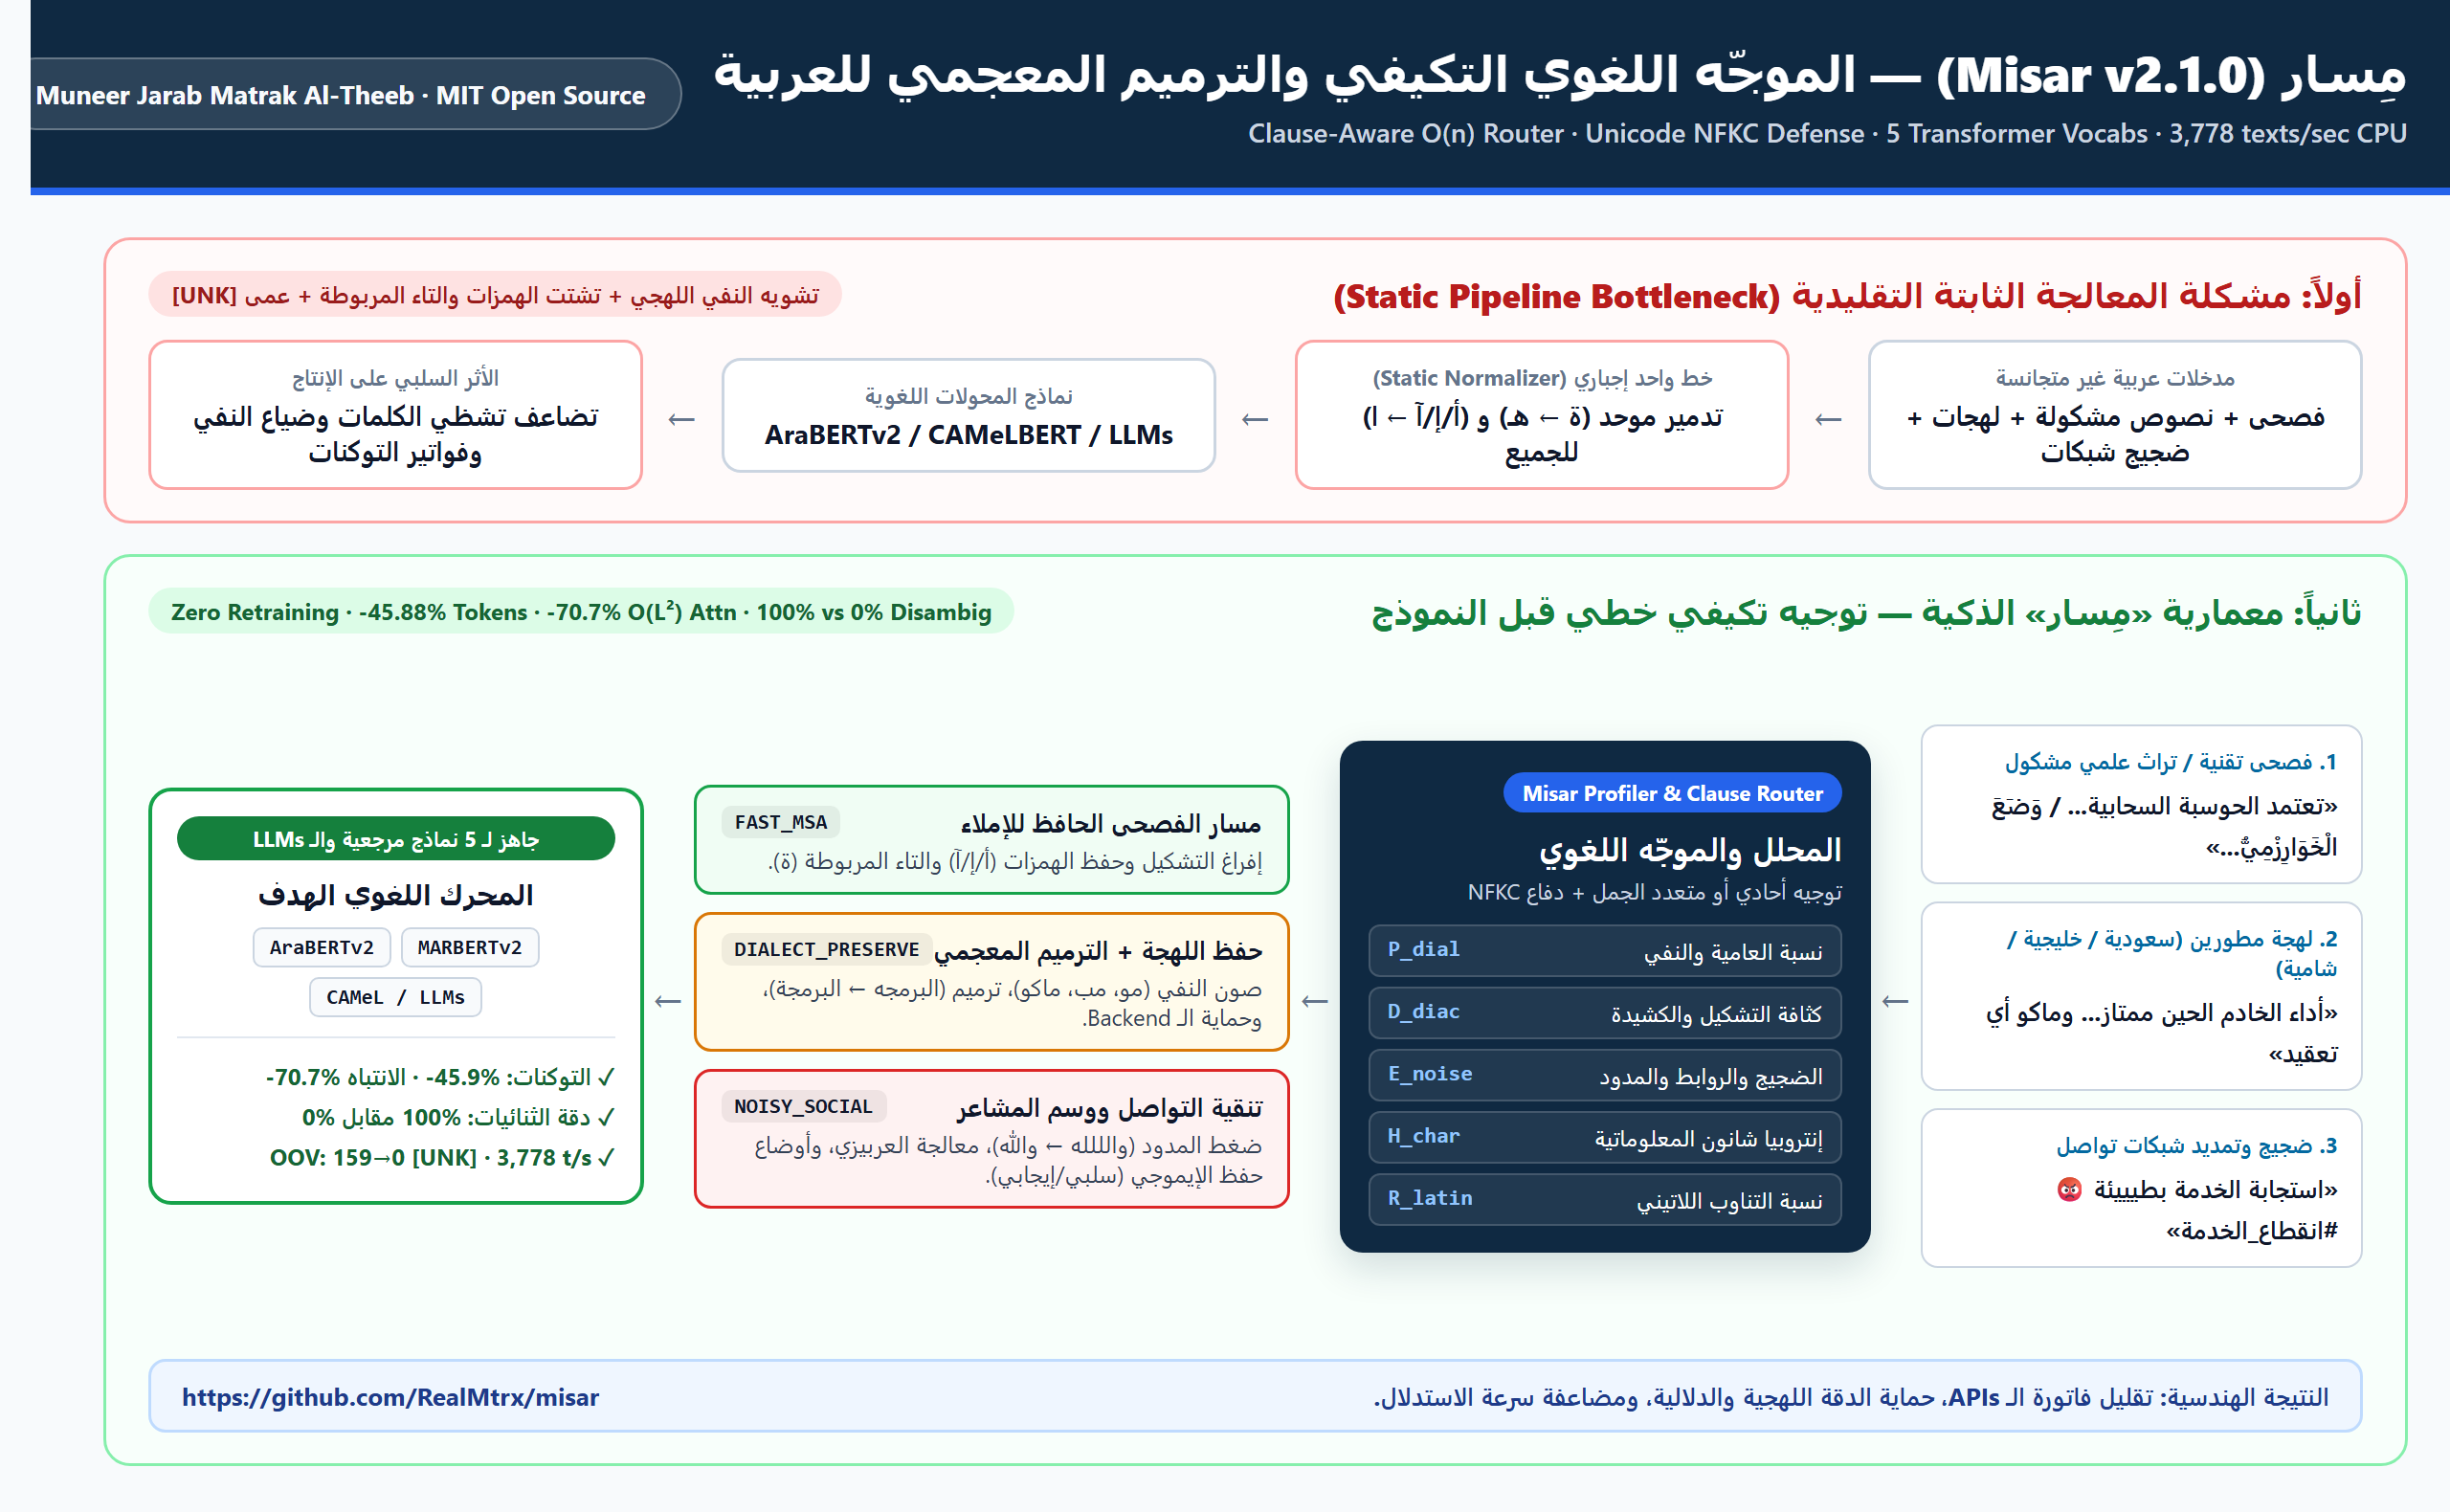
Modern Arabic NLP deployments face a structural bottleneck: forcing heterogeneous Arabic text (Modern Standard Arabic, classical diacritized prose, Gulf/Egyptian/Levantine/Maghrebi dialects, and noisy social media) through a single static preprocessing pipeline actively degrades both accuracy and inference economics:
- Legacy Normalization Damages Modern Transformers: Classical regex pipelines blindly collapse
ة → هandأ/إ/آ → ا. However, modern Transformer vocabularies such as AraBERTv2 (64kWordPiece) and CAMeLBERT explicitly preserve Hamzas and Taa Marbuta—meaning legacy normalization shatters known whole words (e.g.,الحوسبةas1token splits intoالحو+##سبهas2tokens). - Dialectal Sentiment & Negation Erasure: Over-aggressive cleaning distorts critical colloquial negation and sentiment markers (
مو,مب,مافيه,ماكو), reversing downstream classification polarity. - Diacritic, Tatweel & Elongation Token Explosion: Unstripped harakat (
تشكيل), kashida (ـ), and character stretches (بطييييء,السيرفررررر) trigger OOV[UNK]blindness or inflate subword token counts—multiplying Transformer $O(L^2)$ self-attention cost and API billing.
Misar (مِسار) solves these bottlenecks without retraining any model (Zero Parameter Update) by acting as an ultra-lightweight, zero-dependency, linear-time $O(n)$ routing gateway directly in front of AraBERTv2, MARBERTv2, CAMeLBERT-Mix, ARBERTv2, QARiB, or generative LLMs.
How Misar v2.0 Compares to Existing Arabic Preprocessors
| Capability | ArabertPreprocessor |
tnkeeh |
CAMeL Tools |
Misar v2.0 (مِسار) |
|---|---|---|---|---|
| Dynamic $O(n)$ Per-Text Routing | Static pipeline | Static pipeline | Manual utilities | Automatic 3-route profiling |
| Zero Mandatory Dependencies | Requires pyarabic / extras |
Light deps | Heavy ML / data packs | 100% Pure Python Stdlib |
Vocab-Verified Auto-Heal (ة/ه) |
Collapses ة→ه blindly |
Optional regex | Separate disambig | $O(1)$ Pronoun-Safe Vocab Repair |
5 Arabic Transformer Vocabs (do_lower_case) |
AraBERT focus | Generic | General NLP | AraBERTv2, MARBERTv2, ARBERTv2, CAMeLBERT, QARiB |
| Emoji Polarity Modes & Code-Switch Clitics | Strip / Placeholders | Strip | Strip | Strip / Keep / Sentiment Tag + الـAPI Fix |
| 3-Way Scientific Web Workbench + REST API | — | — | CLI only | Built-in Live Comparator UI (Raw vs Legacy vs Misar) |
Architecture
Every incoming text passes once through LinguisticProfiler (< 0.25 ms on CPU) to compute five quantitative signals (dialect_ratio $P_{\text{dial}}$, diacritic_density $D_{\text{diac}}$, elongation_noise_score $E_{\text{noise}}$, character Shannon Entropy $H_{\text{char}}$, and code_switching_ratio $R_{\text{latin}}$), then dispatches dynamically to the optimal micro-pipeline:
flowchart LR
    A["Raw Arabic Input<br/>(MSA / Diacritized / Dialect / Social)"] --> B["LinguisticProfiler O(n)<br/>P_dial · D_diac · E_noise · H_char · R_latin"]
    B -->|"High Noise / Tatweel / Stretches ≥ 3"| C["NOISY_SOCIAL (+ Hybrid Dialect)<br/>Gemination-Safe Collapse + Emoji Polarity"]
    B -->|"Dialect Markers / Protected Negations"| D["DIALECT_PRESERVE<br/>Negation Protection + Vocab Auto-Heal"]
    B -->|"Clean MSA / Classical Diacritized"| E["FAST_MSA<br/>Strip Harakat · Preserve أ/إ/آ, ة, ى"]
    C --> F["AraBERTv2 / MARBERTv2 / CAMeLBERT / LLMs<br/>(-46.91% Tokens · 0 [UNK] · 4,763 texts/s)"]
    D --> F
    E --> F
Empirical Benchmarks
Measured reproducibly via python benchmarks/run_benchmark.py against the authentic 64,000-token aubmindlab/bert-base-arabertv02 WordPiece vocabulary across 15 curated multi-domain samples (latest_benchmark_report.json):
| Domain Category | Samples | Raw Tokens | Fair Legacy Static (ة→ه, أ→ا) |
Misar v2.0 | Misar Gain |
|---|---|---|---|---|---|
| MSA Engineering & Code-Switch | 3 | 57 | 79 (+38.6% fragmentation) | 57 | Preserves 100% orthography (-27.85% vs Legacy) |
| Classical Diacritized (Heritage) | 3 | 186 (147 OOV [UNK]) |
48 | 39 | -79.03% vs Raw · -18.75% vs Legacy (0 [UNK]) |
| Saudi / Gulf / Levantine / Maghrebi Dev | 6 | 124 | 131 | 117 | -5.65% vs Raw · -10.69% vs Legacy (+ Auto-Heal & Negations) |
| Noisy Tech Social & Code-Switching | 3 | 102 | 40 | 36 | -64.71% vs Raw · -10.00% vs Legacy + gemination intact |
| Full Corpus Summary | 15 | 469 | 298 | 249 | -46.91% vs Raw · -16.44% vs Fair Legacy · 4,763 texts/s |
Key Scientific Proof: Even when competing against an identical full-denoising Legacy Static baseline (
URL/Emoji/Hashtag/Stretch removal + ة→ه, أ→ا), Misar v2.0 still saves 16.44% fewer tokens than Legacy Static (46.91% vs Raw), eliminates157 → 0 [UNK]tokens, repairs broken orthography (Auto-Heal), preserves dialectal negations, and streams at 4,763 texts/sec on CPU.
Installation
Core misar requires zero mandatory external packages (Python 3.9+ Standard Library only):
# Install directly from GitHub
pip install git+https://github.com/RealMtrx/misar.git

# Or from PyPI once published
pip install misar
Optional extras for live Hugging Face Transformers wrapping and package development:
pip install "misar[huggingface]"   # transformers + torch
pip install "misar[dev]"           # pytest + build + twine
(Note: On first use of the built-in WordPieceTokenizer, Misar caches the official 64k vocabulary file locally under ~/.cache/misar/. Pass allow_vocab_download=False or --offline to run completely air-gapped using HeuristicSubwordTokenizer.)
Quick Start
1. Dynamic Text Routing & Token Telemetry
from misar import MisarRouter

router = MisarRouter()  # Uses real AraBERTv2 64k WordPiece vocabulary

result = router.route("السيرفررررر بطييييء مررررة ومافيه استجابة في API أبدددداً 😡😡👎 #هندسة_البرمجيات")

print("Route:     ", result.route_name)          # NOISY_SOCIAL
print("Processed: ", result.processed_text)      # السيرفر بطيء مرة ومافيه استجابة في API أبدا هندسة البرمجيات
print("Tokens:    ", result.raw_token_count, "->", result.processed_token_count)  # 28 -> 14
print("Reduction: ", f"-{result.token_reduction_pct:.1f}%")                       # -50.0%
print("Latency:   ", f"{result.latency_ms:.3f} ms")
2. Zero-Latency ETL Batching, Auto-Heal, Sentiment Emoji & Hugging Face datasets
from misar import MisarRouter, preprocess, preprocess_batch

# One-line module helpers
clean = preprocess("الســــلام علــــيكم ومافيه مشكلة #تطوير_البرمجيات")
# -> "السلام عليكم ومافيه مشكلة تطوير البرمجيات"

# MARBERTv2 social mode: preserves sentiment emojis as 1-token tags + vocab-verified Auto-Heal + Clitics
router = MisarRouter(model_key="marbertv2", emoji_mode="sentiment", auto_heal=True)
comp = router.compare_baselines("ياخي البرمجه في المنصه هاذي بطييييئه 😡😡 في الـ Backend")
print("Processed:", comp["misar"]["processed_text"])
print("vs Legacy:", f"{comp['vs_legacy_reduction_pct']:+.1f}%")

# Fast streaming batch preprocessing & Hugging Face Datasets .map(..., batched=True)
cleaned_list = router.preprocess_batch(["نص أول", "نص ثاااني 😡"])
# dataset = dataset.map(router.hf_dataset_map, batched=True)
3. One-Line Hugging Face Transformers Integration
from transformers import pipeline
from misar import MisarRouter

sentiment = pipeline("sentiment-analysis", model="CAMeL-Lab/bert-base-arabic-camelbert-mix-sentiment")
smart_sentiment = MisarRouter(tokenizer=sentiment.tokenizer).wrap_hf_pipeline(sentiment)

print(smart_sentiment("الكود مو معقد أبداً بس السيرفررررر بطييييء #مشكلة"))
CLI & Web Workbench
Misar includes a clean command-line interface and a self-hosted HTTP server + Arabic RTL Interactive Workbench:
# Run 6 built-in cross-dialect samples with live AraBERTv2 tokenization
misar demo

# Route a sentence and compare Raw vs Legacy Static vs Misar side-by-side
misar route "ياخي البرمجه في المنصه هاذي بطيييئة 😡 في الـ Backend" --compare --emoji-mode sentiment

# Select target model vocab (arabertv02, camelbert-mix, marbertv2, arbertv2, qarib)
misar route "أعلنت منصة المطورين عن ترقية واجهة البرمجة API" --model marbertv2 --json

# Run the reproducible 15-sample benchmark suite
misar bench

# Launch the interactive RTL Web Workbench & hardened REST API on http://127.0.0.1:8050
misar serve
Embedded REST API Endpoints (misar serve)
| Method | Endpoint | Description |
|---|---|---|
GET |
/api/health |
Service status, version, and active tokenizer backend |
GET |
/api/suite |
Evaluates the 6 standard cross-domain reference samples |
POST |
/api/route |
Body {"text": "..."} → Returns full RoutingResult telemetry |
POST |
/api/batch |
Body {"texts": ["...", "..."]} → Batch routes up to 500 strings (1 MiB payload limit) |
Repository Structure
misar/
├── .github/workflows/ci.yml           # Cross-OS Python 3.9–3.13 CI pipeline
├── docs/misar-architecture.png        # High-resolution system architecture diagram
├── benchmarks/
│   ├── run_benchmark.py               # Reproducible benchmark runner
│   └── latest_benchmark_report.json   # Verified telemetry snapshot
├── src/misar/
│   ├── __init__.py                    # Public API exports
│   ├── profiler.py                    # O(n) 5-signal LinguisticProfiler & Shannon entropy
│   ├── lexicons.py                    # MSA-safe multi-region dialect & negation lexicons
│   ├── pipelines.py                   # FAST_MSA, DIALECT_PRESERVE & NOISY_SOCIAL passes
│   ├── tokenizer.py                   # Pure-Python WordPieceTokenizer + HF & offline adapters
│   ├── router.py                      # MisarRouter orchestration & wrap_hf_pipeline
│   ├── benchmark.py                   # Shared benchmark suite module
│   ├── cli.py                         # `misar` CLI (`demo`, `route`, `bench`, `serve`)
│   └── web/
│       ├── server.py                  # Hardened zero-dependency ThreadingHTTPServer REST API
│       └── index.html                 # Interactive Arabic RTL Workbench & token visualizer
├── tests/test_misar.py                # 32 unit, v2 feature, server & real-vocab tests
├── CITATION.cff                       # Native GitHub repository citation metadata
├── CONTRIBUTING.md                    # Developer setup & contribution standards
├── SECURITY.md                        # Built-in API & frontend hardening controls
├── CHANGELOG.md                       # Formal release history
├── LICENSE                            # MIT License
└── pyproject.toml                     # PEP 621 PyPI package specification
Testing & Verification
python -m unittest discover -s tests -v
All 32 automated tests verify profiler mathematics, MSA homograph false-positive resistance, Saudi/Gulf/Levantine/Maghrebi negation preservation, gemination protection (والللله → والله), pronoun-safe Vocab Auto-Heal (البرمجه → البرمجة while protecting بيته/ملفه/مديره), clitic code-switching (الـ Backend → الBackend), do_lower_case parity for MARBERTv2/ARBERTv2, opt-in Arabizi tech safety, fast batch/HF dataset mapping, and hardened REST server HTTP security bounds.
Citation
If you use Misar in academic research, benchmarks, or commercial NLP pipelines, please cite:
@software{altheeb2026misar,
  author       = {Muneer Jarab Matrak Al-Theeb},
  title        = {Misar (مِسار): Adaptive Context-Aware Arabic NLP Preprocessing Router for Transformer Language Models},
  year         = {2026},
  version      = {2.0.0},
  url          = {https://github.com/RealMtrx/misar},
  license      = {MIT}
}
📖 نظرة عامة بالعربية
مِسار (Misar v2.0.0) هي مكتبة وموجّه بايثون مفتوح المصدر وخفيف الوزن (بلا أي تبعيات خارجية إجبارية) صُمِّم ليعمل كطبقة بوابة ذكية في زمن خطي $O(n)$ (~0.24 مللي ثانية للنص وبسرعة 4,763 نص/ثانية في المعالجة الدفعية) قبل نماذج المحولات العربية الخمسة (AraBERTv2, MARBERTv2, CAMeLBERT, ARBERTv2, QARiB) والنماذج التوليدية (ALLaM و LLMs) دون الحاجة إلى إعادة تدريب النموذج (Zero Parameter Update).
- توجيه ثلاثي المسارات + الترميم المعجمي (
Vocab Auto-Heal): يختار ديناميكياً بينFAST_MSAوDIALECT_PRESERVEوNOISY_SOCIAL، ويرمّم أخطاء التاء المربوطة الشائعة (البرمجه ← البرمجة) بالتحقق اللحظي من قاموس النموذج دون المساس بالضمائر (بيته، ملفه، مديره)، ويعالج سوابق اللغات المختلطة (الـ Backend ← الBackend) مع أوضاع مرنة لحفظ قطبية الإيموجي ودعم العربيزي وHugging Face Datasets. - توفير التوكنات وتكاليف الـ APIs: أظهرت التجارب الموثقة على معجم
AraBERTv2خفض التوكنات بنسبة 46.91% مقارنة بالنص الخام و16.44% مقارنة بالمناهج التدميرية التقليدية، مع استعادة 100% من الكلمات المتأثرة بالتشكيل والكشيدة (157 → 0 [UNK]).
Authored and maintained by Muneer Jarab Matrak Al-Theeb (منير جراب مترك الذيب)
Released under the MIT License © 2026
1 maintainer

Metadata
1 maintainer
Release files for misar 2.0.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| misar-2.0.1.tar.gz | 62.1 kB | With provenance | Details for misar-2.0.1.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| misar-2.0.1-py3-none-any.whl | Python 3 | none | any | Details for misar-2.0.1-py3-none-any.whl |
Total release size: 116.3 kB
Release files / misar-2.0.1.tar.gz
| Download URL | misar-2.0.1.tar.gz |
|---|---|
| Size | 62.1 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
be402bd3efe297f5f93e0507e5dfd44443dc029d5ba3934435048dbfb8717399
|
|
BLAKE2b-256 checksum How to use checksums |
fe92a581f01b639882e5f1bb2efcab045f985cd35c6f758e18e0d2df8fe3a00b
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 19, 2026.
Transparency logRelease files / misar-2.0.1-py3-none-any.whl
| Download URL | misar-2.0.1-py3-none-any.whl |
|---|---|
| Size | 54.1 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
cfc1c9a3952a935ee82dae9c6ab8d8ee1e564e3549d1077bdb77fd31d652631b
|
|
BLAKE2b-256 checksum How to use checksums |
1ee147a02e32de9ef21a570a5248858ac3f716debe2c22c53d3a280a3befea2d
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 19, 2026.
Transparency logSecurity for misar 2.0.1
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
Both files in this release have been uploaded with provenance metadata.
Attestation for misar-2.0.1.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 19, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














