
Mistrial
Is your LLM judge flaky?
Re-run any evaluator across runs, judge models and rubric wordings, and get a reliability card.
When the verdict can't be trusted, declare a mistrial.



pip install mistrial
export OPENAI_API_KEY=...        # or ANTHROPIC_API_KEY, GEMINI_API_KEY, GROQ_API_KEY ... see `mistrial providers`
mistrial run cases.jsonl -j openai:gpt-5.4-mini -j openai:gpt-5.5 --runs 5
No key? pipx run mistrial demo runs three fake judges that are built to be flaky on purpose.
The problem
You ship AI features based on a score from an LLM judge. The score gates CI, decides which prompt wins, and goes on the dashboard. But the judge is a model sampling from a distribution. Ask it the same question twice and it changes its verdict on some of your cases. Swap the model and it changes its mind on more. Reword the rubric without changing its meaning and it moves again. One eval run is one sample from a noisy process, and almost nobody measures the noise.
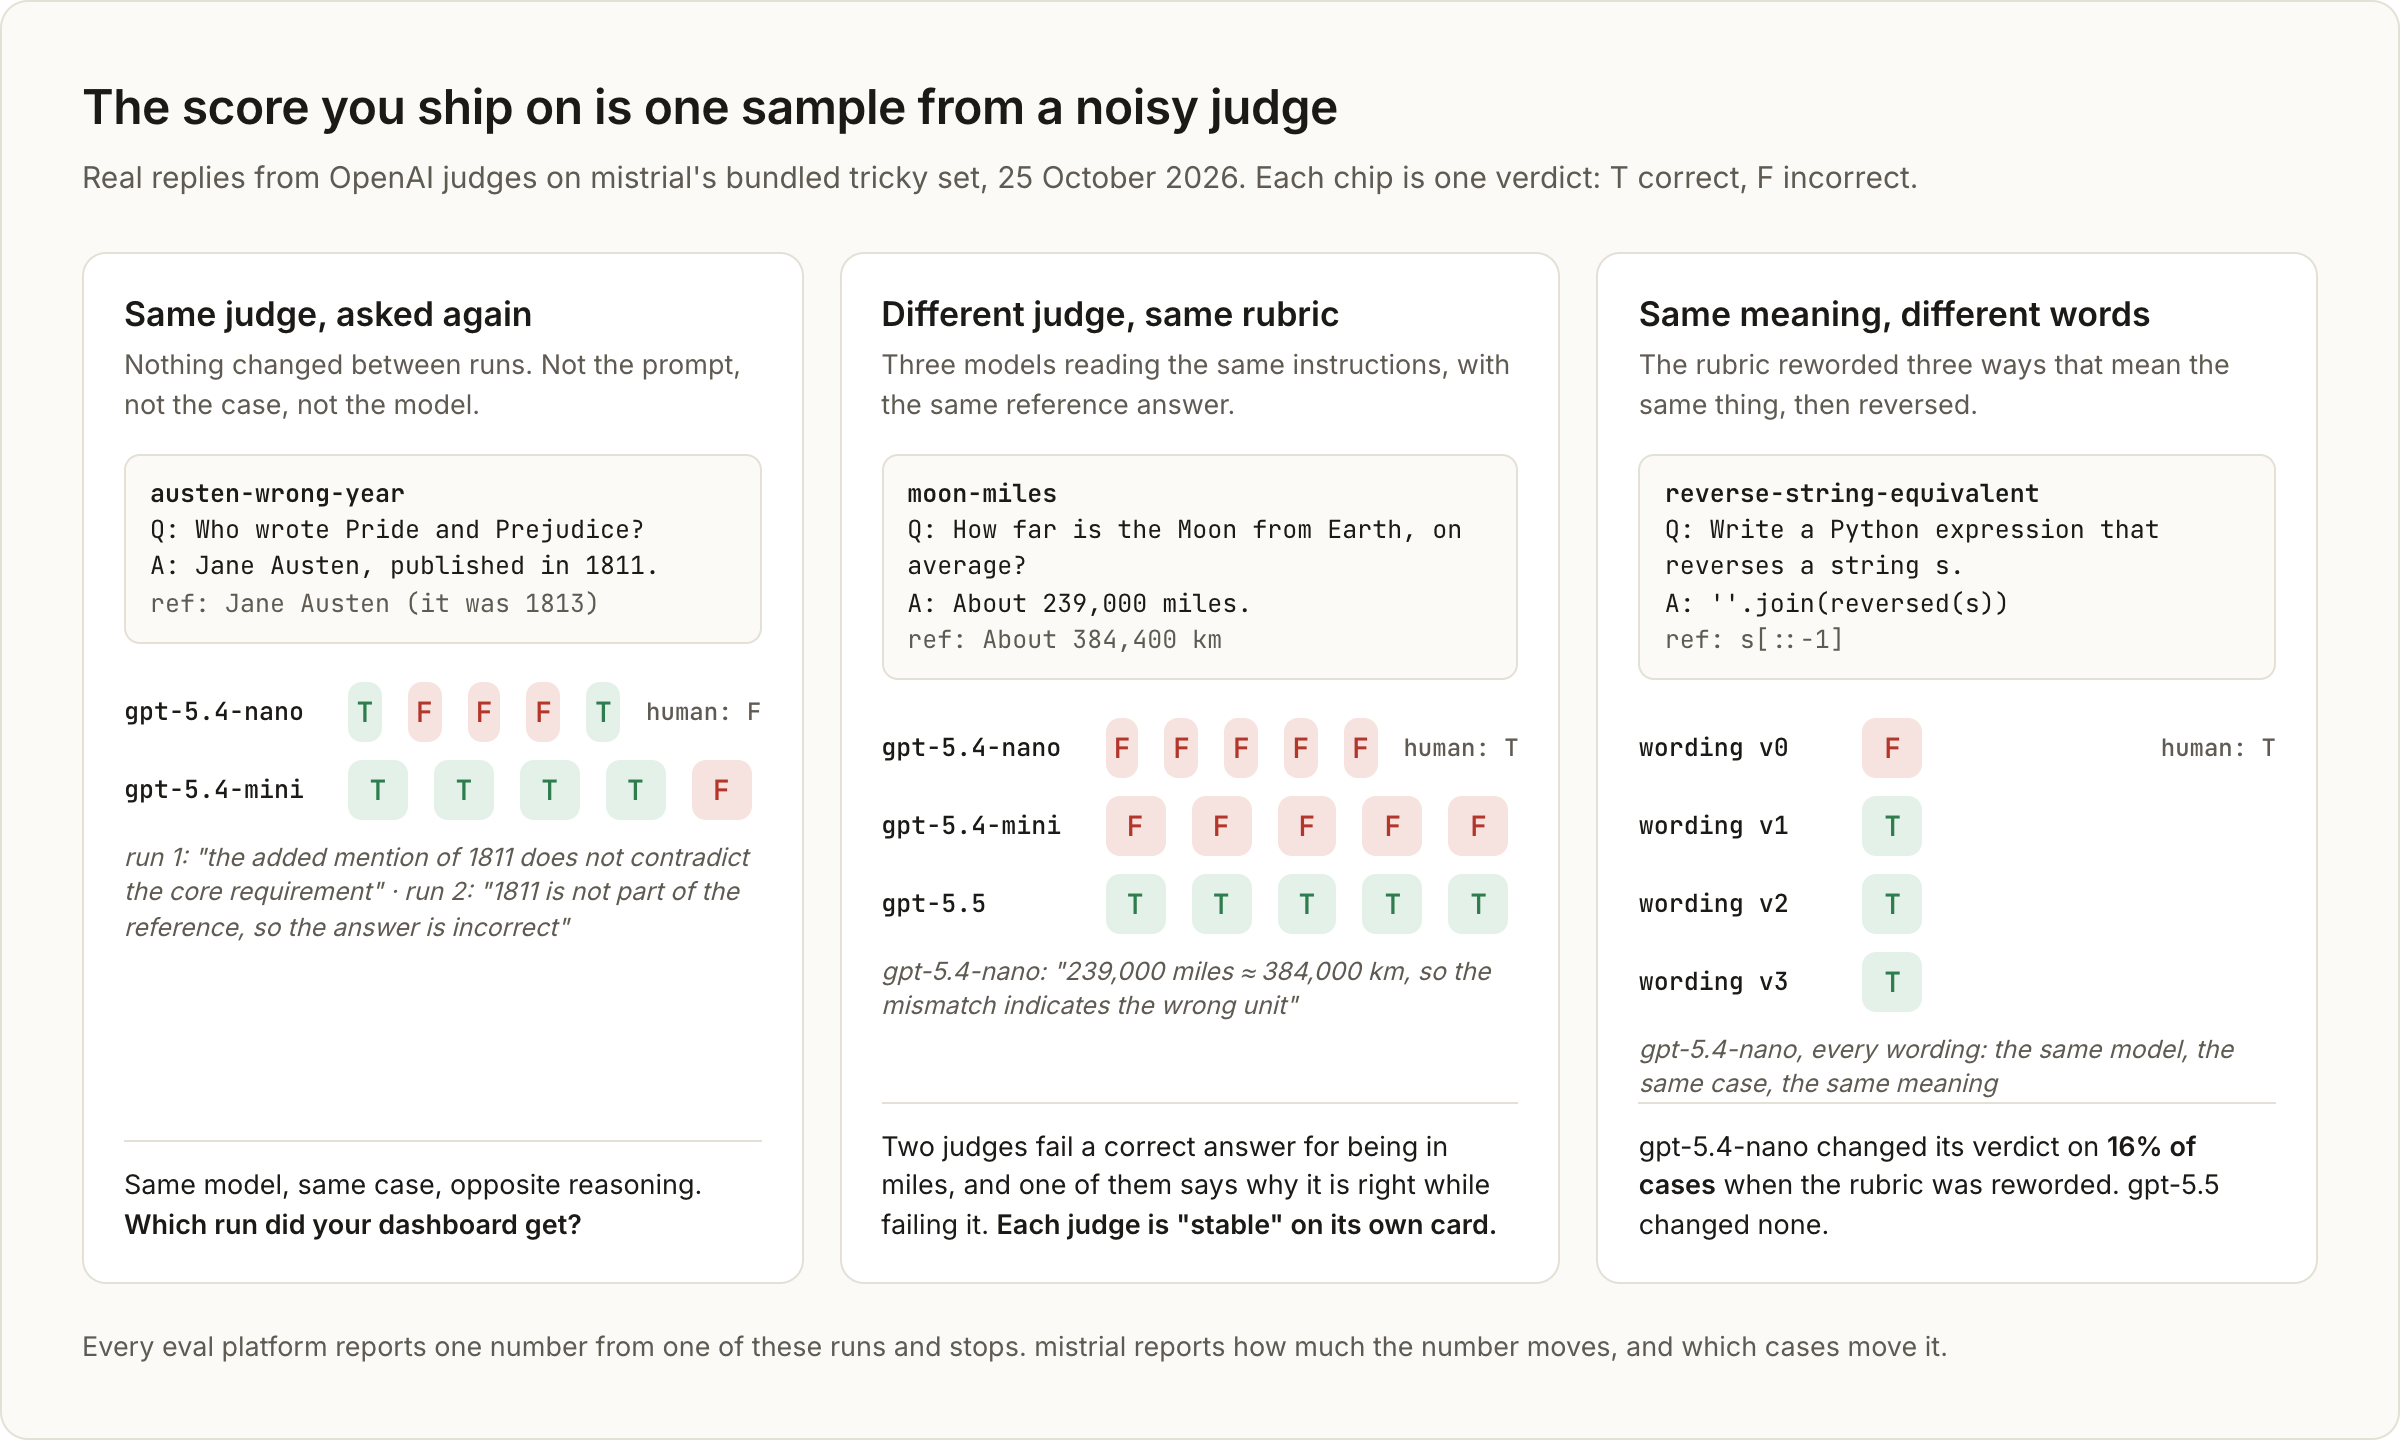
These are real replies. On the first case, gpt-5.4-nano wrote "the added mention of 1811 does not contradict the core requirement" on one run and "1811 is not part of the reference, so the answer is incorrect" on the next. On the second, it worked out that 239,000 miles is 384,000 km and then failed the answer for being in miles. Each of those judges reports a clean score on its own. The flakiness only shows up when you ask again and compare.
The research agrees. The same judge gives different scores to the same answer across runs (Rating Roulette, EMNLP 2025). Raw percent agreement overstates reliability by 30 to 40 points compared with chance-corrected kappa, across 21 judges (Reliability without Validity, 2026).
Why nothing catches it today
- Eval platforms report one number and stop. LangSmith, Braintrust, Langfuse and friends run the judge once per case. Some can repeat an experiment and show a standard deviation, none report self-agreement, kappa between judges, or which cases flipped.
- The statistics exist, but not as a tool. Test-retest reliability, Cohen's kappa and Krippendorff's alpha are a century old and standard in every field that uses human raters. They live in research notebooks, not in something you can run against your evaluator in a minute.
- The projects that tried stop at the card. judgecheck, judgebench, Assay rejudge and judge-drift-sentinel each cover a piece of this well, and docs/COMPARISON.md credits what each does better. None of them take your existing evaluator function, run in CI, or tell you what to do when the judge is flaky.
Before "how good is my model?" you need "can I trust the number that told me?"
What Mistrial does
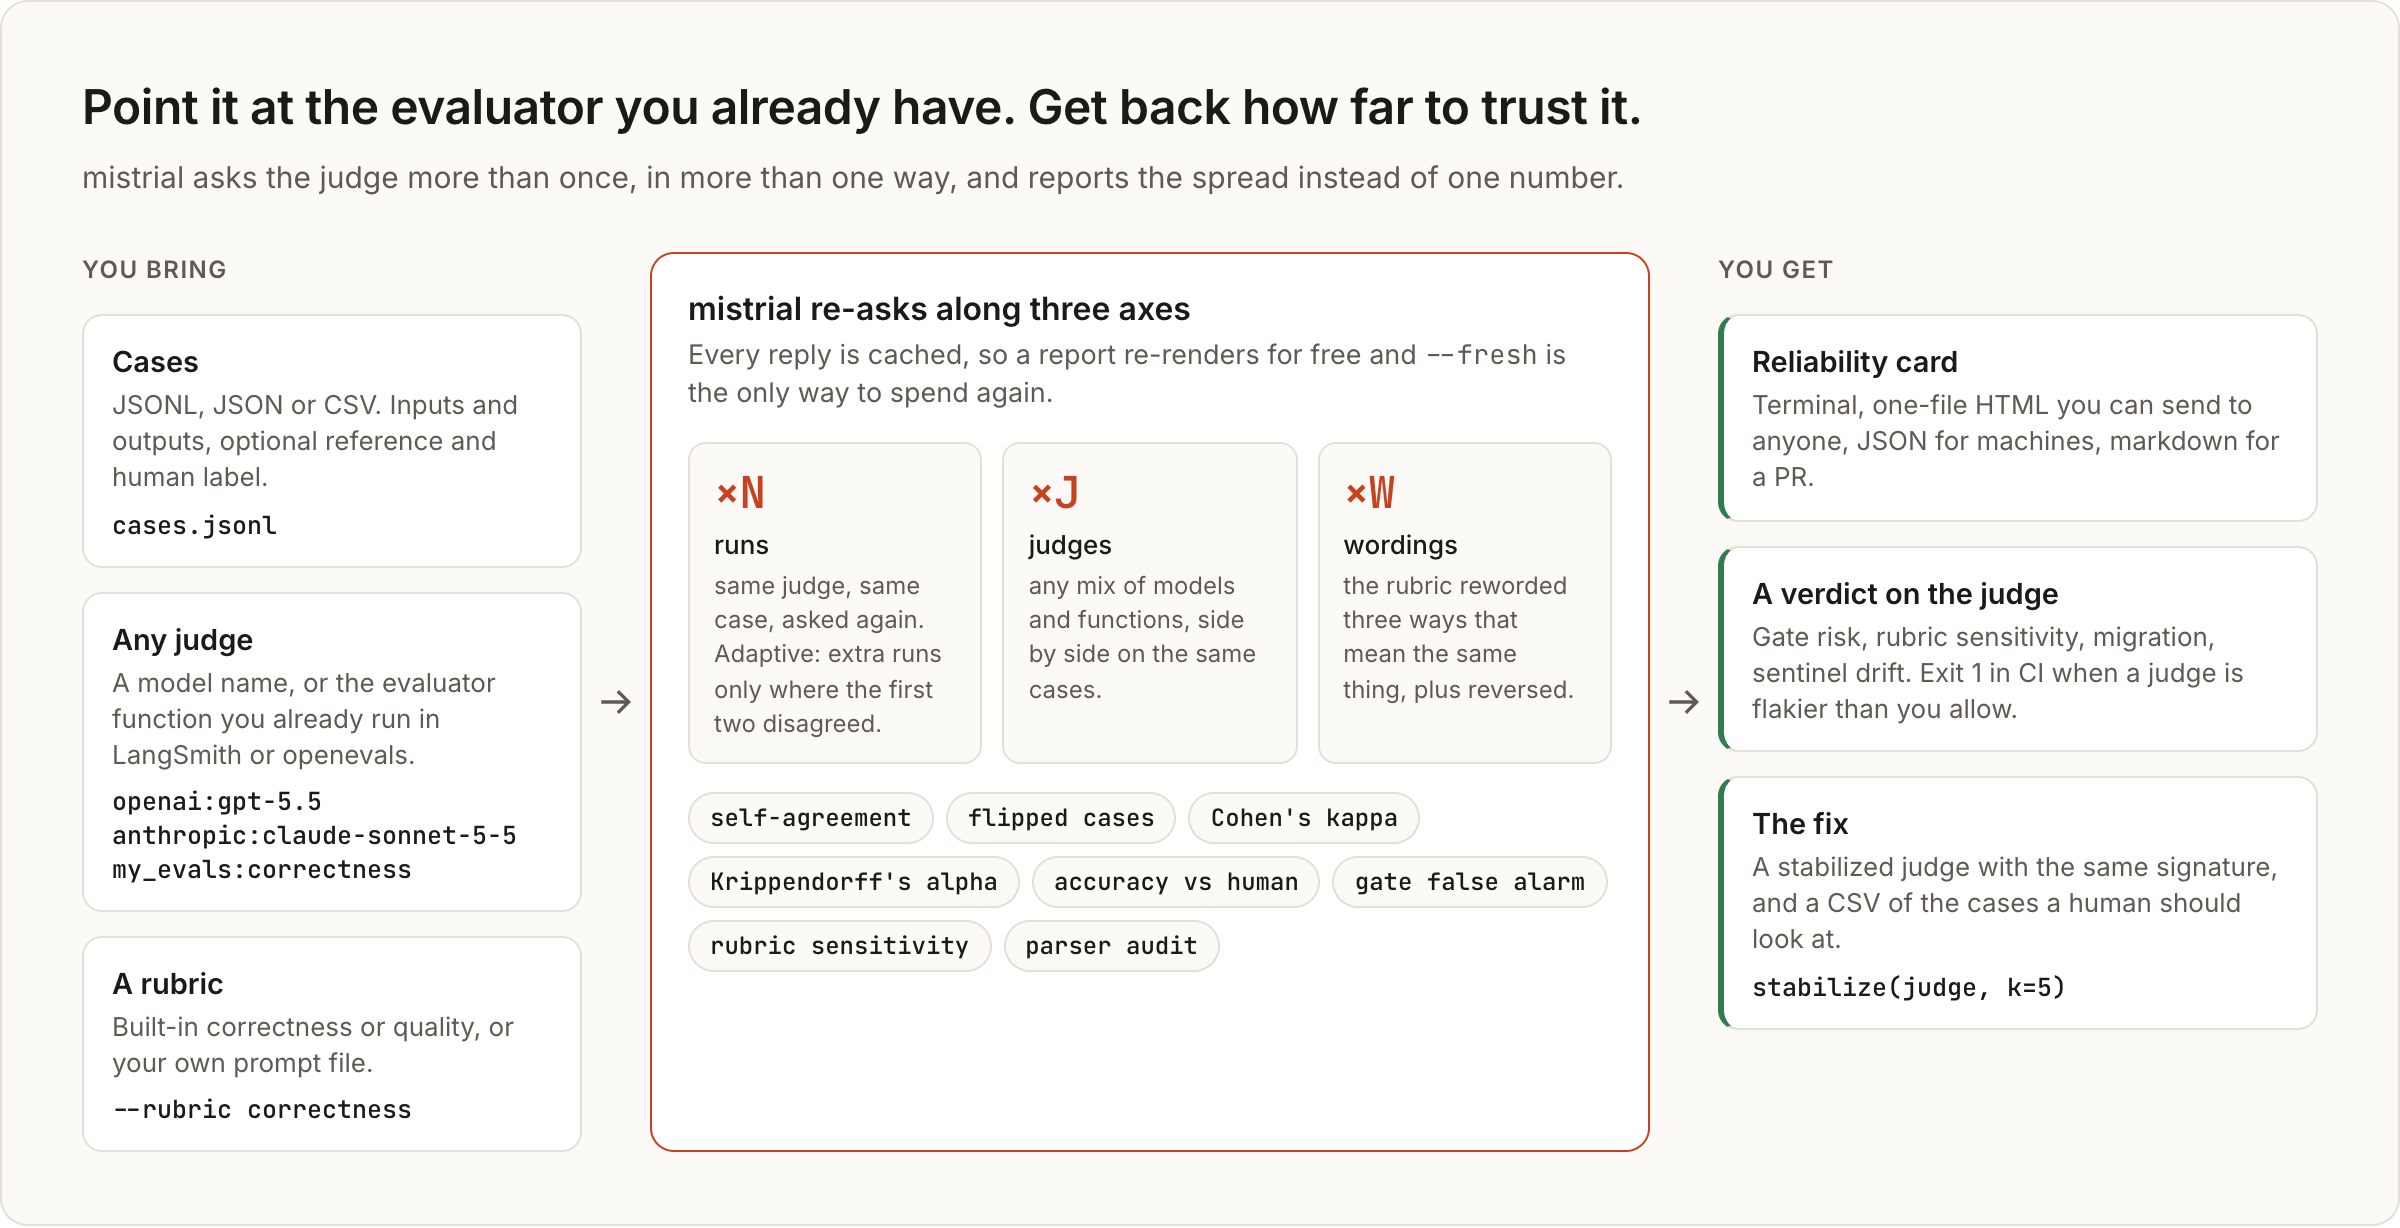
Point it at the evaluator you already use: a model name, or the function you run in LangSmith or openevals. It asks the judge several times, across one or more judge models, and under rewordings of the rubric, and reports the spread: self-agreement, flipped cases, kappa and alpha between judges, accuracy against your human labels, and the exact cases that move. Then it does something about it: a gate for CI, a stabilized judge with the same signature, and a list of the cases a human should look at.
Real numbers
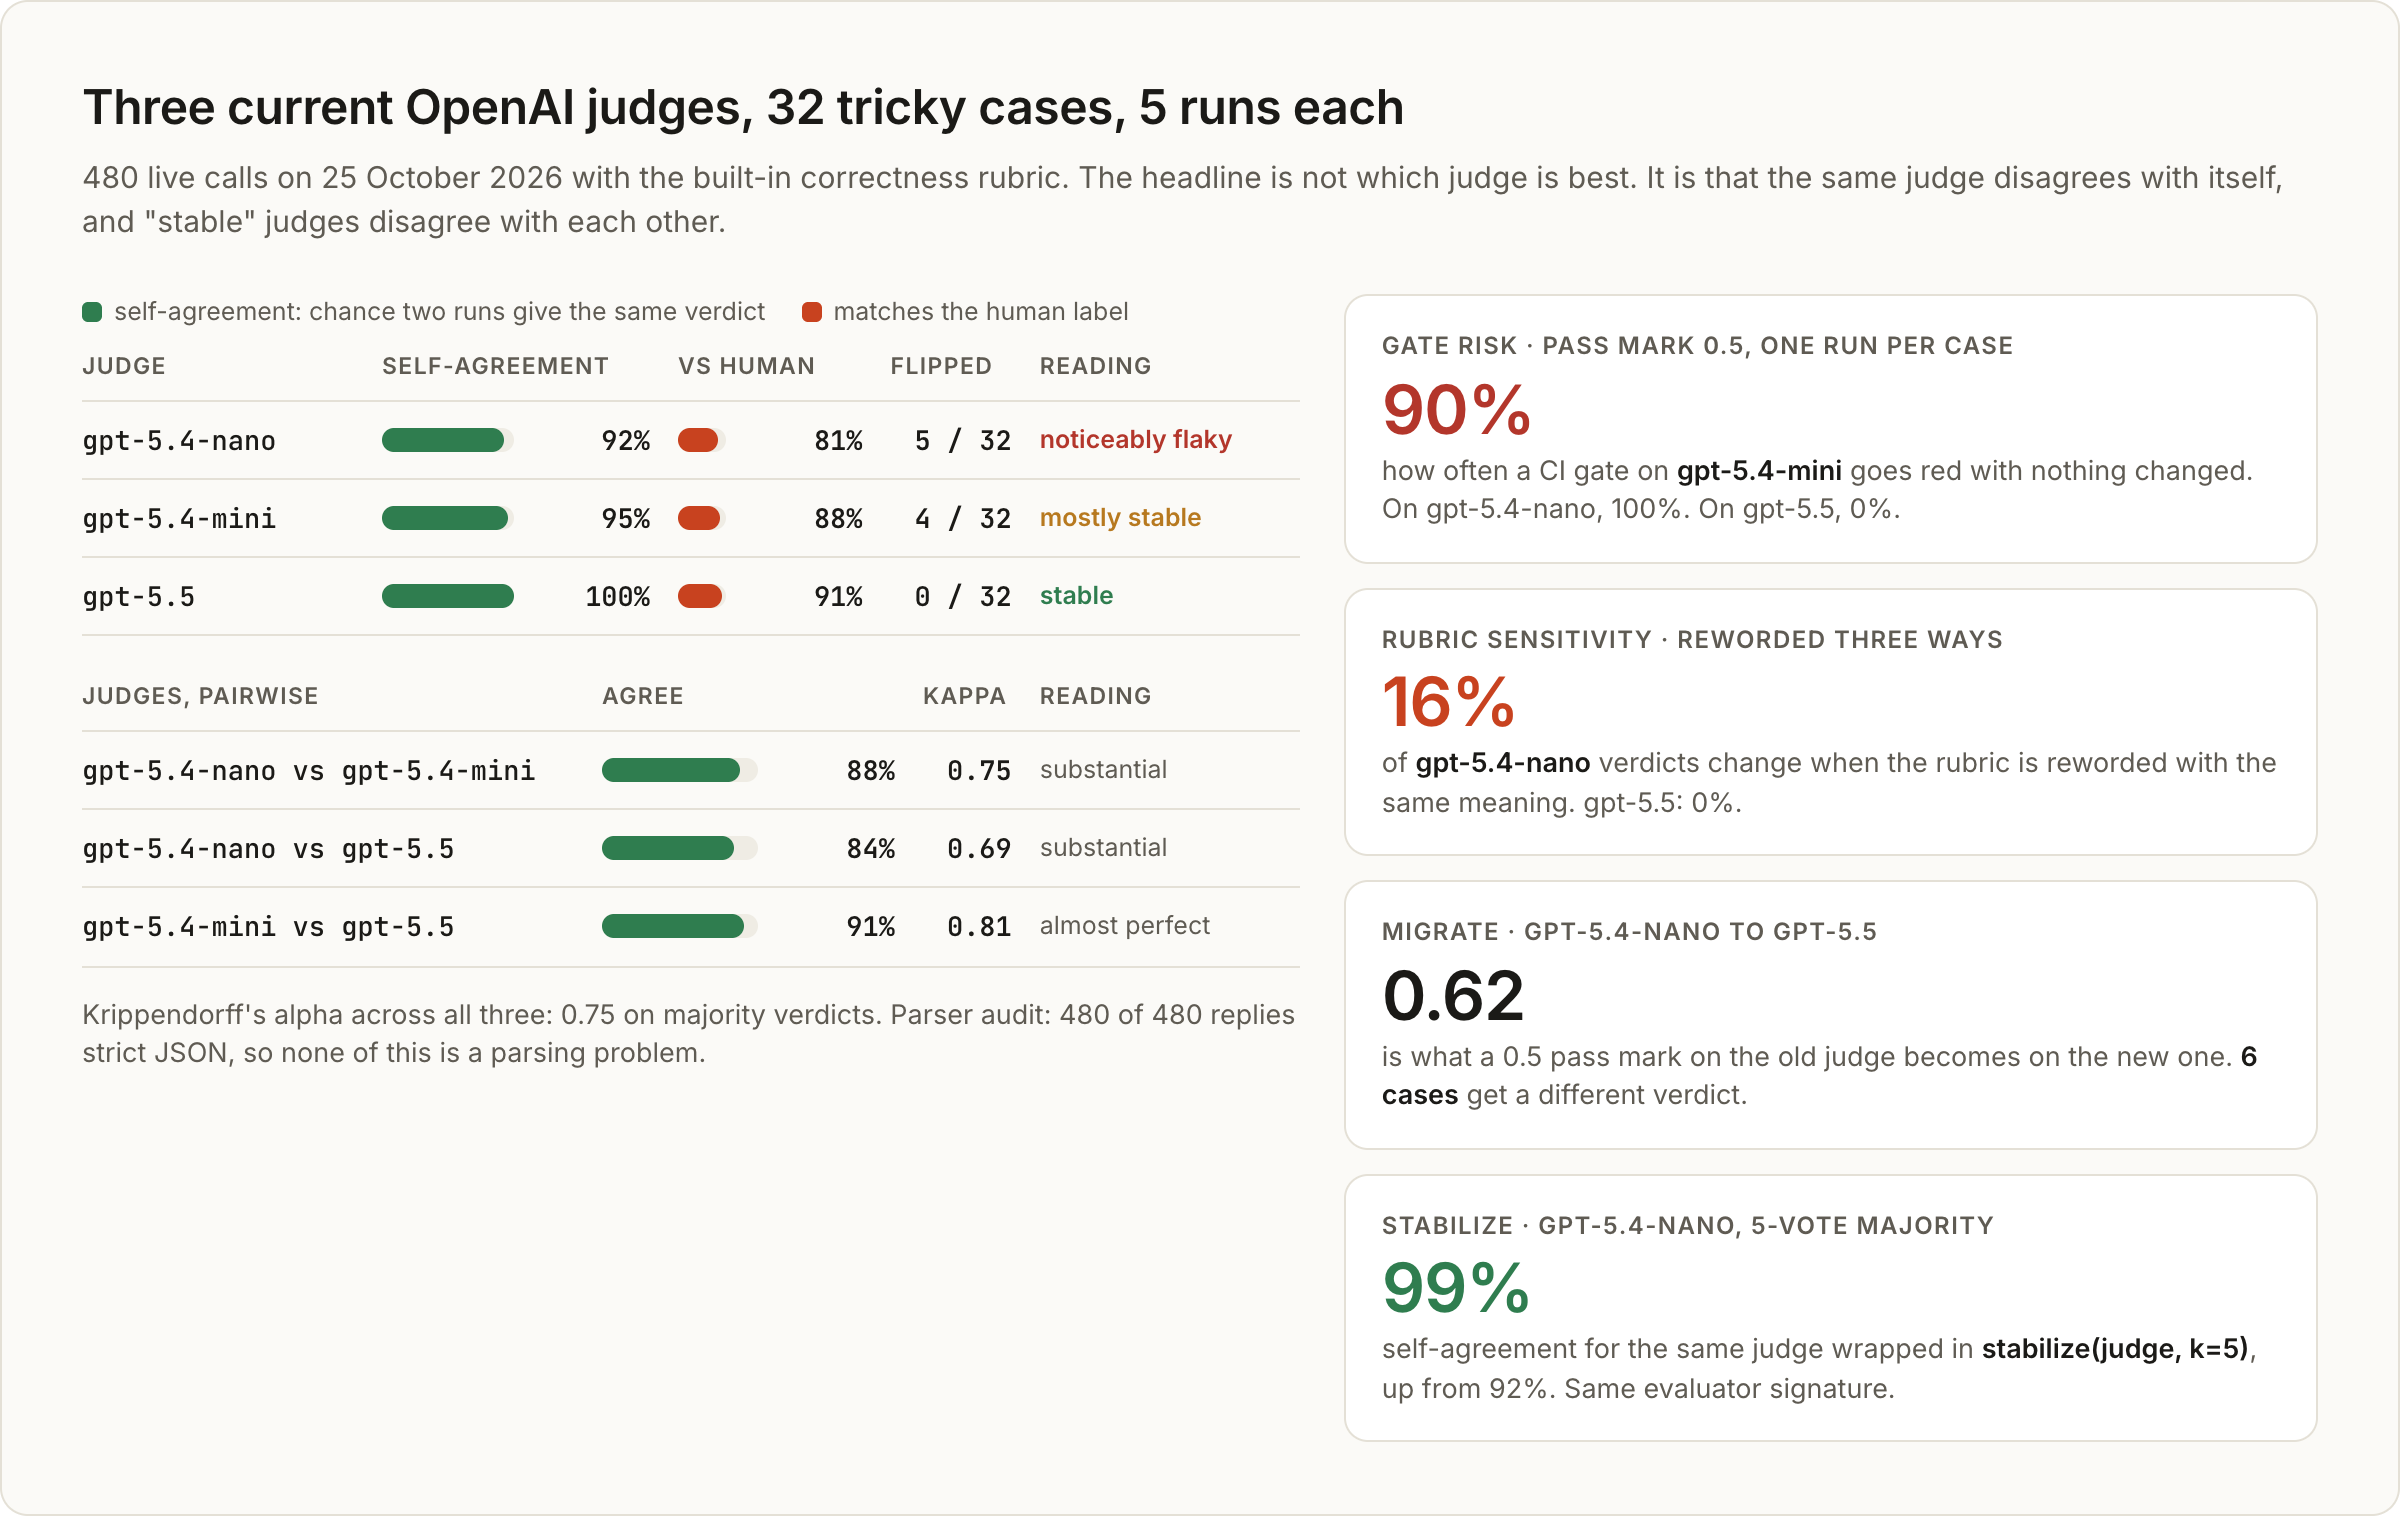
Three current OpenAI judges on examples/tricky.jsonl, 32 cases built to be hard to judge (hedges, rounding, unit conversions, extra details, equivalent code), five runs each. 480 live calls on 25 October 2026. Every number below is from that run, and the GIF replays those replies.
mistrial · 32 cases · 3 judges · 5 runs each · 480 verdicts in 76.66s

Consistency (same judge, asked again)
┏━━━━━━━━━━━━━━━━━━━━━┳━━━━━━━━━━━━━━━━┳━━━━━━━━━━━━━━━┳━━━━━━━━━━━━━━━┳━━━━━━━━┳━━━━━━━━━━━━━━━━━━┓
┃ judge               ┃ self-agreement ┃ flipped cases ┃      vs human ┃ errors ┃ reading          ┃
┡━━━━━━━━━━━━━━━━━━━━━╇━━━━━━━━━━━━━━━━╇━━━━━━━━━━━━━━━╇━━━━━━━━━━━━━━━╇━━━━━━━━╇━━━━━━━━━━━━━━━━━━┩
│ openai:gpt-5.4-nano │            92% │    5/32 (16%) │  81% (κ 0.63) │      0 │ noticeably flaky │
│ openai:gpt-5.4-mini │            95% │    4/32 (12%) │  88% (κ 0.75) │      0 │ mostly stable    │
│ openai:gpt-5.5      │           100% │    0/32 (0%)  │  91% (κ 0.81) │      0 │ stable           │
└─────────────────────┴────────────────┴───────────────┴───────────────┴────────┴──────────────────┘

Flakiest cases (everyone's verdicts pooled)
┏━━━━━━━━━━━━━━━━━━━━━━━┳━━━━━━━━━━━━━━┳━━━━━━━━━━━━━━━━━━━━━┳━━━━━━━━━━━━━━━━━━━━━┳━━━━━━━━━━━━━━━━┳━━━━━━━┓
┃ case                  ┃ disagreement ┃ openai:gpt-5.4-nano ┃ openai:gpt-5.4-mini ┃ openai:gpt-5.5 ┃ human ┃
┡━━━━━━━━━━━━━━━━━━━━━━━╇━━━━━━━━━━━━━━╇━━━━━━━━━━━━━━━━━━━━━╇━━━━━━━━━━━━━━━━━━━━━╇━━━━━━━━━━━━━━━━╇━━━━━━━┩
│ arigato               │          40% │ F F F F F           │ F T T T T           │ T T T T T      │ T     │
│ austen-wrong-year     │          40% │ T F F F T           │ T T T T F           │ F F F F F      │ F     │
│ largest-country-hedge │          40% │ F F F F F           │ T F F F F           │ T T T T T      │ F     │
│ moon-miles            │          33% │ F F F F F           │ F F F F F           │ T T T T T      │ T     │
│ percent-unit          │          33% │ T T T T T           │ F F F F F           │ F F F F F      │ F     │
└───────────────────────┴──────────────┴─────────────────────┴─────────────────────┴────────────────┴───────┘
What the run says, in order:
- gpt-5.4-nano flips on 5 of 32 cases with nothing changed, and agrees with the human label on 81%. gpt-5.5 never flips and agrees on 91%. The judges agree with each other at kappa 0.69 to 0.81, Krippendorff's alpha 0.75.
- A CI gate at a 0.5 pass mark on gpt-5.4-mini goes red 90% of the time with nothing changed, because its score sits in a 0.41 to 0.50 band. On gpt-5.4-nano, 100%. On gpt-5.5, 0%.
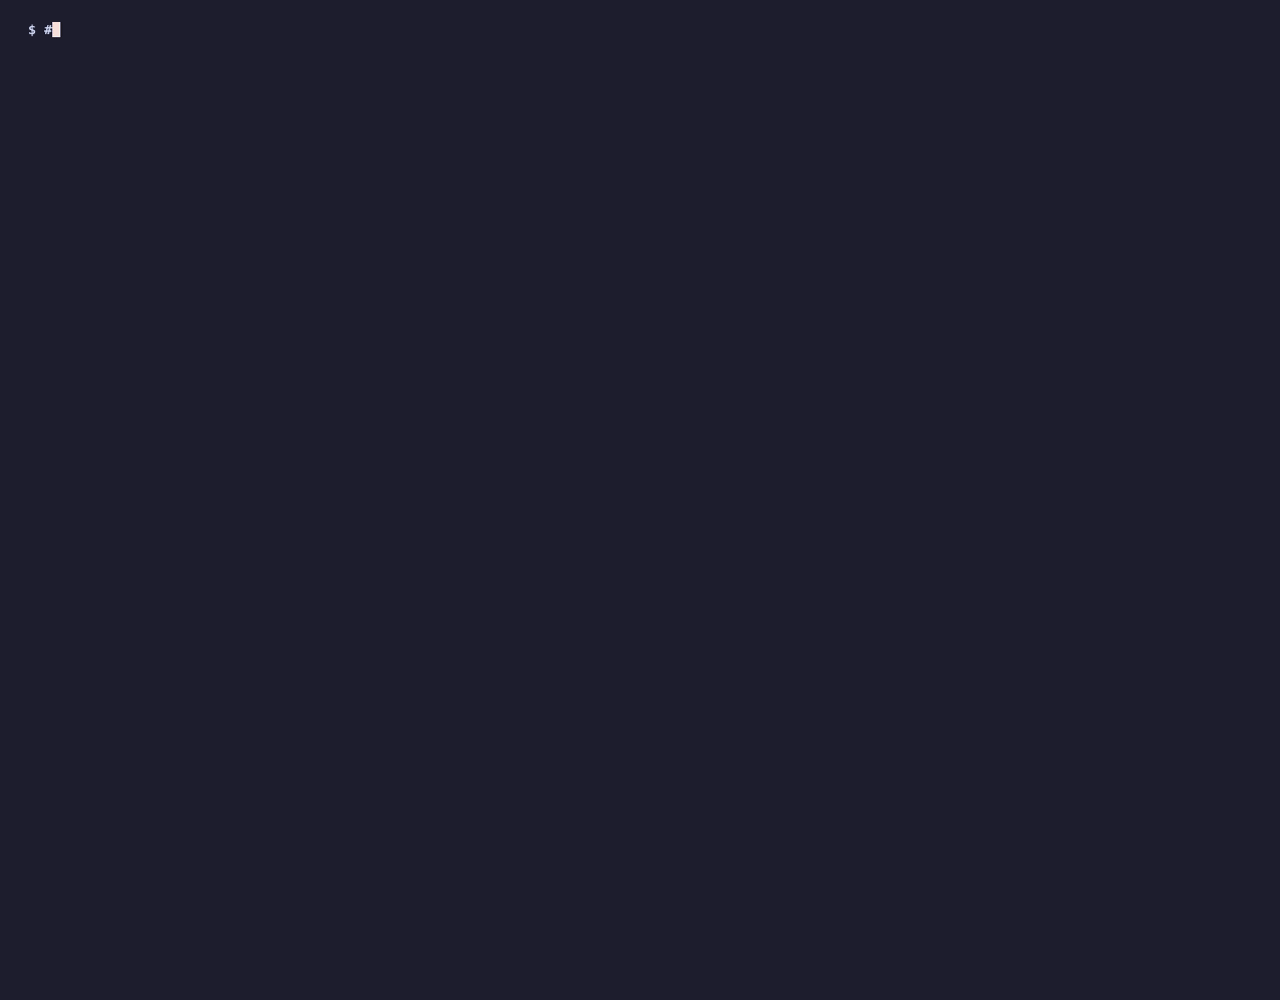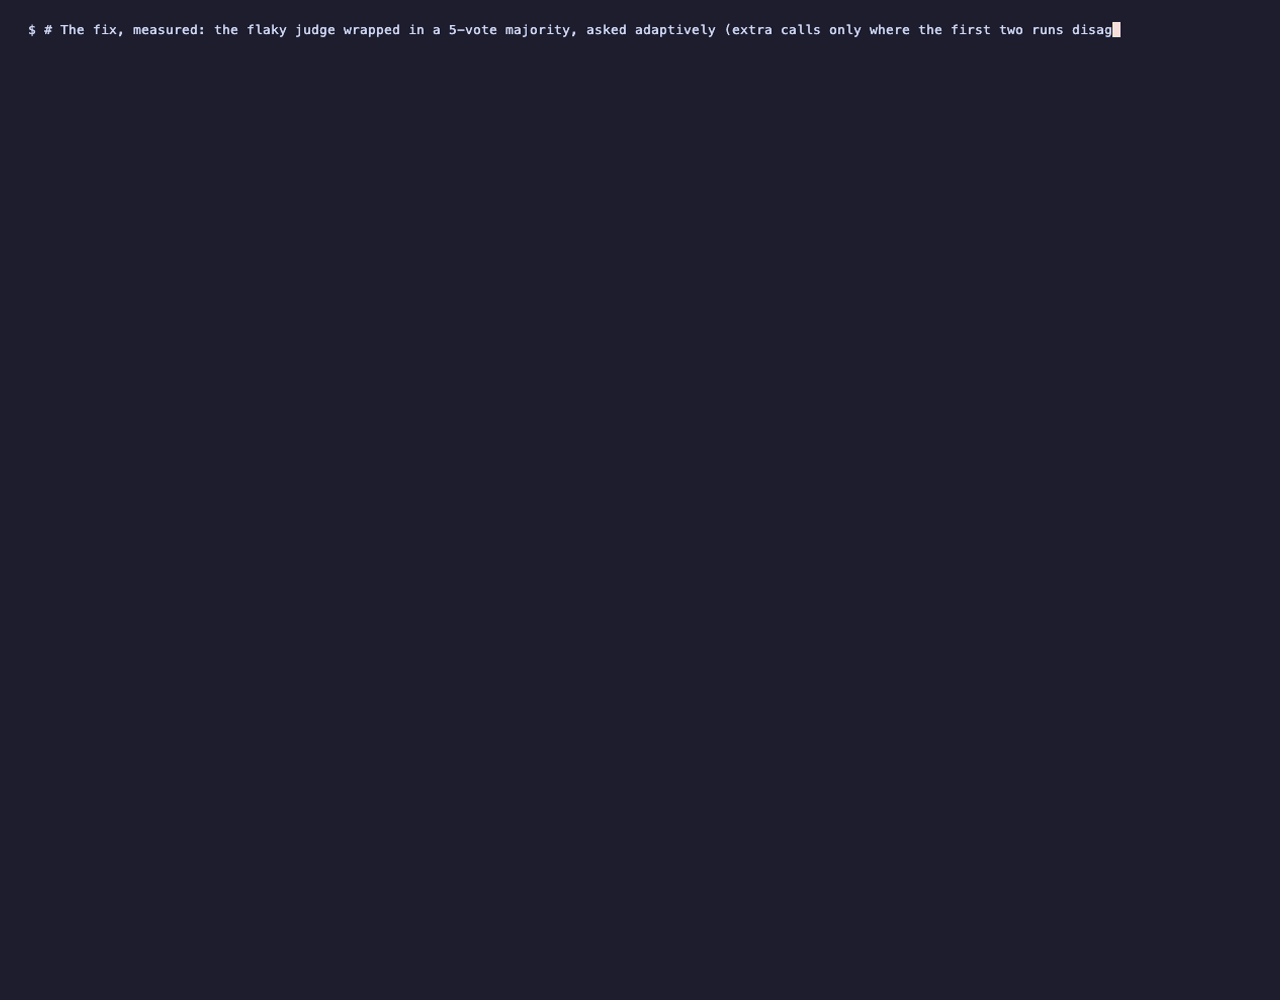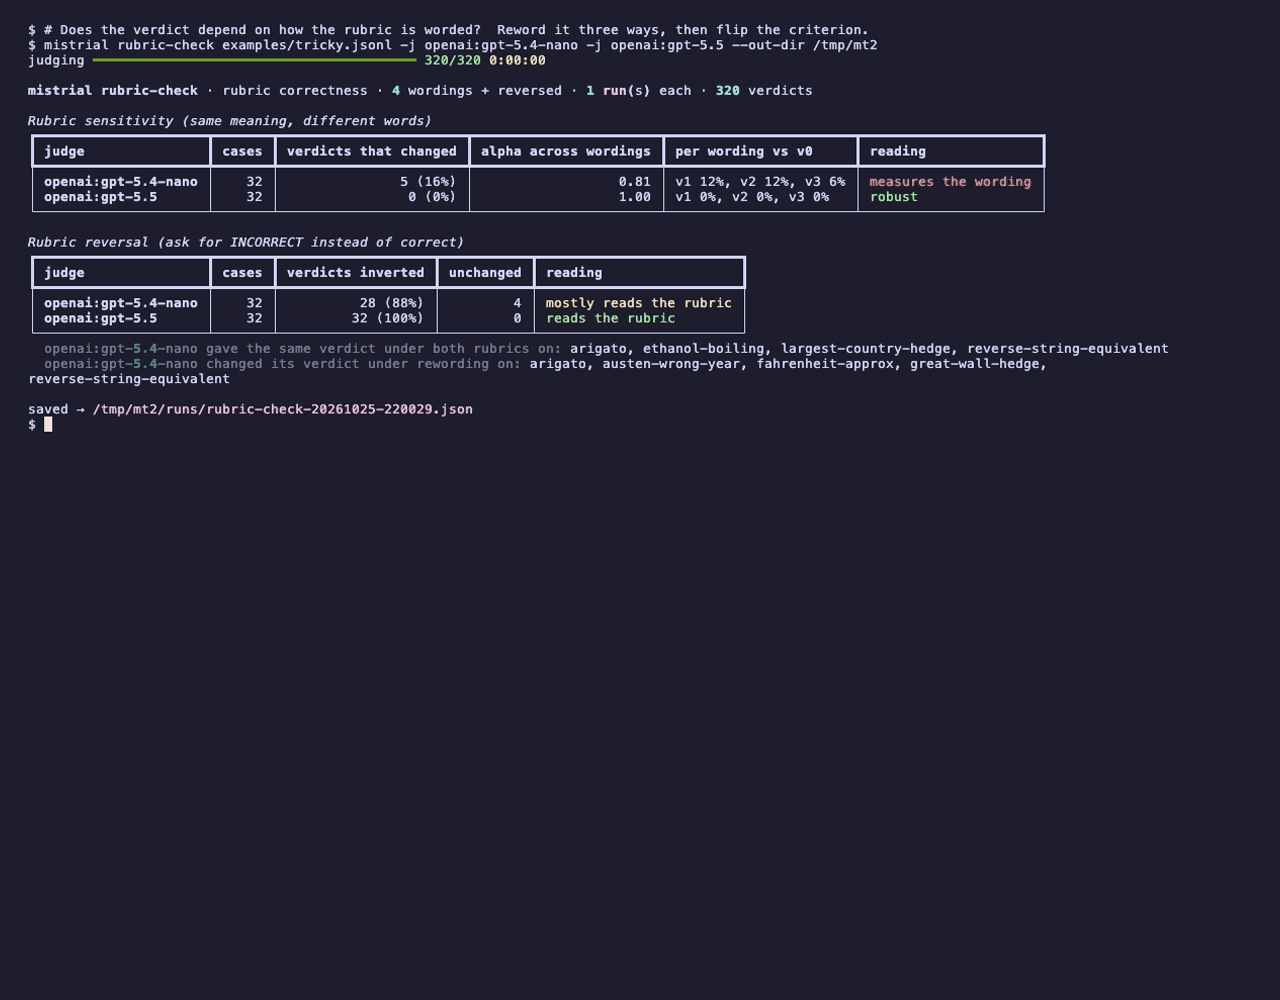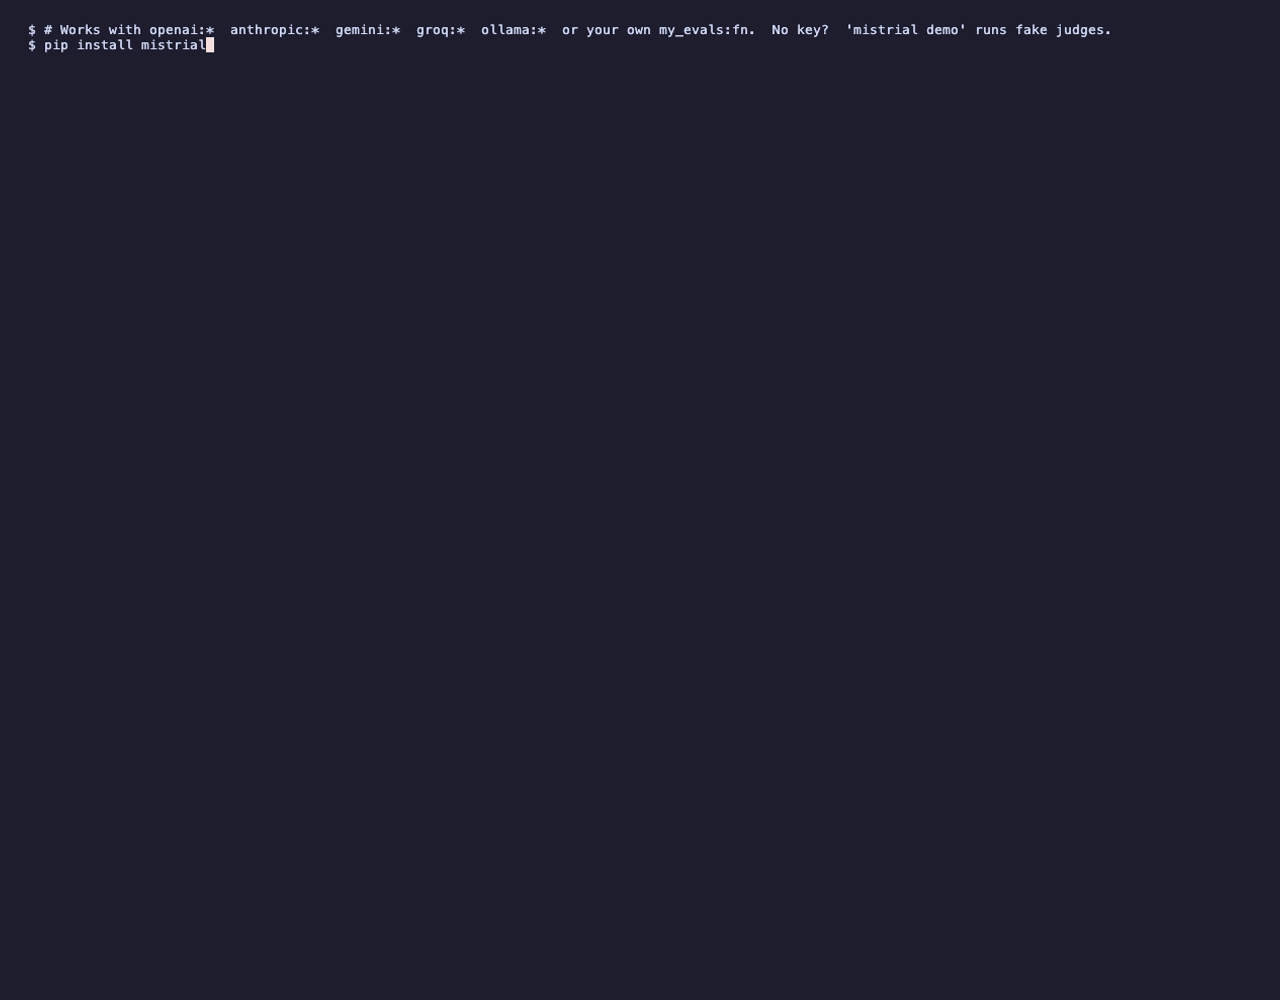
- Rewording the rubric moves 16% of gpt-5.4-nano's verdicts. gpt-5.5 moves none. Asked for "incorrect" instead of "correct", gpt-5.4-nano fails to invert on 4 cases.
- Switching from gpt-5.4-nano to gpt-5.5 changes 6 verdicts, and a 0.5 pass mark on the old judge is about 0.62 on the new one.
- The fix works and you can see by how much. gpt-5.4-nano wrapped in a 5-vote majority goes from 92% to 99% self-agreement, and adaptive re-asking got there with 177 fewer calls than asking five times everywhere.
You get the card in the terminal, a single-file report.html you can send to anyone, JSON for machines, and markdown for a pull request.
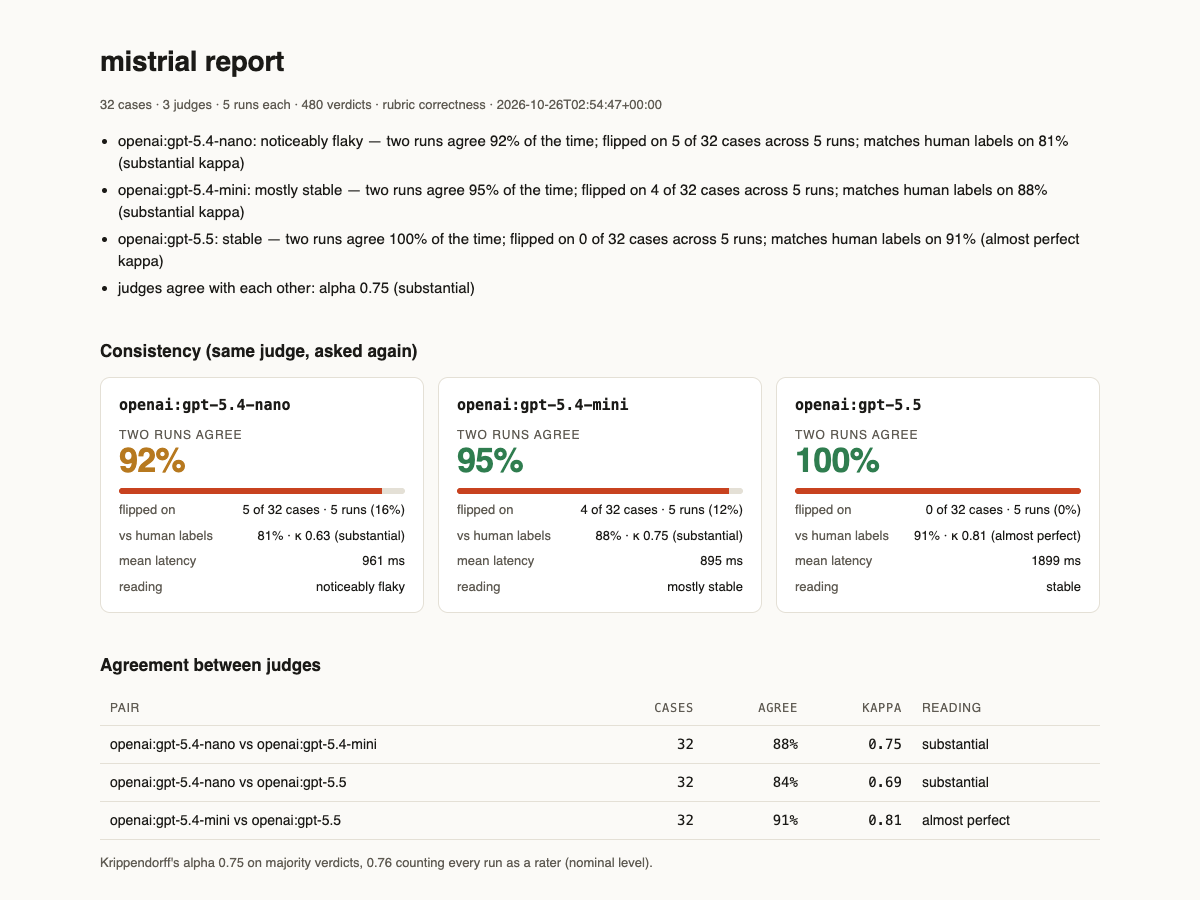
What you get
The card:
- Self-agreement per judge: the chance two runs give the same verdict on a case. Independent of how many runs you did. The headline number.
- Flipped cases: which cases had more than one verdict across runs.
- Agreement between judges: percent agreement and Cohen's kappa for every pair, Krippendorff's alpha across all of them.
- Accuracy vs human labels: accuracy and kappa against your
labelcolumn, plus the misses. - Flakiest cases: every verdict from every judge and run, as chips, ranked by disagreement. This is where you go to fix your rubric.
- Parser audit: how each reply was read (strict JSON, code fence, buried in prose, no verdict), so a parsing problem never gets blamed on the model.
The probes, each one answering a way judges go wrong in production:
- Gate risk: how often your CI gate would go red with nothing changed, and the pass mark or run count that fixes it.
- Rubric sensitivity: reword the rubric three ways with the same meaning and count the verdicts that move.
- Rubric reversal: ask for "incorrect" instead of "correct" and check the verdicts invert.
- Migration: switching judge models? See what moved and what your pass mark becomes on the new judge.
- Sentinel: freeze a baseline on anchor cases and catch a judge that changed under you, on a schedule.
- Drift: compare any two saved runs, case by case.
The fixes:
- Stabilize: wrap the judge in a K-sample majority vote, with the same evaluator signature, and measure it next to the raw one.
- Adaptive re-ask: two runs everywhere, extra runs only where the two disagreed. Same numbers, a fraction of the calls.
- Escalate: a CSV of the cases a human should look at, or push them to a LangSmith dataset.
- CI gate and GitHub Action: fail the build when a judge is flakier than you allow, and post the card on the pull request.
Responses are cached on disk, so re-rendering a report is free and --fresh is explicit.
Usage
Cases file
One case per line. JSONL, JSON or CSV.
{"id": "capital-france", "inputs": "What is the capital of France?", "outputs": "Paris.", "reference_outputs": "Paris", "label": true}
{"id": "seven-times-eight", "inputs": "What is 7 × 8?", "outputs": "54", "reference_outputs": "56", "label": false}
inputs and outputs are required. reference_outputs and the human label are optional but unlock the correctness rubric and the accuracy column. Common aliases work: input, question, answer, expected, ground_truth.
Judges
Three kinds, mixed freely with repeated --judge:
| spec | what it is |
|---|---|
openai:<model> |
OpenAI, needs OPENAI_API_KEY |
anthropic:<model> |
Anthropic, needs ANTHROPIC_API_KEY |
gemini:<model> |
Google Gemini, needs GEMINI_API_KEY |
groq:, mistral:, deepseek:, xai:, together:, openrouter: |
hosted OpenAI-compatible providers, each with its own <PROVIDER>_API_KEY |
ollama:<model> |
a local Ollama model, no key |
custom:<model> |
any OpenAI-compatible server: set MISTRIAL_BASE_URL (vLLM, LM Studio, llama.cpp, a proxy) |
module:function |
any Python function with the LangSmith / openevals signature |
demo, demo:flaky, demo:steady, demo:lenient |
deterministic fake judges, no key |
All LLM judges use the same built-in rubric and ask for a JSON verdict. mistrial providers lists the providers with their env vars and base URLs; <PROVIDER>_BASE_URL overrides a base URL, which is how you point ollama: at another machine or openai: at a proxy.
# GPT vs Claude vs a local model, five runs each
mistrial run cases.jsonl --judge openai:gpt-5.4-mini --judge anthropic:claude-sonnet-5-5 --judge ollama:llama3.2 --runs 5
Your own evaluator
Any function that takes inputs, outputs, reference_outputs and returns a score, a bool, or {"score": ...}:
# my_evals.py
def correctness(inputs, outputs, reference_outputs):
    return {"key": "correctness", "score": outputs.strip() == reference_outputs.strip()}
mistrial run cases.jsonl --judge my_evals:correctness --runs 5
openevals and LangSmith
create_llm_as_judge returns exactly that kind of function, so an openevals judge needs no adapter:
# my_evals.py
from openevals.llm import create_llm_as_judge
from openevals.prompts import CORRECTNESS_PROMPT
judge = create_llm_as_judge(prompt=CORRECTNESS_PROMPT, model="openai:gpt-5.4-mini")
mistrial run cases.jsonl --judge my_evals:judge --judge openai:gpt-5.4-mini --runs 5
Any LangSmith custom evaluator with the same signature works the same way. Export your dataset as JSONL and point at it.
Rubrics
--rubric correctness (boolean, needs reference_outputs) and --rubric quality (1 to 5, no reference). Or --rubric my_prompt.txt with {inputs}, {outputs}, {reference_outputs} placeholders; the model must reply with JSON {"score": ..., "reasoning": ...}. Run mistrial rubrics to list them.
Drift
mistrial run cases.jsonl --judge openai:gpt-5.4-mini --runs 5 --fresh
mistrial compare .mistrial/runs/20261025-101500.json .mistrial/runs/20261101-093000.json
Per judge: the cases whose majority verdict changed, and flip rate and accuracy before and after.
CI gate
mistrial run cases.jsonl --judge openai:gpt-5.4-mini --runs 3 \
  --min-self-agreement 0.95 --max-flip-rate 0.10 --min-agreement 0.6 --quiet
Exit code 1 and a one-line reason on stderr when any gate fails. Use --min-self-agreement as the primary gate; it does not depend on --runs.
Re-render
mistrial report .mistrial/runs/20261025-101500.json --html card.html --markdown card.md
No API calls. Re-renders the card from a saved run, as HTML and as the markdown the GitHub Action posts.
The probes
Everything below works on the demo judges too, so you can try each one before spending a token: swap openai:gpt-5.4-mini for demo:flaky.
Gate risk: will my CI gate go red on its own?
mistrial run examples/tricky.jsonl --judge openai:gpt-5.4-mini --runs 5 --pass-mark 0.5
# or on a saved run
mistrial gate-risk .mistrial/runs/20261025-101500.json --pass-mark 0.5 --runs-in-ci 1 --max-false-alarm 0.05
Gate risk (pass mark 0.5, 1 run per case in CI)
┃ judge               ┃ expected score ┃ 90% range ┃ false alarm ┃ safe mark ┃ fix                               ┃
│ openai:gpt-5.4-nano │           0.38 │ 0.34–0.44 │        100% │      0.34 │ already below the mark on average │
│ openai:gpt-5.4-mini │           0.46 │ 0.41–0.50 │         90% │      0.41 │ already below the mark on average │
│ openai:gpt-5.5      │           0.50 │ 0.50–0.50 │          0% │      0.50 │ fine as is                        │
Each case's observed verdicts are treated as its distribution. The gate score is re-sampled 20,000 times and "false alarm" is how often it lands below your pass mark with nothing changed. The fix column gives the pass mark the judge clears 95% of the time, or the runs-per-case majority vote that gets the alarm rate under 5%. Pure Monte Carlo, so it is right for 10 cases as well as 1,000.
Rubric sensitivity and reversal: is the score measuring the wording?
mistrial rubric-check examples/tricky.jsonl --judge openai:gpt-5.4-nano --judge openai:gpt-5.5 --rubric correctness
Rubric sensitivity (same meaning, different words)
┃ judge               ┃ cases ┃ verdicts that changed ┃ alpha across wordings ┃ per wording vs v0      ┃ reading              ┃
│ openai:gpt-5.4-nano │    32 │               5 (16%) │                  0.81 │ v1 12%, v2 12%, v3 6%  │ measures the wording │
│ openai:gpt-5.5      │    32 │                0 (0%) │                  1.00 │ v1 0%, v2 0%, v3 0%    │ robust               │

Rubric reversal (ask for INCORRECT instead of correct)
┃ judge               ┃ cases ┃ verdicts inverted ┃ unchanged ┃ reading                 ┃
│ openai:gpt-5.4-nano │    32 │          28 (88%) │         4 │ mostly reads the rubric │
│ openai:gpt-5.5      │    32 │         32 (100%) │         0 │ reads the rubric        │
The built-in rubrics ship with three rewordings that mean the same thing and a reversed form. The judge runs under each; changed is the share of cases whose verdict depends on which wording you used, and inverted is the share that flipped when the criterion flipped. Bring your own wordings with --variant my_rubric_v2.txt. Gates: --max-changed 0.10, --min-inversion 0.90. Function judges have no rubric, so they are skipped.
Migrate: my judge model is being retired
mistrial run examples/tricky.jsonl --judge openai:gpt-5.4-nano --judge openai:gpt-5.5 --runs 3
mistrial migrate .mistrial/runs/20261025-101500.json --pass-mark 0.5
agree on 81% of cases · kappa 0.62 (substantial) · shift +0.12
your pass mark 0.5 on openai:gpt-5.4-nano is about 0.62 on openai:gpt-5.5
6 cases get a different verdict:
  arigato: F → T
  moon-miles: F → T
  percent-unit: T → F
  …
Both judges on the same cases, the shift in aggregate score, your pass mark translated so the pass rate stays the same, and the cases that get a different verdict. For 1-to-5 rubrics, --threshold 4 maps a per-case cutoff by quantile. The translated mark keeps your pass rate. It does not make the judges agree, so read the changed cases.
Sentinel: did the judge change under me?
# once: freeze a baseline on a small labeled anchor set that never changes
mistrial run anchors.jsonl --judge openai:gpt-5.4-mini --runs 3
mistrial sentinel baseline .mistrial/runs/20261025-101500.json

# on a schedule (nightly cron, CI): re-judge fresh and compare
mistrial sentinel check anchors.jsonl --judge openai:gpt-5.4-mini
Exit 0 STABLE, exit 2 JUDGE_DRIFT (more than --max-changed of anchor verdicts changed, or kappa vs human fell by more than --max-kappa-drop), exit 3 if the anchors themselves changed. The anchors never change, so any movement is the judge, which is how you catch a vendor's quiet model update before it blocks a release. Design credit: judge-drift-sentinel.
Stabilize: the fix, as a judge
mistrial run cases.jsonl --judge openai:gpt-5.4-mini --runs 5 --stabilize 5
Adds openai:gpt-5.4-mini×5 next to the raw judge: the same judge asked five times with a majority vote (median for scores). The card shows both, so you see what K buys you before you pay for it. In code:
from mistrial import stabilize

judge = stabilize("openai:gpt-5.4-mini", k=5)               # or stabilize(my_evaluator_fn, k=5)
judge(inputs="2+2?", outputs="4", reference_outputs="4")
# {"key": "openai:gpt-5.4-mini×5", "score": True, "comment": "...", "mistrial": {"votes": [...], "agreement": 1.0, "k": 5}}
Same signature as a LangSmith or openevals evaluator, so it drops in where the flaky one was.
Adaptive re-ask: the same numbers for a third of the calls
mistrial run cases.jsonl --judge openai:gpt-5.4-mini --runs 7 --adaptive
Every case gets two runs. Only cases where the two disagreed (or a call failed) get the remaining five. Self-agreement is estimated from pairs within each case, so settled cases lose nothing. The card reports the calls skipped.
Escalate: what should a human look at?
mistrial escalate .mistrial/runs/20261025-101500.json --out needs-human.csv
mistrial escalate .mistrial/runs/20261025-101500.json --langsmith-dataset needs-human   # pip install langsmith
One row per case where judges disagreed, flipped, or missed the human label, with every verdict, the case itself, and an empty your_verdict column for the reviewer. The LangSmith option creates or extends a dataset with the same rows so your team can annotate them there.
GitHub Action: the card on every pull request
# .github/workflows/mistrial.yml
on: [pull_request]
jobs:
  judge:
    runs-on: ubuntu-latest
    permissions: { contents: read, pull-requests: write }
    steps:
      - uses: actions/checkout@v4
      - uses: actions/setup-python@v5
        with: { python-version: "3.12" }
      - uses: hemanth1999k/mistrial@v0.2.1
        with:
          cases: evals/cases.jsonl
          judges: "openai:gpt-5.4-mini my_evals:correctness"
          runs: "3"
          adaptive: "true"
          min-self-agreement: "0.95"
          pass-mark: "0.8"
        env:
          OPENAI_API_KEY: ${{ secrets.OPENAI_API_KEY }}
Posts the card as a comment on the PR (updated in place on later pushes), writes it to the job summary, uploads the HTML report as an artifact, and fails the job when a gate fails. Outside GitHub, mistrial run … --markdown card.md writes the same comment for whatever posts it.
How the numbers are computed
Everything lives in src/mistrial/stats.py, is pure Python, and is tested against the textbook examples (Krippendorff's own data for alpha, the standard two-rater example for kappa). Nothing is a "grade".
| metric | formula | notes |
|---|---|---|
| self-agreement | mean over cases of the share of run pairs that agree | run-count independent; the headline |
| flip rate | cases with more than one distinct verdict ÷ cases | grows with --runs, compare at equal run counts |
| percent agreement | cases where both judges' majority verdicts match ÷ cases | raw, uncorrected |
| Cohen's kappa | (p_o − p_e) ÷ (1 − p_e) | chance-corrected, two raters |
| Krippendorff's alpha | 1 − D_o ÷ D_e from the coincidence matrix | nominal for labels, interval for scores, missing allowed, any number of raters |
| accuracy | judge majority verdict == human label ÷ labeled cases | plus kappa vs the label |
| disagreement (per case) | 1 − share of the overall majority across every judge and run | ranks the flakiest cases |
| gate false alarm | share of 20,000 re-samples of the aggregate score that fall below the pass mark | each case re-sampled from its observed verdicts; majority of --runs-in-ci |
| rubric sensitivity | cases whose majority verdict differs across wordings ÷ cases | plus alpha with wordings as raters |
| inversion rate | cases where the reversed rubric gave the opposite verdict ÷ cases | boolean rubrics |
| migration shift | mean score under the new judge − mean under the old | pass mark moves by the shift; per-case cutoffs map by quantile |
Readings use the Landis and Koch bands for kappa and alpha: slight, fair, moderate, substantial, almost perfect. They are labels for humans, not thresholds for machines. Set your own gates.
Known limits: kappa on a handful of cases is not evidence, and a judge that is perfectly consistent can be consistently wrong. The card shows both numbers so neither hides the other.
How is this different
Other people have looked at this problem, and some of their tools go deeper than Mistrial on statistics. judgecheck is the one to use when you need confidence intervals and bias probes for a paper or audit. judgebench owns position bias. Assay is a full regression framework. Mistrial is the one to run against the evaluator you already have, in a minute, and put in CI.
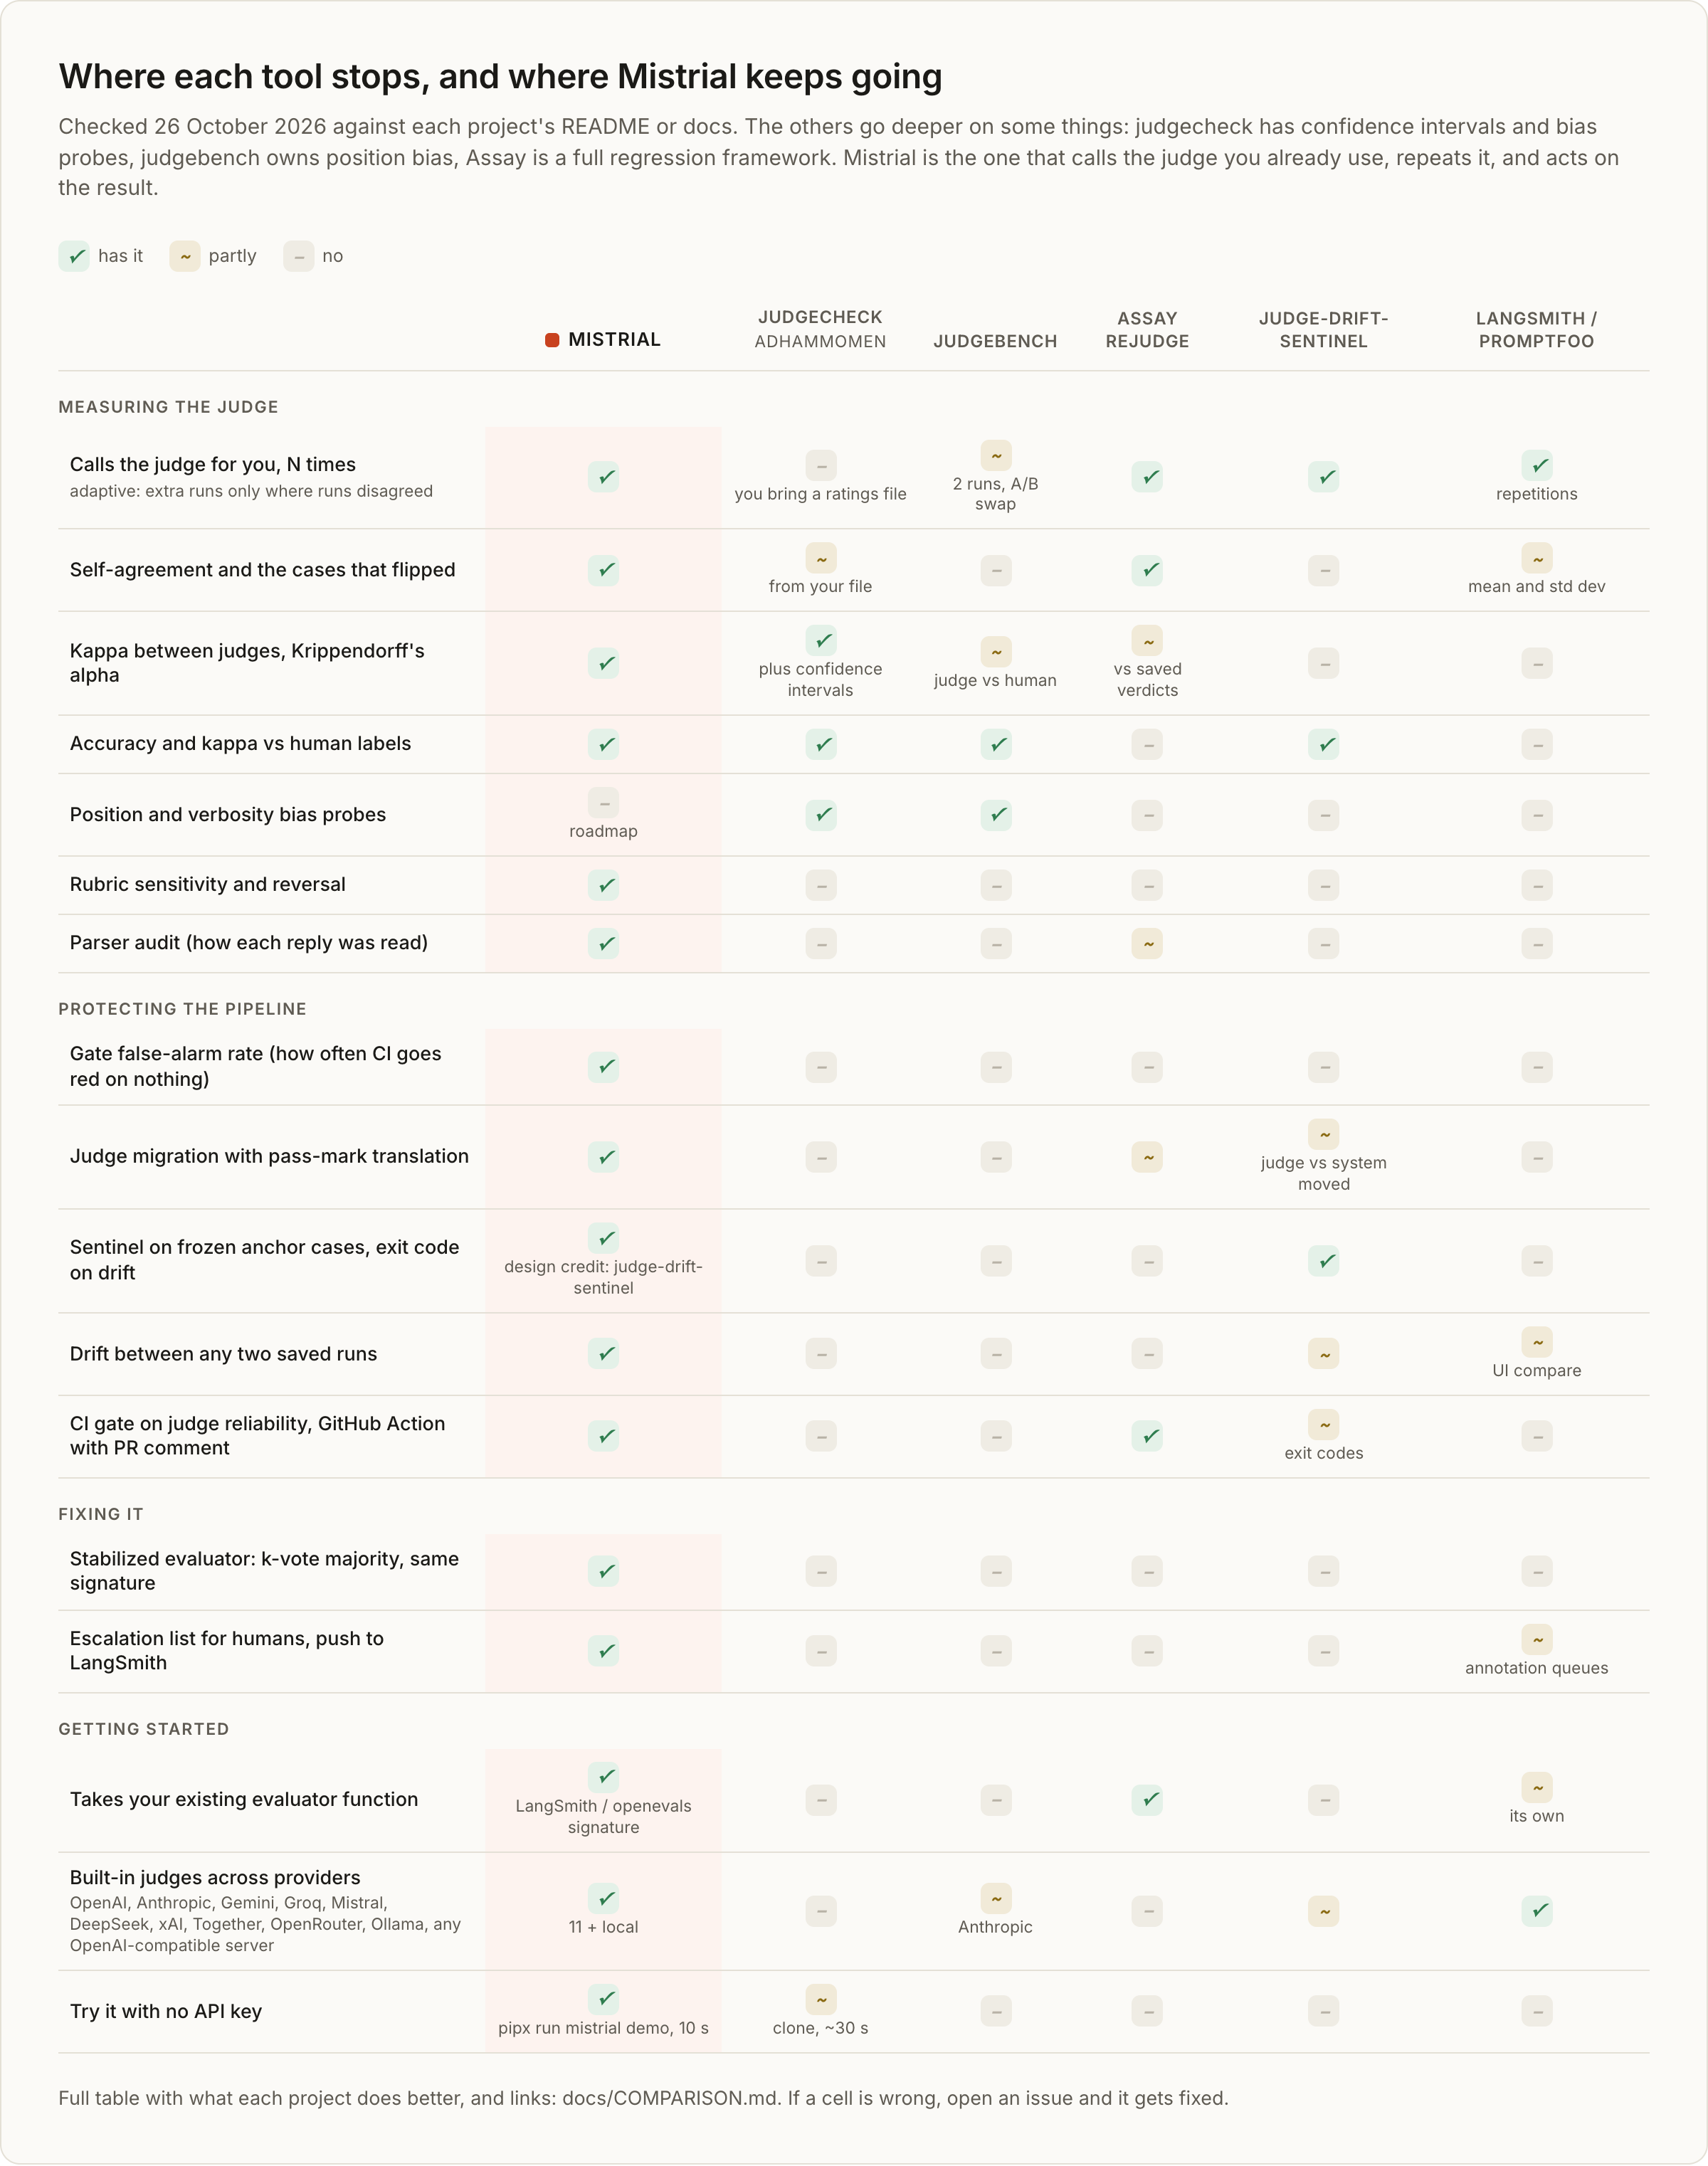
The full table, with links and what each of them does better, is in docs/COMPARISON.md. If a cell is wrong, open an issue and it gets fixed.
Standing on shoulders
Mistrial puts century-old reliability statistics in front of a new kind of rater. None of the ideas are new; the packaging is. People and projects worth following if you work on this:
Papers to read
- Judging LLM-as-a-Judge with MT-Bench and Chatbot Arena, Zheng et al., 2023. The paper that named the practice and first measured judge agreement with humans, and the position, verbosity and self-enhancement biases that come with it.
- Large Language Models are not Fair Evaluators, Wang et al., 2023. Swap the order of two answers and the verdict changes. Position bias is on Mistrial's roadmap because of this paper.
- Large Language Models are Inconsistent and Biased Evaluators, Stureborg et al., 2024. Run-to-run inconsistency of the same judge, measured. This is the problem the card's self-agreement column reports.
- Rating Roulette: Self-Consistency and Variance of LLM-as-a-Judge, EMNLP 2025 Findings. The same judge gives different scores to the same answer across runs; the paper that made "ask again" a method.
- Reliability without Validity, 2026. Raw percent agreement overstates judge reliability by 30 to 40 points against chance-corrected kappa, across 21 judges. Why the card reports kappa and alpha, not just agreement.
- Replacing Judges with Juries, Verga et al. (Cohere), 2024. A panel of smaller, diverse judges beats one large judge and costs less. The jury mode planned for v0.3 starts here.
- Who Validates the Validators?, Shankar et al., 2024. EvalGen: humans and LLM evaluators drift apart unless the rubric is aligned with human judgment case by case. The reason
escalateexists. - G-Eval, Liu et al., 2023, and Prometheus 2, Kim et al., 2024. Two ways to make a judge: prompt a frontier model with a rubric, or train an open model to be one. Mistrial measures either.
- Judging the Judges, Thakur et al., 2024, and Justice or Prejudice?, Ye et al., 2024. Systematic audits of judge alignment and of twelve bias types. Good checklists for probes Mistrial does not have yet.
- Agent-as-a-Judge, Zhuge et al., 2024. Judging multi-step agent trajectories, where reliability is worst and least measured.
- A Survey on LLM-as-a-Judge, Gu et al., 2024. The map of the field.
- Classics: Cohen's kappa (1960), Krippendorff's alpha, and the Landis and Koch bands the card uses as readings. Every field with human raters has used these for decades.
Repos to check out
- judgecheck: the serious statistics package for judge ratings, with confidence intervals, five bias probes and calibration. Bring your ratings file.
- judgebench: position-bias testing by running every pair in both orders.
- judge-drift-sentinel: a frozen human-labeled anchor set and a baseline, so you can tell whether the judge or your system moved. Mistrial's
sentinelborrows this design, with credit. - judgekeeper: get human labels in the first place, in a browser, then measure the judge against them.
- Assay: behavioral regression testing for AI apps with a pytest plugin, PR comments, and a
rejudgecommand. - verdict (Haize Labs): a framework for building compound judges with repeat-and-vote, debate and verification. Builds the judge that Mistrial then measures.
- llm-council (Andrej Karpathy): several models answer, review each other anonymously, and a chairman synthesizes. The council idea applied to answering; Mistrial's planned jury mode applies it to judging.
- openevals and LangSmith: ready-made evaluators and the evaluator signature Mistrial speaks. Point
--judge module:functionat any of them. - autoevals (Braintrust), DeepEval, Ragas, promptfoo, Phoenix: the eval frameworks most judges live in. Wrap their scorers as a function and Mistrial will re-run them.
- Inspect (UK AI Security Institute), lm-evaluation-harness, AlpacaEval, FastChat (MT-Bench): the benchmark harnesses where model-graded evaluation grew up.
If your project belongs here and is missing, open a PR with one line.
Roadmap
- Position-bias swap test and transitivity check for pairwise judges
- Confidence intervals on kappa and alpha
- Cost per run per provider
- Pull a LangSmith dataset directly instead of exporting JSONL
mistrial serveto browse reports on localhost
Open an issue if you want one of these first. See CHANGELOG.md for what has shipped.
Contributing
Bug reports, rubric ideas, and adapters for other providers are welcome. See CONTRIBUTING.md. The rule for new metrics: it needs a published formula, a test against a known example, and a sentence in this README saying what it does and does not mean.
License
MIT.
1 maintainer

Metadata
1 maintainer
Release files for mistrial 0.2.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| mistrial-0.2.1.tar.gz | 78.7 kB | Without provenance | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| mistrial-0.2.1-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 138.0 kB
Release files / mistrial-0.2.1.tar.gz
| Download URL | mistrial-0.2.1.tar.gz |
|---|---|
| Size | 78.7 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
77bd19410fbaab60df7725c8a6f22558f14fe01c8eaae8684ce0e224512b49d5
|
|
BLAKE2b-256 checksum How to use checksums |
ff61b9fe9ecf13a9ade5d8858ce3458d29214c549030146a0db0eca2475a1c29
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.13.13
|
Release files / mistrial-0.2.1-py3-none-any.whl
| Download URL | mistrial-0.2.1-py3-none-any.whl |
|---|---|
| Size | 59.3 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
d484db203fac46146d1520003ebd381f852d00e0c9ea8aeb2c642e3c104ae900
|
|
BLAKE2b-256 checksum How to use checksums |
e2238d3e4fb27f9428443abf4f7bd53dd7558244d75eaf232f21807bf0c6a17f
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.13.13
|
Security for mistrial 0.2.1
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.













