
MLPal Gateway
One API for every model provider.
Anthropic, OpenAI, Google, and AWS Bedrock ship built in; new providers are an adapter away.
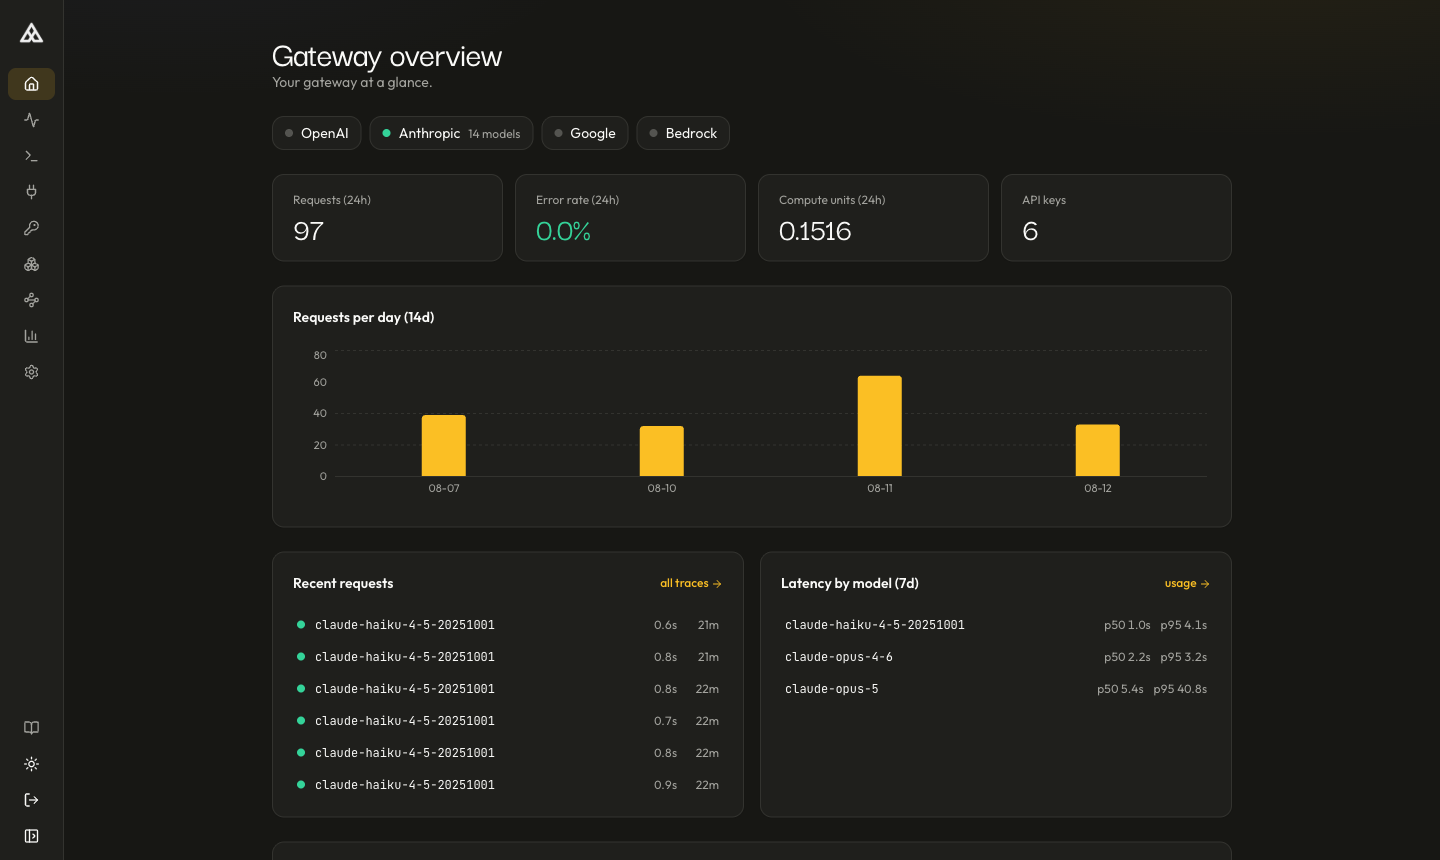
Self-hosted. Model routing, per-request cost metering, per-key access control, admin console.


Quick start
cp .env.oss.example .env      # add whichever provider keys you have
docker compose up             # Postgres + Redis + gateway + admin console
| Gateway | http://localhost:8000 — Swagger at /docs |
| Admin console | http://localhost:8080 |
| Bootstrap admin key | printed once: docker compose logs seed |
Adapters activate based on which provider keys you set. GET /v1/models lists
only what your box can serve; a single-provider deployment works without any
extra configuration.
Don't want to run infrastructure? The managed deployment of this same codebase
runs at mlpal.ai — create a key and point the same
SDK/CLI at https://models.mlpal.ai instead of localhost. Pricing is simple:
routing is free for your first 300M tokens each month, then $50 flat per
month up to 5B tokens; your tokens are always billed at provider list price,
passed through with no markup, either way.
Prebuilt multi-arch images are on GHCR if you'd rather not build from source:
ghcr.io/mlpal-ai/mlpal-gateway and ghcr.io/mlpal-ai/mlpal-gateway-console
(tags: latest, version, commit SHA).
Calling it
Anthropic wire, any provider's model:
curl http://localhost:8000/v1/messages \
  -H "Authorization: Bearer $MLPAL_KEY" -H "content-type: application/json" \
  -d '{"model":"mlpal","max_tokens":512,"messages":[{"role":"user","content":"hi"}]}'
Existing OpenAI SDK code — point it at http://localhost:8000/v1. Python SDK —
pip install mlpal-assistants:
from mlpal_assistants import MLPal

client = MLPal(base_url="http://localhost:8000")   # key from MLPAL_API_KEY
msg = client.messages.create(
    model="mlpal", max_tokens=512,
    messages=[{"role": "user", "content": "Hello"}],
)
print(msg.text, msg.compute_units)
What you get
- One wire format for every provider.
POST /v1/messagesspeaks the Anthropic Messages format for all served models; the gateway translates to each provider's native API and relays the SSE stream without re-chunking. OpenAI-compatible endpoints (/v1/chat/completions, embeddings, images, audio) serve existing OpenAI SDK code unchanged. - Router tags.
"model": "mlpal"resolves to the best model your deployment serves, walking a curated candidate list that spans providers. Model retired? Provider key missing? Resolution falls through to the next candidate. Client code never changes. - Cost on every response. Requests are metered in compute units
(1 CU = $10 of provider list price, no markup) and returned in an
X-MLPal-Compute-Unitsheader. The meter reproduces provider list pricing exactly, including prompt-cache discounts. - Per-key control. Model-policy globs (
allow: ["claude-*"]), multi-window spend budgets, permissions — all enforced at admission, before the provider call. A running stream is never cut. - Observability. Per-key cache hit rate, latency p50/p95, time-to-first-token, request traces, and optional payload capture (zlib-compressed, runtime toggle — your box, your data).
- Provider semantics preserved. Prompt caching (
cache_control), tools, structured output, and MCP config pass through untouched. - Catalog that keeps itself current (opt-in, free). By default your box
ships with the bundled model catalog, frozen at this version — fully
functional offline, zero calls home. Subscribe to the hosted feed (Models
page, or
MLPAL_CATALOG_FEED=hosted) and the gateway pulls the curated catalog daily — new models appear and retired ones are absorbed with no upgrade. Subscribing requires a free mlpal.ai account key purely as identity — we recommend a dedicated key with no permissions (it can authenticate the feed and nothing else; feed pulls are never billed). See Telemetry.
Measured
Gateway overhead isolated against a zero-latency fake upstream, so provider
variance can't hide anything — MLPal with its full admission pipeline
(auth, rate limit, billing, model policy, budgets, metering, capture) against
LiteLLM in both its bare mode and a production configuration with
database-backed virtual keys, budgets, and spend tracking (N=100 per system;
methodology in the technical report,
raw data and harness in paper/bench/):
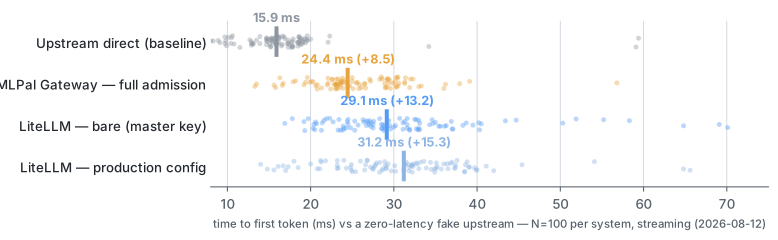
+8.5 ms with everything on — less than a bare proxy checks one static key for, and with the tightest tail (p95 33 ms vs 58/41 ms). Admission-time governance is computationally free. Provider semantics survive the hop too: a 22k-token cached prefix passes through byte-faithfully and metered 0.002756 CU on write, 0.000224 CU on read (12.3×) — matching Anthropic's list price to five decimals. The managed deployment of this same codebase, measured the same night from the same client, served claude-haiku-4.5 at 642 ms median TTFT vs OpenRouter's 898 ms (report §5.3–5.4).
Why a curated catalog
Production models retire on roughly a 12-month cycle now — from the providers' own deprecation ledgers:
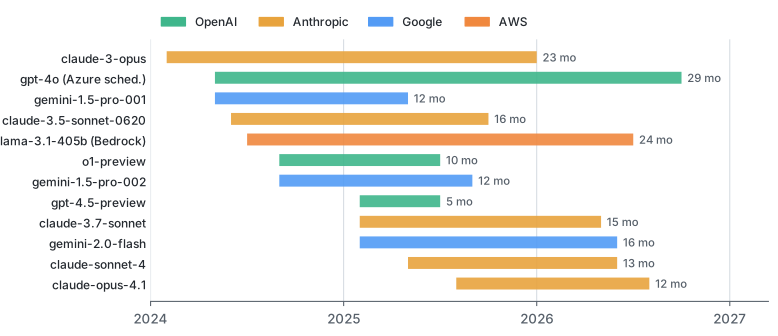
Serving a model well — valid parameter ranges, per-model cache minimums, reasoning budgets, provider quirks — is per-model engineering that does not scale to a 1,600-entry catalog. This gateway serves a curated set (~75 models) kept current by a data feed, and router tags absorb every retirement above server-side. You can always pin any explicit model tag or register your own adapter.
The full argument with benchmarks and sources: Curation Over Breadth · feature matrix vs. OpenRouter / LiteLLM / Portkey: docs/POSITIONING.md.
Router tags vs. catalog
Two ways to use the curated set — they differ in who picks the model:
Router tags — mlpal, mlpal-flash, mlpal-lite |
Catalog — GET /v1/catalog |
|
|---|---|---|
| Who decides | The gateway: tag resolves to the best served model for the operation | Your client: a ranked list with tiers, capabilities, per-token rates |
| Use when | You want a good default and zero model-name maintenance | You are writing routing logic (agents route sub-tasks this way) |
| One-provider box | Falls through to whatever your key serves | Unserved candidates are marked |
Both are driven by the same feed (catalog/*.json) and update as data, not
code.
API surface
| Endpoint | Purpose |
|---|---|
POST /v1/messages |
Anthropic-wire inference, all providers, streaming SSE |
POST /v1/chat/completions |
OpenAI-compatible chat |
/v1/embeddings · /v1/images/generations · /v1/audio/* |
OpenAI-compatible modalities |
GET /v1/models |
Models this deployment serves |
GET /v1/catalog |
Ranked catalog: tiers, capabilities, rates |
POST /v1/feedback |
Outcome feedback for routing scores |
GET /v1/usage/* · /v1/keys/* |
Self-scoped usage, traces, per-key stats |
/admin/v1/* |
Keys, policies, budgets, capture, routing |
Details: docs/API_SURFACE.md.
Use it with a coding agent
Yodex is a coding CLI built on this
gateway — it speaks the Anthropic wire and uses GET /v1/catalog to route
sub-tasks to cheaper models (~10× lower sub-agent cost in its
benchmarks):
npm install -g @mlpal/yodex
export YODEX_GATEWAY_URL=http://localhost:8000
export YODEX_API_KEY=mlpal_sk_...    # minted in the console
yodex "fix the failing test"
Repository layout
src/                 # FastAPI gateway: adapters, services, api, seams
console/             # admin UI (React + Vite): keys, traces, catalog, usage
docker-compose.yaml  # one-command local deployment
alembic/             # database migrations
paper/               # technical report + benchmark harness + raw results
enterprise/          # commercial add-ons (separate license, NOT Apache)
docs/                # API surface, positioning, figures
Auth and billing sit behind composition-root seams (api/mounting.py); the
defaults (MLPAL_AUTH_BACKEND=local, MLPAL_BILLING_BACKEND=local) run fully
standalone with no external dependencies. src/ never imports from
enterprise/.
Telemetry
None by default. If you opt in to the hosted catalog feed, each daily pull
sends exactly three things to models.mlpal.ai: the mlpal.ai API key you
subscribed with (identity — links the install to your account), a random
per-install UUID, and your gateway version. Feed pulls are free and never
metered. No provider keys, no payloads, no usage data, ever. Stay in
bundled mode (the default) and the gateway makes zero calls home.
License and contact
Apache-2.0, except the enterprise/ directory (commercial — see
enterprise/LICENSE). Contributions welcome:
CONTRIBUTING.md · security and everything else:
contact@mlpal.ai
1 maintainer

Metadata
1 maintainer
Release files for mlpal-gateway 0.2.4
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| mlpal_gateway-0.2.4.tar.gz | 1.3 MB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| mlpal_gateway-0.2.4-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 1.6 MB
Release files / mlpal_gateway-0.2.4.tar.gz
| Download URL | mlpal_gateway-0.2.4.tar.gz |
|---|---|
| Size | 1.3 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
3ebb3e36393a4c8fe0dfced6007d348b3b514665f8a8f8bb424f92ee86402d98
|
|
BLAKE2b-256 checksum How to use checksums |
cfefde96678c05064f082f4e624c2f9992ce23e22c2362b00c5fecb1c6fbabda
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
uv/0.8.9
|
Release files / mlpal_gateway-0.2.4-py3-none-any.whl
| Download URL | mlpal_gateway-0.2.4-py3-none-any.whl |
|---|---|
| Size | 325.1 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
b5a45bd2d420a136c692aa1a25f1b5dbc25137fdab66a65f5439b3109ded5dd7
|
|
BLAKE2b-256 checksum How to use checksums |
9d0aee6cd73ec3150098377609bb4f8e8f481f6fef7264e4219a9fc2b2ed8c3c
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
uv/0.8.9
|














