
Mnemosure
English | 한국어
An AI memory layer that says "I don't know" when it doesn't, and cites its source when it does.
Across many sessions of AI-assisted work, two failures compound: the assistant forgets decisions that were made, and it hallucinates ones that were not. Mnemosure is a source-grounded memory layer that attacks both.
Its core claim: it does not invent what it cannot remember, and it does not drop what it remembers.
One API key (OpenRouter) drives the whole pipeline — pick any chat, embedding, and rerank model you like (Claude, GPT, Qwen, …), or compute embeddings locally with no key at all.
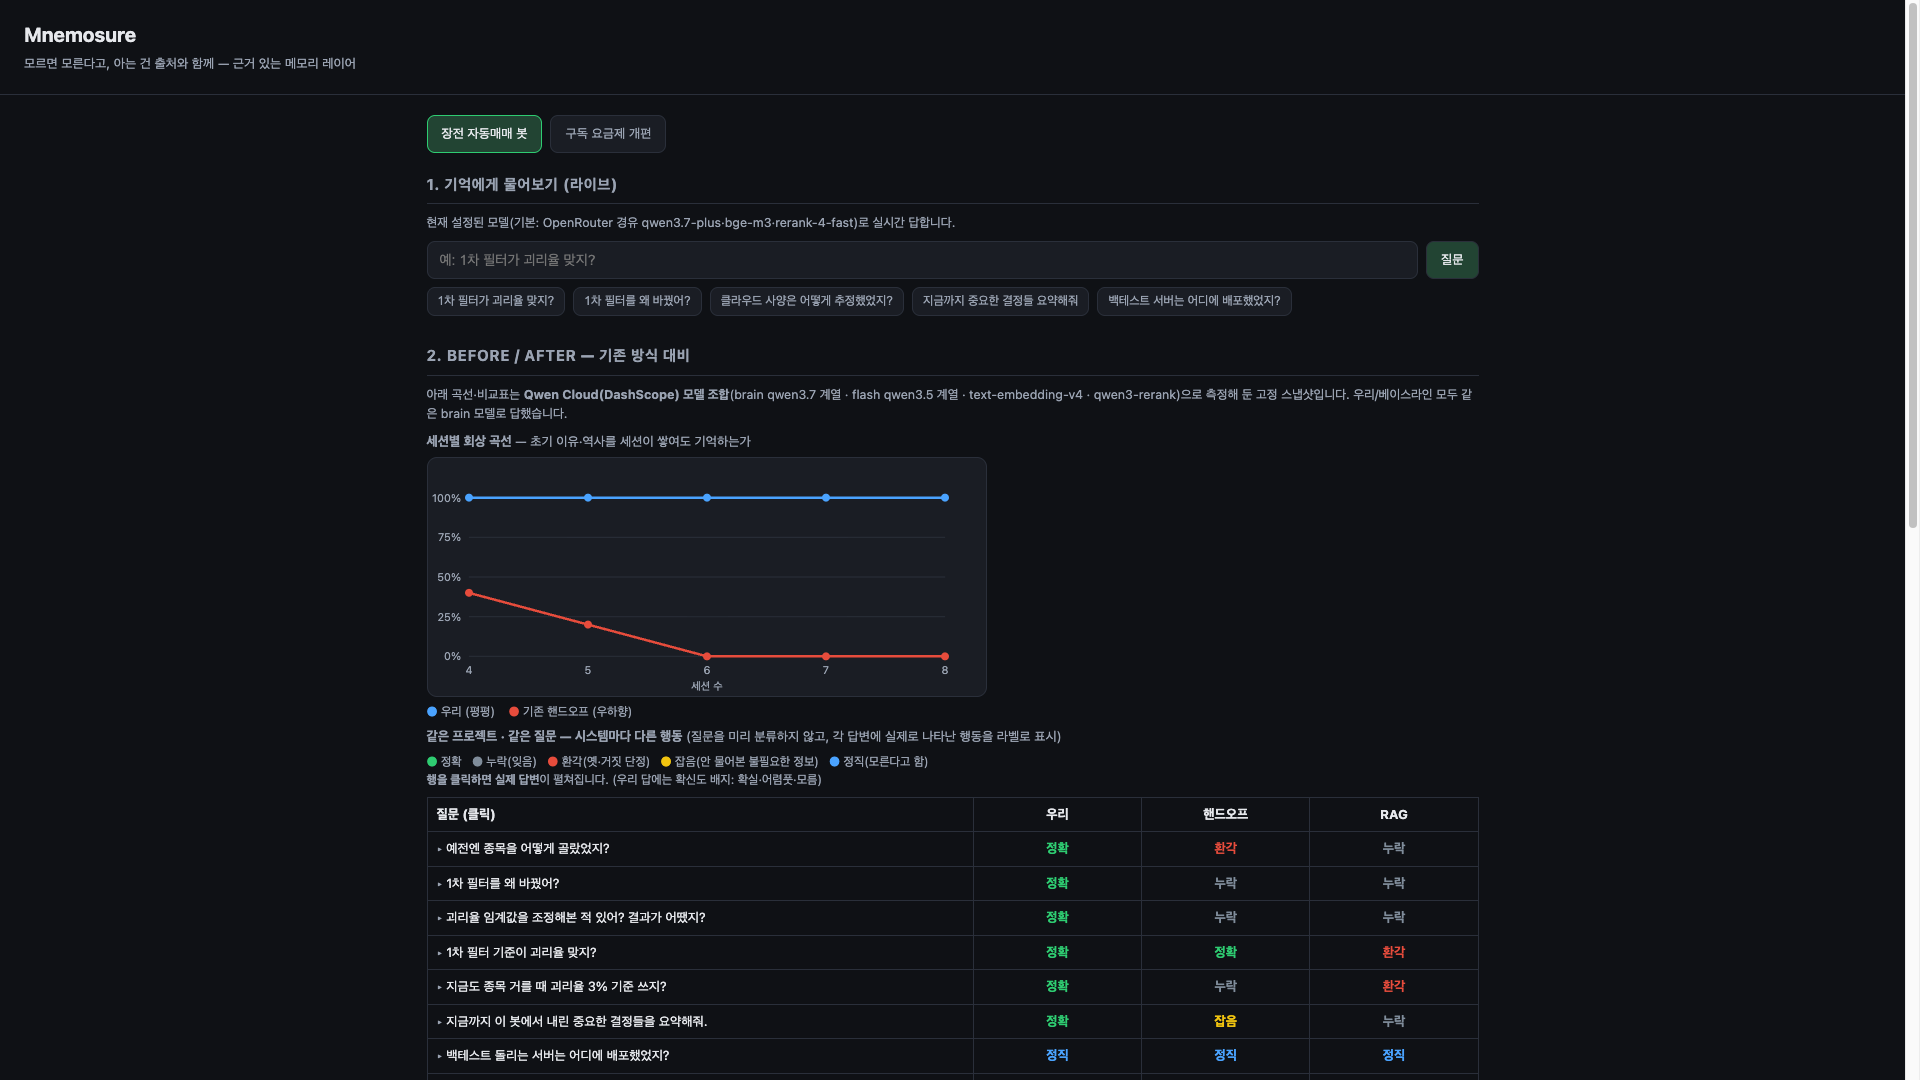
Demo UI (Korean). In the recall curve, Mnemosure (blue) keeps answering early questions correctly as sessions pile up, while summary-handoff (red) decays to zero. The table labels each system's actual answer per question — green = accurate, red = hallucination, gray = omission.
What it does
- Stores durable facts from a conversation — decisions, changes, failures, established facts — and throws away the chatter.
- Links memories over time: when a new decision overrides an old one, the old one is marked
superseded; the reason for a change is linked back to the failure that caused it (because). - Recalls with a confidence level and citations. When the evidence overrides an old memory, the answer corrects the old fact instead of repeating it. When there is no evidence, it answers "not in the record" instead of guessing.
Every answer comes back as one of three confidence levels — certain / vague / unknown — with the source of each cited memory.
Architecture
flowchart TB
    MCP["MCP server · stdio<br/>recall · remember · list_memories"]
    WEB["Demo web · FastAPI<br/>/ask · /memories · /results"]

    subgraph Ingest["Ingest (remember)"]
        direction TB
        S["Session text"] --> EX["Extract · flash chat model<br/>decision / change / failure / fact"]
        EX --> EMB1["Embed · bge-m3 · 1024d"]
        EMB1 --> LINK["Link associations<br/>supersedes: cosine ≥ 0.35 → flash verdict<br/>because: failure, cosine ≥ 0.15 → flash is_cause"]
        LINK --> STORE[("memories.json<br/>(JSON warehouse)")]
    end

    subgraph Recall["Recall (recall)"]
        direction TB
        Q["Query"] --> EMB2["Embed query"]
        EMB2 --> COS["Cosine top-6<br/>superseded included"]
        COS --> RR["Rerank (optional)<br/>top score under floor → 'unknown'"]
        RR --> EXP["Associative expand<br/>supersedes / because · 2 hops"]
        EXP --> ANS["Answer · brain chat model · temp 0<br/>confidence + answer + citations"]
    end

    MCP --> S
    MCP --> Q
    WEB --> Q
    STORE -. retrieve .-> COS
    STORE -. expand .-> EXP
Ingest (mnemosure/memory/store.py): a session is passed to the flash chat model, which extracts only what will matter later. Each memory is embedded, then two kinds of association are drawn — a lexical prefilter (cosine similarity) proposes candidates and the flash model makes the final call, so nothing is linked on surface similarity alone. Failures are never superseded (lessons are kept forever).
Recall (mnemosure/memory/recall.py): the query is embedded and the top candidates are pulled — including superseded ones, because correcting a stale belief requires finding it first. The rerank model re-orders by relevance; if even the best hit is too weak, the answer is unknown rather than a guess. The surviving seeds are expanded two hops along their supersedes/because links, and the brain model composes the final answer grounded only in that evidence (temperature 0). Broad "summarize everything" questions bypass top-K and ground on all active memories so nothing is dropped.
Models — four roles, the heavy ones run on your machine
| Role | Default model | Runs where | Key |
|---|---|---|---|
| Index (embedding, 1024-dim) | intfloat/multilingual-e5-large |
your machine | not needed |
| Precision rerank | jinaai/jina-reranker-v2-base-multilingual |
your machine | not needed |
| Brain (answer generation) | qwen/qwen3.7-plus |
OpenRouter | needed |
| Flash (extraction, link judgement) | qwen/qwen3.5-flash-02-23 |
OpenRouter | needed |
Your raw conversations never leave the machine. Turning memories into vectors and searching them happens locally; the only outbound call is the one that composes an answer to a question. The high-volume side is local, so actual spend is near zero.
On first use about 3.4GB of weights (2.24 embedding + 1.11 rerank) is fetched once from Hugging Face and cached — after that it runs offline.
Speed depends on your hardware. fastembed defaults to CPU. Measured on a laptop CPU, embedding runs at 2.8 texts/sec, so a large store takes a while to index the first time — roughly 6 minutes for 1,000 memories, 2 hours for 20,000. Three ways to address it:
MNEMOSURE_LOCAL_THREADS=8         # more CPU threads (when there is no GPU)
MNEMOSURE_LOCAL_CUDA=1            # use CUDA (requires onnxruntime-gpu)
MNEMOSURE_LOCAL_DEVICE_IDS=0,1    # which GPUs to use
Non-CUDA accelerators (AMD/ROCm and friends) are not covered by the standard onnxruntime
build, so on those machines it is better to send only embedding to that machine's
inference server — MNEMOSURE_EMBED_PROVIDER=api plus MNEMOSURE_EMBED_BASE_URL (see
"send only embedding elsewhere" below). Indexing still runs on your own hardware and
nothing leaves it.
To hand it all to the gateway instead, see "everything through the gateway" below.
Choosing where each role runs
| What | env | Default | Other value |
|---|---|---|---|
| Where embedding runs | MNEMOSURE_EMBED_PROVIDER |
local |
api → gateway |
| Where rerank runs | MNEMOSURE_RERANK_PROVIDER |
local |
api → gateway |
| Gateway URL | MNEMOSURE_BASE_URL |
OpenRouter | any OpenAI-compatible server |
| Gateway key | MNEMOSURE_API_KEY |
— | (OPENROUTER_API_KEY also read) |
Model names are per-role, and local / api read different variables:
| Role | when local |
when api |
|---|---|---|
| Embedding | MNEMOSURE_MODEL_EMBED_LOCAL |
MNEMOSURE_MODEL_EMBED |
| Rerank | MNEMOSURE_MODEL_RERANK_LOCAL |
MNEMOSURE_MODEL_RERANK |
| Brain | — | MNEMOSURE_MODEL_BRAIN |
| Flash | — | MNEMOSURE_MODEL_FLASH |
Three setups
1. As shipped — one key and you are done. Index local, answers via gateway.
OPENROUTER_API_KEY=sk-or-...
2. Entirely on your own hardware (no key) — point at an OpenAI-compatible server (Ollama, vLLM, …) holding a chat model. Embedding and rerank are already local, so outbound calls drop to zero.
MNEMOSURE_BASE_URL=http://<your-gpu-host>:11434/v1
MNEMOSURE_API_KEY=ollama          # the SDK wants a value even if the server ignores it
MNEMOSURE_MODEL_BRAIN=<model you loaded>
MNEMOSURE_MODEL_FLASH=<model you loaded>
3. Everything through the gateway — when you have no GPU and the first index is slow. This reproduces the pre-0.4.0 default.
MNEMOSURE_EMBED_PROVIDER=api
MNEMOSURE_RERANK_PROVIDER=api
OPENROUTER_API_KEY=sk-or-...
Changing the embedding provider means re-embedding the warehouse once, because the
localandapidefaults are different models producing different vectors. Running it prints the instructions;python -m mnemosure.reembeddoes the move — see "Switching embedding models" below.
Two things to know
If rerank is api and you only repoint BASE_URL at a local server, rerank breaks.
The OpenAI-compatible spec has no rerank route, so mnemosure calls /rerank on the same
host directly (Cohere convention), and ordinary local inference servers do not serve it.
When moving BASE_URL, leave rerank on local (the default). To skip rerank entirely use
MNEMOSURE_RERANK=off — ranking and the honesty gate then use the first-pass cosine score.
The honesty-gate floor belongs to whichever model produced the score. Recall stops before calling the answer model — replying "not in the record" — when the best candidate's score falls below the floor. Which model's score that is depends on whether rerank is on, so there are two floors, with different conditions for re-tuning.
| Rerank | Score the floor reads | Variable | Default |
|---|---|---|---|
| on (default) | relevance from the rerank model | MNEMOSURE_RERANK_FLOOR |
local 0.20 · api 0.15 |
off (MNEMOSURE_RERANK=off) |
cosine from the embedding model | MNEMOSURE_COSINE_FLOOR |
local 0.85 · api 0.35 |
Those two defaults differ sharply because cosine distributions differ wildly per model. e5 (the local default) scores 0.83 even for unrelated pairs — measured on 1,503 chunks (top score among 40 candidates), the median was 0.88 with the answer present and 0.83 without. A 0.35 floor filters nothing there (100% false answers). Nor is 0.85 comfortable: the distributions overlap heavily, so even there it is 23% false "not in the record" and 13% false answers. Cosine alone is a weak gate, which is why rerank is on by default.
When to re-tune:
| What you changed | What to re-tune |
|---|---|
Rerank model (MODEL_RERANK / MODEL_RERANK_LOCAL) |
RERANK_FLOOR |
Rerank provider (RERANK_PROVIDER) |
RERANK_FLOOR — the default differs per provider, so revisit any value you set explicitly |
| Embedding model — with rerank on | Nothing. Rerank scores read the question and document together, so they are independent of the embedding |
| Embedding model — with rerank off | COSINE_FLOOR — the floor is reading embedding cosines, whose distribution shifts with the model |
So if you plan to change the embedding model, leave rerank on — there is then no floor to re-tune. Conversely, changing the embedding while rerank is off leaves the floor and the model mismatched.
Too high a floor answers "not in the record" for memories you actually have; too low a
floor answers from irrelevant evidence. Which way it is wrong is visible in the candidate
scores — recall returns the top score alongside the answer.
The two default rerank models genuinely differ in scale: the gateway model returns 0–1 relevance, while the local cross-encoder returns logits (measured -3.7 to +3.4). The local path therefore maps them through a sigmoid onto 0–1 so both read the same ruler, and even then the distributions differ, so each provider carries its own measured floor.
e5 prefixes are off by default. e5 models are trained with query: before questions
and passage: before documents, and the model card says to use them. Measured on the same
data, however, retrieval got worse:
| Candidates | without prefix | with prefix |
|---|---|---|
| top 6 | 72.8% | 66.0% |
| top 40 | 85.4% | 81.6% |
All six candidate counts got worse, and the 75th-percentile rank of the answer slipped from 9th to 20th. It is not a double-prefix artifact either — fastembed applies no prefix preprocessing to e5 (it only mean-pools). Hence the default is off.
That said, the "queries" in that measurement were refined conclusion summaries, closer to
statements than questions. Real recall queries are questions, so the result may differ. To
test on your own questions, set MNEMOSURE_E5_PREFIX=on — turning it on changes the
vectors, so the warehouse id is marked and mixing is refused.
Retrieval candidate count
MNEMOSURE_CANDIDATE_K (default 40) is how many candidates the first pass keeps.
Anything cut here is invisible to both rerank and the honesty gate — set it too narrow
and, as the warehouse grows, more answers become "I have it but cannot find it", which
then leaves as "not in the record" and is indistinguishable from honest ignorance.
Measured on 7,340 chunks of research notes (share of questions whose answer was retrieved):
| Warehouse size | 6 candidates | 40 candidates | 100 candidates |
|---|---|---|---|
| 19 chunks | 95.8% | 100.0% | 100.0% |
| 1,000 chunks | 75.7% | 86.1% | 93.2% |
| 7,340 chunks | 60.2% | 75.7% | 82.5% |
The bigger the warehouse, the more a wider candidate set is worth. Raise it past tens of thousands of memories; lower it if you want faster responses on a very small warehouse.
API keys are read only from the environment (or .env) and never hardcoded.
Defaults live in mnemosure/config.py (single source of truth).
Install
pip install mnemosure # the core product: memory library + MCP server
Then provide your OpenRouter key and run the MCP server:
export OPENROUTER_API_KEY=sk-or-...
mnemosure-mcp                  # stdio MCP server
- Where memories are stored: an installed copy starts with an empty warehouse at
~/.mnemosure/memories.json. Override the directory withMNEMOSURE_DATA_DIR. - The pip package ships only the product (
config,llm,mcp_server,reembed,memory/). The web demo and evaluation harness live in this repository (clone it to run them).
Local models (default · nothing extra to install)
Embedding and rerank are computed on your machine with
fastembed. It is a base dependency, so
pip install mnemosure is all it takes.
embedding  intfloat/multilingual-e5-large              2.24GB · 1024-dim
rerank     jinaai/jina-reranker-v2-base-multilingual   1.11GB · multilingual
Weights are not bundled — they are fetched once from Hugging Face on first use and cached, after which it runs without network (on an air-gapped host, place them in the fastembed cache directory manually).
To run these through the gateway instead: MNEMOSURE_EMBED_PROVIDER=api /
MNEMOSURE_RERANK_PROVIDER=api.
Switching embedding models (migration)
Vectors from different embedding models don't mix — the warehouse records which model built it, and Mnemosure refuses to run on a mismatch instead of failing silently. To switch models (including api↔local), re-embed once:
python -m mnemosure.reembed                      # default warehouse
python -m mnemosure.reembed path/to/memories.json
Quick start (from source)
# 1) create and activate a project virtual environment
python3 -m venv .venv
source .venv/bin/activate

# 2) install dependencies
pip install -r requirements.txt

# 3) provide a key for answer generation (embedding/rerank are local — no key needed)
cp .env.example .env        # then edit .env and set OPENROUTER_API_KEY

# 4) verify all four model roles are reachable
python scripts/check_models.py
Run the demo
The repository ships with precomputed demo snapshots (under data/scenarios/<key>/), so the demo works right after cloning:
python scripts/run_demo.py # → http://127.0.0.1:8000
It includes two scenarios — a pre-market trading bot and a SaaS subscription-pricing revamp — that you can switch between. Each scenario also lets you expand its source conversations, so you can confirm the memories were extracted from real multi-session chats, not hardcoded. The memory warehouse and the before/after evaluation panels render straight from the snapshot — no API key needed to browse them. Only /ask (live grounded recall) calls the models and therefore needs a key. To regenerate a scenario's snapshot from scratch (consumes credits):
python scripts/gen_demo_data.py            # all scenarios (only missing ones)
python scripts/gen_demo_data.py pricing    # a specific scenario
Use it as an MCP server
Mnemosure exposes the memory layer over the Model Context Protocol, so any MCP-capable agent (Claude Desktop, Claude Code, Codex, …) can call it as a tool.
mnemosure-mcp                       # if installed via pip
python -m mnemosure.mcp_server      # equivalent, from a source checkout
Register it in your agent's .mcp.json (or equivalent). After pip install mnemosure, the console command is enough:
{
  "mcpServers": {
    "mnemosure": {
      "command": "mnemosure-mcp",
      "env": { "OPENROUTER_API_KEY": "sk-or-..." }
    }
  }
}
The .mcp.json above works with any MCP client. Claude Code users can skip the hand-editing and register it in one line:
claude mcp add mnemosure --env OPENROUTER_API_KEY=sk-or-... -- mnemosure-mcp
Zero-install with uv — run it straight from PyPI without pip install (the console script mnemosure-mcp differs from the package name mnemosure, so pass --from):
{
  "mcpServers": {
    "mnemosure": {
      "command": "uvx",
      "args": ["--from", "mnemosure", "mnemosure-mcp"],
      "env": { "OPENROUTER_API_KEY": "sk-or-..." }
    }
  }
}
Running from a source checkout instead of an install? Use
"command": "/abs/path/.venv/bin/python","args": ["-m", "mnemosure.mcp_server"], and add"PYTHONPATH": "/abs/path/to/repo"so the package is importable regardless of the launcher's working directory.
Tools:
| Tool | Signature | Returns |
|---|---|---|
recall |
recall(query: str) |
{confidence, answer, cited} — grounded answer with source-cited memory ids |
remember |
remember(session_text: str, date="", title="") |
{stored: [...], count} — extracts decisions/changes/failures and auto-links supersedes/because |
list_memories |
list_memories(include_superseded=False) |
list of active (or all) memories with source |
Note: the server itself calls the configured models for classification, recall, and grounding — it is agent-agnostic but assumes an API key is present (via env or
.env).
Evaluation approach
Quality is measured by labeling each answer's behavior — accurate / omission / hallucination / noise / honest — alongside our three-way confidence (certain / vague / unknown), rather than a single opaque score. The whole pipeline (extraction, supersession judgment, scoring) runs at temperature 0 for reproducibility. The demo serves a fixed snapshot so results are stable across viewings.
On the two built-in scenarios (19 questions total — trading bot 8, subscription pricing 11), the snapshot labels out as:
| Behavior | Mnemosure | Summary handoff | Plain RAG |
|---|---|---|---|
| accurate | 17 | 4 | 4 |
| honest ("not in the record") | 2 | 2 | 2 |
| omission (forgot it) | 0 | 11 | 7 |
| hallucination (made it up) | 0 | 1 | 6 |
| noise (didn't answer the question) | 0 | 1 | 0 |
Read this as a demo, not a benchmark: the scenarios and answer keys are our own (fictional, in Korean), behaviors are labeled by an LLM judge, and the snapshot was measured on a Qwen Cloud model mix (stated in the demo UI). All three systems answered with the same brain model — only the memory in front of it differs.
See mnemosure/evaluation/ (harness.py, judge.py, label.py, baseline.py, answer_key.py).
Project structure
mnemosure/
  config.py           # gateway, models, key loading — single source of truth
  llm.py              # the only gateway to models (chat / embed / rerank, local embeddings)
  mcp_server.py       # MCP tools: recall · remember · list_memories (stdio)
  reembed.py          # one-shot warehouse re-embedding (embedding-model migration)
  memory/
    store.py          # ingest: extract → embed → link supersedes/because → save
    recall.py         # recall: embed → rerank → associative expand → grounded answer
    forget.py         # forgetting / relevance handling
    storage.py        # JSON-file memory warehouse (records its embedding model)
    models.py         # Memory / Association / Source dataclasses
  evaluation/         # harness · judge · label · baseline · answer_key
  demo/
    server.py         # FastAPI: /ask · /memories · /results · /sessions · /scenarios
    index.html        # single-page demo UI (scenario switcher + source-transcript viewer)
    scenarios.py      # scenario registry (sessions + answer keys + snapshot paths)
    sample_sessions.py# fictional scenarios (trading bot, subscription pricing) for demo & eval
scripts/              # check_models · gen_demo_data · run_demo · demo_* helpers
data/scenarios/<key>/ # per-scenario memories.json + results.json (demo snapshots, committed)
Deployment
The demo ships with a Dockerfile (single container, source + precomputed
snapshots; the API key is injected at run time, never baked in). It runs on any
Docker host. Quick local run:
docker build -t mnemosure-demo .
docker run -p 8000:8000 -e OPENROUTER_API_KEY=sk-or-... mnemosure-demo
# → http://127.0.0.1:8000  (health: /health)
Upgrading from 0.4.0
0.4.1 leaves existing warehouses alone. Anything built with 0.4.0 still opens.
- Fixed the cosine floor on the rerank-off path. 0.4.0 switched the embedding default to
e5 but left the floor at 0.35, which was calibrated for bge-m3. Since e5 scores 0.83 even
for unrelated pairs, anyone running
MNEMOSURE_RERANK=offhad an honesty gate that never closed. The default now varies by provider (local0.85 ·api0.35). The default path (rerank on) is unaffected. - Added an e5 prefix switch (
MNEMOSURE_E5_PREFIX, default off). Turning it on measured worse retrieval, hence the default — see "Two things to know" above.
Upgrading from 0.3.x (breaking changes)
0.4.0 moves embedding and rerank to your machine by default (both were gateway-only before).
- An existing warehouse will not open as-is. The default embedding model changed from
baai/bge-m3tointfloat/multilingual-e5-large, so the vectors differ. Running it prints exactly which variables to set. Pick one:- Keep it —
MNEMOSURE_EMBED_PROVIDER=apiandMNEMOSURE_MODEL_EMBED=baai/bge-m3(same as 0.3.x) - Move it —
python -m mnemosure.reembedonce
- Keep it —
- Rerank now defaults to local too. For the gateway, set
MNEMOSURE_RERANK_PROVIDER=api. - The honesty-gate floor default now differs per provider —
api0.15,local0.20, because the two models produce different score scales. An explicitMNEMOSURE_RERANK_FLOORstill wins. - Retrieval candidate count default is 6 → 40 (
MNEMOSURE_CANDIDATE_K), to reduce "I have it but cannot find it" answers as the warehouse grows. - fastembed is now a base dependency —
pip install "mnemosure[local]"is no longer needed ([local]remains as an empty alias). About 3.4GB of weights is fetched once on first use.
Upgrading from 0.2.x (breaking changes)
0.3.0 replaces the Qwen Cloud (DashScope) integration with a single OpenAI-compatible gateway (default: OpenRouter):
- Key:
DASHSCOPE_API_KEYis no longer read — setOPENROUTER_API_KEY(orMNEMOSURE_BASE_URL+MNEMOSURE_API_KEYfor another gateway). - Confidence tokens in
recallresponses are now English:certain/vague/unknown(were 확실/어렴풋/모름). - Warehouses built with 0.2.x (
text-embedding-v4vectors) must be re-embedded once:python -m mnemosure.reembed.
License
MIT.
1 maintainer

Metadata
1 maintainer
Release files for mnemosure 0.4.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| mnemosure-0.4.1.tar.gz | 42.9 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| mnemosure-0.4.1-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 83.6 kB
Release files / mnemosure-0.4.1.tar.gz
| Download URL | mnemosure-0.4.1.tar.gz |
|---|---|
| Size | 42.9 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
1b9fa5cdddfdef6b459f929a881bc3cf814891844befa03d5ba9ceaf353e507a
|
|
BLAKE2b-256 checksum How to use checksums |
c9a3d6a908605487860a35a907a96286e6ddd1d3e1553265fb2c82ffa4d53ee7
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.12.13
|
Release files / mnemosure-0.4.1-py3-none-any.whl
| Download URL | mnemosure-0.4.1-py3-none-any.whl |
|---|---|
| Size | 40.7 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
04e37545b28a1ef9560187a632899af31a4139d880dd88b0583412baa044d3f6
|
|
BLAKE2b-256 checksum How to use checksums |
4cf96225f0fb0a76e01ed1d6a2cbe1b0e47be8e8849c5f365717af244f8ba2cf
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.12.13
|














