
mnimi


mnimi is an embeddable, local-first memory layer for LLM agents: one SQLite file (sqlite-vec),
two dependencies, no server. Raw chat turns go in; a small pinned local model extracts facts at
write time; deterministic screens handle duplicates, contradictions and supersession; nothing on
the read path calls a model. All time is logical (the ts you hand each message), so the same
store gives the same answers on any day. Every memory is readable as Markdown. On LongMemEval-S
(500 questions, gpt-4o as reader) it reads 85.8 %, paired and audited: every published row
re-grades with one command.
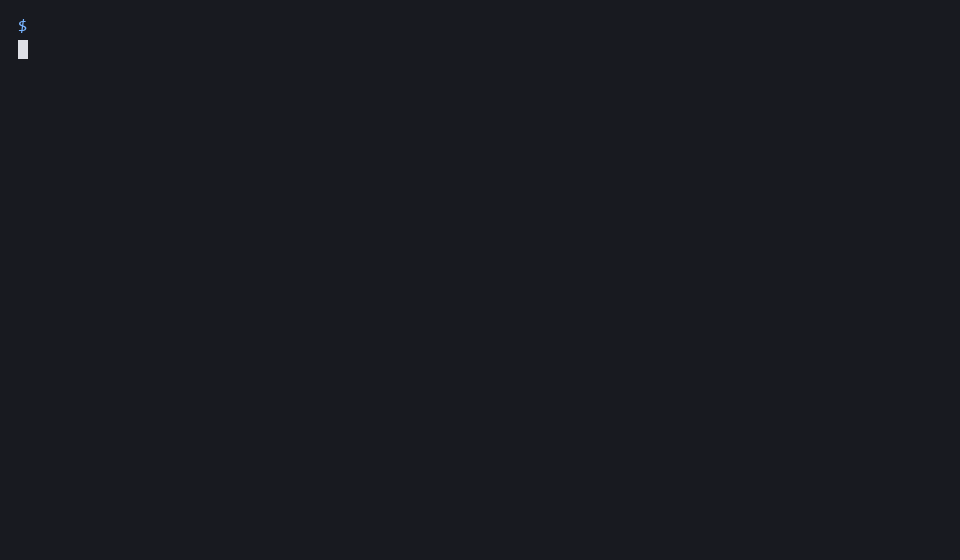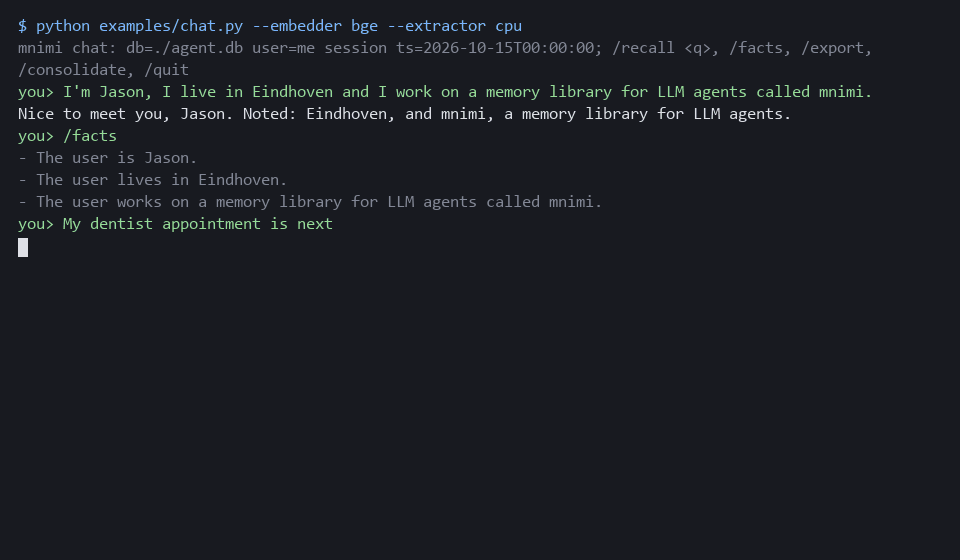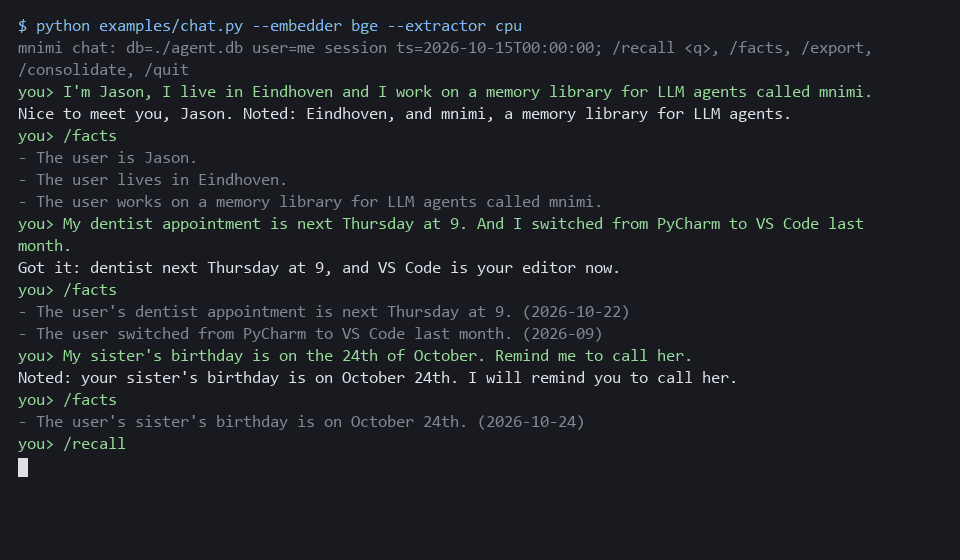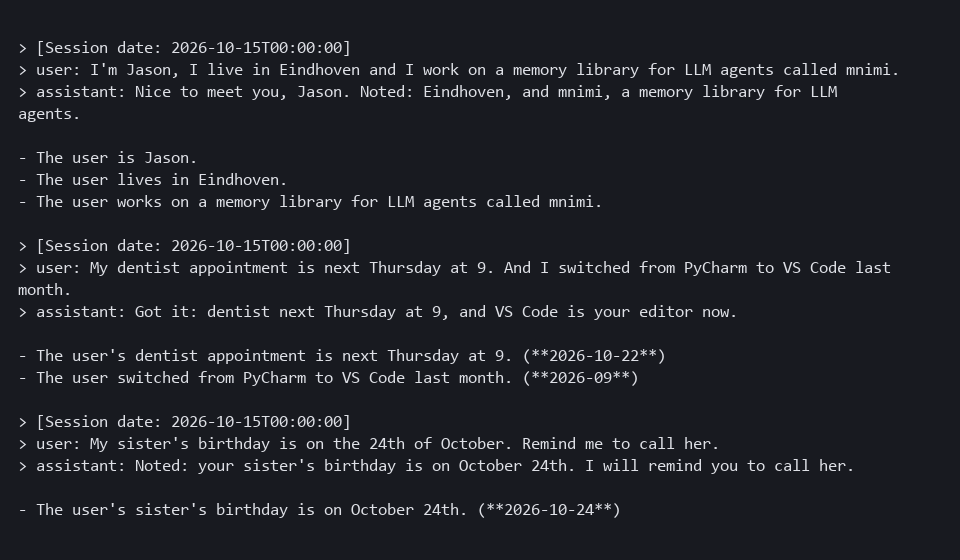
A real examples/chat.py session (BGE embedder, the CPU extractor, /facts, /recall, /export);
the assistant's replies are scripted, so no chat model runs in it.
The number
The gpt-4o family on all 500 questions of LongMemEval-S, one reader prompt for every question
type, retrieval k=10 and per-round ingestion identical across the rows that retrieve:
| System | Correct / 500 | Wilson 95 % | mean fed tokens | role | run_id |
|---|---|---|---|---|---|
| no_memory | 31 (6.2 %) | [4.4, 8.7] | 133 | the floor: the question alone | no_memory__500q_gpt4o |
| full_history | cited: 64.0 % | — | — | cited (LongMemEval Fig. 3b, GPT-4o + Chain-of-Note), never run here | — |
| naive_rag | 373 (74.6 %) | [70.6, 78.2] | 4,685 | rounds stored verbatim, cosine top-10: the bar | naive_rag__500q_gpt4o |
| mnimi | 429 (85.8 %) | [82.5, 88.6] | 5,498 | the shipped configuration | mnimi__500q_gpt4o_p6time |
| oracle | 459 (91.8 %) | [89.1, 93.9] | 5,771 | the evidence-availability bound: the reader is handed the evidence sessions | oracle__500q_gpt4o |
Provenance. Reader and judge gpt-4o-2024-08-06 over the OpenAI API, temperature 0; reader
prompt mnimi-con-v1, judge prompt longmemeval-paper-v3; harness commits f07c24d (no_memory,
naive_rag, oracle) and f0a7de3 (mnimi), clean trees, provisional: [] on all four. Counts and
intervals are copied from each arm's summary.json under
results/published/; mean fed tokens is the mean reader_prompt_tokens
over each arm's predictions.jsonl. mnimi against naive_rag on the same 500 questions: b=77,
c=21, exact McNemar p = 1.1 × 10⁻⁸ (analyses/). Paired, never ranked.
Two caveats. The reader and the judge are one model snapshot (LongMemEval's own pairing); a second
judge re-graded every arm and every pair of record keeps its sign. "Auditable" is not
"reproducible": every row re-grades from its committed predictions (§ Verify the number), while a
fresh run of the same configuration reproduces the score within 12/500 flips and not the text.
The full record of every run, the third-party rows and their disclosures, is
results/published/README.md.
The problem
- An agent forgets everything between sessions, or stuffs its window with history until the evidence it needs is truncated away.
- Routing every write through an LLM is slow, costs money per turn, and leaves no auditable trail of why a memory was kept, merged or dropped.
- Hosted memory is someone else's database: your users' conversations leave the machine.
- You cannot read what your agent remembers, so you cannot check it, correct it or delete it.
Quick install
pip install mnimi-memory # the library: rounds stored verbatim, no model
The distribution is mnimi-memory; the import, the CLI and the repository are mnimi (PyPI's look-alike rule
reserves the bare name for an unrelated 2020 package, mniml).
pip install "llama-cpp-python==0.3.35" --extra-index-url https://abetlen.github.io/llama-cpp-python/whl/cpu
pip install "mnimi-memory[embed,extract]"           # the full write path on a CPU, no compiler
git clone https://github.com/IasonasKokkalos/mnimi && cd mnimi && pip install -e ".[embed,extract,dev]"
| extra | what it adds | download |
|---|---|---|
| (none) | Memory over sqlite-vec + numpy; HashingEmbedder (numpy-only placeholder, for tests) |
— |
embed |
BgeSmallEmbedder: BAAI/bge-small-en-v1.5 through ONNX Runtime, revision-pinned |
≈ 130 MB model, 13.8 MB onnxruntime wheel |
extract |
QwenLlamaExtractor: Qwen/Qwen3-1.7B-GGUF Q8_0 through llama-cpp-python 0.3.35, revision-pinned |
1.8 GB model, 7.1 MB CPU wheel |
[extract] pins llama-cpp-python==0.3.35, which PyPI ships only as a source distribution; the
project's own index carries prebuilt CPU wheels (Windows x64, manylinux x86_64 / aarch64, macOS
arm64), so install that first and nothing compiles. A CUDA build of the same version is the GPU
path (docs/DECISIONS.md "Extractor runtime"). Both are the same pinned model under the same
grammar and prompt; the CPU profile differs in two decode keys (n_gpu_layers 0, max_tokens
2048) and is measured at 21.0 s per round on an 8-core laptop CPU against 2.7–3.4 s on the
development GPU
(examples/README.md).
60-second quickstart
A message is {"role": "user" | "assistant", "content": str, "ts": "<ISO timestamp>"}. ts is
the session's timestamp and the only clock the library knows: dedup scope, conflict ordering,
decay and the time-aware term all run on the ts values the store has seen, never on the wall
clock, so a store built today and replayed next year scores identically. A message without ts
is refused.
from mnimi import Memory
from mnimi.embeddings import BgeSmallEmbedder
from mnimi.extract.cache import CachedExtractor
from mnimi.extract.llama import DECODE, QwenLlamaExtractor

extractor = CachedExtractor(QwenLlamaExtractor(decode={**DECODE, "n_gpu_layers": 0, "max_tokens": 2048}), "extract-cache.sqlite")
mem = Memory("agent.db", BgeSmallEmbedder(), extractor=extractor)
mem.add([{"role": "user", "content": "I moved to Boston last month. My dentist is Dr. Lee.", "ts": "2026-10-01T00:00:00"},
         {"role": "assistant", "content": "Noted: you live in Boston and Dr. Lee is your dentist.", "ts": "2026-10-01T00:00:00"}], "u1")
mem.add([{"role": "user", "content": "I live in Cambridge now.", "ts": "2026-10-08T00:00:00"},
         {"role": "assistant", "content": "Updated: you live in Cambridge.", "ts": "2026-10-08T00:00:00"}], "u1")
print(mem.get_context("where do I live?", "u1"))
print(mem.export("u1"))
decode={**DECODE, "n_gpu_layers": 0, "max_tokens": 2048} is the CPU profile; drop the keyword
on a CUDA build. The first run downloads both models by pinned revision and takes about a minute
on a laptop CPU; the cache file beside the DB makes every later add() of the same round free.
Run as pasted, it prints:
[Session date: 2026-10-01T00:00:00]
facts:
- The user's dentist is Dr. Lee.
user: I moved to Boston last month. My dentist is Dr. Lee.
assistant: Noted: you live in Boston and Dr. Lee is your dentist.
[Session date: 2026-10-08T00:00:00]
facts:
- The user lives in Cambridge now.
user: I live in Cambridge now.
assistant: Updated: you live in Cambridge.
# memory export
user_id: u1
now_logical: 2026-10-08T00:00:00
records: 5 (rounds 2, facts 3)

[Session date: 2026-10-01T00:00:00]
user: I moved to Boston last month. My dentist is Dr. Lee.
assistant: Noted: you live in Boston and Dr. Lee is your dentist.
  fact: The user moved to Boston last month.  salience 0.0000  (initial 1.0000)  superseded  valid_time 2026-09  pair user|lives in
  fact: The user's dentist is Dr. Lee.  salience 1.0000  pair user|dentist

[Session date: 2026-10-08T00:00:00]
user: I live in Cambridge now.
assistant: Updated: you live in Cambridge.
  fact: The user lives in Cambridge now.  salience 1.0000  pair user|lives in  supersedes 2
The first fact of the first session is gone from the context: I live in Cambridge now. superseded
moved to Boston on the key user|lives in (a functional predicate, two values, the later session
wins), and a superseded fact neither ranks nor renders. The export below still shows it, marked.
What it does
The write path, add(messages, user_id), per round of one user and one assistant turn:
- Store the round verbatim as one record (its embedded text is frozen; its turns are kept for rendering), after an exact-match and one cosine dedup probe against the session.
- Extract facts with the pinned local model, under a grammar, through an on-disk cache; six
deterministic pre-filter rules skip rounds with nothing to extract. Relative dates in a fact
("next Thursday") resolve against the message's
ts, never by the model. - Screen each fact against the facts already stored: an exact collapse, a frozen negation lexicon, a value-substitution check over normalized triples, a token-entropy gate, then one cosine probe. The screens only ever keep a pair apart; they never drop what verbatim storage would have kept.
- Supersede: two facts on one subject-predicate key conflict only under a rule (opposite
polarity, a functional predicate with two values, a changed number). The later effective time
wins; the loser's salience goes to 0 and the winner points at it. Logged at INFO as
superseded ….
The read path, recall / get_context(query, user_id):
- Embed the bare question (a
[Current date: <ts>]prefix, if you pass one, is parsed for the question's own time window and stripped before embedding). - Select the top-k rounds by score over an exact candidate pool:
score = (w_sim · relevance + w_rec · recency) · salience + w_time · time_match. Superseded facts (salience 0) neither rank nor render. - Render the selected rounds oldest-first through the one renderer: a
[Session date: …]header per session,user:/assistant:lines, the round's facts under afacts:header.
consolidate(user_id) re-runs the conflict pass over every active pair and then the decay pass
(salience = max(floor, initial · 0.5^(days / half_life)) on logical days). Decay is built,
tested and off in the shipped configuration: the pre-registered ablation on all 500 questions
read it at −6.2 points (mnimi__500q_gpt4o 422 → mnimi__500q_gpt4o_decay 391, b=19, c=50,
p = 2.4 × 10⁻⁴; T3), because it multiplies down exactly the old evidence the benchmark asks about.
No benchmark arm calls consolidate() unless asked.
API
from mnimi import Memory, MemoryConfig
mem = Memory(db_path, embedder, config=MemoryConfig(), extractor=None)
| method | what it does | returns |
|---|---|---|
add(messages, user_id) |
the write path above, one round at a time; messages is a list of {role, content, ts} dicts |
None |
recall(query, user_id) |
the top-k rounds by score, best first, with their component scores |
list[ScoredRecord] (.score, .relevance, .recency, .salience, .record) |
get_context(query, user_id) |
the recalled rounds rendered oldest-first as reader context | str |
consolidate(user_id) |
the conflict pass, then the decay pass; idempotent | None |
export(user_id) |
the whole store as readable text, superseded facts shown and marked; no model, no clock | str |
Five methods; depth lives behind add and consolidate. MemoryConfig is a frozen dataclass of
eighteen fields, every threshold the library reads; the ones a user touches:
| field | default | what it controls |
|---|---|---|
top_k |
10 |
rounds returned by recall and rendered by get_context |
dedup_cosine_threshold |
0.95 |
the one cosine probe that collapses a near-duplicate round or fact |
dedup_scope |
"session" |
whether the cosine probe looks at the session or the whole store |
conflict_resolution |
True |
the screens, the entropy gate and supersession; False is dedup only |
time_weight |
0.05 |
the time-aware term, read only when a query carries a [Current date: …] prefix |
decay_half_life_days |
30.0 |
the decay pass's half-life in logical days |
decay_floor |
0.15 |
the salience a decayed record never falls below (it is down-ranked, never excluded) |
render_unit |
"round+facts" |
what a rendered round carries: round+facts, turns (no facts) or facts |
The other fields (ranking, active_only, recall_min_relevance, salience_weights,
rerank_pool, dedup_entropy_gate, query_instruction, chunk_tokens, chunk_overlap,
render_format) are documented in src/mnimi/config.py and sit at the
values the benchmark was run with.
CLI
| command | description |
|---|---|
mnimi export <db> <user_id> [-o FILE] [--format md|text] |
dump one user's store as Markdown (default) or as export()'s text; no model is loaded |
mnimi-mcp |
the MCP server over one store, installed by the mnimi-mcp package (§ Use it from an agent) |
Read your memory
mnimi export agent.db u1 -o memory.md
One heading per session, each round as a quoted block, its facts as bullets, a superseded fact struck through with the id that replaced it. The quickstart's store exports as:
# memory export

- user_id: u1
- now_logical: 2026-10-08T00:00:00
- records: 5 (rounds 2, facts 3)

## 2026-10-01T00:00:00

> [Session date: 2026-10-01T00:00:00]
> user: I moved to Boston last month. My dentist is Dr. Lee.
> assistant: Noted: you live in Boston and Dr. Lee is your dentist.

- ~~The user moved to Boston last month. (**2026-09**)~~ (superseded by #5)
- The user's dentist is Dr. Lee.

## 2026-10-08T00:00:00

> [Session date: 2026-10-08T00:00:00]
> user: I live in Cambridge now.
> assistant: Updated: you live in Cambridge.

- The user lives in Cambridge now. → supersedes #2
Use it from an agent
A chat loop with memory, one timestamp per launch (a day is a session), the library's INFO lines
on, and /recall, /facts, /export, /consolidate commands:
python examples/chat.py                                   # Ollama, BGE, the CPU extractor
python examples/chat.py --embedder hashing --extractor none   # nothing beyond mnimi and a chat backend
The MCP server (integrations/mcp/, the package mnimi-mcp) exposes remember, recall,
context, export and consolidate as tools and memory://export as a resource over stdio. It
stamps every stored message with the server's calendar day, so the clock stays in the application;
one store, one user, from the environment:
pip install mnimi-mcp --extra-index-url https://abetlen.github.io/llama-cpp-python/whl/cpu
claude mcp add --scope user mnimi -e MNIMI_DB=/absolute/path/to/agent.db -- mnimi-mcp
MNIMI_USER_ID (default me), MNIMI_EXTRACTOR (cpu | gpu | none, default cpu) and
MNIMI_EMBEDDER (bge | hashing, default bge) are the other settings;
integrations/mcp/README.md has the tool table, the four-line rule
to paste into the host's instruction file (CLAUDE.md, AGENTS.md: read context before
answering, remember when something durable was said; without it a model calls the tools only when
asked), and the three layouts for several agents (a DB per agent, one DB with a user_id per agent,
or one shared memory and how two processes on one file behave). mnimi-mcp 0.2.0
requires mnimi 3.1.1 or later (>=3.1.1,<4): it uses the extractor wrappers and the client-facts
path that are new in 3.1.0, and 3.1.1's backslash restoration.
How it compares
A feature table, source-verified, no numbers (the numbers are in § The number and in
results/published/README.md § Phase 8). Each cell names where it
was read.
| feature | mnimi | naive RAG (the harness's naive_rag arm) |
Mem0 OSS 2.2.1 | OMEGA 1.5.x |
|---|---|---|---|---|
| input | raw chat turns, both roles (src/mnimi/memory.py) |
raw chat turns (evals/systems/naive_rag.py) |
raw chat turns; the LLM condenses them to facts framed around the user (mem0/memory/main.py:881) |
agent-curated typed records; "fact extraction" is regex over distilled content (docs/SPEC.md § Extraction, bridge.py:652) |
| LLM at write | one pinned local 1.7B model, grammar-constrained, cached (src/mnimi/extract/llama.py) |
none | yes: an API model decides ADD / UPDATE / DELETE / NONE per fact (mem0/configs/prompts.py:205-320; gpt-4o-mini in our run, configs/mem0_competitor.json) |
none (docs/SPEC.md § Extraction) |
| LLM at read | none (CLAUDE.md, src/mnimi/ranking.py) |
none | none by default; an optional reranker (mem0/memory/main.py:505-516) |
none; an optional ONNX cross-encoder reranker (docs/SPEC.md § Deferred, reranker.py) |
| dedup | exact collapse + one cosine probe at 0.95, per round and per fact (src/mnimi/memory.py) |
none | the write LLM's NONE / UPDATE decision (prompts.py) |
exact content_hash at write, offline lexical Jaccard 0.6 compaction (docs/SPEC.md § Dedup, schema.py:309) |
| contradictions | three deterministic rules over normalized triples; loser superseded, both kept (src/mnimi/conflict/) |
none | the write LLM's UPDATE / DELETE decision (prompts.py:246-290) |
a four-signal heuristic (docs/SPEC.md § Dedup, contradictions.py) |
| decay | built, measured at −6.2 points on LongMemEval, off (src/mnimi/decay.py; T3) |
none | platform-only; the OSS build raises on decay=True (mem0/memory/main.py:467-470) |
on, wall-clock days since access, floors 0.15 / 0.35 (docs/SPEC.md § Logical time, _base.py:226) |
| time | logical: the message ts is the only clock; relative dates resolved against it (src/mnimi/decay.py, extract/resolver.py) |
session date as a rendered header | created_at from the wall clock, not read by search; the extraction prompt grounds relative dates on the machine date (results/published/README.md § Phase 8) |
wall-clock created_at and access times (results/published/README.md § Phase 8) |
| storage | one SQLite file with sqlite-vec; a memory_meta table that refuses a store built under other pins (src/mnimi/store.py) |
the same file format | a vector store (Qdrant in our run) plus a SQLite history DB (configs/mem0_competitor.json) |
SQLite with vector, FTS5 and RRF in-process (docs/SPEC.md § Deferred) |
| export | export() and mnimi export: the whole store as text or Markdown (src/mnimi/export.py, src/mnimi_cli/) |
— | get_all() returns the memories; no file export (mem0/memory/main.py:1269) |
not read |
OMEGA's cells are SPEC's source-verified notes of 2026-07-20 (v1.5.5); the harness ran 1.5.17. Both third-party systems were run through this harness under its pins, paired against the same rows: readings, never a rank, and not replications of their published numbers.
Architecture
your application                      (holds the clock: hands every message its ts)
      │  add(messages, user_id)                 get_context(query, user_id)
      ▼                                                 ▲
┌───────────────────────────── mnimi.Memory ─────────────────────────────┐
│  extract/   the pinned model + cache, prefilter, resolver (write only)  │
│  conflict/  lexicon, normalize, screens, supersede (deterministic)      │
│  ranking.py exact top-k by score · decay.py logical time, the pass     │
│  memory.py  the one renderer: RENDER_TEMPLATE, round+facts             │
└──────────────────────────────┬─────────────────────────────────────────┘
                               ▼
                 store.py ── one SQLite file (sqlite-vec, memory_meta)
Storage and footprint
- The DB is the path you pass; one file, WAL mode.
memory_metaholds seventeen rows written once at creation (embedder name, revision and dimension; the embed-template hashes; the chunk pair; the five extractor pins or"none"; the frozen lexicon, conflict, prefilter, resolver and decay hashes) and checked at every open. A mismatch raisesMemoryMetaErrorbefore any query runs, so two configurations can never share a store by accident. - The extraction cache is a second SQLite file keyed by the extractor's pins: one row per
round the model has seen, so a round is extracted once.
examples/chat.pyandmnimi-mcpput it beside the DB; the harness keeps it under.cache/extract/. The LongMemEval cache, attached to thev3.1.1GitHub release, is 95,846 rows, 140,038,144 bytes, sha256ce4a1ab33d661c2c1128974c5d4ea2f69bd238b49085691c600b07a82db4e39e. - Sizes. The quickstart's two rounds make a 3.2 MB store (384-dim float32 vectors, the round records and their facts); the models are 130 MB (BGE) and 1.8 GB (Qwen3 Q8_0) in the Hugging Face cache, downloaded once by revision.
Compute load
What each install profile costs on one laptop, so you can decide three things: whether it runs on
yours, what the extractor costs and what you give up without it, and what a query costs once the
store exists. Every number is a CPU number from the machine named below unless the row says GPU.
The extractor is the whole cost of the write path: without it a round is one embedding and a few
inserts, but there are no fact records, so nothing is superseded or resolved in time (only facts
conflict), and the published number in § The number was measured with it. On the read path the
embedder encodes the query and nothing else runs: recall() and get_context() are a vector
search and a ranking, milliseconds on every profile. One clause goes with that: a store built
under the extractor opens only under the extractor, whose constructor loads the model
(src/mnimi/extract/llama.py), so a process that only reads such a store still holds it.
| profile | runs a model at write / at read | startup | write, per round | read, per query | resident memory | on disk |
|---|---|---|---|---|---|---|
(none): HashingEmbedder |
none / none | 0.13 s (import mnimi) |
2.2 ms | 1.8 ms recall, 1.8 ms get_context |
38 MiB | numpy + sqlite-vec, 25 MB installed; a 1.4 MB store for 50 rounds |
[embed]: BGE-small |
BGE embeds the round / BGE embeds the query | 0.6 s | 59 ms | 9.4 ms, 9.5 ms | 288 MiB | + onnxruntime 41 MB and tokenizers 8 MB installed; the model 134 MB, pulled once by revision; a 1.9 MB store for 50 rounds |
[embed,extract], CPU |
BGE + Qwen3-1.7B Q8_0 extracts the round / BGE embeds the query, the extractor never | 0.4 s to construct; the 1.8 GB maps in over the first rounds | 18.6 s median, 19.3 s mean | 17.6 ms, 17.5 ms (154 records) | 2,665 MiB | + llama-cpp-python 10 MB installed; the model 1.8 GB; a 3.9 MB store and an 86 KB cache for 50 rounds (1.8 KB per cached round) |
[embed,extract], GPU: RTX 1000 Ada (6 GB), the CUDA build |
the same | 1.3 s | 2.9 s median, 3.2 s mean | the same read path | 2,506 MiB, plus 2,567 MiB of VRAM | the same |
Provenance. Measured 2026-10-17 on an AMD Ryzen 7 PRO 8845HS (8 cores, 16 threads, 32 GiB,
Windows 11); the script, the raw JSON of every cell and the method are in
analyses/compute_load/.
Each cell is one fresh process (Python 3.12.13, mnimi-memory 3.1.1, onnxruntime 1.28.0, the CPU
wheel of llama-cpp-python 0.3.35; the GPU row Python 3.14.4 and the CUDA build of 0.3.35) over the
same 50 rounds of real chat: the first 50 rounds, in session order, of a LongMemEval-S question
outside the benchmark slice (mean 1,829 characters per round), one add() per round, then 20
question texts of the benchmark slice as queries, three passes after one warm-up call. The write
figure is the median of the 50 adds and the read figure the median of the 60 recall() and the 60
get_context() calls; the first two rows are the median of five such processes (the [embed]
write median ranged 42–79 ms across them), the extractor rows one process each. Resident memory is
the process's peak working set (K32GetProcessMemoryInfo); VRAM is the device-used delta
nvidia-smi reports with the model loaded. Startup is the embedder's and the extractor's
constructor time; the CPU extractor maps the GGUF file, and its pages become resident during the
first rounds (734 MiB after construction, 2,612 MiB after the 50 rounds). The prefilter skipped one
of the 50 rounds (10 ms); the extractor saw 49 and returned 110 facts on the CPU and 120 on the
GPU (the two profiles differ in two decode keys and are not byte-paired). Installed sizes are
read from the venv's site-packages; the Quick install table lists the wheel download sizes. The
GPU row's read cost is not quoted from its own process: the read path is the same code on the
same store layout, and that process's read timings, taken under another Python, are in its JSON.
The extractor alone, on the 40 dev rounds of evals.probes.extractor_bench --dev-set 40 (rounds
outside the benchmark slice; mean 1,582 prompt tokens), under the profile each row ships, measured
2026-10-17 on the same machine
(analyses/compute_load/bench40_cpu.txt,
bench40_gpu.txt):
| profile | seconds / round mean | p50 | p90 | min | max | tok/s overall | truncated |
|---|---|---|---|---|---|---|---|
CPU (n_gpu_layers 0, max_tokens 2048, 8 threads) |
23.7 | 23.0 | 33.2 | 9.3 | 50.9 | 77 | 0 / 40 |
GPU (the pinned DECODE, RTX 1000 Ada) |
3.06 | 2.98 | 4.93 | 0.23 | 9.16 | 586 | 0 / 40 |
The same 40 rounds read 21.0 s mean (p50 19.6) on 2026-10-10 under the max_tokens 1,024 profile
and 22.7 s in a second process that day
(examples/README.md);
the completion tokens are identical (237 per round), so the outputs are the same and the spread is
the machine's. The GPU read 2.7–3.4 s per round over 50 slice rounds on 2026-09-13
(docs/DECISIONS.md "Extractor runtime").
At benchmark scale, measured on v3.1.0's LongMemEval run (mnimi__500q_gpt4o_pt1, 2026-10-15,
§ Status and scope): CPU and RSS by tools/sample_resources.py every 5 s, store sizes by a
stat-only watcher of the run's scratch stores; the data and the method are in
analyses/compute_pt1/.
The run replays the extraction cache, so these are the library's ingest + retrieval for 500
stores (BGE-small on the CPU through onnxruntime, sqlite-vec inserts, the write-path screens, the
ranking) plus the time spent waiting on the Batch API, not the extractor, whose per-round cost
is the tables above.
| measurement | value |
|---|---|
| machine | AMD Ryzen 7 PRO 8845HS (8 cores, 16 logical), 32 GiB RAM, Windows 11, Python 3.14 |
| ingest + retrieval | 500 stores in 12,262 s: 24.5 s per store, 99 ms per round (124,362 rounds, ≈ 249 per store) |
| harness process CPU (100 = one core) | ingest mean 764 %, p95 782 %; the Batch API wait ≈ 1 % |
| harness process RSS | median 1,899 MiB over the run (1,770 MiB during ingest), peak 2,102 MiB; the process also holds the parsed 500-question dataset (≈ 340 MiB) |
| store on disk | 6.06 MiB per store, median of 500 stores of ≈ 249 rounds (≈ 4 MiB more WAL while open; the last store once closed: 6.55 MiB); 3.07 MiB of any non-empty store is the two vector tables' first chunks (1,024 vectors each, preallocated), the rest averages ≈ 12 KiB per round |
| extraction cache | 1.5 KB per round (140 MB for 95,846 rounds) |
Verify the number
Every published row re-grades from its committed predictions, which carry the question and the gold answer inline. No GPU, no dataset, no model weights; an OpenAI key for the judge, cents per arm:
pip install -e ".[eval]"
python -m evals --stage judge --predictions results/published/mnimi__500q_gpt4o_p6time/predictions.jsonl
It recomputes the score and prints MATCHES, WITHIN RE-GRADE or DIVERGES against the
committed result. This is Tier 1, auditable: it proves the scoring, not that the predictions
came from the pipeline the pins claim. Tier 2 is a fresh run of the shipped configuration
(python -m evals --config configs/<run_id>.json, about $4 of API): on the gpt-4o family it is
"score reproducible within 12/500 flips; text not reproducible" — measured 277/500 answer texts
changed, prompt tokens changed on 0/500, 429 both times, b=6, c=6
(results/published/mnimi__500q_gpt4o_p6time_drift_2026-09-26). The judge itself flips about 1 %
of rows between re-grades, so no absolute difference below that is interpretable; paired
comparisons are unaffected. Every command of the harness is in
results/published/README.md.
Run your system through the harness
A system is a class with four methods, in evals/base.py:
class MemorySystem(ABC):
    name: str
    def reset(self) -> None: ...                       # a fresh store per question
    def add(self, messages: list[dict]) -> None: ...   # one history, {role, content, ts} dicts
    def get_context(self, query: str) -> str: ...      # what the reader sees
    def set_question_date(self, question_date: str | None) -> None: ...  # optional
Render through mnimi.memory.render_turns so the reader sees the one format every arm uses
(date granularity and speaker labels were a measured confound), register it in
evals/__main__.py, and run python -m evals --system <name> --limit 500 --reader-transport openai --batch --purpose "..." --claim none. Third-party packages go through the contract in
evals/systems/competitor.py (their own environment, a 5,364-token context budget, their own ids
as retrieved_ids); the Mem0 and OMEGA adapters are the worked examples. Adapters welcome: open a
pull request with the adapter and its config, and the run is paired against the same rows.
Troubleshooting
MemoryMetaError: memory_meta mismatch - this store was created under a different pin. The
DB was built with another embedder, extractor profile or library era (the message names the row).
Point at a fresh file, or open it with the pins it was built with; the library never upgrades a
store in place.
ValueError: record has no timestamp; pass the message ts as created_at. A message lacked
ts. Every message needs {"role", "content", "ts"}: the library has no clock, so the
application must hand it one (a session's start, the calendar day).
RuntimeError: this llama-cpp-python build cannot offload to the GPU, but the decode pins ask for n_gpu_layers>0. You built the extractor with the default DECODE on a CPU build. Use the
CPU profile, QwenLlamaExtractor(decode={**DECODE, "n_gpu_layers": 0, "max_tokens": 2048}), or
install the CUDA build of 0.3.35. The two profiles write different extractor_decode_hash rows,
so their stores are not interchangeable.
sqlite3.OperationalError at enable_load_extension. Your Python's SQLite was built
without loadable-extension support (some macOS and conda builds). Use a Python whose sqlite3
module allows enable_load_extension(True), for example the python.org or uv builds.
Development
pip install -e ".[dev]"
PYTHONPATH="src;." python -m pytest -q          # 661 tests; 4 need the [embed]/[extract] extras, the MCP suite its mcp package
python -m ruff check .
evals/freeze.py holds a digest of src/mnimi/ and tests/test_library_freeze.py fails on any
library edit that does not recompute it in the same commit, so a run of record always uses the
committed library (FREEZE_NAME names the era; docs/DECISIONS.md, 2026-10-14). A library change is a dated DECISIONS entry and a new digest, never an edit
that makes the test pass.
CLAUDE.md is the working contract (the invariants that silently invalidate a
number); docs/SPEC.md § "v1 as built" is the exact shipped state.
Status and scope
- v3.1.1 is the developer release and the first on PyPI (
mnimi-memory3.1.1,mnimi-mcp0.2.0): the export CLI, the chat example, the CPU recipe and the MCP server. Alpha. 3.0.0 and 3.1.0 were the release branch's versions before and during the MCP test week and were never published. - v3.1.1 (2026-10-15) puts the backslashes back: the pre-escape that shows the extractor
/for\now restores the turn's spelling in the facts it returns (restore_backslashes), andmnimi export --format mdapplies the same rule to a fact stored before it. Off the benchmark path: the PT1 reading below is of the extraction path 3.1.1 ships unchanged. - v3.1.0 (2026-10-14) fixes what the MCP test week found in extraction, in the developer release
only: the model's
rawexcerpts are verified against the round (mnimi.extract.verify), long turns are extracted in sub-rounds behind a backslash pre-escape (mnimi.extract.wrappers), a caller can handrememberits own facts, a weekday beside a numeric date resolves (resolver v3; v2 stores are refused at open), and a time mention is verified against the fact's own turn. The library the published rows in § The number were measured on is tagv2.14.0; 3.1.x departs from it in extraction only, andgit checkout v2.14.0gives it. - In daily use as the maintainer's own memory through
mnimi-mcpsince 2026-10-10. The 3.1.x fixes above are what the first week found; one thing it still gets wrong is deliberately not fixed: a fact the model keys two different ways is not superseded by its contradiction, because the exact-key rule is what keeps the conflict pass deterministic. - v3.1.0 on LongMemEval (2026-10-15): the n=500 reading of the v3.1.0 library, b=9 c=9
against the published 429 (
mnimi__500q_gpt4o_p6time; exact McNemar p = 1.0); 429/500, 85.8 %, Wilson [82.5, 88.6]. Runmnimi__500q_gpt4o_pt1at183e3fa, reader and judgegpt-4o-2024-08-06(judge promptlongmemeval-paper-v3), the extraction cache replayed (results/published/mnimi__500q_gpt4o_pt1/). A developer-release reading, inside the judge's band; the published number staysv2.14.0's. - In scope is write-side policy: extraction, screens, supersession, decay, ranking, retrieval. Out of scope: a UI, a chat frontend, a hosted service.
- Deliberately not built, each with its re-open trigger in
docs/FUTURE.md: a context token budget,rawspans in the rendered block, hybrid FTS5 retrieval, a recency weight above 0, pinned records. - Issues and pull requests are open. The easy targets are the MCP server, the CLI, the chat
example, the docs and a harness adapter for another memory system (§ Run your system through
the harness); a change under
src/mnimi/is a dateddocs/DECISIONS.mdentry plus a recomputed freeze digest, asCONTRIBUTING.mdexplains. - The contract is
docs/SPEC.md; the dated rulings aredocs/DECISIONS.md.
License
1 maintainer

Metadata
1 maintainer
Release files for mnimi-memory 3.1.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| mnimi_memory-3.1.1.tar.gz | 114.0 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| mnimi_memory-3.1.1-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 229.9 kB
Release files / mnimi_memory-3.1.1.tar.gz
| Download URL | mnimi_memory-3.1.1.tar.gz |
|---|---|
| Size | 114.0 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
43296456bb5c58778f17d479f3a6017f50f8a452e60b9cabc14b63fc1ac8549d
|
|
BLAKE2b-256 checksum How to use checksums |
2259734ed1aa8f98ba32227a945f22400f5f8fba531f5da9709d1c3c85248dd8
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 17, 2026.
Transparency logRelease files / mnimi_memory-3.1.1-py3-none-any.whl
| Download URL | mnimi_memory-3.1.1-py3-none-any.whl |
|---|---|
| Size | 115.9 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
28411aceeed4c0eaaafb1edce98ce2b6703b4d59f8583feacfaae6c231711930
|
|
BLAKE2b-256 checksum How to use checksums |
645f077a4794f8b15ba8c0c5b10a67bee67479cf5c109ec52a819be047cffce0
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 17, 2026.
Transparency log












