


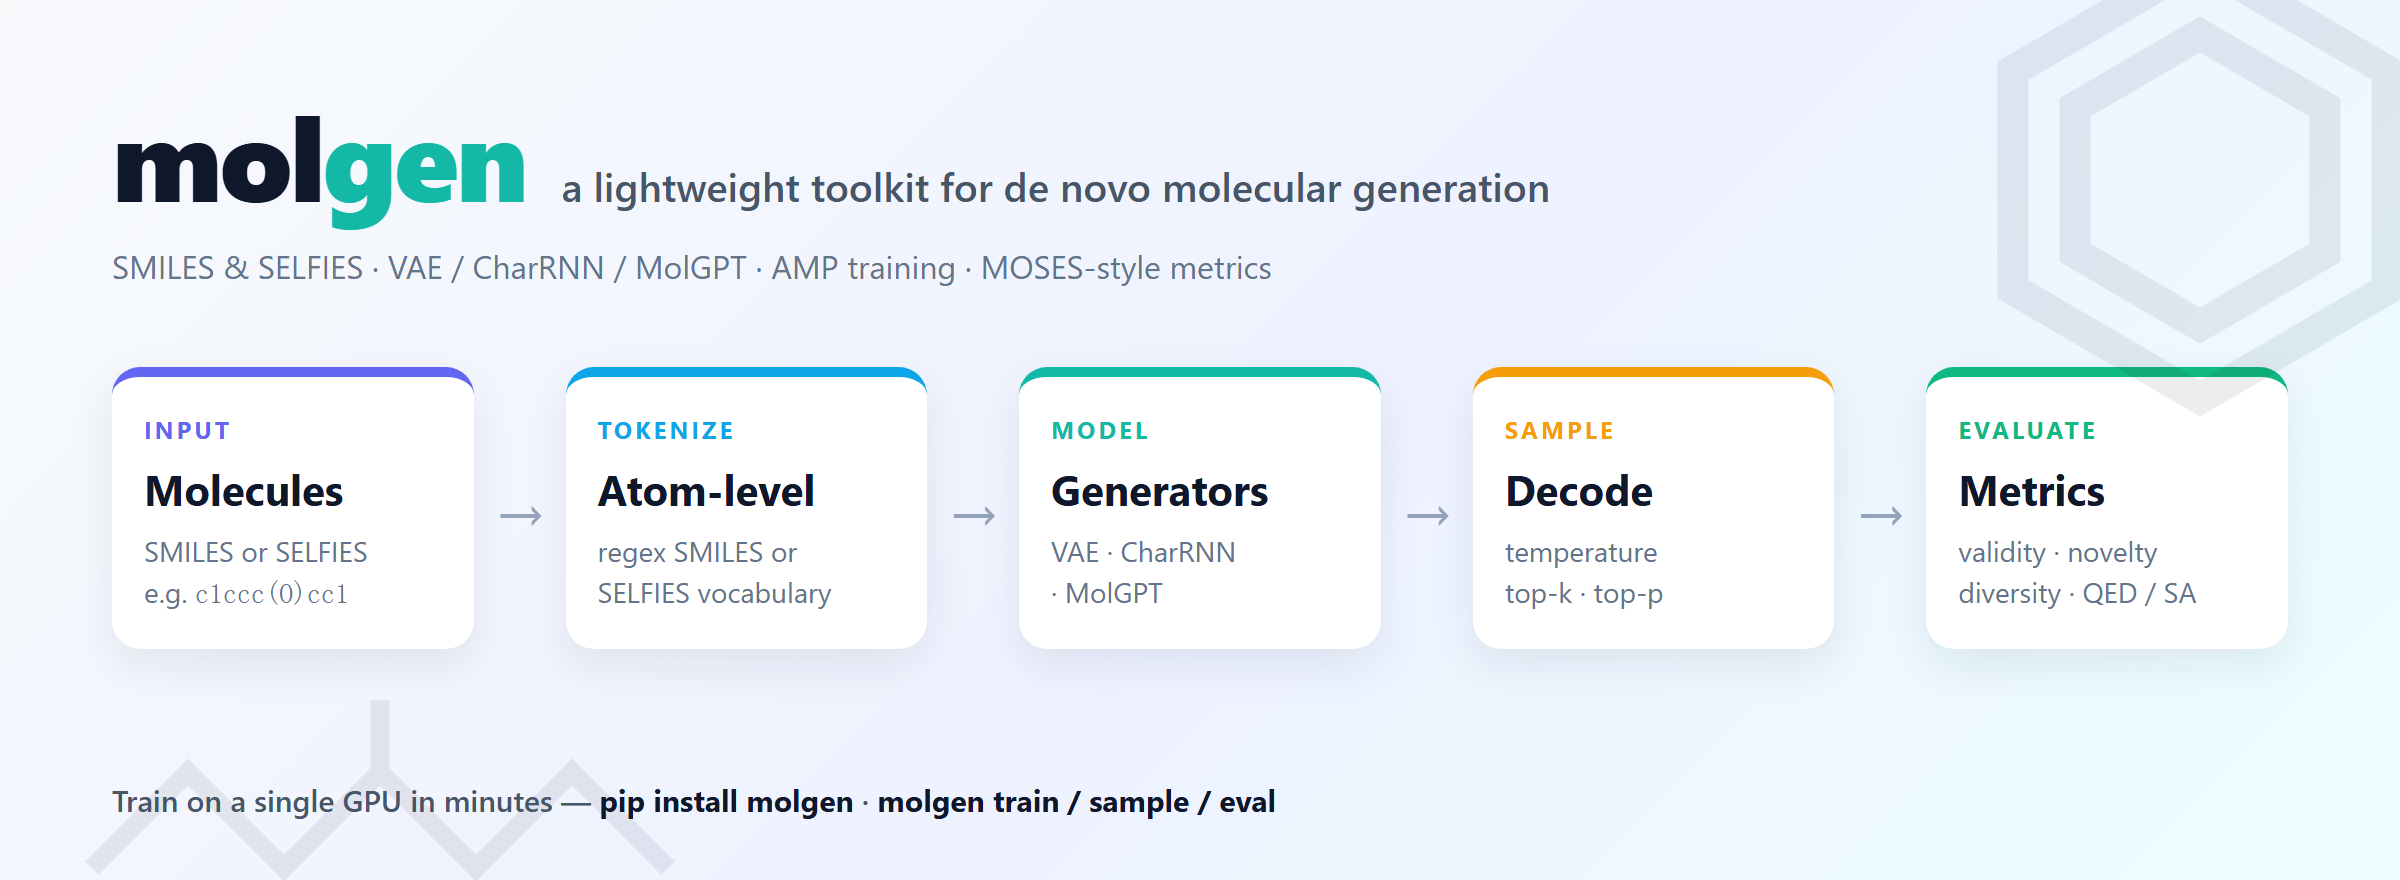
A lightweight, modern toolkit for de novo molecular generation with deep sequence models. It provides atom-level SMILES and SELFIES tokenizers, several generator architectures, a mixed-precision training loop, configurable sampling, and a MOSES-style evaluation suite — small enough to train on a single GPU in minutes, while still reflecting current practice.
Features
- Representations — atom-aware regex SMILES tokenizer and a SELFIES tokenizer (every sequence decodes to a valid molecule).
- Models — a Transformer β-TC-VAE, a GRU/LSTM
CharRNN, and a decoder-onlyMolGPT. - Training — teacher-forced loop with AdamW, gradient clipping, and automatic mixed precision (AMP) on CUDA.
- Sampling — autoregressive generation with temperature, top-k, and top-p (nucleus) filtering.
- Metrics — validity, uniqueness, novelty, internal diversity, unique scaffolds, SNN, and QED / logP / MW / SA-score property summaries.
- Tooling —
molgenCLI, a bundled sample dataset, tests, CI, and ruff.
Installation
pip install molgen              # from PyPI
pip install "molgen[selfies]"   # + SELFIES (always-valid decoding)
From source (for development / running the tests):
git clone https://github.com/DaoyuanLi2816/molgen.git
cd molgen
pip install -e ".[selfies,dev]"
Quickstart (Python)
from molgen.data import build_dataloaders, load_sample_smiles
from molgen.tokenizers import SmilesTokenizer
from molgen.molgpt import MolGPT
from molgen.trainer import TrainConfig, train_language_model
from molgen.sampling import sample
from molgen.metrics import evaluate_generation

smiles = load_sample_smiles()                      # bundled sample, or your own list
tokenizer = SmilesTokenizer.from_smiles(smiles)
train_loader, val_loader = build_dataloaders(smiles, tokenizer, augment=True)

model = MolGPT(tokenizer.vocab_size, pad_idx=tokenizer.pad_id)
train_language_model(model, train_loader, val_loader, TrainConfig(epochs=20), pad_idx=tokenizer.pad_id)

generated = sample(model, tokenizer, num_samples=1000, top_p=0.95)
print(evaluate_generation(generated, reference=smiles))
Quickstart (CLI)
molgen train  --data molecules.smi --model molgpt --epochs 20 --out model.pt
molgen sample --checkpoint model.pt --num 1000 --top-p 0.95 --out generated.smi
molgen eval   --generated generated.smi --reference molecules.smi
Example output
Training MolGPT on the bundled (synthetic) sample and sampling 300 molecules
produces a report like:
n_generated: 300
validity: 0.30
uniqueness: 0.96
novelty: 0.90
internal_diversity: 0.90
unique_scaffolds: 0.32
snn: 0.47
properties: {'qed': 0.52, 'logp': 1.71, 'mol_weight': 133.2, 'sa_score': 2.70}
These numbers reflect the tiny bundled sample — train on MOSES/QM9/ZINC for stronger models. (SELFIES mode guarantees 100% validity.)
Visualizations
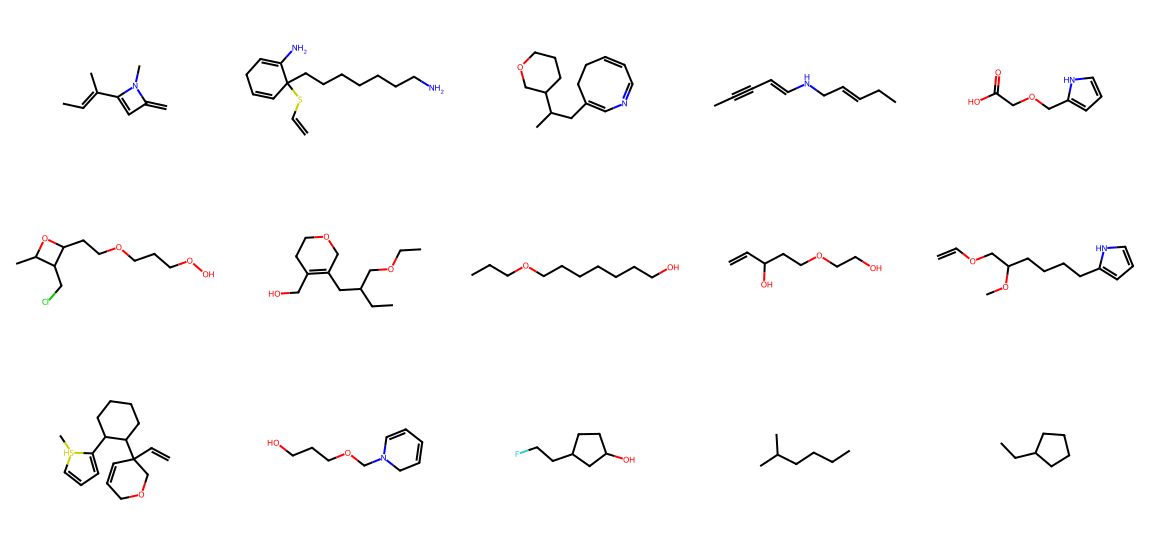
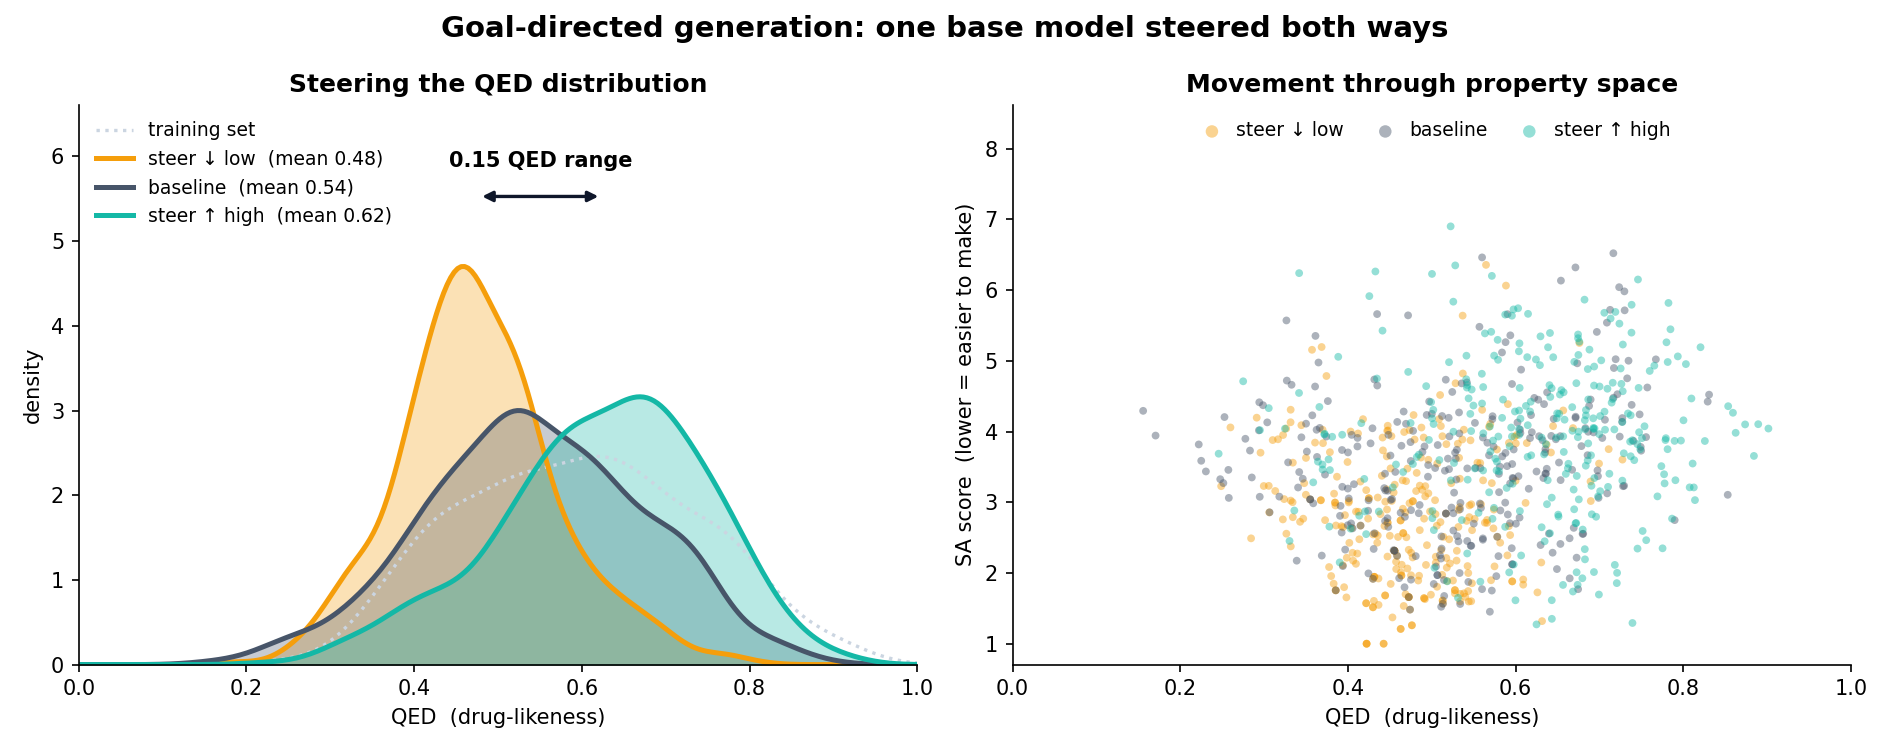
Both figures come from real model output and are reproducible with
python scripts/make_figures.py (trains a SELFIES MolGPT on the bundled sample).
Generated molecules — structures sampled directly from the trained model:
Goal-directed generation — from a single base model, fine-tuning toward the most (or least) drug-like molecules steers the generated QED distribution in both directions (a ~0.15 QED span) and moves the samples through QED-vs-SA property space. Generation can be steered toward a target, not just imitated:
Models
| Model | Module | Description |
|---|---|---|
CharRNN |
molgen.char_rnn |
GRU/LSTM next-token language model (classic strong baseline) |
MolGPT |
molgen.molgpt |
Decoder-only Transformer with causal attention |
BetaTCVAE |
molgen.vae |
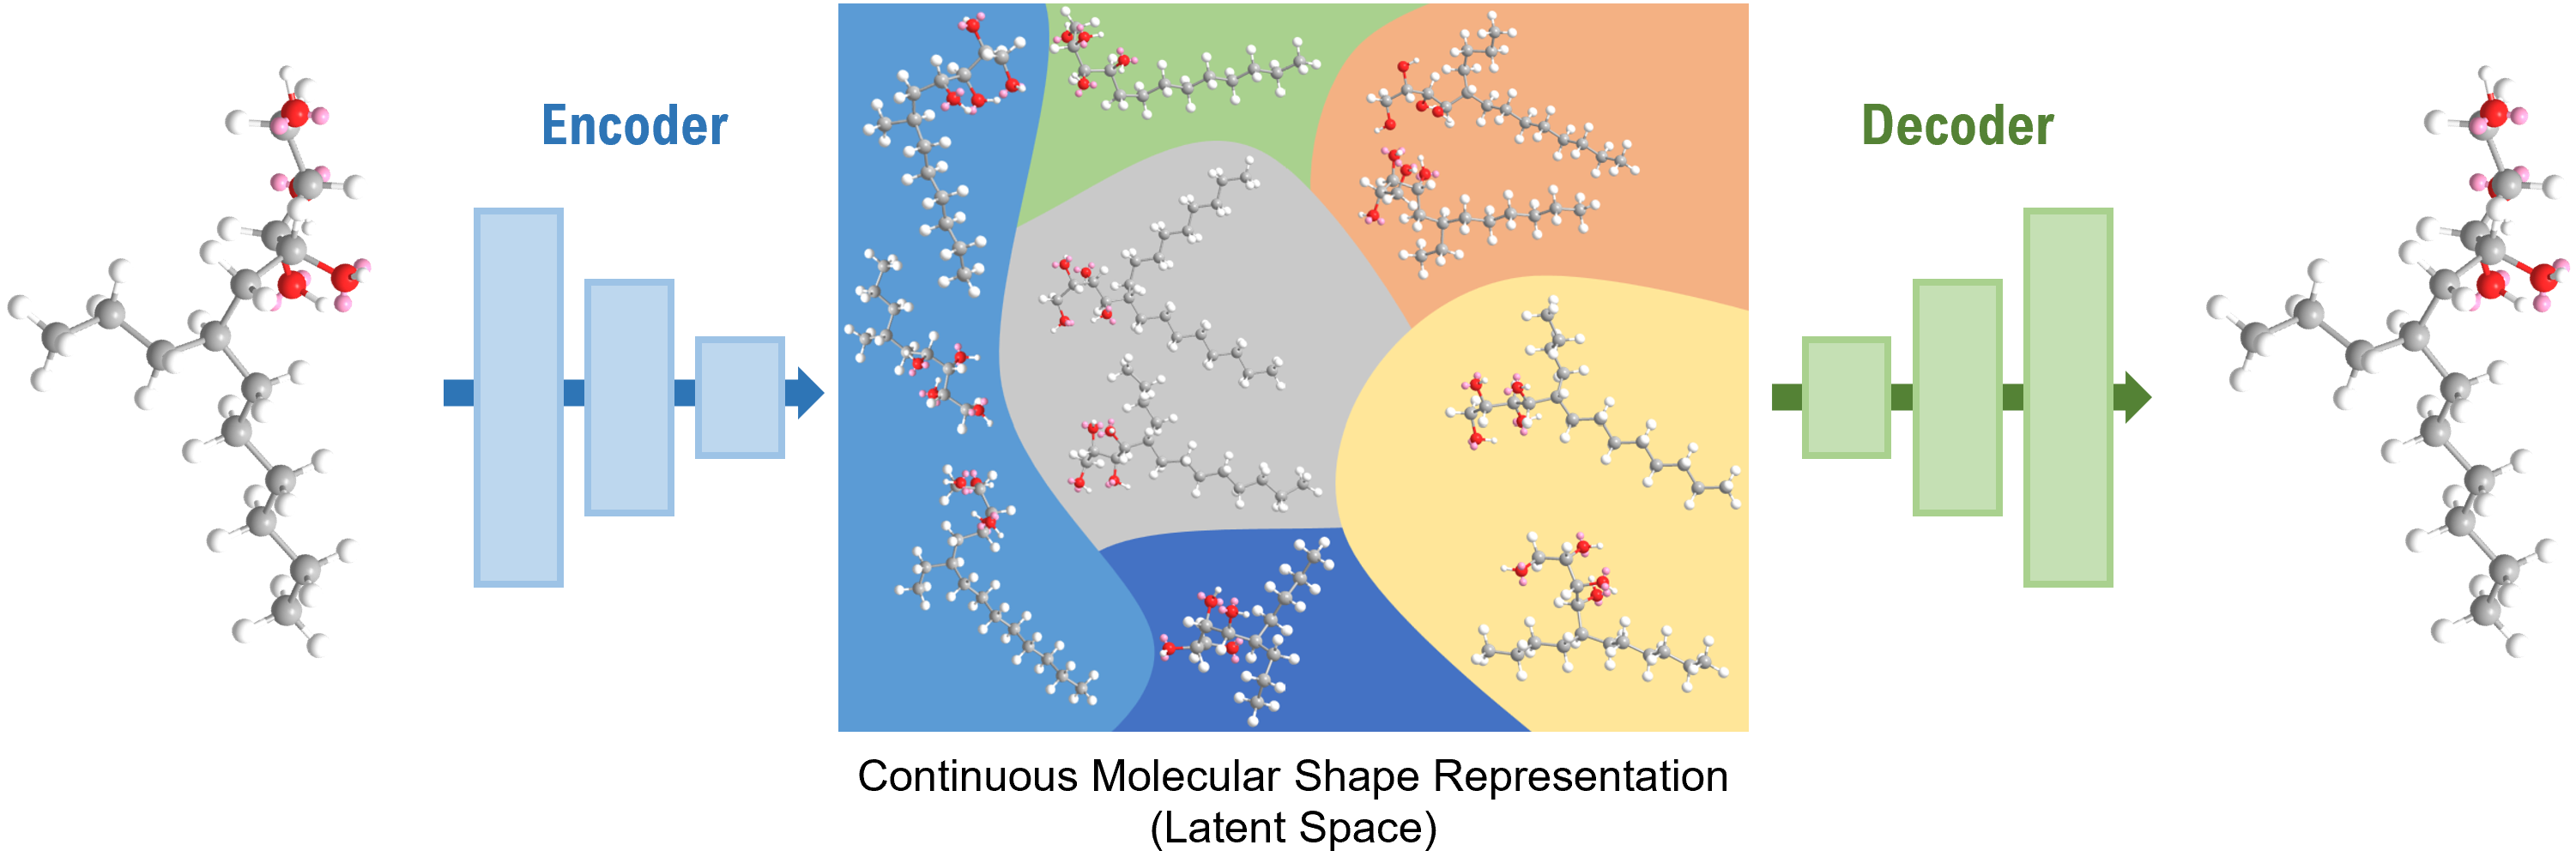
Sentence VAE (one fixed-size latent per molecule) for reconstruction, nearby sampling, and interpolation |
Both CharRNN and MolGPT train and sample through the same trainer/sampler.
Latent-space exploration (VAE)
Unlike the autoregressive models, the VAE supports latent-space operations:
generate molecules near a seed, or interpolate between two molecules. Pair it
with the SELFIES tokenizer (--tokenizer selfies, the default for these
commands) so every decoded point is a syntactically valid molecule.
Note: these commands need
molgen0.2.0+. The current PyPI release is 0.1.1, which predates thevae-train/vae-sample/vae-interpolateCLI commands — until 0.2.0 ships, install from source (see Installation) to use this section.
# Train a VAE and save a checkpoint (model + tokenizer in one file).
molgen vae-train --data molgen/datasets/sample_smiles.smi --epochs 20 --out vae.pt

# Sample molecules near a seed by perturbing its latent.
molgen vae-sample --checkpoint vae.pt --seed-smiles "BrCC1CCCCC1" --num 100

# Walk the latent line between two molecules.
molgen vae-interpolate --checkpoint vae.pt --start "BrCC1CCCCC1" --end "BrCc1ccc[nH]1"
Each command also has a zero-config demo entry point that trains a tiny model on
the bundled dataset and runs end to end: python -m molgen.generate /
python -m molgen.interpolate.
Project structure
molgen/
├── chem.py              # validity / canonicalization / randomization (RDKit)
├── tokenizers.py        # atom-level regex SMILES tokenizer
├── selfies_tokenizer.py # SELFIES tokenizer (always-valid decoding)
├── data.py              # SmilesDataset, padding collate, augmentation, sample loader
├── synthetic.py         # synthetic dataset generators
├── vae.py               # Transformer β-TC-VAE
├── char_rnn.py          # GRU/LSTM language model
├── molgpt.py            # decoder-only Transformer
├── trainer.py           # AMP training loop
├── sampling.py          # temperature / top-k / top-p decoding
├── metrics.py           # validity, novelty, diversity, scaffolds, SNN, report
├── properties.py        # QED / logP / MW / SA score
├── checkpoint.py        # save & load model + tokenizer
├── cli.py               # `molgen` command-line interface
└── datasets/            # bundled sample SMILES
Notes
The bundled load_sample_smiles() set is synthetic (assembled from
fragments) and intended for examples and tests; for real results, train on a
dataset such as MOSES, QM9, or ZINC. SELFIES mode guarantees 100% validity;
SMILES mode tends to learn the data distribution more faithfully.
Contributing
Contributions are welcome — see CONTRIBUTING.md. Please run
ruff check ., ruff format ., and pytest before opening a pull request.
Citation
If you use this toolkit in your work, please cite it via the Cite this
repository button on GitHub (metadata in CITATION.cff).
License
This project is licensed under the MIT License. See LICENSE.
1 maintainer

Metadata
1 maintainer
Release files for molgen 0.2.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| molgen-0.2.0.tar.gz | 42.0 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| molgen-0.2.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 78.7 kB
Release files / molgen-0.2.0.tar.gz
| Download URL | molgen-0.2.0.tar.gz |
|---|---|
| Size | 42.0 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
f1c67b2456b1ef3d43de0889547d93964dd683432e9c468ac7f3b304f57aa75a
|
|
BLAKE2b-256 checksum How to use checksums |
a37dbe1ae69229801ca6409ca85645bfe483ef58dd60c364728c47fed4e12554
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.13.12
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Jul 11, 2026.
Transparency logRelease files / molgen-0.2.0-py3-none-any.whl
| Download URL | molgen-0.2.0-py3-none-any.whl |
|---|---|
| Size | 36.7 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
c10bd481beee7153472dd166672490896b43844e2fd9818a3345ff3abfdfddb8
|
|
BLAKE2b-256 checksum How to use checksums |
66f399bf00140021f19242cc1c415ac1f75549753e573b0da6c0de9755ebfead
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.13.12
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Jul 11, 2026.
Transparency log













