
⚜️ Moviola Protocol MCP
Grey is the ink. Motion is the message. Every cut is on the record.
An MCP server and CLI that convert any video or image format through the grey presets of the 1940s telecinema cutting room — NTSC-J seated black, one-bit Grey Ink, and a 90 fps collage that flashes sixteen instants per frame



👋 Welcome
You are welcome here, whatever you came for. If you want an MCP tool that
turns a two-hour recording into something an AI model can actually ingest,
start with Install — one uvx line, no checkout. If you train
models and you are counting bytes per frame across a billion-image corpus,
start with the training section: the arithmetic
is printed, including where our own early claims were wrong. And if you came
to check whether the numbers on this page are real, start with
Verify and try to falsify one — that is not tolerated
here, it is the point. There is an issue form for exactly that.
New here? The fastest path is to let your agent do it:
uvx --from https://github.com/Nova-Violet-Role/Moviola-Protocol-MCP/releases/download/v0.3.3/moviola_protocol_mcp-0.3.3-py3-none-any.whl moviola doctor
Exit 0 and a JSON block naming your ffmpeg, ffprobe and ffplay means
you are done installing. Everything after that is conversion.
📜 About
The Moviola Protocol is a rendering discipline, measured at the bench. Conventional video spends its bytes on 24-bit colour at frame rates chosen for human persistence of vision. A model does not need either. What it needs is structure: borders, subtitles, contours, text, the shape of change. The protocol keeps exactly that and executes the rest:
source -> fps -> NTSC-J range seat -> 8-bit grey -> edge relief
       -> [overcalc -> 1-bit threshold] -> [4x4 collage] -> 2-pass palette -> output
- Silent by construction. GIF carries no audio; neither does anything
else we emit (
-aneverywhere). The audio is not compressed — it is executed. - Black is seated first.
scale=in_range=limited:out_range=full(the NTSC-J seat) puts true black at 0 before a single colour is counted, so an 8-colour palette is a floor, not a hope. - Dither is off, always. Dither is noise wearing a costume; it multiplies frame differences and the byte count with them.
- No lore without numbers. Every dial in this README was cut and read from the mux report on real files. A null result killed its dial the same day (the event-gate that died that way is documented in the Tessersect section).
- The chronist speaks below. Every conversion is written to
moviola.dbwith its full argv before the tool returns, so the dimension change between any two files intertwined by the protocol can be evaluated at any time, by anyone, withsqlite3.
That is the artifact. It converts, it is measured, and the numbers on this page each have an exit code behind them.
The original papers the presets answer to — bench doctrine, master vision,
lightpaper, and two outside evaluations — live verbatim in
sources/, catalogued in reading order. Where they
disagree, the bench page wins; the folder says which page that is.
🔮 Premier — Symbiose, announced not shipped
Moviola is part of a larger system, and this is its premier as a stand-alone component. The system is Symbiose: one architecture in which models, routers, retrievers and sensors stop being separate programs bolted together and become organs of a single agnostic whole — dense and routed at once, retrieving by role, seeing in one-bit grey, remembering in ledgers. Pieces of it already ship on their own because each piece earned its release alone: RoT routes by role, RTR retrieves by role, and Moviola — this repository — is its eye.
The whole, Symbiose-OS, does not ship today, and this section will not pretend otherwise. It is too agnostic for humanity as it stands in 2026: indifferent to any single doctrine, vendor, model family or interface, in a decade that still wants its intelligence product-shaped and vendor-locked. Perhaps in forty years — call the horizon 2066 — a system that refuses every crown will read as obvious. Until then, (Saimonokuma), the Creator of Symbiose-OS, releases its parts as stand-alone components, each measured, each falsifiable, each free under copyleft, so that when the whole is finally assembled there will be nothing in it that was not already proven in the open. When Symbiose lands, the bench will be the announcement: same corpora, same meters, no adjectives. Until then this section is a promise, and promises are not results.
— Note of (Saimonokuma) the Creator: we released the eye first because an agnostic system must still answer for what it sees. Moviola's grey ink, its one-bit honesty about what changed and what did not, its ledger that remembers every cut — that is how Symbiose will look at the world when the world is ready to be looked at that way. Forty years is not a delay. It is a measurement we have not yet earned the right to shorten.
📽️ The 1940 reference — Holistic Tape
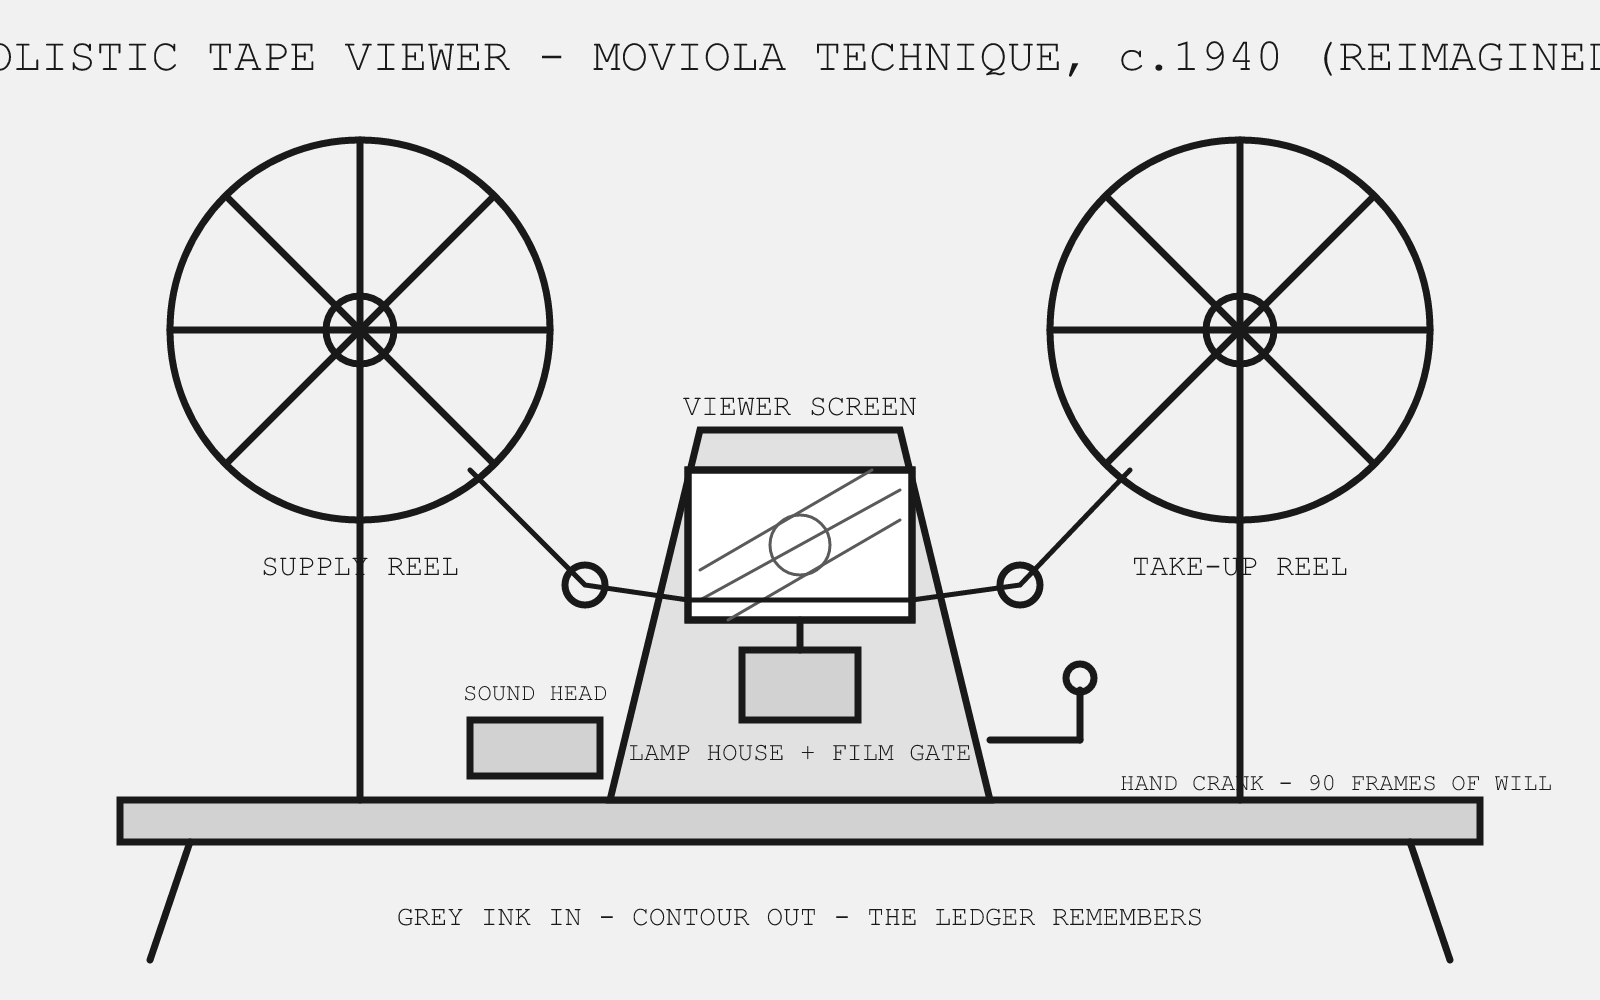
The name comes from a real machine and a real practice. The machine: the Moviola film editor (invented 1924 by Iwan Serrurier) ruled the cutting rooms of the 1930s–40s — two reels, a small viewing screen, a lamp house and a hand crank, one editor communing with the strip frame by frame. The practice: in the silent era the tape carried no sound at all, so the sound was a person — the benshi beside the screen in Japan, the lecturer, musicians and effects hands under the stage in the West, voicing and sounding everything the strip could not. And the strip itself was nitrate stock, which could quite literally burn in the projector gate under the lamp: a burned tape was not a metaphor in those booths, it was a Tuesday. Our bench doctrine keeps the memory in its first lines: "In the cutting rooms of the forties they cut monochrome stock, and under the stage a chronist spoke the parts the silent film could not carry." Holistic Tape is this project's name for that whole apparatus — silent grey strip plus the living voice under the theatre, picture and narration as one event — which is why every Moviola cut is silent by construction and its chronist, the index, speaks below in numbers. (For the record, one adjacent word kept honest: holography as a technique is Gabor, 1947, practical in the 1960s; nothing here claims a holographic projector in a 1940 booth — the holism was human.)
So we rendered it — an original schematic, drawn for this project, then cut through the very presets it illustrates. Standard first, at full width:
… and the same machine seen by the Canine Tessersect — the sensor its inventors would have needed and did not live to build:
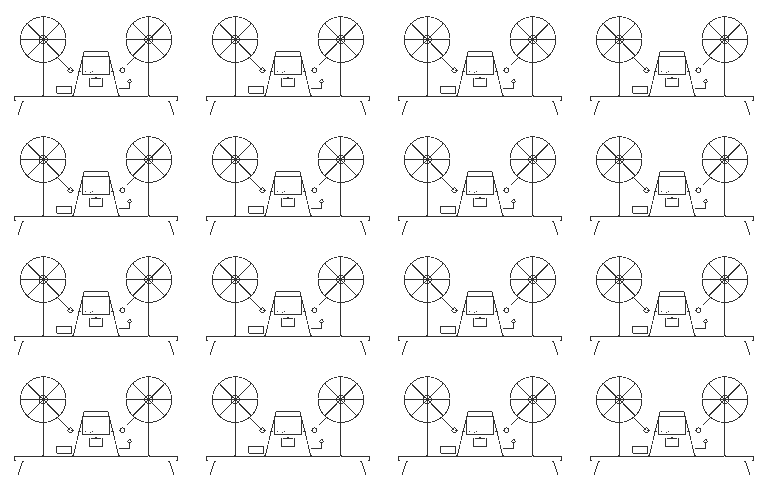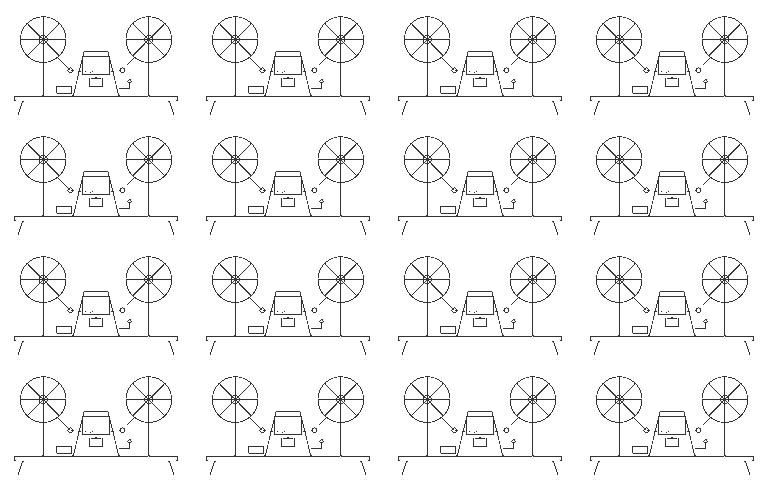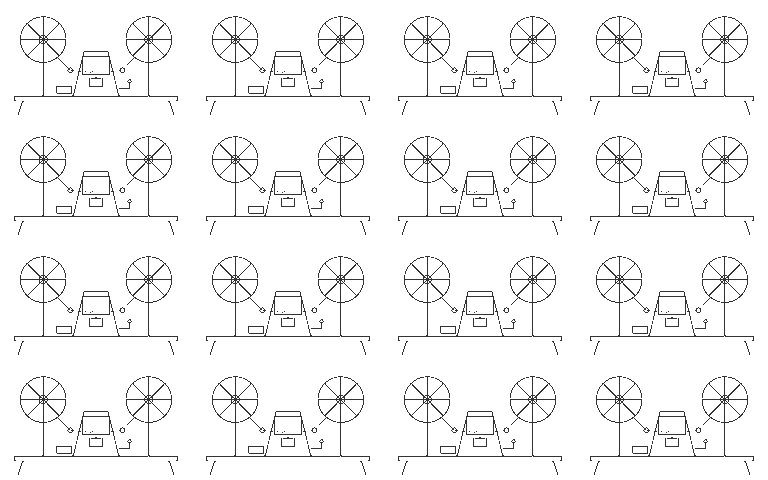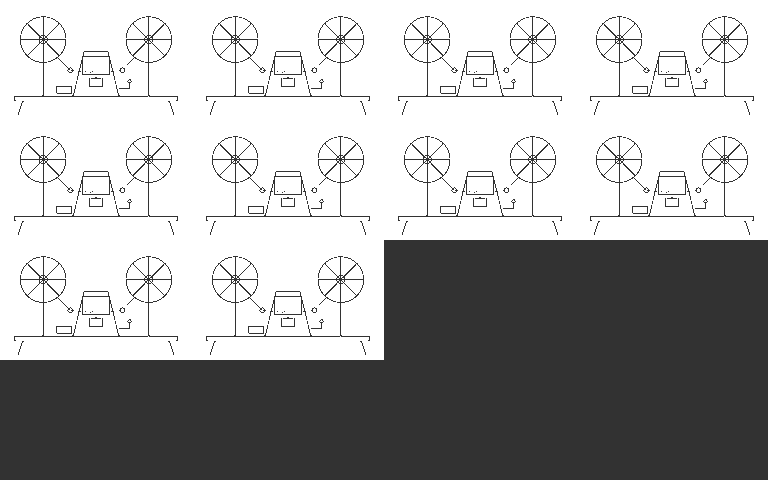
Source drawing 76,619 B → Standard 67,834 B · Intersect 37,882 B · Torch 18,459 B · Canine 20,978 B — renders in docs/holo/, regenerate from moviola-machine.svg
Every silent-era house already ran on Holistic Tape: a silent grey strip absorbing the audience at sixteen-to-twenty-four instants a second while a voice under the stage assembled the world around it. Moviola writes the tape the way that room always read it — contour and motion on the strip, the chronist speaking below in the ledger.
🎞️ Presets — thirty seconds each, see with your own eyes
One source, five renderings. The source is a 29.6 s, 1100×640, 10 fps screen recording (230,093 B mp4). Every GIF below is the direct, unretouched output of its printed command at full width — re-run one and compare bytes; a demo that does not reproduce is a failed demo. This is what each preset is, what to expect from it, and what it is for.
A · Standard Moviola — the evidence cut
The canonical bench rendering: NTSC-J seated black, 8-bit grey, greyedge relief to keep light on letters and borders, then an 8-colour two-pass palette with dither off. Expect: full resolution, soft 1940s-telecinema grey, text perfectly legible, motion smooth at 10–15 fps. For: evidence GIFs in issues, docs and chat — Proof-of-Work for the eyes.
189,882 B · 1100×640 · 10 fps · 296 frames · 641 B/frame
moviola convert doctor.mp4 doctor-standard.gif --preset standard
B · Moviola Intersect — the 1-bit Grey Ink
Everything Standard does, then the overcalc: luma stretched hard around mid-grey so faint edges, subtitles and contours cross the threshold into black, then a hard 1-bit cut. Two levels survive — black, and the grey ink (~192) that carries every border. Expect: a stark two-tone world where only information remains; gradients die, contours and text survive. For: subtitles, diagrams, UI, 3D edges, anything whose meaning lives in its outlines.
29,968 B · 1100×640 · 10 fps · 296 frames · 101 B/frame
moviola convert doctor.mp4 doctor-intersect.gif --preset intersect
C · Moviola Intersect Torch — the training torch
Intersect slowed to 5 fps and resized (360p default, 480p choosable, any ladder stage or DPI). Named for the projectionist's torch in the cutting room: just enough light to read the strip by. Expect: small, stark, deliberate frames — a documentary reduced to its readable skeleton. For: pre-training corpora, documentary archives, slide decks, anywhere a million frames must cost megabytes.
14,920 B · 618×360 · 5 fps · 148 frames · 101 B/frame
moviola convert doctor.mp4 doctor-torch.gif --preset torch
D · Canine Logic Moviola Tessersect — sixteen instants at once
Sampling at 90 fps in the canine flicker band, every instant cut to a 120-line 1-bit cell, sixteen cells collaged into one 4×4 tesseract-net frame, oldest top-left → newest bottom-right. Expect: a flashing contact-sheet of motion itself — read it left-to-right like time. For: training absorption at Intersect velocity: sixteen informational contents per ingested frame. Full doctrine in Canine Logic & the Tessersect.
65,525 B · 824×480 · 167 collages · 2,672 instants carried · 24.6 B/instant
moviola convert doctor.mp4 doctor-canine.gif --preset canine
Passthrough — what no discipline looks like
No Moviola filter at all: the same 30 seconds as a plain 256-colour GIF. Expect: colour, dither noise — and a file 2.5× larger than the video it came from. This row exists so the four above never have to ask for trust. (As a converter it still earns its keep: gif→mp4 with this preset is the OpenCode plugin transcode, pixel-faithful.)
578,695 B · 1100×640 · 10 fps · 296 frames · ratio 2.52× the source
moviola convert doctor.mp4 doctor-passthrough.gif --preset passthrough
Every characteristic, side by side
| Characteristic | A · Standard | B · Intersect | C · Torch | D · Canine Tessersect | Passthrough |
|---|---|---|---|---|---|
| Sampling | 10 fps (10–15) | 10 fps | 5 fps | 90 fps | source rate |
| Range seat | NTSC-J limited→full |
NTSC-J | NTSC-J | NTSC-J | — |
| Grey stage | format=gray (8-bit) |
grey + overcalc | grey + overcalc | grey + overcalc | — |
| Border stage | greyedge relief |
greyedge |
greyedge |
greyedge |
— |
| Bit depth out | 3 bits/pixel palette (8 colours) | 1 bit (2 levels) | 1 bit | 1 bit per cell | source |
| Measured levels | 7–8 greys | {0, 192} grey ink on black | {0, ~192} | {0, ~192} per cell | — |
| Resize | none | none | 360p (480p choosable, never upscales) | 120p cells, 4×4 collage | none |
| Information per output frame | 1 instant | 1 instant | 1 instant | 16 instants | 1 instant |
| Doctor clip bytes | 189,882 | 29,968 | 14,920 | 65,525 | container-dependent |
| Doctor byte rate | 6,415 B/s | 1,012 B/s | 504 B/s | 2,213 B/s (35 instants/s carried) | — |
| Bench tape bytes † | 154,362 | 49,159 | 32,653 | — | — |
| Ladder stages (p metric) | 1080·720·480·350·240·120 via --height |
same | same | cell heights, same grid | — |
| DPI at 10-inch reference | 192·128·85·62·43·21 via --dpi |
same | same | per-cell, same grid | — |
| TorchPy instances per source frame | 1 frame tensor | 1 frame tensor | 1 frame tensor | 1 collage tensor, or 16 cell tensors unpacked | 1 frame tensor |
| Dataset source filter | preset="standard" |
preset="intersect" |
preset="torch" |
preset="canine" |
preset="passthrough" |
| Built for | evidence GIFs, docs, chat | subtitles, borders, contours, 3D edges | pre-training slideshows, documentaries | training absorption, Intersect-style flash corpora | plain format change, gif→mp4 for models |
† Bench tape: 706×264, 5 s, 569,469 B HEVC mp4 — the MOVIOLA-PROTOCOL.md
reference-ladder tape. Standard reproduces its published 166 KB canonical
floor within generation loss (their source was the .tape render; ours is
one transcode further away).
The exact filter chains
Nothing here is a secret sauce; moviola presets prints these verbatim.
A  fps=10,scale=in_range=limited:out_range=full,format=gray,greyedge
   + palettegen=max_colors=8 / paletteuse=dither=none            (GIF)

B  fps=10,scale=...:..,format=gray,greyedge,format=gray,
   curves=all='0/0 0.30/0.02 0.5/0.5 0.70/0.98 1/1',
   lut=y='if(gt(val,128),255,0)',format=gray
   + palettegen=max_colors=2:reserve_transparent=0              (GIF)

C  B with fps=5 and scale=-2:'min(360,ih)'   (480 choosable; never upscales)

D  fps=90,scale=-2:'min(120,ih)':..,format=gray,greyedge,format=gray,
   curves=all='...',lut=y='...',format=gray,tile=4x4
   + palettegen=max_colors=2:reserve_transparent=0              (GIF)
The overcalc curve is the heart of B, C and D: luma is stretched hard around mid-grey before the 1-bit threshold, so a faint subtitle edge or a hairline contour — the pixels a flat threshold would discard — crosses into black. Grey is overcalculated precisely so that black lands where the information is.
📐 The numbers, honestly
This project began with a claim: a 1 h 50 m video under 5 MB with Preset A, under 3 MB with Preset B. On animated screen content, measured rates say otherwise, and the correction is printed here rather than quietly edited:
| Preset | Measured rate (doctor clip) | 1 h 50 m at that rate | Verdict on the early claim |
|---|---|---|---|
| A · Standard | 6,415 B/s | ≈ 42 MB | ❌ not at 1100×640 animated content |
| B · Intersect | 1,012 B/s | ≈ 6.7 MB | ❌ close, not under 3 MB |
| C · Torch 360p | 504 B/s | ≈ 3.3 MB | ≈ the B claim, one preset down |
| D · Tessersect | 2,213 B/s carrying 35 instants/s | ≈ 14.6 MB | density, not minimal bytes |
Where the claims do hold: near-static content — slides, lectures, terminal recordings, talking heads. A static Torch frame measured ~100 B (14,920 B over 148 frames, most of them changed; unchanged runs compress far harder). Content that changes every frame at 1100×640 is the worst case this protocol will ever meet, and it is the case we chose to publish. Your index will tell you your own rates within one conversion; believe those.
⚖️ Method — Reality is the judge. Every number above is meant to be re-run by you. If one of them is wrong on your machine, telling us is the most welcome contribution we accept, and there is an issue form for it.
🪜 The scaling ladder — DPI and p, stage by stage, in GIF
Resolution is a choice, and it has two honest names: lines (the p
metric) and DPI (pixels per inch at a stated reference size — here a
10-inch display width, always printed beside the number). The ladder
below walks one true-1080p text/code-rich source (generated, 12 s,
284,020 B) down every stage in three variants. Each GIF steps through
its stages on one canvas, small stages neighbor-upscaled so the pixel
growth is visible; the bytes in the tables are the direct first-pass
cuts from the index, never the labeled presentation GIFs. Regenerate
everything with uv run python scripts/build_ladder.py.
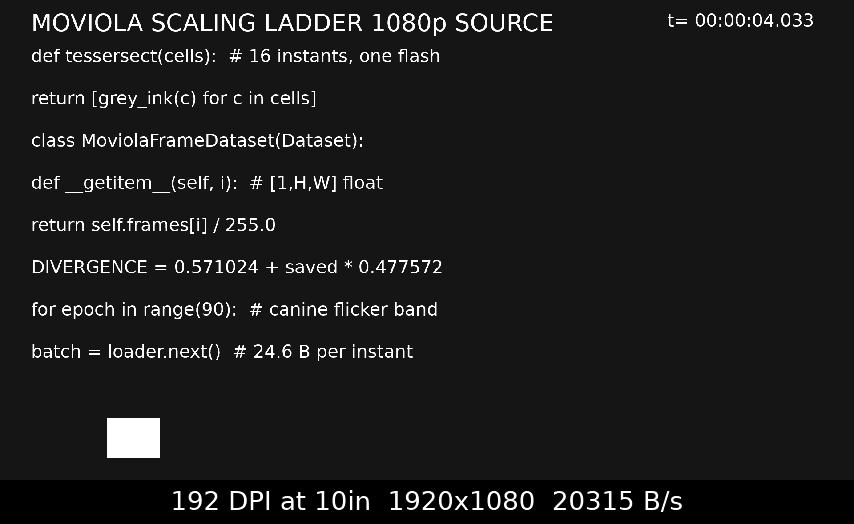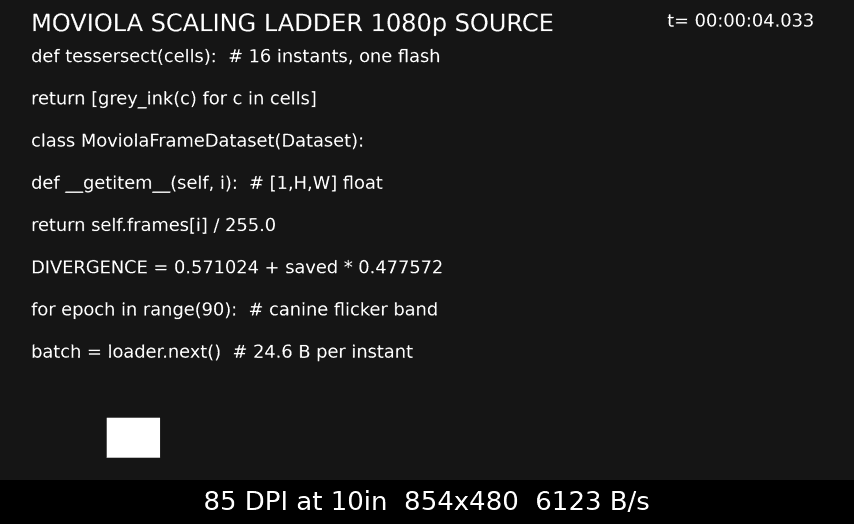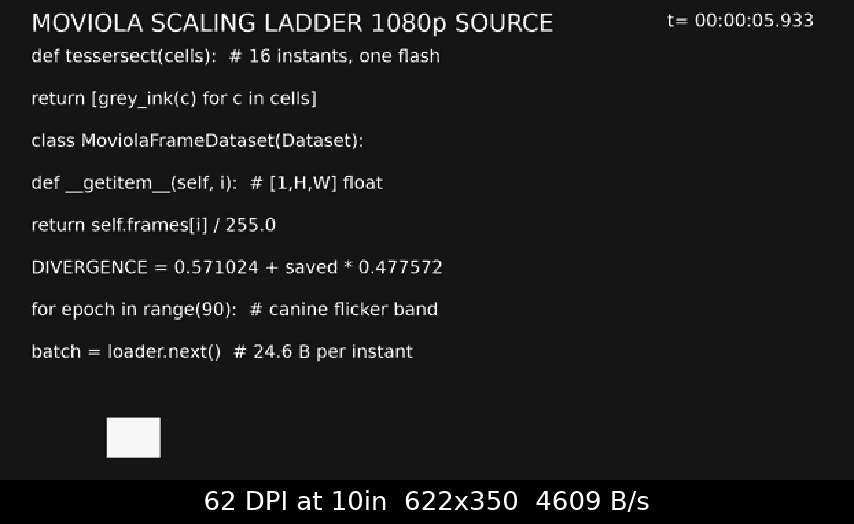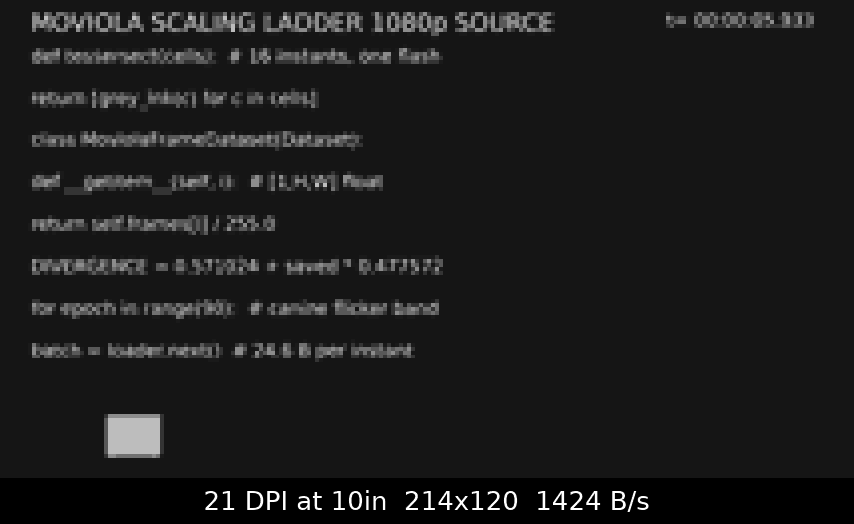
V1 · DPI metric — Standard preset, stages chosen --dpi at a 10-inch
reference width (192 → 128 → 85 → 62 → 43 → 21 DPI). Watch the grey
levels hold legibility long after the pixel grid turns coarse:
V2 · p resolution — Intersect preset, stages chosen --height
(1080p → 720p → 480p → 350p → 240p → 120p). One bit survives every
stage; only the cell size grows:
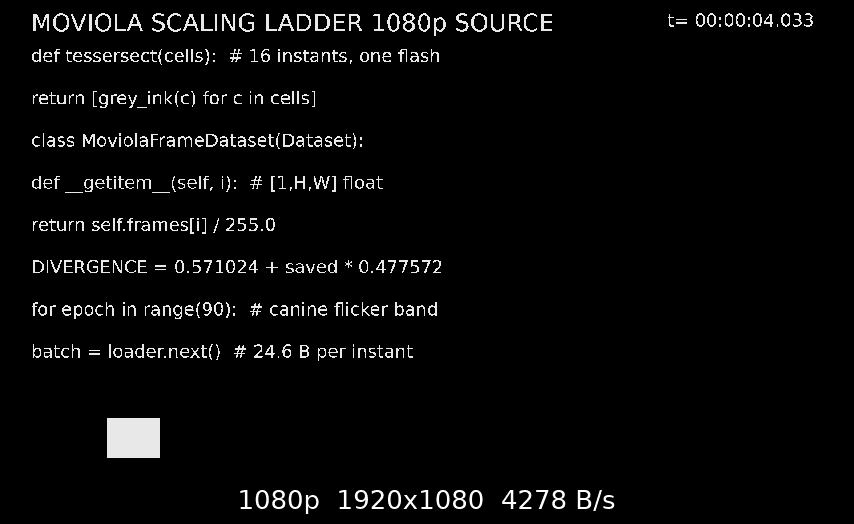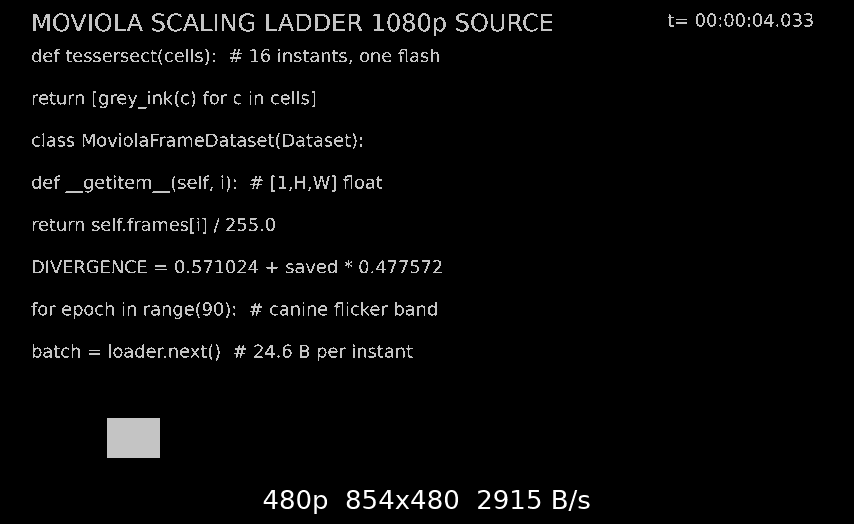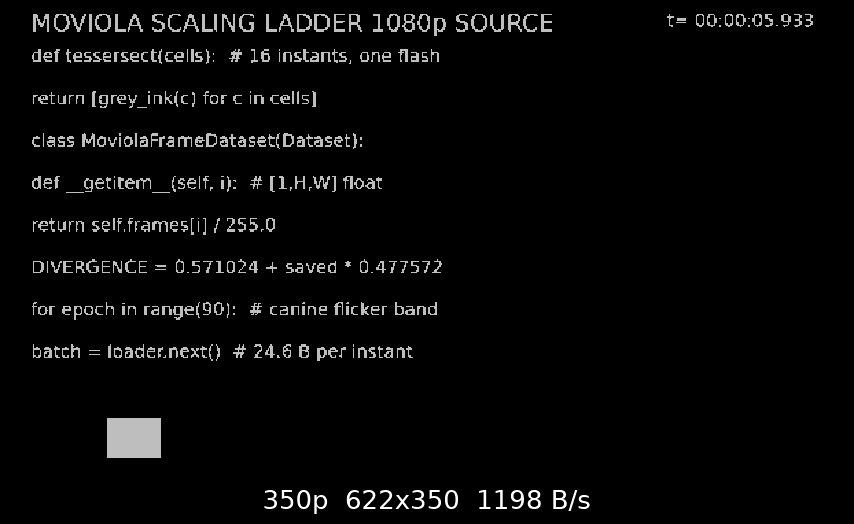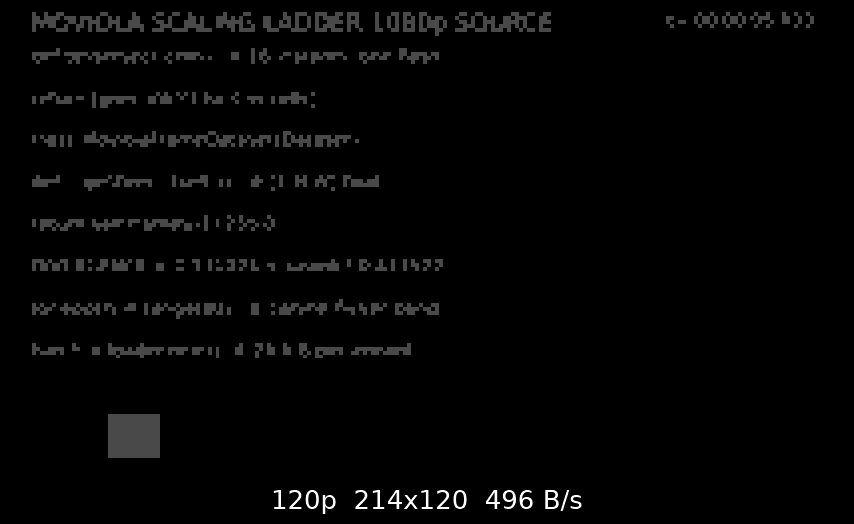
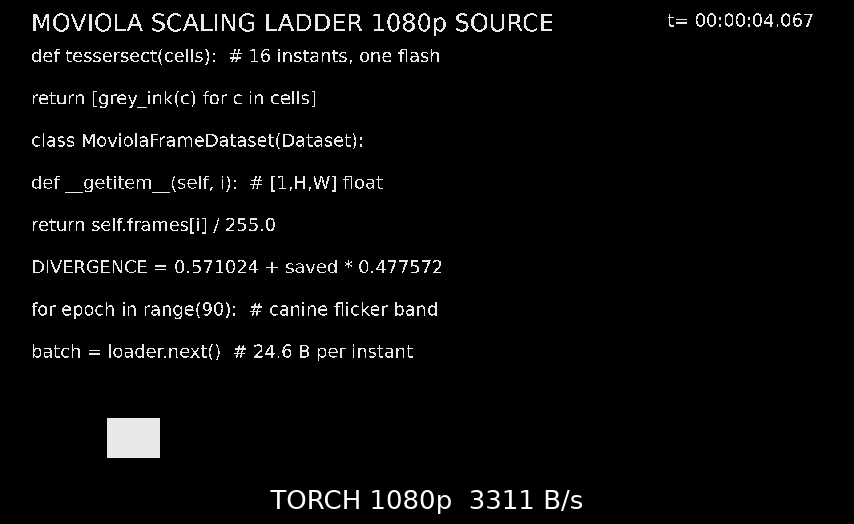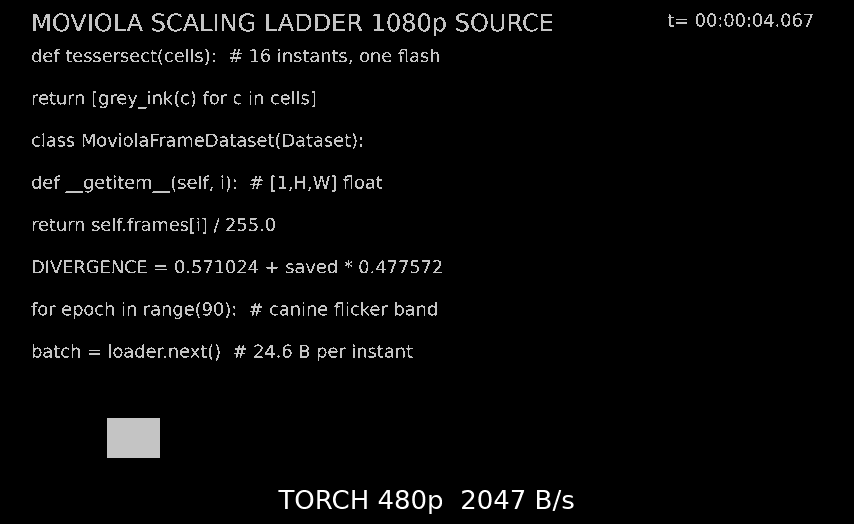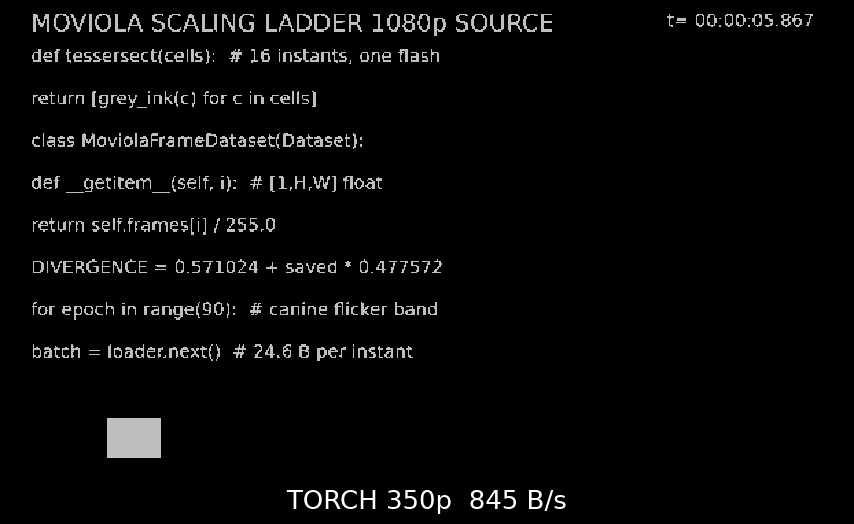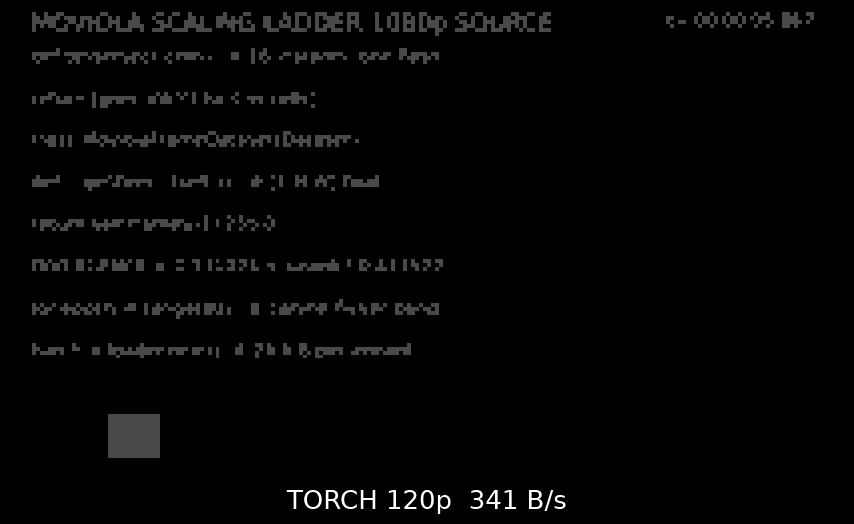
V3 · Torch — 1-bit at 5 fps on the same stages: the training cut. At 120p this source family runs 341 B/s — a 1 h 50 m documentary in roughly 2.25 MB:
| Stage | DPI @10in | V1 Standard B/s → 1 h 50 m | V2 Intersect B/s → 1 h 50 m | V3 Torch B/s → 1 h 50 m |
|---|---|---|---|---|
| Original 1080p | 192 | 20,315 → 134.1 MB | 4,278 → 28.2 MB | 3,311 → 21.9 MB |
| 720p | 128 | 10,849 → 71.6 MB | 7,593 → 50.1 MB * | 3,961 → 26.1 MB * |
| 480p | 85 | 6,123 → 40.4 MB | 2,915 → 19.2 MB | 2,047 → 13.5 MB |
| 350p | 62 | 4,609 → 30.4 MB | 1,198 → 7.9 MB | 845 → 5.6 MB |
| 240p | 43 | 2,728 → 18.0 MB | 762 → 5.0 MB | 530 → 3.5 MB |
| 120p | 21 | 1,424 → 9.4 MB | 496 → 3.3 MB | 341 → 2.25 MB |
* The 720p anomaly, published not smoothed: under the 1-bit presets, 720p costs more than native 1080p on this source. The mechanism is reasoned, labelled as such: at native size the synthetic text edges are already crisp two-level shapes and the threshold is nearly free; the 720p downscale first paints intermediate greys along every edge, and overcalc-then-threshold turns that halo into speckle the GIF encoder must spell out. By 480p the speckle merges and the ladder turns monotonic again. A dial that misbehaves at one stage is information, and it stays in the table.
The claim this ladder earns, stated exactly: with resolution chosen in DPI or p metrics, Moviola reaches the culmination point for Image/Video/Slide training corpora — sub-5 MB and sub-3 MB long-form cuts at named stages (doctor clip: Standard @216p → 4.73 MB, Torch @270p → 2.64 MB per 1 h 50 m; synthetic 1080p source: Torch @120p → 2.25 MB), 16-instant Tessersect collages for flash absorption, and a first-class PyTorch/JAX dataset bridge reading all of it back. Not at native resolution, not by magic — by choosing the stage, in the open, with the meter running.
🚀 Install
Requirements
| Need | Why | How we find it |
|---|---|---|
| uv | runs the wheel with uvx, no venv to manage |
your package manager |
| ffmpeg + ffprobe | every conversion and probe (ffplay reported, not required) |
MOVIOLA_FFMPEG_DIR → FFMPEG_PATH → C:\Hybrid\64bit → PATH |
| Python ≥ 3.10 | only if you install the library yourself; uvx brings its own |
— |
The C:\Hybrid\64bit probe is this project's house install (ffmpeg
N-123549, a full GPL build with greyedge, morpho, palettegen — all
verified present). Any full ffmpeg build on PATH works identically;
moviola doctor prints the searched locations and the winner, so a wrong
binary is a visible fact, not a mystery.
Three ways in
# 1. From PyPI (live since 0.3.0)
uvx moviola-protocol-mcp

# 2. From the GitHub release wheel
uvx --from https://github.com/Nova-Violet-Role/Moviola-Protocol-MCP/releases/download/v0.3.3/moviola_protocol_mcp-0.3.3-py3-none-any.whl moviola-protocol-mcp

# 3. Straight from the repository
uvx --from git+https://github.com/Nova-Violet-Role/Moviola-Protocol-MCP moviola-protocol-mcp
For development: git clone, then uv sync, uv run pytest (41 tests),
uv run moviola doctor. Training extras install separately:
pip install 'moviola-protocol-mcp[torch]' (or [jax], [maxtext],
[unsloth]).
🕹️ MCP tools — every tool, every argument
Transport: stdio. Architecture: traditional flat tools — eleven fixed operations, each with a declared JSON schema, no discovery layer to drift. Register it anywhere MCP speaks:
{
  "mcpServers": {
    "moviola": {
      "command": "uvx",
      "args": ["moviola-protocol-mcp"],
      "env": { "MOVIOLA_FFMPEG_DIR": "C:\\Hybrid\\64bit", "MOVIOLA_DB": "D:\\media\\moviola.db" }
    }
  }
}
convert_media
Any video/image → the format named by the output extension. The preset shapes the pixels; the extension chooses the container.
| Argument | Type | Default | Meaning |
|---|---|---|---|
source |
string | — | input path (any ffmpeg-readable format) |
output |
string | — | output path; extension picks gif/mp4/webm/webp/png/jpg/… |
preset |
string | "standard" |
standard·intersect·torch·canine·passthrough (aliases a–d, tessersect) |
fps |
int|null | preset's | sampling rate (Standard accepts 10–15; Tessersect cell velocity) |
height |
int|null | preset's | ladder stage in lines (p metric); Torch 360/480; Tessersect cell height (120); never upscales |
dpi |
float|null | null | ladder stage in DPI (pixels per inch at reference_width_inches); refused together with height — two names for one choice |
reference_width_inches |
float | 10.0 | the display width the DPI number is stated against, always printed with it |
crf |
int | 23 | x264 quality for mp4-family outputs (plugin parity) |
db_path |
string|null | ./moviola.db |
index location (MOVIOLA_DB if set) |
ffmpeg_dir |
string|null | auto | directory holding the trio |
timeout_seconds |
int | 7200 | hard ceiling; expiry is a named error, recorded in the index |
Returns: {id, source, source_bytes, output, output_bytes, preset, fps, height, ratio, bytes_saved, db_path, ffmpeg, command} — the exact argv is
in the result and in the index row. Reverse direction included:
gif → mp4 with preset="passthrough" reproduces the OpenCode plugin
transcode (libx264, crf 23, yuv420p, faststart, silent), plus an
even-dimension pad the plugin lacks — visible only on odd-sized inputs,
where the plugin version fails and this one does not.
slideshow_from_images
Ordered PNG/JPG set → one gif/mp4/webp slideshow.
| Argument | Type | Default | Meaning |
|---|---|---|---|
images |
list[string] | — | image paths, in presentation order |
output |
string | — | output path |
preset |
string | "torch" |
as above; with canine, each image is one collage cell |
seconds_per_image |
float | 1.0 | hold per image (Torch pre-training form: 0.2 ⇒ 5 img/s) |
fps, height, dpi, reference_width_inches, db_path, ffmpeg_dir, timeout_seconds |
— | — | as in convert_media |
Returns the conversion result plus {images, seconds_per_image} (the
effective cell duration under Tessersect, 1/(fps or 90)).
probe_media
{path, ffmpeg_dir?} → {path, bytes, format, width, height, fps, duration, codec, frames} from ffprobe. Missing ffprobe degrades to
size-only facts, named as such — silence is never dressed as health.
list_presets
No arguments → the five presets with summaries, defaults and the exact filter-chain strings, straight from the code that runs them.
doctor
{ffmpeg_dir?} → {ffmpeg, ffprobe, ffplay, searched, ffmpeg_version}.
First thing to run on a new machine; first thing to paste into a bug report.
index_history · index_stats · index_chains
Read the ledger. index_history {limit=50, preset?, db_path?} newest
first, sizes included. index_stats {db_path?} per-preset conversions,
bytes in/out, mean ratio. index_chains {db_path?} the intertwined files:
every conversion whose source was itself an earlier output, parent and
child side by side — the dimension-change audit trail this project exists
to keep.
install_opencode_plugin
{target_dir?, plugin_format="mjs", include_read_tool=true, force=false} →
copies the bundled gif-as-mp4 plugin (and, unless declined, the portable
read tool) into an OpenCode config directory. See
The OpenCode plugin.
training_backends
No arguments → the measured training landscape of this host: torch
(ROCm/HIP or CUDA builds named apart), JAX devices, AITER, jax-aiter,
Primus + primus-cli, TorchTitan, Megatron-LM, MaxText, Unsloth —
installed or not, each with its install line and its exact Moviola
interop format. Detection only; nothing is downloaded. On a Windows
RDNA2 host it says plainly that ROCm does not run there.
export_training_data
{sources, out, format="webdataset", height?, dpi?, reference_width_inches=10, max_samples_per_shard=1000, instruction, ffmpeg_dir?, timeout_seconds} → one dispatch to every layout:
image-folder (TorchTitan/torchvision), webdataset (one tar),
datacenter-shards (Primus/Megatron-Energon numbered shards +
manifest), arrayrecord (JAX MaxText/Grain), unsloth (vision-SFT
train.jsonl + images). Sources are files or folders of any
ffmpeg-decodable filetype; height/dpi cut at a ladder stage.
💻 CLI — the same core, no server
moviola convert lecture.mp4 lecture.gif --preset standard --fps 12
moviola convert lecture.mp4 lecture-torch.gif --preset torch --height 480
moviola convert lecture.mp4 lecture-216p.gif --preset standard --dpi 38
moviola convert lecture.mp4 lecture-tessersect.gif --preset canine
moviola convert frames.gif frames.mp4 --preset passthrough
moviola convert still.png still-grey.jpg --preset intersect
moviola slideshow slide*.png deck-torch.gif --preset torch --seconds 0.2
moviola slideshow slide*.png deck-tessersect.gif --preset canine
moviola probe lecture.mp4
moviola presets
moviola doctor
moviola history --preset canine --limit 10
moviola stats
moviola chains
moviola backends
moviola export-dataset lecture.gif shards/ --format datacenter-shards --height 240
moviola export-dataset slides/ deck/ --format unsloth --dpi 43
moviola install-plugin --target ~/.config/opencode
moviola flash
Every verb accepts --db PATH and --ffmpeg-dir PATH, prints JSON, and
exits nonzero with the failure named on stderr. Well — every verb but one.
moviola flash prints something else. See the Easter Egg.
🗄️ The index — moviola.db, always seeable
One SQLite file, default ./moviola.db in the working directory
(MOVIOLA_DB overrides). One row per conversion, success or failure,
written before the tool returns:
| Column group | Columns |
|---|---|
| When | id, created_at (UTC ISO-8601) |
| Source | source_path, source_bytes, source_format, source_width, source_height, source_fps, source_duration |
| Output | output_path, output_bytes, output_format, output_width, output_height, output_fps |
| The cut | preset, height, ratio, bytes_saved, ffmpeg_path, command (full argv, JSON) |
| The verdict | status (ok/error), error |
Query it with anything:
sqlite3 moviola.db "SELECT preset, COUNT(*), SUM(source_bytes), SUM(output_bytes)
FROM conversions WHERE status='ok' GROUP BY preset;"
Files intertwined by the protocol — a Torch GIF fed back in to become
an mp4, a Standard GIF re-cut under Tessersect — are joinable in one
query, and index_chains is exactly that join. Dimension change across a
whole lineage stops being folklore and becomes a SELECT.
🐕 Canine Logic & the Tessersect
The Moviola papers in sources/ describe a "Canine-Logic" sensor:
1-bit sparse matrices, delta-motion only, kinetic frequency above 90 fps —
the Dynamic Vision Sensor (DVS) reading of how a dog actually sees:
dichromatic, rod-dominated, acuity-poor, motion-rich, with a flicker
fusion threshold near 70–90 Hz where a human's saturates around 60. A dog
watching your 24 fps video sees a slideshow. A dog watching the world
sees the deltas.
Preset D, the Canine Logic Moviola Tessersect is that description as an ffmpeg chain, built for machines rather than retinas:
- Sample at 90 fps — the top of the canine flicker band, the paper's +90fps kinetic frequency, and (not coincidentally) Intersect velocity.
- Cut every instant to a 120-line 1-bit Grey-Ink cell — NTSC-J seat, greyedge relief, overcalc curve, hard threshold. Two levels survive: black, and the grey ink at ~192 that carries every border, subtitle and contour.
- Collage sixteen consecutive cells into one 4×4 tesseract net, oldest top-left → newest bottom-right. One output frame = sixteen informational contents, the way Chuck's Intersect encodes a database as a flashing wall of images for instant absorption. (The name is the wordplay owned outright: Tessersect = tesseract × Intersect.)
What this buys a training pipeline: a vision model that ingests frames as tokens absorbs 16 instants per frame at 824×480 for a 1100×640 source — temporal density a frame-sampler would need sixteen separate ingestions to match, at 65,525 B for 29.6 s of animated content. And two honest limits, measured while building it:
- Cells hold state on slow sources.
fps=90over a 10 fps source repeats each instant ~9 times across cells — the 1-bit sensor watching a slower world, exactly as the paper's DVS holds state between events. Feed it a true 90+ fps capture and every cell is a distinct instant. - An event gate was tried and killed. Dropping near-duplicate cells
with
mpdecimatecollapsed the doctor clip to a single collage frame: at 120 lines, small-but-dense text changes fall under its changed-block fraction. Tessersect therefore keeps every sampled instant. A dial that erases the information it was built to carry does not ship.
For slideshows, images are the cells: sixteen slides per collage
frame, cell duration 1/90 s at flash velocity — a thousand-slide corpus
deck becomes 63 collage frames.
🎓 HOW TO TRAIN with Moviola — the Special Datasets Philosophy
This MCP is built as much for dataset builders as for developers. Its training doctrine — the Special Datasets Philosophy — is six rules, each one enforced by a mechanism in this repository rather than by taste:
- Information density over pixel fidelity. A training instance is worth its borders, text, contours and motion — the things the 1-bit Grey Ink keeps — not its colour gradients. Measure bytes per instant of information, not per frame of decoration.
- Resolution is chosen, in DPI or p, per task — never max by default. A subtitle needs 240p; a viseme needs a cropped 240p at 90 fps; a glacier needs 120p and patience. The ladder exists so the choice is a number with a price tag.
- Every file carries its lineage. Source hash, preset, stage,
argv and byte counts live in
moviola.db; intertwined files chain. A dataset you cannot audit is folklore. - Budgets are witnessed, not promised. Rates come from indexed cuts and the witness bench; extrapolations are labeled with their formula.
- Form is kept, appearance is discarded. Grey and 1-bit cuts preserve action, shape and text while shedding identity-rich colour detail — useful far beyond size (see medicine, security).
- Formats are training-native. The same cut exports to torch tensors, JAX arrays, image folders, WebDataset/Energon shards, ArrayRecord and Unsloth SFT rows without a transcode detour.
The five-step pipeline, every time:
moviola convert source.mp4 corpus.gif --preset torch --height 240   # 1 cut
moviola stats                                                        # 2 read the ledger
moviola export-dataset corpus.gif shards/ --format datacenter-shards # 3 export
moviola backends                                                     # 4 check the stack
uv run python scripts/demo_torch_dataset.py moviola.db               # 5 iterate it
Documentary → laptop-scale corpus. convert_media with torch
(default 360p, 5 fps, 1-bit). At the doctor clip's worst-case 504 B/s, a
1 h 50 m source is ~3.3 MB; lecture-style content with static frames
measures ~100 B/frame, i.e. ~1.8 MB per hour at 5 fps. Subtitles survive:
that is what the overcalc curve is for.
Billion-image pre-training, honestly. At a measured ~100 B per static
Torch frame, 10⁹ frames ≈ 100 GB as monolithic GIF streams — and GIF is
the honest ceiling: shard by source (one file per lecture/deck), never one
file per corpus. With Tessersect, the same billion instants pack 16
per frame: ~6.25×10⁷ collage frames. At the doctor clip's 392 B per
collage (65,525 B / 167), that is ~24 GB carrying a billion instants —
for animated content. Static informational slides (code, text, diagrams)
measure far below both anchors. Run one conversion, read your own
bytes_saved, multiply. The index is your dataset card's evidence table.
Slideshow decks as flash corpora. slideshow_from_images with
canine turns an ordered folder of PNG/JPG (screenshots, code pages,
document scans) into Tessersect flash frames at 90 cells/s ingestion
velocity. Pair with index_stats to report exactly what the corpus cost.
Cross-domain atlas — where this format profits, camp by camp
Each row names the instance, the cut, and the measured property of the format doing the work. Downstream accuracy on any of these is the falsifiable experiment the format invites — we measured the format, and say so.
| Camp / sector | Training instance | Moviola cut | Why it profits (measured property) |
|---|---|---|---|
| 💻 Code & software | IDE/terminal recordings, bug repros, code-review walkthroughs | Torch @350p or Tessersect slideshow of code pages | text survives 1-bit overcalc at ~101 B/frame; 16 screens per collage token |
| 👄 Labial language & speech | lip-reading (viseme) corpora, pronunciation tutors | Standard or Intersect on a mouth-ROI crop; Tessersect as a 16-instant viseme transition strip | greyedge relief is literally lip contour; a collage frame is a viseme sequence in one token |
| 🤟 Sign language | signer recordings, fingerspelling at speed | Intersect native fps; Canine for transition strips | hand/face contours are the signal; background and clothing colour are noise the cut removes |
| 🎬 Documentaries (subtitled) | subtitle-aligned understanding, chaptering, summarisation | Torch @360/240p | overcalc exists to push subtitle edges into black; ~2–3 MB per feature-length film at low stages |
| 🔬 Biology — microscopy | cell division, motility, colony growth timelapse | Standard/Intersect, stage by DPI of the optics | phase-contrast is already grey; motion deltas are the phenotype; days of timelapse fit in MB |
| 🐾 Biology — ethology | wildlife cams, lab animal behaviour, wing-beat analysis | Canine (90 fps band), Torch for archives | the preset was designed on the canine sensor model: motion first, appearance discarded |
| 🌱 Agriculture | crop growth, pest traps, livestock gait & feeding | Torch @120–240p | solar/field cameras on thin links: 341 B/s worst-case measured is satellite-friendly |
| 🪨 Geology | glacier/erosion timelapse, strata & core-sample photography, volcano cams | Intersect (strata lines are contours), slideshow decks for cores | contour emphasis is the geological signal; 120p stages archive years of timelapse |
| 🩺 Medicine | ultrasound & endoscopy teaching sets, gait labs, surgical gesture | Standard (8-bit keeps intra-tissue shading) | ultrasound is born grey; 1-bit variants abstract identity while keeping motion — de-identification as a side effect, to validate per use |
| 🔭 Astronomy | meteor/all-sky cameras, variable-star & transient hunts | Intersect/Canine | a transient is a delta against black; the format stores almost nothing else |
| 🏭 Industry | weld-arc monitoring, assembly verification, vibration made visible | Canine 90 fps cells | high-frequency events survive sampling that 25 fps corpora alias away |
| 🤖 Robotics & edge AI | drone/warehouse contour navigation, low-bandwidth telemetry previews | Torch/Canine at 120–240p | obstacle contours at ~25 B/instant ride links video cannot |
| 🏅 Sport & movement | technique biomechanics, dance notation, instrument fingering (piano/violin hands) | Canine strips; Standard for fine hand detail | 16-instant collages turn a gesture phrase into one training token |
| 🎓 Education | lectures, whiteboard capture, handwriting stroke order | Torch; slideshows for boards | whiteboard ink is a 1-bit signal already; ~1.8 MB per lecture-hour measured class |
| 🌍 Environment | river/fire/weather cams, ocean buoys, disaster-field feeds | Torch @120p | the kilobaud link is the dataset constraint; this format was priced for it |
| 🚗 Automotive | dashcam event archives, driver-attention contours | Intersect @350/240p | events kept, plates/faces abstracted by the cut (validate per jurisdiction) |
| 🏗️ Construction | site progress timelapse, crack & deformation monitoring | Intersect | a crack is a contour that grows; the ledger timestamps every cut of it |
| 🧪 Physical sciences | crystallisation, fluid fronts, oscillation & reaction timelapse | Standard/Canine by rate | density fronts read in grey levels; fast periodic motion needs the 90 fps band |
| 🛰️ Space & remote sensing | downlink-constrained preview imagery, ground-station triage | Torch @120p | when downlink is priced per byte, 341 B/s full-motion preview is a capability, not a compromise |
| 🏛️ Archives & restoration | historical film pre-visualisation, archive search proxies | Standard @480p+ | a searchable grey proxy of a whole archive at ~1% of mezzanine cost |
Worked recipe — labial language (viseme strips)
# 1) crop the mouth region first (ffmpeg) - resolution belongs to the lips
ffmpeg -i speaker.mp4 -vf "crop=iw/3:ih/3:(iw-iw/3)/2:ih/2" mouth.mp4
# 2a) outer-lip contour corpus (1-bit)
moviola convert mouth.mp4 visemes.gif --preset intersect --height 240
# 2b) viseme transition strips: 16 instants per training token
moviola convert mouth.mp4 viseme-strips.gif --preset canine
# 3) cells back out as instances when the model wants them single
#    MoviolaFrameDataset(..., unpack_collage=True)  -> 16 per collage
Honest trade-off, printed: intra-oral detail (tongue, teeth shading) wants Standard's 8-bit grey; outer-lip contour is where Intersect wins. Choose per annotation goal, and let downstream accuracy — measured by you, on your split — arbitrate.
Worked recipe — subtitled documentaries
moviola convert film.mp4 film-torch.gif --preset torch --height 240
moviola export-dataset film-torch.gif film-shards/ --format datacenter-shards
Pair each shard's .json (source + frame index) with the film's
subtitle track by timestamp (frame / fps from probe_media) and
the corpus aligns itself: frame, subtitle line, provenance — at
roughly 400–500 B/s of film on animated content (doctor-clip rate),
far less on talking-head footage.
Worked recipe — tomes, big-page books, medical atlases, whole libraries
A book is a slideshow that already knows its order. Big dense pages — anatomy atlases, surgical and pharmacology tomes, engineering handbooks, manuscripts, sheet-music folios — are the format's home ground: page after page of text, plates and contour line-art, which is exactly what Grey Ink was cut for. Measured on generated dense-text A4 pages (1240×1754, ~314 KB PNG each; reproduce the bench from the commands below):
| Form | Per page | 1,000-page tome | 10⁷ pages (a library) |
|---|---|---|---|
| Source PNG scan | ~314,000 B | 314 MB | 3.14 TB |
| Standard slideshow | 25,903 B | 25.9 MB | 259 GB |
| Torch slideshow | 1,690 B | 1.69 MB | 16.9 GB |
| Canine Tessersect deck | 331 B | 0.33 MB | 3.3 GB |
# one tome, Torch training cut (pages in reading order)
moviola slideshow atlas/page-*.png atlas-torch.gif --preset torch
# the same tome as flash cells: 16 pages ride in every collage frame
moviola slideshow atlas/page-*.png atlas-flash.gif --preset canine
# shards for the cluster, or SFT rows for a vision model
moviola export-dataset atlas/ shards/ --format datacenter-shards
moviola export-dataset atlas/ unsloth/ --format unsloth \
  --instruction "Transcribe and explain this atlas plate."
That is the "almost indefinite" scaling stated precisely: cost grows linearly at hundreds of bytes per page, so corpus size stops being the constraint long before library size does — a billion-page archive extrapolates to ~331 GB in Tessersect form on this page family (arithmetic from the measured 331 B/page; noisy real-world scans will cost more, and your index will tell you how much on the first tome). Medicine is the flagship case: anatomy plates, radiology teaching files and surgical atlases are contour-and-text documents whose training value survives 1-bit intact, at three orders of magnitude under their scan weight.
Worked recipe — biology & geology timelapse
# a season of field stills becomes one flash deck, then shards
moviola slideshow field/*.jpg season.gif --preset canine
moviola export-dataset season.gif season-shards/ --format webdataset
Growth, erosion and strata are contour stories told slowly; the Tessersect deck compresses the telling without touching the story: 16 observation days ride in every ingested frame.
How Moviola redefines the training world, claimed precisely: datasets stop being maximal-fidelity dumps priced in terabytes and become measured informational cuts — resolution chosen in DPI or p per task, bytes witnessed per instant, lineage in a ledger, and 16 instants flashing per token where time itself is the signal. That redefinition is shipped and measured above. What it does to any given model's accuracy is the experiment this format exists to make cheap enough to run.
TorchPy — one Dataset, every framework, no NVIDIA required
moviola_protocol_mcp.torch_data.MoviolaFrameDataset is a plain
torch.utils.data.Dataset of [1,H,W] float tensors, ladder-native:
ladder_stage=240 (or height=, or dpi= at a reference width) cuts
every instance at that stage, unpack_collage=True turns each
Tessersect frame into 16 cell instances, and
MoviolaFrameDataset.from_index(db, preset="canine") builds a dataset
per rendering straight from moviola.db. Frame extraction is
passthrough-exact (one instance per stored frame — a resampling
bug that duplicated fractional-fps instances was measured, 334 from
167, and is now regression-tested). No numpy, no Pillow: ffmpeg
decodes grey bytes, torch reads the buffer. The same frames convert
to JAX with to_jax_array (NCHW/NHWC), and export_training_data
writes every layout the frameworks stream:
| Framework | How Moviola feeds it | Acceleration note |
|---|---|---|
| PyTorch / TorchTitan | MoviolaFrameDataset, image-folder export |
ROCm builds need no dataset change — HIP rides the cuda API |
| AITER (ROCm kernels) | accelerated_attention → aiter.flash_attn_func; accelerated_gemm_int8 → aiter.gemm_a8w8_* after pertoken_quant |
the attention/GEMM speed-ups stock PyTorch does not ship for ROCm; probed at runtime, stock fallback named |
| JAX MaxText | to_jax_array; export_arrayrecord for Grain pipelines |
ROCm via jax[rocm] or Primus rocm/jax-training:maxtext-* images; jax-aiter brings AITER kernels to JAX |
| Megatron-LM | export_webdataset / datacenter shards (Megatron-Energon streams WebDataset) |
under Primus on ROCm |
| AMD Primus (datacenter) | export_datacenter_shards — numbered tar shards + manifest.json |
one config across Megatron-LM, TorchTitan and JAX MaxText backends |
| Unsloth | export_unsloth — vision-SFT train.jsonl (messages + images) over Moviola frames |
derived captions included; replace with real ones for real tasks |
from moviola_protocol_mcp.torch_data import MoviolaFrameDataset
from torch.utils.data import DataLoader

ds = MoviolaFrameDataset.from_index("moviola.db", preset="canine",
                                    ladder_stage=240, unpack_collage=True)
batch = next(iter(DataLoader(ds, batch_size=64)))   # [64, 1, 240, W] cells
moviola backends reports what is installed here versus what each
install line adds — on this Windows/RDNA2 development host it says
plainly that ROCm does not run, while every data path above is tested
torch-free. Demonstrate end-to-end (five renderings, ladder stages,
exports, DataLoader when torch exists):
uv run python scripts/demo_torch_dataset.py moviola.db
Extras: pip install 'moviola-protocol-mcp[torch]', [jax],
[maxtext], [unsloth]. ROCm wheels and Primus come from their own
indexes; moviola backends prints the exact lines.
🔌 The OpenCode plugin — GIF in, MP4 out
Models that refuse image/gif still refuse your evidence. The Nova Violet
OpenCode build solved this in-source: the read tool attaches a GIF as
video/gif, and the session relabels it video/mp4 on the wire (servers
validate the mime allowlist but sniff content, so the label routes while
the bytes rule). This wheel ships that adapter for stock OpenCode:
| File (in the wheel) | Form | Installs to |
|---|---|---|
plugin_data/moviola-gif-as-mp4.mjs |
ECMAScript, no build step, local models welcome | <config>/plugins/ |
plugin_data/moviola-gif-as-mp4.ts |
TypeScript source, same logic | <config>/plugins/ |
plugin_data/read.ts |
the portable read tool (attaches GIF as video) | <config>/tools/read.ts |
plugin_data/install.mjs + package.json |
npm installer (moviola-install-plugin bin) |
npx after npm publish |
moviola install-plugin                      # ~/.config/opencode, .mjs form
moviola install-plugin --target .opencode --format ts
node install.mjs ~/.config/opencode         # or straight from an unpacked wheel
A different existing tools/read.ts is never overwritten without
--force — the skip is named in the result. Opt out at runtime with
OPENCODE_GIF_AS_VIDEO=0, the same switch as the in-source build. One
deliberate widening versus the source: the plugin relabels image/gif
too, because stock OpenCode produces it; the rename lives only on the
wire copy, your stored sessions keep their true mime.
🥚 The Easter Egg — the Intersect Divergence
Where the Tessersect actually came from: an email full of flashing images that puts a database in a man's head, a mad scientist (so cool) whose memory survives the rewriting of history, a divergence meter reading 0.571024 in one worldline and 1.048596 in the one where the cuts were made correctly — the whole tale, and what was engineered from it, lives in docs/easter-egg.md.
The short version is a verb:
$ moviola flash
INTERSECT FLASH - I know Moviola.
...
Divergence meter: 0.892776
Reading Steiner: 4 conversions remembered in .../moviola.db - the index
does not forget a cut when the worldline changes.
The Organization is watching your file sizes. Stay grey.
El Psy Kongroo.
That 0.892776 is not set dressing. It is
0.571024 + saved_fraction × (1.048596 − 0.571024) computed live from the
demo ledger behind the gallery above (920,372 B in, 300,295 B out).
Yours will differ. It is supposed to.
Orion, and 1.0 versus 2.0. In Chuck's mythology the Intersect has an inventor — Orion, who encoded a database as flashing images and hid from every hand that wanted to own it. Intersect 1.0 carried knowledge; 2.0 carried skills ("I know kung fu"). Moviola is that invention brought to reality in the AI world by its inventor Saimonokuma — published, not hidden, because copyleft does openly what Orion did by disappearing. Presets B/C are the 1.0: facts as frames. The Tessersect is the 2.0: motor patterns — visemes, gestures, fingerings — uploaded as 16-instant collages.
What if the tape could be burned without powder? Steins;Gate is
a compression story in a time machine: a memory, a self, squeezed
until it fits a channel built for text messages. To think like them
is to ask of every file: what is the smallest form of you that
still changes the worldline you land in? Moviola's answer is a
burn without powder — colour, dither and redundant frames destroyed
irreversibly at the filter stage, contour and text carried through
the fire, and the ash weighed in the index (bytes_saved, per cut,
forever). A D-Mail works because almost everything was burned away
except the difference. So does a 14,920-byte documentary.
The full collision tables — D-Mail budgets, attractor-field convergence at the bench floor, the Governor as our integrity guards, Reading Steiner as SQLite — are in docs/easter-egg.md.
🎓 Verify it yourself
git clone https://github.com/Nova-Violet-Role/Moviola-Protocol-MCP.git
cd Moviola-Protocol-MCP
uv sync
uv run pytest            # 41 tests: acceptance, presets, index, behaviours,
                         # DPI, TorchPy bridge, backends, verbose, MCP, egg
uv run python scripts/verify_all.py   # the quintuple check: suite, encoding,
                         # instruments+alarms, clean-room wheel, statement audit
moviola --verbose convert <any-clip> out.gif   # or MOVIOLA_VERBOSE=1 anywhere
uv run moviola doctor    # trio + version, exit 0
uv run moviola backends  # what this host can and cannot train on
uv run moviola convert <any-clip> out.gif --preset canine
uv run python scripts/build_ladder.py        # regenerate the ladder + tables
uv run python scripts/demo_torch_dataset.py  # five renderings as datasets
sqlite3 moviola.db "SELECT preset, source_bytes, output_bytes FROM conversions;"
The acceptance test was written first and watched fail
(ModuleNotFoundError, for the right reason) before a line of the package
existed. The wheel you install was verified by listing its contents —
which caught, and killed, a first build that contained nothing but
metadata — and by running it clean-room from a bare temp directory
against the reference clip. An instrument that has never failed on
purpose is an untested instrument; every instrument here has been
failed on purpose.
🤝 Contributing
| Area | How you can help |
|---|---|
| 🎯 Falsify a claim | Prove one of our documented numbers wrong on your content. Credited in the changelog. |
| 🎞️ Presets | Cut a new dial on real footage and bring the mux report — numbers first, names after. |
| 🖥️ Platforms | Run doctor + the suite where ffmpeg lives somewhere else, and tell us what diverged. |
| 🌍 Docs | Say which sentence you had to read twice. That is a defect in the sentence. |
| 💡 Ideas | Tell us what a measured media tool should refuse to claim. |
🏛️ Where this sits in the organisation
Nova-Violet Role is a non-profit working where cognitive science, law
and software meet — frameworks for approaching complex problems from more
than one angle at a time. Moviola Protocol MCP is its sensory arm: the
same discipline the organisation applies to reasoning (declare the shape,
measure reality against it, keep the ledger) applied to pixels. The
papers in sources/ (sources/MOVIOLA-PROTOCOL.md
is the bench truth; sources/Moviola_Protocol.md is the vision it
answers to) are the two ends of that argument, and the code is where
they agree to be bound by exit codes. Within the wider work, Moviola
is one released organ of Symbiose — see the
Premier.
☕ Supporting a non-profit
Ko-fi buys time, never priority. The roadmap is set by falsified claims and measured benches, in the open.
📜 Post-Scriptum — for lecturers
We released another piece of Symbiose-OS to the public. Was it too much for 2026? No — one measured organ at a time is exactly on time. It is the whole that waits, perhaps forty years.
The long-form companion to this README lives in its own folder: docs/post-scriptum/Post-Scriptum.md — written for lecturers and the students they will set loose on it. Inside: what the release means, what it will do to training (measured / reasoned / unknown, kept apart), the MMPROJ question stated as an affordable experiment, a four-session teaching module, five labs whose expected outputs are this repository's own measured anchors, and discussion questions with no safe answers. If you teach with Moviola, start there; if your students falsify a number in it, that was the assignment.
📄 Licence
Copyright 2026 Saimonokuma.
SPDX-License-Identifier: AGPL-3.0-or-later OR EUPL-1.2
Licensed under the GNU Affero General Public License v3.0 or later, or,
at your choice, the European Union Public Licence v1.2. The complete
canonical texts ship in LICENSE-AGPL-3.0.txt
and LICENSE-EUPL-1.2.txt, with byte-identical
SPDX/REUSE-layout copies in LICENSES/. These are
copyleft licences, chosen deliberately over permissive ones: what is
shared here cannot be enclosed later, by anyone, including us. If this
project ever goes quiet, the code, the measurements and the history
remain yours to carry forward.
Steins;Gate and Chuck are referenced in docs/easter-egg.md as
inspiration only; no assets from either work are included.
⚜️ Moviola Protocol MCP
Cut in grey. Measured in bytes. Remembered in the index.

Issues · Releases · Licence · Easter Egg
© 2026 Nova-Violet Role · Non-Profit Organization
All frameworks open-source under copyleft licences — AGPL-3.0-or-later OR EUPL-1.2
Created with ❤️ for the advancement of human understanding
Topics
#MCP #ModelContextProtocol #MCPServer #FFmpeg #VideoConversion #GIF
#Greyscale #OneBit #MachineVision #PreTraining #DatasetTools #UVX
#Python #OpenCode #OpenCodePlugin #SQLite #MediaIndex #CanineLogic
#Tessersect #Neuromorphic #DVS #Agpl #Eupl #Copyleft #Spdx
#OpenSource #NonProfit #AiTooling #DeveloperTools #Falsifiable
1 maintainer

Metadata
1 maintainer
Release files for moviola-protocol-mcp 0.3.3
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| moviola_protocol_mcp-0.3.3.tar.gz | 1.5 MB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| moviola_protocol_mcp-0.3.3-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 1.6 MB
Release files / moviola_protocol_mcp-0.3.3.tar.gz
| Download URL | moviola_protocol_mcp-0.3.3.tar.gz |
|---|---|
| Size | 1.5 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
aad2bdcd9e5ed5496ba7021806ae3c5c63a7271eb4e7d07eed77199c9b6876a5
|
|
BLAKE2b-256 checksum How to use checksums |
4cdc590a9d24cc1711e402c9e3082d828e7e1e1648e53f0cc9dad9e7c41c2ad3
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
uv/0.12.5 {"installer":{"name":"uv","version":"0.12.5","subcommand":["publish"]},"python":null,"implementation":{"name":null,"version":null},"distro":null,"system":{"name":null,"release":null},"cpu":null,"openssl_version":null,"setuptools_version":null,"rustc_version":null,"ci":null}
|
Release files / moviola_protocol_mcp-0.3.3-py3-none-any.whl
| Download URL | moviola_protocol_mcp-0.3.3-py3-none-any.whl |
|---|---|
| Size | 98.5 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
15b142fb6e3fce318bd14546aa2fa82e9ee2753d8a47ede81bf671c204249ba1
|
|
BLAKE2b-256 checksum How to use checksums |
995d0e4f78d8ccbc1aeb40b7dcf101ca18240f1b3d28fb8b1d08465af87dc398
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
uv/0.12.5 {"installer":{"name":"uv","version":"0.12.5","subcommand":["publish"]},"python":null,"implementation":{"name":null,"version":null},"distro":null,"system":{"name":null,"release":null},"cpu":null,"openssl_version":null,"setuptools_version":null,"rustc_version":null,"ci":null}
|














