
Nano-Jev







Jev-style decision model. Independent; not affiliated with TypeSafe AI or the NanoJev GitHub project.
A small (33M parameter) calibrated decision model for RAG pipelines. Give it a question, some options and some context; it returns a probability for each option in a few milliseconds. It never generates text, so it can't return a malformed answer.
Use it for the small decisions an agentic RAG loop makes over and over:
| Decision | Options | Asks |
|---|---|---|
relevance |
irrelevant / partially relevant / directly answers | Is this passage useful for the query? |
sufficient |
yes / no | Do these passages contain enough to answer? |
grounded |
yes / no | Is this claim supported by the context? |
decide |
your own options | Anything else, e.g. topic or route |
At a glance
| Package | nano-jev 1.0.0 on PyPI (import nanojev, command nano-jev) |
| Weights | sdmlai/nano-jev: v1.0 (default) and v0.1, downloaded automatically on first use |
| Model (v1.0) | MiniLM cross-encoder, 12 layers, hidden size 384, 33.4M parameters, max 512 tokens |
| Test accuracy | relevance 0.815, sufficient 0.845, grounded 0.844 (results) |
| Held-out accuracy | 0.635 / 0.670 / 0.675 on MuSiQue + VitaminC, datasets it never saw |
| Speed | ~1–4 ms per decision batched on an RTX 3060; ~17 ms on CPU |
| Python | 3.10+ · PyTorch 2.1+ · Transformers 4.45+ |
| Licence | Code Apache-2.0 · v1.0 weights MIT (clean base, no MS MARCO) |
| Status | Stable (v1.0) · changelog |
Install
pip install nano-jev
PyTorch is installed from PyPI if you don't have it. For a CUDA build, install PyTorch first following pytorch.org.
Quick start
import nanojev

d = nanojev.load()   # default weights (v1.0); downloads ~130 MB the first time, then cached

d.relevance("When was UCL founded?", [
    "University College London was founded in 1826.",
    "The Analytical Engine was a proposed mechanical computer.",
])
# [{'irrelevant': 0.149, 'partially relevant': 0.172, 'directly answers': 0.679},
#  {'irrelevant': 0.917, 'partially relevant': 0.041, 'directly answers': 0.042}]

d.sufficient("In which year was the university attended by Ada Lovelace's tutor founded?", [
    "Augustus De Morgan tutored Ada Lovelace. He was a professor at University College London.",
    "University College London was founded in 1826.",
])
# {'yes': 0.726, 'no': 0.274}      (with only the first passage: {'yes': 0.188, 'no': 0.812})

d.grounded("UCL was founded in 1900.", "University College London was founded in 1826.")
# {'yes': 0.086, 'no': 0.914}
Custom options work with any label set, but v1.0 is weak at them (see limitations); v0.1 does better for now:
nanojev.load("v0.1").decide("Which topic is this passage about?", ["computing", "cooking", "football"],
                            "The Analytical Engine was a proposed mechanical computer.")
# {'computing': 0.783, 'cooking': 0.144, 'football': 0.073}
In a RAG loop
d = nanojev.load()

def answer(query, retrieve, llm):
    passages = retrieve(query, k=10)
    scores = d.relevance(query, passages)
    kept = [p for p, s in zip(passages, scores) if s["irrelevant"] < 0.5]

    if d.sufficient(query, kept)["yes"] < 0.85:          # not enough context
        kept += retrieve(query, k=10, page=2)            # retrieve more / rewrite the query / abstain

    reply = llm(query, kept)
    if d.grounded(reply, "\n".join(kept))["yes"] < 0.5:  # unsupported answer
        reply = llm(query, kept, strict=True)            # regenerate, flag, or escalate
    return reply
Escalate only when unsure (cascade)
def grounded(claim, context, threshold=0.8):
    p = d.grounded(claim, context)
    if max(p.values()) >= threshold:
        return p                        # confident: ~1 ms
    return ask_llm(claim, context)      # unsure: ask a bigger model
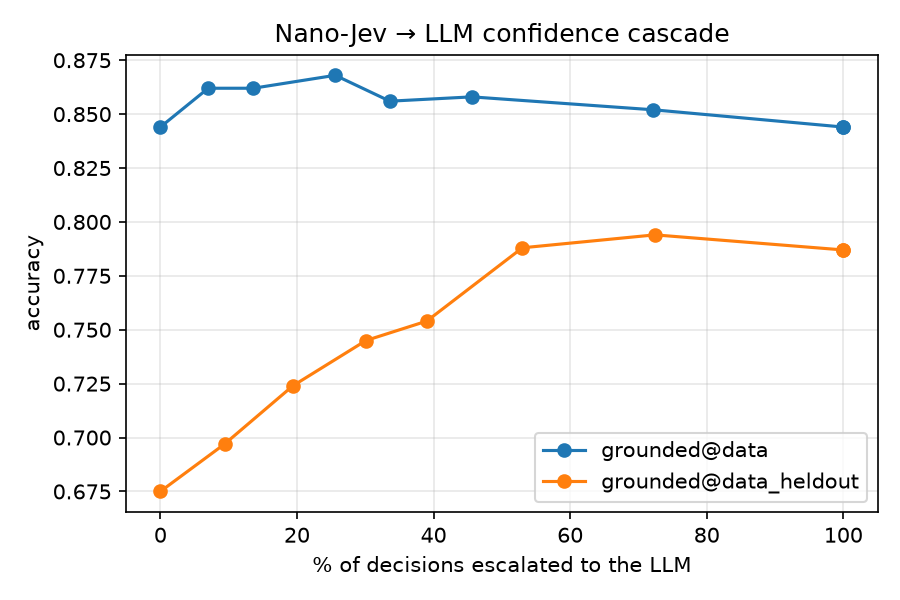
With Qwen3-4B as the fallback and threshold 0.80, this beats both models alone on the test split (0.868 vs 0.844) while sending only 26% of decisions to the LLM (details).
The thresholds are examples. Calibrated probabilities make thresholds meaningful, but check them on your own data, since calibration drifts on new domains.
Choosing weights
Weights live on Hugging Face at sdmlai/nano-jev,
one git tag per version. Every released version stays available. A version
downloads the first time you use it and then loads from the local cache (works offline).
| Version | Base | Params | Weights licence | Pick it when |
|---|---|---|---|---|
v1.0 (default) |
microsoft/MiniLM-L12-H384-uncased |
33.4M | MIT | built-in decisions, commercial use |
v0.1 |
cross-encoder/ms-marco-MiniLM-L6-v2 |
22.7M | Apache-2.0 + MS MARCO note | custom option sets, fastest CPU speed, non-commercial |
import nanojev

models, online = nanojev.list_models()           # versions on the Hub (+ which are downloaded)
for m in models:
    print(m.name, m.status, m.params, "downloaded" if m.downloaded else "")

d = nanojev.load("v1.0")                          # a specific version
d = nanojev.load("v0.1")                          # older versions keep working
d = nanojev.load("sdmlai/nano-jev@v1.0")          # any Hub repo, optionally @tag
d = nanojev.load("path/to/my-trained-model")      # a local folder
print(d.version, d.config["base"], d.config["params"])
Which weights nanojev.load() uses when you don't say:
- the
NANOJEV_MODELenvironment variable - the choice saved with
nano-jev use ...(stored in~/.nanojev/config.json) - the package default,
v1.0(pinned per package release, so results stay reproducible)
Command line
Installing the package adds a nano-jev command (python -m nanojev does the same).
nano-jev --version
nano-jev list                         # available weights; * marks the selected one
nano-jev list --local runs            # also list your own trained folders under runs/
nano-jev download v1.0                # fetch ahead of time, e.g. before going offline
nano-jev use v0.1                     # choose default weights: a version, Hub repo[@tag] or folder
nano-jev use --reset                  # back to the package default
nano-jev current                      # what's selected and where it is on disk

nano-jev relevance -q "When was UCL founded?" -p "University College London was founded in 1826." -p "Another passage."
nano-jev sufficient -q "QUERY" -p "PASSAGE 1" -p "PASSAGE 2"
nano-jev grounded --claim "UCL was founded in 1900." --context "University College London was founded in 1826."
nano-jev decide --question "Which topic is this passage about?" -o computing -o cooking --state "TEXT"
Decision commands accept --model (override the selection for one call) and --json.
$ nano-jev list
   MODEL  SOURCE  STATUS            BASE                                 PARAMS  RELEASED    DOWNLOADED
   v0.1   hub     research preview  cross-encoder/ms-marco-MiniLM-L6-v2  22.7M   2026-09-25  yes
*  v1.0   hub     stable            microsoft/MiniLM-L12-H384-uncased    33.4M   2026-09-25  yes

selected: v1.0  (from default)

$ nano-jev grounded --claim "UCL was founded in 1900." --context "University College London was founded in 1826."
yes=0.086  no=0.914
How it works
Each (question, option, context) triple goes through a small cross-encoder that outputs one logit:
[CLS] question: <q> option: <opt> [SEP] <context> [SEP] → encoder → linear → logit
A decision's option logits are divided by that decision's temperature (fitted on held-out data) and softmaxed, so the probabilities are calibrated. Options are scored independently, which is why you can pass option sets the model never saw in training.
Results
Temperatures and baseline mappings are fitted on the in-distribution calibration split and applied unchanged to both test sets. Full write-up: results/v1.0_comparison.md.
Test split (held-out halves of the HotpotQA / SQuAD 2.0 / MultiNLI validation sets):
| Decision | Nano-Jev v1.0 (33M) | Nano-Jev v0.1 (23M) | bge-reranker-v2-m3 (568M) | Qwen3-4B-Instruct, prompted (4B) |
|---|---|---|---|---|
| relevance (3-way) | 0.815 | 0.798 | 0.694 | 0.660 |
| sufficient | 0.845 | 0.759 | 0.692 | 0.706 |
| grounded | 0.844 | 0.804 | 0.798 | 0.844 |
Held-out datasets it never saw (MuSiQue multi-hop QA, VitaminC claim verification):
| Decision | Nano-Jev v1.0 | Nano-Jev v0.1 | bge-reranker-v2-m3 | Qwen3-4B-Instruct, prompted |
|---|---|---|---|---|
| relevance (MuSiQue) | 0.635 | 0.631 | 0.478 | 0.503 |
| sufficient (MuSiQue 2-hop) | 0.670 | 0.680 | 0.597 | 0.653 |
| grounded (VitaminC) | 0.675 | 0.672 | 0.737 | 0.787 |
Every model drops on unseen data. Nano-Jev still leads on relevance and sufficiency; the 4B LLM leads on groundedness. Nano-Jev v1.0 is ~55–95× faster than the LLM (batched, GPU).
Cascade
Nano-Jev v1.0 answers grounded when its confidence ≥ 0.80 and escalates the rest to
Qwen3-4B (threshold chosen on the calibration split):
| escalated to LLM | test accuracy | held-out accuracy | |
|---|---|---|---|
| Nano-Jev v1.0 only | 0% | 0.844 | 0.675 |
| cascade, threshold 0.80 | 26–30% | 0.868 | 0.745 |
| cascade, threshold 0.90 | 46–53% | 0.858 | 0.788 |
| Qwen3-4B only | 100% | 0.844 | 0.787 |
Tests
git clone https://github.com/shubham10divakar/nano-jev
cd nano-jev
pip install -e ".[test,train]"

pytest                                   # offline: builds a tiny random model, ~10 s
NANOJEV_NETWORK_TESTS=1 pytest           # also downloads v0.1 and v1.0 and checks both
What the tests cover (see tests/):
| File | Examples of what's checked |
|---|---|
test_decider.py |
every decision returns a probability distribution over its options; option order doesn't change probabilities; temperatures and config are loaded |
test_registry.py |
version names, repo@tag parsing, selection order (env > saved > default), local folders |
test_cli.py |
--version, use / current / use --reset, relevance and decide with --json, offline list |
test_calibration.py |
temperature fitting recovers a known temperature; ECE of an overconfident model |
test_network.py |
(opt-in) every released version is listed on the Hub, downloads, and makes sensible decisions |
Smoke test on Kaggle / Colab / a fresh machine
- Kaggle: click the Open in Kaggle badge above (or upload
examples/kaggle_smoke_test.ipynb), turn on Settings → Internet, then Run All. - Anywhere:
pip install nano-jev
wget https://raw.githubusercontent.com/shubham10divakar/nano-jev/main/examples/smoke_test.py
python smoke_test.py        # 10 checks, ends with ALL SMOKE TESTS PASSED
Train your own
The repo also contains the full training and evaluation pipeline:
pip install -e ".[train]"
python scripts/prepare_data.py --preset default          # HotpotQA + SQuAD 2.0 + MultiNLI -> data/ (splits included)
python scripts/prepare_data.py --heldout --out data_heldout   # MuSiQue + VitaminC held-out set (included)
python scripts/train.py --base microsoft/MiniLM-L12-H384-uncased --epochs 3 --lr 5e-5   # ~40 min on an RTX 3060
python scripts/evaluate.py --model runs/nano-jev-dev --name heldout --test-data data_heldout
python scripts/baselines.py --which all                  # bge-reranker + prompted Qwen3-4B
python scripts/cascade.py --model runs/nano-jev-dev --test-data data data_heldout
nano-jev use runs/nano-jev-dev                            # use your model everywhere
--preset smoke gives a 1-minute end-to-end run. Layout:
nanojev/        the package: decider (API), registry (weights), model, schema,
                calibration, report, data, __main__ (CLI)
scripts/        prepare_data, train, evaluate, baselines, cascade, demo
tests/          pytest suite
examples/       smoke_test.py, kaggle_smoke_test.ipynb
data/           train / calib / test splits (JSONL)
data_heldout/   MuSiQue + VitaminC held-out test set (JSONL)
results/        evaluation tables, baselines, cascade, per-version comparisons
model_cards/    Hugging Face model card per released version
Limitations
- Accuracy drops on new domains (≈15–20 points on held-out datasets), and calibration fitted in-distribution is overconfident there (ECE ≈ 0.17). Re-fit the temperatures on a few hundred of your own labelled examples, or at least re-check thresholds.
- Groundedness on hard claims (VitaminC) trails a prompted 4B LLM by 11 points; use the cascade for those.
- Custom option sets (
decide) are weak in v1.0; v0.1 is better at them for now. - English, Wikipedia-style text.
- "partially relevant" follows HotpotQA rules: a supporting paragraph without the answer string.
Licence
- Code: Apache-2.0.
- v1.0 weights: MIT, the same licence as the base model (
microsoft/MiniLM-L12-H384-uncased); no MS MARCO lineage. - v0.1 weights: Apache-2.0, but they start from
cross-encoder/ms-marco-MiniLM-L6-v2, which was trained on MS MARCO, whose terms are non-commercial. - Data: training and evaluation data derive from HotpotQA
(CC BY-SA 4.0), SQuAD 2.0 (CC BY-SA 4.0),
MultiNLI, MuSiQue
(CC BY 4.0) and VitaminC (CC BY-SA 3.0); the
files in
data/anddata_heldout/carry those licences.
Roadmap
- Train on open-ended option sets so custom
decide()calls get useful probabilities. - A
next_actiondecision (answer / retrieve more / rewrite / decompose / abstain) for agentic RAG loops. - A larger model that reads the query and all chunks in one pass.
1 maintainer

Release files for nano-jev 1.0.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| nano_jev-1.0.0.tar.gz | 26.5 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| nano_jev-1.0.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 52.4 kB
Release files / nano_jev-1.0.0.tar.gz
| Download URL | nano_jev-1.0.0.tar.gz |
|---|---|
| Size | 26.5 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
1893261afb3ff2435a7004eb9083c954fb9a2e47e03933679bf24232e1c4a053
|
|
BLAKE2b-256 checksum How to use checksums |
8f0ac5bf21c4d33b8cb510c0e265ad8d95181a51b1fab9969199d3cc883555ed
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.2.0 CPython/3.14.5
|
Release files / nano_jev-1.0.0-py3-none-any.whl
| Download URL | nano_jev-1.0.0-py3-none-any.whl |
|---|---|
| Size | 25.9 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
b97e133050d453fc4aaf0642636063a73704064a2b498c97b8d8e3a49d8268e9
|
|
BLAKE2b-256 checksum How to use checksums |
c3ed1c0d3fe319c11b12ceac153faaf2d33ab2ae61e9964b191e659ae52fa6cc
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.2.0 CPython/3.14.5
|














