
NanoFetch
Ridiculously easy gene-region BAM extraction.
nanofetch tumor.bam EGFR --index
Genome: GRCh38
Annotation: GENCODE 50 (GRCh38.p14)
Wrote EGFR.bam (18432 alignments) + EGFR.bam.bai
nanofetch turns gene symbols into reproducible genomic intervals, adds padding,
and extracts overlapping alignments from coordinate-sorted BAM or CRAM files. It
supports GRCh37, GRCh38, and the telomere-to-telomere T2T-CHM13v2.0 (hs1)
assembly.
Install
Python 3.9 or newer is required.
python -m pip install nanofetch
For an isolated command-line installation, use pipx install nanofetch.
For local development:
git clone https://github.com/AlexanderM-M/Nanofetch.git
cd Nanofetch
python -m pip install -e '.[test]'
pytest
pysam is the only runtime dependency. A separate samtools installation is not
required.
Usage
One gene, using the default 1 Mb padding on both sides:
nanofetch tumor.bam EGFR
Several genes:
nanofetch tumor.bam --genes EGFR CDK4 PDGFRA CDKN2A MET
Write one deduplicated, indexed BAM for all selected genes:
nanofetch tumor.bam --panel cns --combined cns.bam --index
Read a custom panel containing whitespace- or comma-separated symbols and #
comments:
nanofetch tumor.bam --gene-file my-panel.txt --combined panel.bam --index
Compact families are accepted:
nanofetch tumor.bam CDKN2A/B NTRK1/2/3
Use the built-in CNS convenience panel:
nanofetch tumor.bam --panel cns --index --output-dir cns-regions
Use T2T-CHM13 explicitly, or let nanofetch detect it from chromosome lengths:
nanofetch t2t-aligned.bam EGFR --genome t2t
nanofetch t2t-aligned.bam --panel cns --genome hs1
Indexed CRAM input is supported. Supply its reference explicitly when required:
nanofetch tumor.cram EGFR --reference GRCh38.fa --index
Inspect the resolved regions without writing BAMs:
nanofetch tumor.bam EGFR --dry-run
Genome: GRCh38
Annotation: GENCODE 50 (GRCh38.p14)
EGFR   chr7:54018820-56211628   EGFR.bam
Generate a reproducibility manifest:
nanofetch tumor.bam EGFR MET --index --manifest regions.tsv
Export resolved padded regions as BED without extracting BAMs:
nanofetch tumor.bam --gene-file my-panel.txt --write-bed regions.bed --dry-run
Write compact gene-body coverage QC for every selected gene:
nanofetch tumor.bam --panel cns --combined cns.bam --summary coverage.tsv
The summary reports alignment count, mean depth, mean mapping quality, and the percentage of gene bases covered at 1×, 10×, and 30×.
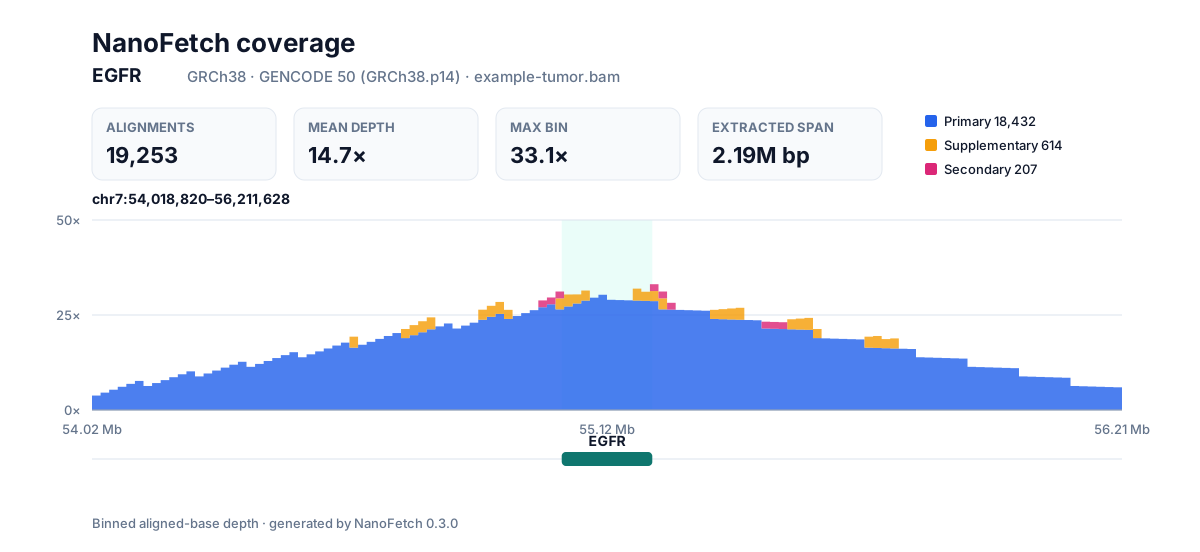
SVG coverage plot
Create a self-contained coverage overview for one extracted gene:
nanofetch tumor.bam EGFR --plot EGFR.coverage.svg
The plot shows mean aligned-base depth in fixed-width bins, the annotated gene
body, requested extraction span, assembly and annotation provenance, and counts
for primary, supplementary, and secondary alignments. It visualizes the output
BAM, so --include-supplementary and --include-secondary are reflected in the
plot. SVG generation has no dependency beyond NanoFetch itself.
Run nanofetch --help for all options.
What is selected?
An alignment is selected when its aligned reference span overlaps the padded gene interval. It does not need to span the entire region.
By default, secondary (0x100) and supplementary (0x800) records are excluded.
Use --include-secondary and --include-supplementary to retain records of those
types that overlap the region.
--include-supplementary does not retrieve distant segments merely because a
different segment from the same read overlaps the requested gene. That operation
requires a read-name-based second pass and is intentionally outside the default
semantics.
Overlapping padded intervals for multiple copies of the same symbol are merged, so an alignment is not written twice. Separate gene output BAMs may contain the same alignment when their padded regions overlap; this is expected.
Genome detection and contig names
Automatic detection compares exact primary-chromosome lengths in the BAM header. It will stop rather than guess when the build is ambiguous. The explicit spellings below are accepted:
| Assembly | Accepted names | Bundled annotation |
|---|---|---|
| GRCh37 | grch37, hg19 |
GENCODE 50lift37 |
| GRCh38 | grch38, hg38 |
GENCODE 50 |
| T2T-CHM13v2.0 | t2t, hs1, chm13, chm13v2.0 |
RefSeq/Liftoff v5.3 |
Both chr7 and 7 naming styles are supported. T2T GenBank names such as
CP068271.2 and RefSeq names such as NC_060931.1 are also mapped to their
chromosomes.
Input and output safety
The input must be coordinate-sorted and indexed: BAM uses BAI or CSI, while CRAM
uses CRAI. CRAM decoding can use --reference FASTA. nanofetch does not modify
the input or create an input index automatically.
Existing output BAMs are protected unless --force is supplied. Outputs are
written to a temporary file and moved into place only after writing succeeds.
When an output is replaced, any stale BAI or CSI is removed. --index creates a
fresh BAI. Plot and manifest files receive the same collision protection, and
manifests are also written atomically.
Before extraction starts, nanofetch checks all planned BAM, index, plot, and
manifest paths for conflicts. It refuses to use the input BAM or either of its
conventional index paths as an output, even when --force is supplied.
Built-in CNS panel
The cns panel currently contains:
EGFR PDGFRA CDK4 MDM2 MDM4 MET CDKN2A CDKN2B NF1 PTEN TERT
BRAF FGFR3 NTRK1 NTRK2 NTRK3 ALK
This is a transparent convenience set, not a validated clinical assay. Use
nanofetch --list-panels to inspect installed panels.
Annotation provenance
The package works offline. It bundles compact gene-level tables generated from pinned upstream files; it does not bundle complete GTF/GFF files.
- GRCh38: GENCODE release 50
- GRCh37: GENCODE 50lift37
- T2T: T2T-CHM13v2.0 RefSeq/Liftoff v5.3
Source URLs, SHA-256 digests, labels, and record counts are stored in
src/nanofetch/data/annotations.json. The deterministic build script is
scripts/build_annotations.py.
Scope
NanoFetch writes one BAM per gene by default or a single union with --combined.
Potential later additions include custom GTF annotations, CRAM output, mate
retrieval, and all-segment retrieval.
License
MIT. T2T consortium data are released under CC0; see the upstream CHM13 repository.
1 maintainer

Metadata
1 maintainer
Release files for nanofetch 0.3.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| nanofetch-0.3.0.tar.gz | 4.2 MB | With provenance | Details for nanofetch-0.3.0.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| nanofetch-0.3.0-py3-none-any.whl | Python 3 | none | any | Details for nanofetch-0.3.0-py3-none-any.whl |
Total release size: 8.4 MB
Release files / nanofetch-0.3.0.tar.gz
| Download URL | nanofetch-0.3.0.tar.gz |
|---|---|
| Size | 4.2 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
23c36ec658af688f044d522909d4a2e8bce28b549a11091e3c026cd4d1910274
|
|
BLAKE2b-256 checksum How to use checksums |
11f2c636cfc3b15f84ceca90db6f05c5549276bd5e6d5a6aa308e8c1e702a9e3
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 3, 2026.
Transparency logRelease files / nanofetch-0.3.0-py3-none-any.whl
| Download URL | nanofetch-0.3.0-py3-none-any.whl |
|---|---|
| Size | 4.2 MB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
50c9fdbe8b5ae86056203c892d3befa1036498e5920a106fe969de8ec52512a4
|
|
BLAKE2b-256 checksum How to use checksums |
ba5d0fe0c37e955d7950fe3bf0506bd52f308f38e26930e9464a64ee31b9e86a
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 3, 2026.
Transparency logSecurity for nanofetch 0.3.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
All 2 files in this release have been uploaded with provenance metadata.
Attestation for nanofetch-0.3.0.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 3, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














