


Documentation | Deployment | API reference | Issues | Contributing
About
Narwhal is a disaggregated LLM inference framework, which reallocates prefill and decode roles as demand changes while model weights stay loaded.
Narwhal provides:
- Hot-swap prefill/decode role assignment across a fixed GPU fleet.
- Separate prefill and decode routing with NIXL KV transfer.
- Latency-aware admission and placement using measured per-engine profiles.
- Streaming and non-streaming completion and chat APIs, including function tools and reasoning output where supported by the engine and model.
- Request deadlines, disconnect cancellation, bounded queues and optional retries.
- Engine health checks, transfer validation and warm-standby router failover.
- Prometheus metrics, request journals and a Grafana dashboard.
Architecture
On regular controller passes, Narwhal estimates prefill and decode pressure against their SLOs for the current and adjacent role splits, using measured engine curves, offered demand, and resident work. It moves an eligible engine when a candidate improves the worst projected SLO ratio by the configured margin and passes role-floor, cooldown, and health checks. New requests follow the revised split while resident requests finish on their assigned engines.
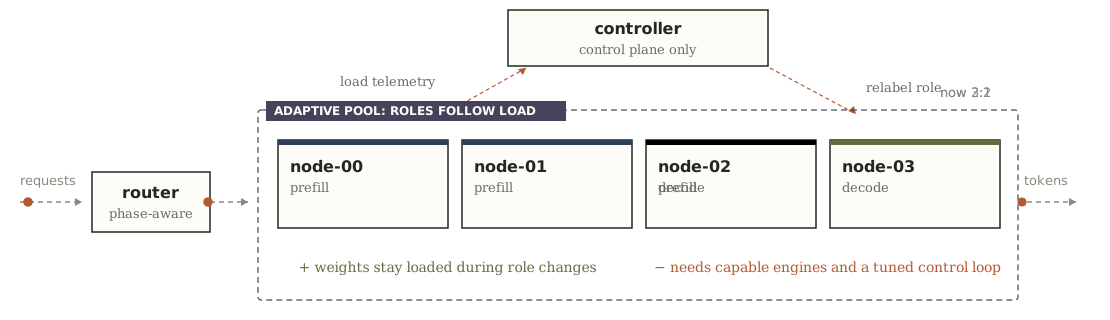
See Core concepts for request flow and scheduling, and Configuration for controller settings.
Benchmark snapshot
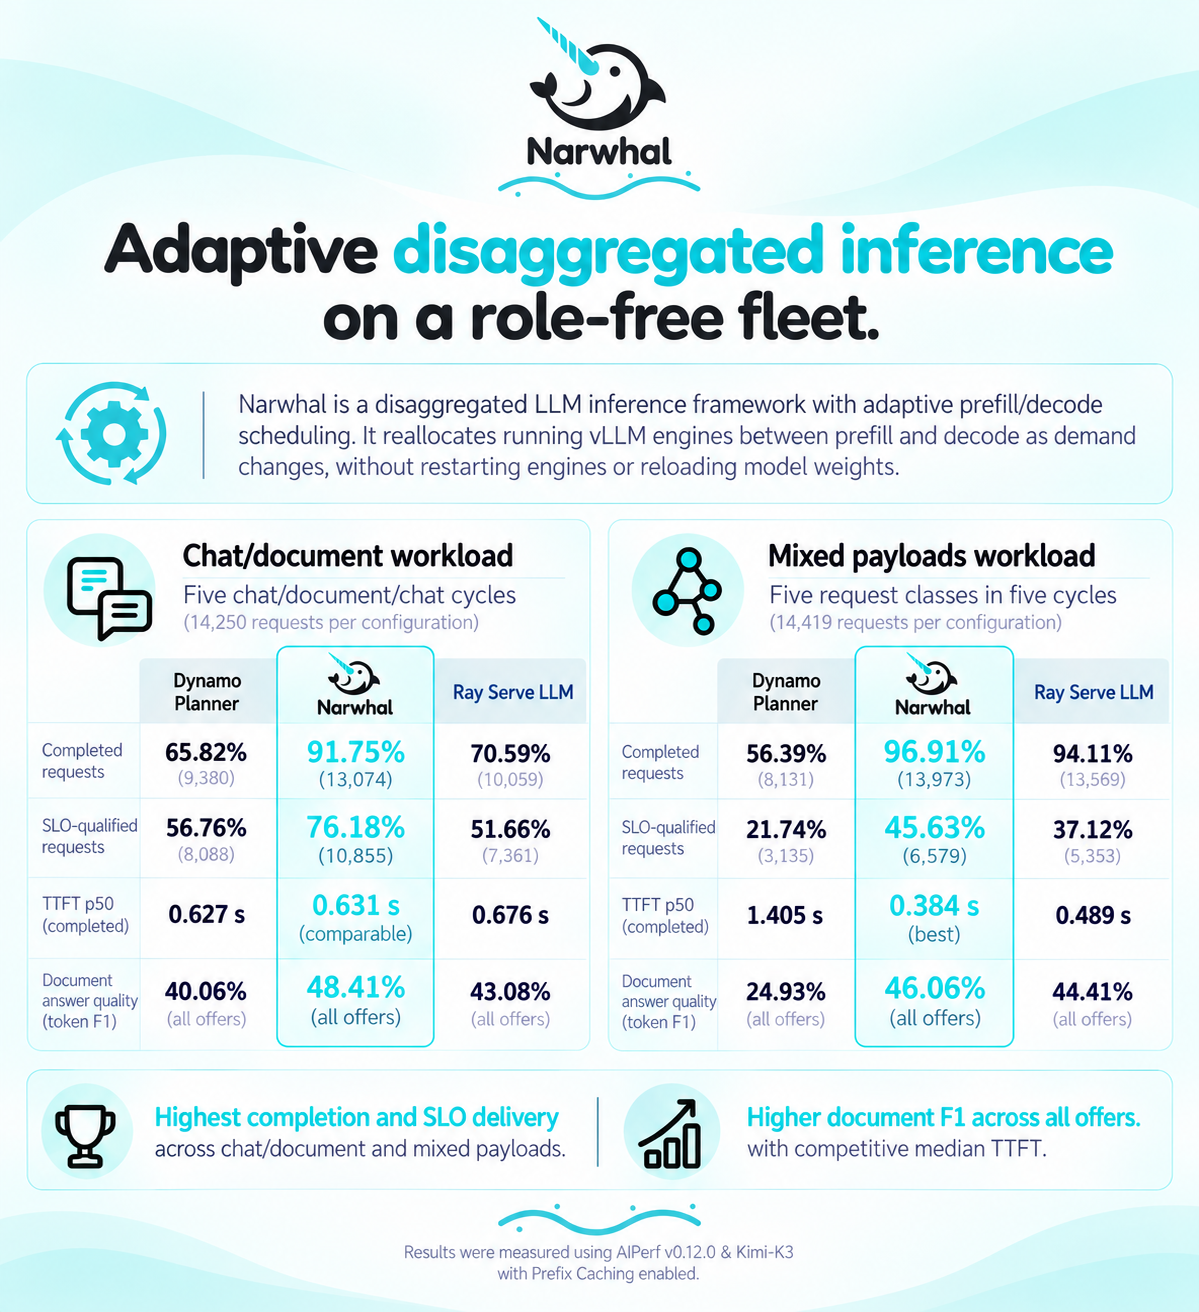
AlPerf v0.12.0 ran chat/document and mixed-payload Kimi-K3 workloads with prefix caching enabled across Narwhal, Dynamo Planner, and Ray Serve LLM.
Install from PyPI
Install the router commands on Linux with Python 3.11 or newer:
python3 -m venv .venv
source .venv/bin/activate
python -m pip install narwhal-inference
python -m pip show narwhal-inference
narwhal-check --help
The wheel installs narwhal, narwhal-engine, narwhal-serve, narwhal-attest, narwhal-profile, and narwhal-check. Record the version reported by pip show with the fleet configuration and engine image, then pin it across router hosts. The PyPI installation guide covers the engine and profile inputs required before serving requests.
Narwhal dev
Narwhal dev runs a local NVIDIA CUDA fleet on Ubuntu or Ubuntu under WSL2 with narwhal dev init/up/verify/status/down. Its installed two-engine template targets GPUs with 8 GB of VRAM or less and checks available memory at initialization. A separate RTX 5090 template records the measured four-engine configuration. Contributors can add qualified CUDA recipes and support for other GPU vendors.
Deploy a fleet
Follow Deploy a fleet from a management workstation. Inspect the target hardware and model, install an approved source revision, and validate the running vLLM processes and KV paths. Then profile and run preflight before routing traffic.
The final gate measures the workload through the private path, reconciles client outcomes with the router journal, and checks Prometheus and Grafana.
Reference
- Architecture and scheduling
- Fleet configuration
- CLI reference
- HTTP API
- Fleet measurement
- Prometheus and Grafana
- Ingress and maintenance
- Troubleshooting
Contributing
Contributing covers checkout setup, local checks and the pull request flow. Participation follows the code of conduct, and the security policy covers vulnerability reports.
Attribution and citation
Narwhal's scheduling algorithms derive from Arrow: Adaptive Scheduling Mechanisms for Disaggregated LLM Inference Architecture by Wu et al. (2025). Cite Arrow for those algorithms and Narwhal for this software. CITATION.cff contains both references.
License: Apache-2.0.
1 maintainer

Release files for narwhal-inference 0.3.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| narwhal_inference-0.3.0.tar.gz | 2.6 MB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| narwhal_inference-0.3.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 2.9 MB
Release files / narwhal_inference-0.3.0.tar.gz
| Download URL | narwhal_inference-0.3.0.tar.gz |
|---|---|
| Size | 2.6 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
ac4ff012605dcb55b3f5ca5a228ee3d065b711189f3b8618d7435334f9849d95
|
|
BLAKE2b-256 checksum How to use checksums |
48a32c4cd76eadda0df1d9c085efe0123bd273225d55ef3edffd14732a7cd4ff
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 25, 2026.
Transparency logRelease files / narwhal_inference-0.3.0-py3-none-any.whl
| Download URL | narwhal_inference-0.3.0-py3-none-any.whl |
|---|---|
| Size | 267.7 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
348ab54042cf9f010dd63893892ea60f75bf254abe8036e0bc90f173c68ba9ae
|
|
BLAKE2b-256 checksum How to use checksums |
70781d3bf56894928189c013d02e0485ff70e0aa5210205772ea553d491e53cb
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 25, 2026.
Transparency log













