
neural-trees
Soft decision trees, mixture of experts, and statistical model comparison tests for Python. A scikit-learn compatible library implementing classic machine learning algorithms from research papers, with a PyTorch backend.
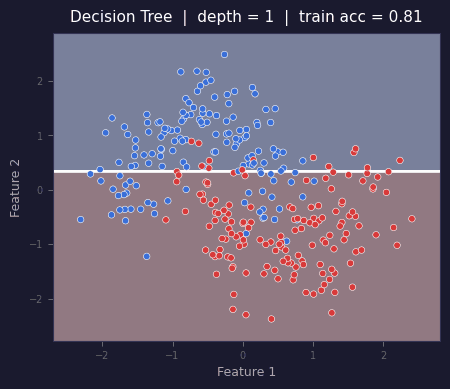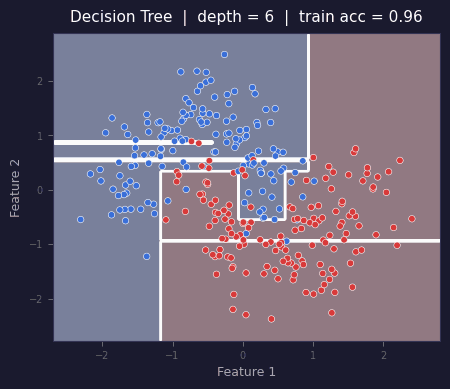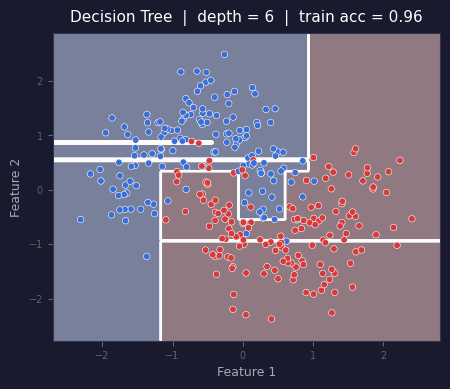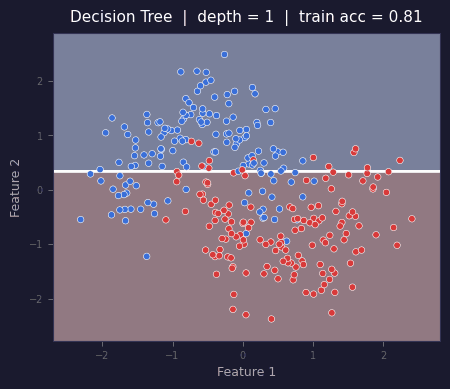
Decision boundary learning with Soft Decision Trees on a toy dataset.



Features
- scikit-learn compatible API (
fit,predict,score, works inPipeline) - PyTorch backend with GPU support (
device="auto"picks CUDA, then Apple silicon MPS, then CPU) - Torch imported lazily, so the numpy-only half of the library works without it
- Soft Decision Trees (classifier and regressor), Hierarchical Mixture of Experts, Multivariate and Omnivariate Trees, GAL
explain(): per-prediction explanations with the path taken, the gates on it and a verified counterfactual- Exports without PyTorch:
to_numpy()is the same model in numpy with a JSON round trip,to_onnx()the same model for any ONNX runtime (11 microseconds a row),to_hard_tree()a readable rule tree - Combined 5x2cv F test, McNemar's test, paired t-test for classifier comparison
sample_weightandclass_weighton every classifier; sparse input where it is cheap- Tested on standard benchmarks (Iris, Wine, Breast Cancer), with the table checked in CI
Try it in the browser: every model in this library against CART, Random Forest and SVM, with live decision boundaries and a hypothesis test instead of an eyeballed accuracy difference.
Installation
pip install neural-trees
PyTorch comes with it and backs SoftDecisionTree, HierarchicalMixtureOfExperts
and GALNetwork. It is imported lazily, so in an environment where torch cannot
be installed at all, a browser running Pyodide being the case that prompted
this, the rest of the library still works:
MultivariateDecisionTree, OmnivariateDecisionTree, WeightedKNN,
NaiveBayesClassifier, the two hard exports and the comparison tests. Touching
a torch-backed estimator there raises an error naming pip install torch
rather than failing at import.
Install from source
git clone https://github.com/cgrtml/neural-trees.git
cd neural-trees
pip install -e .
Quick Start
Train a Soft Decision Tree on the Iris dataset:
from neural_trees import SoftDecisionTree
from sklearn.datasets import load_iris
from sklearn.model_selection import train_test_split

X, y = load_iris(return_X_y=True)
X_train, X_test, y_train, y_test = train_test_split(X, y, random_state=42)

model = SoftDecisionTree(depth=4, max_epochs=40)
model.fit(X_train, y_train)
print(model.score(X_test, y_test))  # ~0.97
Use it inside a scikit-learn pipeline:
from sklearn.pipeline import Pipeline
from sklearn.preprocessing import StandardScaler

pipe = Pipeline([
    ("scaler", StandardScaler()),
    ("model", SoftDecisionTree(depth=4, max_epochs=40)),
])
pipe.fit(X_train, y_train)
pipe.score(X_test, y_test)
Interactive playground
app.py is a Streamlit app built around the questions a visitor
asks, one page each:
- Start here: what the library is, and the boundary every model learns on the same two-dimensional data, so the difference between the models is seen rather than described.
- Compare: pick a dataset and models; every model is trained on the same cross-validation folds, and the page says who scored highest, who is within fold noise of them (paired t-test over the folds) and who is measurably behind, then runs the combined 5x2cv F test on any pair.
- Try it on your data: upload a CSV or Excel file, pick the column to
predict (a class or a number), and run the same flow on it with
imputation, scaling, one-hot encoding and, for free-text columns, the
most frequent words as features, all fitted inside every fold; then the
soft tree's rules (naming words where the data is text), one row
explained with its counterfactual,
model.jsonandmodel.onnx, and the Python that reproduces the page. - How a model works: one model at a time: what it does, when to use it, how it works, its knobs on a live boundary, a drawing of the structure it learned (gates, branch probabilities and leaves for the soft tree; split types for the omnivariate tree; the routing tree of the mixture; the layer GAL grew to), and what it learned: rules, a per-prediction explanation, growth and pruning.
- What was fixed and verified: the four models that did not work, the scikit-learn checks every estimator passes, and the design choices that were measured rather than assumed.
- Against the field: the nine-model, 24-dataset benchmark against XGBoost, LightGBM, GRANDE and NODE.
pip install -r requirements.txt
streamlit run app.py
The registry of models and every cached fit live in playground/,
the pages in views/. Hosted at
https://neural-trees.streamlit.app on Streamlit Community Cloud's free
tier, which puts an app to sleep after a few days without visitors; the
first visit after that shows a wake-up button and takes about a minute. The
same requirements.txt installs it there and locally.
Benchmark
5-fold stratified cross-validation accuracy with StandardScaler preprocessing,
averaged over 5 seeds. Every number comes from
benchmarks/run_benchmarks.py, so the table can
be re-run and checked:
python benchmarks/run_benchmarks.py --seeds 5
A CI job re-runs the script and fails when a cell no longer rounds to the
value shown (python benchmarks/run_benchmarks.py --check). The reference
machine is that Linux runner; on an Apple Silicon laptop 20 of the 21 cells
come out identical and the multivariate tree on Breast Cancer reads 0.952.
| Model | Iris | Wine | Breast Cancer |
|---|---|---|---|
| Soft Decision Tree (depth=4) | 0.900 | 0.979 | 0.976 |
| Multivariate Tree (depth=3) | 0.973 | 0.989 | 0.950 |
| Hierarchical MoE (depth=2) | 0.904 | 0.979 | 0.977 |
| GAL Network | 0.952 | 0.982 | 0.978 |
| CART (sklearn) | 0.943 | 0.917 | 0.920 |
| Random Forest | 0.945 | 0.980 | 0.960 |
| SVM (RBF) | 0.959 | 0.984 | 0.978 |
On Wine and Breast Cancer every model here beats CART by five points or more, and the mixture of experts and GAL land within noise of Random Forest and SVM.
Iris is the honest counterexample. The two depth-based tree models sit below
CART there (0.900 and 0.904 against 0.943): 150 samples over 3 classes is too
little data for a depth-4 tree with 15 gates trained for 40 epochs, and a single
oblique split does better. growth="incremental" lets a soft tree choose its own
depth against a validation split rather than being handed one. This is also why
the comparison scripts in examples/ use a hypothesis test rather
than a single accuracy number.
Against XGBoost, LightGBM, GRANDE and NODE
A second benchmark, benchmarks/rakipler.py, runs
nine models on 24 datasets (the four above plus twenty from OpenML CC-18,
capped at 5 000 rows), three seeds of five-fold cross-validation, nothing
tuned: every model in one fixed configuration everywhere. Over all 24 the
boosted ensembles, Random Forest and an MLP lead and the soft models sit a
point or two behind. Split by size the order reverses: on the eight datasets
with at most 1 000 rows, GAL beats untuned XGBoost on every one (+2.9 points
on average) and the per-leaf soft tree on seven of eight (+2.1), while above
1 000 rows XGBoost wins nearly every comparison. The MLP wins on the small
datasets too, so the finding is that smooth gradient-trained models beat
untuned boosting on small tables; what the soft tree adds is that it can be
read, exported and explained. The split at 1 000 rows was chosen after
seeing the data. Full tables and the caveats are on the
Against the field
page.
Algorithms
These implementations start from the published algorithms below and depart from them where this library makes its own design choices. Where an implementation deviates deliberately, the module docstring says so. Treat the references as the lineage of an idea, not as a claim of exact reproduction.
| Algorithm | Reference |
|---|---|
| Soft Decision Trees | İrsoy, Yıldız, Alpaydın (ICPR 2012) |
| Hard export of a soft tree | to_hard_tree(), this library |
| Hard routing export of a mixture | to_hard_router(), this library |
| Multivariate Decision Trees | Alpaydın & Çetin (1995), Yıldız & Alpaydın (IEEE TNN 2001) |
| Omnivariate Decision Trees | Yıldız & Alpaydın (IEEE TNN 2001) |
| Hierarchical Mixture of Experts with subtree dropout | İrsoy & Alpaydın (Neurocomputing 2021) |
| GAL: Grow and Learn Networks | Alpaydın (IJPRAI 1994) |
| Combined 5x2cv F Test | Alpaydın (Neural Computation 1999) |
| McNemar's Test, Paired t-test | Standard references |
| Naive Bayes, Weighted KNN | Textbook chapters 3 to 8 |
Use Cases
An auditable model package. cases/german-credit is a complete example on the public German Credit data: a soft tree measured against logistic regression, CART, random forest, XGBoost and LightGBM on identical folds with the dataset's cost matrix, then calibration, the rules, three explained decisions with counterfactuals a real applicant could reach, slices by age, sex and residency, refit stability, and the JSON and ONNX model files with an agreement check, all written into a model document from the numbers. Result: the soft tree ties logistic regression on accuracy, AUC and cost and adds the rules and the per-decision paths; the untuned boosters lose on cost because their probabilities are not calibrated. If you have a table of a few hundred to a few thousand rows where every decision must be explained, open an issue and I will run the same package on it.
Research. Reproduce or extend results from the original papers with a clean, tested codebase.
Statistical model comparison. Compare classifiers with proper hypothesis tests instead of ad hoc accuracy diffs:
from neural_trees import combined_5x2cv_f_test
from sklearn.svm import SVC
from sklearn.tree import DecisionTreeClassifier
from sklearn.datasets import load_breast_cancer

X, y = load_breast_cancer(return_X_y=True)

result = combined_5x2cv_f_test(
    DecisionTreeClassifier(),
    SVC(kernel="rbf"),
    X, y,
)

print(result)
Education. A working reference for soft splits and mixtures of experts beyond textbook diagrams.
Why Soft Decision Trees
Standard decision trees use hard splits, which makes them non-differentiable and unstable to small input changes. Soft Decision Trees replace each split with a sigmoid gate, which means:
- The tree is fully differentiable and trains with gradient descent
- Predictions are smooth, not piecewise constant
- Performance often lands between CART and ensemble methods
- The tree stays interpretable, you can still read off split decisions
Examples
Runnable scripts in examples/:
| Script | What it shows |
|---|---|
01_iris_classification.py |
Minimal train/test loop on Iris |
02_pipeline_with_scaler.py |
StandardScaler + SoftDecisionTree in a Pipeline, 5-fold CV |
03_classifier_comparison.py |
Combined 5x2cv F test against CART |
04_decision_boundary.py |
Decision boundary plot on make_moons |
python examples/01_iris_classification.py
Notebooks

01_soft_decision_trees.ipynb: training, decision boundary visualization, comparison with CART02_classifier_comparison_tests.ipynb: when to use which statistical test03_multivariate_decision_trees.ipynb: oblique splits against CART and soft trees
What is original here
The algorithms below come from published work. What this library adds on top
of them, and what the @software entry in the next section is for:
- Four models that did not work.
HierarchicalMixtureOfExpertscould not take a single gradient step,OmnivariateDecisionTreereturned the same leaf for every input,GALNetworkscored at chance on separable data, and condensed nearest neighbour produced an inconsistent prototype set. Each was diagnosed, fixed, and covered by a regression test that fails against the old code. - Design choices the papers do not make, each measured rather than assumed: residual-fitted units for GAL, growth decided on held-out error rather than a fixed threshold, per-leaf growth for soft trees, and a temperature on the soft gates that is off by default because the effect is mixed.
- Exports.
to_numpy()is the fitted soft tree in plain numpy with the mixture over leaves kept and a JSON round trip, for serving without PyTorch.to_hard_tree()andto_hard_router()turn a soft model into readable rules, and report how often the export agrees with the model it came from instead of assuming it does; three export rules were measured and the default kept because none won on both agreement and cost. - Explanations.
explain()gives, per prediction, the leaf that received the sample, every gate on the path with its direction and largest terms, a per-feature contribution along the path, and the smallest single-feature change that flips the class, verified by re-predicting. - A defect the papers do not warn about. Deepening a soft tree by giving both new children the parent's distribution leaves the new gate's gradient exactly zero, so the added level can never learn. The proof, the measurements and the one-line fix are in the accompanying paper, and the same defect was found and fixed in the per-leaf growth.
- A library around the algorithms: one scikit-learn API across seven
classifiers and a regressor,
sample_weightandclass_weighton every classifier,check_estimatorclean apart from the row-repetition check where the model's weighting is not row repetition (the docstrings say which and why), 363 tests, and a benchmark table generated by a script in the repo and re-checked in CI rather than typed by hand.
Where an implementation deviates from its source deliberately, the module docstring says so and gives the numbers.
Citation
To cite this library, which is the software described above:
@software{temel_neural_trees,
  author    = {Temel, Cagri},
  title     = {neural-trees: scikit-learn compatible soft decision trees,
               mixtures of experts and classifier comparison tests},
  year      = {2026},
  publisher = {Zenodo},
  doi       = {10.5281/zenodo.22718897},
  url       = {https://doi.org/10.5281/zenodo.22718897}
}
That DOI always resolves to the most recent release. To cite the exact version you ran, use the DOI of that release instead; v0.7.0 is 10.5281/zenodo.22929121.
GitHub's "Cite this repository" button reads
CITATION.cff, which carries the same information.
If you use one of the underlying algorithms, cite its source as well. These are the lineage of the ideas, not co-authorship of this implementation:
@inproceedings{irsoy2012soft,
  title     = {Soft Decision Trees},
  author    = {İrsoy, Oğuzhan and Yıldız, Olcay Taner and Alpaydın, Ethem},
  booktitle = {ICPR},
  year      = {2012}
}

@article{irsoy2021dropout,
  title   = {Dropout Regularization in Hierarchical Mixture of Experts},
  author  = {İrsoy, Oğuzhan and Alpaydın, Ethem},
  journal = {Neurocomputing},
  volume  = {419},
  pages   = {148--156},
  year    = {2021}
}

@article{yildiz2001omnivariate,
  title   = {Omnivariate Decision Trees},
  author  = {Yıldız, Olcay Taner and Alpaydın, Ethem},
  journal = {IEEE Transactions on Neural Networks},
  volume  = {12},
  number  = {6},
  pages   = {1539--1546},
  year    = {2001}
}

@article{alpaydin1994gal,
  title   = {GAL: Networks that Grow when they Learn and Shrink when they Forget},
  author  = {Alpaydın, Ethem},
  journal = {International Journal of Pattern Recognition and Artificial Intelligence},
  volume  = {8},
  pages   = {391--414},
  year    = {1994}
}

@article{alpaydin1997voting,
  title   = {Voting over Multiple Condensed Nearest Neighbors},
  author  = {Alpaydın, Ethem},
  journal = {Artificial Intelligence Review},
  volume  = {11},
  pages   = {115--132},
  year    = {1997}
}

@article{alpaydin1999combined,
  title   = {Combined 5x2cv {F} Test for Comparing Supervised Classification Learning Algorithms},
  author  = {Alpaydın, Ethem},
  journal = {Neural Computation},
  volume  = {11},
  number  = {8},
  pages   = {1885--1892},
  year    = {1999}
}

@article{fahlman1990cascade,
  title   = {The Cascade-Correlation Learning Architecture},
  author  = {Fahlman, Scott E. and Lebiere, Christian},
  journal = {Advances in Neural Information Processing Systems},
  volume  = {2},
  year    = {1990}
}
Limitations
neural-trees is not the right tool for every problem:
- Very high-dimensional data. Every internal node holds a dense weight
vector, so parameter count grows as
2^depth x n_features. Beyond a few thousand features, reduce dimensionality first or use a linear model. - Streaming or online learning. Training is batch only.
warm_start=Truecontinues a fit from where the last one stopped, which covers training in stages, but there is nopartial_fit: mini-batch gradient descent over a second dataset drifts toward that dataset rather than toward the union, so the contractpartial_fitimplies would not hold. - Sub-millisecond inference. The PyTorch backend adds per-call overhead.
SoftDecisionTree.to_numpy()is the same model in numpy without it, andto_hard_tree()exports the learned gates as a rule tree that predicts about 5x faster, at the cost of reading each gate as a hard decision rather than a soft one.HierarchicalMixtureOfExperts.to_hard_router()does the same for the mixture, evaluating one expert instead of all of them. - Very large sample counts. Training is mini-batch gradient descent over epochs, not an optimized tree-growing routine like CART. Fit time is linear in the number of rows (a depth-4 tree, 30 epochs: 2 s at 1 000 rows, 58 s at 50 000 on a laptop CPU; see the Performance page), so millions of rows will be slow on CPU.
- Categorical features. There is no built-in encoding; sigmoid gates
expect continuous, scaled inputs. Encode and scale in a
Pipeline.
Changelog
See CHANGELOG.md. Versions 0.2.0 and 0.3.0 fixed four models that did not work in 0.1.x, so upgrade if you are on an earlier release. Every classifier passes scikit-learn's estimator checks as of 0.4.0.
Contributing
Contributions are welcome. New to open source? See CONTRIBUTING.md for a beginner-friendly walkthrough.
Every open issue states what would close it, so you can judge the size before you start.
First contribution, no deep ML background needed, tagged
good first issue:
write a test file for one of the pure-numpy estimators, wire ruff into CI,
move packaging to pyproject.toml, add a coverage threshold, or run the
notebooks in CI so their committed outputs cannot go stale.
If you know scikit-learn and PyTorch: sample_weight and class_weight
support, or vectorizing the mixture-of-experts gating tree the way
SoftDecisionTree already is (that one has a worked reference implementation
in the repo to copy).
If you want a research problem: incremental tree growing from İrsoy, Yıldız and Alpaydın (ICPR 2012), which the fixed-depth implementation here does not do, or distilling a trained soft tree into a hard one for readable rules and fast inference.
For larger changes, open an issue first to discuss the approach. If this project is useful to you, a star helps others find it.
Contributors
Thanks to everyone who has improved this library.
| Contributor | Contribution |
|---|---|
| @snoopuppy582 | Symmetric McNemar disagreement test (#20), development requirements (#23), depth validation (#22), reproducibility test (#24) |
| @aribaskagan | Fixed the coverage target in CI, which had been measuring a module that no longer exists (#25) |
| @yunaremaia | Migrated packaging to pyproject.toml and wired ruff into CI (#46) |
The list began with the GitHub Sprint segment of the WSU Data and Analytics Breakout (May 15, 2026) and stays open to anyone. Full history: the contributors graph.
License
MIT. See LICENSE.
1 maintainer

Metadata
1 maintainer
Release files for neural-trees 0.8.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| neural_trees-0.8.0.tar.gz | 135.5 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| neural_trees-0.8.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 235.4 kB
Release files / neural_trees-0.8.0.tar.gz
| Download URL | neural_trees-0.8.0.tar.gz |
|---|---|
| Size | 135.5 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
e1b90374e6192b17c7b9e43c106dfe25d8f294f42cdb0c09f5e37c20e28751a7
|
|
BLAKE2b-256 checksum How to use checksums |
2db8f92f708da5331c12e4389315afeba01cfa09b12a305e2e0a6dd72adca2aa
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.2.0 CPython/3.9.7
|
Release files / neural_trees-0.8.0-py3-none-any.whl
| Download URL | neural_trees-0.8.0-py3-none-any.whl |
|---|---|
| Size | 99.9 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
6f7eba3bf828ba4fa616f8b551f321c0401af44be2c3560452ad333f200bfeac
|
|
BLAKE2b-256 checksum How to use checksums |
0d4a155ebcab06e6809ec1de6d619c646805da49645eaa9fbdb39166953d2777
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.2.0 CPython/3.9.7
|














