
NeuroAtlas: Benchmarking Foundation Models for
Clinical EEG and Brain-Computer Interfaces
Konstantinos Kontras1,2,*, Trui Osselaer1,*, Stylianos G. Mouslech1,*,
Angeliki-Ilektra Karaiskou1,*, Guido Gagliardi1,*, Thomas Strypsteen1,*,
Mohammad Hossein Badiei1, Anku Rani2, Maarten Vanmarcke1,
Miguel Bhagubai1, Chanakya Ekbote2, Jaedong Hwang2,
Christos Chatzichristos1, Paul Pu Liang2, Maarten De Vos1
1KU Leuven 2MIT *Equal contribution
Paper | Documentation | Citation
Abstract
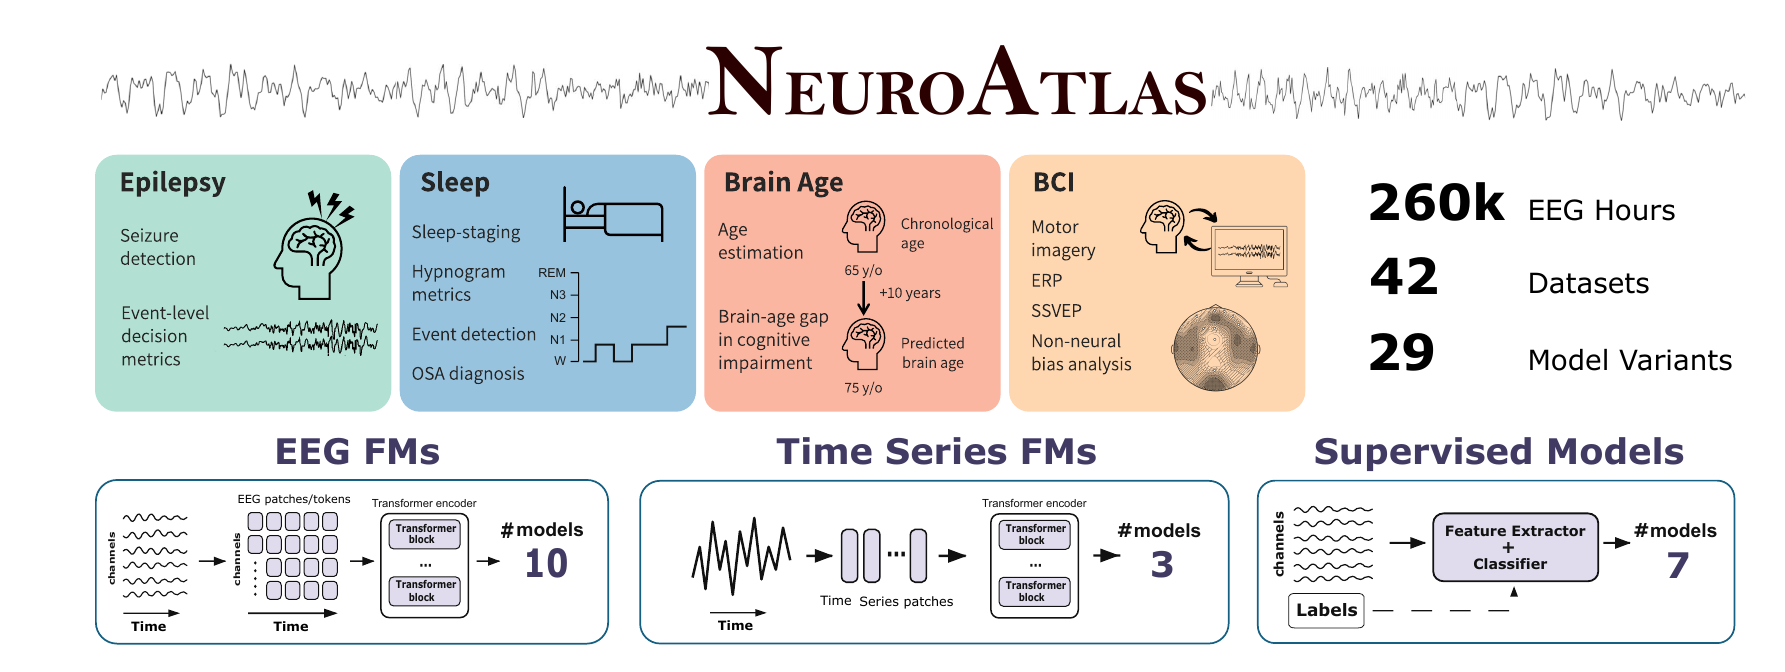
Foundation models (FMs) promise to extract unified representations that generalize across downstream tasks. They have emerged across fields including electroencephalography (EEG), but it is less clear how effective they are in this particular field. Published evaluations differ in datasets, in the EEG-specific preprocessing that might influence reported results, and in the reported metrics frequently obscuring the clinical relevance in EEG. We introduce NeuroAtlas, the largest EEG benchmark to date: 42 datasets and ∼260k hours covering clinical EEG (epilepsy, sleep medicine, brain age estimation) and brain-computer interfaces, and include multiple datasets per task along with bespoke clinical evaluation metrics. Besides evaluating EEG-FMs with respect to supervised baselines, we present results from generic time-series FMs. We report three findings. First, EEG-specific FMs do not consistently outperform time-series FMs which have neither EEG-focused architectures nor been pretrained on EEG. Second, standard machine learning metrics are insufficient to assess clinical utility: Thus, we thoroughly evaluate more appropriate measures such as the quality of event-level decision-making, hypnogram-derived features, and the brain-age gap in the domains of epilepsy, sleep and brain age respectively. Third, model rankings and performance can vary substantially within domains. We conclude that pretrained models perform largely on par, with only narrow advantages for a few, and that current FMs do not yet deliver on the promise of an out-of-the-box unified EEG model. NeuroAtlas exposes this gap and provides the datasets and metrics for the next generation of unified EEG-FMs.
Overview
This repository contains the code to run the NeuroAtlas benchmark. It is installed as a Python
package that provides the neuroatlas command. The command downloads datasets and model weights,
extracts embeddings with a frozen backbone, trains the probes on the paper's folds and reports
the results.
The benchmark has 12 tasks across four domains, 42 datasets and 44 model checkpoints. The models fall into four groups: EEG foundation models, time-series foundation models, supervised baselines, and randomly initialized baselines.
Installation
We tested the code on Linux with Python 3.11.
pip install "neuroatlas-bench[fm]" -c https://raw.githubusercontent.com/kkontras/NeuroAtlas/v0.1.0/requirements-fm.txt
The constraints file pins every dependency to the version used in the paper. The install takes
about 5 minutes and 6.5 GB of disk space. The command and the Python import are both neuroatlas.
Some models and datasets need extra packages:
# BCI datasets (MOABB)
pip install "neuroatlas-bench[fm,bci]" -c https://raw.githubusercontent.com/kkontras/NeuroAtlas/v0.1.0/requirements-fm.txt
pip install --no-deps "moabb==1.2.0"

# Chronos and MOMENT
pip install "neuroatlas-bench[fm,ts]" -c https://raw.githubusercontent.com/kkontras/NeuroAtlas/v0.1.0/requirements-fm.txt
pip install --no-deps "momentfm==0.1.4"
Moirai needs an older PyTorch and has its own environment, described in requirements-tsfm.txt.
The default PyTorch build needs a GPU with compute capability 7.5 or higher and a CUDA 13 driver. On older hardware, install a CUDA 12 build of PyTorch first. The probes themselves run on the CPU.
To work on the code, or to run run/default_runs.sh and the notebook in reproduction/, install
from a clone instead:
git clone https://github.com/kkontras/NeuroAtlas.git
cd NeuroAtlas
pip install -e ".[fm]" -c requirements-fm.txt
Note that the package on PyPI called neuroatlas is unrelated to this project.
Quick start
Choose a project folder. Data, cache, results and model weights go into sub-folders of it:
neuroatlas config init ~/neuroatlas
To keep one of them elsewhere, add for example --data-root /path/to/datasets.
Download Sleep-EDF and the BIOT weights, then run sleep staging:
neuroatlas data download sleep_edf_expanded --mirror aws
neuroatlas models download biot_pretrained

neuroatlas check sleep_stage -m biot_pretrained          # quick test on one batch
neuroatlas run sleep_stage -m biot_pretrained --debug    # fold 0 only
neuroatlas run sleep_stage -m biot_pretrained            # all folds
neuroatlas results sleep_stage
See the walkthrough for a full example with the expected output.
Running a benchmark
Every benchmark runs the same way:
neuroatlas show epilepsy                          # description, datasets and commands
neuroatlas run epilepsy -m cbramod_pretrained     # its default dataset (Siena)
neuroatlas run epilepsy -m all_fm --dataset full  # all EEG FMs on all datasets you have
neuroatlas results epilepsy
neuroatlas list benchmarks lists all twelve, and neuroatlas show <benchmark> describes one.
To run many jobs on a cluster, neuroatlas submit writes one HTCondor or SLURM job per dataset
and model. run/default_runs.sh lists every experiment in the paper.
Data
Each dataset has its own folder in the data folder (~/neuroatlas/data/<dataset> with the setup
above). Run neuroatlas data status to see which datasets you have and how to get the others.
| Access | Datasets |
|---|---|
Open, downloaded with neuroatlas data download |
Sleep-EDF Expanded, HMC, UCDDB, DOD, Siena, CHB-MIT, Helsinki Neonatal, Bonn, EEGMat, ArithmeticTask, 14 MOABB BCI datasets |
NSRR account, then neuroatlas config token nsrr |
CFS, HomePAP, MESA, MrOS, SHHS, STAGES, WSC |
| Request from the data owners | DCSM, ISRUC, MASS, PhysioNet 2026, NMT, EPILEPSIAE, TUSZ, TUAB, DREAMER |
| Available from the authors | SeizeIT1, SeizeIT2 |
If you already have a dataset, point to it with neuroatlas config set <dataset>.data_root DIR.
To test the setup before a large download, neuroatlas data download <dataset> --first 5
downloads only the first five recordings.
Models
| Group | Selector | Models |
|---|---|---|
| EEG foundation models | all_fm |
BIOT, CBraMod, EEGPT, LaBraM, Neuro-GPT, NeuroLM, NeuroRVQ, REVE, SleepFM, ST-EEGFormer (S/B/L) |
| Time-series foundation models | all_ts |
Chronos-T5 (T/S/B/L), Moirai (S/B/L), MOMENT (S/B/L) |
| Supervised baselines | all_supervised |
CoRe-Sleep, SleepTransformer, SleePyCo, DeepSOZ-HEM, Seizure-Transformer, EEGNet (12 checkpoints) |
| Random initialization | all_random |
CBraMod, REVE |
Download weights with neuroatlas models download <model> and list all checkpoints with
neuroatlas list models. Each benchmark only includes the models that the paper evaluates on it.
Repository structure
src/neuroatlas/
├── cli/                    command-line interface
├── benchmarking_helpers/   runner, embedding cache, probes, channel maps
├── entrypoints/            embed, probe and hypnogram steps
├── extensions/
│   ├── datasets/           dataset readers
│   ├── models/backbones/   model wrappers
│   └── tasks/              probe tasks
└── configs/                benchmarks, datasets, channel maps, folds, task settings
run/default_runs.sh         all experiments in the paper
docs/                       user guide, walkthrough, command reference
reproduction/               step-by-step notebook of the pipeline
License
The code is released under the MIT license (see LICENSE). The vendored
Seizure-Transformer code (MIT) and MOABB readers (BSD-3-Clause) keep their original licenses.
DeepSOZ-HEM is GPL-3.0 and is not included; neuroatlas models download deepsoz_hem_pretrained
fetches it from the original repository. Each dataset
is subject to its own license and terms of use.
Citation
@article{kontras2026neuroatlas,
  title   = {NeuroAtlas: Benchmarking Foundation Models for Clinical EEG and Brain-Computer Interfaces},
  author  = {Kontras, Konstantinos and Osselaer, Trui and Mouslech, Stylianos G. and
             Karaiskou, Angeliki-Ilektra and Gagliardi, Guido and Strypsteen, Thomas and
             Badiei, Mohammad Hossein and Rani, Anku and Vanmarcke, Maarten and
             Bhagubai, Miguel and Ekbote, Chanakya and Hwang, Jaedong and
             Chatzichristos, Christos and Liang, Paul Pu and De Vos, Maarten},
  journal = {arXiv preprint arXiv:2605.14698},
  year    = {2026}
}
Contact
For questions, contact Konstantinos Kontras (konstantinos.kontras@kuleuven.be) or open an issue.
1 maintainer

Metadata
1 maintainer
Release files for neuroatlas-bench 0.1.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| neuroatlas_bench-0.1.0.tar.gz | 1.2 MB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| neuroatlas_bench-0.1.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 2.7 MB
Release files / neuroatlas_bench-0.1.0.tar.gz
| Download URL | neuroatlas_bench-0.1.0.tar.gz |
|---|---|
| Size | 1.2 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
953ce4fd92c1a1afffc825700b4be73b67d04ed475d72fc129e0d82af2ddcf68
|
|
BLAKE2b-256 checksum How to use checksums |
ab6c4494c295bc0162effddc913bb8e08223d2f827ab9b2d7868992be2ec73f7
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 9, 2026.
Transparency logRelease files / neuroatlas_bench-0.1.0-py3-none-any.whl
| Download URL | neuroatlas_bench-0.1.0-py3-none-any.whl |
|---|---|
| Size | 1.5 MB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
c3892f9e2c285394da3be6a89b621d7a486ea2a8bb78c8c3b5023206ae722d0a
|
|
BLAKE2b-256 checksum How to use checksums |
a7a3eb88268215ce86b4c7de0cb5d5b5e1549845c9c28b2e71cbf6f1489453b3
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 9, 2026.
Transparency log













