
NeuSpell: A Neural Spelling Correction Toolkit
Contents
- Installation & Quick Start
- Introduction
- Pretrained models
- Demo Setup
- Datasets
- Applications
- Additional Requirements
Updates
- April 2021:
neuspellis now available through pip. To install, simply dopip install neuspell. - March, 2021: Code-base reformatted. Addressed some bug fixes.
- November, 2020: Neuspell's
BERTpretrained model is now available as part of huggingface models asmurali1996/bert-base-cased-spell-correction. We provide an example code snippet at ./scripts/huggingface for curious practitioners. - September, 2020: This work is accepted at EMNLP 2020 (system demonstrations)
Installation
git clone https://github.com/neuspell/neuspell; cd neuspell
pip install -e .
To install extra requirements,
pip install -r extras-requirements.txt
or individually as (NOTE: For zsh, use ".[elmo]" and ".[spacy]")
pip install -e .[elmo]
pip install -e .[spacy]
Additionally, spacy models can be downloaded as:
python -m spacy download en_core_web_sm
Follow Additional Requirements for installing non-neural spell checkers- Aspell and Jamspell.
Then, download pretrained models following Pretrained models
Here is a quick-start code snippet (command line usage). (See test.py for more usage
patterns)
""" select spell checkers """
from neuspell import BertChecker

""" load spell checkers """
checker = BertChecker()
checker.from_pretrained()

""" spell correction """
checker.correct("I luk foward to receving your reply")
# → "I look forward to receiving your reply"
checker.correct_strings(["I luk foward to receving your reply", ])
# → ["I look forward to receiving your reply"]
checker.correct_from_file(src="noisy_texts.txt")
# → "Found 450 mistakes in 322 lines, total_lines=350"

""" evaluation of models """
checker.evaluate(clean_file="bea60k.txt", corrupt_file="bea60k.noise.txt")
# → data size: 63044
# → total inference time for this data is: 998.13 secs
# → total token count: 1032061
# → confusion table: corr2corr:940937, corr2incorr:21060,
#                    incorr2corr:55889, incorr2incorr:14175
# → accuracy is 96.58%
# → word correction rate is 79.76%

""" fine-tuning on domain specific dataset """
checker.finetune(clean_file="sample_clean.txt", corrupt_file="sample_corrupt.txt")
# Once the model is fine-tuned, you can use the saved model checkpoint path
#   to load and infer by calling `checker.from_pretrained(...)` as above
Alternatively, once can also select and load a spell checker differently as follows:
from neuspell import SclstmChecker
checker = SclstmChecker()
checker = checker.add_("elmo", at="input")  # elmo or bert, input or output
checker.from_pretrained()
checker.finetune(clean_file="./data/traintest/test.bea322", corrupt_file="./data/traintest/test.bea322.noise")
Introduction
NeuSpell is an open-source toolkit for context sensitive spelling correction in English. This toolkit comprises of 10 spell checkers, with evaluations on naturally occurring mis-spellings from multiple (publicly available) sources. To make neural models for spell checking context dependent, (i) we train neural models using spelling errors in context, synthetically constructed by reverse engineering isolated mis-spellings; and (ii) use richer representations of the context.This toolkit enables NLP practitioners to use our proposed and existing spelling correction systems, both via a simple unified command line, as well as a web interface. Among many potential applications, we demonstrate the utility of our spell-checkers in combating adversarial misspellings.
Demo available at http://neuspell.github.io/
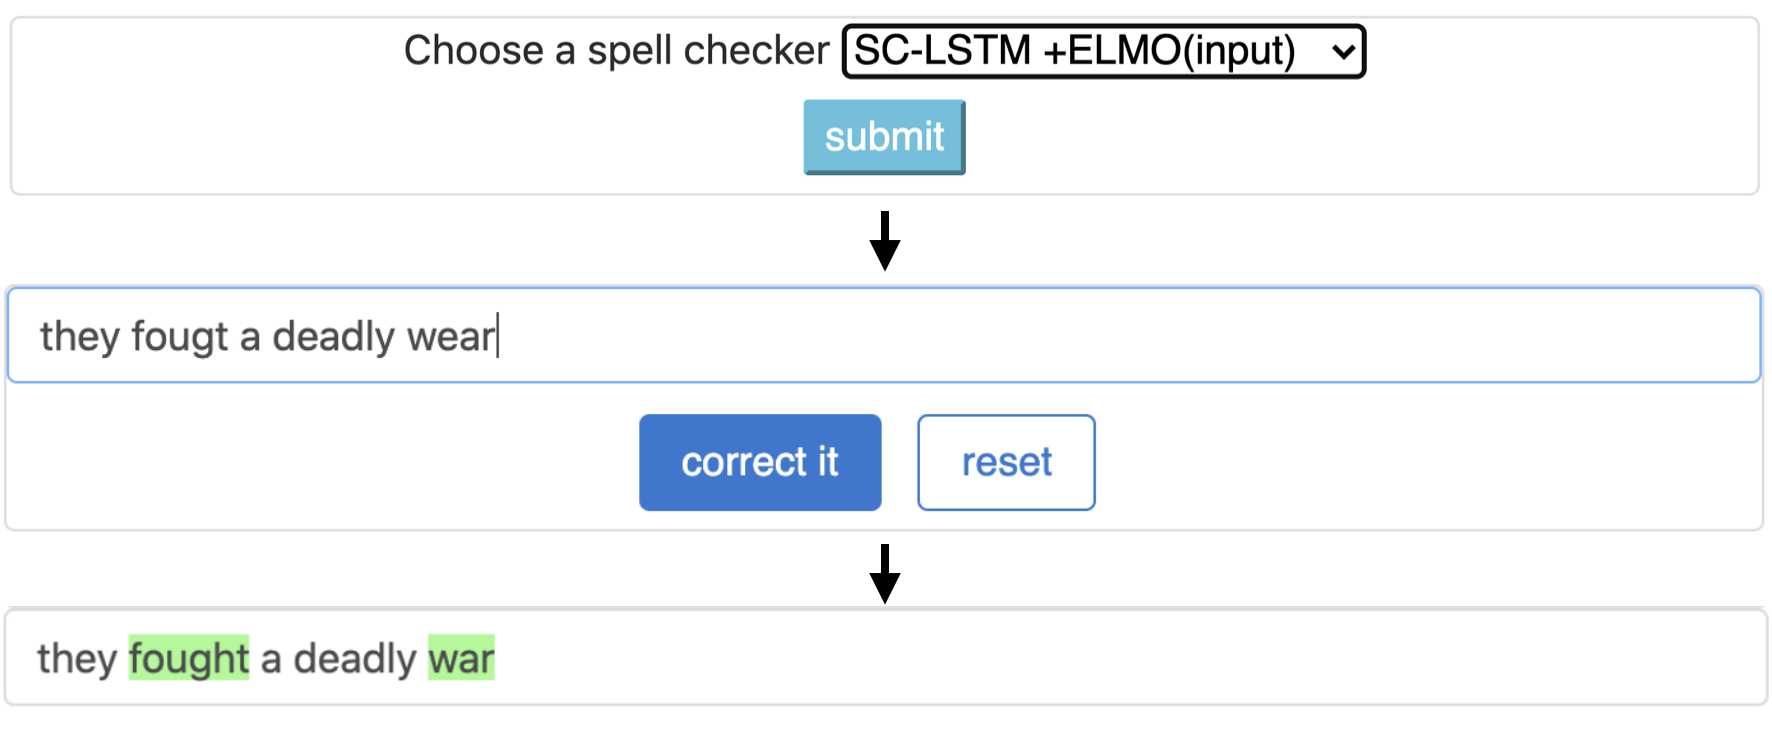
List of neural models in the toolkit:
CNN-LSTMSC-LSTMNested-LSTMBERTSC-LSTM plus ELMO (at input)SC-LSTM plus ELMO (at output)SC-LSTM plus BERT (at input)SC-LSTM plus BERT (at output)
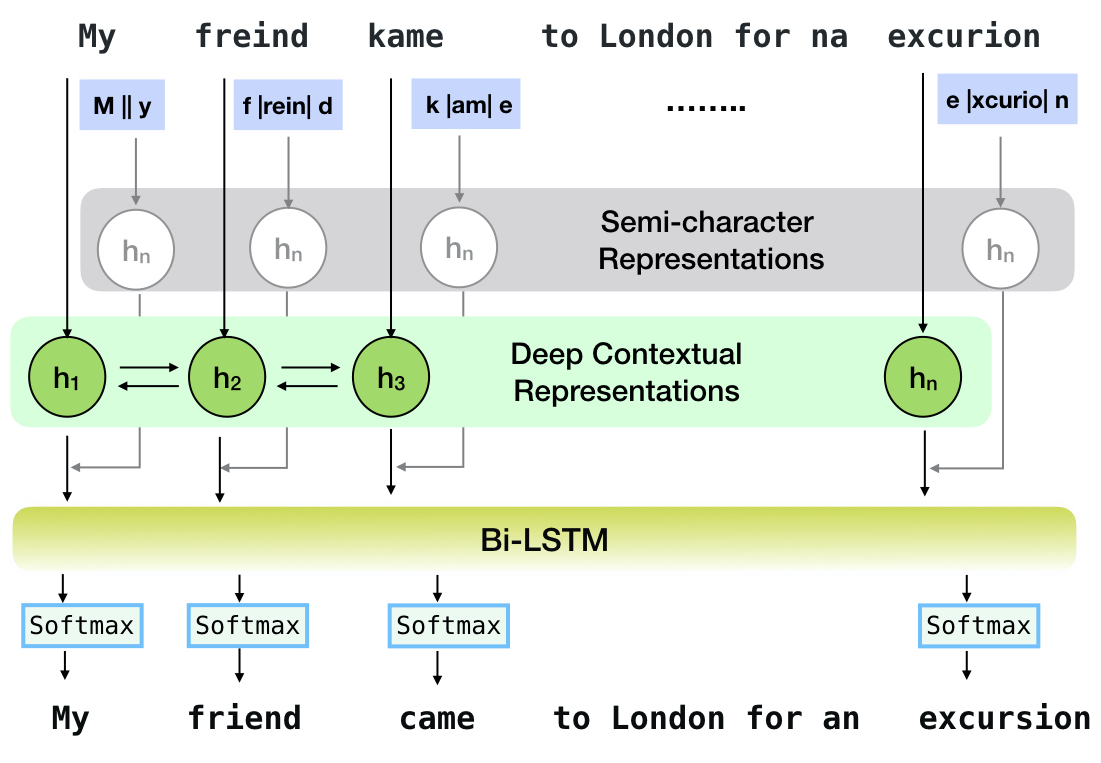
This pipeline corresponds to the `SC-LSTM plus ELMO (at input)` model.
Performances
| Spell Checker |
Word Correction Rate |
Time per sentence (in milliseconds) |
|---|---|---|
Aspell |
48.7 | 7.3* |
Jamspell |
68.9 | 2.6* |
CNN-LSTM |
75.8 | 4.2 |
SC-LSTM |
76.7 | 2.8 |
Nested-LSTM |
77.3 | 6.4 |
BERT |
79.1 | 7.1 |
SC-LSTM plus ELMO (at input) |
79.8 | 15.8 |
SC-LSTM plus ELMO (at output) |
78.5 | 16.3 |
SC-LSTM plus BERT (at input) |
77.0 | 6.7 |
SC-LSTM plus BERT (at output) |
76.0 | 7.2 |
Performance of different correctors in the NeuSpell toolkit on the BEA-60K dataset with real-world spelling
mistakes. ∗ indicates evaluation on a CPU (for others we use a GeForce RTX 2080 Ti GPU).
Pretrained models
Checkpoints
Run the following to download checkpoints of all neural models
cd data/checkpoints
python download_checkpoints.py
See data/checkpoints/README.md for more details. You can alternatively choose to download only selected models'
checkpoints.
Demo Setup
In order to setup a demo, follow these steps:
- Do Installation
- Download checkpoints
- Start a flask server at neuspell/flask-server by running
CUDA_VISIBLE_DEVICES=0 python app.py(on GPU) orpython app.py(on CPU)
Datasets
Download datasets
Run the following to download datasets
cd data/traintest
python download_datafiles.py
See data/traintest/README.md for more details.
Synthetic Training Dataset Creation
The toolkit offers 4 kinds of noising strategies to generate synthetic parallel training data to train neural models for spell correction.
RANDOMWord ReplacementProbabilistic Replacement- A combination of
Word ReplacementandProbabilistic Replacement
Train files are dubbed with names .random, .word, .prob, .probword respectively. For each
strategy, we noise ∼20% of the tokens in the clean corpus. We use 1.6 Million sentences from
the One billion word benchmark dataset as our clean corpus.
Potential applications for practitioners
- Defenses against adversarial attacks in NLP
- example implementation available in folder
./applications/Adversarial-Misspellings
- example implementation available in folder
- Improving OCR text correction systems
- Improving grammatical error correction systems
- Improving Intent/Domain classifiers in conversational AI
- Spell Checking in Collaboration and Productivity tools
Additional requirement
Requirements for Aspell checker:
wget https://files.pythonhosted.org/packages/53/30/d995126fe8c4800f7a9b31aa0e7e5b2896f5f84db4b7513df746b2a286da/aspell-python-py3-1.15.tar.bz2
tar -C . -xvf aspell-python-py3-1.15.tar.bz2
cd aspell-python-py3-1.15
python setup.py install
Requirements for Jamspell checker:
sudo apt-get install -y swig3.0
wget -P ./ https://github.com/bakwc/JamSpell-models/raw/master/en.tar.gz
tar xf ./en.tar.gz --directory ./
Citation
@inproceedings{jayanthi-etal-2020-neuspell,
    title = "{N}eu{S}pell: A Neural Spelling Correction Toolkit",
    author = "Jayanthi, Sai Muralidhar  and
      Pruthi, Danish  and
      Neubig, Graham",
    booktitle = "Proceedings of the 2020 Conference on Empirical Methods in Natural Language Processing: System Demonstrations",
    month = oct,
    year = "2020",
    address = "Online",
    publisher = "Association for Computational Linguistics",
    url = "https://www.aclweb.org/anthology/2020.emnlp-demos.21",
    doi = "10.18653/v1/2020.emnlp-demos.21",
    pages = "158--164",
    abstract = "We introduce NeuSpell, an open-source toolkit for spelling correction in English. Our toolkit comprises ten different models, and benchmarks them on naturally occurring misspellings from multiple sources. We find that many systems do not adequately leverage the context around the misspelt token. To remedy this, (i) we train neural models using spelling errors in context, synthetically constructed by reverse engineering isolated misspellings; and (ii) use richer representations of the context. By training on our synthetic examples, correction rates improve by 9{\%} (absolute) compared to the case when models are trained on randomly sampled character perturbations. Using richer contextual representations boosts the correction rate by another 3{\%}. Our toolkit enables practitioners to use our proposed and existing spelling correction systems, both via a simple unified command line, as well as a web interface. Among many potential applications, we demonstrate the utility of our spell-checkers in combating adversarial misspellings. The toolkit can be accessed at neuspell.github.io.",
}
1 maintainer

Metadata
1 maintainer
Release files for neuspell 1.0.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| neuspell-1.0.0.tar.gz | 143.2 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| neuspell-1.0.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 327.5 kB
Release files / neuspell-1.0.0.tar.gz
| Download URL | neuspell-1.0.0.tar.gz |
|---|---|
| Size | 143.2 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
91c8918a132a21eb45e8c87cecdb9593ce2eb88379fe534745c7f6ffdab6a51e
|
|
BLAKE2b-256 checksum How to use checksums |
0c27397c5275ec55488a13f379f87b597ad7094b3eaa205da5e31dc5bba31b6a
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/3.4.1 importlib_metadata/3.10.0 pkginfo/1.7.0 requests/2.25.1 requests-toolbelt/0.9.1 tqdm/4.59.0 CPython/3.7.5
|
Release files / neuspell-1.0.0-py3-none-any.whl
| Download URL | neuspell-1.0.0-py3-none-any.whl |
|---|---|
| Size | 184.3 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
4afbba61cf9d2db5e32e4cc5a23f5cc12a516188ba09b09ddafbe07822353c3b
|
|
BLAKE2b-256 checksum How to use checksums |
824edc440b25c326b701ddfe57bfe80fc7377880296c4ebb426109dcca0d62ba
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/3.4.1 importlib_metadata/3.10.0 pkginfo/1.7.0 requests/2.25.1 requests-toolbelt/0.9.1 tqdm/4.59.0 CPython/3.7.5
|














