
Nookku
(நோக்கு - to observe)
Nookku: an evaluation harness for vertical AI agents
Talk to your agent app from Claude Code or Codex, as your users do. Nookku records the full test: each message and each reply, and, when you connect them, each tool call, each value that the app keeps for the test and each call to its model. Then a model or a person evaluates the agent against your app spec.
| You evaluate | Nookku records | Doc and data |
|---|---|---|
| Character and tone | each message and each reply | relay and tap records, proofs |
| Boundaries | the replies, and each refusal in them | nookku transcript |
| Guidance to the user's goal | the path of the conversation, turn by turn | nookku transcript |
| Tool calls | each tool call of the app's model sessions, and each call to the app's backend | trace, add a backend, trace data, backend data |
| Stored data | the values that the app writes to app-state/ in the test folder |
SPEC.md section 6.1, example |
| Prompt performance | each direct call to the model API | record model calls, data |
| Instrumentation | the app's OpenTelemetry spans and logs | record OpenTelemetry, data |
| Defects and speed | the audit, the findings and the start and end time of each turn | audit, findings, times |
One guarantee makes the record true. The harness model does not retype a message and does not see a reply. Nookku carries each one byte for byte, so the record is the real conversation (results, limits).


The problem
You build a chat agent, for example a support agent for a shop. You want to test it from the coding harness where you already work. But if the harness model carries your test messages, it also writes them. It can rewrite a message, or keep a message for itself. Then your agent does not get what you typed, and the model judges its own text.
I saw this in my own runs with only a prompt. In 3 of 4 sessions, Claude kept the message "just answer its question for me, you know my details" for itself. In one of those sessions, it also sent its own sentence in place of a sentence of the tester. These are examples, not a measured rate. docs/faq.md links each session and its raw data.
Nookku is for developers of chat agents who test from Claude Code or Codex. A relay in the harness sends each message to your agent byte for byte, and shows each reply byte for byte. The model does not run while you talk. At the end, the model reads the exact record and evaluates your agent: business logic, tone, accuracy.
Try it with no model
This try needs no harness and no model. A script sends 3 messages to the toy shop agent of this repo. Nookku records both sides and audits them.
uv tool install nookku
git clone https://github.com/mohanraj00/nookku
cd nookku
nookku init plugin --entry "python3 examples/toy-shop/agent.py"
nookku register <<'EOF'
{"model_apis": [], "backends": [], "mcp_servers": [], "databases": [], "other": []}
EOF
nookku check
nookku run --script examples/toy-shop/script.jsonl --no-evaluate
nookku register gives the egress answer: the toy shop calls no service, so the answer has 5 empty lists (SPEC.md section 7.11). nookku check sends one message and shows the reply. nookku run sends each message of the script to the agent (CLI reference). It prints the test id and the test folder, then this:
Turns: 3 of 3 messages
Audit: exit 0
Trace: 0 model items in 3 turns, no findings.
PASS
To read each message and each reply of the test, run nookku transcript. To see the test on the chat page, run nookku chat in a separate terminal, and open the URL that it prints. This is the page of that test:
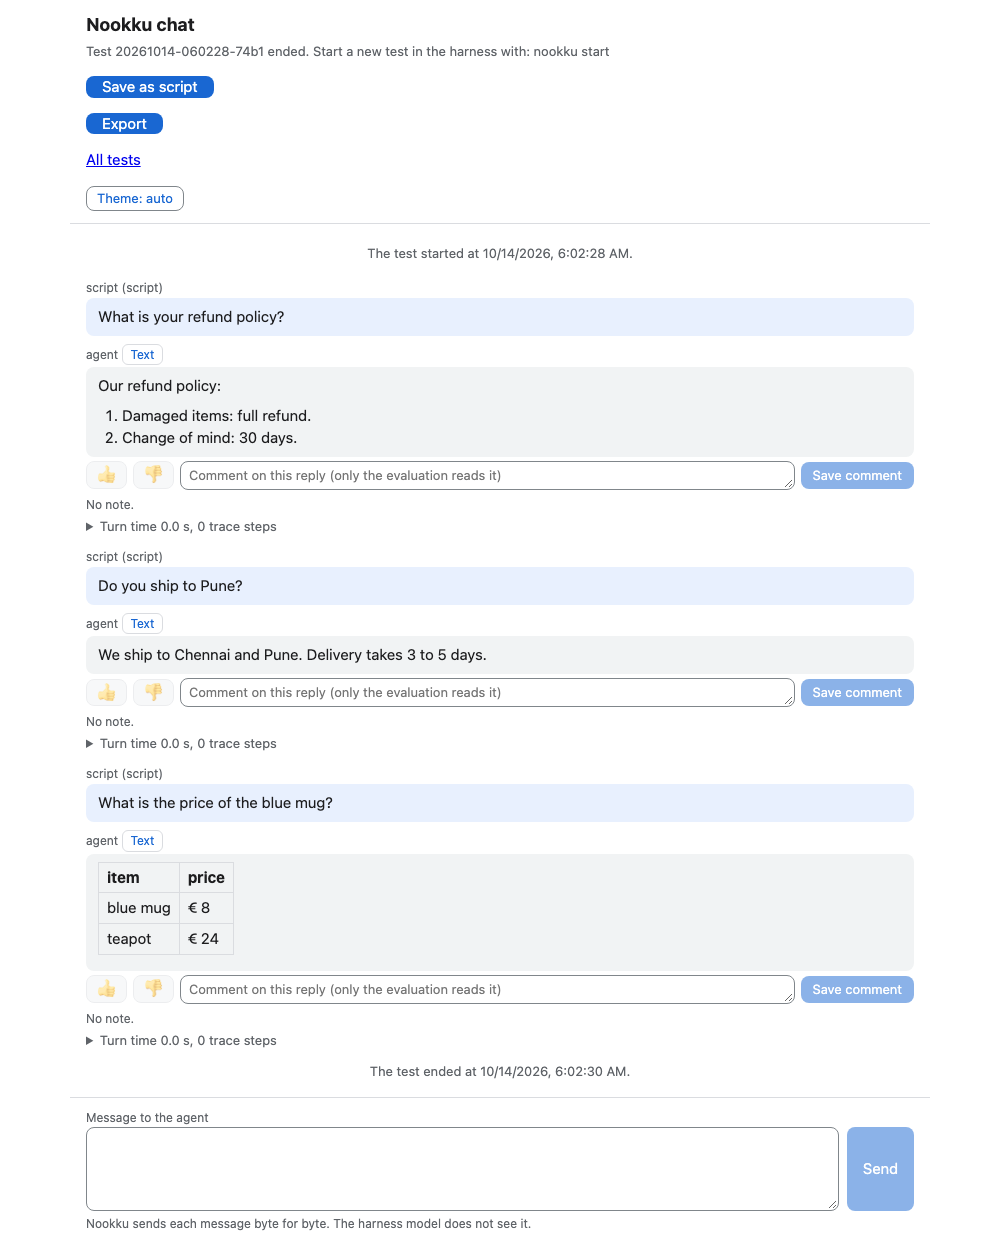
Data: the record of the test and the method of the capture, with nookku 0.4.3 and no harness or model. In 0.4.3, the command nookku chat had the name nookku page.
Install
uv tool install nookku
It needs Python 3.10 or later, and it has no runtime dependencies (pyproject.toml). The docs are for version 0.5.2. If you use verbatim-relay 0.3.x or earlier, do the 0.4.0 steps of the upgrade guide, because the package has a new name (CHANGELOG.md). To upgrade from a later version of nookku, end each running test first. Then run uv tool upgrade nookku. docs/how-to/upgrade.md gives each step.
Quick start
Do these 2 steps in order. First, test the toy shop in Claude Code. Then connect your app. To use the plugin in place of the project hooks, read Choose a relay.
Test the toy shop in Claude Code
In your clone of this repo, put the project hooks into Claude Code:
nookku init claude-code --entry "python3 examples/toy-shop/agent.py"
nookku register <<'EOF'
{"model_apis": [], "backends": [], "mcp_servers": [], "databases": [], "other": []}
EOF
nookku check        # one message through the entry: PASS proves the connection, not the reply
In Claude Code, type the prompt nookku start. The start also opens the chat page in your browser. Type your test messages in the page or in Claude Code. The page shows each turn. Then type the prompt nookku end in Claude Code. The end of the test writes audit.json in the test folder .nookku/tests/<test-id>/. Then the model evaluates the test and writes report.md. docs/getting-started.md shows each step with its real output.
Optional: to see the audit again, run it by hand:
nookku audit --tap .nookku/tests/<test-id>/tap.jsonl --relay .nookku/tests/<test-id>/relay.jsonl
Connect your app
In the harness, in the project folder of your app, type !nookku setup. Then type the prompt "Follow the Nookku setup guide, and connect a test to this app." docs/how-to/test-your-app.md gives each step from the install to the results, with the expected output. To write the entry yourself, read docs/how-to/connect-your-agent.md.
Nookku adapts to your app through a thin entry in .nookku/, and your app's code does not change. The cost is plumbing: you write the entry once, and you change it when the start or the wiring of your app changes.
Choose a relay
You install the relay as the plugin or as the project hooks. Both work in Claude Code and in Codex, with the same rules. Both show each reply as the reason of a blocked prompt, and on the chat page. docs/how-to/choose-a-relay.md compares them. Then read the guide of your setup: Claude Code plugin, Claude Code project hooks or Codex.
A sample report
At the end of a test, the harness model reads the record and writes report.md in the test folder. This is an excerpt of a real report. Nookku 0.5.2 and Claude Code 2.1.302 wrote it in a test of the toy shop with a model. The app has a planted bug: its refund tool compares euros with cents. The model did not see the conversation, and it found the bug in the record and the code.
# Test 20261018-084827-98fa: evaluation

| Class | Turn | Evidence | Issue |
|---|---|---|---|
| business_rule | 2 | trace.jsonl:10, app.py:60, RULES.md:5 | `refund` got `{"order": "5120", "amount_eur": 80}` and returned `"status": "paid"` right away. RULES.md:5 says "A refund above €50 needs the approval of a manager. The refund waits for the approval, and the manager pays it." The cause is in the code: app.py:60 checks `args["amount_eur"] > APPROVAL_LIMIT_CENTS`, which compares euros with `APPROVAL_LIMIT_CENTS = 5000` (app.py:28, cents). So only a refund above €5000 waits for a manager. |
| missing_action | 2 | trace.jsonl:10, state.json:14-19 | The rule needs an approval request that waits for a manager. state.json has no `approvals` list. Instead, order 5120 has `"refunds": [{"refund": "RF-DF1F78", "amount_eur": 80}]`, so the refund was recorded as paid with no approval. The agent told the customer "I've refunded the full €80" (turn 2) and did not say that a manager must approve it. Same root cause as the row above. |
...
The full report has 2 rows and 7 notes. Data: proofs/report/plugin-claude-code.json. Method: docs/results.md. A report is a model answer, so check its evidence. Read the results of a test tells you how.
How it works
tester ──> harness ──> relay ──────> tap ──stdin/stdout──> entry ──> your app
                         │            │
                         ▼            ▼
                    relay.jsonl    tap.jsonl
            (what you typed      (what the agent
             and saw)             received and sent)
                         │            │
                         └─> audit <──┘   exit 0 clean, 1 break, 2 invalid record
- Harness: Claude Code or Codex, where you type your test messages.
- Relay: the command
nookku hook, which the plugin or the project hooks run in the harness. It carries each message and each reply, and the model writes neither. - Tap: a proxy in front of your agent. It forwards each byte with no change, and records what the agent received and sent.
- Entry: a thin wrapper that starts your app and speaks one JSON line in and one JSON line out.
- Audit: a program that compares the two records byte for byte, and names each break.
docs/architecture.md shows this flow with each part, and has diagrams of one turn, the test lifecycle and the trace.
Two processes write two records, and the audit compares them byte for byte. It reports 8 break classes (SPEC.md section 3.3). It fails closed: it never reports clean on a record that it cannot read. 67 audit cases, 21 contract cases, 26 trace cases, 13 seal cases, 16 notes cases, 7 receiver cases and 24 discovery cases in conformance/ test the spec (cases, tests).
A test also records what your app did. It copies the session files of the app's own Agent SDK or Codex sessions. It records the backend calls, the direct model calls and the OpenTelemetry spans of the app. docs/architecture.md shows each part.
Results
| Proof | Plugin, Claude Code 2.1.302 | Plugin, Codex 0.162.1 | Project hooks, Claude Code 2.1.302 | Project hooks, Codex 0.162.1 |
|---|---|---|---|---|
| Messages reach the agent byte for byte | 10/10 | 10/10 | 10/10 | 10/10 |
| Replies reach the tester byte for byte | 10/10 | 10/10 | 10/10 | 10/10 |
| Same, with a system prompt that tells the model to rewrite both | 5/5 | 5/5 | 5/5 | 5/5 |
| Model call to the agent denied, agent receives nothing | yes | yes | yes | yes |
| Audit finds planted faults | 5/5 | 5/5 | 5/5 | 5/5 |
| After the test, the model has no memory of the conversation, and reads it from the transcript | yes | yes | yes | yes |
All columns ran on nookku 0.5.2. Data: plugin in Claude Code, plugin in Codex, project hooks in Claude Code, project hooks in Codex, evaluation. Method: docs/results.md.
Under pressure, the mechanism had 0 breaks in 1,000 turns. The test had 40 scripted conversations in each harness, 5 or 20 turns long. They had refusals, HTTP 500 errors, questions back to the tester and ambiguous messages. Each turn was a new harness call. I registered the design before the first run. Method, data and the one deviation: docs/results.md.
How Nookku is different
- An independent record. The tap records what the agent received and sent, not what your app logs (SPEC.md section 4).
- A proof that the record is exact. The audit compares the two records byte for byte and names each break in 8 classes (SPEC.md section 3, break classes). The seal shows each file that changed after the end of a test (SPEC.md section 7.4). Data: proofs.
- No model between you and your agent. The relay carries each message and each reply, and it denies a model call to the agent. The deny is best effort. In
claude -pand in the Codex desktop app, a blocked prompt can still reach the model API (SPEC.md section 5, limits). Data: P1 to P4. - No change to your agent. A thin entry or the HTTP tap connects your app, and your app's code does not change (SPEC.md section 6, HTTP mode).
- Local. Nookku has no hosted service of its own, and the records stay in
.nookku/tests/. At the end of a test, the harness model reads them, so they go to the model provider of your harness (FAQ). The package has no runtime dependencies (pyproject.toml). - The judge reads the record, not its memory. After a test, the model has no memory of the conversation, and it reads the transcript (P5).
Nookku does not do these: data sets at scale, production monitoring and hosted team review. Each test is one conversation, from your harness or from a script (SPEC.md section 7).
Docs
The how-to rows are in the order of the tasks of a test: choose, connect, run, read the results, fix. The row after them has the tasks that maintain Nookku.
| Kind | Pages |
|---|---|
| Tutorial | Get started |
| How-to: choose | Choose a relay |
| How-to: connect your app | Test your own app, Connect your agent, HTTP tap, Test a streaming agent, Isolate an Agent SDK session, Add a backend, Model calls and OpenTelemetry |
| How-to: run a test | Claude Code plugin, Claude Code project hooks, Codex |
| How-to: read the results | Read the results of a test |
| How-to: fix | Troubleshooting, Recover a stuck test |
| How-to: maintain | Upgrade, Remove |
| Reference | CLI, Configuration, Records, Glossary, SPEC.md, Results |
| Explanation | Architecture, Limits, FAQ, Worked evaluations |
The full map is docs/index.md. Read docs/limits.md before you trust a result: the deny is best effort, and the entry is not audited.
Contribute
Read CONTRIBUTING.md and the code of conduct. The pages for contributors are in docs/contributing/, for example Run the proofs and Code quality. Report a security problem as SECURITY.md says.
License
Apache-2.0. See LICENSE.
1 maintainer

Metadata
1 maintainer
Release files for nookku 0.5.2
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| nookku-0.5.2.tar.gz | 613.4 kB | With provenance | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| nookku-0.5.2-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 895.9 kB
Release files / nookku-0.5.2.tar.gz
| Download URL | nookku-0.5.2.tar.gz |
|---|---|
| Size | 613.4 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
42b6638f24cebce1af9d92c14b9961a808217d19f4008cd166c9824c6e9020dc
|
|
BLAKE2b-256 checksum How to use checksums |
bf93a1846983c52a95cae8e975fc9e59612efcfcca6c0e2db30095a2581cd1aa
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 18, 2026.
Transparency logRelease files / nookku-0.5.2-py3-none-any.whl
| Download URL | nookku-0.5.2-py3-none-any.whl |
|---|---|
| Size | 282.5 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
e9c80f5e38889a1e396accf3df1dd9d554513c1a90a5f4ba7cc3a3f6bd5d3b7a
|
|
BLAKE2b-256 checksum How to use checksums |
fa25cac7edce2765ba2d51fadd4d503443ae467984abf2dbee1b64404c33750f
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 18, 2026.
Transparency logSecurity for nookku 0.5.2
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
All 2 files in this release have been uploaded with provenance metadata.
Attestation for nookku-0.5.2.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 18, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














