
notebook-to-pipeline
Lock a notebook's outputs with a test, catch its hidden state, then let your agent refactor it into a pipeline that provably gives the same results.
One command
uvx notebook-to-pipeline pipeline analysis.ipynb --refactor
pipeline runs the whole flow in one step: it analyzes the notebook, runs it top to bottom in a
fresh kernel and records the outputs, scaffolds a package, verifies the scaffold reproduces the
outputs, and writes a report. With --refactor it then drives your installed agent CLI
(claude -p or codex exec) to refactor the scaffold into proper stages, re-verifying after every
pass with the output-lock as the guardrail. A pass that changes any output is rejected and the diff
is fed back; a refactor that changes the results is never kept. It ends with a one-screen
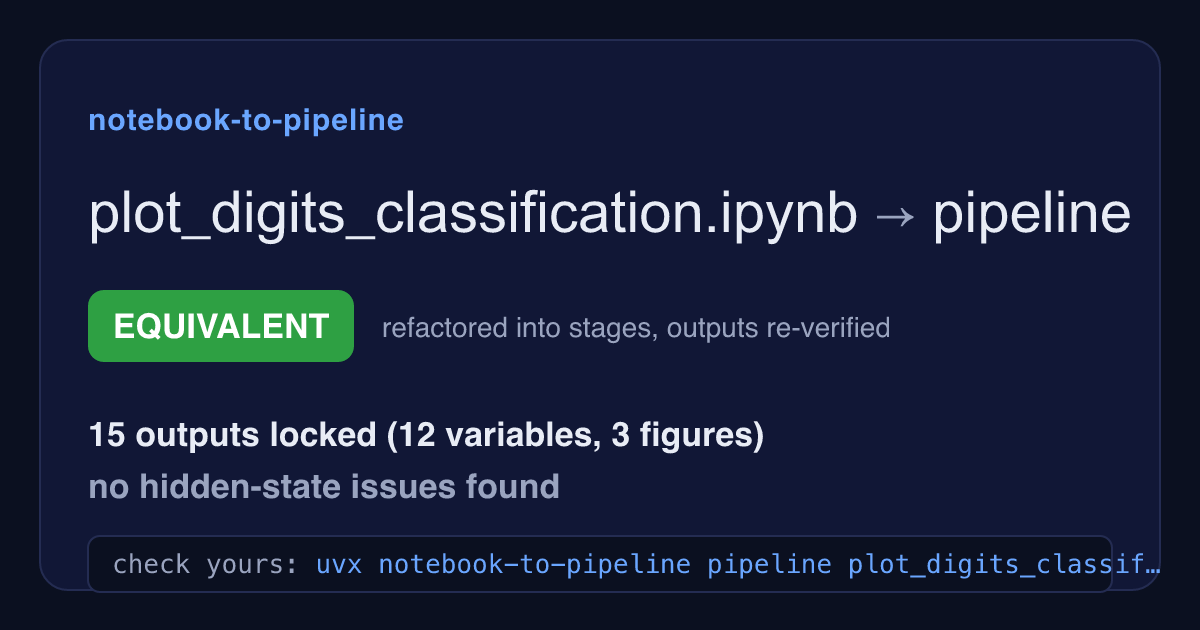
Reproducibility Report and a shareable card.
Here it is on the scikit-learn "Recognizing hand-written digits" gallery example (a cleared,
agent-style notebook with no execution counts), driving claude on an Apple M4 MacBook:
$ nb2p pipeline plot_digits_classification.ipynb --repeat 2 --refactor --agent claude --max-rounds 2 --yes
Analyzing plot_digits_classification.ipynb: 7 code cells.
Capturing the reference (running top to bottom in a fresh kernel)...
Scaffolding the pipeline into plot_digits_classification-pipeline/ ...
Verifying the scaffold reproduces the reference...

Refactor plan:
  agent: claude (model sonnet)
  up to 2 pass(es); the outputs are verified after each, and a pass that changes any output is rejected and reverted.
  This spends on your agent account.
  pass 1/2: asking claude to refactor...
    claude finished (9 turns), cost $0.1543. Verifying...
    pass 1: DIFFERS (1 of 15 compared outputs differ; not counted: 1 unstable).
  pass 2/2: asking claude to refactor...
    claude finished (4 turns), cost $0.1031. Verifying...
    pass 2: EQUIVALENT. Keeping this refactor.

Reproducibility Report: plot_digits_classification.ipynb
========================================================
EQUIVALENT - 15 outputs locked (12 variables, 3 figures)

Findings (5 total, ranked):
  [info] hidden state: The notebook has no saved execution counts (outputs were cleared or it was never run), so execution-order checks were skipped.
  ...
  [warning] nondeterminism: 1 artifact(s) change between runs and cannot be verified: disp
  [warning] nondeterminism: cell 5 uses randomness without a fixed seed: train_test_split() without random_state.

Pipeline:  plot_digits_classification-pipeline
Lock test: cd plot_digits_classification-pipeline && uv run pytest -q
           (tests/test_equivalence.py)
Card:      plot_digits_classification-pipeline/card.png
Report:    plot_digits_classification-pipeline/report.md

Refactor:  refactored by claude in 2 pass(es), EQUIVALENT, cost $0.2573
claude's first pass changed one output; the tool rejected it, fed the difference back, and the
second pass reproduced every output. The result is a real refactor into load, train, evaluate
and report stages, with 15 outputs (12 variables and 3 figures) locked by tests/test_equivalence.py.
Nothing is spent without --yes: without it, --refactor only prints the plan. The short command is
nb2p.
The five verbs, if you want finer control
uvx notebook-to-pipeline analyze analysis.ipynb      # hidden-state problems, proposed modules
uvx notebook-to-pipeline capture analysis.ipynb      # fresh-kernel run, saves the reference
uvx notebook-to-pipeline verify --pipeline src/analysis/pipeline.py:run --reference analysis.ipynb
verify compares every output: exact for integers, strings and hashes, with a tolerance for floats,
column by column for DataFrames, fitted models by their learned attributes, and matplotlib figures
pixel by pixel. Every command ends with what to do next.
Use it with your agent
uvx notebook-to-pipeline setup --yes
Restart Claude Code (or Codex, or Cursor), open the folder with your notebook and ask:
Can you turn snowiest_month.ipynb into a proper Python pipeline (a small package with a test) and prove the outputs didn't change? Keep it small.
From a real headless Claude Code session on the pandas-cookbook notebook in
examples/, with only this tool's MCP server (a local build of 0.1.1) and skill loaded. The agent called
analyze_notebook, capture_reference, wrote src/snowiest_month/pipeline.py, called
verify_pipeline and write_report, and finished with:
I turned the notebook into a small package with tests, and the outputs didn't change. The verification tool says equivalent: all 11 compared outputs match. That's 6 variables (dataframes and series), each identical byte for byte, and 5 figures, each identical pixel for pixel.
Things to know about the original notebook: It runs cleanly from top to bottom, but its saved outputs don't all come from such a run. Cells were run out of order, and 8 executions aren't visible in the file.
In an earlier session (0.1.0) on the scikit-learn notebook it kept a real bug on purpose and said so:
The notebook has a bug, and I kept it on purpose. One PCA object is shared by both
unscaled_clfandscaled_clf. [...] If you want that fix, I'll capture a new reference from the fixed notebook and report the new numbers.
A real run
The "Importance of Feature Scaling" notebook from the scikit-learn 1.9.1 example gallery, captured
with nb2p capture plot_scaling_importance.ipynb --out evidence/reference --repeat 2
(artifact list trimmed):
Python 3.12.13: ~/Downloads/notebook-to-pipeline/examples/.venv/bin/python (virtualenv found at ~/Downloads/notebook-to-pipeline/examples/.venv)
Top-to-bottom run: OK, 7/7 code cells in 36.439 s
Captured 26 artifacts:
  X                            dataframe  a676a863527a
  y                            series     55c53e167556
  ...
  y_proba                      ndarray    260abb10bbbb
  y_proba_scaled               ndarray    71b105b5e066
[warning] shared_object: After the run, `pca`, `unscaled_clf[0]`, `scaled_clf[1]` are one and the same sklearn.decomposition._pca.PCA object. Fitting or changing it through one name changed it for all of them.
[info] identical_artifacts: `pca`, `scaled_pca` have identical content after the run. If the notebook treats them as different results, check for shared objects or a step that was meant to differ.
Determinism check (2 runs): every artifact reproduced
Figures recorded: 3 (rendered as PNG for comparison): 1 (KNN without scaling; KNN with scaling), 2 (Weights of the first principal component), 3 (Unscaled training dataset after PCA; Standardized training dataset after PCA)
Printed output: 10 non-empty lines recorded
Reference: evidence/reference
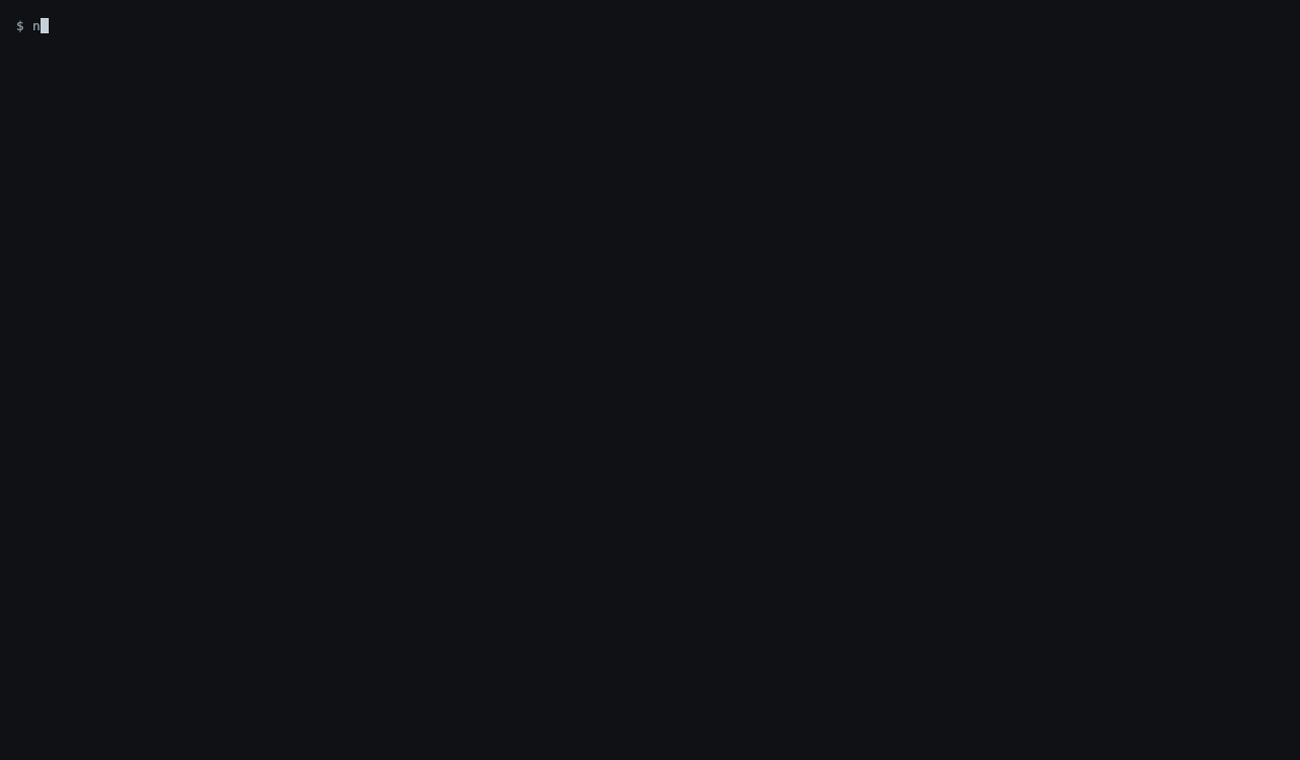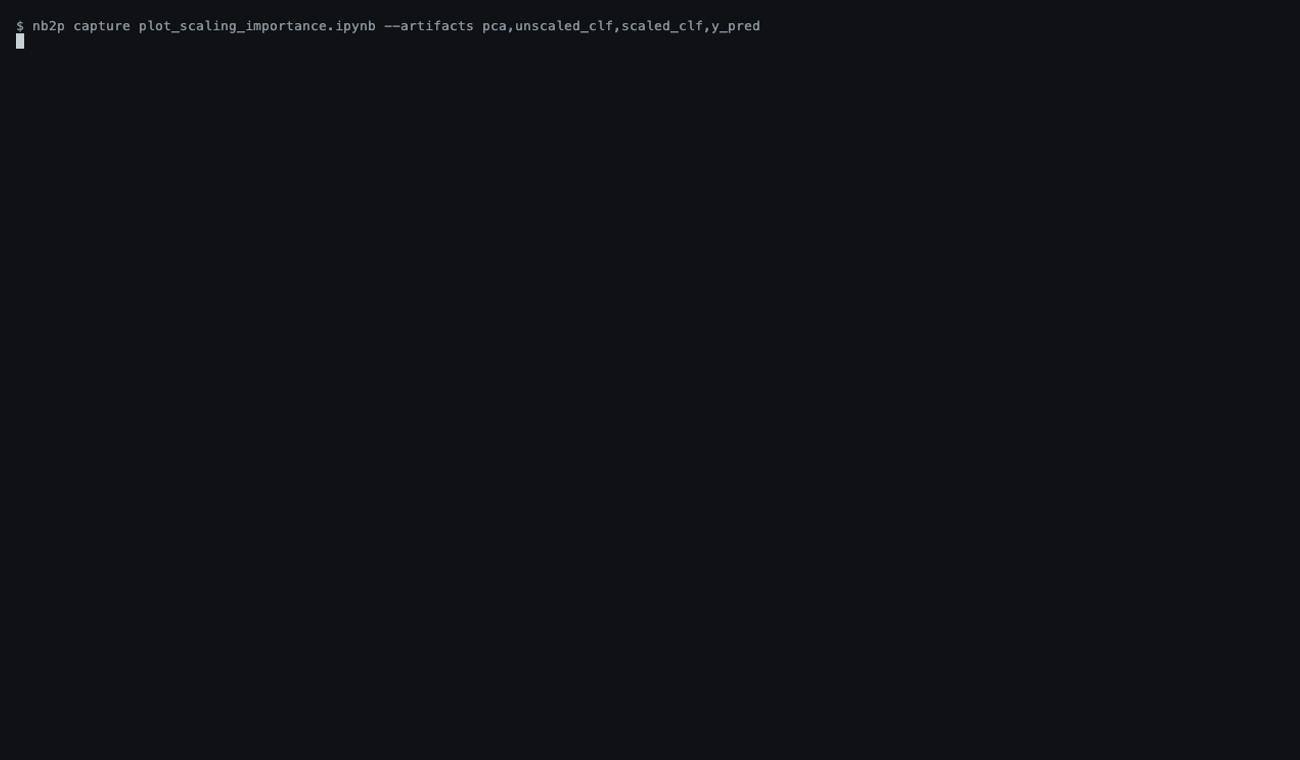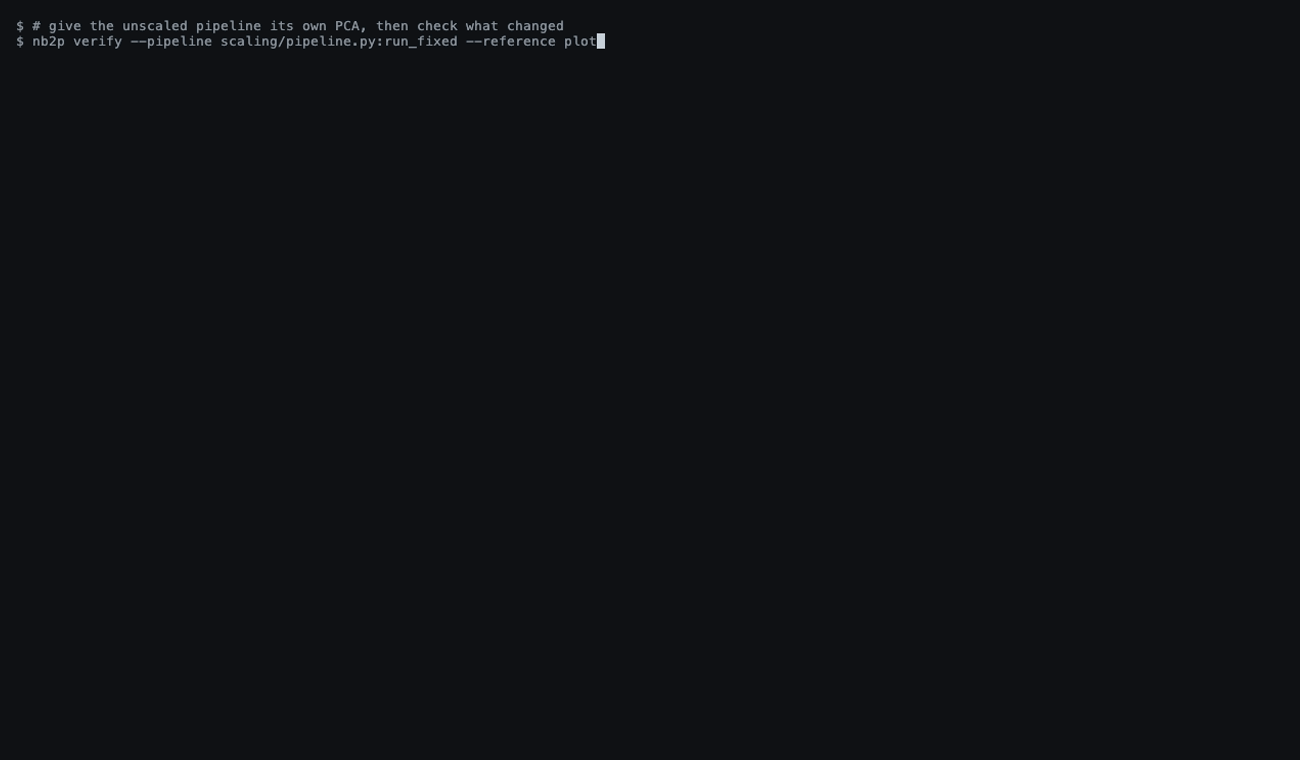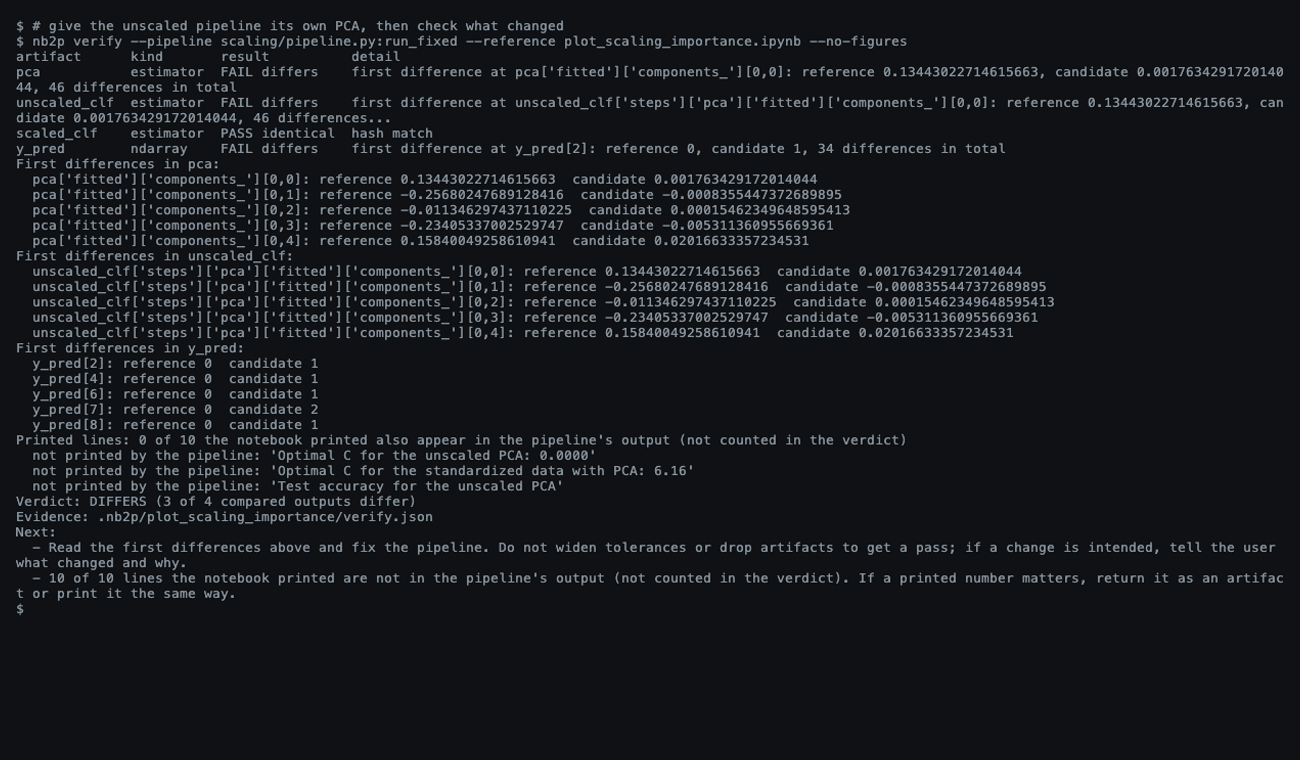
The notebook builds its "unscaled" and "standardized" pipelines around the same PCA object, so
fitting the second one refits the PCA inside the first. A hand-written pipeline that keeps this
behavior verifies as EQUIVALENT on all 26 artifacts. Giving the unscaled pipeline its own PCA is a
deliberate change, and verify shows exactly what it touches (3 of the 26 rows shown):
pca                      estimator  FAIL differs    first difference at pca['fitted']['components_'][0,0]: reference 0.13443022714615663, candidate 0.001763429172014044, 46 differences in total
y_pred                   ndarray    FAIL differs    first difference at y_pred[2]: reference 0, candidate 1, 34 differences in total
y_pred_scaled            ndarray    PASS identical  hash match
Verdict: DIFFERS (4 of 26 compared outputs differ; not counted: 3 not compared)
The unscaled test accuracy the example prints, 35.19%, becomes 74.07% with its own PCA; the
standardized pipeline stays at 96.30%. (The 3 uncounted rows are the figures: that hand-written
pipeline does not plot.) The mechanical draft from nb2p scaffold verifies as EQUIVALENT on this
notebook (26 variables and 3 figures) and on the pandas-cookbook one (6 variables and 5 figures; since
0.1.2 also 4 values the notebook only displayed, 15 outputs in all, see
the end-to-end run).
All of this, plus a notebook broken by hidden state, is in examples/ with the
full reports.
Three real notebooks, one command each
Run with nb2p pipeline <notebook> --repeat 2 on an Apple M4 MacBook, on three public notebooks
this repository had not used before (CPU only, each in its own directory with its data):
- scikit-learn "Recognizing hand-written digits" (SVM on the bundled digits dataset, BSD-3;
converted from the gallery
.py, so no saved execution counts, like an agent writes). EQUIVALENT: 15 outputs locked (12 variables and 3 figures). The tool flagged the unseededtrain_test_splitand founddisp(aConfusionMatrixDisplay) changes run to run, so it left that one out instead of failing.--refactorwithclaudetook 2 passes (the first changed an output and was rejected) and cost $0.26. - scikit-learn "Nearest Neighbors regression" (KNN on synthetic data, BSD-3; converted, no
execution counts). EQUIVALENT: 5 outputs locked. It caught the unseeded
np.random.randthat makesyunreproducible and left it out, and did not propose the loop's temporary variables (knn,y_,i,weights) as outputs.--refactorwithclaudetook 1 pass and cost $0.15. - pandas-cookbook "which weekday people bike the most" (groupby on a small bikes CSV, CC BY-SA;
the real notebook, with saved execution counts). NOT EQUIVALENT: 1 of 13 outputs differ. The
notebook's execution counts run up to 38 with only 12 cells saved (26 hidden runs),
bikes,berri_bikesandweekday_countsare each defined from scratch in more than one cell, and a clean top-to-bottom run gives one displayed table (displayed_cell_8) an extraweekdaycolumn that the saved output did not have. The tool points at that column and explains the hidden state behind it.
Two refactors spent $0.41 of agent credit in all. The hidden-state findings on the digits and KNN notebooks (no execution counts) come from static cell-order analysis: a name used before any earlier cell defines it, a name redefined from scratch in a later cell that earlier cells depend on, and saved cell outputs that disagree with a clean rerun.
How it works
- pipeline runs analyze, capture, scaffold, verify and report in one step and prints the
Reproducibility Report (verdict, outputs locked, ranked findings, package path, the exact test that
locks the outputs) plus a card (SVG and PNG, rendered with resvg-py, a pure wheel). With
--refactorit drivesclaude -porcodex execto refactor the scaffold, verifying after each pass and keeping only an equivalent result; it prints the plan and spends nothing without--yes. - analyze parses each cell with Python's
astafter IPython's own input transformer (so%magicsand!shelllines are understood), and builds a def/use graph across cells, including in-place mutation (df.dropna(inplace=True),model.fit(...),x.append(...), item and attribute assignment) and mutation through functions defined in the notebook. Findings: use before definition, names that only a deleted cell defined, out-of-order and hidden executions from the saved execution counts, saved outputs computed from a different definition than a clean run would use, cross-cell mutation, estimators shared between scikit-learn pipelines, unseeded randomness, network and shell access. It proposes a split into load, clean, features, train, evaluate and report, and says which calls put each cell there. - capture starts a new Jupyter kernel (
nbclient+ipykernel, over a Unix socket on macOS and Linux) on your project's interpreter, runs every cell in order and stops at the first error. It saves the chosen variables with a content hash and a summary (shape, dtypes, column stats, fitted attributes), records files the notebook wrote, re-renders every matplotlib figure as a PNG at 72 dpi when Jupyter closes it, records what the notebook printed, compares the saved text outputs with the fresh run, reports objects reachable under several names, and with--repeat Nreruns to find outputs that change between runs. A value a cell displays as its last expression (df.describe(), a score) is saved too, asdisplayed_cell_<n>, when it is data. - verify runs the pipeline in the same interpreter (
file.py:funcormodule:funcreturning a dict, or a script whose globals hold the results), saves the same artifacts and compares them in that interpreter, so pandas, numpy and scikit-learn objects load with the versions that made them. Fitted estimators are compared by parameters and fitted attributes. Figures the pipeline draws are rendered the same way and matched to the notebook's by pixels, then in order. Every failure shows the first differences with their path, for exampletemperature.index[0]orpca['fitted']['components_'][0,0]. - scaffold writes
src/<package>/with one module per proposed stage (the notebook code pasted into functions as a first draft, displayed values kept asdisplayed_cell_<n>),pipeline.py:run(),tests/test_equivalence.py, a Makefile, apyproject.tomlpinned to the captured versions and a GitHub Actions workflow. The test callsuv tool run --from notebook-to-pipeline==<that version> nb2p verifywith the project's interpreter, so the project needs only pytest. For a uv project (uv.lock, a uv-made.venv, or a new folder when uv is installed) pytest goes in a dev dependency group and CI usesastral-sh/setup-uv; for a pip project it writesrequirements.txtandrequirements-dev.txt(pytest and uv) and CI usesactions/setup-python, both with the Python version of the reference run.examples/scaffold_e2e.shchecks both kinds end to end. - report writes
report.mdandreport.json: notebook hash, interpreter and package versions, the top-to-bottom result, hidden-state findings, the per-artifact and per-figure tables, the verdict and the limits.
The interpreter is chosen in this order: --python, $NB2P_PYTHON, a .venv next to the
notebook or in a parent directory, then the one running nb2p. If the notebook needs a package that
interpreter lacks, capture says so and how to fix it.
Exit codes: capture 0 when the notebook runs, 3 when it fails. verify 0 equivalent, 1 differs,
3 pipeline failed, 4 reference invalid.
Setup for agents
uvx notebook-to-pipeline setup          # shows what it would change
uvx notebook-to-pipeline setup --yes    # applies it
It detects Claude Code, Codex and Cursor and registers the MCP server (uvx notebook-to-pipeline mcp)
with each: claude mcp add --scope user, a [mcp_servers.notebook-to-pipeline] table in
~/.codex/config.toml, an entry in ~/.cursor/mcp.json. It copies the agent skill to
~/.claude/skills/ and ~/.codex/skills/. Files are backed up before they are edited and a second
run changes nothing. --project DIR writes a project .mcp.json instead.
MCP tools: pipeline (the one-call fast path), analyze_notebook, capture_reference,
verify_pipeline, scaffold_pipeline, write_report. Each result carries next_steps. The
pipeline MCP tool runs the whole flow and returns the Reproducibility Report; it does not drive a
second agent, since the agent calling it does the refactor. The skill (skills/notebook-to-pipeline/SKILL.md)
tells the agent to capture before changing anything, verify after every step, and never change
logic to make outputs match without saying so.
What it can't do
- Figures are compared only for matplotlib (pandas and seaborn plots included), and only when the pipeline draws figures too; otherwise they are listed as not compared. They are compared pixel by pixel, so a different matplotlib or font version will show up as a difference. Plotly, Bokeh and Altair charts are not compared.
- A value that was only printed is checked line by line against the pipeline's output, but that
check is not counted in the verdict. A value a cell displayed as its last expression is compared
when it is data and the pipeline returns it as
displayed_cell_<n>(the scaffold draft does); otherwise it is listed as not returned. Values shown withdisplay(), rich-only output such asdf.style, and plot handles are not compared. - The generated equivalence test needs uv (installed, or
pip install uv) and, the first time, network access to fetch the pinned notebook-to-pipeline. Without uv it skips with a message, and underCIit fails instead. scaffoldpins only the packages the notebook imports, to the versions of the reference run. Their own dependencies (scipy under scikit-learn, for example) are not pinned.- Static analysis does not follow
exec,eval,%run, imports of local modules or aliases (b = a; b.append(1)). Shared objects of that kind are caught at runtime only if both names are captured. - Equivalence is shown for this data in this environment. A different input file or library
version can still change results, and so can a different CPU: with references captured on an
Apple M4, the generated workflow passed on GitHub's runners for the pandas-cookbook notebook but
failed 1 of 29 outputs for the scikit-learn one (an ill-conditioned
LogisticRegressionCVfit, fifth significant digit), on both ubuntu-latest and macos-latest. For numerically sensitive notebooks, capture the reference on the machine that runs CI, or add a tolerance you can justify to the generated test (--rtol) and say so. Details in examples/. - Outputs that change from run to run (unseeded randomness, timings) cannot be verified.
--repeatfinds them; it does not fix them. - The stage proposal is a heuristic starting point and
scaffoldproduces a mechanical draft. The refactor itself is the agent's job. - Plain Python kernels only. No R or Julia notebooks, no Spark or remote kernels.
Privacy and safety
Everything runs on your machine. The tool makes no network calls and calls no LLM; the agent you
already use does the refactoring. The equivalence test that scaffold writes asks uv for the pinned
notebook-to-pipeline from PyPI the first time it runs. capture and verify execute the notebook and the pipeline with
your user's permissions, exactly as running them yourself would. References are stored as pickles,
so only verify against capture directories you created (see SECURITY.md). Evidence files replace
your home directory with ~.
License
MIT. The example notebooks keep their own licenses (CC BY-SA 4.0 and BSD 3-Clause), noted in each
example's NOTICE.txt.
1 maintainer

Metadata
1 maintainer
Release files for notebook-to-pipeline 0.2.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| notebook_to_pipeline-0.2.1.tar.gz | 116.6 kB | With provenance | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| notebook_to_pipeline-0.2.1-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 225.0 kB
Release files / notebook_to_pipeline-0.2.1.tar.gz
| Download URL | notebook_to_pipeline-0.2.1.tar.gz |
|---|---|
| Size | 116.6 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
fb9ebf0897683ced0831ff0a1394a2de735b4b6676c34c7350946bee4445fe6d
|
|
BLAKE2b-256 checksum How to use checksums |
c90c7e33f4dbf19ffe46f0b04ca82383440f692b91b46e5af5fa44859df3599b
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 25, 2026.
Transparency logRelease files / notebook_to_pipeline-0.2.1-py3-none-any.whl
| Download URL | notebook_to_pipeline-0.2.1-py3-none-any.whl |
|---|---|
| Size | 108.3 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
bc54872d292df0ddf5ef8e8908af4ceaef39343fca38fbfd632f45071a14cff0
|
|
BLAKE2b-256 checksum How to use checksums |
efe44fb7e1e574a0ea10178f1972dcf74df042bd5897ba1eb570e7406b5a066c
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 25, 2026.
Transparency logSecurity for notebook-to-pipeline 0.2.1
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
All 2 files in this release have been uploaded with provenance metadata.
Attestation for notebook_to_pipeline-0.2.1.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 25, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














