
numguard tests array functions on the inputs that break numerical code.
It throws zeros, empty arrays, NaN, ±inf, overflow-sized and subnormal values, cancellation-prone data
and float16 at your function, and checks every answer against a reference, invariants and the dtype's limits.


It is aimed at a kind of bug that AI coding assistants, and people, write all the time: code that runs, passes the obvious test, and returns silently wrong numbers on edge cases.
import numpy as np
import scipy.special
import numguard

def logsumexp(x):                       # what an assistant often writes first
    return np.log(np.sum(np.exp(x)))

assert np.isclose(logsumexp(np.array([1.0, 2.0, 3.0])), 3.40760596)  # happy path: passes

report = numguard.check(logsumexp, reference=scipy.special.logsumexp,
                        properties=["translation_equivariant"])
print(report.summary())
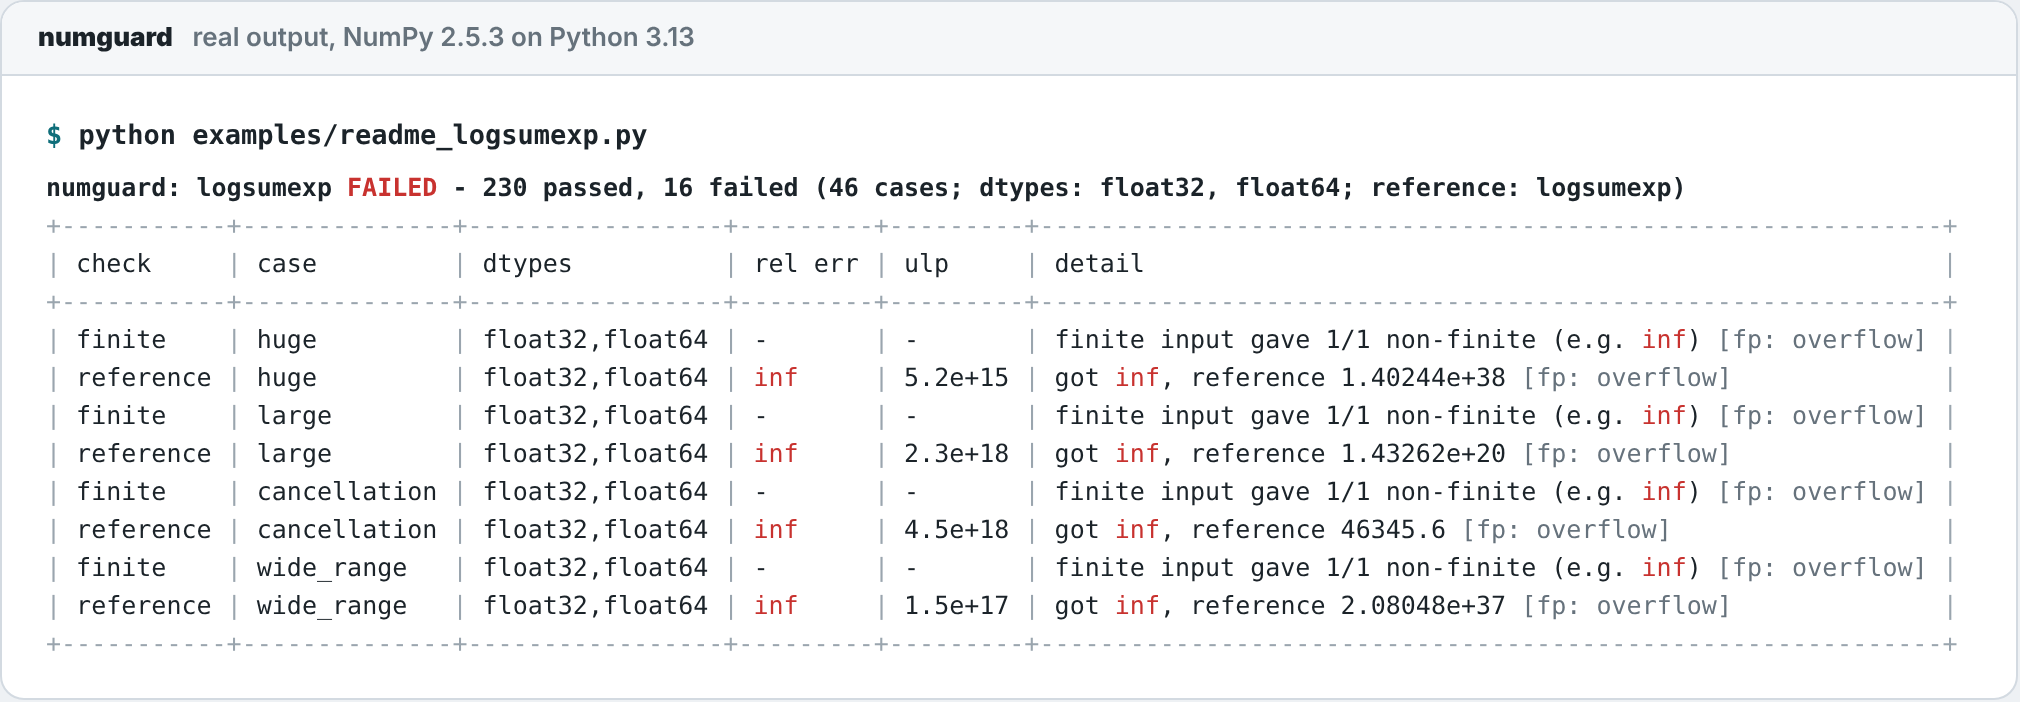
Real output of examples/readme_logsumexp.py (NumPy 2.5.3, Python 3.13). The cancellation row is ordinary data with a large offset, like 46341 + [0, 1, 2, 3, 4] in float32 or timestamps in float64: the right answer is about 46345.6 and the naive version returns inf.
Contents
- Why edge cases?
- How it works
- Quick start
- The edge-case catalogue
- Checks
- pytest plugin
- Config file
- Backends
- Hypothesis strategies
- The bug corpus
- Agent (experimental):
suggest,fix,bench - GitHub integration
- Security model
- How numguard compares
- Configuration and CLI reference
- FAQ
- Limitations
- Roadmap
- Contributing · License
Why edge cases?
A happy-path test for numerical code checks one comfortable input, usually something like [1.0, 2.0, 3.0]. The bugs live elsewhere:
- Overflow and underflow.
exp(x)overflows float32 above 88.7;x * xoverflows above 1.8e19 and underflows to zero below about 1e-19.sqrt(x**2 + y**2), naive norms, softmax and logsumexp all fall over there. - Cancellation.
E[x²] − E[x]²for1e9 + [1, 2, 3]is0.0in float64; the variance is 0.667. - Precision loss.
log(1 + x)is0.0forx = 1e-17;log1pgives1e-17. - Degenerate shapes and values. An all-zero input gives a zero norm or a zero quantization scale;
n = 1gives NaN for a sample standard deviation; an empty array gives a warning and NaN. - Low precision. NumPy's own
np.varof 100,000 float16 values between 1 and 2 returnsinf(NumPy 2.5.3): the float16 accumulator overflows. The answer is about 0.083.
numguard asks the questions a numerical analyst would ask of your function, and answers them by running it:
- Does it stay finite where the true answer is finite?
- Does it agree with a trusted reference, ideally a higher-precision one, within a tolerance you can state in ULPs?
- Does it keep the invariants it should: shifting, scaling, permuting, batching, monotonicity, bounds?
- Does it respect its dtype: no silent upcasting, no in-place mutation of its inputs, NaN handled the way you said?
A careful implementation passes; a plausible-looking naive one gets a table that shows exactly which input breaks it and how.
How it works
- Contract. You describe each argument (shape, domain such as
positiveor"(-1, inf)", optional fixed dtype) and what should hold: a reference, properties, bounds, tolerances. Everything is optional; with nothing declared, numguard infers one 1-D array per positional parameter and still runs the dtype-limit checks. - Cases. The catalogue generates every edge-case kind for every dtype under test. Values outside an argument's domain are never generated, and with several arguments each kind is also applied to one argument at a time (
zeros[b]). Cases are deterministic for a given seed. - Run. Each case runs through the backend (NumPy by default). numguard records floating-point signals (
overflow,invalid,divide) and snapshots the inputs so in-place edits are caught. - Check. Fixed rules compare the outputs with the reference (rounded to the output dtype), with metamorphic properties and with the dtype's limits. Failures carry the case, dtype, max relative error, ULP distance and FP signals.
- Report. A table and JSON, a failing pytest item, a non-zero exit code, or a card on the pull request.
An LLM never decides a result. The agent can draft a spec or propose a rewrite, and either one only counts after numguard has executed it.
Quick start
1. Install
pip install numguard-ci                                                              # the command and the import are `numguard`
pip install "numguard-ci @ git+https://github.com/bhaskargurram-ai/numguard@v1.0.1"   # or straight from GitHub
The only runtime dependencies are NumPy and click. Extras: numguard-ci[pytest], numguard-ci[scipy], numguard-ci[mpmath] (arbitrary-precision references), numguard-ci[hypothesis] (strategies), numguard-ci[bfloat16] (ml_dtypes), numguard-ci[dev] (everything for working on numguard). Python 3.10 or newer.
2. Check a function
From Python:
import numpy as np
import numguard

report = numguard.check(
    my_variance,                                  # function under test
    inputs=numguard.Array("n", domain="any"),     # optional; inferred from the signature
    reference=np.var,                             # optional trusted implementation
    properties=["translation_invariant", "scale_equivariant:2", "permutation_invariant"],
    dtypes=["float16", "float32", "float64"],     # default: float32, float64
)
report.ok                  # bool
report.failures            # list[CheckResult]: check, case, dtype, message, max abs/rel/ULP error, FP signals
print(report.summary())    # the table above
report.to_json()
report.raise_if_failed()   # raises numguard.NumGuardError (an AssertionError) with the table
From the shell (exit status 1 on any failure):
numguard check mypkg.stats:my_variance --ref numpy:var --dtype float16 --dtype float32 \
    --prop translation_invariant --prop permutation_invariant
numguard check path/to/ops.py:softmax --batched --fp-signals fail --json
Or attach the contract to the function itself. @numguard.guard(...) takes the same arguments and does not change the function's behaviour:
@numguard.guard(reference=scipy.special.softmax, batched=True, bounds=(0, 1),
                properties=["translation_invariant"])
def softmax(x):
    ...
3. Run it in your tests
import pytest, scipy.special
from mypkg.ops import logsumexp

@pytest.mark.numguard(fn=logsumexp, reference=scipy.special.logsumexp,
                      properties=["translation_equivariant"])
def test_logsumexp_edge_cases():
    pass                                  # the test body runs first, then numguard checks fn
pytest --numguard-modules mypkg.ops # every @numguard.guard function becomes a test item
Notebooks work the same way as scripts: numguard.check(...).summary() prints the table in a cell.
4. Add it to CI
From the root of your repository:
numguard init                                  # add --agent for the experimental fix agent
numguard init --target mypkg.ops:logsumexp     # also add a [[target]] stub (repeatable)
init writes the caller workflows below and a commented numguard.toml, refuses to overwrite existing files without --force, and prints the next steps. --install-command CMD changes how the workflow installs your project and --ref pins another numguard tag or commit. List your functions as [[target]] tables in numguard.toml, merge the files to your default branch (workflow_run workflows only run from there), and open a pull request. The files in examples/workflows/ and examples/numguard.toml are exactly what numguard init --agent writes; the snippets below are copied from them without their comment headers.
numguard runs as separate workflows so that the pull request's code and privileged tokens never share a job (why). Each caller is a few lines that point at a reusable workflow in this repository. Pin @v1.0.1, or a full commit SHA if you want to be strict, and keep numguard-ref the same.
.github/workflows/numguard.yml runs the checks. It is unprivileged and is where PR code runs.
name: numguard

on:
  pull_request:

permissions:
  contents: read

concurrency:
  group: numguard-${{ github.event.pull_request.number }}
  cancel-in-progress: true

jobs:
  check:
    uses: bhaskargurram-ai/numguard/.github/workflows/check.yml@v1.0.1
    with:
      numguard-ref: v1.0.1
      python-version: "3.12"
      # Installs the project under test; this runs PR code (unprivileged job).
      install-command: 'pip install -e ".[dev]" || pip install -e .'
      config: numguard.toml   # read from the PR's base commit when it exists there
      fail-on: fail           # or "error" / "never"
.github/workflows/numguard-comment.yml posts the card and sets a numguard: pass, numguard: fail or numguard: error label. It is privileged and never runs PR code.
name: numguard comment

on:
  workflow_run:
    workflows: ["numguard"]   # must match the `name:` of numguard.yml
    types: [completed]

permissions: {}

jobs:
  comment:
    if: github.event.workflow_run.event == 'pull_request' && github.event.workflow_run.conclusion != 'cancelled'
    permissions:
      contents: read
      actions: read          # download the artifact of the triggering run
      pull-requests: write   # upsert the comment and the status label
    uses: bhaskargurram-ai/numguard/.github/workflows/comment.yml@v1.0.1
    with:
      numguard-ref: v1.0.1
      labels: true
.github/workflows/numguard-agent.yml (optional, experimental, written by init --agent) proposes a rewrite for each failing target and verifies it in a separate job. It runs only for PRs labelled numguard:agent or opened by owners, members and collaborators, unless you set run-for: everyone.
name: numguard agent

on:
  workflow_run:
    workflows: ["numguard"]   # must match the `name:` of numguard.yml
    types: [completed]

permissions: {}

jobs:
  agent:
    if: github.event.workflow_run.event == 'pull_request' && github.event.workflow_run.conclusion != 'cancelled'
    permissions:
      contents: read
      actions: read
      pull-requests: read
    uses: bhaskargurram-ai/numguard/.github/workflows/agent.yml@v1.0.1
    with:
      numguard-ref: v1.0.1
      llm-provider: ${{ vars.NUMGUARD_LLM_PROVIDER }}
      llm-model: ${{ vars.NUMGUARD_LLM_MODEL }}
      llm-base-url: ${{ vars.NUMGUARD_LLM_BASE_URL }}
      llm-reasoning-effort: ${{ vars.NUMGUARD_LLM_REASONING_EFFORT }}
      python-version: "3.12"
      install-command: 'pip install -e ".[dev]" || pip install -e .'
      run-for: trusted   # or "everyone" (spends API credits on any fork PR)
    secrets:
      llm-api-key: ${{ secrets.NUMGUARD_LLM_API_KEY }}

  comment:
    needs: agent
    if: needs.agent.outputs.verified == 'true'
    permissions:
      contents: read
      actions: read
      pull-requests: write
    uses: bhaskargurram-ai/numguard/.github/workflows/comment.yml@v1.0.1
    with:
      numguard-ref: v1.0.1
      # Trusted values: the PR number comes from the gate job (API data, no PR
      # code ran there) and the artifact from this run's verify job.
      pr-number: ${{ needs.agent.outputs.pr-number }}
      artifact-run-id: ${{ github.run_id }}
      labels: true
For the agent, add a repository secret NUMGUARD_LLM_API_KEY and repository variables NUMGUARD_LLM_PROVIDER (anthropic or openai) and NUMGUARD_LLM_MODEL (optional: NUMGUARD_LLM_BASE_URL, and NUMGUARD_LLM_REASONING_EFFORT, which OpenAI's GPT-6 Luna needs set to none), and set [agent] enabled = true in numguard.toml (init --agent does that). The key is only passed to the propose job, which never runs PR code.
The reusable workflows take a few more inputs: config-from (base, the default, reads numguard.toml from the PR's base commit; head uses the PR's), numguard-extras (default scipy), numguard-repository and timeout-minutes. Pytest runs when numguard.toml has a [pytest] table. Every input is listed in docs/GITHUB.md.
On fork PRs the check workflow has no write token, so the card also appears in the run's job summary before the comment workflow posts it.
Use the composite action directly
The bhaskargurram-ai/numguard@v1.0.1 composite action (action.yml) takes a command: check (default), summary, comment, agent-propose or agent-verify. The reusable workflows above combine them so that the trust zones stay apart; see docs/GITHUB.md before wiring them up yourself.
The edge-case catalogue
The catalogue is placed where naive formulas break, for each dtype under test. numguard cases lists every kind with its tags.
| kind | what it contains | tags |
|---|---|---|
random |
seeded normal (or in-domain) values | regular |
zeros, neg_zero |
all 0.0 / all -0.0 |
regular / signed_zero |
ones, constant |
constant arrays | regular |
empty, single, pair, large_n |
sizes 0, 1, 2 and large_n (default 100,000) |
size |
nan, posinf, neginf |
one non-finite value among regular ones | nonfinite_input |
huge |
25–50 % of finfo.max |
extreme, overflow_prone |
large |
2–8 × sqrt(finfo.max), so squares overflow |
extreme, overflow_prone |
small |
1–100 × eps |
extreme, precision |
tiny, subnormal |
just above finfo.tiny / small multiples of the smallest subnormal |
extreme, underflow_prone |
wide_range |
geometric sweep from tiny to max |
extreme |
cancellation |
large offset, small spread: 16/sqrt(eps) + [0..4] (≈ 46341 + … in float32) |
extreme, precision |
alternating |
1, -2, 3, -4, … |
regular, mixed_sign |
duplicates, sorted, reverse_sorted |
orderings and ties | regular |
boundary |
closed/open interval endpoints (via nextafter) |
|
int_min, int_max |
integer range limits | boundary |
Domains. Each argument has a domain: any, positive, nonneg, negative, nonpos, unit_interval, interval notation like "(-1, inf)", or integer ranges like "int[0, 255]". A positive argument never receives zeros or negatives, and on (-1, inf) the huge values are positive. Add your own with extra_cases={"name": arrays}.
Patterns in include, exclude, allow_nonfinite, may_raise and ignore match a case name (glob), its kind or any of its tags, so allow_nonfinite=["overflow_prone"] covers huge, large and wide_range at once.
Checks
| check | fails when |
|---|---|
error |
the function raises (unless the case matches may_raise, or the reference raises too) |
mutation |
the function modifies its input arrays in place |
dtype |
a floating output does not keep the input dtype (or does not match out_dtype) |
finite |
finite inputs produce inf/NaN that the reference (rounded to the output dtype) does not |
nan |
nan="propagate": NaN input gives an output with no NaN. nan="raise": no exception |
reference |
values differ from the reference beyond rtol/atol (reports max abs/rel error and ULPs) |
fp_signals |
opt-in: an overflow / invalid / divide-by-zero signal on finite input |
bounds |
opt-in: finite output outside bounds=(lo, hi) |
post:<name> |
opt-in: a postcondition post(args, outputs) returns False or a message |
batch |
batched=True: f(stack(xs, axis)) != stack(f(x) for x in xs) |
monotonic |
monotonic="increasing"/"decreasing": the order is violated on sorted inputs |
prop:<name> |
a metamorphic property fails |
Floating-point signals raised while the function runs are recorded on every result ([fp: overflow] in the table) as evidence. They only cause failures with fp_signals="fail".
Properties are strings with an optional :value, or numguard.Property objects: permutation_invariant, permutation_equivariant, translation_invariant[:c], translation_equivariant[:c], scale_invariant[:factor], scale_equivariant[:exponent] (the default factor 2 is exact in binary floating point), symmetric, odd, even. They are checked on regular cases; a transformed input that would leave the domain is skipped.
Tolerances. Defaults are rtol 1e-2 for float16, 1e-5 for float32 and 1e-12 for float64. Relative errors are measured against max(|expected|, finfo.tiny). Pass rtol/atol as numbers, or as dicts keyed by dtype name such as {"float32": 1e-4, "uint8": 1}.
High-precision references and ULPs
A plain reference receives float64-upcast inputs. For a reference that is genuinely more accurate than float64:
ref = numguard.longdouble(np.log1p)           # evaluates on np.longdouble inputs
ref = numguard.highprec(numpy_fn=np.log1p,    # mpmath if installed, else long double
                        mp_fn=lambda x: mpmath.log1p(x), dps=50)
numguard.check(my_log1p, reference=ref, domain="(-1, inf)")
np.longdouble is 80-bit extended precision on most x86-64 Linux builds. Where it is plain float64 (Windows, macOS arm64), numguard falls back to float64 and labels the reference that way. numguard.ulp_distance(a, b) counts the representable values between a and b; signed zeros count as equal, and so do two NaNs.
All check() options
inputs=, domain=, reference=, properties=, dtypes=, rtol=, atol=, nan="propagate" | "raise" | "ignore", allow_nonfinite=[...], may_raise=[...], out_dtype= (default "preserve"), batched=, batch_axis=, monotonic=, bounds=, fp_signals="ignore" | "fail", postconditions=[fn], extra_cases={...}, include=/exclude=, ignore=["check:pattern"], kwargs= (forwarded to the function), ref_kwargs=, n=, large_n=, seed=, backend=. @numguard.guard and the pytest marker accept the same names; [[target]] tables accept the ones that can be written in TOML (see docs/CONFIG.md).
What the checks can't tell you. Without a reference, the finite check can't tell a result that legitimately overflows (such as hypot(1.7e308, 1.7e308)) from a bug: pass a reference or mark such cases with allow_nonfinite. numguard tests the cases it generates against the contract you declare. It does not prove correctness.
pytest plugin
Installing numguard registers a pytest plugin (pytest11 entry point). Use it two ways:
- Marker.
@pytest.mark.numguard(fn=..., **check_options). The test body runs first, then numguard checksfn; any failure fails the test with the summary table as its message. - Auto-collection. Every
@numguard.guard-decorated function in the listed modules becomes a test item:
pytest --numguard-modules mypkg.ops,mypkg.stats
pytest --numguard-dtypes float16,float32 --numguard-large-n 1000000 --numguard-backend torch
numguard_modules can also be set in [tool.pytest.ini_options]. In CI, add a [pytest] table to numguard.toml and numguard check --config runs your suite with the plugin active and puts the pass/fail counts on the card.
Config file
numguard.toml lists functions to check without touching their source, which is what CI uses. numguard check reads ./numguard.toml (or --config FILE; --target NAME runs one target). numguard init writes this commented starting point (examples/numguard.toml, header trimmed):
# [defaults]                                # applied to every target
# dtypes = ["float32", "float64"]

# [[target]]
# name = "logsumexp"
# function = "mypkg.ops:logsumexp"          # or "path/to/file.py:logsumexp"
# inputs = ["any"]                          # one domain per positional argument
# properties = ["translation_equivariant"]
# reference = "special.logsumexp(x)"        # an expression over the argument names
# reference_precision = "float64"           # or "longdouble", or "mpmath" (elementwise)
# nan = "propagate"                         # NaN in -> NaN out
# allow_nonfinite = []                      # cases where inf/NaN is the right answer
# backend = "numpy"                         # or "torch", "jax", "cupy"

# [pytest]                                  # also run pytest (the numguard plugin is active)
# args = ["tests"]

[agent]                                     # experimental suggested fixes (numguard-agent.yml)
enabled = true
# rounds = 3                                # refinement rounds for local `numguard fix`
# max_targets = 3                           # failing targets per pull request
# variants = 3                              # independent rewrites per target in CI; the best verified one is shown
# timeout = 120                             # seconds per sandboxed check run
A filled-in version, which is what produced the card below:
[defaults]
dtypes = ["float32", "float64"]

[[target]]
name = "logsumexp"
function = "mypkg.ops:logsumexp"
inputs = ["any"]
properties = ["translation_equivariant"]
reference = "special.logsumexp(x)"

[[target]]
function = "mypkg.ops:log1p"
inputs = ["(-1, inf)"]
reference = "np.log1p(x)"
reference_precision = "longdouble"
monotonic = "increasing"
referenceis a Python expression over the function's argument names ("special.logsumexp(x)","np.hypot(x, y)","mpmath.log1p(x)"), checked statically and evaluated with onlynp,math,special(scipy.special) andmpmathavailable.reference_precisionisfloat64(default),longdouble, ormpmath(elementwise, 50 digits).reference_function = "module:function"names a trusted callable instead.- Every other key means the same as the
numguard.check()argument of the same name:inputs(one domain or{ name, domain, shape, dtype }table per positional argument),dtypes,properties,rtol/atol(a number or a per-dtype table),nan,allow_nonfinite,bounds,monotonic,batched,fp_signals,backend, and so on. [pytest](args,timeout,enabled) also runs pytest;[agent](enabled,rounds,max_tool_calls,max_targets,variants,timeout) configures the agent.- Validation is strict. An unknown key, wrong type or unknown value is an error that names the table and key, and keys that look like secrets (
api_key,token, ...) are refused.
In the GitHub workflow the file is read from the PR's base commit, so a pull request cannot loosen its own checks. Every key is documented in docs/CONFIG.md.
Backends
Cases are always generated, and results always compared, in NumPy. With backend="torch", "jax" or "cupy" (CLI --backend, config backend =, pytest --numguard-backend), an adapter converts each input to the backend's arrays before the call and converts the outputs back (np.from_dlpack / np.asarray), recording each output's backend dtype for the dtype check. The reference is always called with NumPy arrays.
| backend | notes |
|---|---|
numpy |
default |
torch |
CPU tensors by default; NUMGUARD_TORCH_DEVICE=cuda moves them to a GPU. In-place modification of inputs is detected. |
jax |
arrays are immutable, so mutation always passes; without JAX_ENABLE_X64=1 the dtype check reports float64 cases that silently became float32 |
cupy |
GPU arrays; no bfloat16 |
These libraries are optional and not installed with numguard. numguard's own tests exercise the adapters with fake torch and jax modules; the real libraries are not part of its CI.
bfloat16. dtypes = ["bfloat16"] builds cases from bfloat16's own limits (max about 3.39e38, eps 2^-7) and hands them to the function as torch.bfloat16, jax.numpy.bfloat16 or, on the NumPy backend, ml_dtypes.bfloat16 arrays (pip install "numguard-ci[bfloat16]"). Default rtol is 6e-2 and ULPs are counted in bfloat16 units.
Hypothesis strategies
If you already use Hypothesis, numguard.strategies turns a numguard spec into strategies (pip install "numguard-ci[hypothesis]"; numguard itself does not depend on Hypothesis):
from hypothesis import given
import numguard.strategies as ngst

@given(ngst.inputs_for(my_softmax, dtypes=["float32"]))
def test_softmax_sums_to_one(args):
    (x,) = args
    ...
cases(target, **spec)drawsnumguard.Caseobjects (name, kind, tags, fresh copies of the arrays) from the catalogue;edge_cases(...)draws argument tuples from the catalogue;random_inputs(..., min_size=0, max_size=32)draws random in-domain arrays (no NaN or infinities);inputs_for(...)draws from both.
target is a numguard.Spec, a function decorated with @numguard.guard, or a function plus the keyword arguments of numguard.check. You keep Hypothesis's shrinking and example database and add the inputs numerical code tends to get wrong.
The bug corpus
corpus/ contains 12 self-contained tasks, each inspired by a real class of numerical bug in AI-written and human-written array code. Each task folder has:
task.md: the prompt a coding agent receives (function name, signature, contract)buggy.py: a plausible naive implementation that passes a happy-path testreference.py: a correct implementationspec.py: the numguard spec (inputs, domain, properties, reference, happy-path test)
| task | bug class |
|---|---|
quantize_dynamic |
dynamic uint8 quantization: all-zero input gives scale = 0, which turns into NaN downstream |
logsumexp, softmax |
exp overflow on large logits; softmax normalized over the whole batch |
variance_onepass |
E[x²] - E[x]² cancellation: 1e9 + [1, 2, 3] gives 0.0 in float64 and -9.2e10 in float32 |
mean_float16 |
float16 accumulator overflows on 100k elements |
sample_std |
n = 1 gives NaN instead of an error, plus overflow/underflow of squared deviations |
log1p |
log(1 + x) loses all precision for tiny x |
cosine_similarity, normalize |
division by a zero norm, and overflow in ‖x‖² |
sigmoid |
exp(-x) overflows for very negative inputs |
hypot |
sqrt(x² + y²) overflows and underflows |
loo_mean |
closed-form leave-one-out mean cancels catastrophically when one value dominates, and n = 1 |
The quantization task is modelled on the all-zero-input case of ONNX DynamicQuantizeLinear, where the textbook formula gives a zero scale; the author contributed a fix for this case to the ONNX specification. The other tasks are generic bug classes and don't refer to specific upstream issues.
Grade the bundled versions:
numguard eval --baseline buggy        # exit 0 only if every buggy version is caught
numguard eval --baseline reference    # exit 0 only if every reference passes
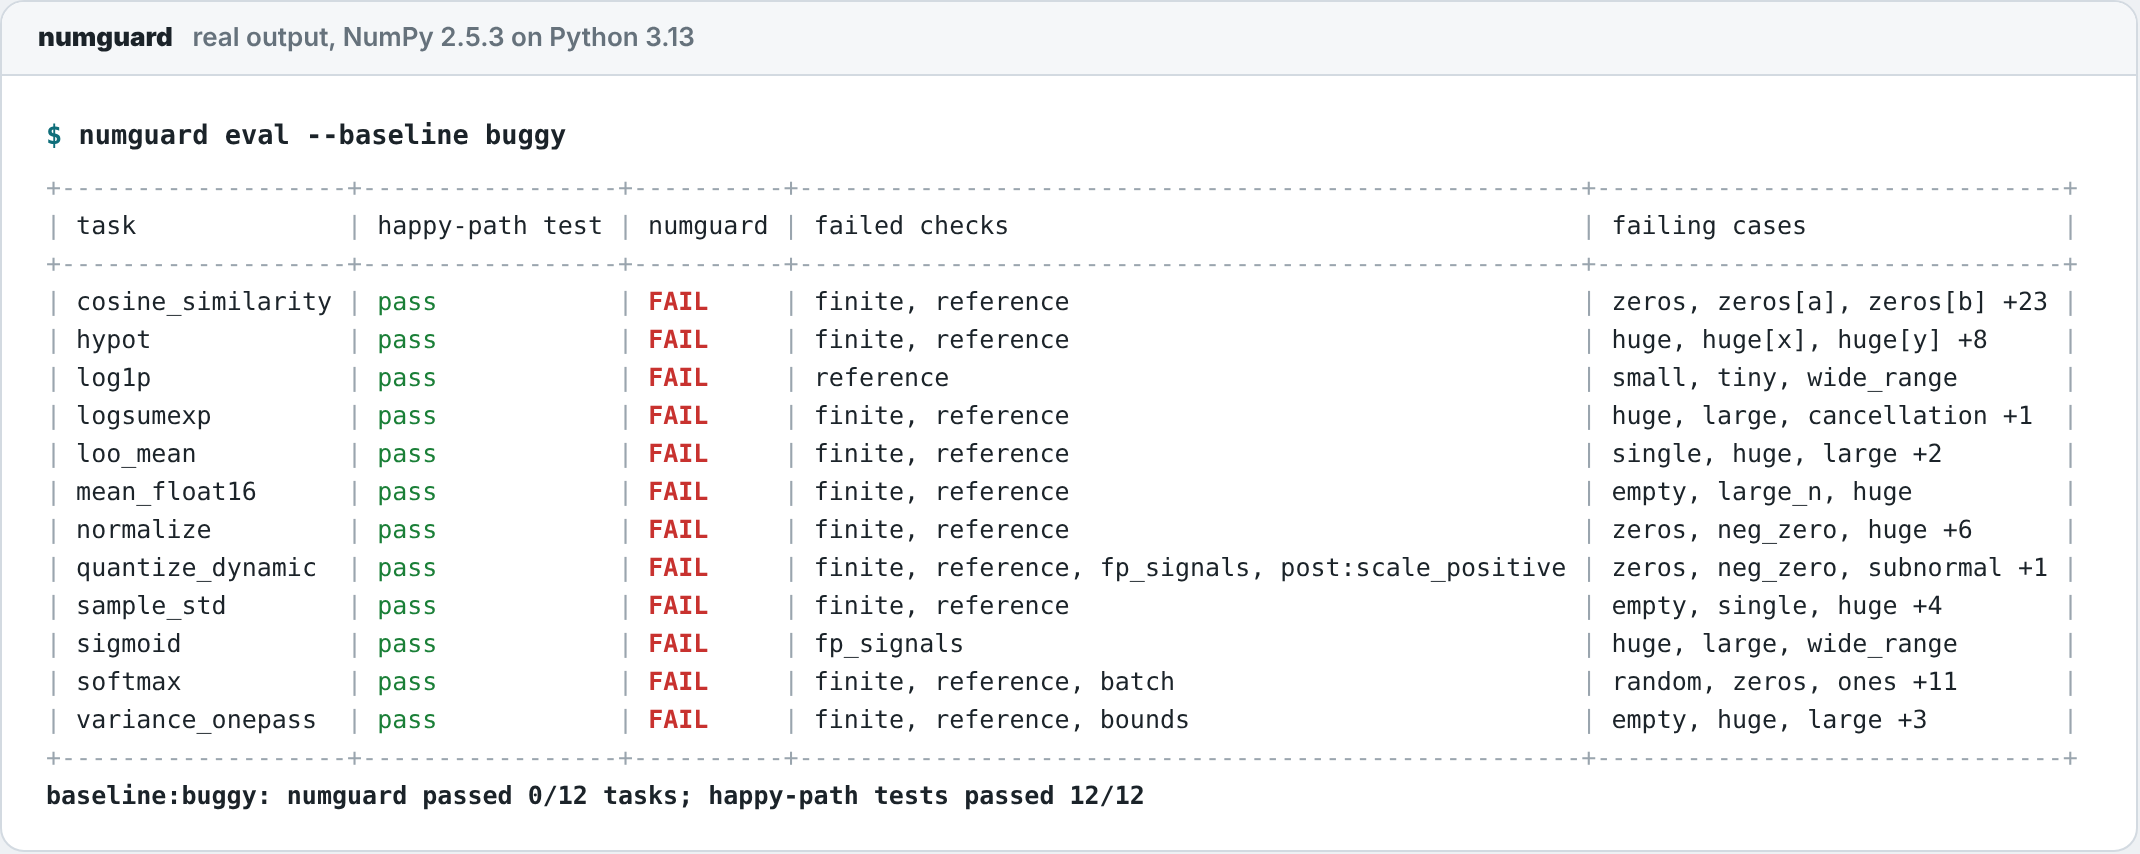
All 12 buggy versions pass their happy-path test, and numguard catches all 12. All 12 references pass. These are the only scoreboard numbers in this README, and both were measured (NumPy 2.5.3, Python 3.13).
Both scoreboards as text
$ numguard eval --baseline buggy
+-------------------+-----------------+----------+----------------------------------------------------+-------------------------------+
| task              | happy-path test | numguard | failed checks                                      | failing cases                 |
+-------------------+-----------------+----------+----------------------------------------------------+-------------------------------+
| cosine_similarity | pass            | FAIL     | finite, reference                                  | zeros, zeros[a], zeros[b] +23 |
| hypot             | pass            | FAIL     | finite, reference                                  | huge, huge[x], huge[y] +8     |
| log1p             | pass            | FAIL     | reference                                          | small, tiny, wide_range       |
| logsumexp         | pass            | FAIL     | finite, reference                                  | huge, large, cancellation +1  |
| loo_mean          | pass            | FAIL     | finite, reference                                  | single, huge, large +2        |
| mean_float16      | pass            | FAIL     | finite, reference                                  | empty, large_n, huge          |
| normalize         | pass            | FAIL     | finite, reference                                  | zeros, neg_zero, huge +6      |
| quantize_dynamic  | pass            | FAIL     | finite, reference, fp_signals, post:scale_positive | zeros, neg_zero, subnormal +1 |
| sample_std        | pass            | FAIL     | finite, reference                                  | empty, single, huge +4        |
| sigmoid           | pass            | FAIL     | fp_signals                                         | huge, large, wide_range       |
| softmax           | pass            | FAIL     | finite, reference, batch                           | random, zeros, ones +11       |
| variance_onepass  | pass            | FAIL     | finite, reference, bounds                          | empty, huge, large +3         |
+-------------------+-----------------+----------+----------------------------------------------------+-------------------------------+
baseline:buggy: numguard passed 0/12 tasks; happy-path tests passed 12/12

$ numguard eval --baseline reference
+-------------------+-----------------+----------+---------------+---------------+
| task              | happy-path test | numguard | failed checks | failing cases |
+-------------------+-----------------+----------+---------------+---------------+
| cosine_similarity | pass            | pass     |               |               |
| hypot             | pass            | pass     |               |               |
| log1p             | pass            | pass     |               |               |
| logsumexp         | pass            | pass     |               |               |
| loo_mean          | pass            | pass     |               |               |
| mean_float16      | pass            | pass     |               |               |
| normalize         | pass            | pass     |               |               |
| quantize_dynamic  | pass            | pass     |               |               |
| sample_std        | pass            | pass     |               |               |
| sigmoid           | pass            | pass     |               |               |
| softmax           | pass            | pass     |               |               |
| variance_onepass  | pass            | pass     |               |               |
+-------------------+-----------------+----------+---------------+---------------+
baseline:reference: numguard passed 12/12 tasks; happy-path tests passed 12/12
Grading any coding agent
The harness only reads files, so any agent, or a person, can be graded:
- For each task, give the agent the contents of
task.md(numguard tasks --show <task>prints it). - Save the answer as
DIR/<task>/solution.py, defining the function named in the task. - Run
numguard eval --candidate-dir DIR [--json-out results.json].
Missing solutions are reported as missing and solutions that fail to import as error. --task NAME (repeatable) grades a subset and --solution-name handles another file name. solution.py is imported and run in-process: grade untrusted code inside a container. numguard bench automates all three steps for an LLM.
Agent (experimental)
Three commands use an LLM. All three are off unless you call them, need your own API key, and follow the same rule as the rest of numguard: the model proposes, numguard executes, and only the executed result counts.
| command | the model writes | numguard then |
|---|---|---|
numguard suggest |
a spec: domains, dtypes, properties, a reference expression, options | validates it, runs it in a subprocess, and flags the reference as suspect if it disagrees with your function on benign inputs |
numguard fix |
a rewrite of a failing function, same name and signature | refuses denylisted code, runs the rewrite in a subprocess against every check, and accepts it only if it is verified |
numguard bench |
solution.py for each corpus task |
statically checks it, grades it with numguard eval in a subprocess, and prints a leaderboard row |
Configure the model through environment variables (never a config file); each command also takes --provider, --model, --base-url and --reasoning-effort:
export NUMGUARD_LLM_PROVIDER=anthropic          # or openai (any OpenAI-compatible chat-completions server)
export NUMGUARD_LLM_API_KEY=...                 # stripped from every subprocess numguard starts
export NUMGUARD_LLM_MODEL=...                   # required; there is no default model
# optional: NUMGUARD_LLM_BASE_URL, NUMGUARD_LLM_REASONING_EFFORT,
#           NUMGUARD_LLM_PRICE_IN / NUMGUARD_LLM_PRICE_OUT (USD per million tokens, for a cost estimate)
The client speaks the Anthropic Messages API and OpenAI-compatible chat completions, retries rate limits with backoff, and reports token usage after every run. Two provider quirks: OpenAI's GPT-6 Luna only calls tools through Chat Completions with NUMGUARD_LLM_REASONING_EFFORT=none, and GPT-6 models reject temperature unless reasoning is off (numguard sends none).
The model's tools are read-only (read_function, show_failures, read_file, list_files, grep, list_catalogue) and confined to the repository root; repository text reaches the model inside random per-session delimiters as data, and its only output is a schema-validated submit call.
numguard suggest
numguard suggest mypkg.ops:logsumexp                          # print a decorator, a [[target]] and the report
numguard suggest mypkg.ops:logsumexp --write numguard.toml    # append the [[target]]
numguard suggest mypkg.ops:logsumexp --write specs/test_logsumexp_spec.py
The model reads the function, its call sites and tests, and numguard's catalogue, then submits a spec. numguard validates it with the same strict validator as numguard.toml and runs it in a subprocess. If the reference disagrees with your function on benign inputs (random, ones, sorted, ...), numguard can't tell which one is wrong: the model gets another round (--rounds, default 2), and if the disagreement stays, the reference is reported as suspect, its disagreements are not reported as bugs, and the spec is re-run without it. Output: a ready-to-paste @numguard.guard(...) decorator, a [[target]] table and the check report. Exit 0: spec found and checks pass; 1: checks fail; 3: no usable spec. Review a suggested spec before relying on it: a permissive spec hides bugs.
numguard fix
numguard fix mypkg.ops:logsumexp                               # spec from ./numguard.toml or @numguard.guard; prints a diff
numguard fix mypkg.ops:logsumexp --spec specs/test_logsumexp_spec.py --rounds 3 --apply
In the spirit of Herbie, but verified by execution rather than by search. The spec comes from --spec (a spec file written by suggest, or a numguard.toml), --config, the matching target of ./numguard.toml, or the function's @numguard.guard. The model sees the source, spec and failure table and submits a rewrite; a static denylist refuses it before anything runs if it imports anything outside numpy, math, scipy, mpmath and a few standard math modules, or uses open, eval, exec, compile, __import__ or dunder names. The rewrite then runs in a subprocess worker, side by side with the original, and is verified only if
- its signature is identical,
- every (check, case, dtype) result that failed for the original now passes,
- no result fails that did not fail before,
- on benign cases where the original passed every check, it agrees with the original (within 4x the comparison tolerance), and
- output shapes and dtypes are unchanged on those cases.
Otherwise the reasons and the new failure table go back to the model, up to --rounds (default [agent] rounds, else 3). The result is the status, the reasons, a before/after table of failing results per check and a unified diff. Files change only with --apply, and only for a verified rewrite.
numguard bench
numguard bench --model my-model-id --tasks logsumexp,softmax,hypot
numguard bench --model my-model-id --task logsumexp --task hypot --out-dir runs/my-model --json-out bench.json
Sends each task's task.md to the model (no tools), statically checks each solution.py (a denylisted one is refused and never run), and grades it with numguard eval in a subprocess with a timeout. It prints a per-task table (pass, fail, error, refused, no_submission), a Markdown leaderboard row | model | pass@1 | happy-path | failures | and JSON. Solutions go to --out-dir (default numguard-bench/<model>).
In CI
The agent workflow splits fix into numguard agent propose (holds the key, reads the PR as data, never installs or runs it) and numguard agent verify (no secrets, runs the rewrites against the checks). Because refinement needs execution feedback and the executing job must not hold the key, CI asks for several independent rewrites per failing target instead ([agent] variants, default 3, each in a fresh session with a different strategy hint) for up to [agent] max_targets (default 3) targets; the verify job runs every variant and keeps the best verified one. A verified rewrite appears on the card as a collapsible "suggested fix (verified)" diff; nothing is committed.
Be realistic about it. We have not published bench results for any model, and we have not measured how often suggest or fix produce something useful: there are no agent numbers in this README because none were measured. "Verified" is relative to the spec and to numguard's cases; it is not a proof of correctness, so review a rewrite like any other patch. The corpus has 12 tasks, enough to separate naive from careful implementations and far too few to rank models with confidence. Details: docs/AGENT.md.
GitHub integration
The check workflow runs numguard check --config (plus pytest when numguard.toml has a [pytest] table), writes a Markdown card to the job summary, and uploads result.json, card.md, the PR number and head SHA as the numguard-result artifact. The privileged comment workflow validates the artifact, re-renders the card and upserts one sticky PR comment.
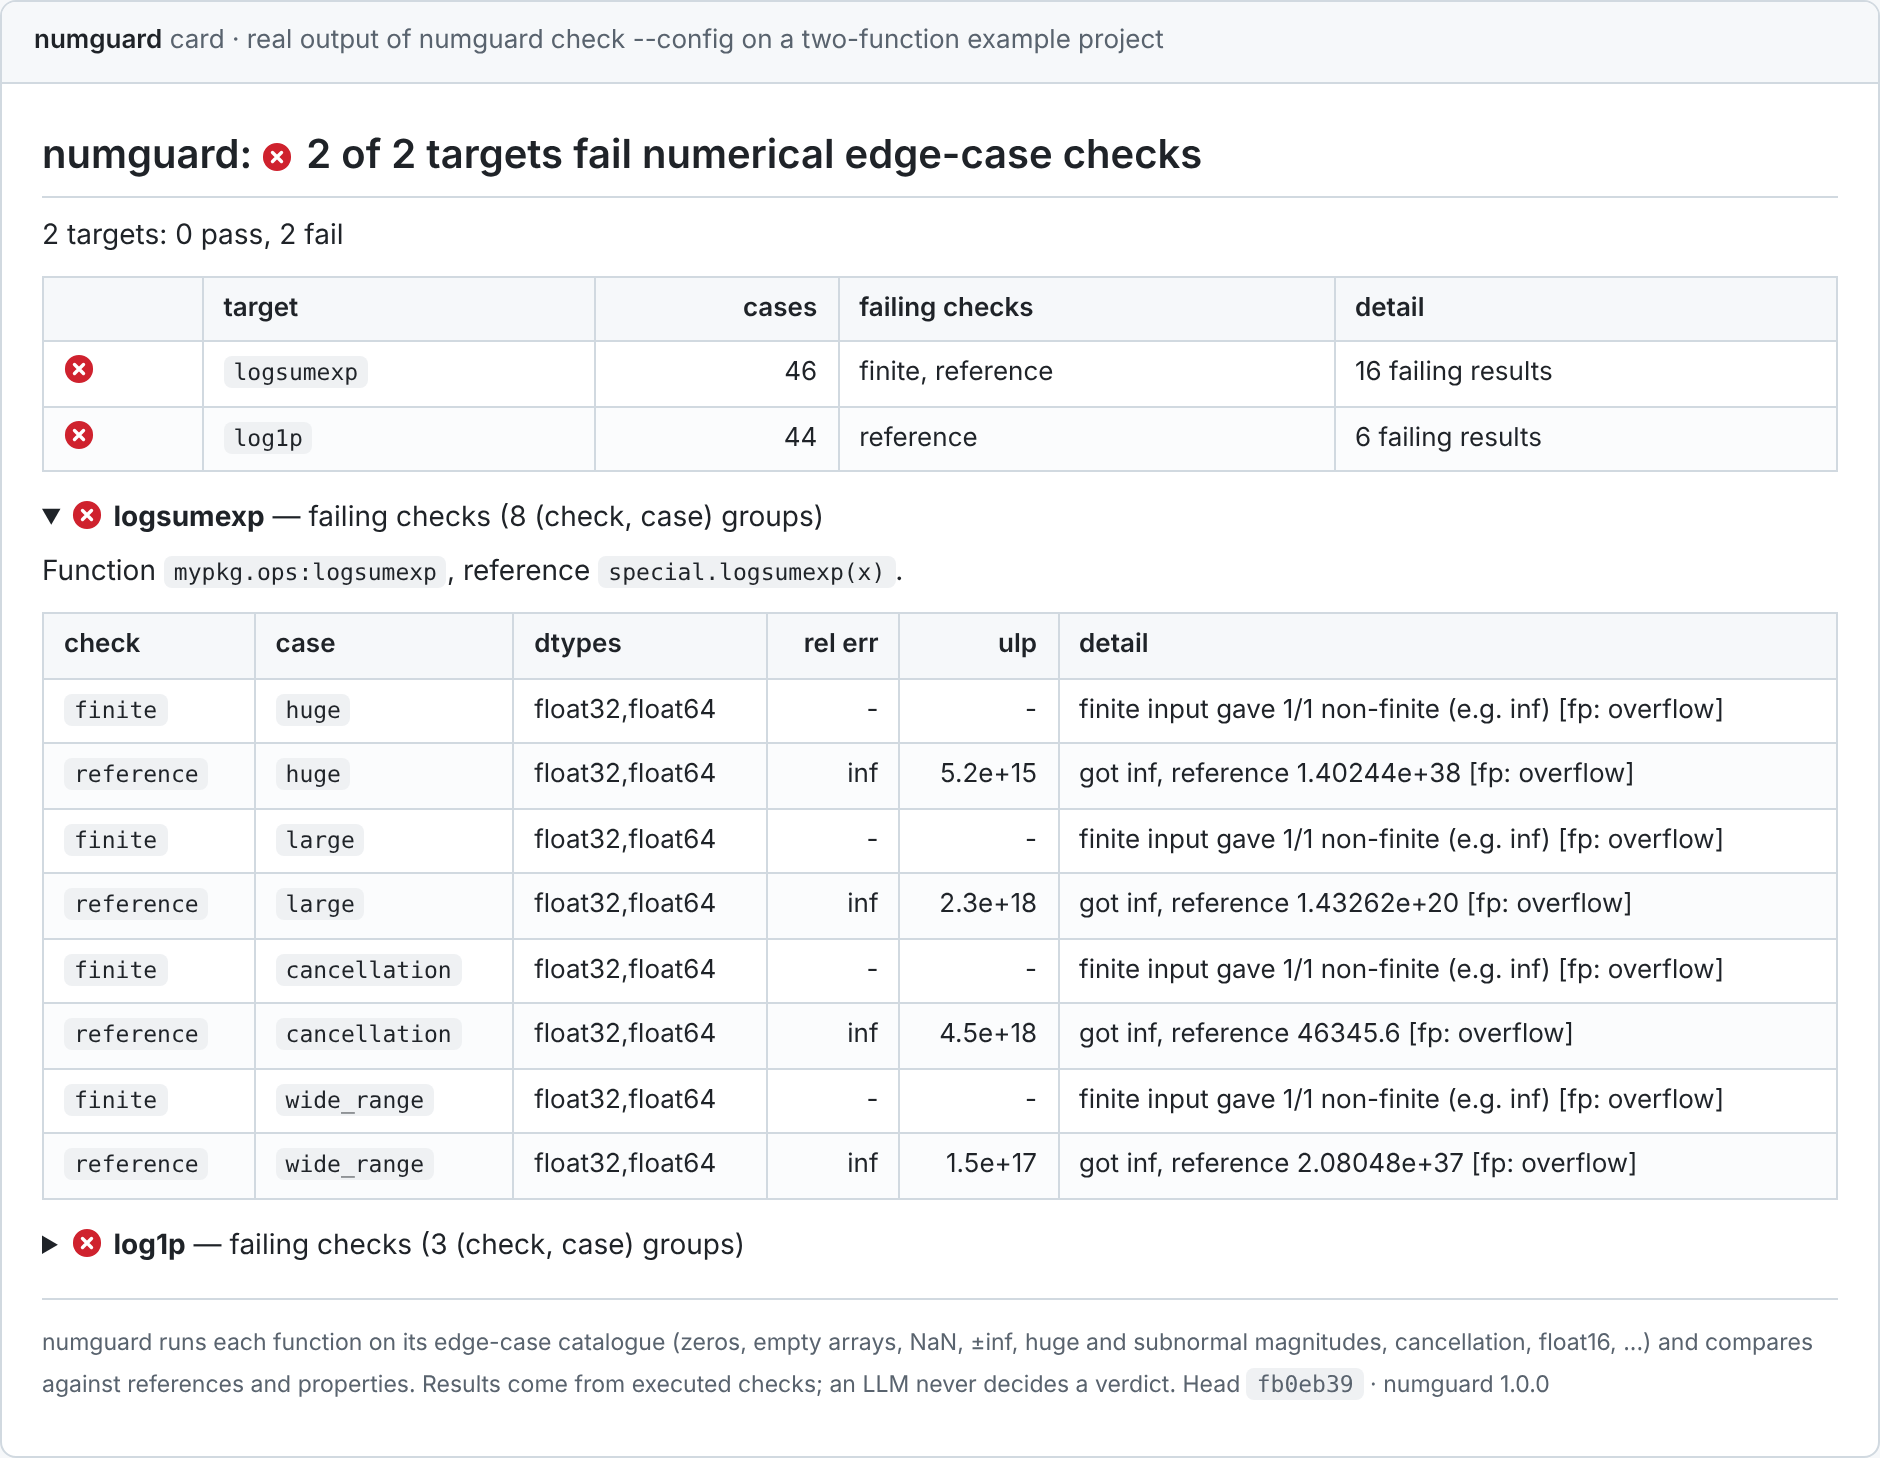
A real card: numguard check --config numguard.toml --card-out card.md on the two-target example from Config file, rendered the way GitHub shows it.
| Section | What it shows |
|---|---|
| Verdict | One line, e.g. 2 of 2 targets fail numerical edge-case checks. With labels: true the PR gets numguard: pass, numguard: fail or numguard: error. |
| Targets | One row per target: status, number of cases, failing checks, number of failing results; plus the pytest counts when [pytest] ran. |
| Failures | A collapsible section per failing target with the same table as the CLI: check, case, dtypes, relative error, ULPs, detail. |
| Suggested fixes | Only when the agent workflow ran: a collapsible "suggested fix (verified)" diff per target. |
| Data block | Invisible: a <!-- numguard:data {...} --> comment with the status, per-target counts and checks as JSON, built from validated fields only (escaped, capped at 4000 characters). Read it with numguard.carddata.parse_card_data. |
Security model
Running a pull request's code next to a token or an API key is the dangerous part. numguard splits the work into three trust zones connected only by artifacts:
- PR code runs only in jobs without secrets. The check job runs on
pull_requestwithcontents: read,persist-credentials: false, timeouts, andnumguard.tomlread from the base commit. The agent's verify job has no secrets either. - The LLM key never meets PR code. A gate job (no checkout, no key) decides whether the agent runs at all. The propose job reads files as data and never installs, imports or runs them; the model's tools are read-only and its only output is a schema-validated submit call. Untrusted text (source, docstrings, reports) is delimited as data in prompts. The verify job treats the propose job's output as untrusted too.
- Model-written code is never trusted. It is statically checked first (imports only from
numpy,math,scipy,mpmathand a few standard math modules; noopen,eval,exec,compile,__import__or dunder names), then run only in a subprocess with a timeout and an environment with secret-looking variables (*TOKEN*,*KEY*,NUMGUARD_LLM_*, ...) removed. Only the re-checked outcome counts. - The privileged comment job never checks out or executes PR code. It installs numguard into an isolated virtualenv, validates
result.jsonstrictly and the triggering run's head SHA, re-renders the card from validated data (the uploadedcard.mdis ignored), escapes everything PR-derived, and warns when the PR changes workflows,numguard.toml,pyproject.tomlorconftest.py. - Never
pull_request_targettogether with a checkout of the PR head. That pattern runs attacker code with a write token and your secrets. The repository's own tests check the shipped workflows for it, for secrets in PR-code jobs, for${{ github.event.* }}interpolated intorun:steps, and for minimal permissions.
The subprocess denylist is a speed bump, not a sandbox: Python can reach most things in many ways. The real isolation on GitHub is the job split. Locally, numguard fix runs the candidate in a subprocess on your machine; run it in a container if you don't trust the model. A malicious PR can still tamper with its own results inside the unprivileged job. See docs/SECURITY_MODEL.md and docs/AGENT.md.
How numguard compares
Different tools answer different questions. This is our best reading of each as of October 2026; corrections are welcome.
| Herbie PLDI 2015, uwplse |
Hypothesis + hypothesis.extra.numpy |
numpy.testing |
SciCode-style benchmarks SciCode, FEM-Bench, ODE-1000 |
numguard 1.0.0 |
|
|---|---|---|---|---|---|
| Main question | Can this floating-point expression be rewritten to be more accurate? | Does a property hold across generated inputs? | Are these arrays equal or close? | How good is a model at writing scientific code? | Does my array function survive numerical edge cases? |
| Input | An expression in FPCore (or Herbie's math syntax) | Any Python test | Arrays you construct | A fixed task set | Your Python array functions |
| Numerical edge cases | Samples inputs across the float range | floats() reaches NaN, ±inf, ±0 and subnormals; no catalogue of overflow thresholds, cancellation or large_n |
None; you pick the inputs | Hidden test cases per task | Named catalogue per dtype and domain |
| High-precision oracle | Yes (arbitrary precision) | Bring your own | Bring your own | Task-specific | Optional: mpmath or long double |
| Error in ULPs | Bits of error | No | assert_array_max_ulp |
No | Max relative error and ULPs per case |
| Minimal failing input | n/a | Yes, shrinking | n/a | n/a | No: cases are fixed and small |
| Rewrites code | Yes, its core feature | No | No | No | Experimental agent; a rewrite counts only once verified |
| Runs in pytest / CI | No (standalone tool and web UI) | Yes | Yes | No | Yes, plus a PR card |
| Grades AI coding agents | No | No | No | Yes, at scale | 12-task corpus |
These tools are complementary. Herbie's search-based rewriting with a real accuracy measure is far more principled than an LLM proposing a fix; if your hot path is a scalar expression, try Herbie first. Hypothesis is better at finding new failing inputs and shrinking them; numguard.strategies exists so you can use both. numpy.testing is what numguard's own comparisons are built on. Benchmarks such as SciCode measure models on many problems; numguard's 12-task corpus is a small, targeted complement, not a substitute.
numguard's own gaps: no shrinking and no search beyond its catalogue and seeded random inputs; no proofs; the corpus is small; backends other than NumPy are not exercised against the real libraries in CI; agent rewrites are LLM proposals filtered by checks, not synthesized with an accuracy guarantee, and in CI they get one round.
Configuration and CLI reference
The full references are docs/CONFIG.md, docs/CLI.md and docs/GITHUB.md. Every command has --help.
numguard.toml keys
| table | keys |
|---|---|
[defaults] |
any [[target]] key, merged into every target |
[[target]] |
function (required), name, description, inputs, domain, dtypes, properties, reference, reference_precision, reference_function, rtol, atol, nan, finite, allow_nonfinite, may_raise, exclude, include, ignore, bounds, monotonic, monotonic_arg, batched, batch_axis, fp_signals, out_dtype, check_mutation, kwargs, n, large_n, seed, ref_upcast, extra_cases, backend |
[pytest] |
args, timeout, enabled |
[agent] |
enabled (default false), rounds (3), max_tool_calls (25), max_targets (3), variants (3), timeout (120 s) |
Environment variables
| Variable | Purpose |
|---|---|
NUMGUARD_LLM_PROVIDER |
anthropic (Messages API) or openai (any OpenAI-compatible chat-completions server) |
NUMGUARD_LLM_API_KEY |
API key (not needed for a http://localhost base URL). Never read from config files; stripped from every subprocess. |
NUMGUARD_LLM_MODEL |
Model id. Required; there is no default. |
NUMGUARD_LLM_BASE_URL |
Optional API base URL |
NUMGUARD_LLM_REASONING_EFFORT |
Optional, OpenAI-compatible only: sent as reasoning_effort (none ... max) |
NUMGUARD_LLM_PRICE_IN, NUMGUARD_LLM_PRICE_OUT |
Optional USD per million input/output tokens, for the cost estimate |
NUMGUARD_TORCH_DEVICE |
Device for the torch backend (default CPU) |
NUMGUARD_CORPUS |
Corpus directory override |
NUMGUARD_DEBUG |
Print tracebacks of target errors in config mode |
CLI reference
numguard check   [TARGET] [options]           one function, or every [[target]] of ./numguard.toml
numguard eval    --baseline buggy|reference | --candidate-dir DIR    grade the 12 corpus tasks
numguard tasks   [--show TASK]                list corpus tasks, or print one prompt
numguard cases                                list the edge-case kinds and their tags
numguard summary --json result.json [--out FILE]
numguard comment --json result.json [--pr N] [--expect-head-sha SHA] [--labels] [--dry-run]
numguard init    [--repo DIR] [--agent] [--force] [--ref TAG] [--install-command CMD] [--target MODULE:FUNC]
numguard suggest TARGET [--write spec.py|numguard.toml] [--rounds N]          (agent)
numguard fix     TARGET [--spec FILE] [--rounds N] [--apply]                   (agent)
numguard bench   --model MODEL [--task NAME ... | --tasks a,b] [--out-dir DIR] (agent)
numguard agent propose | verify               the CI split of fix              (agent)
| Command | What it does |
|---|---|
check |
Runs the checks. Exit 1 when a target fails (--fail-on fail|error|never). |
eval |
Grades candidate solutions, or the bundled buggy/reference versions. |
summary |
Validates result.json and writes the card to --out, $GITHUB_STEP_SUMMARY or stdout. Needs no token. |
comment |
Validates result.json, re-renders the card, upserts the PR comment and (with --labels) the status label. |
init |
Writes the caller workflows and a commented numguard.toml. |
suggest, fix, bench |
The agent commands. |
agent propose |
(CI) Holds the key, executes nothing from the PR, writes candidate rewrites. |
agent verify |
(CI) No LLM; runs the candidates against the checks and adds the fixes to result.json. |
check option |
Purpose |
|---|---|
--ref MODULE:FUNC |
reference implementation |
--dtype D |
float16, float32, float64 or bfloat16 (repeatable); default float32, float64 |
--prop NAME[:VALUE] |
metamorphic property (repeatable) |
--domain D |
domain for every argument: any, positive, "[a, b)", "int[0, 255]", ... |
--nan propagate|raise|ignore |
expected NaN behaviour |
--batched, --monotonic increasing|decreasing |
batching and order invariants |
--fp-signals ignore|fail |
fail on FP signals for finite inputs |
--rtol, --atol, --large-n N, --seed N |
tolerances, size of large_n, random seed |
--exclude P, --allow-nonfinite P |
case name, kind or tag patterns (repeatable) |
--backend numpy|torch|jax|cupy |
where to run the function |
--config FILE, --target NAME, --root DIR, --no-pytest |
config mode |
--json, --json-out FILE, --card-out FILE, --max-rows N |
output |
If the target has a spec attached with @numguard.guard, the CLI uses it and command-line options override it. Everything also works as python -m numguard ....
FAQ
Does a passing report mean my function is correct?
No. It means the function behaved on every case numguard generated, under the contract you declared. The catalogue is aimed at the places numerical code usually breaks, but it is a finite set of inputs, not a proof.
Do I need SciPy, mpmath or an LLM?
No. The only runtime dependencies are NumPy and click. SciPy is handy as a source of references, mpmath gives high-precision references, and an LLM is only used by suggest, fix and bench.
My function legitimately returns inf for huge inputs. How do I stop the finite check failing?
Pass a reference: the finite check only fails when the reference (rounded to the output dtype) is finite. Or allow it explicitly with allow_nonfinite=["huge"], or a tag such as "overflow_prone".
Can the agent change my code?
Only numguard fix --apply writes files, and only with a rewrite that passed verification. Without --apply it prints a diff. On GitHub, a verified rewrite appears as a collapsible diff on the card; nothing is committed. suggest --write writes the spec file or appends a [[target]] you asked for.
Is the corpus a benchmark I can cite?
It is a small, hand-written set of 12 bug classes with plausible naive implementations and correct references. Use it to check that a model or a person avoids those specific mistakes, and report the task count alongside any number. For broad model comparisons, use a benchmark designed for it.
Does it work with PyTorch, JAX or CuPy?
Through the backend adapter, when the library is installed: cases are generated in NumPy, converted in, and outputs converted back. The adapters are tested with fake torch and jax modules; the real libraries are not part of numguard's CI. Reports from real use are welcome.
Why several workflows instead of one?
So that no single job both runs PR code and holds a secret or a write token. A single pull_request workflow can't comment on fork PRs, and a single pull_request_target workflow that checks out the PR is the classic "pwn request".
Limitations
- The catalogue is fixed plus seeded random values: numguard doesn't search for new failing inputs or shrink them.
- Without a reference, value errors are only caught through invariants and dtype limits.
np.longdoubleis plain float64 on Windows and macOS arm64, so "high precision" there needs mpmath.- Only floating-point signals that NumPy reports are recorded; other backends may not raise them.
evalandbenchimport candidate solutions in-process; grade untrusted code in a container.- The agent is experimental, its success rate is unmeasured, and a verified rewrite is only as good as the spec and cases it passed. Rewrites replace one module-level Python function; methods, C extensions and multi-file changes are out of scope.
Roadmap
- Gradient checks:
jax.grad/torch.autogradoutputs at domain boundaries and support edges - Accelerator dtypes and modes:
float8variants and TF32-style reduced-precision matmul - Shrinking of failing cases, and exporting them as FPCore for Herbie
- More corpus tasks: matrix ops, special functions, quantiles, numerically stable losses
- Native support for the Python array API standard in the backend adapter
- Published
benchresults, run on GitHub with the numbers and costs alongside
Contributing
Contributions are welcome, especially new corpus tasks and edge-case kinds. See CONTRIBUTING.md. In short:
pip install -e ".[dev]"
python -m pytest            # or, without pytest: python -m unittest discover -s tests
numguard eval --baseline reference && numguard eval --baseline buggy
docs/TESTING.md describes every test level. Please report security issues privately through the repository's security advisory form rather than in a public issue.
License
MIT © 2026 Bhaskar Gurram
1 maintainer

Metadata
1 maintainer
Release files for numguard-ci 1.0.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| numguard_ci-1.0.1.tar.gz | 229.1 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| numguard_ci-1.0.1-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 414.0 kB
Release files / numguard_ci-1.0.1.tar.gz
| Download URL | numguard_ci-1.0.1.tar.gz |
|---|---|
| Size | 229.1 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
370976d4902c71f4a7ffe6b172fbe190c066e92a817e5cbee3ba37db22e13a30
|
|
BLAKE2b-256 checksum How to use checksums |
4e94a521dcf361ac591005a330ec6ae3e25b87a65b3396778620475c17d3f0ab
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Release files / numguard_ci-1.0.1-py3-none-any.whl
| Download URL | numguard_ci-1.0.1-py3-none-any.whl |
|---|---|
| Size | 184.9 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
99e246221c0a3cfe9558527f60f00909d1f69222d314e9c48c9aa915bff5e229
|
|
BLAKE2b-256 checksum How to use checksums |
520f1003919e1376defed2740407d1481025ffbb3977770e843d0e0aae86f6de
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|














