
oblitus
Oblitus is Latin for "erased, forgotten". It is a Python library and command-line tool for tables that contain personal data. It:
- detects which columns hold personal or sensitive data. It reads column names and values, and checks the check digits of about 30 document formats, Brazilian and international;
- proposes a plan, a JSON file you can review and edit, that assigns one of 29 techniques to each flagged column;
- applies the plan as pseudonymization (keyed, re-linkable by whoever holds the key) or true anonymization (no link left, and checked; the default), keeping either the statistics or the privacy first;
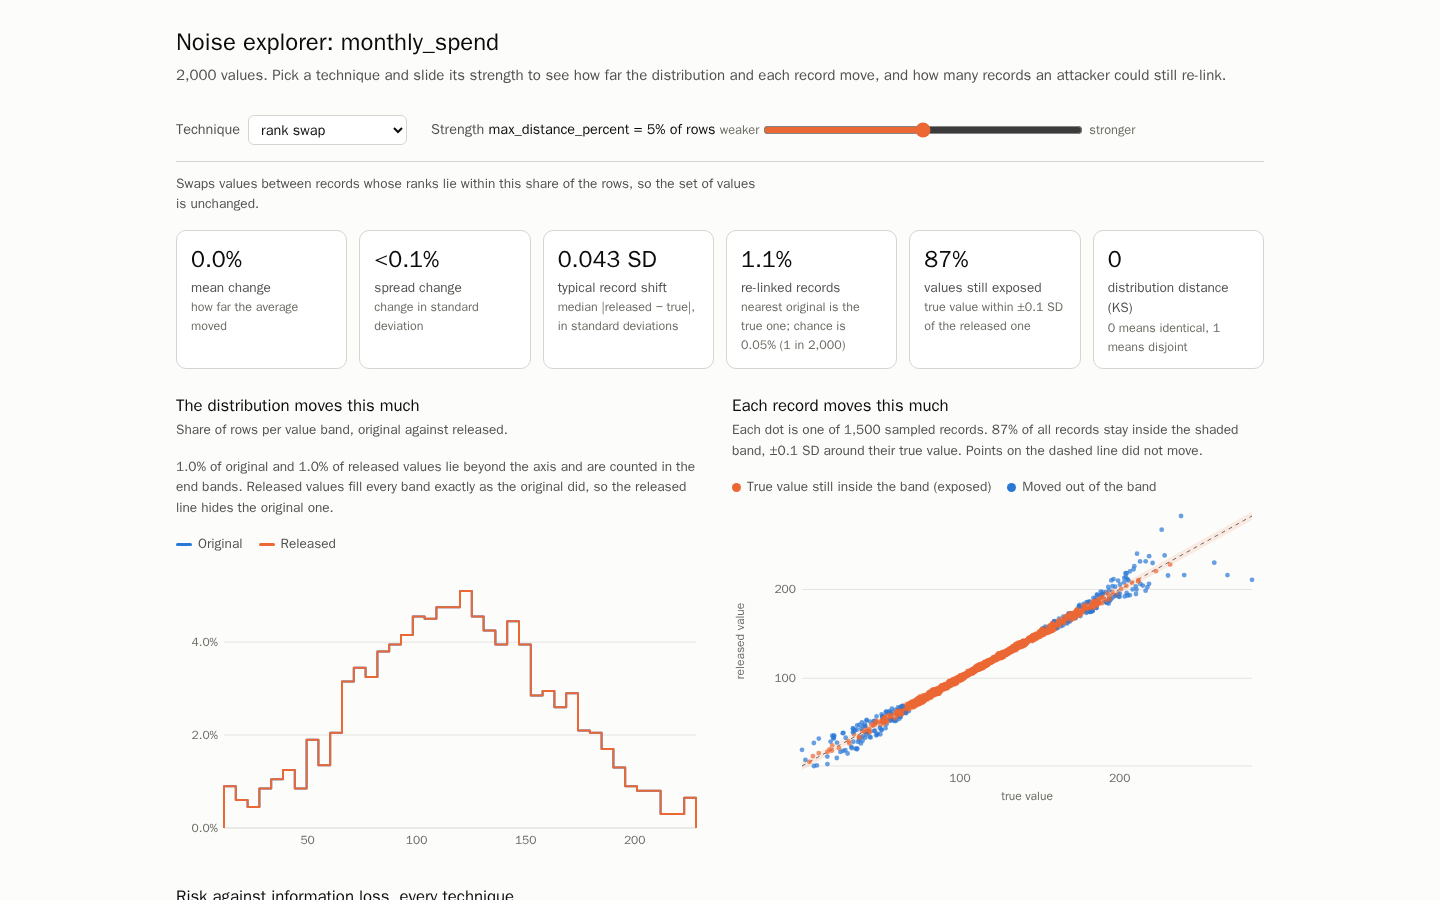
- shows how noise deflects your data on an interactive page: distributions, per-record shifts and re-identification risk for every noise technique and strength;
- reveals the original values of reversibly encrypted columns, for whoever holds the key;
- generates synthetic data from a sample or from a schema. A schema can plant correlations, conditional rules, formulas, trends, seasonality, outliers and exact statistics. It can also generate data-science challenges with a known answer key.
Features and algorithms
| Area | What is implemented |
|---|---|
| Detection | Patterns with checksum validation. Brazil: CPF, CNPJ (numeric and the new alphanumeric format), CNH, PIS/PASEP/NIS, CNS, Título de Eleitor, RENAVAM, NF-e key, vehicle plates, PIX keys, CEP, phones. International: cards (Luhn and issuer prefix), IBAN, US SSN and ITIN, IMEI, IPv4/IPv6, MAC, Aadhaar (Verhoeff), Spanish DNI/NIE, Portuguese NIF, Dutch BSN, German tax ID, UK NINO, Italian codice fiscale. Column-name hints in English and Portuguese, with negative hints for order numbers and timestamps. All candidates are scored, ties are flagged, and confidence comes in tiers. Also: leading zeros lost to integer storage are restored, birth dates are recognized from their values, and personal data embedded in free text is found |
| Masking, one-way | Redaction, suppression, partial masking that keeps separators, entity redaction inside free text |
| Hashing, one-way | HMAC with SHA-256, SHA-512, SHA3-256, SHA3-512, BLAKE2b or BLAKE2s. Argon2id and bcrypt, with a keyed salt (joins survive) or a random one |
| Pseudonymization | Keyed format-preserving scrambling. Realistic surrogates: names, emails, phones, valid CPF/CNPJ, SSN, cards, IBAN, IPs, addresses, URLs. A surrogate is either consistent per value (a pseudonym) or random per cell (no link) |
| Encryption, reversible | AES-SIV deterministic encryption (RFC 5297). AES-256-GCM randomized encryption. FF1 format-preserving encryption (NIST SP 800-38G, checked against the NIST sample vectors). Keys derived from one secret with HKDF-SHA256 |
| Generalization | Fixed-width, equal-width and quantile binning. Rounding. Date and string truncation. Top and bottom coding. Rare-category suppression |
| Noise | Gaussian noise rescaled to keep mean and variance. Laplace mechanism (ε-local differential privacy with fixed bounds). Multiplicative noise. Date shifting, with one offset per person or company |
| Perturbation | Shuffling, rank swapping, univariate microaggregation, randomized response (local differential privacy) |
| Business confidentiality | Opaque category codes in random order, with small segments merged. Per-store indexing by default, so no known value plus a public total gives the money back; recentring and rescaling (robust, z-score, min-max) when sizes must stay comparable; rank, log-ratio and growth too. Dominance and p% checks, so a segment's biggest contributor cannot be read from the release. See docs/business-confidentiality.md |
| Protection modes | Anonymization (the default) or pseudonymization, each with statistical or privacy fidelity. Anonymization refuses linking techniques and runs under a throwaway key. Identifiers are checked on the data, not only by technique name, and unique columns released unchanged are flagged. Each result is labelled anonymized, at_risk, pseudonymized or identifiable, by checks named after the EDPB 2026 criteria: no record isolation, no linkage, no inference |
| Privacy and risk | k-anonymity, l-diversity, t-closeness (earth mover's distance), k-anonymity enforcement by local suppression or by Mondrian generalization, l-diversity enforcement, generalization hierarchies (with a Brazilian CEP preset), joint microaggregation (MDAV), whole-record uniqueness, distance-based record linkage, interval disclosure, and attack-based risk (singling out, linkability, inference) with the optional Anonymeter extra |
| Utility | Change in mean and standard deviation, Kolmogorov–Smirnov, Wasserstein / IQR, total variation distance, correlation change, per-record shift in standard deviations |
| Noise explorer | A self-contained interactive HTML page per column. For every technique and strength it shows before/after distributions, original against released per record with an exposure band, and a risk-utility map. It works offline and follows light and dark themes |
| Synthesis | Distributions (normal, lognormal, gamma, exponential, Poisson, uniform, quantile curves) truncated to bounds. Spearman correlations imposed through a Gaussian copula. Conditional overrides that keep correlations. Formula columns using a safe expression language with date and random functions. Outlier planting, exact statistics, row constraints, unique keys, null shares (random, or following the data: MAR and MNAR) and templates. Related tables with foreign keys, class imbalance and difficulty levels for challenges. Learned Gaussian copula from a reference table |
| Challenges | A schema question produces train and test files and a private answer key. The key lists the true drivers, the correlated-but-not-causal columns and the distractors, plus the best score any model can reach (RMSE/R², or accuracy/AUC/log loss). Columns that leak the target are flagged. With a treatment, the key also holds the true average, treated-only and per-group effects, the bias of the naive comparison, the confounders, mediators, colliders and instruments, and a valid adjustment set. Optional test-set drift (covariate or concept) and label noise on the train or test labels, both reported in the key. Panels of entities over periods (entity-level and period-level columns, lag, AR series, seasonality, regimes) with a time split that holds out the last periods |
| Interfaces | Python API (Anonymizer), editable JSON plans and schemas, the oblitus CLI, CSV and Parquet, custom techniques |
Install
Python 3.12 or later:
pip install oblitus
# with DuckDB support:
pip install "oblitus[duckdb]"
# microphone and camera entropy sources for `oblitus keygen`:
pip install "oblitus[audio]" "oblitus[camera]"
# with PySpark, for Spark DataFrames (needs Java to run Spark itself):
pip install "oblitus[spark]"
# with OpenDP, for differentially private aggregates:
pip install "oblitus[opendp]"
# AIM differentially private synthesis (Private-PGM and JAX, no PyTorch):
pip install "oblitus[aim]"
# with attack-based risk checks (Anonymeter):
pip install "oblitus[anonymeter]"
# more countries' identifiers and international phone numbers:
pip install "oblitus[identifiers]"
# names and addresses inside free text, with a named-entity model:
pip install "oblitus[ner]"
uv add oblitus works too. The package imports as oblitus and installs the oblitus
command. Each GitHub release also
carries the wheel and the source archive. Versions up to 0.2.0 were called data-anonymizer
and were published on GitHub only.
Quick start
From a clone of the repository, this writes a sample customer table from the bundled example schema, then scans, plans, anonymizes it and writes a noise explorer page:
git clone https://github.com/rmonteiro-pereira/oblitus.git
cd oblitus
uv sync
export OBLITUS_SECRET_KEY="$(openssl rand -hex 32)"

uv run oblitus synthesize --schema examples/customers_schema.json --rows 2000 -o customers.csv
uv run oblitus scan customers.csv
uv run oblitus propose customers.csv --protection anonymization -o plan.json
# review and edit plan.json, then:
uv run oblitus apply customers.csv --plan plan.json -o customers_anon.csv --report report.json
uv run oblitus explore-noise customers.csv --column monthly_spend -o monthly_spend_noise.html
apply ends with a line such as
wrote 2000 rows to customers_anon.csv; k-anonymity 1 -> 5; result is anonymized. Open the
explorer page in a browser; docs/noise-explorer.md
gives the command for each system, and warns that the page holds real values from the column.
How it works, on one row
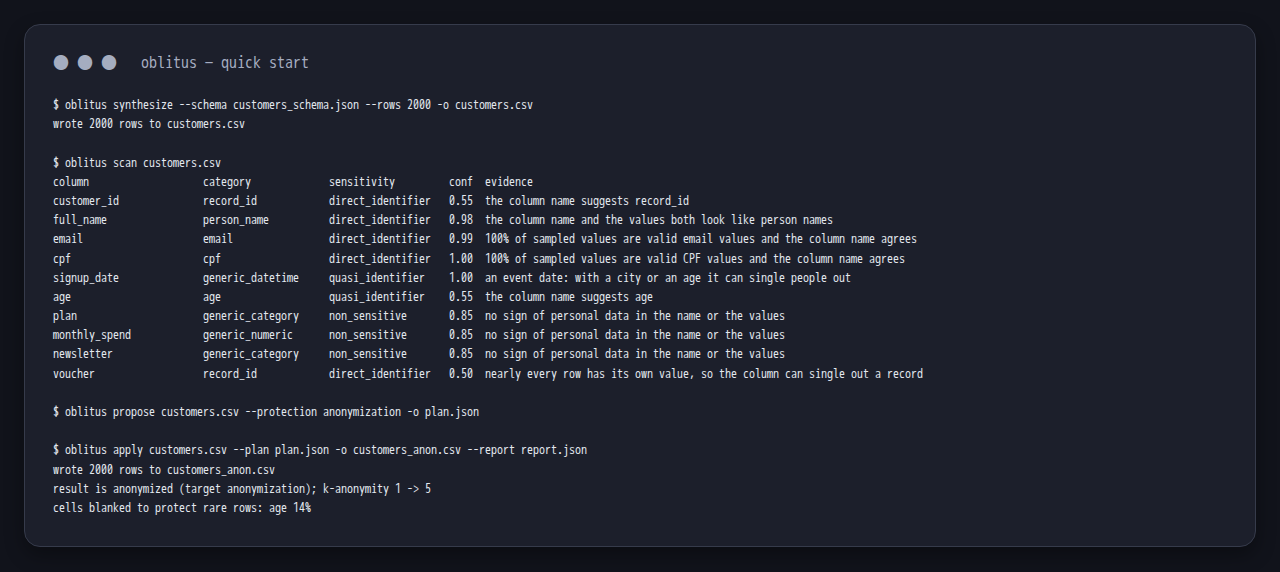
scan classifies every column. On the sample table it finds five direct identifiers
(customer_id, full_name, email, cpf, and voucher, whose few filled values are almost
all distinct) and age as a quasi-identifier. propose turns that into a plan, and apply
runs it. One row before and after; your values will differ, and timestamps and amounts are
shortened here:
| customer_id | full_name | signup_date | age | monthly_spend | ||
|---|---|---|---|---|---|---|
| Before | 6242 | Barbara Sanchez | alexandererica@example.net | 2024-07-01 15:20:42 | 33 | 100.98131 |
| After | ID-0498 | Steven Edwards | rvasquez@example.net | 2024-11-18 | 47 | 136.0 |
- The identifiers are replaced: fresh codes for the ID and voucher, random fakes for name, email and CPF.
- Timestamps are cut to the day and amounts rounded to three significant figures, because a value distinct in every row would single the row out.
- Ages are averaged in groups of five, and local suppression blanks the rare cells that would still make a row unique.
- The rows come back in a fresh random order, so the "after" row is a different customer: nothing in the release lines it up with the original.
apply then checks the released table and labels it anonymized, at_risk, pseudonymized
or identifiable, with the reason for anything short of the target.
The same flow in Python. scan, propose, validate, apply and reveal take pandas,
Polars, DuckDB and Spark tables and return the same kind. A DuckDB or Spark table needs the
plan's row_key (see docs/protection.md).
import pandas as pd
from oblitus import Anonymizer, Fidelity, Protection

# Parse dates, so the plan treats signup_date as a timestamp rather than text.
customers = pd.read_csv("customers.csv", parse_dates=["signup_date"])
anonymizer = Anonymizer(secret_key="replace-with-a-long-random-secret", seed=42, locale="pt_BR")

for finding in anonymizer.scan(customers):
    print(finding.column, finding.category, finding.confidence, finding.evidence)

plan = anonymizer.propose(
    customers, protection=Protection.ANONYMIZATION, fidelity=Fidelity.STATISTICAL
)
result = anonymizer.apply(customers, plan)
result.data  # the anonymized DataFrame, of the kind you passed in
result.protection.level  # anonymized, at_risk, pseudonymized or identifiable
result.protection.problems  # why a level was not reached
result.utility.max_correlation_change
Configuration
| Variable | Required | Default | What it does |
|---|---|---|---|
OBLITUS_SECRET_KEY |
for reveal |
random per run | At least 16 bytes; a shorter key is refused. Keys every pseudonym and keyed salt, and is the master secret for the encryption keys. With the same key, the same value always gets the same pseudonym, so tables pseudonymized separately still join. reveal refuses to run without it. apply warns and uses a random key, so pseudonyms change on every run and encrypted columns can never be revealed. Anonymization plans use a throwaway key instead for everything that could link a release back or to another release: pseudonyms, encryption, category codes and random fakes. The key still drives their noise, which is reproducible for the key holder, so keep it secret even then. |
In Python, pass secret_key= to Anonymizer; the library never reads the environment.
Treat the key like a password. Anyone who holds it can decrypt the reversible columns,
and can test whether a guessed real value produces a given pseudonym.
Generate a key with oblitus keygen, which mixes os.urandom (always) with the extra
sources you name: hardware (/dev/hwrng), microphone and camera (low-order bits of
ambient noise, extras audio and camera), timing (CPU jitter) and beacon (drand and
NIST, opt-in, public). A source that is absent or fails its health check is skipped and
reported on stderr. See docs/protection.md.
In Python, generate_key(sources) returns the key and a report, and
Anonymizer(throwaway_key_source=...) draws the anonymization throwaway key from the same mix.
Command line
All commands take --seed N (reproducible noise and synthesis; with a secret key the
noise is reproducible only for the key's holder, with a seed alone anyone who knows the
seed can recompute it) and --locale (Faker
locale for fake values, such as pt_BR; default en_US). Tables can be .csv or
.parquet, read and written with Polars.
| Command | What it does |
|---|---|
oblitus scan INPUT [--sample-size N] |
Prints each column's category, sensitivity, confidence and evidence |
oblitus propose INPUT [--protection P] [--fidelity F] [-o PLAN] |
Writes a plan as JSON (stdout without -o) |
oblitus apply INPUT -o OUTPUT [--plan PLAN] [--protection P] [--fidelity F] [--report REPORT] [--attack-risks] [--row-key COLUMN] [--vault PATH] [--chunk-rows N] |
Applies a plan, or proposes one first. Prints the protection level reached. --report writes privacy, utility and protection results as JSON. --attack-risks also runs the Anonymeter singling-out, linkability and inference attacks, prints each risk with its confidence interval and adds them to the report (needs pip install "oblitus[anonymeter]"). --row-key overrides the plan's row_key. --chunk-rows N streams a CSV or Parquet file N rows at a time and writes the output incrementally, for files larger than memory. It needs --plan with a row_key and refuses, with the reasons, any technique that reads the whole column (see docs/protection.md) |
oblitus apply-many MANIFEST [--protection P] [--fidelity F] [--report REPORT] [--vault PATH] |
Applies a plan to each related table listed in a JSON manifest, so one person gets the same pseudonym, token and date offset in every table. See docs/protection.md |
oblitus reveal INPUT --plan PLAN -o OUTPUT [--row-key COLUMN] [--vault PATH] |
Decrypts the columns the plan encrypted, detokenizes those it tokenized (with --vault), and leaves one-way columns as they are |
oblitus explore-noise INPUT --column NAME -o PAGE.html [--band SD] [--max-rows N] |
Writes the interactive noise explorer for one numeric column. Columns longer than N values (default 200,000) are explored on a random sample |
oblitus infer-schema INPUT [--fidelity F] [-o SCHEMA] |
Learns a generation schema from a table |
oblitus synthesize -o OUTPUT [--rows N] [--schema SCHEMA] [--reference INPUT] [--fidelity F] |
Generates a synthetic table. A schema with related tables writes one CSV per table into the folder OUTPUT |
oblitus dp-synthesize INPUT --domains DOMAINS.json -o OUTPUT (--epsilon E [--delta D] | --rho R) [--rows N] [--method mst|aim] [--workload COLUMNS ...] |
Generates a differentially private synthetic copy with MST, or with AIM (oblitus[aim]), which measures the column groups the model gets most wrong. --workload a,b,c names a group whose joint distribution matters (AIM only, repeatable). The JSON file declares each column's public domain. Needs --delta or --rho (Gaussian noise). Prints the budget spent and the column groups measured |
oblitus check-synthetic SYNTHETIC --real TRAIN [--holdout HOLDOUT] [--report REPORT.json] |
Checks whether a synthetic table memorized its training records: exact copies, near and partial copies of the most isolated training records, distance to the closest real record and, with a holdout the generator never saw, the DCR share and a membership-inference attack. Prints a verdict and exits 3 on a finding. Thresholds are in docs/synthesis.md |
oblitus dp-aggregate INPUT --spec SPEC.json -o OUTPUT (--epsilon E [--delta D] | --rho R) [--confidence C] [--accuracy-output FILE] |
Releases noisy counts, sums and means per group with OpenDP (oblitus[opendp]). The JSON spec declares each group's values and each sum's bounds. Also writes the interval half-width of every value |
oblitus challenge --schema SCHEMA [--rows N] -o FOLDER |
Generates a data-science challenge: train.csv, test.csv, QUESTION.md (a task description written from the schema), one CSV per child table for related-table schemas, and answers/ with the answer key |
oblitus keygen [--source NAME ...] [--format hex|base64] |
Prints a key for OBLITUS_SECRET_KEY on stdout and the per-source report on stderr. NAME is hardware, microphone, camera, timing or beacon; os is always mixed in |
oblitus techniques |
Lists every technique, its parameters and whether it is reversible |
P is anonymization (the default) or pseudonymization. F is statistical (the
default) or privacy. -o is short for --output.
Exit codes:
0: success.2: an error.3:applywrote its output, but the result does not reach the plan's protection target.
Documentation
- docs/detection.md: categories, recognized identifiers, and how a column is classified
- docs/protection.md: pseudonymization against anonymization, the default proposals, plan files and the protection checks
- docs/techniques.md: every technique, its parameters and its effect
- docs/business-confidentiality.md: sharing company data, such as tenant revenue and rent, without revealing any one company's figures
- docs/noise-explorer.md: writing and opening the noise explorer page, and reading its metrics
- docs/synthesis.md: schemas, planted patterns, synthesis from a sample, and data-science challenges
- docs/differential-privacy.md: what epsilon means, public bounds and domains, DP aggregates, MST and AIM synthesis and the budget report
- ARCHITECTURE.md: C4-style system views, how the code is organised and where to change things
- CONTRIBUTING.md: the project's standards for code, design, tests, docs, privacy review, commits and releases
- CHANGELOG.md: released changes
Development
uv sync
uv run pytest
uv run ruff format .
uv run ruff check .
uv run mypy src
GitHub Actions runs the same checks on Python 3.12 and 3.13 for every push to main and every
pull request (.github/workflows/ci.yml); there, formatting is checked with
ruff format --check instead of rewritten.
The standards every change follows are in CONTRIBUTING.md.
1 maintainer

Metadata
1 maintainer
Release files for oblitus 1.0.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| oblitus-1.0.0.tar.gz | 397.8 kB | With provenance | Details for oblitus-1.0.0.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| oblitus-1.0.0-py3-none-any.whl | Python 3 | none | any | Details for oblitus-1.0.0-py3-none-any.whl |
Total release size: 745.5 kB
Release files / oblitus-1.0.0.tar.gz
| Download URL | oblitus-1.0.0.tar.gz |
|---|---|
| Size | 397.8 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
ba6bec0a5c3bc8f18fb089562f8726159418ccf8d7a81fa2e8984eb8147d1f3b
|
|
BLAKE2b-256 checksum How to use checksums |
84aeaf826c5fc35a4830664d291403cb83589764eee190f0922593df979d760b
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 28, 2026.
Transparency logRelease files / oblitus-1.0.0-py3-none-any.whl
| Download URL | oblitus-1.0.0-py3-none-any.whl |
|---|---|
| Size | 347.6 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
11e1af746b7066eaa1138ce28cb20d0f76b97363cd66f8edd5dd3f36c3ef4014
|
|
BLAKE2b-256 checksum How to use checksums |
b2061d7385eefb214c37f9483309a29a3c7d5cd612c1521bbc5a5371f8c9eed1
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 28, 2026.
Transparency logSecurity for oblitus 1.0.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
All 2 files in this release have been uploaded with provenance metadata.
Attestation for oblitus-1.0.0.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 28, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














