
obsidian-wiki
A digital brain you grow with your AI agent.
It remembers what you figure out, connects it to what you already know,
and answers when you ask.


English | 繁體中文
You solve a hard problem on a Tuesday. Three months later, in a different repo, you solve it again from scratch — because the answer lived in a chat log you'll never find.
This fixes that. Point it at a folder, tell your agent what to remember, and it compiles what you learn into interconnected markdown you own. The pattern comes from Andrej Karpathy's LLM Wiki gist: compile knowledge once and keep it current, instead of asking an LLM the same questions forever or re-running RAG every time.
Your second brain. Your AI agent is how you grow it.
Every skill here is a markdown file that any agent — Claude Code, Cursor, Codex, Windsurf, Gemini CLI, and a dozen more — reads and runs. No runtime, no API keys, no vendor.
60 seconds
pip install obsidian-wiki
obsidian-wiki setup --vault ~/brain
That also registers the two session hooks, so every new session starts with who you are and what's open, and ends by capturing anything reusable. Pass --no-hooks to skip them.
Using uv or pipx? uv tool install obsidian-wiki and pipx install obsidian-wiki work the same way. (Not uvx — see Installation.)
Then open any project in your agent and say "set up my wiki".
Prefer not to touch a terminal? Give your agent this and it'll do the whole thing:
https://github.com/Ar9av/obsidian-wiki — set up my wiki
Other paths — git clone, Skills CLI, multiple vaults → Installation
What you actually do
Feed it. Anything text-shaped: docs, PDFs, chat exports, meeting transcripts, screenshots, URLs.
/wiki-ingest ~/research
/wiki-update                        # distill the repo you're standing in (code-graph aware)
/wiki-capture                       # save this conversation
/wiki-history-ingest claude         # mine everything you've ever asked Claude
Ask it. Answers come back with [[wikilink]] citations, not vibes.
/wiki-query what do I know about rate limiting?
/wiki-narrate MCP security          # a cited briefing on a topic
/wiki-digest week                   # what did I learn this week?
Find that session you can't name.
obsidian-wiki sessions-build
obsidian-wiki sessions-query "the auth bug with the weird retry loop"
Keep it honest. The vault gets messy on its own; these clean it.
/wiki-lint            # broken links, orphans, contradictions
/wiki-dedup           # "RSC" and "React Server Components" are one page now
/cross-linker         # weave new pages into the graph
/wiki-status          # what's ingested, what's pending, where the hubs are
All 39 skills → Skills Reference
See it
Open the vault in Obsidian and hit the graph view (Cmd/Ctrl+P → "Open graph view"). Say "color my graph" and it tints nodes by tag, category, or visibility.
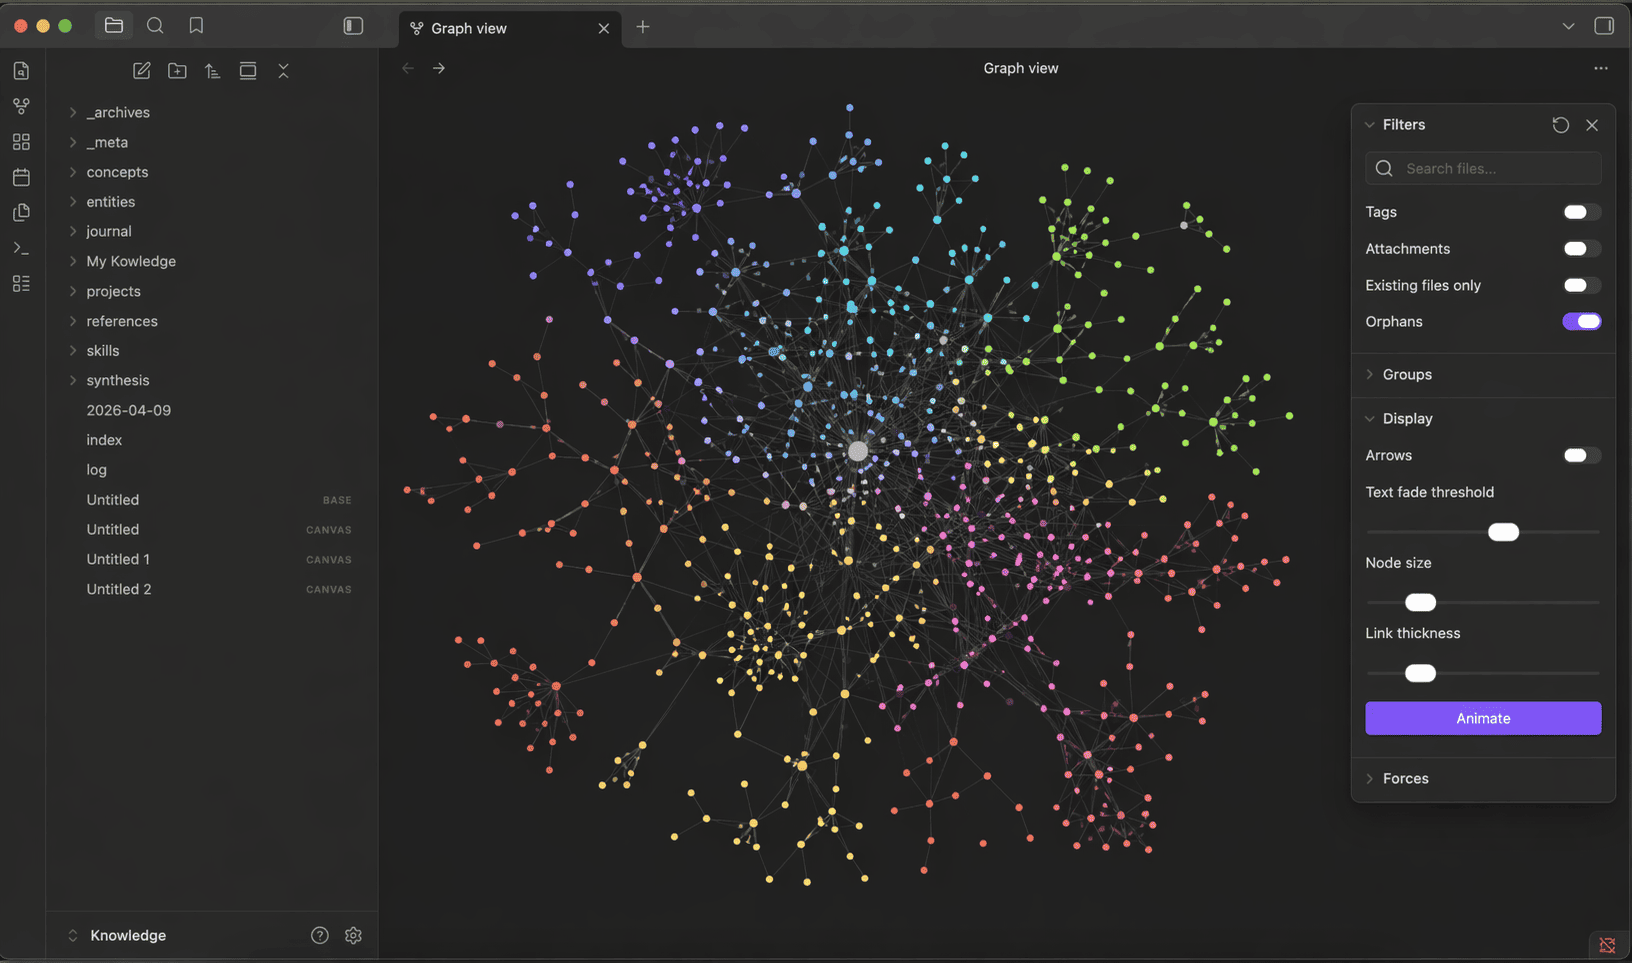
Or export the whole graph to graph.json, GraphML (Gephi/yEd), Neo4j Cypher, Postgres SQL, or a self-contained interactive graph.html.
Use it from Python
from obsidian_wiki import Memory

memory = Memory("~/brain")
memory.remember("stack", "Python, FastAPI", confidence=0.9)
memory.add("Postgres was chosen over MySQL for partial indexes.")
memory.search("postgres")
memory.recap()                       # inject at session start
No API key, no embedding model, no vector store, no network — the vault is markdown on disk, so everything your agent remembers is readable, greppable and diffable. user_id scopes per-person memory while knowledge stays shared.
More → Python API
It remembers between sessions
A session starts with the vault's memory already in context — who you are, what threads are open, what changed recently — and ends by capturing anything reusable before the context closes.
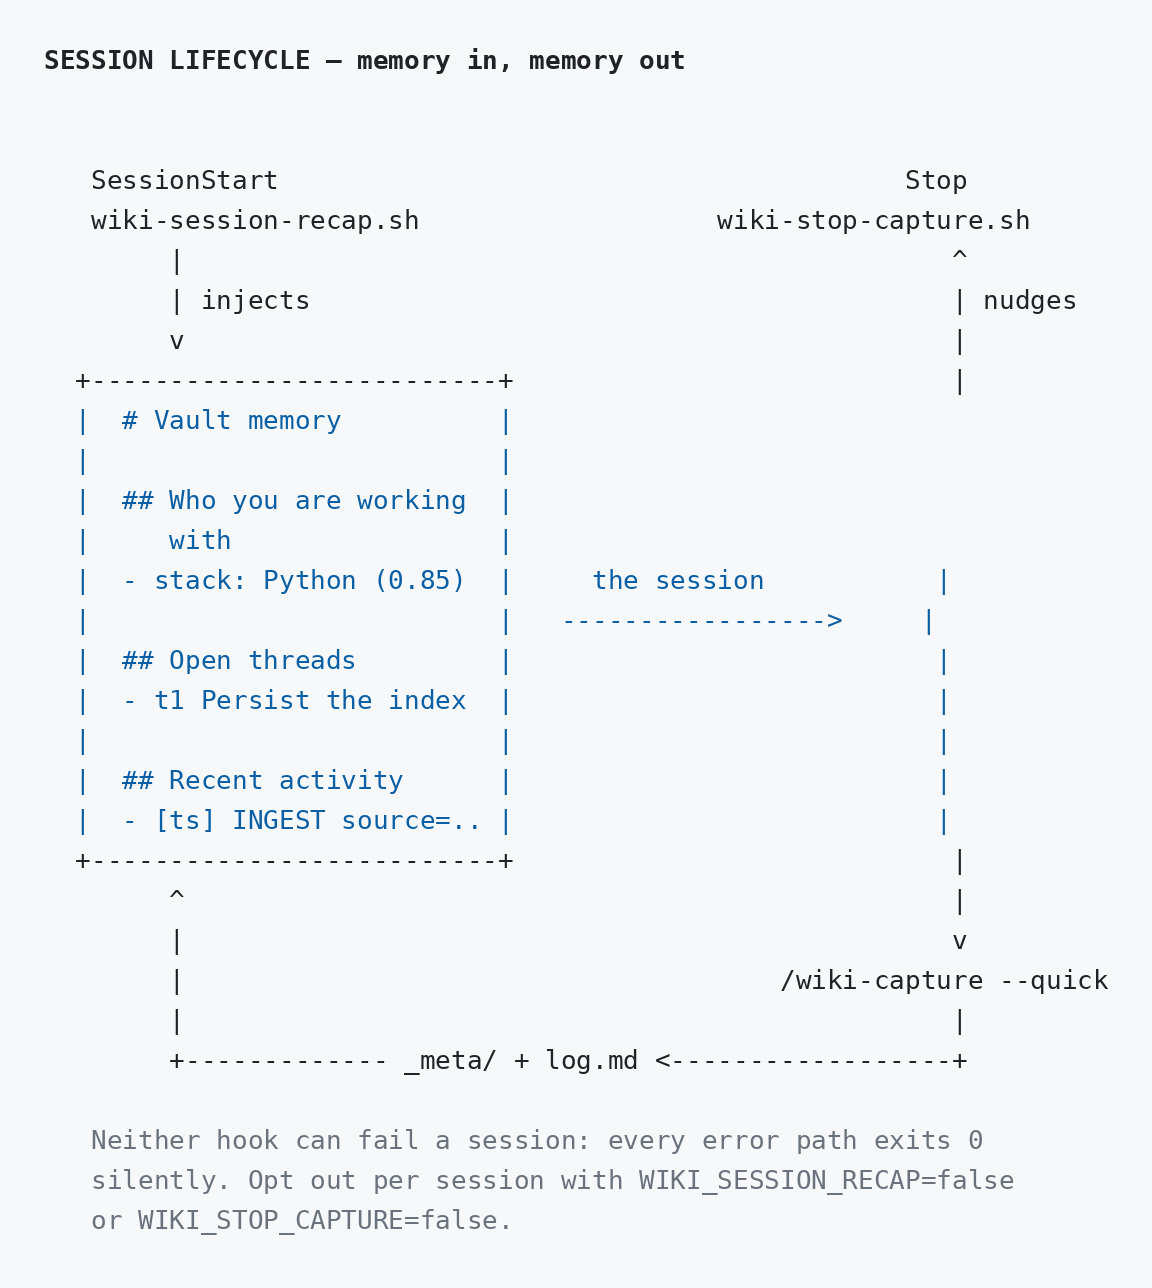
index.md, log.md, hot.md, and the owner profile and todo index under _meta/ all go through one writer that takes a lock and writes atomically, so parallel agents can't drop each other's updates.
More → Memory Surface
Why this and not a notes folder
- It compiles, it doesn't accumulate. New knowledge merges into existing pages. Contradictions get flagged. Nothing gets duplicated.
- It only reads what changed. A manifest tracks every source ingested, so the second run processes the delta — not your whole library again.
- You can tell knowledge from guessing. Every claim is tagged
extracted,^[inferred], or^[ambiguous], and lint flags pages drifting into speculation. - Queries stay cheap as it grows. Titles, tags, and summaries get read before page bodies. 20 pages or 2000, roughly the same cost.
- It's yours. Plain markdown in a folder. Push it to a private repo, open it in Obsidian, grep it, delete it. No service, no lock-in, nothing leaves your machine.
- It carries context across sessions. An owner profile, open threads, and a running snapshot get injected at session start, so you don't re-explain yourself.
- Works where you already work. One
.skills/directory, symlinked into every agent you use.
More → Architecture
Does it actually help?
Structural questions — "how is X connected to Y", "which pages hold my vault together", "what breaks if I delete this" — are the ones a plain agent is worst at. It has to grep every file and reconstruct the link graph by hand, every single time.
Same model, same vault, same questions. The only difference is whether obsidian-wiki
was installed:
| Plain agent | With obsidian-wiki | |
|---|---|---|
| Time to answer | 81s | 19s — 4.4× faster |
| Correct answers | 44% | 83% |
| Tool calls used | 9.9 | 4.6 |
| API cost | $0.202 | $0.208 — unchanged |
| Question | Plain agent | With obsidian-wiki |
|---|---|---|
| "How is X connected to Y?" | 122s | 18s |
| "What topic clusters do I have?" | 117s | 21s |
| "Which pages hold my vault together?" | 61s | 12s |
| "What breaks if I delete X?" | 26s | 24s |
The accuracy gap is not a rounding error. Asked to trace a connection, the plain agent
routed through index.md — which links to every page, so it "found" a short path that
means nothing. It made the same mistake in both runs, and named index as one of the
most important pages in the vault. The graph the skills query excludes bookkeeping files,
so that answer isn't reachable.
Method, and what this doesn't prove
Claude Sonnet, headless, on a real 38-page vault. Questions were asked in plain English
with no definition of the graph supplied — the plain agent had Read/Grep/Glob/Bash
and had to work it out, which it did competently (it wrote its own centrality
implementation rather than guessing). 4 questions × 2 conditions × 2 repetitions, run
serially so nothing competed for CPU.
Ground truth came from networkx, not from this project's own code: betweenness matches to 3.5e-18 across every node, and all 630 shortest-path pairs agree.
It's a small study — n=2 per cell on one 38-page vault — so treat the exact percentages as indicative. The wall-clock gaps (3–6×) are much larger than the run-to-run spread; the accuracy figures rest on fewer samples. One run in the "with" column failed outright: the model ignored the CLI, grepped by hand, and got it wrong.
Full data, per-run logs and the scaling measurements are in PR #175.
Documentation
| Installation | pip, clone, agent-driven setup, multiple vaults |
| Skills Reference | All 39 skills and their slash commands |
| Agent Compatibility | The full matrix + per-agent manual setup |
| CLI Reference | Every obsidian-wiki subcommand |
| Configuration | Config vars, QMD semantic search, _raw/ staging, GitHub sync |
| Architecture | The four ingest stages, vault structure, what we added to Karpathy's pattern |
| Python API | from obsidian_wiki import Memory — use a vault as agent memory |
| Memory Surface | The index, log, hot cache, owner profile, and todo index |
| Session Brain | Topic graph over your agent session history |
| Browser Extension | Capture pages into the vault, and fill web forms from it |
| Deployment | Run a vault as a Dockerized memory service agents reach over HTTP/MCP |
| Contributing | Adding skills, keeping the READMEs in sync |
Contributing
This is early. The skills work, but there's room to make the brain smarter — better cross-referencing, sharper deduplication, bigger vaults, new ingest sources. If you have a workflow that could be a skill, PRs are welcome.
License
1 maintainer

Metadata
1 maintainer
Release files for obsidian-wiki 2026.10.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| obsidian_wiki-2026.10.1.tar.gz | 4.2 MB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| obsidian_wiki-2026.10.1-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 5.4 MB
Release files / obsidian_wiki-2026.10.1.tar.gz
| Download URL | obsidian_wiki-2026.10.1.tar.gz |
|---|---|
| Size | 4.2 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
06a7e9ed6391474794af3f816507a4395f4f6c7eaffc3c6fb4e5efe294b3aa1d
|
|
BLAKE2b-256 checksum How to use checksums |
91b3c18d7165a28ad22ad85e31054bbdfb7054076ae1f5ff2c3351ac72f56e0e
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 1, 2026.
Transparency logRelease files / obsidian_wiki-2026.10.1-py3-none-any.whl
| Download URL | obsidian_wiki-2026.10.1-py3-none-any.whl |
|---|---|
| Size | 1.2 MB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
22fd05bd77f2e4e1167b561a3b869f914ca49b8a55fd5f201eecd01a9ef216cb
|
|
BLAKE2b-256 checksum How to use checksums |
5d9f829b8e38a53063f28af520d41a7a927fd937e78053ab13226b207f027055
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 1, 2026.
Transparency log













