
Open Data Stack


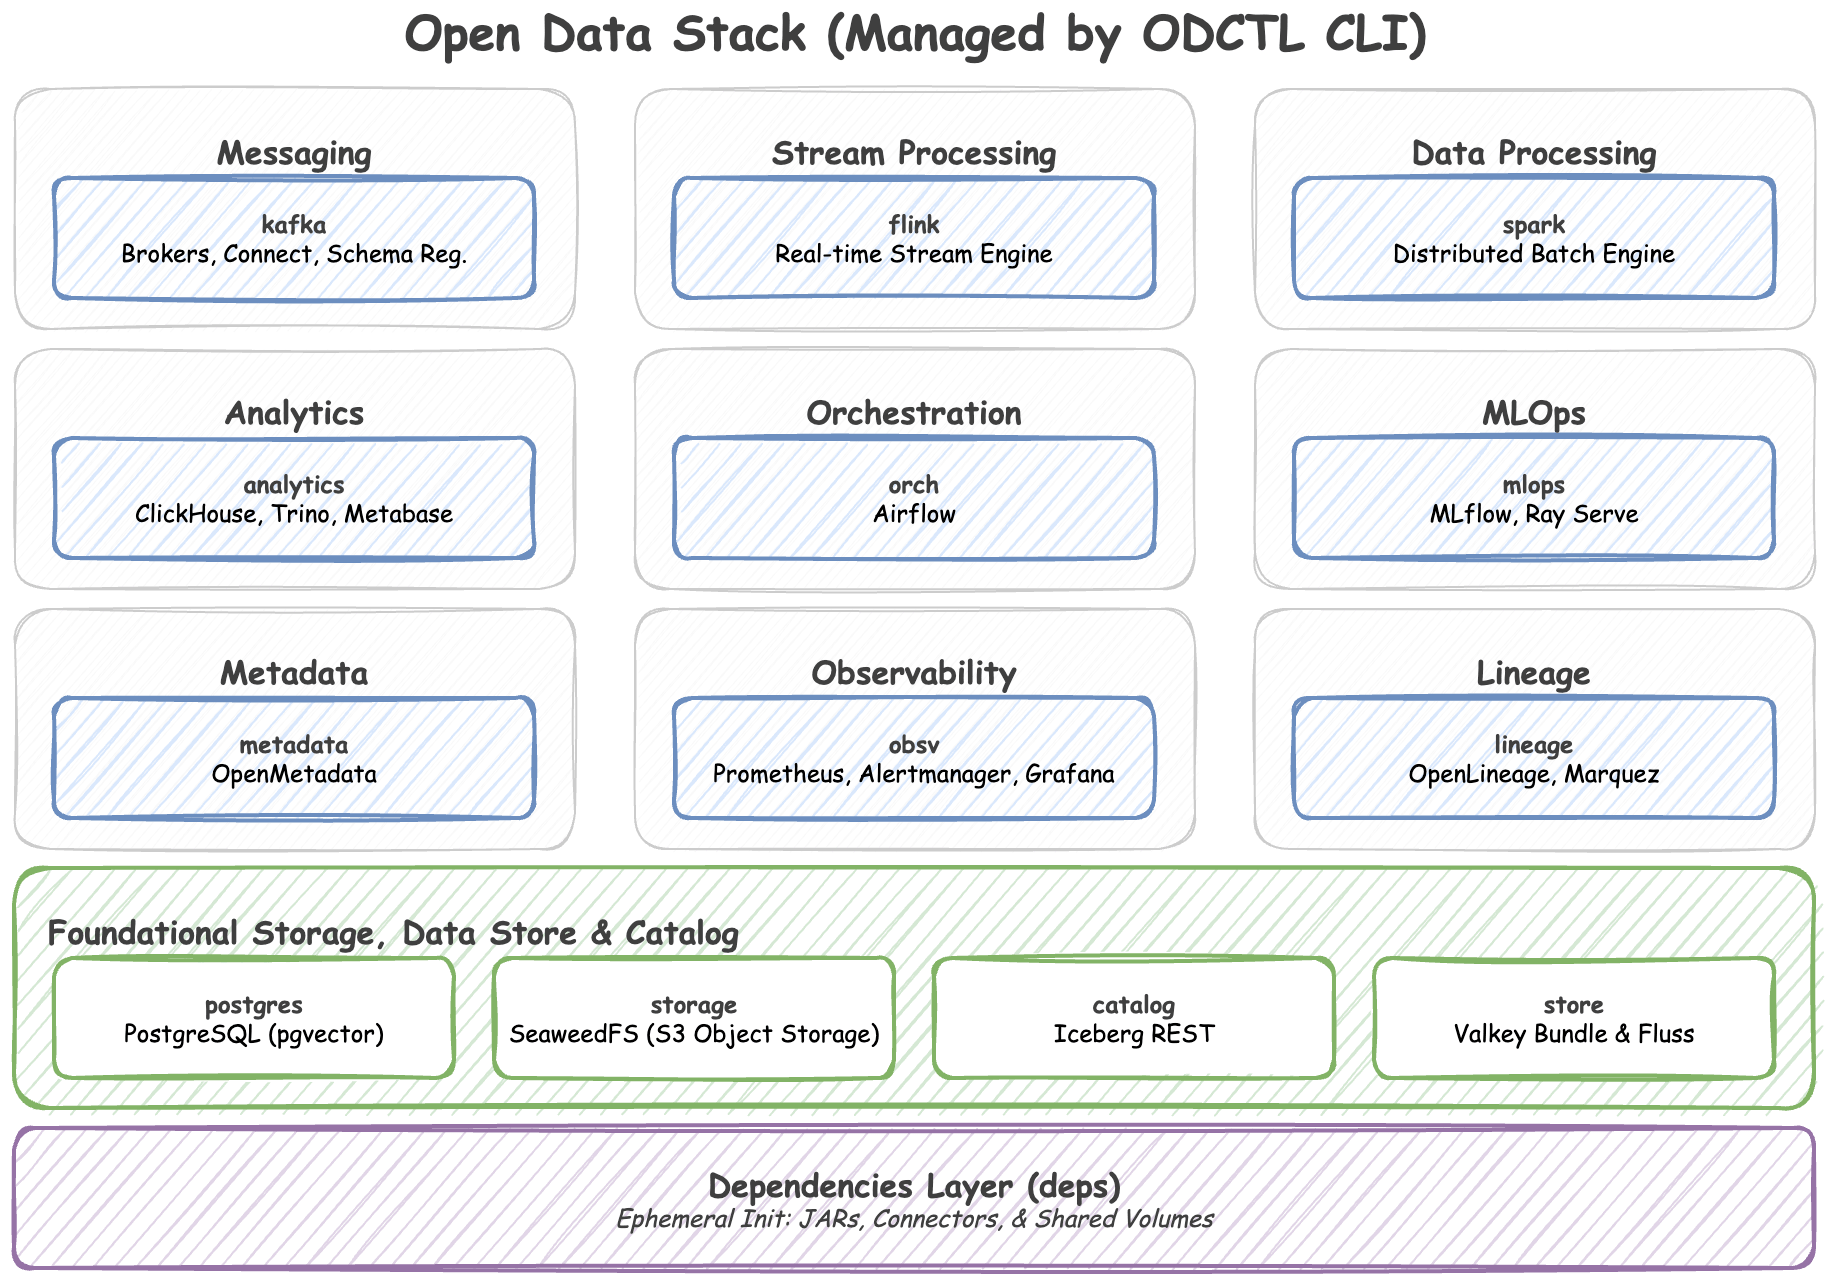
A curated collection of open-source technologies and an accompanying CLI (odctl) for experimenting with modern data architecture and MLOps locally.
Provisioning a local data environment with distributed systems can be highly complex. The Open Data Stack streamlines this process by resolving dependency conflicts, network routing configurations, and integration challenges across tools like Kafka, Spark, Flink, Iceberg, and Airflow. It provides a cohesive, Docker-based blueprint that operates seamlessly out of the box.
Bundled Technologies
The stack is organized into distinct profiles that can be launched independently or together:
- Messaging: Real-time event streaming, schema validation, and robust data ingestion.
- Stack: Kafka (KRaft), Schema Registry (Karapace), Kafka Connect, Kafka UI (kafbat)
- Stream Processing: Stateful stream processing and continuous real-time data transformations.
- Stack: Apache Flink
- Data Processing: Distributed batch processing and large-scale ETL pipelines.
- Stack: Apache Spark
- Analytics: Real-time OLAP querying, federated SQL execution, and interactive BI dashboards.
- Stack: ClickHouse, Trino, Metabase
- Orchestration: Workflow scheduling, DAG execution, and complex pipeline automation, in one container that reads DAGs from object storage.
- Stack: Apache Airflow (standalone, with the MLflow and Feast clients and the XGBoost, LightGBM and PyTorch runtimes)
- MLOps: Machine learning experiment tracking, model registry, HTTP model serving, and a feature store.
- Stack: MLflow, Feast
- Metadata: Centralized data catalog, data discovery, and enterprise governance.
- Stack: OpenMetadata
- Observability: Metrics, traces and logs over OpenTelemetry, with dashboards, in one container.
- Stack: grafana/otel-lgtm (OpenTelemetry Collector, Prometheus, Tempo, Loki, Grafana)
- Lineage: Data provenance, pipeline dependency tracking, and troubleshooting.
- Stack: OpenLineage, Marquez
- Foundational Storage, Data Store, & Catalog: Persistent state, S3-compatible object storage, unified table metadata, high-performance caching/vector search, and unified stream storage.
- Stack: PostgreSQL (pgvector), SeaweedFS (S3), Iceberg REST Catalog, Valkey Bundle, Apache Fluss
Prerequisites & Installation
Requirements
- Docker: Docker Engine or Docker Desktop must be running. We highly recommend allocating at least 8GB to 16GB of RAM to Docker, as data processing engines are resource-heavy.
- Python: Version 3.10 or higher.
Installation
Since odctl is a CLI tool, it is highly recommended to install it in an isolated environment using uv tool or pipx.
Using uv (Recommended):
uv tool install odctl
Using pipx:
pipx install odctl
Using pip:
pip install odctl
Quick Start
Get your local cluster up and running in three simple steps.
1. Initialize your workspace
This command copies the default Docker Compose files and configurations into a hidden .odctl folder in your current directory.
odctl init
2. Explore available profiles See a full list of technologies you can launch.
odctl list
3. Launch the streaming and batch processing engines Bring up a robust data engineering environment.
odctl up kafka-lite flink-lite spark-lite
Note: You do not need to memorize dependencies. The CLI will automatically detect that these profiles require foundational infrastructure and will launch PostgreSQL, SeaweedFS (S3), and the Iceberg REST Catalog for you before starting the target compute engines.
CLI Command Reference
The odctl CLI orchestrates the Open Data Stack and is logically grouped by functionality. You can append --help to any command for deeper parameter details.
Global Options
--verbose: Enable debug-level logging across all commands.-w, --workspace PATH: Path to the ODCTL workspace directory (default:./.odctl).
Inspection & Info
odctl list: List all available profiles and their capabilities.odctl explain <profile>: Explain the details, services, images, and dependencies of a profile.odctl ps: List Docker containers managed by the Open Data Stack.odctl info: View package and system-wide Docker daemon health status.
Host addresses in odctl explain use 127.0.0.1. With IPv6 enabled in Docker, localhost can reach a service's IPv6 address, and services that listen on IPv4 only reset the connection. localhost works when Docker's IPv6 is off.
Workspace
odctl init: Initialize a local.odctlworkspace for custom configurations.
Cluster Lifecycle
odctl pull: Pre-fetch Docker images without starting the containers.odctl up: Launch Open Data profiles (automatically resolves upstream dependencies).odctl down: Stop and remove profile containers and networks.
Management
odctl logs: Fetch the logs of containers managed by specific profiles.odctl restart: Restart one or more specific profiles, keeping their containers.odctl recreate: Replace one or more profiles' containers, which is what applies an edited compose file. Add--pullto refresh the images too.
restart and recreate differ in one way that matters: a restart bounces the process inside the existing container, so a new memory limit, port, image tag or environment variable never reaches it, while a recreate replaces the container from its current definition. Recreating therefore discards whatever that container held. Both act only on the profiles you name, unlike up, which stops the ones you leave out.
Examples
# View all profiles and exposed ports
$ odctl list -d

# See exactly what the kafka profile provisions
$ odctl explain kafka-lite

# Launch specific profiles
$ odctl up flink-lite kafka-lite spark-lite

# Complete teardown and wipe all data
$ odctl down --all --volumes
Workspace Customization (.odctl)
The Open Data Stack is designed to be fully hackable. When you run odctl init, a local ./.odctl/ workspace is generated in your current working directory.
This folder contains all the underlying configurations that power the stack:
compose-*.yml: The actual Docker Compose definitions. You can edit these to change exposed ports, adjust memory limits, or inject new environment variables.registry.yml: The internal dependency graph..env: The environment variables used across the stack (e.g., default credentials or timezones).trino/rules.json: Trino's file-based access control. The shipped policy is deliberately generic: it grants every identity full table privileges and deniesanalystschema ownership, and it names no catalog, schema or table, because those belong to your project rather than to this tool. Add your own table rules here for row filtering and column masking, and restart Trino afterwards, since the file is read at startup.
The CLI will always prioritize the files in your local ./.odctl/ directory. If you make a mistake, you can always revert to the pristine default state by running odctl init --force.
Related reading
Blog posts that use this CLI:
- Productionizing an Online Product Recommender using Event Driven Architecture: splits a contextual bandit recommender into a serving layer and a training layer on Kafka, Flink and Valkey.
- Introducing odctl: One CLI for a Local Open Data Stack: why the tool exists and how one command launches the stack.
- Building an Agentic Analytics System over an Iceberg Lakehouse: runs Trino, Iceberg and object storage from this CLI under a semantic layer an agent queries.
Local Development & Contributing
If you want to contribute to the CLI itself, we welcome pull requests!
- Clone the repository.
- Install uv for dependency management.
- Sync the dependencies and install the project in development mode:
uv sync - Install the pre-commit hooks to ensure formatting checks pass:
uv run pre-commit install
- Run the test suite:
uv run pytest tests/
License
This project is licensed under the Apache License 2.0. See the LICENSE file for details.
1 maintainer

Release files for odctl 0.9.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| odctl-0.9.0.tar.gz | 315.5 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| odctl-0.9.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 406.9 kB
Release files / odctl-0.9.0.tar.gz
| Download URL | odctl-0.9.0.tar.gz |
|---|---|
| Size | 315.5 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
de02a5160a3b3c4a1e714eb4ff01aac60efab44eaa83d060f7eddf1c8080fcf4
|
|
BLAKE2b-256 checksum How to use checksums |
91f56cab59d3304c3dfe46d3fb98d97bc1b8b93ec64666c304a2e782e76fa9df
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 25, 2026.
Transparency logRelease files / odctl-0.9.0-py3-none-any.whl
| Download URL | odctl-0.9.0-py3-none-any.whl |
|---|---|
| Size | 91.4 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
af8a419a8b1167eb0a865d48052221a288883ab70d38590983b0b0b18afff1a4
|
|
BLAKE2b-256 checksum How to use checksums |
6c698e3fe13e2fa67462a9ebff8160ec766f9dc546d847be66edc0ae98114fac
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 25, 2026.
Transparency log













